diff --git a/animation/hallo-83dd4eb/.github/workflows/static-check.yaml b/animation/hallo-83dd4eb/.github/workflows/static-check.yaml
new file mode 100644
index 0000000..0cfef51
--- /dev/null
+++ b/animation/hallo-83dd4eb/.github/workflows/static-check.yaml
@@ -0,0 +1,26 @@
+name: Pylint
+
+on: [push, pull_request]
+
+jobs:
+ static-check:
+ runs-on: ${{ matrix.os }}
+ strategy:
+ matrix:
+ os: [ubuntu-22.04]
+ python-version: ["3.10"]
+ steps:
+ - uses: actions/checkout@v3
+ - name: Set up Python ${{ matrix.python-version }}
+ uses: actions/setup-python@v3
+ with:
+ python-version: ${{ matrix.python-version }}
+ - name: Install dependencies
+ run: |
+ python -m pip install --upgrade pylint
+ python -m pip install --upgrade isort
+ python -m pip install -r requirements.txt
+ - name: Analysing the code with pylint
+ run: |
+ isort $(git ls-files '*.py') --check-only --diff
+ pylint $(git ls-files '*.py')
diff --git a/animation/hallo-83dd4eb/.gitignore b/animation/hallo-83dd4eb/.gitignore
new file mode 100644
index 0000000..137ede8
--- /dev/null
+++ b/animation/hallo-83dd4eb/.gitignore
@@ -0,0 +1,170 @@
+# running cache
+mlruns/
+
+# Test directories
+test_data/
+pretrained_models/
+
+# Poetry project
+poetry.lock
+
+# Byte-compiled / optimized / DLL files
+__pycache__/
+*.py[cod]
+*$py.class
+
+# C extensions
+*.so
+
+# Distribution / packaging
+.Python
+build/
+develop-eggs/
+dist/
+downloads/
+eggs/
+.eggs/
+lib/
+lib64/
+parts/
+sdist/
+var/
+wheels/
+share/python-wheels/
+*.egg-info/
+.installed.cfg
+*.egg
+MANIFEST
+
+# PyInstaller
+# Usually these files are written by a python script from a template
+# before PyInstaller builds the exe, so as to inject date/other infos into it.
+*.manifest
+*.spec
+
+# Installer logs
+pip-log.txt
+pip-delete-this-directory.txt
+
+# Unit test / coverage reports
+htmlcov/
+.tox/
+.nox/
+.coverage
+.coverage.*
+.cache
+nosetests.xml
+coverage.xml
+*.cover
+*.py,cover
+.hypothesis/
+.pytest_cache/
+cover/
+
+# Translations
+*.mo
+*.pot
+
+# Django stuff:
+*.log
+local_settings.py
+db.sqlite3
+db.sqlite3-journal
+
+# Flask stuff:
+instance/
+.webassets-cache
+
+# Scrapy stuff:
+.scrapy
+
+# Sphinx documentation
+docs/_build/
+
+# PyBuilder
+.pybuilder/
+target/
+
+# Jupyter Notebook
+.ipynb_checkpoints
+
+# IPython
+profile_default/
+ipython_config.py
+
+# pyenv
+# For a library or package, you might want to ignore these files since the code is
+# intended to run in multiple environments; otherwise, check them in:
+# .python-version
+
+# pipenv
+# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
+# However, in case of collaboration, if having platform-specific dependencies or dependencies
+# having no cross-platform support, pipenv may install dependencies that don't work, or not
+# install all needed dependencies.
+#Pipfile.lock
+
+# poetry
+# Similar to Pipfile.lock, it is generally recommended to include poetry.lock in version control.
+# This is especially recommended for binary packages to ensure reproducibility, and is more
+# commonly ignored for libraries.
+# https://python-poetry.org/docs/basic-usage/#commit-your-poetrylock-file-to-version-control
+#poetry.lock
+
+# pdm
+# Similar to Pipfile.lock, it is generally recommended to include pdm.lock in version control.
+#pdm.lock
+# pdm stores project-wide configurations in .pdm.toml, but it is recommended to not include it
+# in version control.
+# https://pdm.fming.dev/#use-with-ide
+.pdm.toml
+
+# PEP 582; used by e.g. github.com/David-OConnor/pyflow and github.com/pdm-project/pdm
+__pypackages__/
+
+# Celery stuff
+celerybeat-schedule
+celerybeat.pid
+
+# SageMath parsed files
+*.sage.py
+
+# Environments
+.env
+.venv
+env/
+venv/
+ENV/
+env.bak/
+venv.bak/
+
+# Spyder project settings
+.spyderproject
+.spyproject
+
+# Rope project settings
+.ropeproject
+
+# mkdocs documentation
+/site
+
+# mypy
+.mypy_cache/
+.dmypy.json
+dmypy.json
+
+# Pyre type checker
+.pyre/
+
+# pytype static type analyzer
+.pytype/
+
+# Cython debug symbols
+cython_debug/
+
+# IDE
+.idea/
+.vscode/
+data
+pretrained_models
+test_data
\ No newline at end of file
diff --git a/animation/hallo-83dd4eb/.pre-commit-config.yaml b/animation/hallo-83dd4eb/.pre-commit-config.yaml
new file mode 100644
index 0000000..855baf4
--- /dev/null
+++ b/animation/hallo-83dd4eb/.pre-commit-config.yaml
@@ -0,0 +1,17 @@
+repos:
+ - repo: local
+ hooks:
+ - id: isort
+ name: isort
+ language: system
+ types: [python]
+ pass_filenames: false
+ entry: isort
+ args: ["."]
+ - id: pylint
+ name: pylint
+ language: system
+ types: [python]
+ pass_filenames: false
+ entry: pylint
+ args: ["**/*.py"]
diff --git a/animation/hallo-83dd4eb/.pylintrc b/animation/hallo-83dd4eb/.pylintrc
new file mode 100644
index 0000000..784bf18
--- /dev/null
+++ b/animation/hallo-83dd4eb/.pylintrc
@@ -0,0 +1,633 @@
+[MAIN]
+
+# Analyse import fallback blocks. This can be used to support both Python 2 and
+# 3 compatible code, which means that the block might have code that exists
+# only in one or another interpreter, leading to false positives when analysed.
+analyse-fallback-blocks=no
+
+# Clear in-memory caches upon conclusion of linting. Useful if running pylint
+# in a server-like mode.
+clear-cache-post-run=no
+
+# Load and enable all available extensions. Use --list-extensions to see a list
+# all available extensions.
+#enable-all-extensions=
+
+# In error mode, messages with a category besides ERROR or FATAL are
+# suppressed, and no reports are done by default. Error mode is compatible with
+# disabling specific errors.
+#errors-only=
+
+# Always return a 0 (non-error) status code, even if lint errors are found.
+# This is primarily useful in continuous integration scripts.
+#exit-zero=
+
+# A comma-separated list of package or module names from where C extensions may
+# be loaded. Extensions are loading into the active Python interpreter and may
+# run arbitrary code.
+extension-pkg-allow-list=
+
+# A comma-separated list of package or module names from where C extensions may
+# be loaded. Extensions are loading into the active Python interpreter and may
+# run arbitrary code. (This is an alternative name to extension-pkg-allow-list
+# for backward compatibility.)
+extension-pkg-whitelist=cv2
+
+# Return non-zero exit code if any of these messages/categories are detected,
+# even if score is above --fail-under value. Syntax same as enable. Messages
+# specified are enabled, while categories only check already-enabled messages.
+fail-on=
+
+# Specify a score threshold under which the program will exit with error.
+fail-under=10
+
+# Interpret the stdin as a python script, whose filename needs to be passed as
+# the module_or_package argument.
+#from-stdin=
+
+# Files or directories to be skipped. They should be base names, not paths.
+ignore=CVS
+
+# Add files or directories matching the regular expressions patterns to the
+# ignore-list. The regex matches against paths and can be in Posix or Windows
+# format. Because '\\' represents the directory delimiter on Windows systems,
+# it can't be used as an escape character.
+ignore-paths=
+
+# Files or directories matching the regular expression patterns are skipped.
+# The regex matches against base names, not paths. The default value ignores
+# Emacs file locks
+ignore-patterns=^\.#
+
+# List of module names for which member attributes should not be checked
+# (useful for modules/projects where namespaces are manipulated during runtime
+# and thus existing member attributes cannot be deduced by static analysis). It
+# supports qualified module names, as well as Unix pattern matching.
+ignored-modules=cv2
+
+# Python code to execute, usually for sys.path manipulation such as
+# pygtk.require().
+init-hook='import sys; sys.path.append(".")'
+
+# Use multiple processes to speed up Pylint. Specifying 0 will auto-detect the
+# number of processors available to use, and will cap the count on Windows to
+# avoid hangs.
+jobs=1
+
+# Control the amount of potential inferred values when inferring a single
+# object. This can help the performance when dealing with large functions or
+# complex, nested conditions.
+limit-inference-results=100
+
+# List of plugins (as comma separated values of python module names) to load,
+# usually to register additional checkers.
+load-plugins=
+
+# Pickle collected data for later comparisons.
+persistent=yes
+
+# Minimum Python version to use for version dependent checks. Will default to
+# the version used to run pylint.
+py-version=3.10
+
+# Discover python modules and packages in the file system subtree.
+recursive=no
+
+# Add paths to the list of the source roots. Supports globbing patterns. The
+# source root is an absolute path or a path relative to the current working
+# directory used to determine a package namespace for modules located under the
+# source root.
+source-roots=
+
+# When enabled, pylint would attempt to guess common misconfiguration and emit
+# user-friendly hints instead of false-positive error messages.
+suggestion-mode=yes
+
+# Allow loading of arbitrary C extensions. Extensions are imported into the
+# active Python interpreter and may run arbitrary code.
+unsafe-load-any-extension=no
+
+# In verbose mode, extra non-checker-related info will be displayed.
+#verbose=
+
+
+[BASIC]
+
+# Naming style matching correct argument names.
+argument-naming-style=snake_case
+
+# Regular expression matching correct argument names. Overrides argument-
+# naming-style. If left empty, argument names will be checked with the set
+# naming style.
+#argument-rgx=
+
+# Naming style matching correct attribute names.
+attr-naming-style=snake_case
+
+# Regular expression matching correct attribute names. Overrides attr-naming-
+# style. If left empty, attribute names will be checked with the set naming
+# style.
+#attr-rgx=
+
+# Bad variable names which should always be refused, separated by a comma.
+bad-names=foo,
+ bar,
+ baz,
+ toto,
+ tutu,
+ tata
+
+# Bad variable names regexes, separated by a comma. If names match any regex,
+# they will always be refused
+bad-names-rgxs=
+
+# Naming style matching correct class attribute names.
+class-attribute-naming-style=any
+
+# Regular expression matching correct class attribute names. Overrides class-
+# attribute-naming-style. If left empty, class attribute names will be checked
+# with the set naming style.
+#class-attribute-rgx=
+
+# Naming style matching correct class constant names.
+class-const-naming-style=UPPER_CASE
+
+# Regular expression matching correct class constant names. Overrides class-
+# const-naming-style. If left empty, class constant names will be checked with
+# the set naming style.
+#class-const-rgx=
+
+# Naming style matching correct class names.
+class-naming-style=PascalCase
+
+# Regular expression matching correct class names. Overrides class-naming-
+# style. If left empty, class names will be checked with the set naming style.
+#class-rgx=
+
+# Naming style matching correct constant names.
+const-naming-style=UPPER_CASE
+
+# Regular expression matching correct constant names. Overrides const-naming-
+# style. If left empty, constant names will be checked with the set naming
+# style.
+#const-rgx=
+
+# Minimum line length for functions/classes that require docstrings, shorter
+# ones are exempt.
+docstring-min-length=-1
+
+# Naming style matching correct function names.
+function-naming-style=snake_case
+
+# Regular expression matching correct function names. Overrides function-
+# naming-style. If left empty, function names will be checked with the set
+# naming style.
+#function-rgx=
+
+# Good variable names which should always be accepted, separated by a comma.
+good-names=i,
+ j,
+ k,
+ ex,
+ Run,
+ _
+
+# Good variable names regexes, separated by a comma. If names match any regex,
+# they will always be accepted
+good-names-rgxs=
+
+# Include a hint for the correct naming format with invalid-name.
+include-naming-hint=no
+
+# Naming style matching correct inline iteration names.
+inlinevar-naming-style=any
+
+# Regular expression matching correct inline iteration names. Overrides
+# inlinevar-naming-style. If left empty, inline iteration names will be checked
+# with the set naming style.
+#inlinevar-rgx=
+
+# Naming style matching correct method names.
+method-naming-style=snake_case
+
+# Regular expression matching correct method names. Overrides method-naming-
+# style. If left empty, method names will be checked with the set naming style.
+#method-rgx=
+
+# Naming style matching correct module names.
+module-naming-style=snake_case
+
+# Regular expression matching correct module names. Overrides module-naming-
+# style. If left empty, module names will be checked with the set naming style.
+#module-rgx=
+
+# Colon-delimited sets of names that determine each other's naming style when
+# the name regexes allow several styles.
+name-group=
+
+# Regular expression which should only match function or class names that do
+# not require a docstring.
+no-docstring-rgx=^_
+
+# List of decorators that produce properties, such as abc.abstractproperty. Add
+# to this list to register other decorators that produce valid properties.
+# These decorators are taken in consideration only for invalid-name.
+property-classes=abc.abstractproperty
+
+# Regular expression matching correct type alias names. If left empty, type
+# alias names will be checked with the set naming style.
+#typealias-rgx=
+
+# Regular expression matching correct type variable names. If left empty, type
+# variable names will be checked with the set naming style.
+#typevar-rgx=
+
+# Naming style matching correct variable names.
+variable-naming-style=snake_case
+
+# Regular expression matching correct variable names. Overrides variable-
+# naming-style. If left empty, variable names will be checked with the set
+# naming style.
+variable-rgx=(_?[a-z][A-Za-z0-9]{0,30})|([A-Z0-9]{1,30})
+
+
+[CLASSES]
+
+# Warn about protected attribute access inside special methods
+check-protected-access-in-special-methods=no
+
+# List of method names used to declare (i.e. assign) instance attributes.
+defining-attr-methods=__init__,
+ __new__,
+ setUp,
+ asyncSetUp,
+ __post_init__
+
+# List of member names, which should be excluded from the protected access
+# warning.
+exclude-protected=_asdict,_fields,_replace,_source,_make,os._exit
+
+# List of valid names for the first argument in a class method.
+valid-classmethod-first-arg=cls
+
+# List of valid names for the first argument in a metaclass class method.
+valid-metaclass-classmethod-first-arg=mcs
+
+
+[DESIGN]
+
+# List of regular expressions of class ancestor names to ignore when counting
+# public methods (see R0903)
+exclude-too-few-public-methods=
+
+# List of qualified class names to ignore when counting class parents (see
+# R0901)
+ignored-parents=
+
+# Maximum number of arguments for function / method.
+max-args=7
+
+# Maximum number of attributes for a class (see R0902).
+max-attributes=20
+
+# Maximum number of boolean expressions in an if statement (see R0916).
+max-bool-expr=5
+
+# Maximum number of branch for function / method body.
+max-branches=12
+
+# Maximum number of locals for function / method body.
+max-locals=15
+
+# Maximum number of parents for a class (see R0901).
+max-parents=7
+
+# Maximum number of public methods for a class (see R0904).
+max-public-methods=20
+
+# Maximum number of return / yield for function / method body.
+max-returns=6
+
+# Maximum number of statements in function / method body.
+max-statements=300
+
+# Minimum number of public methods for a class (see R0903).
+min-public-methods=1
+
+
+[EXCEPTIONS]
+
+# Exceptions that will emit a warning when caught.
+overgeneral-exceptions=builtins.BaseException,builtins.Exception
+
+
+[FORMAT]
+
+# Expected format of line ending, e.g. empty (any line ending), LF or CRLF.
+expected-line-ending-format=
+
+# Regexp for a line that is allowed to be longer than the limit.
+ignore-long-lines=^\s*(# )??$
+
+# Number of spaces of indent required inside a hanging or continued line.
+indent-after-paren=4
+
+# String used as indentation unit. This is usually " " (4 spaces) or "\t" (1
+# tab).
+indent-string=' '
+
+# Maximum number of characters on a single line.
+max-line-length=150
+
+# Maximum number of lines in a module.
+max-module-lines=2000
+
+# Allow the body of a class to be on the same line as the declaration if body
+# contains single statement.
+single-line-class-stmt=no
+
+# Allow the body of an if to be on the same line as the test if there is no
+# else.
+single-line-if-stmt=no
+
+
+[IMPORTS]
+
+# List of modules that can be imported at any level, not just the top level
+# one.
+allow-any-import-level=
+
+# Allow explicit reexports by alias from a package __init__.
+allow-reexport-from-package=no
+
+# Allow wildcard imports from modules that define __all__.
+allow-wildcard-with-all=no
+
+# Deprecated modules which should not be used, separated by a comma.
+deprecated-modules=
+
+# Output a graph (.gv or any supported image format) of external dependencies
+# to the given file (report RP0402 must not be disabled).
+ext-import-graph=
+
+# Output a graph (.gv or any supported image format) of all (i.e. internal and
+# external) dependencies to the given file (report RP0402 must not be
+# disabled).
+import-graph=
+
+# Output a graph (.gv or any supported image format) of internal dependencies
+# to the given file (report RP0402 must not be disabled).
+int-import-graph=
+
+# Force import order to recognize a module as part of the standard
+# compatibility libraries.
+known-standard-library=
+
+# Force import order to recognize a module as part of a third party library.
+known-third-party=enchant
+
+# Couples of modules and preferred modules, separated by a comma.
+preferred-modules=
+
+
+[LOGGING]
+
+# The type of string formatting that logging methods do. `old` means using %
+# formatting, `new` is for `{}` formatting.
+logging-format-style=old
+
+# Logging modules to check that the string format arguments are in logging
+# function parameter format.
+logging-modules=logging
+
+
+[MESSAGES CONTROL]
+
+# Only show warnings with the listed confidence levels. Leave empty to show
+# all. Valid levels: HIGH, CONTROL_FLOW, INFERENCE, INFERENCE_FAILURE,
+# UNDEFINED.
+confidence=HIGH,
+ CONTROL_FLOW,
+ INFERENCE,
+ INFERENCE_FAILURE,
+ UNDEFINED
+
+# Disable the message, report, category or checker with the given id(s). You
+# can either give multiple identifiers separated by comma (,) or put this
+# option multiple times (only on the command line, not in the configuration
+# file where it should appear only once). You can also use "--disable=all" to
+# disable everything first and then re-enable specific checks. For example, if
+# you want to run only the similarities checker, you can use "--disable=all
+# --enable=similarities". If you want to run only the classes checker, but have
+# no Warning level messages displayed, use "--disable=all --enable=classes
+# --disable=W".
+disable=too-many-arguments,
+ too-many-locals,
+ too-many-branches,
+ protected-access
+
+
+# Enable the message, report, category or checker with the given id(s). You can
+# either give multiple identifier separated by comma (,) or put this option
+# multiple time (only on the command line, not in the configuration file where
+# it should appear only once). See also the "--disable" option for examples.
+enable=
+
+
+[METHOD_ARGS]
+
+# List of qualified names (i.e., library.method) which require a timeout
+# parameter e.g. 'requests.api.get,requests.api.post'
+timeout-methods=requests.api.delete,requests.api.get,requests.api.head,requests.api.options,requests.api.patch,requests.api.post,requests.api.put,requests.api.request
+
+
+[MISCELLANEOUS]
+
+# List of note tags to take in consideration, separated by a comma.
+notes=FIXME,
+ XXX
+
+# Regular expression of note tags to take in consideration.
+notes-rgx=
+
+
+[REFACTORING]
+
+# Maximum number of nested blocks for function / method body
+max-nested-blocks=5
+
+# Complete name of functions that never returns. When checking for
+# inconsistent-return-statements if a never returning function is called then
+# it will be considered as an explicit return statement and no message will be
+# printed.
+never-returning-functions=sys.exit,argparse.parse_error
+
+# Let 'consider-using-join' be raised when the separator to join on would be
+# non-empty (resulting in expected fixes of the type: ``"- " + " -
+# ".join(items)``)
+# suggest-join-with-non-empty-separator=yes
+
+
+[REPORTS]
+
+# Python expression which should return a score less than or equal to 10. You
+# have access to the variables 'fatal', 'error', 'warning', 'refactor',
+# 'convention', and 'info' which contain the number of messages in each
+# category, as well as 'statement' which is the total number of statements
+# analyzed. This score is used by the global evaluation report (RP0004).
+evaluation=max(0, 0 if fatal else 10.0 - ((float(5 * error + warning + refactor + convention) / statement) * 10))
+
+# Template used to display messages. This is a python new-style format string
+# used to format the message information. See doc for all details.
+msg-template=
+
+# Set the output format. Available formats are: text, parseable, colorized,
+# json2 (improved json format), json (old json format) and msvs (visual
+# studio). You can also give a reporter class, e.g.
+# mypackage.mymodule.MyReporterClass.
+#output-format=
+
+# Tells whether to display a full report or only the messages.
+reports=no
+
+# Activate the evaluation score.
+score=yes
+
+
+[SIMILARITIES]
+
+# Comments are removed from the similarity computation
+ignore-comments=yes
+
+# Docstrings are removed from the similarity computation
+ignore-docstrings=yes
+
+# Imports are removed from the similarity computation
+ignore-imports=yes
+
+# Signatures are removed from the similarity computation
+ignore-signatures=yes
+
+# Minimum lines number of a similarity.
+min-similarity-lines=4
+
+
+[SPELLING]
+
+# Limits count of emitted suggestions for spelling mistakes.
+max-spelling-suggestions=4
+
+# Spelling dictionary name. No available dictionaries : You need to install
+# both the python package and the system dependency for enchant to work.
+spelling-dict=
+
+# List of comma separated words that should be considered directives if they
+# appear at the beginning of a comment and should not be checked.
+spelling-ignore-comment-directives=fmt: on,fmt: off,noqa:,noqa,nosec,isort:skip,mypy:
+
+# List of comma separated words that should not be checked.
+spelling-ignore-words=
+
+# A path to a file that contains the private dictionary; one word per line.
+spelling-private-dict-file=
+
+# Tells whether to store unknown words to the private dictionary (see the
+# --spelling-private-dict-file option) instead of raising a message.
+spelling-store-unknown-words=no
+
+
+[STRING]
+
+# This flag controls whether inconsistent-quotes generates a warning when the
+# character used as a quote delimiter is used inconsistently within a module.
+check-quote-consistency=no
+
+# This flag controls whether the implicit-str-concat should generate a warning
+# on implicit string concatenation in sequences defined over several lines.
+check-str-concat-over-line-jumps=no
+
+
+[TYPECHECK]
+
+# List of decorators that produce context managers, such as
+# contextlib.contextmanager. Add to this list to register other decorators that
+# produce valid context managers.
+contextmanager-decorators=contextlib.contextmanager
+
+# List of members which are set dynamically and missed by pylint inference
+# system, and so shouldn't trigger E1101 when accessed. Python regular
+# expressions are accepted.
+generated-members=
+
+# Tells whether to warn about missing members when the owner of the attribute
+# is inferred to be None.
+ignore-none=yes
+
+# This flag controls whether pylint should warn about no-member and similar
+# checks whenever an opaque object is returned when inferring. The inference
+# can return multiple potential results while evaluating a Python object, but
+# some branches might not be evaluated, which results in partial inference. In
+# that case, it might be useful to still emit no-member and other checks for
+# the rest of the inferred objects.
+ignore-on-opaque-inference=yes
+
+# List of symbolic message names to ignore for Mixin members.
+ignored-checks-for-mixins=no-member,
+ not-async-context-manager,
+ not-context-manager,
+ attribute-defined-outside-init
+
+# List of class names for which member attributes should not be checked (useful
+# for classes with dynamically set attributes). This supports the use of
+# qualified names.
+ignored-classes=optparse.Values,thread._local,_thread._local,argparse.Namespace
+
+# Show a hint with possible names when a member name was not found. The aspect
+# of finding the hint is based on edit distance.
+missing-member-hint=yes
+
+# The minimum edit distance a name should have in order to be considered a
+# similar match for a missing member name.
+missing-member-hint-distance=1
+
+# The total number of similar names that should be taken in consideration when
+# showing a hint for a missing member.
+missing-member-max-choices=1
+
+# Regex pattern to define which classes are considered mixins.
+mixin-class-rgx=.*[Mm]ixin
+
+# List of decorators that change the signature of a decorated function.
+signature-mutators=
+
+
+[VARIABLES]
+
+# List of additional names supposed to be defined in builtins. Remember that
+# you should avoid defining new builtins when possible.
+additional-builtins=
+
+# Tells whether unused global variables should be treated as a violation.
+allow-global-unused-variables=yes
+
+# List of names allowed to shadow builtins
+allowed-redefined-builtins=
+
+# List of strings which can identify a callback function by name. A callback
+# name must start or end with one of those strings.
+callbacks=cb_,
+ _cb
+
+# A regular expression matching the name of dummy variables (i.e. expected to
+# not be used).
+dummy-variables-rgx=_+$|(_[a-zA-Z0-9_]*[a-zA-Z0-9]+?$)|dummy|^ignored_|^unused_
+
+# Argument names that match this expression will be ignored.
+ignored-argument-names=_.*|^ignored_|^unused_
+
+# Tells whether we should check for unused import in __init__ files.
+init-import=no
+
+# List of qualified module names which can have objects that can redefine
+# builtins.
+redefining-builtins-modules=six.moves,past.builtins,future.builtins,builtins,io
diff --git a/animation/hallo-83dd4eb/LICENSE b/animation/hallo-83dd4eb/LICENSE
new file mode 100644
index 0000000..77e0c56
--- /dev/null
+++ b/animation/hallo-83dd4eb/LICENSE
@@ -0,0 +1,21 @@
+MIT License
+
+Copyright (c) 2024 Fusion Lab: Generative Vision Lab of Fudan University
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in all
+copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
+SOFTWARE.
diff --git a/animation/hallo-83dd4eb/README.md b/animation/hallo-83dd4eb/README.md
new file mode 100644
index 0000000..34c3ef7
--- /dev/null
+++ b/animation/hallo-83dd4eb/README.md
@@ -0,0 +1,399 @@
+Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
+
+
+
+
+
+ 1Fudan University 2Baidu Inc 3ETH Zurich 4Nanjing University
+
+
+
+
+
+
+
+## 📸 Showcase
+
+
+https://github.com/fudan-generative-vision/hallo/assets/17402682/9d1a0de4-3470-4d38-9e4f-412f517f834c
+
+### 🎬 Honoring Classic Films
+
+
+
+ | Devil Wears Prada |
+ Green Book |
+ Infernal Affairs |
+
+
+  |
+ 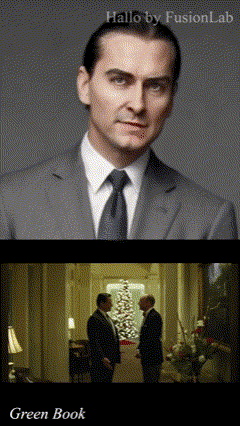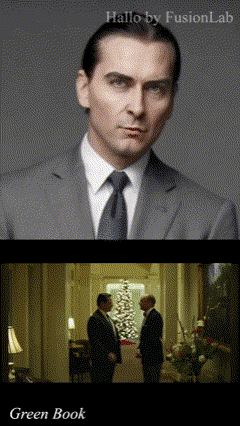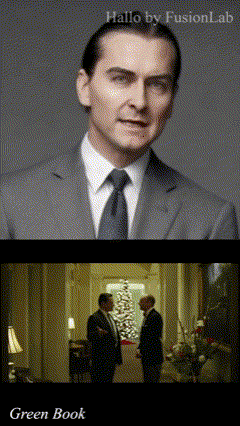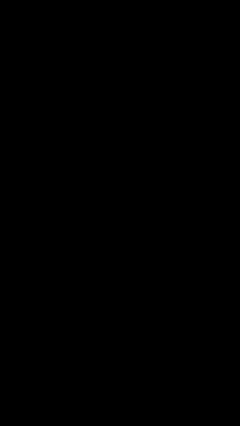 |
+  |
+
+
+ | Patch Adams |
+ Tough Love |
+ Shawshank Redemption |
+
+
+  |
+  |
+  |
+
+
+
+Explore [more examples](https://fudan-generative-vision.github.io/hallo).
+
+## 📰 News
+
+- **`2024/06/28`**: 🎉🎉🎉 We are proud to announce the release of our model training code. Try your own training data. Here is [tutorial](#training).
+- **`2024/06/21`**: 🚀🚀🚀 Cloned a Gradio demo on [🤗Huggingface space](https://huggingface.co/spaces/fudan-generative-ai/hallo).
+- **`2024/06/20`**: 🌟🌟🌟 Received numerous contributions from the community, including a [Windows version](https://github.com/sdbds/hallo-for-windows), [ComfyUI](https://github.com/AIFSH/ComfyUI-Hallo), [WebUI](https://github.com/fudan-generative-vision/hallo/pull/51), and [Docker template](https://github.com/ashleykleynhans/hallo-docker).
+- **`2024/06/15`**: ✨✨✨ Released some images and audios for inference testing on [🤗Huggingface](https://huggingface.co/datasets/fudan-generative-ai/hallo_inference_samples).
+- **`2024/06/15`**: 🎉🎉🎉 Launched the first version on 🫡[GitHub](https://github.com/fudan-generative-vision/hallo).
+
+## 🤝 Community Resources
+
+Explore the resources developed by our community to enhance your experience with Hallo:
+
+- [TTS x Hallo Talking Portrait Generator](https://huggingface.co/spaces/fffiloni/tts-hallo-talking-portrait) - Check out this awesome Gradio demo by [@Sylvain Filoni](https://huggingface.co/fffiloni)! With this tool, you can conveniently prepare portrait image and audio for Hallo.
+- [Demo on Huggingface](https://huggingface.co/spaces/multimodalart/hallo) - Check out this easy-to-use Gradio demo by [@multimodalart](https://huggingface.co/multimodalart).
+- [hallo-webui](https://github.com/daswer123/hallo-webui) - Explore the WebUI created by [@daswer123](https://github.com/daswer123).
+- [hallo-for-windows](https://github.com/sdbds/hallo-for-windows) - Utilize Hallo on Windows with the guide by [@sdbds](https://github.com/sdbds).
+- [ComfyUI-Hallo](https://github.com/AIFSH/ComfyUI-Hallo) - Integrate Hallo with the ComfyUI tool by [@AIFSH](https://github.com/AIFSH).
+- [hallo-docker](https://github.com/ashleykleynhans/hallo-docker) - Docker image for Hallo by [@ashleykleynhans](https://github.com/ashleykleynhans).
+- [RunPod Template](https://runpod.io/console/deploy?template=aeyibwyvzy&ref=2xxro4syy) - Deploy Hallo to RunPod by [@ashleykleynhans](https://github.com/ashleykleynhans).
+
+Thanks to all of them.
+
+Join our community and explore these amazing resources to make the most out of Hallo. Enjoy and elevate their creative projects!
+
+## 🔧️ Framework
+
+
+
+
+## ⚙️ Installation
+
+- System requirement: Ubuntu 20.04/Ubuntu 22.04, Cuda 12.1
+- Tested GPUs: A100
+
+Create conda environment:
+
+```bash
+ conda create -n hallo python=3.10
+ conda activate hallo
+```
+
+Install packages with `pip`
+
+```bash
+ pip install -r requirements.txt
+ pip install .
+```
+
+Besides, ffmpeg is also needed:
+```bash
+ apt-get install ffmpeg
+```
+
+## 🗝️️ Usage
+
+The entry point for inference is `scripts/inference.py`. Before testing your cases, two preparations need to be completed:
+
+1. [Download all required pretrained models](#download-pretrained-models).
+2. [Prepare source image and driving audio pairs](#prepare-inference-data).
+3. [Run inference](#run-inference).
+
+### 📥 Download Pretrained Models
+
+You can easily get all pretrained models required by inference from our [HuggingFace repo](https://huggingface.co/fudan-generative-ai/hallo).
+
+Clone the pretrained models into `${PROJECT_ROOT}/pretrained_models` directory by cmd below:
+
+```shell
+git lfs install
+git clone https://huggingface.co/fudan-generative-ai/hallo pretrained_models
+```
+
+Or you can download them separately from their source repo:
+
+- [hallo](https://huggingface.co/fudan-generative-ai/hallo/tree/main/hallo): Our checkpoints consist of denoising UNet, face locator, image & audio proj.
+- [audio_separator](https://huggingface.co/huangjackson/Kim_Vocal_2): Kim\_Vocal\_2 MDX-Net vocal removal model. (_Thanks to [KimberleyJensen](https://github.com/KimberleyJensen)_)
+- [insightface](https://github.com/deepinsight/insightface/tree/master/python-package#model-zoo): 2D and 3D Face Analysis placed into `pretrained_models/face_analysis/models/`. (_Thanks to deepinsight_)
+- [face landmarker](https://storage.googleapis.com/mediapipe-models/face_landmarker/face_landmarker/float16/1/face_landmarker.task): Face detection & mesh model from [mediapipe](https://ai.google.dev/edge/mediapipe/solutions/vision/face_landmarker#models) placed into `pretrained_models/face_analysis/models`.
+- [motion module](https://github.com/guoyww/AnimateDiff/blob/main/README.md#202309-animatediff-v2): motion module from [AnimateDiff](https://github.com/guoyww/AnimateDiff). (_Thanks to [guoyww](https://github.com/guoyww)_).
+- [sd-vae-ft-mse](https://huggingface.co/stabilityai/sd-vae-ft-mse): Weights are intended to be used with the diffusers library. (_Thanks to [stablilityai](https://huggingface.co/stabilityai)_)
+- [StableDiffusion V1.5](https://huggingface.co/runwayml/stable-diffusion-v1-5): Initialized and fine-tuned from Stable-Diffusion-v1-2. (_Thanks to [runwayml](https://huggingface.co/runwayml)_)
+- [wav2vec](https://huggingface.co/facebook/wav2vec2-base-960h): wav audio to vector model from [Facebook](https://huggingface.co/facebook/wav2vec2-base-960h).
+
+Finally, these pretrained models should be organized as follows:
+
+```text
+./pretrained_models/
+|-- audio_separator/
+| |-- download_checks.json
+| |-- mdx_model_data.json
+| |-- vr_model_data.json
+| `-- Kim_Vocal_2.onnx
+|-- face_analysis/
+| `-- models/
+| |-- face_landmarker_v2_with_blendshapes.task # face landmarker model from mediapipe
+| |-- 1k3d68.onnx
+| |-- 2d106det.onnx
+| |-- genderage.onnx
+| |-- glintr100.onnx
+| `-- scrfd_10g_bnkps.onnx
+|-- motion_module/
+| `-- mm_sd_v15_v2.ckpt
+|-- sd-vae-ft-mse/
+| |-- config.json
+| `-- diffusion_pytorch_model.safetensors
+|-- stable-diffusion-v1-5/
+| `-- unet/
+| |-- config.json
+| `-- diffusion_pytorch_model.safetensors
+`-- wav2vec/
+ `-- wav2vec2-base-960h/
+ |-- config.json
+ |-- feature_extractor_config.json
+ |-- model.safetensors
+ |-- preprocessor_config.json
+ |-- special_tokens_map.json
+ |-- tokenizer_config.json
+ `-- vocab.json
+```
+
+### 🛠️ Prepare Inference Data
+
+Hallo has a few simple requirements for input data:
+
+For the source image:
+
+1. It should be cropped into squares.
+2. The face should be the main focus, making up 50%-70% of the image.
+3. The face should be facing forward, with a rotation angle of less than 30° (no side profiles).
+
+For the driving audio:
+
+1. It must be in WAV format.
+2. It must be in English since our training datasets are only in this language.
+3. Ensure the vocals are clear; background music is acceptable.
+
+We have provided [some samples](examples/) for your reference.
+
+### 🎮 Run Inference
+
+Simply to run the `scripts/inference.py` and pass `source_image` and `driving_audio` as input:
+
+```bash
+python scripts/inference.py --source_image examples/reference_images/1.jpg --driving_audio examples/driving_audios/1.wav
+```
+
+Animation results will be saved as `${PROJECT_ROOT}/.cache/output.mp4` by default. You can pass `--output` to specify the output file name. You can find more examples for inference at [examples folder](https://github.com/fudan-generative-vision/hallo/tree/main/examples).
+
+For more options:
+
+```shell
+usage: inference.py [-h] [-c CONFIG] [--source_image SOURCE_IMAGE] [--driving_audio DRIVING_AUDIO] [--output OUTPUT] [--pose_weight POSE_WEIGHT]
+ [--face_weight FACE_WEIGHT] [--lip_weight LIP_WEIGHT] [--face_expand_ratio FACE_EXPAND_RATIO]
+
+options:
+ -h, --help show this help message and exit
+ -c CONFIG, --config CONFIG
+ --source_image SOURCE_IMAGE
+ source image
+ --driving_audio DRIVING_AUDIO
+ driving audio
+ --output OUTPUT output video file name
+ --pose_weight POSE_WEIGHT
+ weight of pose
+ --face_weight FACE_WEIGHT
+ weight of face
+ --lip_weight LIP_WEIGHT
+ weight of lip
+ --face_expand_ratio FACE_EXPAND_RATIO
+ face region
+```
+
+## Training
+
+### Prepare Data for Training
+
+The training data, which utilizes some talking-face videos similar to the source images used for inference, also needs to meet the following requirements:
+
+1. It should be cropped into squares.
+2. The face should be the main focus, making up 50%-70% of the image.
+3. The face should be facing forward, with a rotation angle of less than 30° (no side profiles).
+
+Organize your raw videos into the following directory structure:
+
+
+```text
+dataset_name/
+|-- videos/
+| |-- 0001.mp4
+| |-- 0002.mp4
+| |-- 0003.mp4
+| `-- 0004.mp4
+```
+
+You can use any `dataset_name`, but ensure the `videos` directory is named as shown above.
+
+Next, process the videos with the following commands:
+
+```bash
+python -m scripts.data_preprocess --input_dir dataset_name/videos --step 1
+python -m scripts.data_preprocess --input_dir dataset_name/videos --step 2
+```
+
+**Note:** Execute steps 1 and 2 sequentially as they perform different tasks. Step 1 converts videos into frames, extracts audio from each video, and generates the necessary masks. Step 2 generates face embeddings using InsightFace and audio embeddings using Wav2Vec, and requires a GPU. For parallel processing, use the `-p` and `-r` arguments. The `-p` argument specifies the total number of instances to launch, dividing the data into `p` parts. The `-r` argument specifies which part the current process should handle. You need to manually launch multiple instances with different values for `-r`.
+
+Generate the metadata JSON files with the following commands:
+
+```bash
+python scripts/extract_meta_info_stage1.py -r path/to/dataset -n dataset_name
+python scripts/extract_meta_info_stage2.py -r path/to/dataset -n dataset_name
+```
+
+Replace `path/to/dataset` with the path to the parent directory of `videos`, such as `dataset_name` in the example above. This will generate `dataset_name_stage1.json` and `dataset_name_stage2.json` in the `./data` directory.
+
+### Training
+
+Update the data meta path settings in the configuration YAML files, `configs/train/stage1.yaml` and `configs/train/stage2.yaml`:
+
+
+```yaml
+#stage1.yaml
+data:
+ meta_paths:
+ - ./data/dataset_name_stage1.json
+
+#stage2.yaml
+data:
+ meta_paths:
+ - ./data/dataset_name_stage2.json
+```
+
+Start training with the following command:
+
+```shell
+accelerate launch -m \
+ --config_file accelerate_config.yaml \
+ --machine_rank 0 \
+ --main_process_ip 0.0.0.0 \
+ --main_process_port 20055 \
+ --num_machines 1 \
+ --num_processes 8 \
+ scripts.train_stage1 --config ./configs/train/stage1.yaml
+```
+
+#### Accelerate Usage Explanation
+
+The `accelerate launch` command is used to start the training process with distributed settings.
+
+```shell
+accelerate launch [arguments] {training_script} --{training_script-argument-1} --{training_script-argument-2} ...
+```
+
+**Arguments for Accelerate:**
+
+- `-m, --module`: Interpret the launch script as a Python module.
+- `--config_file`: Configuration file for Hugging Face Accelerate.
+- `--machine_rank`: Rank of the current machine in a multi-node setup.
+- `--main_process_ip`: IP address of the master node.
+- `--main_process_port`: Port of the master node.
+- `--num_machines`: Total number of nodes participating in the training.
+- `--num_processes`: Total number of processes for training, matching the total number of GPUs across all machines.
+
+**Arguments for Training:**
+
+- `{training_script}`: The training script, such as `scripts.train_stage1` or `scripts.train_stage2`.
+- `--{training_script-argument-1}`: Arguments specific to the training script. Our training scripts accept one argument, `--config`, to specify the training configuration file.
+
+For multi-node training, you need to manually run the command with different `machine_rank` on each node separately.
+
+For more settings, refer to the [Accelerate documentation](https://huggingface.co/docs/accelerate/en/index).
+
+## 📅️ Roadmap
+
+| Status | Milestone | ETA |
+| :----: | :---------------------------------------------------------------------------------------------------- | :--------: |
+| ✅ | **[Inference source code meet everyone on GitHub](https://github.com/fudan-generative-vision/hallo)** | 2024-06-15 |
+| ✅ | **[Pretrained models on Huggingface](https://huggingface.co/fudan-generative-ai/hallo)** | 2024-06-15 |
+| ✅ | **[Releasing data preparation and training scripts](#training)** | 2024-06-28 |
+| 🚀 | **[Improving the model's performance on Mandarin Chinese]()** | TBD |
+
+
+Other Enhancements
+
+- [x] Enhancement: Test and ensure compatibility with Windows operating system. [#39](https://github.com/fudan-generative-vision/hallo/issues/39)
+- [x] Bug: Output video may lose several frames. [#41](https://github.com/fudan-generative-vision/hallo/issues/41)
+- [ ] Bug: Sound volume affecting inference results (audio normalization).
+- [ ] ~~Enhancement: Inference code logic optimization~~. This solution doesn't show significant performance improvements. Trying other approaches.
+
+
+
+
+## 📝 Citation
+
+If you find our work useful for your research, please consider citing the paper:
+
+```
+@misc{xu2024hallo,
+ title={Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation},
+ author={Mingwang Xu and Hui Li and Qingkun Su and Hanlin Shang and Liwei Zhang and Ce Liu and Jingdong Wang and Yao Yao and Siyu zhu},
+ year={2024},
+ eprint={2406.08801},
+ archivePrefix={arXiv},
+ primaryClass={cs.CV}
+}
+```
+
+## 🌟 Opportunities Available
+
+Multiple research positions are open at the **Generative Vision Lab, Fudan University**! Include:
+
+- Research assistant
+- Postdoctoral researcher
+- PhD candidate
+- Master students
+
+Interested individuals are encouraged to contact us at [siyuzhu@fudan.edu.cn](mailto://siyuzhu@fudan.edu.cn) for further information.
+
+## ⚠️ Social Risks and Mitigations
+
+The development of portrait image animation technologies driven by audio inputs poses social risks, such as the ethical implications of creating realistic portraits that could be misused for deepfakes. To mitigate these risks, it is crucial to establish ethical guidelines and responsible use practices. Privacy and consent concerns also arise from using individuals' images and voices. Addressing these involves transparent data usage policies, informed consent, and safeguarding privacy rights. By addressing these risks and implementing mitigations, the research aims to ensure the responsible and ethical development of this technology.
+
+## 🤗 Acknowledgements
+
+We would like to thank the contributors to the [magic-animate](https://github.com/magic-research/magic-animate), [AnimateDiff](https://github.com/guoyww/AnimateDiff), [ultimatevocalremovergui](https://github.com/Anjok07/ultimatevocalremovergui), [AniPortrait](https://github.com/Zejun-Yang/AniPortrait) and [Moore-AnimateAnyone](https://github.com/MooreThreads/Moore-AnimateAnyone) repositories, for their open research and exploration.
+
+If we missed any open-source projects or related articles, we would like to complement the acknowledgement of this specific work immediately.
+
+## 👏 Community Contributors
+
+Thank you to all the contributors who have helped to make this project better!
+
+
+  +
diff --git a/animation/hallo-83dd4eb/accelerate_config.yaml b/animation/hallo-83dd4eb/accelerate_config.yaml
new file mode 100644
index 0000000..6fa766f
--- /dev/null
+++ b/animation/hallo-83dd4eb/accelerate_config.yaml
@@ -0,0 +1,21 @@
+compute_environment: LOCAL_MACHINE
+debug: true
+deepspeed_config:
+ deepspeed_multinode_launcher: standard
+ gradient_accumulation_steps: 1
+ offload_optimizer_device: none
+ offload_param_device: none
+ zero3_init_flag: false
+ zero_stage: 2
+distributed_type: DEEPSPEED
+downcast_bf16: "no"
+main_training_function: main
+mixed_precision: "fp16"
+num_machines: 1
+num_processes: 8
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
diff --git a/animation/hallo-83dd4eb/assets/framework.png b/animation/hallo-83dd4eb/assets/framework.png
new file mode 100644
index 0000000..2ed98db
Binary files /dev/null and b/animation/hallo-83dd4eb/assets/framework.png differ
diff --git a/animation/hallo-83dd4eb/assets/framework_1.jpg b/animation/hallo-83dd4eb/assets/framework_1.jpg
new file mode 100644
index 0000000..72de2f8
Binary files /dev/null and b/animation/hallo-83dd4eb/assets/framework_1.jpg differ
diff --git a/animation/hallo-83dd4eb/assets/framework_2.jpg b/animation/hallo-83dd4eb/assets/framework_2.jpg
new file mode 100644
index 0000000..bf9344c
Binary files /dev/null and b/animation/hallo-83dd4eb/assets/framework_2.jpg differ
diff --git a/animation/hallo-83dd4eb/assets/wechat.jpeg b/animation/hallo-83dd4eb/assets/wechat.jpeg
new file mode 100644
index 0000000..f641fd9
Binary files /dev/null and b/animation/hallo-83dd4eb/assets/wechat.jpeg differ
diff --git a/animation/hallo-83dd4eb/configs/inference/.gitkeep b/animation/hallo-83dd4eb/configs/inference/.gitkeep
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/configs/inference/default.yaml b/animation/hallo-83dd4eb/configs/inference/default.yaml
new file mode 100644
index 0000000..f755bde
--- /dev/null
+++ b/animation/hallo-83dd4eb/configs/inference/default.yaml
@@ -0,0 +1,90 @@
+source_image: examples/reference_images/1.jpg
+driving_audio: examples/driving_audios/1.wav
+
+weight_dtype: fp16
+
+data:
+ n_motion_frames: 2
+ n_sample_frames: 16
+ source_image:
+ width: 512
+ height: 512
+ driving_audio:
+ sample_rate: 16000
+ export_video:
+ fps: 25
+
+inference_steps: 40
+cfg_scale: 3.5
+
+audio_ckpt_dir: ./pretrained_models/hallo
+
+base_model_path: ./pretrained_models/stable-diffusion-v1-5
+
+motion_module_path: ./pretrained_models/motion_module/mm_sd_v15_v2.ckpt
+
+face_analysis:
+ model_path: ./pretrained_models/face_analysis
+
+wav2vec:
+ model_path: ./pretrained_models/wav2vec/wav2vec2-base-960h
+ features: all
+
+audio_separator:
+ model_path: ./pretrained_models/audio_separator/Kim_Vocal_2.onnx
+
+vae:
+ model_path: ./pretrained_models/sd-vae-ft-mse
+
+save_path: ./.cache
+
+face_expand_ratio: 1.2
+pose_weight: 1.0
+face_weight: 1.0
+lip_weight: 1.0
+
+unet_additional_kwargs:
+ use_inflated_groupnorm: true
+ unet_use_cross_frame_attention: false
+ unet_use_temporal_attention: false
+ use_motion_module: true
+ use_audio_module: true
+ motion_module_resolutions:
+ - 1
+ - 2
+ - 4
+ - 8
+ motion_module_mid_block: true
+ motion_module_decoder_only: false
+ motion_module_type: Vanilla
+ motion_module_kwargs:
+ num_attention_heads: 8
+ num_transformer_block: 1
+ attention_block_types:
+ - Temporal_Self
+ - Temporal_Self
+ temporal_position_encoding: true
+ temporal_position_encoding_max_len: 32
+ temporal_attention_dim_div: 1
+ audio_attention_dim: 768
+ stack_enable_blocks_name:
+ - "up"
+ - "down"
+ - "mid"
+ stack_enable_blocks_depth: [0,1,2,3]
+
+
+enable_zero_snr: true
+
+noise_scheduler_kwargs:
+ beta_start: 0.00085
+ beta_end: 0.012
+ beta_schedule: "linear"
+ clip_sample: false
+ steps_offset: 1
+ ### Zero-SNR params
+ prediction_type: "v_prediction"
+ rescale_betas_zero_snr: True
+ timestep_spacing: "trailing"
+
+sampler: DDIM
diff --git a/animation/hallo-83dd4eb/configs/train/stage1.yaml b/animation/hallo-83dd4eb/configs/train/stage1.yaml
new file mode 100644
index 0000000..28760ed
--- /dev/null
+++ b/animation/hallo-83dd4eb/configs/train/stage1.yaml
@@ -0,0 +1,63 @@
+data:
+ train_bs: 8
+ train_width: 512
+ train_height: 512
+ meta_paths:
+ - "./data/HDTF_meta.json"
+ # Margin of frame indexes between ref and tgt images
+ sample_margin: 30
+
+solver:
+ gradient_accumulation_steps: 1
+ mixed_precision: "no"
+ enable_xformers_memory_efficient_attention: True
+ gradient_checkpointing: False
+ max_train_steps: 30000
+ max_grad_norm: 1.0
+ # lr
+ learning_rate: 1.0e-5
+ scale_lr: False
+ lr_warmup_steps: 1
+ lr_scheduler: "constant"
+
+ # optimizer
+ use_8bit_adam: False
+ adam_beta1: 0.9
+ adam_beta2: 0.999
+ adam_weight_decay: 1.0e-2
+ adam_epsilon: 1.0e-8
+
+val:
+ validation_steps: 500
+
+noise_scheduler_kwargs:
+ num_train_timesteps: 1000
+ beta_start: 0.00085
+ beta_end: 0.012
+ beta_schedule: "scaled_linear"
+ steps_offset: 1
+ clip_sample: false
+
+base_model_path: "./pretrained_models/stable-diffusion-v1-5/"
+vae_model_path: "./pretrained_models/sd-vae-ft-mse"
+face_analysis_model_path: "./pretrained_models/face_analysis"
+
+weight_dtype: "fp16" # [fp16, fp32]
+uncond_ratio: 0.1
+noise_offset: 0.05
+snr_gamma: 5.0
+enable_zero_snr: True
+face_locator_pretrained: False
+
+seed: 42
+resume_from_checkpoint: "latest"
+checkpointing_steps: 500
+exp_name: "stage1"
+output_dir: "./exp_output"
+
+ref_image_paths:
+ - "examples/reference_images/1.jpg"
+
+mask_image_paths:
+ - "examples/masks/1.png"
+
diff --git a/animation/hallo-83dd4eb/configs/train/stage2.yaml b/animation/hallo-83dd4eb/configs/train/stage2.yaml
new file mode 100644
index 0000000..baa3072
--- /dev/null
+++ b/animation/hallo-83dd4eb/configs/train/stage2.yaml
@@ -0,0 +1,119 @@
+data:
+ train_bs: 4
+ val_bs: 1
+ train_width: 512
+ train_height: 512
+ fps: 25
+ sample_rate: 16000
+ n_motion_frames: 2
+ n_sample_frames: 14
+ audio_margin: 2
+ train_meta_paths:
+ - "./data/hdtf_split_stage2.json"
+
+wav2vec_config:
+ audio_type: "vocals" # audio vocals
+ model_scale: "base" # base large
+ features: "all" # last avg all
+ model_path: ./pretrained_models/wav2vec/wav2vec2-base-960h
+audio_separator:
+ model_path: ./pretrained_models/audio_separator/Kim_Vocal_2.onnx
+face_expand_ratio: 1.2
+
+solver:
+ gradient_accumulation_steps: 1
+ mixed_precision: "no"
+ enable_xformers_memory_efficient_attention: True
+ gradient_checkpointing: True
+ max_train_steps: 30000
+ max_grad_norm: 1.0
+ # lr
+ learning_rate: 1e-5
+ scale_lr: False
+ lr_warmup_steps: 1
+ lr_scheduler: "constant"
+
+ # optimizer
+ use_8bit_adam: True
+ adam_beta1: 0.9
+ adam_beta2: 0.999
+ adam_weight_decay: 1.0e-2
+ adam_epsilon: 1.0e-8
+
+val:
+ validation_steps: 1000
+
+noise_scheduler_kwargs:
+ num_train_timesteps: 1000
+ beta_start: 0.00085
+ beta_end: 0.012
+ beta_schedule: "linear"
+ steps_offset: 1
+ clip_sample: false
+
+unet_additional_kwargs:
+ use_inflated_groupnorm: true
+ unet_use_cross_frame_attention: false
+ unet_use_temporal_attention: false
+ use_motion_module: true
+ use_audio_module: true
+ motion_module_resolutions:
+ - 1
+ - 2
+ - 4
+ - 8
+ motion_module_mid_block: true
+ motion_module_decoder_only: false
+ motion_module_type: Vanilla
+ motion_module_kwargs:
+ num_attention_heads: 8
+ num_transformer_block: 1
+ attention_block_types:
+ - Temporal_Self
+ - Temporal_Self
+ temporal_position_encoding: true
+ temporal_position_encoding_max_len: 32
+ temporal_attention_dim_div: 1
+ audio_attention_dim: 768
+ stack_enable_blocks_name:
+ - "up"
+ - "down"
+ - "mid"
+ stack_enable_blocks_depth: [0,1,2,3]
+
+trainable_para:
+ - audio_modules
+ - motion_modules
+
+base_model_path: "./pretrained_models/stable-diffusion-v1-5/"
+vae_model_path: "./pretrained_models/sd-vae-ft-mse"
+face_analysis_model_path: "./pretrained_models/face_analysis"
+mm_path: "./pretrained_models/motion_module/mm_sd_v15_v2.ckpt"
+
+weight_dtype: "fp16" # [fp16, fp32]
+uncond_img_ratio: 0.05
+uncond_audio_ratio: 0.05
+uncond_ia_ratio: 0.05
+start_ratio: 0.05
+noise_offset: 0.05
+snr_gamma: 5.0
+enable_zero_snr: True
+stage1_ckpt_dir: "./exp_output/stage1/"
+
+single_inference_times: 10
+inference_steps: 40
+cfg_scale: 3.5
+
+seed: 42
+resume_from_checkpoint: "latest"
+checkpointing_steps: 500
+exp_name: "stage2"
+output_dir: "./exp_output"
+
+ref_img_path:
+ - "examples/reference_images/1.jpg"
+
+audio_path:
+ - "examples/driving_audios/1.wav"
+
+
diff --git a/animation/hallo-83dd4eb/configs/unet/unet.yaml b/animation/hallo-83dd4eb/configs/unet/unet.yaml
new file mode 100644
index 0000000..aa4e3d9
--- /dev/null
+++ b/animation/hallo-83dd4eb/configs/unet/unet.yaml
@@ -0,0 +1,44 @@
+unet_additional_kwargs:
+ use_inflated_groupnorm: true
+ unet_use_cross_frame_attention: false
+ unet_use_temporal_attention: false
+ use_motion_module: true
+ use_audio_module: true
+ motion_module_resolutions:
+ - 1
+ - 2
+ - 4
+ - 8
+ motion_module_mid_block: true
+ motion_module_decoder_only: false
+ motion_module_type: Vanilla
+ motion_module_kwargs:
+ num_attention_heads: 8
+ num_transformer_block: 1
+ attention_block_types:
+ - Temporal_Self
+ - Temporal_Self
+ temporal_position_encoding: true
+ temporal_position_encoding_max_len: 32
+ temporal_attention_dim_div: 1
+ audio_attention_dim: 768
+ stack_enable_blocks_name:
+ - "up"
+ - "down"
+ - "mid"
+ stack_enable_blocks_depth: [0,1,2,3]
+
+enable_zero_snr: true
+
+noise_scheduler_kwargs:
+ beta_start: 0.00085
+ beta_end: 0.012
+ beta_schedule: "linear"
+ clip_sample: false
+ steps_offset: 1
+ ### Zero-SNR params
+ prediction_type: "v_prediction"
+ rescale_betas_zero_snr: True
+ timestep_spacing: "trailing"
+
+sampler: DDIM
diff --git a/animation/hallo-83dd4eb/docker-56038fd/.editorconfig b/animation/hallo-83dd4eb/docker-56038fd/.editorconfig
new file mode 100755
index 0000000..65d71f7
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/.editorconfig
@@ -0,0 +1,20 @@
+root = true
+
+[*]
+charset = utf-8
+end_of_line = lf
+insert_final_newline = true
+indent_style = space
+indent_size = 4
+trim_trailing_whitespace = true
+
+[*.md]
+trim_trailing_whitespace = false
+
+[*.yml]
+indent_size = 2
+indent_style = space
+
+[*.yaml]
+indent_size = 2
+indent_style = space
diff --git a/animation/hallo-83dd4eb/docker-56038fd/.github/FUNDING.yml b/animation/hallo-83dd4eb/docker-56038fd/.github/FUNDING.yml
new file mode 100644
index 0000000..83d2ceb
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/.github/FUNDING.yml
@@ -0,0 +1,4 @@
+# These are supported funding model platforms
+
+github: ashleykleynhans
+buy_me_a_coffee: ashleyk
diff --git a/animation/hallo-83dd4eb/docker-56038fd/.gitignore b/animation/hallo-83dd4eb/docker-56038fd/.gitignore
new file mode 100644
index 0000000..090a1f0
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/.gitignore
@@ -0,0 +1,2 @@
+.idea
+.DS_Store
diff --git a/animation/hallo-83dd4eb/docker-56038fd/Dockerfile b/animation/hallo-83dd4eb/docker-56038fd/Dockerfile
new file mode 100644
index 0000000..670e6fe
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/Dockerfile
@@ -0,0 +1,60 @@
+ARG BASE_IMAGE
+FROM ${BASE_IMAGE}
+
+SHELL ["/bin/bash", "-o", "pipefail", "-c"]
+ENV DEBIAN_FRONTEND=noninteractive \
+ PYTHONUNBUFFERED=1 \
+ PIP_NO_CACHE_DIR=on \
+ SHELL=/bin/bash
+
+# Create and use the Python venv
+WORKDIR /
+RUN python3 -m venv --system-site-packages /venv
+
+# Install torch and xformers
+ARG INDEX_URL
+ARG TORCH_VERSION
+ARG XFORMERS_VERSION
+RUN source /venv/bin/activate && \
+ pip3 install --no-cache-dir torch==${TORCH_VERSION} torchvision torchaudio --index-url ${INDEX_URL} && \
+ pip3 install --no-cache-dir xformers==${XFORMERS_VERSION} --index-url ${INDEX_URL} && \
+ deactivate
+
+# Clone the git repo of hallo and set version
+ARG HALLO_COMMIT
+RUN git clone https://github.com/fudan-generative-vision/hallo.git && \
+ cd /hallo && \
+ git checkout ${HALLO_VERSION}
+
+# Install the dependencies for hallo
+WORKDIR /hallo
+RUN source /venv/bin/activate && \
+ pip3 install -r requirements.txt && \
+ pip3 install . && \
+ pip3 install huggingface_hub && \
+ deactivate
+
+# Install models
+RUN source /venv/bin/activate && \
+ huggingface-cli download fudan-generative-ai/hallo \
+ --local-dir pretrained_models \
+ --local-dir-use-symlinks False && \
+ deactivate
+
+# Remove existing SSH host keys
+RUN rm -f /etc/ssh/ssh_host_*
+
+# NGINX Proxy
+COPY nginx/nginx.conf /etc/nginx/nginx.conf
+
+# Set template version
+ARG RELEASE
+ENV TEMPLATE_VERSION=${RELEASE}
+
+# Copy the scripts
+WORKDIR /
+COPY --chmod=755 scripts/* ./
+
+# Start the container
+SHELL ["/bin/bash", "--login", "-c"]
+CMD [ "/start.sh" ]
diff --git a/animation/hallo-83dd4eb/docker-56038fd/LICENSE b/animation/hallo-83dd4eb/docker-56038fd/LICENSE
new file mode 100644
index 0000000..f288702
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/LICENSE
@@ -0,0 +1,674 @@
+ GNU GENERAL PUBLIC LICENSE
+ Version 3, 29 June 2007
+
+ Copyright (C) 2007 Free Software Foundation, Inc.
+ Everyone is permitted to copy and distribute verbatim copies
+ of this license document, but changing it is not allowed.
+
+ Preamble
+
+ The GNU General Public License is a free, copyleft license for
+software and other kinds of works.
+
+ The licenses for most software and other practical works are designed
+to take away your freedom to share and change the works. By contrast,
+the GNU General Public License is intended to guarantee your freedom to
+share and change all versions of a program--to make sure it remains free
+software for all its users. We, the Free Software Foundation, use the
+GNU General Public License for most of our software; it applies also to
+any other work released this way by its authors. You can apply it to
+your programs, too.
+
+ When we speak of free software, we are referring to freedom, not
+price. Our General Public Licenses are designed to make sure that you
+have the freedom to distribute copies of free software (and charge for
+them if you wish), that you receive source code or can get it if you
+want it, that you can change the software or use pieces of it in new
+free programs, and that you know you can do these things.
+
+ To protect your rights, we need to prevent others from denying you
+these rights or asking you to surrender the rights. Therefore, you have
+certain responsibilities if you distribute copies of the software, or if
+you modify it: responsibilities to respect the freedom of others.
+
+ For example, if you distribute copies of such a program, whether
+gratis or for a fee, you must pass on to the recipients the same
+freedoms that you received. You must make sure that they, too, receive
+or can get the source code. And you must show them these terms so they
+know their rights.
+
+ Developers that use the GNU GPL protect your rights with two steps:
+(1) assert copyright on the software, and (2) offer you this License
+giving you legal permission to copy, distribute and/or modify it.
+
+ For the developers' and authors' protection, the GPL clearly explains
+that there is no warranty for this free software. For both users' and
+authors' sake, the GPL requires that modified versions be marked as
+changed, so that their problems will not be attributed erroneously to
+authors of previous versions.
+
+ Some devices are designed to deny users access to install or run
+modified versions of the software inside them, although the manufacturer
+can do so. This is fundamentally incompatible with the aim of
+protecting users' freedom to change the software. The systematic
+pattern of such abuse occurs in the area of products for individuals to
+use, which is precisely where it is most unacceptable. Therefore, we
+have designed this version of the GPL to prohibit the practice for those
+products. If such problems arise substantially in other domains, we
+stand ready to extend this provision to those domains in future versions
+of the GPL, as needed to protect the freedom of users.
+
+ Finally, every program is threatened constantly by software patents.
+States should not allow patents to restrict development and use of
+software on general-purpose computers, but in those that do, we wish to
+avoid the special danger that patents applied to a free program could
+make it effectively proprietary. To prevent this, the GPL assures that
+patents cannot be used to render the program non-free.
+
+ The precise terms and conditions for copying, distribution and
+modification follow.
+
+ TERMS AND CONDITIONS
+
+ 0. Definitions.
+
+ "This License" refers to version 3 of the GNU General Public License.
+
+ "Copyright" also means copyright-like laws that apply to other kinds of
+works, such as semiconductor masks.
+
+ "The Program" refers to any copyrightable work licensed under this
+License. Each licensee is addressed as "you". "Licensees" and
+"recipients" may be individuals or organizations.
+
+ To "modify" a work means to copy from or adapt all or part of the work
+in a fashion requiring copyright permission, other than the making of an
+exact copy. The resulting work is called a "modified version" of the
+earlier work or a work "based on" the earlier work.
+
+ A "covered work" means either the unmodified Program or a work based
+on the Program.
+
+ To "propagate" a work means to do anything with it that, without
+permission, would make you directly or secondarily liable for
+infringement under applicable copyright law, except executing it on a
+computer or modifying a private copy. Propagation includes copying,
+distribution (with or without modification), making available to the
+public, and in some countries other activities as well.
+
+ To "convey" a work means any kind of propagation that enables other
+parties to make or receive copies. Mere interaction with a user through
+a computer network, with no transfer of a copy, is not conveying.
+
+ An interactive user interface displays "Appropriate Legal Notices"
+to the extent that it includes a convenient and prominently visible
+feature that (1) displays an appropriate copyright notice, and (2)
+tells the user that there is no warranty for the work (except to the
+extent that warranties are provided), that licensees may convey the
+work under this License, and how to view a copy of this License. If
+the interface presents a list of user commands or options, such as a
+menu, a prominent item in the list meets this criterion.
+
+ 1. Source Code.
+
+ The "source code" for a work means the preferred form of the work
+for making modifications to it. "Object code" means any non-source
+form of a work.
+
+ A "Standard Interface" means an interface that either is an official
+standard defined by a recognized standards body, or, in the case of
+interfaces specified for a particular programming language, one that
+is widely used among developers working in that language.
+
+ The "System Libraries" of an executable work include anything, other
+than the work as a whole, that (a) is included in the normal form of
+packaging a Major Component, but which is not part of that Major
+Component, and (b) serves only to enable use of the work with that
+Major Component, or to implement a Standard Interface for which an
+implementation is available to the public in source code form. A
+"Major Component", in this context, means a major essential component
+(kernel, window system, and so on) of the specific operating system
+(if any) on which the executable work runs, or a compiler used to
+produce the work, or an object code interpreter used to run it.
+
+ The "Corresponding Source" for a work in object code form means all
+the source code needed to generate, install, and (for an executable
+work) run the object code and to modify the work, including scripts to
+control those activities. However, it does not include the work's
+System Libraries, or general-purpose tools or generally available free
+programs which are used unmodified in performing those activities but
+which are not part of the work. For example, Corresponding Source
+includes interface definition files associated with source files for
+the work, and the source code for shared libraries and dynamically
+linked subprograms that the work is specifically designed to require,
+such as by intimate data communication or control flow between those
+subprograms and other parts of the work.
+
+ The Corresponding Source need not include anything that users
+can regenerate automatically from other parts of the Corresponding
+Source.
+
+ The Corresponding Source for a work in source code form is that
+same work.
+
+ 2. Basic Permissions.
+
+ All rights granted under this License are granted for the term of
+copyright on the Program, and are irrevocable provided the stated
+conditions are met. This License explicitly affirms your unlimited
+permission to run the unmodified Program. The output from running a
+covered work is covered by this License only if the output, given its
+content, constitutes a covered work. This License acknowledges your
+rights of fair use or other equivalent, as provided by copyright law.
+
+ You may make, run and propagate covered works that you do not
+convey, without conditions so long as your license otherwise remains
+in force. You may convey covered works to others for the sole purpose
+of having them make modifications exclusively for you, or provide you
+with facilities for running those works, provided that you comply with
+the terms of this License in conveying all material for which you do
+not control copyright. Those thus making or running the covered works
+for you must do so exclusively on your behalf, under your direction
+and control, on terms that prohibit them from making any copies of
+your copyrighted material outside their relationship with you.
+
+ Conveying under any other circumstances is permitted solely under
+the conditions stated below. Sublicensing is not allowed; section 10
+makes it unnecessary.
+
+ 3. Protecting Users' Legal Rights From Anti-Circumvention Law.
+
+ No covered work shall be deemed part of an effective technological
+measure under any applicable law fulfilling obligations under article
+11 of the WIPO copyright treaty adopted on 20 December 1996, or
+similar laws prohibiting or restricting circumvention of such
+measures.
+
+ When you convey a covered work, you waive any legal power to forbid
+circumvention of technological measures to the extent such circumvention
+is effected by exercising rights under this License with respect to
+the covered work, and you disclaim any intention to limit operation or
+modification of the work as a means of enforcing, against the work's
+users, your or third parties' legal rights to forbid circumvention of
+technological measures.
+
+ 4. Conveying Verbatim Copies.
+
+ You may convey verbatim copies of the Program's source code as you
+receive it, in any medium, provided that you conspicuously and
+appropriately publish on each copy an appropriate copyright notice;
+keep intact all notices stating that this License and any
+non-permissive terms added in accord with section 7 apply to the code;
+keep intact all notices of the absence of any warranty; and give all
+recipients a copy of this License along with the Program.
+
+ You may charge any price or no price for each copy that you convey,
+and you may offer support or warranty protection for a fee.
+
+ 5. Conveying Modified Source Versions.
+
+ You may convey a work based on the Program, or the modifications to
+produce it from the Program, in the form of source code under the
+terms of section 4, provided that you also meet all of these conditions:
+
+ a) The work must carry prominent notices stating that you modified
+ it, and giving a relevant date.
+
+ b) The work must carry prominent notices stating that it is
+ released under this License and any conditions added under section
+ 7. This requirement modifies the requirement in section 4 to
+ "keep intact all notices".
+
+ c) You must license the entire work, as a whole, under this
+ License to anyone who comes into possession of a copy. This
+ License will therefore apply, along with any applicable section 7
+ additional terms, to the whole of the work, and all its parts,
+ regardless of how they are packaged. This License gives no
+ permission to license the work in any other way, but it does not
+ invalidate such permission if you have separately received it.
+
+ d) If the work has interactive user interfaces, each must display
+ Appropriate Legal Notices; however, if the Program has interactive
+ interfaces that do not display Appropriate Legal Notices, your
+ work need not make them do so.
+
+ A compilation of a covered work with other separate and independent
+works, which are not by their nature extensions of the covered work,
+and which are not combined with it such as to form a larger program,
+in or on a volume of a storage or distribution medium, is called an
+"aggregate" if the compilation and its resulting copyright are not
+used to limit the access or legal rights of the compilation's users
+beyond what the individual works permit. Inclusion of a covered work
+in an aggregate does not cause this License to apply to the other
+parts of the aggregate.
+
+ 6. Conveying Non-Source Forms.
+
+ You may convey a covered work in object code form under the terms
+of sections 4 and 5, provided that you also convey the
+machine-readable Corresponding Source under the terms of this License,
+in one of these ways:
+
+ a) Convey the object code in, or embodied in, a physical product
+ (including a physical distribution medium), accompanied by the
+ Corresponding Source fixed on a durable physical medium
+ customarily used for software interchange.
+
+ b) Convey the object code in, or embodied in, a physical product
+ (including a physical distribution medium), accompanied by a
+ written offer, valid for at least three years and valid for as
+ long as you offer spare parts or customer support for that product
+ model, to give anyone who possesses the object code either (1) a
+ copy of the Corresponding Source for all the software in the
+ product that is covered by this License, on a durable physical
+ medium customarily used for software interchange, for a price no
+ more than your reasonable cost of physically performing this
+ conveying of source, or (2) access to copy the
+ Corresponding Source from a network server at no charge.
+
+ c) Convey individual copies of the object code with a copy of the
+ written offer to provide the Corresponding Source. This
+ alternative is allowed only occasionally and noncommercially, and
+ only if you received the object code with such an offer, in accord
+ with subsection 6b.
+
+ d) Convey the object code by offering access from a designated
+ place (gratis or for a charge), and offer equivalent access to the
+ Corresponding Source in the same way through the same place at no
+ further charge. You need not require recipients to copy the
+ Corresponding Source along with the object code. If the place to
+ copy the object code is a network server, the Corresponding Source
+ may be on a different server (operated by you or a third party)
+ that supports equivalent copying facilities, provided you maintain
+ clear directions next to the object code saying where to find the
+ Corresponding Source. Regardless of what server hosts the
+ Corresponding Source, you remain obligated to ensure that it is
+ available for as long as needed to satisfy these requirements.
+
+ e) Convey the object code using peer-to-peer transmission, provided
+ you inform other peers where the object code and Corresponding
+ Source of the work are being offered to the general public at no
+ charge under subsection 6d.
+
+ A separable portion of the object code, whose source code is excluded
+from the Corresponding Source as a System Library, need not be
+included in conveying the object code work.
+
+ A "User Product" is either (1) a "consumer product", which means any
+tangible personal property which is normally used for personal, family,
+or household purposes, or (2) anything designed or sold for incorporation
+into a dwelling. In determining whether a product is a consumer product,
+doubtful cases shall be resolved in favor of coverage. For a particular
+product received by a particular user, "normally used" refers to a
+typical or common use of that class of product, regardless of the status
+of the particular user or of the way in which the particular user
+actually uses, or expects or is expected to use, the product. A product
+is a consumer product regardless of whether the product has substantial
+commercial, industrial or non-consumer uses, unless such uses represent
+the only significant mode of use of the product.
+
+ "Installation Information" for a User Product means any methods,
+procedures, authorization keys, or other information required to install
+and execute modified versions of a covered work in that User Product from
+a modified version of its Corresponding Source. The information must
+suffice to ensure that the continued functioning of the modified object
+code is in no case prevented or interfered with solely because
+modification has been made.
+
+ If you convey an object code work under this section in, or with, or
+specifically for use in, a User Product, and the conveying occurs as
+part of a transaction in which the right of possession and use of the
+User Product is transferred to the recipient in perpetuity or for a
+fixed term (regardless of how the transaction is characterized), the
+Corresponding Source conveyed under this section must be accompanied
+by the Installation Information. But this requirement does not apply
+if neither you nor any third party retains the ability to install
+modified object code on the User Product (for example, the work has
+been installed in ROM).
+
+ The requirement to provide Installation Information does not include a
+requirement to continue to provide support service, warranty, or updates
+for a work that has been modified or installed by the recipient, or for
+the User Product in which it has been modified or installed. Access to a
+network may be denied when the modification itself materially and
+adversely affects the operation of the network or violates the rules and
+protocols for communication across the network.
+
+ Corresponding Source conveyed, and Installation Information provided,
+in accord with this section must be in a format that is publicly
+documented (and with an implementation available to the public in
+source code form), and must require no special password or key for
+unpacking, reading or copying.
+
+ 7. Additional Terms.
+
+ "Additional permissions" are terms that supplement the terms of this
+License by making exceptions from one or more of its conditions.
+Additional permissions that are applicable to the entire Program shall
+be treated as though they were included in this License, to the extent
+that they are valid under applicable law. If additional permissions
+apply only to part of the Program, that part may be used separately
+under those permissions, but the entire Program remains governed by
+this License without regard to the additional permissions.
+
+ When you convey a copy of a covered work, you may at your option
+remove any additional permissions from that copy, or from any part of
+it. (Additional permissions may be written to require their own
+removal in certain cases when you modify the work.) You may place
+additional permissions on material, added by you to a covered work,
+for which you have or can give appropriate copyright permission.
+
+ Notwithstanding any other provision of this License, for material you
+add to a covered work, you may (if authorized by the copyright holders of
+that material) supplement the terms of this License with terms:
+
+ a) Disclaiming warranty or limiting liability differently from the
+ terms of sections 15 and 16 of this License; or
+
+ b) Requiring preservation of specified reasonable legal notices or
+ author attributions in that material or in the Appropriate Legal
+ Notices displayed by works containing it; or
+
+ c) Prohibiting misrepresentation of the origin of that material, or
+ requiring that modified versions of such material be marked in
+ reasonable ways as different from the original version; or
+
+ d) Limiting the use for publicity purposes of names of licensors or
+ authors of the material; or
+
+ e) Declining to grant rights under trademark law for use of some
+ trade names, trademarks, or service marks; or
+
+ f) Requiring indemnification of licensors and authors of that
+ material by anyone who conveys the material (or modified versions of
+ it) with contractual assumptions of liability to the recipient, for
+ any liability that these contractual assumptions directly impose on
+ those licensors and authors.
+
+ All other non-permissive additional terms are considered "further
+restrictions" within the meaning of section 10. If the Program as you
+received it, or any part of it, contains a notice stating that it is
+governed by this License along with a term that is a further
+restriction, you may remove that term. If a license document contains
+a further restriction but permits relicensing or conveying under this
+License, you may add to a covered work material governed by the terms
+of that license document, provided that the further restriction does
+not survive such relicensing or conveying.
+
+ If you add terms to a covered work in accord with this section, you
+must place, in the relevant source files, a statement of the
+additional terms that apply to those files, or a notice indicating
+where to find the applicable terms.
+
+ Additional terms, permissive or non-permissive, may be stated in the
+form of a separately written license, or stated as exceptions;
+the above requirements apply either way.
+
+ 8. Termination.
+
+ You may not propagate or modify a covered work except as expressly
+provided under this License. Any attempt otherwise to propagate or
+modify it is void, and will automatically terminate your rights under
+this License (including any patent licenses granted under the third
+paragraph of section 11).
+
+ However, if you cease all violation of this License, then your
+license from a particular copyright holder is reinstated (a)
+provisionally, unless and until the copyright holder explicitly and
+finally terminates your license, and (b) permanently, if the copyright
+holder fails to notify you of the violation by some reasonable means
+prior to 60 days after the cessation.
+
+ Moreover, your license from a particular copyright holder is
+reinstated permanently if the copyright holder notifies you of the
+violation by some reasonable means, this is the first time you have
+received notice of violation of this License (for any work) from that
+copyright holder, and you cure the violation prior to 30 days after
+your receipt of the notice.
+
+ Termination of your rights under this section does not terminate the
+licenses of parties who have received copies or rights from you under
+this License. If your rights have been terminated and not permanently
+reinstated, you do not qualify to receive new licenses for the same
+material under section 10.
+
+ 9. Acceptance Not Required for Having Copies.
+
+ You are not required to accept this License in order to receive or
+run a copy of the Program. Ancillary propagation of a covered work
+occurring solely as a consequence of using peer-to-peer transmission
+to receive a copy likewise does not require acceptance. However,
+nothing other than this License grants you permission to propagate or
+modify any covered work. These actions infringe copyright if you do
+not accept this License. Therefore, by modifying or propagating a
+covered work, you indicate your acceptance of this License to do so.
+
+ 10. Automatic Licensing of Downstream Recipients.
+
+ Each time you convey a covered work, the recipient automatically
+receives a license from the original licensors, to run, modify and
+propagate that work, subject to this License. You are not responsible
+for enforcing compliance by third parties with this License.
+
+ An "entity transaction" is a transaction transferring control of an
+organization, or substantially all assets of one, or subdividing an
+organization, or merging organizations. If propagation of a covered
+work results from an entity transaction, each party to that
+transaction who receives a copy of the work also receives whatever
+licenses to the work the party's predecessor in interest had or could
+give under the previous paragraph, plus a right to possession of the
+Corresponding Source of the work from the predecessor in interest, if
+the predecessor has it or can get it with reasonable efforts.
+
+ You may not impose any further restrictions on the exercise of the
+rights granted or affirmed under this License. For example, you may
+not impose a license fee, royalty, or other charge for exercise of
+rights granted under this License, and you may not initiate litigation
+(including a cross-claim or counterclaim in a lawsuit) alleging that
+any patent claim is infringed by making, using, selling, offering for
+sale, or importing the Program or any portion of it.
+
+ 11. Patents.
+
+ A "contributor" is a copyright holder who authorizes use under this
+License of the Program or a work on which the Program is based. The
+work thus licensed is called the contributor's "contributor version".
+
+ A contributor's "essential patent claims" are all patent claims
+owned or controlled by the contributor, whether already acquired or
+hereafter acquired, that would be infringed by some manner, permitted
+by this License, of making, using, or selling its contributor version,
+but do not include claims that would be infringed only as a
+consequence of further modification of the contributor version. For
+purposes of this definition, "control" includes the right to grant
+patent sublicenses in a manner consistent with the requirements of
+this License.
+
+ Each contributor grants you a non-exclusive, worldwide, royalty-free
+patent license under the contributor's essential patent claims, to
+make, use, sell, offer for sale, import and otherwise run, modify and
+propagate the contents of its contributor version.
+
+ In the following three paragraphs, a "patent license" is any express
+agreement or commitment, however denominated, not to enforce a patent
+(such as an express permission to practice a patent or covenant not to
+sue for patent infringement). To "grant" such a patent license to a
+party means to make such an agreement or commitment not to enforce a
+patent against the party.
+
+ If you convey a covered work, knowingly relying on a patent license,
+and the Corresponding Source of the work is not available for anyone
+to copy, free of charge and under the terms of this License, through a
+publicly available network server or other readily accessible means,
+then you must either (1) cause the Corresponding Source to be so
+available, or (2) arrange to deprive yourself of the benefit of the
+patent license for this particular work, or (3) arrange, in a manner
+consistent with the requirements of this License, to extend the patent
+license to downstream recipients. "Knowingly relying" means you have
+actual knowledge that, but for the patent license, your conveying the
+covered work in a country, or your recipient's use of the covered work
+in a country, would infringe one or more identifiable patents in that
+country that you have reason to believe are valid.
+
+ If, pursuant to or in connection with a single transaction or
+arrangement, you convey, or propagate by procuring conveyance of, a
+covered work, and grant a patent license to some of the parties
+receiving the covered work authorizing them to use, propagate, modify
+or convey a specific copy of the covered work, then the patent license
+you grant is automatically extended to all recipients of the covered
+work and works based on it.
+
+ A patent license is "discriminatory" if it does not include within
+the scope of its coverage, prohibits the exercise of, or is
+conditioned on the non-exercise of one or more of the rights that are
+specifically granted under this License. You may not convey a covered
+work if you are a party to an arrangement with a third party that is
+in the business of distributing software, under which you make payment
+to the third party based on the extent of your activity of conveying
+the work, and under which the third party grants, to any of the
+parties who would receive the covered work from you, a discriminatory
+patent license (a) in connection with copies of the covered work
+conveyed by you (or copies made from those copies), or (b) primarily
+for and in connection with specific products or compilations that
+contain the covered work, unless you entered into that arrangement,
+or that patent license was granted, prior to 28 March 2007.
+
+ Nothing in this License shall be construed as excluding or limiting
+any implied license or other defenses to infringement that may
+otherwise be available to you under applicable patent law.
+
+ 12. No Surrender of Others' Freedom.
+
+ If conditions are imposed on you (whether by court order, agreement or
+otherwise) that contradict the conditions of this License, they do not
+excuse you from the conditions of this License. If you cannot convey a
+covered work so as to satisfy simultaneously your obligations under this
+License and any other pertinent obligations, then as a consequence you may
+not convey it at all. For example, if you agree to terms that obligate you
+to collect a royalty for further conveying from those to whom you convey
+the Program, the only way you could satisfy both those terms and this
+License would be to refrain entirely from conveying the Program.
+
+ 13. Use with the GNU Affero General Public License.
+
+ Notwithstanding any other provision of this License, you have
+permission to link or combine any covered work with a work licensed
+under version 3 of the GNU Affero General Public License into a single
+combined work, and to convey the resulting work. The terms of this
+License will continue to apply to the part which is the covered work,
+but the special requirements of the GNU Affero General Public License,
+section 13, concerning interaction through a network will apply to the
+combination as such.
+
+ 14. Revised Versions of this License.
+
+ The Free Software Foundation may publish revised and/or new versions of
+the GNU General Public License from time to time. Such new versions will
+be similar in spirit to the present version, but may differ in detail to
+address new problems or concerns.
+
+ Each version is given a distinguishing version number. If the
+Program specifies that a certain numbered version of the GNU General
+Public License "or any later version" applies to it, you have the
+option of following the terms and conditions either of that numbered
+version or of any later version published by the Free Software
+Foundation. If the Program does not specify a version number of the
+GNU General Public License, you may choose any version ever published
+by the Free Software Foundation.
+
+ If the Program specifies that a proxy can decide which future
+versions of the GNU General Public License can be used, that proxy's
+public statement of acceptance of a version permanently authorizes you
+to choose that version for the Program.
+
+ Later license versions may give you additional or different
+permissions. However, no additional obligations are imposed on any
+author or copyright holder as a result of your choosing to follow a
+later version.
+
+ 15. Disclaimer of Warranty.
+
+ THERE IS NO WARRANTY FOR THE PROGRAM, TO THE EXTENT PERMITTED BY
+APPLICABLE LAW. EXCEPT WHEN OTHERWISE STATED IN WRITING THE COPYRIGHT
+HOLDERS AND/OR OTHER PARTIES PROVIDE THE PROGRAM "AS IS" WITHOUT WARRANTY
+OF ANY KIND, EITHER EXPRESSED OR IMPLIED, INCLUDING, BUT NOT LIMITED TO,
+THE IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR
+PURPOSE. THE ENTIRE RISK AS TO THE QUALITY AND PERFORMANCE OF THE PROGRAM
+IS WITH YOU. SHOULD THE PROGRAM PROVE DEFECTIVE, YOU ASSUME THE COST OF
+ALL NECESSARY SERVICING, REPAIR OR CORRECTION.
+
+ 16. Limitation of Liability.
+
+ IN NO EVENT UNLESS REQUIRED BY APPLICABLE LAW OR AGREED TO IN WRITING
+WILL ANY COPYRIGHT HOLDER, OR ANY OTHER PARTY WHO MODIFIES AND/OR CONVEYS
+THE PROGRAM AS PERMITTED ABOVE, BE LIABLE TO YOU FOR DAMAGES, INCLUDING ANY
+GENERAL, SPECIAL, INCIDENTAL OR CONSEQUENTIAL DAMAGES ARISING OUT OF THE
+USE OR INABILITY TO USE THE PROGRAM (INCLUDING BUT NOT LIMITED TO LOSS OF
+DATA OR DATA BEING RENDERED INACCURATE OR LOSSES SUSTAINED BY YOU OR THIRD
+PARTIES OR A FAILURE OF THE PROGRAM TO OPERATE WITH ANY OTHER PROGRAMS),
+EVEN IF SUCH HOLDER OR OTHER PARTY HAS BEEN ADVISED OF THE POSSIBILITY OF
+SUCH DAMAGES.
+
+ 17. Interpretation of Sections 15 and 16.
+
+ If the disclaimer of warranty and limitation of liability provided
+above cannot be given local legal effect according to their terms,
+reviewing courts shall apply local law that most closely approximates
+an absolute waiver of all civil liability in connection with the
+Program, unless a warranty or assumption of liability accompanies a
+copy of the Program in return for a fee.
+
+ END OF TERMS AND CONDITIONS
+
+ How to Apply These Terms to Your New Programs
+
+ If you develop a new program, and you want it to be of the greatest
+possible use to the public, the best way to achieve this is to make it
+free software which everyone can redistribute and change under these terms.
+
+ To do so, attach the following notices to the program. It is safest
+to attach them to the start of each source file to most effectively
+state the exclusion of warranty; and each file should have at least
+the "copyright" line and a pointer to where the full notice is found.
+
+
+ Copyright (C)
+
+ This program is free software: you can redistribute it and/or modify
+ it under the terms of the GNU General Public License as published by
+ the Free Software Foundation, either version 3 of the License, or
+ (at your option) any later version.
+
+ This program is distributed in the hope that it will be useful,
+ but WITHOUT ANY WARRANTY; without even the implied warranty of
+ MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE. See the
+ GNU General Public License for more details.
+
+ You should have received a copy of the GNU General Public License
+ along with this program. If not, see .
+
+Also add information on how to contact you by electronic and paper mail.
+
+ If the program does terminal interaction, make it output a short
+notice like this when it starts in an interactive mode:
+
+ Copyright (C)
+ This program comes with ABSOLUTELY NO WARRANTY; for details type `show w'.
+ This is free software, and you are welcome to redistribute it
+ under certain conditions; type `show c' for details.
+
+The hypothetical commands `show w' and `show c' should show the appropriate
+parts of the General Public License. Of course, your program's commands
+might be different; for a GUI interface, you would use an "about box".
+
+ You should also get your employer (if you work as a programmer) or school,
+if any, to sign a "copyright disclaimer" for the program, if necessary.
+For more information on this, and how to apply and follow the GNU GPL, see
+.
+
+ The GNU General Public License does not permit incorporating your program
+into proprietary programs. If your program is a subroutine library, you
+may consider it more useful to permit linking proprietary applications with
+the library. If this is what you want to do, use the GNU Lesser General
+Public License instead of this License. But first, please read
+.
diff --git a/animation/hallo-83dd4eb/docker-56038fd/README.md b/animation/hallo-83dd4eb/docker-56038fd/README.md
new file mode 100644
index 0000000..26c8115
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/README.md
@@ -0,0 +1,119 @@
+
+
+# Docker image for Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
+
+
+
+
+
+
+## Installs
+
+* Ubuntu 22.04 LTS
+* CUDA 12.1
+* Python 3.10.12
+* [hallo](
+ https://github.com/fudan-generative-vision/hallo) v1.0.0
+* Torch 2.2.2
+* xformers 0.0.25.post1
+* [Jupyter Lab](https://github.com/jupyterlab/jupyterlab)
+* [code-server](https://github.com/coder/code-server)
+* [runpodctl](https://github.com/runpod/runpodctl)
+* [OhMyRunPod](https://github.com/kodxana/OhMyRunPod)
+* [RunPod File Uploader](https://github.com/kodxana/RunPod-FilleUploader)
+* [croc](https://github.com/schollz/croc)
+* [rclone](https://rclone.org/)
+
+## Available on RunPod
+
+This image is designed to work on [RunPod](https://runpod.io?ref=2xxro4sy).
+You can use my custom [RunPod template](
+https://runpod.io/console/deploy?template=aeyibwyvzy&ref=2xxro4syy)
+to launch it on RunPod.
+
+## Building the Docker image
+
+> [!NOTE]
+> You will need to edit the `docker-bake.hcl` file and update `REGISTRY_USER`,
+> and `RELEASE`. You can obviously edit the other values too, but these
+> are the most important ones.
+
+```bash
+# Clone the repo
+git clone https://github.com/ashleykleynhans/hallo-docker.git
+
+# Log in to Docker Hub
+docker login
+
+# Build the image, tag the image, and push the image to Docker Hub
+cd hallo-docker
+docker buildx bake -f docker-bake.hcl --push
+
+# Same as above but customize registry/user/release:
+REGISTRY=ghcr.io REGISTRY_USER=myuser RELEASE=my-release docker buildx \
+ bake -f docker-bake.hcl --push
+```
+
+## Running Locally
+
+### Install Nvidia CUDA Driver
+
+- [Linux](https://docs.nvidia.com/cuda/cuda-installation-guide-linux/index.html)
+- [Windows](https://docs.nvidia.com/cuda/cuda-installation-guide-microsoft-windows/index.html)
+
+### Start the Docker container
+
+```bash
+docker run -d \
+ --gpus all \
+ -v /workspace \
+ -p 3000:3001 \
+ -p 7777:7777 \
+ -p 8888:8888 \
+ -p 2999:2999 \
+ -e VENV_PATH=/workspace/venvs/hallo \
+ ashleykza/hallo:latest
+```
+
+You can obviously substitute the image name and tag with your own.
+
+## Ports
+
+| Connect Port | Internal Port | Description |
+|--------------|---------------|----------------------|
+| 3000 | 3001 | hallo |
+| 7777 | 7777 | Code Server |
+| 8888 | 8888 | Jupyter Lab |
+| 2999 | 2999 | RunPod File Uploader |
+
+## Environment Variables
+
+| Variable | Description | Default |
+|----------------------|--------------------------------------------------|----------------------------|
+| JUPYTER_LAB_PASSWORD | Set a password for Jupyter lab | not set - no password |
+| DISABLE_AUTOLAUNCH | Disable hallo from launching automatically | (not set) |
+| DISABLE_SYNC | Disable syncing if using a RunPod network volume | (not set) |
+
+## Logs
+
+hallo creates a log file, and you can tail the log instead of
+killing the service to view the logs.
+
+| Application | Log file |
+|-------------|---------------------------|
+| hallo | /workspace/logs/hallo.log |
+
+For example:
+
+```bash
+tail -f /workspace/logs/hallo.log
+```
+
+## Community and Contributing
+
+Pull requests and issues on [GitHub](https://github.com/ashleykleynhans/hallo-docker)
+are welcome. Bug fixes and new features are encouraged.
+
+## Appreciate my work?
+
+ diff --git a/animation/hallo-83dd4eb/docker-56038fd/docker-bake.hcl b/animation/hallo-83dd4eb/docker-56038fd/docker-bake.hcl
new file mode 100644
index 0000000..69f6607
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/docker-bake.hcl
@@ -0,0 +1,47 @@
+variable "REGISTRY" {
+ default = "docker.io"
+}
+
+variable "REGISTRY_USER" {
+ default = "ashleykza"
+}
+variable "APP" {
+ default = "hallo"
+}
+
+variable "RELEASE" {
+ default = "1.2.0"
+}
+
+variable "CU_VERSION" {
+ default = "121"
+}
+
+variable "BASE_IMAGE_REPOSITORY" {
+ default = "ashleykza/runpod-base"
+}
+
+variable "BASE_IMAGE_VERSION" {
+ default = "1.7.0"
+}
+
+variable "CUDA_VERSION" {
+ default = "12.1.1"
+}
+
+variable "TORCH_VERSION" {
+ default = "2.2.2"
+}
+
+target "default" {
+ dockerfile = "Dockerfile"
+ tags = ["${REGISTRY}/${REGISTRY_USER}/${APP}:${RELEASE}"]
+ args = {
+ RELEASE = "${RELEASE}"
+ BASE_IMAGE = "${BASE_IMAGE_REPOSITORY}:${BASE_IMAGE_VERSION}-cuda${CUDA_VERSION}-torch${TORCH_VERSION}"
+ INDEX_URL = "https://download.pytorch.org/whl/cu${CU_VERSION}"
+ TORCH_VERSION = "${TORCH_VERSION}+cu${CU_VERSION}"
+ XFORMERS_VERSION = "0.0.25.post1"
+ HALLO_VERSION = "v1.0.0"
+ }
+}
diff --git a/animation/hallo-83dd4eb/docker-56038fd/nginx/nginx.conf b/animation/hallo-83dd4eb/docker-56038fd/nginx/nginx.conf
new file mode 100644
index 0000000..56f0236
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/nginx/nginx.conf
@@ -0,0 +1,74 @@
+events { worker_connections 2048; }
+
+http {
+ client_max_body_size 500M;
+
+ keepalive_timeout 600;
+ proxy_connect_timeout 600;
+ proxy_send_timeout 600;
+ proxy_read_timeout 600;
+ send_timeout 600;
+
+ server {
+ listen 3000;
+
+ location /ws {
+ proxy_http_version 1.1;
+ proxy_set_header Accept-Encoding gzip;
+ proxy_set_header Upgrade $http_upgrade;
+ proxy_set_header Connection "upgrade";
+ add_header Cache-Control no-cache;
+ proxy_set_header Host $host;
+
+ proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
+ proxy_set_header X-Real-IP $remote_addr;
+ proxy_pass http://localhost:3001;
+ }
+
+ location /queue/join {
+ proxy_http_version 1.1;
+ proxy_set_header Accept-Encoding gzip;
+ proxy_set_header Upgrade $http_upgrade;
+ proxy_set_header Connection "upgrade";
+ add_header Cache-Control no-cache;
+ proxy_set_header Host $host;
+
+ proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
+ proxy_set_header X-Real-IP $remote_addr;
+ proxy_pass http://localhost:3001;
+ }
+
+ location / {
+ add_header Cache-Control no-cache;
+ proxy_pass http://localhost:3001;
+ proxy_http_version 1.1;
+ proxy_set_header Accept-Encoding gzip;
+ proxy_set_header Upgrade $http_upgrade;
+ proxy_set_header Host $host;
+
+ proxy_set_header X-Real-IP $remote_addr;
+ proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
+ proxy_set_header X-Forwarded-Proto $scheme;
+
+
+ proxy_intercept_errors on;
+ error_page 502 =200 @502;
+ }
+
+ location /README.md {
+ root /usr/share/nginx/html;
+ }
+
+ location @502 {
+ # kill cache
+ add_header Last-Modified $date_gmt;
+ add_header Cache-Control 'no-store, no-cache, must-revalidate, proxy-revalidate, max-age=0';
+ if_modified_since off;
+ expires off;
+ etag off;
+
+ root /usr/share/nginx/html;
+ rewrite ^(.*)$ /502.html break;
+ }
+ }
+}
diff --git a/animation/hallo-83dd4eb/docker-56038fd/scripts/pre_start.sh b/animation/hallo-83dd4eb/docker-56038fd/scripts/pre_start.sh
new file mode 100755
index 0000000..21e2af6
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/scripts/pre_start.sh
@@ -0,0 +1,54 @@
+#!/usr/bin/env bash
+
+export PYTHONUNBUFFERED=1
+export TMPDIR=/workspace/tmp
+export APP="hallo"
+DOCKER_IMAGE_VERSION_FILE="/workspace/${APP}/docker_image_version"
+
+echo "Template version: ${TEMPLATE_VERSION}"
+
+if [[ -e ${DOCKER_IMAGE_VERSION_FILE} ]]; then
+ EXISTING_VERSION=$(cat ${DOCKER_IMAGE_VERSION_FILE})
+else
+ EXISTING_VERSION="0.0.0"
+fi
+
+rsync_with_progress() {
+ stdbuf -i0 -o0 -e0 rsync -au --info=progress2 "$@" | stdbuf -i0 -o0 -e0 tr '\r' '\n' | stdbuf -i0 -o0 -e0 grep -oP '\d+%|\d+.\d+[mMgG]' | tqdm --bar-format='{l_bar}{bar}' --total=100 --unit='%' > /dev/null
+}
+
+sync_apps() {
+ # Only sync if the DISABLE_SYNC environment variable is not set
+ if [ -z "${DISABLE_SYNC}" ]; then
+ # Sync application to workspace to support Network volumes
+ echo "Syncing ${APP} to workspace, please wait..."
+ rsync_with_progress --remove-source-files /${APP}/ /workspace/${APP}/
+
+ echo "${TEMPLATE_VERSION}" > ${DOCKER_IMAGE_VERSION_FILE}
+ fi
+}
+
+if [ "$(printf '%s\n' "$EXISTING_VERSION" "$TEMPLATE_VERSION" | sort -V | head -n 1)" = "$EXISTING_VERSION" ]; then
+ if [ "$EXISTING_VERSION" != "$TEMPLATE_VERSION" ]; then
+ sync_apps
+
+ # Create directories
+ mkdir -p /workspace/logs /workspace/tmp
+ else
+ echo "Existing version is the same as the template version, no syncing required."
+ fi
+else
+ echo "Existing version is newer than the template version, not syncing!"
+fi
+
+if [[ ${DISABLE_AUTOLAUNCH} ]]
+then
+ echo "Auto launching is disabled so the application will not be started automatically"
+ echo "You can launch it manually:"
+ echo ""
+ echo " /start_hallo.sh"
+else
+ /start_hallo.sh
+fi
+
+echo "All services have been started"
diff --git a/animation/hallo-83dd4eb/docker-56038fd/scripts/start_hallo.sh b/animation/hallo-83dd4eb/docker-56038fd/scripts/start_hallo.sh
new file mode 100755
index 0000000..72c900e
--- /dev/null
+++ b/animation/hallo-83dd4eb/docker-56038fd/scripts/start_hallo.sh
@@ -0,0 +1,14 @@
+#!/usr/bin/env bash
+
+echo "Starting hallo"
+source /venv/bin/activate
+cd /workspace/hallo
+TCMALLOC="$(ldconfig -p | grep -Po "libtcmalloc.so.\d" | head -n 1)"
+export PYTHONUNBUFFERED=1
+export LD_PRELOAD="${TCMALLOC}"
+export GRADIO_SERVER_NAME="0.0.0.0"
+export GRADIO_SERVER_PORT="3001"
+nohup python3 scripts/app.py > /workspace/logs/hallo.log 2>&1 &
+echo "hallo started"
+echo "Log file: /workspace/logs/hallo.log"
+deactivate
diff --git a/animation/hallo-83dd4eb/examples/driving_audios/1.wav b/animation/hallo-83dd4eb/examples/driving_audios/1.wav
new file mode 100755
index 0000000..9f3e232
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/driving_audios/1.wav differ
diff --git a/animation/hallo-83dd4eb/examples/driving_audios/2.wav b/animation/hallo-83dd4eb/examples/driving_audios/2.wav
new file mode 100755
index 0000000..740a5f0
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/driving_audios/2.wav differ
diff --git a/animation/hallo-83dd4eb/examples/driving_audios/3.wav b/animation/hallo-83dd4eb/examples/driving_audios/3.wav
new file mode 100755
index 0000000..acafdf2
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/driving_audios/3.wav differ
diff --git a/animation/hallo-83dd4eb/examples/driving_audios/4.wav b/animation/hallo-83dd4eb/examples/driving_audios/4.wav
new file mode 100755
index 0000000..d42d587
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/driving_audios/4.wav differ
diff --git a/animation/hallo-83dd4eb/examples/driving_audios/5.wav b/animation/hallo-83dd4eb/examples/driving_audios/5.wav
new file mode 100755
index 0000000..bf35af7
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/driving_audios/5.wav differ
diff --git a/animation/hallo-83dd4eb/examples/masks/1.png b/animation/hallo-83dd4eb/examples/masks/1.png
new file mode 100644
index 0000000..c63e075
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/masks/1.png differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/1.jpg b/animation/hallo-83dd4eb/examples/reference_images/1.jpg
new file mode 100755
index 0000000..d7d4f55
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/1.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/2.jpg b/animation/hallo-83dd4eb/examples/reference_images/2.jpg
new file mode 100755
index 0000000..7a9b000
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/2.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/3.jpg b/animation/hallo-83dd4eb/examples/reference_images/3.jpg
new file mode 100755
index 0000000..3c1161c
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/3.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/4.jpg b/animation/hallo-83dd4eb/examples/reference_images/4.jpg
new file mode 100755
index 0000000..60069f8
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/4.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/5.jpg b/animation/hallo-83dd4eb/examples/reference_images/5.jpg
new file mode 100755
index 0000000..d4f5e47
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/5.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/6.jpg b/animation/hallo-83dd4eb/examples/reference_images/6.jpg
new file mode 100755
index 0000000..22f1940
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/6.jpg differ
diff --git a/animation/hallo-83dd4eb/examples/reference_images/7.jpg b/animation/hallo-83dd4eb/examples/reference_images/7.jpg
new file mode 100755
index 0000000..a1fbf28
Binary files /dev/null and b/animation/hallo-83dd4eb/examples/reference_images/7.jpg differ
diff --git a/animation/hallo-83dd4eb/hallo/__init__.py b/animation/hallo-83dd4eb/hallo/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/hallo/animate/__init__.py b/animation/hallo-83dd4eb/hallo/animate/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/hallo/animate/face_animate.py b/animation/hallo-83dd4eb/hallo/animate/face_animate.py
new file mode 100644
index 0000000..5c38d15
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/animate/face_animate.py
@@ -0,0 +1,442 @@
+# pylint: disable=R0801
+"""
+This module is responsible for animating faces in videos using a combination of deep learning techniques.
+It provides a pipeline for generating face animations by processing video frames and extracting face features.
+The module utilizes various schedulers and utilities for efficient face animation and supports different types
+ of latents for more control over the animation process.
+
+Functions and Classes:
+- FaceAnimatePipeline: A class that extends the DiffusionPipeline class from the diffusers library to handle face animation tasks.
+ - __init__: Initializes the pipeline with the necessary components (VAE, UNets, face locator, etc.).
+ - prepare_latents: Generates or loads latents for the animation process, scaling them according to the scheduler's requirements.
+ - prepare_extra_step_kwargs: Prepares extra keyword arguments for the scheduler step, ensuring compatibility with different schedulers.
+ - decode_latents: Decodes the latents into video frames, ready for animation.
+
+Usage:
+- Import the necessary packages and classes.
+- Create a FaceAnimatePipeline instance with the required components.
+- Prepare the latents for the animation process.
+- Use the pipeline to generate the animated video.
+
+Note:
+- This module is designed to work with the diffusers library, which provides the underlying framework for face animation using deep learning.
+- The module is intended for research and development purposes, and further optimization and customization may be required for specific use cases.
+"""
+
+import inspect
+from dataclasses import dataclass
+from typing import Callable, List, Optional, Union
+
+import numpy as np
+import torch
+from diffusers import (DDIMScheduler, DiffusionPipeline,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ LMSDiscreteScheduler, PNDMScheduler)
+from diffusers.image_processor import VaeImageProcessor
+from diffusers.utils import BaseOutput
+from diffusers.utils.torch_utils import randn_tensor
+from einops import rearrange, repeat
+from tqdm import tqdm
+
+from hallo.models.mutual_self_attention import ReferenceAttentionControl
+
+
+@dataclass
+class FaceAnimatePipelineOutput(BaseOutput):
+ """
+ FaceAnimatePipelineOutput is a custom class that inherits from BaseOutput and represents the output of the FaceAnimatePipeline.
+
+ Attributes:
+ videos (Union[torch.Tensor, np.ndarray]): A tensor or numpy array containing the generated video frames.
+
+ Methods:
+ __init__(self, videos: Union[torch.Tensor, np.ndarray]): Initializes the FaceAnimatePipelineOutput object with the generated video frames.
+ """
+ videos: Union[torch.Tensor, np.ndarray]
+
+class FaceAnimatePipeline(DiffusionPipeline):
+ """
+ FaceAnimatePipeline is a custom DiffusionPipeline for animating faces.
+
+ It inherits from the DiffusionPipeline class and is used to animate faces by
+ utilizing a variational autoencoder (VAE), a reference UNet, a denoising UNet,
+ a face locator, and an image processor. The pipeline is responsible for generating
+ and animating face latents, and decoding the latents to produce the final video output.
+
+ Attributes:
+ vae (VaeImageProcessor): Variational autoencoder for processing images.
+ reference_unet (nn.Module): Reference UNet for mutual self-attention.
+ denoising_unet (nn.Module): Denoising UNet for image denoising.
+ face_locator (nn.Module): Face locator for detecting and cropping faces.
+ image_proj (nn.Module): Image projector for processing images.
+ scheduler (Union[DDIMScheduler, PNDMScheduler, LMSDiscreteScheduler,
+ EulerDiscreteScheduler, EulerAncestralDiscreteScheduler,
+ DPMSolverMultistepScheduler]): Diffusion scheduler for
+ controlling the noise level.
+
+ Methods:
+ __init__(self, vae, reference_unet, denoising_unet, face_locator,
+ image_proj, scheduler): Initializes the FaceAnimatePipeline
+ with the given components and scheduler.
+ prepare_latents(self, batch_size, num_channels_latents, width, height,
+ video_length, dtype, device, generator=None, latents=None):
+ Prepares the initial latents for video generation.
+ prepare_extra_step_kwargs(self, generator, eta): Prepares extra keyword
+ arguments for the scheduler step.
+ decode_latents(self, latents): Decodes the latents to produce the final
+ video output.
+ """
+ def __init__(
+ self,
+ vae,
+ reference_unet,
+ denoising_unet,
+ face_locator,
+ image_proj,
+ scheduler: Union[
+ DDIMScheduler,
+ PNDMScheduler,
+ LMSDiscreteScheduler,
+ EulerDiscreteScheduler,
+ EulerAncestralDiscreteScheduler,
+ DPMSolverMultistepScheduler,
+ ],
+ ) -> None:
+ super().__init__()
+
+ self.register_modules(
+ vae=vae,
+ reference_unet=reference_unet,
+ denoising_unet=denoising_unet,
+ face_locator=face_locator,
+ scheduler=scheduler,
+ image_proj=image_proj,
+ )
+
+ self.vae_scale_factor: int = 2 ** (len(self.vae.config.block_out_channels) - 1)
+
+ self.ref_image_processor = VaeImageProcessor(
+ vae_scale_factor=self.vae_scale_factor, do_convert_rgb=True,
+ )
+
+ @property
+ def _execution_device(self):
+ if self.device != torch.device("meta") or not hasattr(self.unet, "_hf_hook"):
+ return self.device
+ for module in self.unet.modules():
+ if (
+ hasattr(module, "_hf_hook")
+ and hasattr(module._hf_hook, "execution_device")
+ and module._hf_hook.execution_device is not None
+ ):
+ return torch.device(module._hf_hook.execution_device)
+ return self.device
+
+ def prepare_latents(
+ self,
+ batch_size: int, # Number of videos to generate in parallel
+ num_channels_latents: int, # Number of channels in the latents
+ width: int, # Width of the video frame
+ height: int, # Height of the video frame
+ video_length: int, # Length of the video in frames
+ dtype: torch.dtype, # Data type of the latents
+ device: torch.device, # Device to store the latents on
+ generator: Optional[torch.Generator] = None, # Random number generator for reproducibility
+ latents: Optional[torch.Tensor] = None # Pre-generated latents (optional)
+ ):
+ """
+ Prepares the initial latents for video generation.
+
+ Args:
+ batch_size (int): Number of videos to generate in parallel.
+ num_channels_latents (int): Number of channels in the latents.
+ width (int): Width of the video frame.
+ height (int): Height of the video frame.
+ video_length (int): Length of the video in frames.
+ dtype (torch.dtype): Data type of the latents.
+ device (torch.device): Device to store the latents on.
+ generator (Optional[torch.Generator]): Random number generator for reproducibility.
+ latents (Optional[torch.Tensor]): Pre-generated latents (optional).
+
+ Returns:
+ latents (torch.Tensor): Tensor of shape (batch_size, num_channels_latents, width, height)
+ containing the initial latents for video generation.
+ """
+ shape = (
+ batch_size,
+ num_channels_latents,
+ video_length,
+ height // self.vae_scale_factor,
+ width // self.vae_scale_factor,
+ )
+ if isinstance(generator, list) and len(generator) != batch_size:
+ raise ValueError(
+ f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
+ f" size of {batch_size}. Make sure the batch size matches the length of the generators."
+ )
+
+ if latents is None:
+ latents = randn_tensor(
+ shape, generator=generator, device=device, dtype=dtype
+ )
+ else:
+ latents = latents.to(device)
+
+ # scale the initial noise by the standard deviation required by the scheduler
+ latents = latents * self.scheduler.init_noise_sigma
+ return latents
+
+ def prepare_extra_step_kwargs(self, generator, eta):
+ """
+ Prepares extra keyword arguments for the scheduler step.
+
+ Args:
+ generator (Optional[torch.Generator]): Random number generator for reproducibility.
+ eta (float): The eta (η) parameter used with the DDIMScheduler.
+ It corresponds to η in the DDIM paper (https://arxiv.org/abs/2010.02502) and should be between [0, 1].
+
+ Returns:
+ dict: A dictionary containing the extra keyword arguments for the scheduler step.
+ """
+ # prepare extra kwargs for the scheduler step, since not all schedulers have the same signature
+ # eta (η) is only used with the DDIMScheduler, it will be ignored for other schedulers.
+ # eta corresponds to η in DDIM paper: https://arxiv.org/abs/2010.02502
+ # and should be between [0, 1]
+
+ accepts_eta = "eta" in set(
+ inspect.signature(self.scheduler.step).parameters.keys()
+ )
+ extra_step_kwargs = {}
+ if accepts_eta:
+ extra_step_kwargs["eta"] = eta
+
+ # check if the scheduler accepts generator
+ accepts_generator = "generator" in set(
+ inspect.signature(self.scheduler.step).parameters.keys()
+ )
+ if accepts_generator:
+ extra_step_kwargs["generator"] = generator
+ return extra_step_kwargs
+
+ def decode_latents(self, latents):
+ """
+ Decode the latents to produce a video.
+
+ Parameters:
+ latents (torch.Tensor): The latents to be decoded.
+
+ Returns:
+ video (torch.Tensor): The decoded video.
+ video_length (int): The length of the video in frames.
+ """
+ video_length = latents.shape[2]
+ latents = 1 / 0.18215 * latents
+ latents = rearrange(latents, "b c f h w -> (b f) c h w")
+ # video = self.vae.decode(latents).sample
+ video = []
+ for frame_idx in tqdm(range(latents.shape[0])):
+ video.append(self.vae.decode(
+ latents[frame_idx: frame_idx + 1]).sample)
+ video = torch.cat(video)
+ video = rearrange(video, "(b f) c h w -> b c f h w", f=video_length)
+ video = (video / 2 + 0.5).clamp(0, 1)
+ # we always cast to float32 as this does not cause significant overhead and is compatible with bfloa16
+ video = video.cpu().float().numpy()
+ return video
+
+
+ @torch.no_grad()
+ def __call__(
+ self,
+ ref_image,
+ face_emb,
+ audio_tensor,
+ face_mask,
+ pixel_values_full_mask,
+ pixel_values_face_mask,
+ pixel_values_lip_mask,
+ width,
+ height,
+ video_length,
+ num_inference_steps,
+ guidance_scale,
+ num_images_per_prompt=1,
+ eta: float = 0.0,
+ motion_scale: Optional[List[torch.Tensor]] = None,
+ generator: Optional[Union[torch.Generator,
+ List[torch.Generator]]] = None,
+ output_type: Optional[str] = "tensor",
+ return_dict: bool = True,
+ callback: Optional[Callable[[
+ int, int, torch.FloatTensor], None]] = None,
+ callback_steps: Optional[int] = 1,
+ **kwargs,
+ ):
+ # Default height and width to unet
+ height = height or self.unet.config.sample_size * self.vae_scale_factor
+ width = width or self.unet.config.sample_size * self.vae_scale_factor
+
+ device = self._execution_device
+
+ do_classifier_free_guidance = guidance_scale > 1.0
+
+ # Prepare timesteps
+ self.scheduler.set_timesteps(num_inference_steps, device=device)
+ timesteps = self.scheduler.timesteps
+
+ batch_size = 1
+
+ # prepare clip image embeddings
+ clip_image_embeds = face_emb
+ clip_image_embeds = clip_image_embeds.to(self.image_proj.device, self.image_proj.dtype)
+
+ encoder_hidden_states = self.image_proj(clip_image_embeds)
+ uncond_encoder_hidden_states = self.image_proj(torch.zeros_like(clip_image_embeds))
+
+ if do_classifier_free_guidance:
+ encoder_hidden_states = torch.cat([uncond_encoder_hidden_states, encoder_hidden_states], dim=0)
+
+ reference_control_writer = ReferenceAttentionControl(
+ self.reference_unet,
+ do_classifier_free_guidance=do_classifier_free_guidance,
+ mode="write",
+ batch_size=batch_size,
+ fusion_blocks="full",
+ )
+ reference_control_reader = ReferenceAttentionControl(
+ self.denoising_unet,
+ do_classifier_free_guidance=do_classifier_free_guidance,
+ mode="read",
+ batch_size=batch_size,
+ fusion_blocks="full",
+ )
+
+ num_channels_latents = self.denoising_unet.in_channels
+
+ latents = self.prepare_latents(
+ batch_size * num_images_per_prompt,
+ num_channels_latents,
+ width,
+ height,
+ video_length,
+ clip_image_embeds.dtype,
+ device,
+ generator,
+ )
+
+ # Prepare extra step kwargs.
+ extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
+
+ # Prepare ref image latents
+ ref_image_tensor = rearrange(ref_image, "b f c h w -> (b f) c h w")
+ ref_image_tensor = self.ref_image_processor.preprocess(ref_image_tensor, height=height, width=width) # (bs, c, width, height)
+ ref_image_tensor = ref_image_tensor.to(dtype=self.vae.dtype, device=self.vae.device)
+ ref_image_latents = self.vae.encode(ref_image_tensor).latent_dist.mean
+ ref_image_latents = ref_image_latents * 0.18215 # (b, 4, h, w)
+
+
+ face_mask = face_mask.unsqueeze(1).to(dtype=self.face_locator.dtype, device=self.face_locator.device) # (bs, f, c, H, W)
+ face_mask = repeat(face_mask, "b f c h w -> b (repeat f) c h w", repeat=video_length)
+ face_mask = face_mask.transpose(1, 2) # (bs, c, f, H, W)
+ face_mask = self.face_locator(face_mask)
+ face_mask = torch.cat([torch.zeros_like(face_mask), face_mask], dim=0) if do_classifier_free_guidance else face_mask
+
+ pixel_values_full_mask = (
+ [torch.cat([mask] * 2) for mask in pixel_values_full_mask]
+ if do_classifier_free_guidance
+ else pixel_values_full_mask
+ )
+ pixel_values_face_mask = (
+ [torch.cat([mask] * 2) for mask in pixel_values_face_mask]
+ if do_classifier_free_guidance
+ else pixel_values_face_mask
+ )
+ pixel_values_lip_mask = (
+ [torch.cat([mask] * 2) for mask in pixel_values_lip_mask]
+ if do_classifier_free_guidance
+ else pixel_values_lip_mask
+ )
+ pixel_values_face_mask_ = []
+ for mask in pixel_values_face_mask:
+ pixel_values_face_mask_.append(
+ mask.to(device=self.denoising_unet.device, dtype=self.denoising_unet.dtype))
+ pixel_values_face_mask = pixel_values_face_mask_
+ pixel_values_lip_mask_ = []
+ for mask in pixel_values_lip_mask:
+ pixel_values_lip_mask_.append(
+ mask.to(device=self.denoising_unet.device, dtype=self.denoising_unet.dtype))
+ pixel_values_lip_mask = pixel_values_lip_mask_
+ pixel_values_full_mask_ = []
+ for mask in pixel_values_full_mask:
+ pixel_values_full_mask_.append(
+ mask.to(device=self.denoising_unet.device, dtype=self.denoising_unet.dtype))
+ pixel_values_full_mask = pixel_values_full_mask_
+
+
+ uncond_audio_tensor = torch.zeros_like(audio_tensor)
+ audio_tensor = torch.cat([uncond_audio_tensor, audio_tensor], dim=0)
+ audio_tensor = audio_tensor.to(dtype=self.denoising_unet.dtype, device=self.denoising_unet.device)
+
+ # denoising loop
+ num_warmup_steps = len(timesteps) - num_inference_steps * self.scheduler.order
+ with self.progress_bar(total=num_inference_steps) as progress_bar:
+ for i, t in enumerate(timesteps):
+ # Forward reference image
+ if i == 0:
+ self.reference_unet(
+ ref_image_latents.repeat(
+ (2 if do_classifier_free_guidance else 1), 1, 1, 1
+ ),
+ torch.zeros_like(t),
+ encoder_hidden_states=encoder_hidden_states,
+ return_dict=False,
+ )
+ reference_control_reader.update(reference_control_writer)
+
+ # expand the latents if we are doing classifier free guidance
+ latent_model_input = torch.cat([latents] * 2) if do_classifier_free_guidance else latents
+ latent_model_input = self.scheduler.scale_model_input(latent_model_input, t)
+
+ noise_pred = self.denoising_unet(
+ latent_model_input,
+ t,
+ encoder_hidden_states=encoder_hidden_states,
+ mask_cond_fea=face_mask,
+ full_mask=pixel_values_full_mask,
+ face_mask=pixel_values_face_mask,
+ lip_mask=pixel_values_lip_mask,
+ audio_embedding=audio_tensor,
+ motion_scale=motion_scale,
+ return_dict=False,
+ )[0]
+
+ # perform guidance
+ if do_classifier_free_guidance:
+ noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
+ noise_pred = noise_pred_uncond + guidance_scale * (noise_pred_text - noise_pred_uncond)
+
+ # compute the previous noisy sample x_t -> x_t-1
+ latents = self.scheduler.step(noise_pred, t, latents, **extra_step_kwargs, return_dict=False)[0]
+
+ # call the callback, if provided
+ if i == len(timesteps) - 1 or (i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0:
+ progress_bar.update()
+ if callback is not None and i % callback_steps == 0:
+ step_idx = i // getattr(self.scheduler, "order", 1)
+ callback(step_idx, t, latents)
+
+ reference_control_reader.clear()
+ reference_control_writer.clear()
+
+ # Post-processing
+ images = self.decode_latents(latents) # (b, c, f, h, w)
+
+ # Convert to tensor
+ if output_type == "tensor":
+ images = torch.from_numpy(images)
+
+ if not return_dict:
+ return images
+
+ return FaceAnimatePipelineOutput(videos=images)
diff --git a/animation/hallo-83dd4eb/hallo/animate/face_animate_static.py b/animation/hallo-83dd4eb/hallo/animate/face_animate_static.py
new file mode 100644
index 0000000..42c0fd5
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/animate/face_animate_static.py
@@ -0,0 +1,481 @@
+# pylint: disable=R0801
+"""
+This module is responsible for handling the animation of faces using a combination of deep learning models and image processing techniques.
+It provides a pipeline to generate realistic face animations by incorporating user-provided conditions such as facial expressions and environments.
+The module utilizes various schedulers and utilities to optimize the animation process and ensure efficient performance.
+
+Functions and Classes:
+- StaticPipelineOutput: A class that represents the output of the animation pipeline, c
+ ontaining properties and methods related to the generated images.
+- prepare_latents: A function that prepares the initial noise for the animation process,
+ scaling it according to the scheduler's requirements.
+- prepare_condition: A function that processes the user-provided conditions
+ (e.g., facial expressions) and prepares them for use in the animation pipeline.
+- decode_latents: A function that decodes the latent representations of the face animations into
+ their corresponding image formats.
+- prepare_extra_step_kwargs: A function that prepares additional parameters for each step of
+ the animation process, such as the generator and eta values.
+
+Dependencies:
+- numpy: A library for numerical computing.
+- torch: A machine learning library based on PyTorch.
+- diffusers: A library for image-to-image diffusion models.
+- transformers: A library for pre-trained transformer models.
+
+Usage:
+- To create an instance of the animation pipeline, provide the necessary components such as
+ the VAE, reference UNET, denoising UNET, face locator, and image processor.
+- Use the pipeline's methods to prepare the latents, conditions, and extra step arguments as
+ required for the animation process.
+- Generate the face animations by decoding the latents and processing the conditions.
+
+Note:
+- The module is designed to work with the diffusers library, which is based on
+ the paper "Diffusion Models for Image-to-Image Translation" (https://arxiv.org/abs/2102.02765).
+- The face animations generated by this module should be used for entertainment purposes
+ only and should respect the rights and privacy of the individuals involved.
+"""
+import inspect
+from dataclasses import dataclass
+from typing import Callable, List, Optional, Union
+
+import numpy as np
+import torch
+from diffusers import DiffusionPipeline
+from diffusers.image_processor import VaeImageProcessor
+from diffusers.schedulers import (DDIMScheduler, DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler,
+ EulerDiscreteScheduler, LMSDiscreteScheduler,
+ PNDMScheduler)
+from diffusers.utils import BaseOutput, is_accelerate_available
+from diffusers.utils.torch_utils import randn_tensor
+from einops import rearrange
+from tqdm import tqdm
+from transformers import CLIPImageProcessor
+
+from hallo.models.mutual_self_attention import ReferenceAttentionControl
+
+if is_accelerate_available():
+ from accelerate import cpu_offload
+else:
+ raise ImportError("Please install accelerate via `pip install accelerate`")
+
+
+@dataclass
+class StaticPipelineOutput(BaseOutput):
+ """
+ StaticPipelineOutput is a class that represents the output of the static pipeline.
+ It contains the images generated by the pipeline as a union of torch.Tensor and np.ndarray.
+
+ Attributes:
+ images (Union[torch.Tensor, np.ndarray]): The generated images.
+ """
+ images: Union[torch.Tensor, np.ndarray]
+
+
+class StaticPipeline(DiffusionPipeline):
+ """
+ StaticPipelineOutput is a class that represents the output of the static pipeline.
+ It contains the images generated by the pipeline as a union of torch.Tensor and np.ndarray.
+
+ Attributes:
+ images (Union[torch.Tensor, np.ndarray]): The generated images.
+ """
+ _optional_components = []
+
+ def __init__(
+ self,
+ vae,
+ reference_unet,
+ denoising_unet,
+ face_locator,
+ imageproj,
+ scheduler: Union[
+ DDIMScheduler,
+ PNDMScheduler,
+ LMSDiscreteScheduler,
+ EulerDiscreteScheduler,
+ EulerAncestralDiscreteScheduler,
+ DPMSolverMultistepScheduler,
+ ],
+ ):
+ super().__init__()
+
+ self.register_modules(
+ vae=vae,
+ reference_unet=reference_unet,
+ denoising_unet=denoising_unet,
+ face_locator=face_locator,
+ scheduler=scheduler,
+ imageproj=imageproj,
+ )
+ self.vae_scale_factor = 2 ** (
+ len(self.vae.config.block_out_channels) - 1)
+ self.clip_image_processor = CLIPImageProcessor()
+ self.ref_image_processor = VaeImageProcessor(
+ vae_scale_factor=self.vae_scale_factor, do_convert_rgb=True
+ )
+ self.cond_image_processor = VaeImageProcessor(
+ vae_scale_factor=self.vae_scale_factor,
+ do_convert_rgb=True,
+ do_normalize=False,
+ )
+
+ def enable_vae_slicing(self):
+ """
+ Enable VAE slicing.
+
+ This method enables slicing for the VAE model, which can help improve the performance of decoding latents when working with large images.
+ """
+ self.vae.enable_slicing()
+
+ def disable_vae_slicing(self):
+ """
+ Disable vae slicing.
+
+ This function disables the vae slicing for the StaticPipeline object.
+ It calls the `disable_slicing()` method of the vae model.
+ This is useful when you want to use the entire vae model for decoding latents
+ instead of slicing it for better performance.
+ """
+ self.vae.disable_slicing()
+
+ def enable_sequential_cpu_offload(self, gpu_id=0):
+ """
+ Offloads selected models to the GPU for increased performance.
+
+ Args:
+ gpu_id (int, optional): The ID of the GPU to offload models to. Defaults to 0.
+ """
+ device = torch.device(f"cuda:{gpu_id}")
+
+ for cpu_offloaded_model in [self.unet, self.text_encoder, self.vae]:
+ if cpu_offloaded_model is not None:
+ cpu_offload(cpu_offloaded_model, device)
+
+ @property
+ def _execution_device(self):
+ if self.device != torch.device("meta") or not hasattr(self.unet, "_hf_hook"):
+ return self.device
+ for module in self.unet.modules():
+ if (
+ hasattr(module, "_hf_hook")
+ and hasattr(module._hf_hook, "execution_device")
+ and module._hf_hook.execution_device is not None
+ ):
+ return torch.device(module._hf_hook.execution_device)
+ return self.device
+
+ def decode_latents(self, latents):
+ """
+ Decode the given latents to video frames.
+
+ Parameters:
+ latents (torch.Tensor): The latents to be decoded. Shape: (batch_size, num_channels_latents, video_length, height, width).
+
+ Returns:
+ video (torch.Tensor): The decoded video frames. Shape: (batch_size, num_channels_latents, video_length, height, width).
+ """
+ video_length = latents.shape[2]
+ latents = 1 / 0.18215 * latents
+ latents = rearrange(latents, "b c f h w -> (b f) c h w")
+ # video = self.vae.decode(latents).sample
+ video = []
+ for frame_idx in tqdm(range(latents.shape[0])):
+ video.append(self.vae.decode(
+ latents[frame_idx: frame_idx + 1]).sample)
+ video = torch.cat(video)
+ video = rearrange(video, "(b f) c h w -> b c f h w", f=video_length)
+ video = (video / 2 + 0.5).clamp(0, 1)
+ # we always cast to float32 as this does not cause significant overhead and is compatible with bfloa16
+ video = video.cpu().float().numpy()
+ return video
+
+ def prepare_extra_step_kwargs(self, generator, eta):
+ """
+ Prepare extra keyword arguments for the scheduler step.
+
+ Since not all schedulers have the same signature, this function helps to create a consistent interface for the scheduler.
+
+ Args:
+ generator (Optional[torch.Generator]): A random number generator for reproducibility.
+ eta (float): The eta parameter used with the DDIMScheduler. It should be between 0 and 1.
+
+ Returns:
+ dict: A dictionary containing the extra keyword arguments for the scheduler step.
+ """
+ # eta (η) is only used with the DDIMScheduler, it will be ignored for other schedulers.
+ # eta corresponds to η in DDIM paper: https://arxiv.org/abs/2010.02502
+ # and should be between [0, 1]
+
+ accepts_eta = "eta" in set(
+ inspect.signature(self.scheduler.step).parameters.keys()
+ )
+ extra_step_kwargs = {}
+ if accepts_eta:
+ extra_step_kwargs["eta"] = eta
+
+ # check if the scheduler accepts generator
+ accepts_generator = "generator" in set(
+ inspect.signature(self.scheduler.step).parameters.keys()
+ )
+ if accepts_generator:
+ extra_step_kwargs["generator"] = generator
+ return extra_step_kwargs
+
+ def prepare_latents(
+ self,
+ batch_size,
+ num_channels_latents,
+ width,
+ height,
+ dtype,
+ device,
+ generator,
+ latents=None,
+ ):
+ """
+ Prepares the initial latents for the diffusion pipeline.
+
+ Args:
+ batch_size (int): The number of images to generate in one forward pass.
+ num_channels_latents (int): The number of channels in the latents tensor.
+ width (int): The width of the latents tensor.
+ height (int): The height of the latents tensor.
+ dtype (torch.dtype): The data type of the latents tensor.
+ device (torch.device): The device to place the latents tensor on.
+ generator (Optional[torch.Generator], optional): A random number generator
+ for reproducibility. Defaults to None.
+ latents (Optional[torch.Tensor], optional): Pre-computed latents to use as
+ initial conditions for the diffusion process. Defaults to None.
+
+ Returns:
+ torch.Tensor: The prepared latents tensor.
+ """
+ shape = (
+ batch_size,
+ num_channels_latents,
+ height // self.vae_scale_factor,
+ width // self.vae_scale_factor,
+ )
+ if isinstance(generator, list) and len(generator) != batch_size:
+ raise ValueError(
+ f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
+ f" size of {batch_size}. Make sure the batch size matches the length of the generators."
+ )
+
+ if latents is None:
+ latents = randn_tensor(
+ shape, generator=generator, device=device, dtype=dtype
+ )
+ else:
+ latents = latents.to(device)
+
+ # scale the initial noise by the standard deviation required by the scheduler
+ latents = latents * self.scheduler.init_noise_sigma
+ return latents
+
+ def prepare_condition(
+ self,
+ cond_image,
+ width,
+ height,
+ device,
+ dtype,
+ do_classififer_free_guidance=False,
+ ):
+ """
+ Prepares the condition for the face animation pipeline.
+
+ Args:
+ cond_image (torch.Tensor): The conditional image tensor.
+ width (int): The width of the output image.
+ height (int): The height of the output image.
+ device (torch.device): The device to run the pipeline on.
+ dtype (torch.dtype): The data type of the tensor.
+ do_classififer_free_guidance (bool, optional): Whether to use classifier-free guidance or not. Defaults to False.
+
+ Returns:
+ Tuple[torch.Tensor, torch.Tensor]: A tuple of processed condition and mask tensors.
+ """
+ image = self.cond_image_processor.preprocess(
+ cond_image, height=height, width=width
+ ).to(dtype=torch.float32)
+
+ image = image.to(device=device, dtype=dtype)
+
+ if do_classififer_free_guidance:
+ image = torch.cat([image] * 2)
+
+ return image
+
+ @torch.no_grad()
+ def __call__(
+ self,
+ ref_image,
+ face_mask,
+ width,
+ height,
+ num_inference_steps,
+ guidance_scale,
+ face_embedding,
+ num_images_per_prompt=1,
+ eta: float = 0.0,
+ generator: Optional[Union[torch.Generator,
+ List[torch.Generator]]] = None,
+ output_type: Optional[str] = "tensor",
+ return_dict: bool = True,
+ callback: Optional[Callable[[
+ int, int, torch.FloatTensor], None]] = None,
+ callback_steps: Optional[int] = 1,
+ **kwargs,
+ ):
+ # Default height and width to unet
+ height = height or self.unet.config.sample_size * self.vae_scale_factor
+ width = width or self.unet.config.sample_size * self.vae_scale_factor
+
+ device = self._execution_device
+
+ do_classifier_free_guidance = guidance_scale > 1.0
+
+ # Prepare timesteps
+ self.scheduler.set_timesteps(num_inference_steps, device=device)
+ timesteps = self.scheduler.timesteps
+
+ batch_size = 1
+
+ image_prompt_embeds = self.imageproj(face_embedding)
+ uncond_image_prompt_embeds = self.imageproj(
+ torch.zeros_like(face_embedding))
+
+ if do_classifier_free_guidance:
+ image_prompt_embeds = torch.cat(
+ [uncond_image_prompt_embeds, image_prompt_embeds], dim=0
+ )
+
+ reference_control_writer = ReferenceAttentionControl(
+ self.reference_unet,
+ do_classifier_free_guidance=do_classifier_free_guidance,
+ mode="write",
+ batch_size=batch_size,
+ fusion_blocks="full",
+ )
+ reference_control_reader = ReferenceAttentionControl(
+ self.denoising_unet,
+ do_classifier_free_guidance=do_classifier_free_guidance,
+ mode="read",
+ batch_size=batch_size,
+ fusion_blocks="full",
+ )
+
+ num_channels_latents = self.denoising_unet.in_channels
+ latents = self.prepare_latents(
+ batch_size * num_images_per_prompt,
+ num_channels_latents,
+ width,
+ height,
+ face_embedding.dtype,
+ device,
+ generator,
+ )
+ latents = latents.unsqueeze(2) # (bs, c, 1, h', w')
+ # latents_dtype = latents.dtype
+
+ # Prepare extra step kwargs.
+ extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
+
+ # Prepare ref image latents
+ ref_image_tensor = self.ref_image_processor.preprocess(
+ ref_image, height=height, width=width
+ ) # (bs, c, width, height)
+ ref_image_tensor = ref_image_tensor.to(
+ dtype=self.vae.dtype, device=self.vae.device
+ )
+ ref_image_latents = self.vae.encode(ref_image_tensor).latent_dist.mean
+ ref_image_latents = ref_image_latents * 0.18215 # (b, 4, h, w)
+
+ # Prepare face mask image
+ face_mask_tensor = self.cond_image_processor.preprocess(
+ face_mask, height=height, width=width
+ )
+ face_mask_tensor = face_mask_tensor.unsqueeze(2) # (bs, c, 1, h, w)
+ face_mask_tensor = face_mask_tensor.to(
+ device=device, dtype=self.face_locator.dtype
+ )
+ mask_fea = self.face_locator(face_mask_tensor)
+ mask_fea = (
+ torch.cat(
+ [mask_fea] * 2) if do_classifier_free_guidance else mask_fea
+ )
+
+ # denoising loop
+ num_warmup_steps = len(timesteps) - \
+ num_inference_steps * self.scheduler.order
+ with self.progress_bar(total=num_inference_steps) as progress_bar:
+ for i, t in enumerate(timesteps):
+ # 1. Forward reference image
+ if i == 0:
+ self.reference_unet(
+ ref_image_latents.repeat(
+ (2 if do_classifier_free_guidance else 1), 1, 1, 1
+ ),
+ torch.zeros_like(t),
+ encoder_hidden_states=image_prompt_embeds,
+ return_dict=False,
+ )
+
+ # 2. Update reference unet feature into denosing net
+ reference_control_reader.update(reference_control_writer)
+
+ # 3.1 expand the latents if we are doing classifier free guidance
+ latent_model_input = (
+ torch.cat(
+ [latents] * 2) if do_classifier_free_guidance else latents
+ )
+ latent_model_input = self.scheduler.scale_model_input(
+ latent_model_input, t
+ )
+
+ noise_pred = self.denoising_unet(
+ latent_model_input,
+ t,
+ encoder_hidden_states=image_prompt_embeds,
+ mask_cond_fea=mask_fea,
+ return_dict=False,
+ )[0]
+
+ # perform guidance
+ if do_classifier_free_guidance:
+ noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
+ noise_pred = noise_pred_uncond + guidance_scale * (
+ noise_pred_text - noise_pred_uncond
+ )
+
+ # compute the previous noisy sample x_t -> x_t-1
+ latents = self.scheduler.step(
+ noise_pred, t, latents, **extra_step_kwargs, return_dict=False
+ )[0]
+
+ # call the callback, if provided
+ if i == len(timesteps) - 1 or (
+ (i + 1) > num_warmup_steps and (i +
+ 1) % self.scheduler.order == 0
+ ):
+ progress_bar.update()
+ if callback is not None and i % callback_steps == 0:
+ step_idx = i // getattr(self.scheduler, "order", 1)
+ callback(step_idx, t, latents)
+ reference_control_reader.clear()
+ reference_control_writer.clear()
+
+ # Post-processing
+ image = self.decode_latents(latents) # (b, c, 1, h, w)
+
+ # Convert to tensor
+ if output_type == "tensor":
+ image = torch.from_numpy(image)
+
+ if not return_dict:
+ return image
+
+ return StaticPipelineOutput(images=image)
diff --git a/animation/hallo-83dd4eb/hallo/datasets/__init__.py b/animation/hallo-83dd4eb/hallo/datasets/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/hallo/datasets/audio_processor.py b/animation/hallo-83dd4eb/hallo/datasets/audio_processor.py
new file mode 100644
index 0000000..f340a52
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/datasets/audio_processor.py
@@ -0,0 +1,177 @@
+# pylint: disable=C0301
+'''
+This module contains the AudioProcessor class and related functions for processing audio data.
+It utilizes various libraries and models to perform tasks such as preprocessing, feature extraction,
+and audio separation. The class is initialized with configuration parameters and can process
+audio files using the provided models.
+'''
+import math
+import os
+
+import librosa
+import numpy as np
+import torch
+from audio_separator.separator import Separator
+from einops import rearrange
+from transformers import Wav2Vec2FeatureExtractor
+
+from hallo.models.wav2vec import Wav2VecModel
+from hallo.utils.util import resample_audio
+
+
+class AudioProcessor:
+ """
+ AudioProcessor is a class that handles the processing of audio files.
+ It takes care of preprocessing the audio files, extracting features
+ using wav2vec models, and separating audio signals if needed.
+
+ :param sample_rate: Sampling rate of the audio file
+ :param fps: Frames per second for the extracted features
+ :param wav2vec_model_path: Path to the wav2vec model
+ :param only_last_features: Whether to only use the last features
+ :param audio_separator_model_path: Path to the audio separator model
+ :param audio_separator_model_name: Name of the audio separator model
+ :param cache_dir: Directory to cache the intermediate results
+ :param device: Device to run the processing on
+ """
+ def __init__(
+ self,
+ sample_rate,
+ fps,
+ wav2vec_model_path,
+ only_last_features,
+ audio_separator_model_path:str=None,
+ audio_separator_model_name:str=None,
+ cache_dir:str='',
+ device="cuda:0",
+ ) -> None:
+ self.sample_rate = sample_rate
+ self.fps = fps
+ self.device = device
+
+ self.audio_encoder = Wav2VecModel.from_pretrained(wav2vec_model_path, local_files_only=True).to(device=device)
+ self.audio_encoder.feature_extractor._freeze_parameters()
+ self.only_last_features = only_last_features
+
+ if audio_separator_model_name is not None:
+ try:
+ os.makedirs(cache_dir, exist_ok=True)
+ except OSError as _:
+ print("Fail to create the output cache dir.")
+ self.audio_separator = Separator(
+ output_dir=cache_dir,
+ output_single_stem="vocals",
+ model_file_dir=audio_separator_model_path,
+ )
+ self.audio_separator.load_model(audio_separator_model_name)
+ assert self.audio_separator.model_instance is not None, "Fail to load audio separate model."
+ else:
+ self.audio_separator=None
+ print("Use audio directly without vocals seperator.")
+
+
+ self.wav2vec_feature_extractor = Wav2Vec2FeatureExtractor.from_pretrained(wav2vec_model_path, local_files_only=True)
+
+
+ def preprocess(self, wav_file: str, clip_length: int=-1):
+ """
+ Preprocess a WAV audio file by separating the vocals from the background and resampling it to a 16 kHz sample rate.
+ The separated vocal track is then converted into wav2vec2 for further processing or analysis.
+
+ Args:
+ wav_file (str): The path to the WAV file to be processed. This file should be accessible and in WAV format.
+
+ Raises:
+ RuntimeError: Raises an exception if the WAV file cannot be processed. This could be due to issues
+ such as file not found, unsupported file format, or errors during the audio processing steps.
+
+ Returns:
+ torch.tensor: Returns an audio embedding as a torch.tensor
+ """
+ if self.audio_separator is not None:
+ # 1. separate vocals
+ # TODO: process in memory
+ outputs = self.audio_separator.separate(wav_file)
+ if len(outputs) <= 0:
+ raise RuntimeError("Audio separate failed.")
+
+ vocal_audio_file = outputs[0]
+ vocal_audio_name, _ = os.path.splitext(vocal_audio_file)
+ vocal_audio_file = os.path.join(self.audio_separator.output_dir, vocal_audio_file)
+ vocal_audio_file = resample_audio(vocal_audio_file, os.path.join(self.audio_separator.output_dir, f"{vocal_audio_name}-16k.wav"), self.sample_rate)
+ else:
+ vocal_audio_file=wav_file
+
+ # 2. extract wav2vec features
+ speech_array, sampling_rate = librosa.load(vocal_audio_file, sr=self.sample_rate)
+ audio_feature = np.squeeze(self.wav2vec_feature_extractor(speech_array, sampling_rate=sampling_rate).input_values)
+ seq_len = math.ceil(len(audio_feature) / self.sample_rate * self.fps)
+ audio_length = seq_len
+
+ audio_feature = torch.from_numpy(audio_feature).float().to(device=self.device)
+
+ if clip_length>0 and seq_len % clip_length != 0:
+ audio_feature = torch.nn.functional.pad(audio_feature, (0, (clip_length - seq_len % clip_length) * (self.sample_rate // self.fps)), 'constant', 0.0)
+ seq_len += clip_length - seq_len % clip_length
+ audio_feature = audio_feature.unsqueeze(0)
+
+ with torch.no_grad():
+ embeddings = self.audio_encoder(audio_feature, seq_len=seq_len, output_hidden_states=True)
+ assert len(embeddings) > 0, "Fail to extract audio embedding"
+ if self.only_last_features:
+ audio_emb = embeddings.last_hidden_state.squeeze()
+ else:
+ audio_emb = torch.stack(embeddings.hidden_states[1:], dim=1).squeeze(0)
+ audio_emb = rearrange(audio_emb, "b s d -> s b d")
+
+ audio_emb = audio_emb.cpu().detach()
+
+ return audio_emb, audio_length
+
+ def get_embedding(self, wav_file: str):
+ """preprocess wav audio file convert to embeddings
+
+ Args:
+ wav_file (str): The path to the WAV file to be processed. This file should be accessible and in WAV format.
+
+ Returns:
+ torch.tensor: Returns an audio embedding as a torch.tensor
+ """
+ speech_array, sampling_rate = librosa.load(
+ wav_file, sr=self.sample_rate)
+ assert sampling_rate == 16000, "The audio sample rate must be 16000"
+ audio_feature = np.squeeze(self.wav2vec_feature_extractor(
+ speech_array, sampling_rate=sampling_rate).input_values)
+ seq_len = math.ceil(len(audio_feature) / self.sample_rate * self.fps)
+
+ audio_feature = torch.from_numpy(
+ audio_feature).float().to(device=self.device)
+ audio_feature = audio_feature.unsqueeze(0)
+
+ with torch.no_grad():
+ embeddings = self.audio_encoder(
+ audio_feature, seq_len=seq_len, output_hidden_states=True)
+ assert len(embeddings) > 0, "Fail to extract audio embedding"
+
+ if self.only_last_features:
+ audio_emb = embeddings.last_hidden_state.squeeze()
+ else:
+ audio_emb = torch.stack(
+ embeddings.hidden_states[1:], dim=1).squeeze(0)
+ audio_emb = rearrange(audio_emb, "b s d -> s b d")
+
+ audio_emb = audio_emb.cpu().detach()
+
+ return audio_emb
+
+ def close(self):
+ """
+ TODO: to be implemented
+ """
+ return self
+
+ def __enter__(self):
+ return self
+
+ def __exit__(self, _exc_type, _exc_val, _exc_tb):
+ self.close()
diff --git a/animation/hallo-83dd4eb/hallo/datasets/image_processor.py b/animation/hallo-83dd4eb/hallo/datasets/image_processor.py
new file mode 100644
index 0000000..1651522
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/datasets/image_processor.py
@@ -0,0 +1,346 @@
+# pylint: disable=W0718
+"""
+This module is responsible for processing images, particularly for face-related tasks.
+It uses various libraries such as OpenCV, NumPy, and InsightFace to perform tasks like
+face detection, augmentation, and mask rendering. The ImageProcessor class encapsulates
+the functionality for these operations.
+"""
+import os
+from typing import List
+
+import cv2
+import mediapipe as mp
+import numpy as np
+import torch
+from insightface.app import FaceAnalysis
+from PIL import Image
+from torchvision import transforms
+
+from ..utils.util import (blur_mask, get_landmark_overframes, get_mask,
+ get_union_face_mask, get_union_lip_mask)
+
+MEAN = 0.5
+STD = 0.5
+
+class ImageProcessor:
+ """
+ ImageProcessor is a class responsible for processing images, particularly for face-related tasks.
+ It takes in an image and performs various operations such as augmentation, face detection,
+ face embedding extraction, and rendering a face mask. The processed images are then used for
+ further analysis or recognition purposes.
+
+ Attributes:
+ img_size (int): The size of the image to be processed.
+ face_analysis_model_path (str): The path to the face analysis model.
+
+ Methods:
+ preprocess(source_image_path, cache_dir):
+ Preprocesses the input image by performing augmentation, face detection,
+ face embedding extraction, and rendering a face mask.
+
+ close():
+ Closes the ImageProcessor and releases any resources being used.
+
+ _augmentation(images, transform, state=None):
+ Applies image augmentation to the input images using the given transform and state.
+
+ __enter__():
+ Enters a runtime context and returns the ImageProcessor object.
+
+ __exit__(_exc_type, _exc_val, _exc_tb):
+ Exits a runtime context and handles any exceptions that occurred during the processing.
+ """
+ def __init__(self, img_size, face_analysis_model_path) -> None:
+ self.img_size = img_size
+
+ self.pixel_transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ transforms.Normalize([MEAN], [STD]),
+ ]
+ )
+
+ self.cond_transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ ]
+ )
+
+ self.attn_transform_64 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 8, self.img_size[0] // 8)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_32 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 16, self.img_size[0] // 16)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_16 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 32, self.img_size[0] // 32)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_8 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 64, self.img_size[0] // 64)),
+ transforms.ToTensor(),
+ ]
+ )
+
+ self.face_analysis = FaceAnalysis(
+ name="",
+ root=face_analysis_model_path,
+ providers=["CUDAExecutionProvider", "CPUExecutionProvider"],
+ )
+ self.face_analysis.prepare(ctx_id=0, det_size=(640, 640))
+
+ def preprocess(self, source_image_path: str, cache_dir: str, face_region_ratio: float):
+ """
+ Apply preprocessing to the source image to prepare for face analysis.
+
+ Parameters:
+ source_image_path (str): The path to the source image.
+ cache_dir (str): The directory to cache intermediate results.
+
+ Returns:
+ None
+ """
+ source_image = Image.open(source_image_path)
+ ref_image_pil = source_image.convert("RGB")
+ # 1. image augmentation
+ pixel_values_ref_img = self._augmentation(ref_image_pil, self.pixel_transform)
+
+ # 2.1 detect face
+ faces = self.face_analysis.get(cv2.cvtColor(np.array(ref_image_pil.copy()), cv2.COLOR_RGB2BGR))
+ if not faces:
+ print("No faces detected in the image. Using the entire image as the face region.")
+ # Use the entire image as the face region
+ face = {
+ "bbox": [0, 0, ref_image_pil.width, ref_image_pil.height],
+ "embedding": np.zeros(512)
+ }
+ else:
+ # Sort faces by size and select the largest one
+ faces_sorted = sorted(faces, key=lambda x: (x["bbox"][2] - x["bbox"][0]) * (x["bbox"][3] - x["bbox"][1]), reverse=True)
+ face = faces_sorted[0] # Select the largest face
+
+ # 2.2 face embedding
+ face_emb = face["embedding"]
+
+ # 2.3 render face mask
+ get_mask(source_image_path, cache_dir, face_region_ratio)
+ file_name = os.path.basename(source_image_path).split(".")[0]
+ face_mask_pil = Image.open(
+ os.path.join(cache_dir, f"{file_name}_face_mask.png")).convert("RGB")
+
+ face_mask = self._augmentation(face_mask_pil, self.cond_transform)
+
+ # 2.4 detect and expand lip, face mask
+ sep_background_mask = Image.open(
+ os.path.join(cache_dir, f"{file_name}_sep_background.png"))
+ sep_face_mask = Image.open(
+ os.path.join(cache_dir, f"{file_name}_sep_face.png"))
+ sep_lip_mask = Image.open(
+ os.path.join(cache_dir, f"{file_name}_sep_lip.png"))
+
+ pixel_values_face_mask = [
+ self._augmentation(sep_face_mask, self.attn_transform_64),
+ self._augmentation(sep_face_mask, self.attn_transform_32),
+ self._augmentation(sep_face_mask, self.attn_transform_16),
+ self._augmentation(sep_face_mask, self.attn_transform_8),
+ ]
+ pixel_values_lip_mask = [
+ self._augmentation(sep_lip_mask, self.attn_transform_64),
+ self._augmentation(sep_lip_mask, self.attn_transform_32),
+ self._augmentation(sep_lip_mask, self.attn_transform_16),
+ self._augmentation(sep_lip_mask, self.attn_transform_8),
+ ]
+ pixel_values_full_mask = [
+ self._augmentation(sep_background_mask, self.attn_transform_64),
+ self._augmentation(sep_background_mask, self.attn_transform_32),
+ self._augmentation(sep_background_mask, self.attn_transform_16),
+ self._augmentation(sep_background_mask, self.attn_transform_8),
+ ]
+
+ pixel_values_full_mask = [mask.view(1, -1)
+ for mask in pixel_values_full_mask]
+ pixel_values_face_mask = [mask.view(1, -1)
+ for mask in pixel_values_face_mask]
+ pixel_values_lip_mask = [mask.view(1, -1)
+ for mask in pixel_values_lip_mask]
+
+ return pixel_values_ref_img, face_mask, face_emb, pixel_values_full_mask, pixel_values_face_mask, pixel_values_lip_mask
+
+ def close(self):
+ """
+ Closes the ImageProcessor and releases any resources held by the FaceAnalysis instance.
+
+ Args:
+ self: The ImageProcessor instance.
+
+ Returns:
+ None.
+ """
+ for _, model in self.face_analysis.models.items():
+ if hasattr(model, "Dispose"):
+ model.Dispose()
+
+ def _augmentation(self, images, transform, state=None):
+ if state is not None:
+ torch.set_rng_state(state)
+ if isinstance(images, List):
+ transformed_images = [transform(img) for img in images]
+ ret_tensor = torch.stack(transformed_images, dim=0) # (f, c, h, w)
+ else:
+ ret_tensor = transform(images) # (c, h, w)
+ return ret_tensor
+
+ def __enter__(self):
+ return self
+
+ def __exit__(self, _exc_type, _exc_val, _exc_tb):
+ self.close()
+
+
+class ImageProcessorForDataProcessing():
+ """
+ ImageProcessor is a class responsible for processing images, particularly for face-related tasks.
+ It takes in an image and performs various operations such as augmentation, face detection,
+ face embedding extraction, and rendering a face mask. The processed images are then used for
+ further analysis or recognition purposes.
+
+ Attributes:
+ img_size (int): The size of the image to be processed.
+ face_analysis_model_path (str): The path to the face analysis model.
+
+ Methods:
+ preprocess(source_image_path, cache_dir):
+ Preprocesses the input image by performing augmentation, face detection,
+ face embedding extraction, and rendering a face mask.
+
+ close():
+ Closes the ImageProcessor and releases any resources being used.
+
+ _augmentation(images, transform, state=None):
+ Applies image augmentation to the input images using the given transform and state.
+
+ __enter__():
+ Enters a runtime context and returns the ImageProcessor object.
+
+ __exit__(_exc_type, _exc_val, _exc_tb):
+ Exits a runtime context and handles any exceptions that occurred during the processing.
+ """
+ def __init__(self, face_analysis_model_path, landmark_model_path, step) -> None:
+ if step == 2:
+ self.face_analysis = FaceAnalysis(
+ name="",
+ root=face_analysis_model_path,
+ providers=["CUDAExecutionProvider", "CPUExecutionProvider"],
+ )
+ self.face_analysis.prepare(ctx_id=0, det_size=(640, 640))
+ self.landmarker = None
+ else:
+ BaseOptions = mp.tasks.BaseOptions
+ FaceLandmarker = mp.tasks.vision.FaceLandmarker
+ FaceLandmarkerOptions = mp.tasks.vision.FaceLandmarkerOptions
+ VisionRunningMode = mp.tasks.vision.RunningMode
+ # Create a face landmarker instance with the video mode:
+ options = FaceLandmarkerOptions(
+ base_options=BaseOptions(model_asset_path=landmark_model_path),
+ running_mode=VisionRunningMode.IMAGE,
+ )
+ self.landmarker = FaceLandmarker.create_from_options(options)
+ self.face_analysis = None
+
+ def preprocess(self, source_image_path: str):
+ """
+ Apply preprocessing to the source image to prepare for face analysis.
+
+ Parameters:
+ source_image_path (str): The path to the source image.
+ cache_dir (str): The directory to cache intermediate results.
+
+ Returns:
+ None
+ """
+ # 1. get face embdeding
+ face_mask, face_emb, sep_pose_mask, sep_face_mask, sep_lip_mask = None, None, None, None, None
+ if self.face_analysis:
+ for frame in sorted(os.listdir(source_image_path)):
+ try:
+ source_image = Image.open(
+ os.path.join(source_image_path, frame))
+ ref_image_pil = source_image.convert("RGB")
+ # 2.1 detect face
+ faces = self.face_analysis.get(cv2.cvtColor(
+ np.array(ref_image_pil.copy()), cv2.COLOR_RGB2BGR))
+ # use max size face
+ face = sorted(faces, key=lambda x: (
+ x["bbox"][2] - x["bbox"][0]) * (x["bbox"][3] - x["bbox"][1]))[-1]
+ # 2.2 face embedding
+ face_emb = face["embedding"]
+ if face_emb is not None:
+ break
+ except Exception as _:
+ continue
+
+ if self.landmarker:
+ # 3.1 get landmark
+ landmarks, height, width = get_landmark_overframes(
+ self.landmarker, source_image_path)
+ assert len(landmarks) == len(os.listdir(source_image_path))
+
+ # 3 render face and lip mask
+ face_mask = get_union_face_mask(landmarks, height, width)
+ lip_mask = get_union_lip_mask(landmarks, height, width)
+
+ # 4 gaussian blur
+ blur_face_mask = blur_mask(face_mask, (64, 64), (51, 51))
+ blur_lip_mask = blur_mask(lip_mask, (64, 64), (31, 31))
+
+ # 5 seperate mask
+ sep_face_mask = cv2.subtract(blur_face_mask, blur_lip_mask)
+ sep_pose_mask = 255.0 - blur_face_mask
+ sep_lip_mask = blur_lip_mask
+
+ return face_mask, face_emb, sep_pose_mask, sep_face_mask, sep_lip_mask
+
+ def close(self):
+ """
+ Closes the ImageProcessor and releases any resources held by the FaceAnalysis instance.
+
+ Args:
+ self: The ImageProcessor instance.
+
+ Returns:
+ None.
+ """
+ for _, model in self.face_analysis.models.items():
+ if hasattr(model, "Dispose"):
+ model.Dispose()
+
+ def _augmentation(self, images, transform, state=None):
+ if state is not None:
+ torch.set_rng_state(state)
+ if isinstance(images, List):
+ transformed_images = [transform(img) for img in images]
+ ret_tensor = torch.stack(transformed_images, dim=0) # (f, c, h, w)
+ else:
+ ret_tensor = transform(images) # (c, h, w)
+ return ret_tensor
+
+ def __enter__(self):
+ return self
+
+ def __exit__(self, _exc_type, _exc_val, _exc_tb):
+ self.close()
diff --git a/animation/hallo-83dd4eb/hallo/datasets/mask_image.py b/animation/hallo-83dd4eb/hallo/datasets/mask_image.py
new file mode 100644
index 0000000..2d0c94f
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/datasets/mask_image.py
@@ -0,0 +1,154 @@
+# pylint: disable=R0801
+"""
+This module contains the code for a dataset class called FaceMaskDataset, which is used to process and
+load image data related to face masks. The dataset class inherits from the PyTorch Dataset class and
+provides methods for data augmentation, getting items from the dataset, and determining the length of the
+dataset. The module also includes imports for necessary libraries such as json, random, pathlib, torch,
+PIL, and transformers.
+"""
+
+import json
+import random
+from pathlib import Path
+
+import torch
+from PIL import Image
+from torch.utils.data import Dataset
+from torchvision import transforms
+from transformers import CLIPImageProcessor
+
+
+class FaceMaskDataset(Dataset):
+ """
+ FaceMaskDataset is a custom dataset for face mask images.
+
+ Args:
+ img_size (int): The size of the input images.
+ drop_ratio (float, optional): The ratio of dropped pixels during data augmentation. Defaults to 0.1.
+ data_meta_paths (list, optional): The paths to the metadata files containing image paths and labels. Defaults to ["./data/HDTF_meta.json"].
+ sample_margin (int, optional): The margin for sampling regions in the image. Defaults to 30.
+
+ Attributes:
+ img_size (int): The size of the input images.
+ drop_ratio (float): The ratio of dropped pixels during data augmentation.
+ data_meta_paths (list): The paths to the metadata files containing image paths and labels.
+ sample_margin (int): The margin for sampling regions in the image.
+ processor (CLIPImageProcessor): The image processor for preprocessing images.
+ transform (transforms.Compose): The image augmentation transform.
+ """
+
+ def __init__(
+ self,
+ img_size,
+ drop_ratio=0.1,
+ data_meta_paths=None,
+ sample_margin=30,
+ ):
+ super().__init__()
+
+ self.img_size = img_size
+ self.sample_margin = sample_margin
+
+ vid_meta = []
+ for data_meta_path in data_meta_paths:
+ with open(data_meta_path, "r", encoding="utf-8") as f:
+ vid_meta.extend(json.load(f))
+ self.vid_meta = vid_meta
+ self.length = len(self.vid_meta)
+
+ self.clip_image_processor = CLIPImageProcessor()
+
+ self.transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ transforms.Normalize([0.5], [0.5]),
+ ]
+ )
+
+ self.cond_transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ ]
+ )
+
+ self.drop_ratio = drop_ratio
+
+ def augmentation(self, image, transform, state=None):
+ """
+ Apply data augmentation to the input image.
+
+ Args:
+ image (PIL.Image): The input image.
+ transform (torchvision.transforms.Compose): The data augmentation transforms.
+ state (dict, optional): The random state for reproducibility. Defaults to None.
+
+ Returns:
+ PIL.Image: The augmented image.
+ """
+ if state is not None:
+ torch.set_rng_state(state)
+ return transform(image)
+
+ def __getitem__(self, index):
+ video_meta = self.vid_meta[index]
+ video_path = video_meta["image_path"]
+ mask_path = video_meta["mask_path"]
+ face_emb_path = video_meta["face_emb"]
+
+ video_frames = sorted(Path(video_path).iterdir())
+ video_length = len(video_frames)
+
+ margin = min(self.sample_margin, video_length)
+
+ ref_img_idx = random.randint(0, video_length - 1)
+ if ref_img_idx + margin < video_length:
+ tgt_img_idx = random.randint(
+ ref_img_idx + margin, video_length - 1)
+ elif ref_img_idx - margin > 0:
+ tgt_img_idx = random.randint(0, ref_img_idx - margin)
+ else:
+ tgt_img_idx = random.randint(0, video_length - 1)
+
+ ref_img_pil = Image.open(video_frames[ref_img_idx])
+ tgt_img_pil = Image.open(video_frames[tgt_img_idx])
+
+ tgt_mask_pil = Image.open(mask_path)
+
+ assert ref_img_pil is not None, "Fail to load reference image."
+ assert tgt_img_pil is not None, "Fail to load target image."
+ assert tgt_mask_pil is not None, "Fail to load target mask."
+
+ state = torch.get_rng_state()
+ tgt_img = self.augmentation(tgt_img_pil, self.transform, state)
+ tgt_mask_img = self.augmentation(
+ tgt_mask_pil, self.cond_transform, state)
+ tgt_mask_img = tgt_mask_img.repeat(3, 1, 1)
+ ref_img_vae = self.augmentation(
+ ref_img_pil, self.transform, state)
+ face_emb = torch.load(face_emb_path)
+
+
+ sample = {
+ "video_dir": video_path,
+ "img": tgt_img,
+ "tgt_mask": tgt_mask_img,
+ "ref_img": ref_img_vae,
+ "face_emb": face_emb,
+ }
+
+ return sample
+
+ def __len__(self):
+ return len(self.vid_meta)
+
+
+if __name__ == "__main__":
+ data = FaceMaskDataset(img_size=(512, 512))
+ train_dataloader = torch.utils.data.DataLoader(
+ data, batch_size=4, shuffle=True, num_workers=1
+ )
+ for step, batch in enumerate(train_dataloader):
+ print(batch["tgt_mask"].shape)
+ break
diff --git a/animation/hallo-83dd4eb/hallo/datasets/talk_video.py b/animation/hallo-83dd4eb/hallo/datasets/talk_video.py
new file mode 100644
index 0000000..25c3ab8
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/datasets/talk_video.py
@@ -0,0 +1,316 @@
+# pylint: disable=R0801
+"""
+talking_video_dataset.py
+
+This module defines the TalkingVideoDataset class, a custom PyTorch dataset
+for handling talking video data. The dataset uses video files, masks, and
+embeddings to prepare data for tasks such as video generation and
+speech-driven video animation.
+
+Classes:
+ TalkingVideoDataset
+
+Dependencies:
+ json
+ random
+ torch
+ decord.VideoReader, decord.cpu
+ PIL.Image
+ torch.utils.data.Dataset
+ torchvision.transforms
+
+Example:
+ from talking_video_dataset import TalkingVideoDataset
+ from torch.utils.data import DataLoader
+
+ # Example configuration for the Wav2Vec model
+ class Wav2VecConfig:
+ def __init__(self, audio_type, model_scale, features):
+ self.audio_type = audio_type
+ self.model_scale = model_scale
+ self.features = features
+
+ wav2vec_cfg = Wav2VecConfig(audio_type="wav2vec2", model_scale="base", features="feature")
+
+ # Initialize dataset
+ dataset = TalkingVideoDataset(
+ img_size=(512, 512),
+ sample_rate=16000,
+ audio_margin=2,
+ n_motion_frames=0,
+ n_sample_frames=16,
+ data_meta_paths=["path/to/meta1.json", "path/to/meta2.json"],
+ wav2vec_cfg=wav2vec_cfg,
+ )
+
+ # Initialize dataloader
+ dataloader = DataLoader(dataset, batch_size=4, shuffle=True)
+
+ # Fetch one batch of data
+ batch = next(iter(dataloader))
+ print(batch["pixel_values_vid"].shape) # Example output: (4, 16, 3, 512, 512)
+
+The TalkingVideoDataset class provides methods for loading video frames, masks,
+audio embeddings, and other relevant data, applying transformations, and preparing
+the data for training and evaluation in a deep learning pipeline.
+
+Attributes:
+ img_size (tuple): The dimensions to resize the video frames to.
+ sample_rate (int): The audio sample rate.
+ audio_margin (int): The margin for audio sampling.
+ n_motion_frames (int): The number of motion frames.
+ n_sample_frames (int): The number of sample frames.
+ data_meta_paths (list): List of paths to the JSON metadata files.
+ wav2vec_cfg (object): Configuration for the Wav2Vec model.
+
+Methods:
+ augmentation(images, transform, state=None): Apply transformation to input images.
+ __getitem__(index): Get a sample from the dataset at the specified index.
+ __len__(): Return the length of the dataset.
+"""
+
+import json
+import random
+from typing import List
+
+import torch
+from decord import VideoReader, cpu
+from PIL import Image
+from torch.utils.data import Dataset
+from torchvision import transforms
+
+
+class TalkingVideoDataset(Dataset):
+ """
+ A dataset class for processing talking video data.
+
+ Args:
+ img_size (tuple, optional): The size of the output images. Defaults to (512, 512).
+ sample_rate (int, optional): The sample rate of the audio data. Defaults to 16000.
+ audio_margin (int, optional): The margin for the audio data. Defaults to 2.
+ n_motion_frames (int, optional): The number of motion frames. Defaults to 0.
+ n_sample_frames (int, optional): The number of sample frames. Defaults to 16.
+ data_meta_paths (list, optional): The paths to the data metadata. Defaults to None.
+ wav2vec_cfg (dict, optional): The configuration for the wav2vec model. Defaults to None.
+
+ Attributes:
+ img_size (tuple): The size of the output images.
+ sample_rate (int): The sample rate of the audio data.
+ audio_margin (int): The margin for the audio data.
+ n_motion_frames (int): The number of motion frames.
+ n_sample_frames (int): The number of sample frames.
+ data_meta_paths (list): The paths to the data metadata.
+ wav2vec_cfg (dict): The configuration for the wav2vec model.
+ """
+
+ def __init__(
+ self,
+ img_size=(512, 512),
+ sample_rate=16000,
+ audio_margin=2,
+ n_motion_frames=0,
+ n_sample_frames=16,
+ data_meta_paths=None,
+ wav2vec_cfg=None,
+ ):
+ super().__init__()
+ self.sample_rate = sample_rate
+ self.img_size = img_size
+ self.audio_margin = audio_margin
+ self.n_motion_frames = n_motion_frames
+ self.n_sample_frames = n_sample_frames
+ self.audio_type = wav2vec_cfg.audio_type
+ self.audio_model = wav2vec_cfg.model_scale
+ self.audio_features = wav2vec_cfg.features
+
+ vid_meta = []
+ for data_meta_path in data_meta_paths:
+ with open(data_meta_path, "r", encoding="utf-8") as f:
+ vid_meta.extend(json.load(f))
+ self.vid_meta = vid_meta
+ self.length = len(self.vid_meta)
+ self.pixel_transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ transforms.Normalize([0.5], [0.5]),
+ ]
+ )
+
+ self.cond_transform = transforms.Compose(
+ [
+ transforms.Resize(self.img_size),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_64 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 8, self.img_size[0] // 8)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_32 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 16, self.img_size[0] // 16)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_16 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 32, self.img_size[0] // 32)),
+ transforms.ToTensor(),
+ ]
+ )
+ self.attn_transform_8 = transforms.Compose(
+ [
+ transforms.Resize(
+ (self.img_size[0] // 64, self.img_size[0] // 64)),
+ transforms.ToTensor(),
+ ]
+ )
+
+ def augmentation(self, images, transform, state=None):
+ """
+ Apply the given transformation to the input images.
+
+ Args:
+ images (List[PIL.Image] or PIL.Image): The input images to be transformed.
+ transform (torchvision.transforms.Compose): The transformation to be applied to the images.
+ state (torch.ByteTensor, optional): The state of the random number generator.
+ If provided, it will set the RNG state to this value before applying the transformation. Defaults to None.
+
+ Returns:
+ torch.Tensor: The transformed images as a tensor.
+ If the input was a list of images, the tensor will have shape (f, c, h, w),
+ where f is the number of images, c is the number of channels, h is the height, and w is the width.
+ If the input was a single image, the tensor will have shape (c, h, w),
+ where c is the number of channels, h is the height, and w is the width.
+ """
+ if state is not None:
+ torch.set_rng_state(state)
+ if isinstance(images, List):
+ transformed_images = [transform(img) for img in images]
+ ret_tensor = torch.stack(transformed_images, dim=0) # (f, c, h, w)
+ else:
+ ret_tensor = transform(images) # (c, h, w)
+ return ret_tensor
+
+ def __getitem__(self, index):
+ video_meta = self.vid_meta[index]
+ video_path = video_meta["video_path"]
+ mask_path = video_meta["mask_path"]
+ lip_mask_union_path = video_meta.get("sep_mask_lip", None)
+ face_mask_union_path = video_meta.get("sep_mask_face", None)
+ full_mask_union_path = video_meta.get("sep_mask_border", None)
+ face_emb_path = video_meta["face_emb_path"]
+ audio_emb_path = video_meta[
+ f"{self.audio_type}_emb_{self.audio_model}_{self.audio_features}"
+ ]
+ tgt_mask_pil = Image.open(mask_path)
+ video_frames = VideoReader(video_path, ctx=cpu(0))
+ assert tgt_mask_pil is not None, "Fail to load target mask."
+ assert (video_frames is not None and len(video_frames) > 0), "Fail to load video frames."
+ video_length = len(video_frames)
+
+ assert (
+ video_length
+ > self.n_sample_frames + self.n_motion_frames + 2 * self.audio_margin
+ )
+ start_idx = random.randint(
+ self.n_motion_frames,
+ video_length - self.n_sample_frames - self.audio_margin - 1,
+ )
+
+ videos = video_frames[start_idx : start_idx + self.n_sample_frames]
+
+ frame_list = [
+ Image.fromarray(video).convert("RGB") for video in videos.asnumpy()
+ ]
+
+ face_masks_list = [Image.open(face_mask_union_path)] * self.n_sample_frames
+ lip_masks_list = [Image.open(lip_mask_union_path)] * self.n_sample_frames
+ full_masks_list = [Image.open(full_mask_union_path)] * self.n_sample_frames
+ assert face_masks_list[0] is not None, "Fail to load face mask."
+ assert lip_masks_list[0] is not None, "Fail to load lip mask."
+ assert full_masks_list[0] is not None, "Fail to load full mask."
+
+
+ face_emb = torch.load(face_emb_path)
+ audio_emb = torch.load(audio_emb_path)
+ indices = (
+ torch.arange(2 * self.audio_margin + 1) - self.audio_margin
+ ) # Generates [-2, -1, 0, 1, 2]
+ center_indices = torch.arange(
+ start_idx,
+ start_idx + self.n_sample_frames,
+ ).unsqueeze(1) + indices.unsqueeze(0)
+ audio_tensor = audio_emb[center_indices]
+
+ ref_img_idx = random.randint(
+ self.n_motion_frames,
+ video_length - self.n_sample_frames - self.audio_margin - 1,
+ )
+ ref_img = video_frames[ref_img_idx].asnumpy()
+ ref_img = Image.fromarray(ref_img)
+
+ if self.n_motion_frames > 0:
+ motions = video_frames[start_idx - self.n_motion_frames : start_idx]
+ motion_list = [
+ Image.fromarray(motion).convert("RGB") for motion in motions.asnumpy()
+ ]
+
+ # transform
+ state = torch.get_rng_state()
+ pixel_values_vid = self.augmentation(frame_list, self.pixel_transform, state)
+
+ pixel_values_mask = self.augmentation(tgt_mask_pil, self.cond_transform, state)
+ pixel_values_mask = pixel_values_mask.repeat(3, 1, 1)
+
+ pixel_values_face_mask = [
+ self.augmentation(face_masks_list, self.attn_transform_64, state),
+ self.augmentation(face_masks_list, self.attn_transform_32, state),
+ self.augmentation(face_masks_list, self.attn_transform_16, state),
+ self.augmentation(face_masks_list, self.attn_transform_8, state),
+ ]
+ pixel_values_lip_mask = [
+ self.augmentation(lip_masks_list, self.attn_transform_64, state),
+ self.augmentation(lip_masks_list, self.attn_transform_32, state),
+ self.augmentation(lip_masks_list, self.attn_transform_16, state),
+ self.augmentation(lip_masks_list, self.attn_transform_8, state),
+ ]
+ pixel_values_full_mask = [
+ self.augmentation(full_masks_list, self.attn_transform_64, state),
+ self.augmentation(full_masks_list, self.attn_transform_32, state),
+ self.augmentation(full_masks_list, self.attn_transform_16, state),
+ self.augmentation(full_masks_list, self.attn_transform_8, state),
+ ]
+
+ pixel_values_ref_img = self.augmentation(ref_img, self.pixel_transform, state)
+ pixel_values_ref_img = pixel_values_ref_img.unsqueeze(0)
+ if self.n_motion_frames > 0:
+ pixel_values_motion = self.augmentation(
+ motion_list, self.pixel_transform, state
+ )
+ pixel_values_ref_img = torch.cat(
+ [pixel_values_ref_img, pixel_values_motion], dim=0
+ )
+
+ sample = {
+ "video_dir": video_path,
+ "pixel_values_vid": pixel_values_vid,
+ "pixel_values_mask": pixel_values_mask,
+ "pixel_values_face_mask": pixel_values_face_mask,
+ "pixel_values_lip_mask": pixel_values_lip_mask,
+ "pixel_values_full_mask": pixel_values_full_mask,
+ "audio_tensor": audio_tensor,
+ "pixel_values_ref_img": pixel_values_ref_img,
+ "face_emb": face_emb,
+ }
+
+ return sample
+
+ def __len__(self):
+ return len(self.vid_meta)
diff --git a/animation/hallo-83dd4eb/hallo/models/__init__.py b/animation/hallo-83dd4eb/hallo/models/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/hallo/models/attention.py b/animation/hallo-83dd4eb/hallo/models/attention.py
new file mode 100644
index 0000000..d7feec9
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/attention.py
@@ -0,0 +1,921 @@
+# pylint: disable=R0801
+# pylint: disable=C0303
+
+"""
+This module contains various transformer blocks for different applications, such as BasicTransformerBlock,
+TemporalBasicTransformerBlock, and AudioTemporalBasicTransformerBlock. These blocks are used in various models,
+such as GLIGEN, UNet, and others. The transformer blocks implement self-attention, cross-attention, feed-forward
+networks, and other related functions.
+
+Functions and classes included in this module are:
+- BasicTransformerBlock: A basic transformer block with self-attention, cross-attention, and feed-forward layers.
+- TemporalBasicTransformerBlock: A transformer block with additional temporal attention mechanisms for video data.
+- AudioTemporalBasicTransformerBlock: A transformer block with additional audio-specific mechanisms for audio data.
+- zero_module: A function to zero out the parameters of a given module.
+
+For more information on each specific class and function, please refer to the respective docstrings.
+"""
+
+from typing import Any, Dict, List, Optional
+
+import torch
+from diffusers.models.attention import (AdaLayerNorm, AdaLayerNormZero,
+ Attention, FeedForward)
+from diffusers.models.embeddings import SinusoidalPositionalEmbedding
+from einops import rearrange
+from torch import nn
+
+
+class GatedSelfAttentionDense(nn.Module):
+ """
+ A gated self-attention dense layer that combines visual features and object features.
+
+ Parameters:
+ query_dim (`int`): The number of channels in the query.
+ context_dim (`int`): The number of channels in the context.
+ n_heads (`int`): The number of heads to use for attention.
+ d_head (`int`): The number of channels in each head.
+ """
+
+ def __init__(self, query_dim: int, context_dim: int, n_heads: int, d_head: int):
+ super().__init__()
+
+ # we need a linear projection since we need cat visual feature and obj feature
+ self.linear = nn.Linear(context_dim, query_dim)
+
+ self.attn = Attention(query_dim=query_dim, heads=n_heads, dim_head=d_head)
+ self.ff = FeedForward(query_dim, activation_fn="geglu")
+
+ self.norm1 = nn.LayerNorm(query_dim)
+ self.norm2 = nn.LayerNorm(query_dim)
+
+ self.register_parameter("alpha_attn", nn.Parameter(torch.tensor(0.0)))
+ self.register_parameter("alpha_dense", nn.Parameter(torch.tensor(0.0)))
+
+ self.enabled = True
+
+ def forward(self, x: torch.Tensor, objs: torch.Tensor) -> torch.Tensor:
+ """
+ Apply the Gated Self-Attention mechanism to the input tensor `x` and object tensor `objs`.
+
+ Args:
+ x (torch.Tensor): The input tensor.
+ objs (torch.Tensor): The object tensor.
+
+ Returns:
+ torch.Tensor: The output tensor after applying Gated Self-Attention.
+ """
+ if not self.enabled:
+ return x
+
+ n_visual = x.shape[1]
+ objs = self.linear(objs)
+
+ x = x + self.alpha_attn.tanh() * self.attn(self.norm1(torch.cat([x, objs], dim=1)))[:, :n_visual, :]
+ x = x + self.alpha_dense.tanh() * self.ff(self.norm2(x))
+
+ return x
+
+class BasicTransformerBlock(nn.Module):
+ r"""
+ A basic Transformer block.
+
+ Parameters:
+ dim (`int`): The number of channels in the input and output.
+ num_attention_heads (`int`): The number of heads to use for multi-head attention.
+ attention_head_dim (`int`): The number of channels in each head.
+ dropout (`float`, *optional*, defaults to 0.0): The dropout probability to use.
+ cross_attention_dim (`int`, *optional*): The size of the encoder_hidden_states vector for cross attention.
+ activation_fn (`str`, *optional*, defaults to `"geglu"`): Activation function to be used in feed-forward.
+ num_embeds_ada_norm (:
+ obj: `int`, *optional*): The number of diffusion steps used during training. See `Transformer2DModel`.
+ attention_bias (:
+ obj: `bool`, *optional*, defaults to `False`): Configure if the attentions should contain a bias parameter.
+ only_cross_attention (`bool`, *optional*):
+ Whether to use only cross-attention layers. In this case two cross attention layers are used.
+ double_self_attention (`bool`, *optional*):
+ Whether to use two self-attention layers. In this case no cross attention layers are used.
+ upcast_attention (`bool`, *optional*):
+ Whether to upcast the attention computation to float32. This is useful for mixed precision training.
+ norm_elementwise_affine (`bool`, *optional*, defaults to `True`):
+ Whether to use learnable elementwise affine parameters for normalization.
+ norm_type (`str`, *optional*, defaults to `"layer_norm"`):
+ The normalization layer to use. Can be `"layer_norm"`, `"ada_norm"` or `"ada_norm_zero"`.
+ final_dropout (`bool` *optional*, defaults to False):
+ Whether to apply a final dropout after the last feed-forward layer.
+ attention_type (`str`, *optional*, defaults to `"default"`):
+ The type of attention to use. Can be `"default"` or `"gated"` or `"gated-text-image"`.
+ positional_embeddings (`str`, *optional*, defaults to `None`):
+ The type of positional embeddings to apply to.
+ num_positional_embeddings (`int`, *optional*, defaults to `None`):
+ The maximum number of positional embeddings to apply.
+ """
+
+ def __init__(
+ self,
+ dim: int,
+ num_attention_heads: int,
+ attention_head_dim: int,
+ dropout=0.0,
+ cross_attention_dim: Optional[int] = None,
+ activation_fn: str = "geglu",
+ num_embeds_ada_norm: Optional[int] = None,
+ attention_bias: bool = False,
+ only_cross_attention: bool = False,
+ double_self_attention: bool = False,
+ upcast_attention: bool = False,
+ norm_elementwise_affine: bool = True,
+ # 'layer_norm', 'ada_norm', 'ada_norm_zero', 'ada_norm_single'
+ norm_type: str = "layer_norm",
+ norm_eps: float = 1e-5,
+ final_dropout: bool = False,
+ attention_type: str = "default",
+ positional_embeddings: Optional[str] = None,
+ num_positional_embeddings: Optional[int] = None,
+ ):
+ super().__init__()
+ self.only_cross_attention = only_cross_attention
+
+ self.use_ada_layer_norm_zero = (
+ num_embeds_ada_norm is not None
+ ) and norm_type == "ada_norm_zero"
+ self.use_ada_layer_norm = (
+ num_embeds_ada_norm is not None
+ ) and norm_type == "ada_norm"
+ self.use_ada_layer_norm_single = norm_type == "ada_norm_single"
+ self.use_layer_norm = norm_type == "layer_norm"
+
+ if norm_type in ("ada_norm", "ada_norm_zero") and num_embeds_ada_norm is None:
+ raise ValueError(
+ f"`norm_type` is set to {norm_type}, but `num_embeds_ada_norm` is not defined. Please make sure to"
+ f" define `num_embeds_ada_norm` if setting `norm_type` to {norm_type}."
+ )
+
+ if positional_embeddings and (num_positional_embeddings is None):
+ raise ValueError(
+ "If `positional_embedding` type is defined, `num_positition_embeddings` must also be defined."
+ )
+
+ if positional_embeddings == "sinusoidal":
+ self.pos_embed = SinusoidalPositionalEmbedding(
+ dim, max_seq_length=num_positional_embeddings
+ )
+ else:
+ self.pos_embed = None
+
+ # Define 3 blocks. Each block has its own normalization layer.
+ # 1. Self-Attn
+ if self.use_ada_layer_norm:
+ self.norm1 = AdaLayerNorm(dim, num_embeds_ada_norm)
+ elif self.use_ada_layer_norm_zero:
+ self.norm1 = AdaLayerNormZero(dim, num_embeds_ada_norm)
+ else:
+ self.norm1 = nn.LayerNorm(
+ dim, elementwise_affine=norm_elementwise_affine, eps=norm_eps
+ )
+
+ self.attn1 = Attention(
+ query_dim=dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ cross_attention_dim=cross_attention_dim if only_cross_attention else None,
+ upcast_attention=upcast_attention,
+ )
+
+ # 2. Cross-Attn
+ if cross_attention_dim is not None or double_self_attention:
+ # We currently only use AdaLayerNormZero for self attention where there will only be one attention block.
+ # I.e. the number of returned modulation chunks from AdaLayerZero would not make sense if returned during
+ # the second cross attention block.
+ self.norm2 = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(
+ dim, elementwise_affine=norm_elementwise_affine, eps=norm_eps
+ )
+ )
+ self.attn2 = Attention(
+ query_dim=dim,
+ cross_attention_dim=(
+ cross_attention_dim if not double_self_attention else None
+ ),
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ ) # is self-attn if encoder_hidden_states is none
+ else:
+ self.norm2 = None
+ self.attn2 = None
+
+ # 3. Feed-forward
+ if not self.use_ada_layer_norm_single:
+ self.norm3 = nn.LayerNorm(
+ dim, elementwise_affine=norm_elementwise_affine, eps=norm_eps
+ )
+
+ self.ff = FeedForward(
+ dim,
+ dropout=dropout,
+ activation_fn=activation_fn,
+ final_dropout=final_dropout,
+ )
+
+ # 4. Fuser
+ if attention_type in {"gated", "gated-text-image"}: # Updated line
+ self.fuser = GatedSelfAttentionDense(
+ dim, cross_attention_dim, num_attention_heads, attention_head_dim
+ )
+
+ # 5. Scale-shift for PixArt-Alpha.
+ if self.use_ada_layer_norm_single:
+ self.scale_shift_table = nn.Parameter(
+ torch.randn(6, dim) / dim**0.5)
+
+ # let chunk size default to None
+ self._chunk_size = None
+ self._chunk_dim = 0
+
+ def set_chunk_feed_forward(self, chunk_size: Optional[int], dim: int = 0):
+ """
+ Sets the chunk size for feed-forward processing in the transformer block.
+
+ Args:
+ chunk_size (Optional[int]): The size of the chunks to process in feed-forward layers.
+ If None, the chunk size is set to the maximum possible value.
+ dim (int, optional): The dimension along which to split the input tensor into chunks. Defaults to 0.
+
+ Returns:
+ None.
+ """
+ self._chunk_size = chunk_size
+ self._chunk_dim = dim
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ timestep: Optional[torch.LongTensor] = None,
+ cross_attention_kwargs: Dict[str, Any] = None,
+ class_labels: Optional[torch.LongTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ This function defines the forward pass of the BasicTransformerBlock.
+
+ Args:
+ self (BasicTransformerBlock):
+ An instance of the BasicTransformerBlock class.
+ hidden_states (torch.FloatTensor):
+ A tensor containing the hidden states.
+ attention_mask (Optional[torch.FloatTensor], optional):
+ A tensor containing the attention mask. Defaults to None.
+ encoder_hidden_states (Optional[torch.FloatTensor], optional):
+ A tensor containing the encoder hidden states. Defaults to None.
+ encoder_attention_mask (Optional[torch.FloatTensor], optional):
+ A tensor containing the encoder attention mask. Defaults to None.
+ timestep (Optional[torch.LongTensor], optional):
+ A tensor containing the timesteps. Defaults to None.
+ cross_attention_kwargs (Dict[str, Any], optional):
+ Additional cross-attention arguments. Defaults to None.
+ class_labels (Optional[torch.LongTensor], optional):
+ A tensor containing the class labels. Defaults to None.
+
+ Returns:
+ torch.FloatTensor:
+ A tensor containing the transformed hidden states.
+ """
+ # Notice that normalization is always applied before the real computation in the following blocks.
+ # 0. Self-Attention
+ batch_size = hidden_states.shape[0]
+
+ gate_msa = None
+ scale_mlp = None
+ shift_mlp = None
+ gate_mlp = None
+ if self.use_ada_layer_norm:
+ norm_hidden_states = self.norm1(hidden_states, timestep)
+ elif self.use_ada_layer_norm_zero:
+ norm_hidden_states, gate_msa, shift_mlp, scale_mlp, gate_mlp = self.norm1(
+ hidden_states, timestep, class_labels, hidden_dtype=hidden_states.dtype
+ )
+ elif self.use_layer_norm:
+ norm_hidden_states = self.norm1(hidden_states)
+ elif self.use_ada_layer_norm_single:
+ shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = (
+ self.scale_shift_table[None] +
+ timestep.reshape(batch_size, 6, -1)
+ ).chunk(6, dim=1)
+ norm_hidden_states = self.norm1(hidden_states)
+ norm_hidden_states = norm_hidden_states * \
+ (1 + scale_msa) + shift_msa
+ norm_hidden_states = norm_hidden_states.squeeze(1)
+ else:
+ raise ValueError("Incorrect norm used")
+
+ if self.pos_embed is not None:
+ norm_hidden_states = self.pos_embed(norm_hidden_states)
+
+ # 1. Retrieve lora scale.
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+
+ # 2. Prepare GLIGEN inputs
+ cross_attention_kwargs = (
+ cross_attention_kwargs.copy() if cross_attention_kwargs is not None else {}
+ )
+ gligen_kwargs = cross_attention_kwargs.pop("gligen", None)
+
+ attn_output = self.attn1(
+ norm_hidden_states,
+ encoder_hidden_states=(
+ encoder_hidden_states if self.only_cross_attention else None
+ ),
+ attention_mask=attention_mask,
+ **cross_attention_kwargs,
+ )
+ if self.use_ada_layer_norm_zero:
+ attn_output = gate_msa.unsqueeze(1) * attn_output
+ elif self.use_ada_layer_norm_single:
+ attn_output = gate_msa * attn_output
+
+ hidden_states = attn_output + hidden_states
+ if hidden_states.ndim == 4:
+ hidden_states = hidden_states.squeeze(1)
+
+ # 2.5 GLIGEN Control
+ if gligen_kwargs is not None:
+ hidden_states = self.fuser(hidden_states, gligen_kwargs["objs"])
+
+ # 3. Cross-Attention
+ if self.attn2 is not None:
+ if self.use_ada_layer_norm:
+ norm_hidden_states = self.norm2(hidden_states, timestep)
+ elif self.use_ada_layer_norm_zero or self.use_layer_norm:
+ norm_hidden_states = self.norm2(hidden_states)
+ elif self.use_ada_layer_norm_single:
+ # For PixArt norm2 isn't applied here:
+ # https://github.com/PixArt-alpha/PixArt-alpha/blob/0f55e922376d8b797edd44d25d0e7464b260dcab/diffusion/model/nets/PixArtMS.py#L70C1-L76C103
+ norm_hidden_states = hidden_states
+ else:
+ raise ValueError("Incorrect norm")
+
+ if self.pos_embed is not None and self.use_ada_layer_norm_single is False:
+ norm_hidden_states = self.pos_embed(norm_hidden_states)
+
+ attn_output = self.attn2(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=encoder_attention_mask,
+ **cross_attention_kwargs,
+ )
+ hidden_states = attn_output + hidden_states
+
+ # 4. Feed-forward
+ if not self.use_ada_layer_norm_single:
+ norm_hidden_states = self.norm3(hidden_states)
+
+ if self.use_ada_layer_norm_zero:
+ norm_hidden_states = (
+ norm_hidden_states *
+ (1 + scale_mlp[:, None]) + shift_mlp[:, None]
+ )
+
+ if self.use_ada_layer_norm_single:
+ norm_hidden_states = self.norm2(hidden_states)
+ norm_hidden_states = norm_hidden_states * \
+ (1 + scale_mlp) + shift_mlp
+
+ ff_output = self.ff(norm_hidden_states, scale=lora_scale)
+
+ if self.use_ada_layer_norm_zero:
+ ff_output = gate_mlp.unsqueeze(1) * ff_output
+ elif self.use_ada_layer_norm_single:
+ ff_output = gate_mlp * ff_output
+
+ hidden_states = ff_output + hidden_states
+ if hidden_states.ndim == 4:
+ hidden_states = hidden_states.squeeze(1)
+
+ return hidden_states
+
+
+class TemporalBasicTransformerBlock(nn.Module):
+ """
+ A PyTorch module that extends the BasicTransformerBlock to include temporal attention mechanisms.
+ This class is particularly useful for video-related tasks where capturing temporal information within the sequence of frames is necessary.
+
+ Attributes:
+ dim (int): The dimension of the input and output embeddings.
+ num_attention_heads (int): The number of attention heads in the multi-head self-attention mechanism.
+ attention_head_dim (int): The dimension of each attention head.
+ dropout (float): The dropout probability for the attention scores.
+ cross_attention_dim (Optional[int]): The dimension of the cross-attention mechanism.
+ activation_fn (str): The activation function used in the feed-forward layer.
+ num_embeds_ada_norm (Optional[int]): The number of embeddings for adaptive normalization.
+ attention_bias (bool): If True, uses bias in the attention mechanism.
+ only_cross_attention (bool): If True, only uses cross-attention.
+ upcast_attention (bool): If True, upcasts the attention mechanism for better performance.
+ unet_use_cross_frame_attention (Optional[bool]): If True, uses cross-frame attention in the UNet model.
+ unet_use_temporal_attention (Optional[bool]): If True, uses temporal attention in the UNet model.
+ """
+ def __init__(
+ self,
+ dim: int,
+ num_attention_heads: int,
+ attention_head_dim: int,
+ dropout=0.0,
+ cross_attention_dim: Optional[int] = None,
+ activation_fn: str = "geglu",
+ num_embeds_ada_norm: Optional[int] = None,
+ attention_bias: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ ):
+ """
+ The TemporalBasicTransformerBlock class is a PyTorch module that extends the BasicTransformerBlock to include temporal attention mechanisms.
+ This is particularly useful for video-related tasks, where the model needs to capture the temporal information within the sequence of frames.
+ The block consists of self-attention, cross-attention, feed-forward, and temporal attention mechanisms.
+
+ dim (int): The dimension of the input and output embeddings.
+ num_attention_heads (int): The number of attention heads in the multi-head self-attention mechanism.
+ attention_head_dim (int): The dimension of each attention head.
+ dropout (float, optional): The dropout probability for the attention scores. Defaults to 0.0.
+ cross_attention_dim (int, optional): The dimension of the cross-attention mechanism. Defaults to None.
+ activation_fn (str, optional): The activation function used in the feed-forward layer. Defaults to "geglu".
+ num_embeds_ada_norm (int, optional): The number of embeddings for adaptive normalization. Defaults to None.
+ attention_bias (bool, optional): If True, uses bias in the attention mechanism. Defaults to False.
+ only_cross_attention (bool, optional): If True, only uses cross-attention. Defaults to False.
+ upcast_attention (bool, optional): If True, upcasts the attention mechanism for better performance. Defaults to False.
+ unet_use_cross_frame_attention (bool, optional): If True, uses cross-frame attention in the UNet model. Defaults to None.
+ unet_use_temporal_attention (bool, optional): If True, uses temporal attention in the UNet model. Defaults to None.
+
+ Forward method:
+ hidden_states (torch.FloatTensor): The input hidden states.
+ encoder_hidden_states (torch.FloatTensor, optional): The encoder hidden states. Defaults to None.
+ timestep (torch.LongTensor, optional): The current timestep for the transformer model. Defaults to None.
+ attention_mask (torch.FloatTensor, optional): The attention mask for the self-attention mechanism. Defaults to None.
+ video_length (int, optional): The length of the video sequence. Defaults to None.
+
+ Returns:
+ torch.FloatTensor: The output hidden states after passing through the TemporalBasicTransformerBlock.
+ """
+ super().__init__()
+ self.only_cross_attention = only_cross_attention
+ self.use_ada_layer_norm = num_embeds_ada_norm is not None
+ self.unet_use_cross_frame_attention = unet_use_cross_frame_attention
+ self.unet_use_temporal_attention = unet_use_temporal_attention
+
+ # SC-Attn
+ self.attn1 = Attention(
+ query_dim=dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.norm1 = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(dim)
+ )
+
+ # Cross-Attn
+ if cross_attention_dim is not None:
+ self.attn2 = Attention(
+ query_dim=dim,
+ cross_attention_dim=cross_attention_dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ else:
+ self.attn2 = None
+
+ if cross_attention_dim is not None:
+ self.norm2 = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(dim)
+ )
+ else:
+ self.norm2 = None
+
+ # Feed-forward
+ self.ff = FeedForward(dim, dropout=dropout,
+ activation_fn=activation_fn)
+ self.norm3 = nn.LayerNorm(dim)
+ self.use_ada_layer_norm_zero = False
+
+ # Temp-Attn
+ # assert unet_use_temporal_attention is not None
+ if unet_use_temporal_attention is None:
+ unet_use_temporal_attention = False
+ if unet_use_temporal_attention:
+ self.attn_temp = Attention(
+ query_dim=dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ nn.init.zeros_(self.attn_temp.to_out[0].weight.data)
+ self.norm_temp = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(dim)
+ )
+
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ timestep=None,
+ attention_mask=None,
+ video_length=None,
+ ):
+ """
+ Forward pass for the TemporalBasicTransformerBlock.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input hidden states with shape (batch_size, seq_len, dim).
+ encoder_hidden_states (torch.FloatTensor, optional): The encoder hidden states with shape (batch_size, src_seq_len, dim).
+ timestep (torch.LongTensor, optional): The timestep for the transformer block.
+ attention_mask (torch.FloatTensor, optional): The attention mask with shape (batch_size, seq_len, seq_len).
+ video_length (int, optional): The length of the video sequence.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the transformer block with shape (batch_size, seq_len, dim).
+ """
+ norm_hidden_states = (
+ self.norm1(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm1(hidden_states)
+ )
+
+ if self.unet_use_cross_frame_attention:
+ hidden_states = (
+ self.attn1(
+ norm_hidden_states,
+ attention_mask=attention_mask,
+ video_length=video_length,
+ )
+ + hidden_states
+ )
+ else:
+ hidden_states = (
+ self.attn1(norm_hidden_states, attention_mask=attention_mask)
+ + hidden_states
+ )
+
+ if self.attn2 is not None:
+ # Cross-Attention
+ norm_hidden_states = (
+ self.norm2(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm2(hidden_states)
+ )
+ hidden_states = (
+ self.attn2(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ )
+ + hidden_states
+ )
+
+ # Feed-forward
+ hidden_states = self.ff(self.norm3(hidden_states)) + hidden_states
+
+ # Temporal-Attention
+ if self.unet_use_temporal_attention:
+ d = hidden_states.shape[1]
+ hidden_states = rearrange(
+ hidden_states, "(b f) d c -> (b d) f c", f=video_length
+ )
+ norm_hidden_states = (
+ self.norm_temp(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm_temp(hidden_states)
+ )
+ hidden_states = self.attn_temp(norm_hidden_states) + hidden_states
+ hidden_states = rearrange(
+ hidden_states, "(b d) f c -> (b f) d c", d=d)
+
+ return hidden_states
+
+
+class AudioTemporalBasicTransformerBlock(nn.Module):
+ """
+ A PyTorch module designed to handle audio data within a transformer framework, including temporal attention mechanisms.
+
+ Attributes:
+ dim (int): The dimension of the input and output embeddings.
+ num_attention_heads (int): The number of attention heads.
+ attention_head_dim (int): The dimension of each attention head.
+ dropout (float): The dropout probability.
+ cross_attention_dim (Optional[int]): The dimension of the cross-attention mechanism.
+ activation_fn (str): The activation function for the feed-forward network.
+ num_embeds_ada_norm (Optional[int]): The number of embeddings for adaptive normalization.
+ attention_bias (bool): If True, uses bias in the attention mechanism.
+ only_cross_attention (bool): If True, only uses cross-attention.
+ upcast_attention (bool): If True, upcasts the attention mechanism to float32.
+ unet_use_cross_frame_attention (Optional[bool]): If True, uses cross-frame attention in UNet.
+ unet_use_temporal_attention (Optional[bool]): If True, uses temporal attention in UNet.
+ depth (int): The depth of the transformer block.
+ unet_block_name (Optional[str]): The name of the UNet block.
+ stack_enable_blocks_name (Optional[List[str]]): The list of enabled blocks in the stack.
+ stack_enable_blocks_depth (Optional[List[int]]): The list of depths for the enabled blocks in the stack.
+ """
+ def __init__(
+ self,
+ dim: int,
+ num_attention_heads: int,
+ attention_head_dim: int,
+ dropout=0.0,
+ cross_attention_dim: Optional[int] = None,
+ activation_fn: str = "geglu",
+ num_embeds_ada_norm: Optional[int] = None,
+ attention_bias: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ depth=0,
+ unet_block_name=None,
+ stack_enable_blocks_name: Optional[List[str]] = None,
+ stack_enable_blocks_depth: Optional[List[int]] = None,
+ ):
+ """
+ Initializes the AudioTemporalBasicTransformerBlock module.
+
+ Args:
+ dim (int): The dimension of the input and output embeddings.
+ num_attention_heads (int): The number of attention heads in the multi-head self-attention mechanism.
+ attention_head_dim (int): The dimension of each attention head.
+ dropout (float, optional): The dropout probability for the attention mechanism. Defaults to 0.0.
+ cross_attention_dim (Optional[int], optional): The dimension of the cross-attention mechanism. Defaults to None.
+ activation_fn (str, optional): The activation function to be used in the feed-forward network. Defaults to "geglu".
+ num_embeds_ada_norm (Optional[int], optional): The number of embeddings for adaptive normalization. Defaults to None.
+ attention_bias (bool, optional): If True, uses bias in the attention mechanism. Defaults to False.
+ only_cross_attention (bool, optional): If True, only uses cross-attention. Defaults to False.
+ upcast_attention (bool, optional): If True, upcasts the attention mechanism to float32. Defaults to False.
+ unet_use_cross_frame_attention (Optional[bool], optional): If True, uses cross-frame attention in UNet. Defaults to None.
+ unet_use_temporal_attention (Optional[bool], optional): If True, uses temporal attention in UNet. Defaults to None.
+ depth (int, optional): The depth of the transformer block. Defaults to 0.
+ unet_block_name (Optional[str], optional): The name of the UNet block. Defaults to None.
+ stack_enable_blocks_name (Optional[List[str]], optional): The list of enabled blocks in the stack. Defaults to None.
+ stack_enable_blocks_depth (Optional[List[int]], optional): The list of depths for the enabled blocks in the stack. Defaults to None.
+ """
+ super().__init__()
+ self.only_cross_attention = only_cross_attention
+ self.use_ada_layer_norm = num_embeds_ada_norm is not None
+ self.unet_use_cross_frame_attention = unet_use_cross_frame_attention
+ self.unet_use_temporal_attention = unet_use_temporal_attention
+ self.unet_block_name = unet_block_name
+ self.depth = depth
+
+ zero_conv_full = nn.Conv2d(
+ dim, dim, kernel_size=1)
+ self.zero_conv_full = zero_module(zero_conv_full)
+
+ zero_conv_face = nn.Conv2d(
+ dim, dim, kernel_size=1)
+ self.zero_conv_face = zero_module(zero_conv_face)
+
+ zero_conv_lip = nn.Conv2d(
+ dim, dim, kernel_size=1)
+ self.zero_conv_lip = zero_module(zero_conv_lip)
+ # SC-Attn
+ self.attn1 = Attention(
+ query_dim=dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.norm1 = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(dim)
+ )
+
+ # Cross-Attn
+ if cross_attention_dim is not None:
+ if (stack_enable_blocks_name is not None and
+ stack_enable_blocks_depth is not None and
+ self.unet_block_name in stack_enable_blocks_name and
+ self.depth in stack_enable_blocks_depth):
+ self.attn2_0 = Attention(
+ query_dim=dim,
+ cross_attention_dim=cross_attention_dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.attn2_1 = Attention(
+ query_dim=dim,
+ cross_attention_dim=cross_attention_dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.attn2_2 = Attention(
+ query_dim=dim,
+ cross_attention_dim=cross_attention_dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.attn2 = None
+
+ else:
+ self.attn2 = Attention(
+ query_dim=dim,
+ cross_attention_dim=cross_attention_dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ )
+ self.attn2_0=None
+ else:
+ self.attn2 = None
+ self.attn2_0 = None
+
+ if cross_attention_dim is not None:
+ self.norm2 = (
+ AdaLayerNorm(dim, num_embeds_ada_norm)
+ if self.use_ada_layer_norm
+ else nn.LayerNorm(dim)
+ )
+ else:
+ self.norm2 = None
+
+ # Feed-forward
+ self.ff = FeedForward(dim, dropout=dropout,
+ activation_fn=activation_fn)
+ self.norm3 = nn.LayerNorm(dim)
+ self.use_ada_layer_norm_zero = False
+
+
+
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ timestep=None,
+ attention_mask=None,
+ full_mask=None,
+ face_mask=None,
+ lip_mask=None,
+ motion_scale=None,
+ video_length=None,
+ ):
+ """
+ Forward pass for the AudioTemporalBasicTransformerBlock.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input hidden states.
+ encoder_hidden_states (torch.FloatTensor, optional): The encoder hidden states. Defaults to None.
+ timestep (torch.LongTensor, optional): The timestep for the transformer block. Defaults to None.
+ attention_mask (torch.FloatTensor, optional): The attention mask. Defaults to None.
+ full_mask (torch.FloatTensor, optional): The full mask. Defaults to None.
+ face_mask (torch.FloatTensor, optional): The face mask. Defaults to None.
+ lip_mask (torch.FloatTensor, optional): The lip mask. Defaults to None.
+ video_length (int, optional): The length of the video. Defaults to None.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the AudioTemporalBasicTransformerBlock.
+ """
+ norm_hidden_states = (
+ self.norm1(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm1(hidden_states)
+ )
+
+ if self.unet_use_cross_frame_attention:
+ hidden_states = (
+ self.attn1(
+ norm_hidden_states,
+ attention_mask=attention_mask,
+ video_length=video_length,
+ )
+ + hidden_states
+ )
+ else:
+ hidden_states = (
+ self.attn1(norm_hidden_states, attention_mask=attention_mask)
+ + hidden_states
+ )
+
+ if self.attn2 is not None:
+ # Cross-Attention
+ norm_hidden_states = (
+ self.norm2(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm2(hidden_states)
+ )
+ hidden_states = self.attn2(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ ) + hidden_states
+
+ elif self.attn2_0 is not None:
+ norm_hidden_states = (
+ self.norm2(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm2(hidden_states)
+ )
+
+ level = self.depth
+ full_hidden_states = (
+ self.attn2_0(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ ) * full_mask[level][:, :, None]
+ )
+ bz, sz, c = full_hidden_states.shape
+ sz_sqrt = int(sz ** 0.5)
+ full_hidden_states = full_hidden_states.reshape(
+ bz, sz_sqrt, sz_sqrt, c).permute(0, 3, 1, 2)
+ full_hidden_states = self.zero_conv_full(full_hidden_states).permute(0, 2, 3, 1).reshape(bz, -1, c)
+
+ face_hidden_state = (
+ self.attn2_1(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ ) * face_mask[level][:, :, None]
+ )
+ face_hidden_state = face_hidden_state.reshape(
+ bz, sz_sqrt, sz_sqrt, c).permute(0, 3, 1, 2)
+ face_hidden_state = self.zero_conv_face(
+ face_hidden_state).permute(0, 2, 3, 1).reshape(bz, -1, c)
+
+ lip_hidden_state = (
+ self.attn2_2(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ ) * lip_mask[level][:, :, None]
+
+ ) # [32, 4096, 320]
+ lip_hidden_state = lip_hidden_state.reshape(
+ bz, sz_sqrt, sz_sqrt, c).permute(0, 3, 1, 2)
+ lip_hidden_state = self.zero_conv_lip(
+ lip_hidden_state).permute(0, 2, 3, 1).reshape(bz, -1, c)
+
+ if motion_scale is not None:
+ hidden_states = (
+ motion_scale[0] * full_hidden_states +
+ motion_scale[1] * face_hidden_state +
+ motion_scale[2] * lip_hidden_state + hidden_states
+ )
+ else:
+ hidden_states = (
+ full_hidden_states +
+ face_hidden_state +
+ lip_hidden_state + hidden_states
+ )
+ # Feed-forward
+ hidden_states = self.ff(self.norm3(hidden_states)) + hidden_states
+
+ return hidden_states
+
+def zero_module(module):
+ """
+ Zeroes out the parameters of a given module.
+
+ Args:
+ module (nn.Module): The module whose parameters need to be zeroed out.
+
+ Returns:
+ None.
+ """
+ for p in module.parameters():
+ nn.init.zeros_(p)
+ return module
diff --git a/animation/hallo-83dd4eb/hallo/models/audio_proj.py b/animation/hallo-83dd4eb/hallo/models/audio_proj.py
new file mode 100644
index 0000000..9edf7d2
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/audio_proj.py
@@ -0,0 +1,124 @@
+"""
+This module provides the implementation of an Audio Projection Model, which is designed for
+audio processing tasks. The model takes audio embeddings as input and outputs context tokens
+that can be used for various downstream applications, such as audio analysis or synthesis.
+
+The AudioProjModel class is based on the ModelMixin class from the diffusers library, which
+provides a foundation for building custom models. This implementation includes multiple linear
+layers with ReLU activation functions and a LayerNorm for normalization.
+
+Key Features:
+- Audio embedding input with flexible sequence length and block structure.
+- Multiple linear layers for feature transformation.
+- ReLU activation for non-linear transformation.
+- LayerNorm for stabilizing and speeding up training.
+- Rearrangement of input embeddings to match the model's expected input shape.
+- Customizable number of blocks, channels, and context tokens for adaptability.
+
+The module is structured to be easily integrated into larger systems or used as a standalone
+component for audio feature extraction and processing.
+
+Classes:
+- AudioProjModel: A class representing the audio projection model with configurable parameters.
+
+Functions:
+- (none)
+
+Dependencies:
+- torch: For tensor operations and neural network components.
+- diffusers: For the ModelMixin base class.
+- einops: For tensor rearrangement operations.
+
+"""
+
+import torch
+from diffusers import ModelMixin
+from einops import rearrange
+from torch import nn
+
+
+class AudioProjModel(ModelMixin):
+ """Audio Projection Model
+
+ This class defines an audio projection model that takes audio embeddings as input
+ and produces context tokens as output. The model is based on the ModelMixin class
+ and consists of multiple linear layers and activation functions. It can be used
+ for various audio processing tasks.
+
+ Attributes:
+ seq_len (int): The length of the audio sequence.
+ blocks (int): The number of blocks in the audio projection model.
+ channels (int): The number of channels in the audio projection model.
+ intermediate_dim (int): The intermediate dimension of the model.
+ context_tokens (int): The number of context tokens in the output.
+ output_dim (int): The output dimension of the context tokens.
+
+ Methods:
+ __init__(self, seq_len=5, blocks=12, channels=768, intermediate_dim=512, context_tokens=32, output_dim=768):
+ Initializes the AudioProjModel with the given parameters.
+ forward(self, audio_embeds):
+ Defines the forward pass for the AudioProjModel.
+ Parameters:
+ audio_embeds (torch.Tensor): The input audio embeddings with shape (batch_size, video_length, blocks, channels).
+ Returns:
+ context_tokens (torch.Tensor): The output context tokens with shape (batch_size, video_length, context_tokens, output_dim).
+
+ """
+
+ def __init__(
+ self,
+ seq_len=5,
+ blocks=12, # add a new parameter blocks
+ channels=768, # add a new parameter channels
+ intermediate_dim=512,
+ output_dim=768,
+ context_tokens=32,
+ ):
+ super().__init__()
+
+ self.seq_len = seq_len
+ self.blocks = blocks
+ self.channels = channels
+ self.input_dim = (
+ seq_len * blocks * channels
+ ) # update input_dim to be the product of blocks and channels.
+ self.intermediate_dim = intermediate_dim
+ self.context_tokens = context_tokens
+ self.output_dim = output_dim
+
+ # define multiple linear layers
+ self.proj1 = nn.Linear(self.input_dim, intermediate_dim)
+ self.proj2 = nn.Linear(intermediate_dim, intermediate_dim)
+ self.proj3 = nn.Linear(intermediate_dim, context_tokens * output_dim)
+
+ self.norm = nn.LayerNorm(output_dim)
+
+ def forward(self, audio_embeds):
+ """
+ Defines the forward pass for the AudioProjModel.
+
+ Parameters:
+ audio_embeds (torch.Tensor): The input audio embeddings with shape (batch_size, video_length, blocks, channels).
+
+ Returns:
+ context_tokens (torch.Tensor): The output context tokens with shape (batch_size, video_length, context_tokens, output_dim).
+ """
+ # merge
+ video_length = audio_embeds.shape[1]
+ audio_embeds = rearrange(audio_embeds, "bz f w b c -> (bz f) w b c")
+ batch_size, window_size, blocks, channels = audio_embeds.shape
+ audio_embeds = audio_embeds.view(batch_size, window_size * blocks * channels)
+
+ audio_embeds = torch.relu(self.proj1(audio_embeds))
+ audio_embeds = torch.relu(self.proj2(audio_embeds))
+
+ context_tokens = self.proj3(audio_embeds).reshape(
+ batch_size, self.context_tokens, self.output_dim
+ )
+
+ context_tokens = self.norm(context_tokens)
+ context_tokens = rearrange(
+ context_tokens, "(bz f) m c -> bz f m c", f=video_length
+ )
+
+ return context_tokens
diff --git a/animation/hallo-83dd4eb/hallo/models/face_locator.py b/animation/hallo-83dd4eb/hallo/models/face_locator.py
new file mode 100644
index 0000000..f138744
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/face_locator.py
@@ -0,0 +1,113 @@
+"""
+This module implements the FaceLocator class, which is a neural network model designed to
+locate and extract facial features from input images or tensors. It uses a series of
+convolutional layers to progressively downsample and refine the facial feature map.
+
+The FaceLocator class is part of a larger system that may involve facial recognition or
+similar tasks where precise location and extraction of facial features are required.
+
+Attributes:
+ conditioning_embedding_channels (int): The number of channels in the output embedding.
+ conditioning_channels (int): The number of input channels for the conditioning tensor.
+ block_out_channels (Tuple[int]): A tuple of integers representing the output channels
+ for each block in the model.
+
+The model uses the following components:
+- InflatedConv3d: A convolutional layer that inflates the input to increase the depth.
+- zero_module: A utility function that may set certain parameters to zero for regularization
+ or other purposes.
+
+The forward method of the FaceLocator class takes a conditioning tensor as input and
+produces an embedding tensor as output, which can be used for further processing or analysis.
+"""
+
+from typing import Tuple
+
+import torch.nn.functional as F
+from diffusers.models.modeling_utils import ModelMixin
+from torch import nn
+
+from .motion_module import zero_module
+from .resnet import InflatedConv3d
+
+
+class FaceLocator(ModelMixin):
+ """
+ The FaceLocator class is a neural network model designed to process and extract facial
+ features from an input tensor. It consists of a series of convolutional layers that
+ progressively downsample the input while increasing the depth of the feature map.
+
+ The model is built using InflatedConv3d layers, which are designed to inflate the
+ feature channels, allowing for more complex feature extraction. The final output is a
+ conditioning embedding that can be used for various tasks such as facial recognition or
+ feature-based image manipulation.
+
+ Parameters:
+ conditioning_embedding_channels (int): The number of channels in the output embedding.
+ conditioning_channels (int, optional): The number of input channels for the conditioning tensor. Default is 3.
+ block_out_channels (Tuple[int], optional): A tuple of integers representing the output channels
+ for each block in the model. The default is (16, 32, 64, 128), which defines the
+ progression of the network's depth.
+
+ Attributes:
+ conv_in (InflatedConv3d): The initial convolutional layer that starts the feature extraction process.
+ blocks (ModuleList[InflatedConv3d]): A list of convolutional layers that form the core of the model.
+ conv_out (InflatedConv3d): The final convolutional layer that produces the output embedding.
+
+ The forward method applies the convolutional layers to the input conditioning tensor and
+ returns the resulting embedding tensor.
+ """
+ def __init__(
+ self,
+ conditioning_embedding_channels: int,
+ conditioning_channels: int = 3,
+ block_out_channels: Tuple[int] = (16, 32, 64, 128),
+ ):
+ super().__init__()
+ self.conv_in = InflatedConv3d(
+ conditioning_channels, block_out_channels[0], kernel_size=3, padding=1
+ )
+
+ self.blocks = nn.ModuleList([])
+
+ for i in range(len(block_out_channels) - 1):
+ channel_in = block_out_channels[i]
+ channel_out = block_out_channels[i + 1]
+ self.blocks.append(
+ InflatedConv3d(channel_in, channel_in, kernel_size=3, padding=1)
+ )
+ self.blocks.append(
+ InflatedConv3d(
+ channel_in, channel_out, kernel_size=3, padding=1, stride=2
+ )
+ )
+
+ self.conv_out = zero_module(
+ InflatedConv3d(
+ block_out_channels[-1],
+ conditioning_embedding_channels,
+ kernel_size=3,
+ padding=1,
+ )
+ )
+
+ def forward(self, conditioning):
+ """
+ Forward pass of the FaceLocator model.
+
+ Args:
+ conditioning (Tensor): The input conditioning tensor.
+
+ Returns:
+ Tensor: The output embedding tensor.
+ """
+ embedding = self.conv_in(conditioning)
+ embedding = F.silu(embedding)
+
+ for block in self.blocks:
+ embedding = block(embedding)
+ embedding = F.silu(embedding)
+
+ embedding = self.conv_out(embedding)
+
+ return embedding
diff --git a/animation/hallo-83dd4eb/hallo/models/image_proj.py b/animation/hallo-83dd4eb/hallo/models/image_proj.py
new file mode 100644
index 0000000..d6522e0
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/image_proj.py
@@ -0,0 +1,76 @@
+"""
+image_proj_model.py
+
+This module defines the ImageProjModel class, which is responsible for
+projecting image embeddings into a different dimensional space. The model
+leverages a linear transformation followed by a layer normalization to
+reshape and normalize the input image embeddings for further processing in
+cross-attention mechanisms or other downstream tasks.
+
+Classes:
+ ImageProjModel
+
+Dependencies:
+ torch
+ diffusers.ModelMixin
+
+"""
+
+import torch
+from diffusers import ModelMixin
+
+
+class ImageProjModel(ModelMixin):
+ """
+ ImageProjModel is a class that projects image embeddings into a different
+ dimensional space. It inherits from ModelMixin, providing additional functionalities
+ specific to image projection.
+
+ Attributes:
+ cross_attention_dim (int): The dimension of the cross attention.
+ clip_embeddings_dim (int): The dimension of the CLIP embeddings.
+ clip_extra_context_tokens (int): The number of extra context tokens in CLIP.
+
+ Methods:
+ forward(image_embeds): Forward pass of the ImageProjModel, which takes in image
+ embeddings and returns the projected tokens.
+
+ """
+
+ def __init__(
+ self,
+ cross_attention_dim=1024,
+ clip_embeddings_dim=1024,
+ clip_extra_context_tokens=4,
+ ):
+ super().__init__()
+
+ self.generator = None
+ self.cross_attention_dim = cross_attention_dim
+ self.clip_extra_context_tokens = clip_extra_context_tokens
+ self.proj = torch.nn.Linear(
+ clip_embeddings_dim, self.clip_extra_context_tokens * cross_attention_dim
+ )
+ self.norm = torch.nn.LayerNorm(cross_attention_dim)
+
+ def forward(self, image_embeds):
+ """
+ Forward pass of the ImageProjModel, which takes in image embeddings and returns the
+ projected tokens after reshaping and normalization.
+
+ Args:
+ image_embeds (torch.Tensor): The input image embeddings, with shape
+ batch_size x num_image_tokens x clip_embeddings_dim.
+
+ Returns:
+ clip_extra_context_tokens (torch.Tensor): The projected tokens after reshaping
+ and normalization, with shape batch_size x (clip_extra_context_tokens *
+ cross_attention_dim).
+
+ """
+ embeds = image_embeds
+ clip_extra_context_tokens = self.proj(embeds).reshape(
+ -1, self.clip_extra_context_tokens, self.cross_attention_dim
+ )
+ clip_extra_context_tokens = self.norm(clip_extra_context_tokens)
+ return clip_extra_context_tokens
diff --git a/animation/hallo-83dd4eb/hallo/models/motion_module.py b/animation/hallo-83dd4eb/hallo/models/motion_module.py
new file mode 100644
index 0000000..f62877d
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/motion_module.py
@@ -0,0 +1,609 @@
+# pylint: disable=R0801
+# pylint: disable=W0613
+# pylint: disable=W0221
+
+"""
+temporal_transformers.py
+
+This module provides classes and functions for implementing Temporal Transformers
+in PyTorch, designed for handling video data and temporal sequences within transformer-based models.
+
+Functions:
+ zero_module(module)
+ Zero out the parameters of a module and return it.
+
+Classes:
+ TemporalTransformer3DModelOutput(BaseOutput)
+ Dataclass for storing the output of TemporalTransformer3DModel.
+
+ VanillaTemporalModule(nn.Module)
+ A Vanilla Temporal Module class for handling temporal data.
+
+ TemporalTransformer3DModel(nn.Module)
+ A Temporal Transformer 3D Model class for transforming temporal data.
+
+ TemporalTransformerBlock(nn.Module)
+ A Temporal Transformer Block class for building the transformer architecture.
+
+ PositionalEncoding(nn.Module)
+ A Positional Encoding module for transformers to encode positional information.
+
+Dependencies:
+ math
+ dataclasses.dataclass
+ typing (Callable, Optional)
+ torch
+ diffusers (FeedForward, Attention, AttnProcessor)
+ diffusers.utils (BaseOutput)
+ diffusers.utils.import_utils (is_xformers_available)
+ einops (rearrange, repeat)
+ torch.nn
+ xformers
+ xformers.ops
+
+Example Usage:
+ >>> motion_module = get_motion_module(in_channels=512, motion_module_type="Vanilla", motion_module_kwargs={})
+ >>> output = motion_module(input_tensor, temb, encoder_hidden_states)
+
+This module is designed to facilitate the creation, training, and inference of transformer models
+that operate on temporal data, such as videos or time-series. It includes mechanisms for applying temporal attention,
+managing positional encoding, and integrating with external libraries for efficient attention operations.
+"""
+
+# This code is copied from https://github.com/guoyww/AnimateDiff.
+
+import math
+
+import torch
+import xformers
+import xformers.ops
+from diffusers.models.attention import FeedForward
+from diffusers.models.attention_processor import Attention, AttnProcessor
+from diffusers.utils import BaseOutput
+from diffusers.utils.import_utils import is_xformers_available
+from einops import rearrange, repeat
+from torch import nn
+
+
+def zero_module(module):
+ """
+ Zero out the parameters of a module and return it.
+
+ Args:
+ - module: A PyTorch module to zero out its parameters.
+
+ Returns:
+ A zeroed out PyTorch module.
+ """
+ for p in module.parameters():
+ p.detach().zero_()
+ return module
+
+
+class TemporalTransformer3DModelOutput(BaseOutput):
+ """
+ Output class for the TemporalTransformer3DModel.
+
+ Attributes:
+ sample (torch.FloatTensor): The output sample tensor from the model.
+ """
+ sample: torch.FloatTensor
+
+ def get_sample_shape(self):
+ """
+ Returns the shape of the sample tensor.
+
+ Returns:
+ Tuple: The shape of the sample tensor.
+ """
+ return self.sample.shape
+
+
+def get_motion_module(in_channels, motion_module_type: str, motion_module_kwargs: dict):
+ """
+ This function returns a motion module based on the given type and parameters.
+
+ Args:
+ - in_channels (int): The number of input channels for the motion module.
+ - motion_module_type (str): The type of motion module to create. Currently, only "Vanilla" is supported.
+ - motion_module_kwargs (dict): Additional keyword arguments to pass to the motion module constructor.
+
+ Returns:
+ VanillaTemporalModule: The created motion module.
+
+ Raises:
+ ValueError: If an unsupported motion_module_type is provided.
+ """
+ if motion_module_type == "Vanilla":
+ return VanillaTemporalModule(
+ in_channels=in_channels,
+ **motion_module_kwargs,
+ )
+
+ raise ValueError
+
+
+class VanillaTemporalModule(nn.Module):
+ """
+ A Vanilla Temporal Module class.
+
+ Args:
+ - in_channels (int): The number of input channels for the motion module.
+ - num_attention_heads (int): Number of attention heads.
+ - num_transformer_block (int): Number of transformer blocks.
+ - attention_block_types (tuple): Types of attention blocks.
+ - cross_frame_attention_mode: Mode for cross-frame attention.
+ - temporal_position_encoding (bool): Flag for temporal position encoding.
+ - temporal_position_encoding_max_len (int): Maximum length for temporal position encoding.
+ - temporal_attention_dim_div (int): Divisor for temporal attention dimension.
+ - zero_initialize (bool): Flag for zero initialization.
+ """
+
+ def __init__(
+ self,
+ in_channels,
+ num_attention_heads=8,
+ num_transformer_block=2,
+ attention_block_types=("Temporal_Self", "Temporal_Self"),
+ cross_frame_attention_mode=None,
+ temporal_position_encoding=False,
+ temporal_position_encoding_max_len=24,
+ temporal_attention_dim_div=1,
+ zero_initialize=True,
+ ):
+ super().__init__()
+
+ self.temporal_transformer = TemporalTransformer3DModel(
+ in_channels=in_channels,
+ num_attention_heads=num_attention_heads,
+ attention_head_dim=in_channels
+ // num_attention_heads
+ // temporal_attention_dim_div,
+ num_layers=num_transformer_block,
+ attention_block_types=attention_block_types,
+ cross_frame_attention_mode=cross_frame_attention_mode,
+ temporal_position_encoding=temporal_position_encoding,
+ temporal_position_encoding_max_len=temporal_position_encoding_max_len,
+ )
+
+ if zero_initialize:
+ self.temporal_transformer.proj_out = zero_module(
+ self.temporal_transformer.proj_out
+ )
+
+ def forward(
+ self,
+ input_tensor,
+ encoder_hidden_states,
+ attention_mask=None,
+ ):
+ """
+ Forward pass of the TemporalTransformer3DModel.
+
+ Args:
+ hidden_states (torch.Tensor): The hidden states of the model.
+ encoder_hidden_states (torch.Tensor, optional): The hidden states of the encoder.
+ attention_mask (torch.Tensor, optional): The attention mask.
+
+ Returns:
+ torch.Tensor: The output tensor after the forward pass.
+ """
+ hidden_states = input_tensor
+ hidden_states = self.temporal_transformer(
+ hidden_states, encoder_hidden_states
+ )
+
+ output = hidden_states
+ return output
+
+
+class TemporalTransformer3DModel(nn.Module):
+ """
+ A Temporal Transformer 3D Model class.
+
+ Args:
+ - in_channels (int): The number of input channels.
+ - num_attention_heads (int): Number of attention heads.
+ - attention_head_dim (int): Dimension of attention heads.
+ - num_layers (int): Number of transformer layers.
+ - attention_block_types (tuple): Types of attention blocks.
+ - dropout (float): Dropout rate.
+ - norm_num_groups (int): Number of groups for normalization.
+ - cross_attention_dim (int): Dimension for cross-attention.
+ - activation_fn (str): Activation function.
+ - attention_bias (bool): Flag for attention bias.
+ - upcast_attention (bool): Flag for upcast attention.
+ - cross_frame_attention_mode: Mode for cross-frame attention.
+ - temporal_position_encoding (bool): Flag for temporal position encoding.
+ - temporal_position_encoding_max_len (int): Maximum length for temporal position encoding.
+ """
+ def __init__(
+ self,
+ in_channels,
+ num_attention_heads,
+ attention_head_dim,
+ num_layers,
+ attention_block_types=(
+ "Temporal_Self",
+ "Temporal_Self",
+ ),
+ dropout=0.0,
+ norm_num_groups=32,
+ cross_attention_dim=768,
+ activation_fn="geglu",
+ attention_bias=False,
+ upcast_attention=False,
+ cross_frame_attention_mode=None,
+ temporal_position_encoding=False,
+ temporal_position_encoding_max_len=24,
+ ):
+ super().__init__()
+
+ inner_dim = num_attention_heads * attention_head_dim
+
+ self.norm = torch.nn.GroupNorm(
+ num_groups=norm_num_groups, num_channels=in_channels, eps=1e-6, affine=True
+ )
+ self.proj_in = nn.Linear(in_channels, inner_dim)
+
+ self.transformer_blocks = nn.ModuleList(
+ [
+ TemporalTransformerBlock(
+ dim=inner_dim,
+ num_attention_heads=num_attention_heads,
+ attention_head_dim=attention_head_dim,
+ attention_block_types=attention_block_types,
+ dropout=dropout,
+ cross_attention_dim=cross_attention_dim,
+ activation_fn=activation_fn,
+ attention_bias=attention_bias,
+ upcast_attention=upcast_attention,
+ cross_frame_attention_mode=cross_frame_attention_mode,
+ temporal_position_encoding=temporal_position_encoding,
+ temporal_position_encoding_max_len=temporal_position_encoding_max_len,
+ )
+ for d in range(num_layers)
+ ]
+ )
+ self.proj_out = nn.Linear(inner_dim, in_channels)
+
+ def forward(self, hidden_states, encoder_hidden_states=None):
+ """
+ Forward pass for the TemporalTransformer3DModel.
+
+ Args:
+ hidden_states (torch.Tensor): The input hidden states with shape (batch_size, sequence_length, in_channels).
+ encoder_hidden_states (torch.Tensor, optional): The encoder hidden states with shape (batch_size, encoder_sequence_length, in_channels).
+
+ Returns:
+ torch.Tensor: The output hidden states with shape (batch_size, sequence_length, in_channels).
+ """
+ assert (
+ hidden_states.dim() == 5
+ ), f"Expected hidden_states to have ndim=5, but got ndim={hidden_states.dim()}."
+ video_length = hidden_states.shape[2]
+ hidden_states = rearrange(hidden_states, "b c f h w -> (b f) c h w")
+
+ batch, _, height, weight = hidden_states.shape
+ residual = hidden_states
+
+ hidden_states = self.norm(hidden_states)
+ inner_dim = hidden_states.shape[1]
+ hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(
+ batch, height * weight, inner_dim
+ )
+ hidden_states = self.proj_in(hidden_states)
+
+ # Transformer Blocks
+ for block in self.transformer_blocks:
+ hidden_states = block(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ video_length=video_length,
+ )
+
+ # output
+ hidden_states = self.proj_out(hidden_states)
+ hidden_states = (
+ hidden_states.reshape(batch, height, weight, inner_dim)
+ .permute(0, 3, 1, 2)
+ .contiguous()
+ )
+
+ output = hidden_states + residual
+ output = rearrange(output, "(b f) c h w -> b c f h w", f=video_length)
+
+ return output
+
+
+class TemporalTransformerBlock(nn.Module):
+ """
+ A Temporal Transformer Block class.
+
+ Args:
+ - dim (int): Dimension of the block.
+ - num_attention_heads (int): Number of attention heads.
+ - attention_head_dim (int): Dimension of attention heads.
+ - attention_block_types (tuple): Types of attention blocks.
+ - dropout (float): Dropout rate.
+ - cross_attention_dim (int): Dimension for cross-attention.
+ - activation_fn (str): Activation function.
+ - attention_bias (bool): Flag for attention bias.
+ - upcast_attention (bool): Flag for upcast attention.
+ - cross_frame_attention_mode: Mode for cross-frame attention.
+ - temporal_position_encoding (bool): Flag for temporal position encoding.
+ - temporal_position_encoding_max_len (int): Maximum length for temporal position encoding.
+ """
+ def __init__(
+ self,
+ dim,
+ num_attention_heads,
+ attention_head_dim,
+ attention_block_types=(
+ "Temporal_Self",
+ "Temporal_Self",
+ ),
+ dropout=0.0,
+ cross_attention_dim=768,
+ activation_fn="geglu",
+ attention_bias=False,
+ upcast_attention=False,
+ cross_frame_attention_mode=None,
+ temporal_position_encoding=False,
+ temporal_position_encoding_max_len=24,
+ ):
+ super().__init__()
+
+ attention_blocks = []
+ norms = []
+
+ for block_name in attention_block_types:
+ attention_blocks.append(
+ VersatileAttention(
+ attention_mode=block_name.split("_", maxsplit=1)[0],
+ cross_attention_dim=cross_attention_dim
+ if block_name.endswith("_Cross")
+ else None,
+ query_dim=dim,
+ heads=num_attention_heads,
+ dim_head=attention_head_dim,
+ dropout=dropout,
+ bias=attention_bias,
+ upcast_attention=upcast_attention,
+ cross_frame_attention_mode=cross_frame_attention_mode,
+ temporal_position_encoding=temporal_position_encoding,
+ temporal_position_encoding_max_len=temporal_position_encoding_max_len,
+ )
+ )
+ norms.append(nn.LayerNorm(dim))
+
+ self.attention_blocks = nn.ModuleList(attention_blocks)
+ self.norms = nn.ModuleList(norms)
+
+ self.ff = FeedForward(dim, dropout=dropout,
+ activation_fn=activation_fn)
+ self.ff_norm = nn.LayerNorm(dim)
+
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ video_length=None,
+ ):
+ """
+ Forward pass for the TemporalTransformerBlock.
+
+ Args:
+ hidden_states (torch.Tensor): The input hidden states with shape
+ (batch_size, video_length, in_channels).
+ encoder_hidden_states (torch.Tensor, optional): The encoder hidden states
+ with shape (batch_size, encoder_length, in_channels).
+ video_length (int, optional): The length of the video.
+
+ Returns:
+ torch.Tensor: The output hidden states with shape
+ (batch_size, video_length, in_channels).
+ """
+ for attention_block, norm in zip(self.attention_blocks, self.norms):
+ norm_hidden_states = norm(hidden_states)
+ hidden_states = (
+ attention_block(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states
+ if attention_block.is_cross_attention
+ else None,
+ video_length=video_length,
+ )
+ + hidden_states
+ )
+
+ hidden_states = self.ff(self.ff_norm(hidden_states)) + hidden_states
+
+ output = hidden_states
+ return output
+
+
+class PositionalEncoding(nn.Module):
+ """
+ Positional Encoding module for transformers.
+
+ Args:
+ - d_model (int): Model dimension.
+ - dropout (float): Dropout rate.
+ - max_len (int): Maximum length for positional encoding.
+ """
+ def __init__(self, d_model, dropout=0.0, max_len=24):
+ super().__init__()
+ self.dropout = nn.Dropout(p=dropout)
+ position = torch.arange(max_len).unsqueeze(1)
+ div_term = torch.exp(
+ torch.arange(0, d_model, 2) * (-math.log(10000.0) / d_model)
+ )
+ pe = torch.zeros(1, max_len, d_model)
+ pe[0, :, 0::2] = torch.sin(position * div_term)
+ pe[0, :, 1::2] = torch.cos(position * div_term)
+ self.register_buffer("pe", pe)
+
+ def forward(self, x):
+ """
+ Forward pass of the PositionalEncoding module.
+
+ This method takes an input tensor `x` and adds the positional encoding to it. The positional encoding is
+ generated based on the input tensor's shape and is added to the input tensor element-wise.
+
+ Args:
+ x (torch.Tensor): The input tensor to be positionally encoded.
+
+ Returns:
+ torch.Tensor: The positionally encoded tensor.
+ """
+ x = x + self.pe[:, : x.size(1)]
+ return self.dropout(x)
+
+
+class VersatileAttention(Attention):
+ """
+ Versatile Attention class.
+
+ Args:
+ - attention_mode: Attention mode.
+ - temporal_position_encoding (bool): Flag for temporal position encoding.
+ - temporal_position_encoding_max_len (int): Maximum length for temporal position encoding.
+ """
+ def __init__(
+ self,
+ *args,
+ attention_mode=None,
+ cross_frame_attention_mode=None,
+ temporal_position_encoding=False,
+ temporal_position_encoding_max_len=24,
+ **kwargs,
+ ):
+ super().__init__(*args, **kwargs)
+ assert attention_mode == "Temporal"
+
+ self.attention_mode = attention_mode
+ self.is_cross_attention = kwargs.get("cross_attention_dim") is not None
+
+ self.pos_encoder = (
+ PositionalEncoding(
+ kwargs["query_dim"],
+ dropout=0.0,
+ max_len=temporal_position_encoding_max_len,
+ )
+ if (temporal_position_encoding and attention_mode == "Temporal")
+ else None
+ )
+
+ def extra_repr(self):
+ """
+ Returns a string representation of the module with information about the attention mode and whether it is cross-attention.
+
+ Returns:
+ str: A string representation of the module.
+ """
+ return f"(Module Info) Attention_Mode: {self.attention_mode}, Is_Cross_Attention: {self.is_cross_attention}"
+
+ def set_use_memory_efficient_attention_xformers(
+ self,
+ use_memory_efficient_attention_xformers: bool,
+ attention_op = None,
+ ):
+ """
+ Sets the use of memory-efficient attention xformers for the VersatileAttention class.
+
+ Args:
+ use_memory_efficient_attention_xformers (bool): A boolean flag indicating whether to use memory-efficient attention xformers or not.
+
+ Returns:
+ None
+
+ """
+ if use_memory_efficient_attention_xformers:
+ if not is_xformers_available():
+ raise ModuleNotFoundError(
+ (
+ "Refer to https://github.com/facebookresearch/xformers for more information on how to install"
+ " xformers"
+ ),
+ name="xformers",
+ )
+
+ if not torch.cuda.is_available():
+ raise ValueError(
+ "torch.cuda.is_available() should be True but is False. xformers' memory efficient attention is"
+ " only available for GPU "
+ )
+
+ try:
+ # Make sure we can run the memory efficient attention
+ _ = xformers.ops.memory_efficient_attention(
+ torch.randn((1, 2, 40), device="cuda"),
+ torch.randn((1, 2, 40), device="cuda"),
+ torch.randn((1, 2, 40), device="cuda"),
+ )
+ except Exception as e:
+ raise e
+ processor = AttnProcessor()
+ else:
+ processor = AttnProcessor()
+
+ self.set_processor(processor)
+
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ attention_mask=None,
+ video_length=None,
+ **cross_attention_kwargs,
+ ):
+ """
+ Args:
+ hidden_states (`torch.Tensor`):
+ The hidden states to be passed through the model.
+ encoder_hidden_states (`torch.Tensor`, optional):
+ The encoder hidden states to be passed through the model.
+ attention_mask (`torch.Tensor`, optional):
+ The attention mask to be used in the model.
+ video_length (`int`, optional):
+ The length of the video.
+ cross_attention_kwargs (`dict`, optional):
+ Additional keyword arguments to be used for cross-attention.
+
+ Returns:
+ `torch.Tensor`:
+ The output tensor after passing through the model.
+
+ """
+ if self.attention_mode == "Temporal":
+ d = hidden_states.shape[1] # d means HxW
+ hidden_states = rearrange(
+ hidden_states, "(b f) d c -> (b d) f c", f=video_length
+ )
+
+ if self.pos_encoder is not None:
+ hidden_states = self.pos_encoder(hidden_states)
+
+ encoder_hidden_states = (
+ repeat(encoder_hidden_states, "b n c -> (b d) n c", d=d)
+ if encoder_hidden_states is not None
+ else encoder_hidden_states
+ )
+
+ else:
+ raise NotImplementedError
+
+ hidden_states = self.processor(
+ self,
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ **cross_attention_kwargs,
+ )
+
+ if self.attention_mode == "Temporal":
+ hidden_states = rearrange(
+ hidden_states, "(b d) f c -> (b f) d c", d=d)
+
+ return hidden_states
diff --git a/animation/hallo-83dd4eb/hallo/models/mutual_self_attention.py b/animation/hallo-83dd4eb/hallo/models/mutual_self_attention.py
new file mode 100644
index 0000000..d00784e
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/mutual_self_attention.py
@@ -0,0 +1,496 @@
+# pylint: disable=E1120
+"""
+This module contains the implementation of mutual self-attention,
+which is a type of attention mechanism used in deep learning models.
+The module includes several classes and functions related to attention mechanisms,
+such as BasicTransformerBlock and TemporalBasicTransformerBlock.
+The main purpose of this module is to provide a comprehensive attention mechanism for various tasks in deep learning,
+such as image and video processing, natural language processing, and so on.
+"""
+
+from typing import Any, Dict, Optional
+
+import torch
+from einops import rearrange
+
+from .attention import BasicTransformerBlock, TemporalBasicTransformerBlock
+
+
+def torch_dfs(model: torch.nn.Module):
+ """
+ Perform a depth-first search (DFS) traversal on a PyTorch model's neural network architecture.
+
+ This function recursively traverses all the children modules of a given PyTorch model and returns a list
+ containing all the modules in the model's architecture. The DFS approach starts with the input model and
+ explores its children modules depth-wise before backtracking and exploring other branches.
+
+ Args:
+ model (torch.nn.Module): The root module of the neural network to traverse.
+
+ Returns:
+ list: A list of all the modules in the model's architecture.
+ """
+ result = [model]
+ for child in model.children():
+ result += torch_dfs(child)
+ return result
+
+
+class ReferenceAttentionControl:
+ """
+ This class is used to control the reference attention mechanism in a neural network model.
+ It is responsible for managing the guidance and fusion blocks, and modifying the self-attention
+ and group normalization mechanisms. The class also provides methods for registering reference hooks
+ and updating/clearing the internal state of the attention control object.
+
+ Attributes:
+ unet: The UNet model associated with this attention control object.
+ mode: The operating mode of the attention control object, either 'write' or 'read'.
+ do_classifier_free_guidance: Whether to use classifier-free guidance in the attention mechanism.
+ attention_auto_machine_weight: The weight assigned to the attention auto-machine.
+ gn_auto_machine_weight: The weight assigned to the group normalization auto-machine.
+ style_fidelity: The style fidelity parameter for the attention mechanism.
+ reference_attn: Whether to use reference attention in the model.
+ reference_adain: Whether to use reference AdaIN in the model.
+ fusion_blocks: The type of fusion blocks to use in the model ('midup', 'late', or 'nofusion').
+ batch_size: The batch size used for processing video frames.
+
+ Methods:
+ register_reference_hooks: Registers the reference hooks for the attention control object.
+ hacked_basic_transformer_inner_forward: The modified inner forward method for the basic transformer block.
+ update: Updates the internal state of the attention control object using the provided writer and dtype.
+ clear: Clears the internal state of the attention control object.
+ """
+ def __init__(
+ self,
+ unet,
+ mode="write",
+ do_classifier_free_guidance=False,
+ attention_auto_machine_weight=float("inf"),
+ gn_auto_machine_weight=1.0,
+ style_fidelity=1.0,
+ reference_attn=True,
+ reference_adain=False,
+ fusion_blocks="midup",
+ batch_size=1,
+ ) -> None:
+ """
+ Initializes the ReferenceAttentionControl class.
+
+ Args:
+ unet (torch.nn.Module): The UNet model.
+ mode (str, optional): The mode of operation. Defaults to "write".
+ do_classifier_free_guidance (bool, optional): Whether to do classifier-free guidance. Defaults to False.
+ attention_auto_machine_weight (float, optional): The weight for attention auto-machine. Defaults to infinity.
+ gn_auto_machine_weight (float, optional): The weight for group-norm auto-machine. Defaults to 1.0.
+ style_fidelity (float, optional): The style fidelity. Defaults to 1.0.
+ reference_attn (bool, optional): Whether to use reference attention. Defaults to True.
+ reference_adain (bool, optional): Whether to use reference AdaIN. Defaults to False.
+ fusion_blocks (str, optional): The fusion blocks to use. Defaults to "midup".
+ batch_size (int, optional): The batch size. Defaults to 1.
+
+ Raises:
+ ValueError: If the mode is not recognized.
+ ValueError: If the fusion blocks are not recognized.
+ """
+ # 10. Modify self attention and group norm
+ self.unet = unet
+ assert mode in ["read", "write"]
+ assert fusion_blocks in ["midup", "full"]
+ self.reference_attn = reference_attn
+ self.reference_adain = reference_adain
+ self.fusion_blocks = fusion_blocks
+ self.register_reference_hooks(
+ mode,
+ do_classifier_free_guidance,
+ attention_auto_machine_weight,
+ gn_auto_machine_weight,
+ style_fidelity,
+ reference_attn,
+ reference_adain,
+ fusion_blocks,
+ batch_size=batch_size,
+ )
+
+ def register_reference_hooks(
+ self,
+ mode,
+ do_classifier_free_guidance,
+ _attention_auto_machine_weight,
+ _gn_auto_machine_weight,
+ _style_fidelity,
+ _reference_attn,
+ _reference_adain,
+ _dtype=torch.float16,
+ batch_size=1,
+ num_images_per_prompt=1,
+ device=torch.device("cpu"),
+ _fusion_blocks="midup",
+ ):
+ """
+ Registers reference hooks for the model.
+
+ This function is responsible for registering reference hooks in the model,
+ which are used to modify the attention mechanism and group normalization layers.
+ It takes various parameters as input, such as mode,
+ do_classifier_free_guidance, _attention_auto_machine_weight, _gn_auto_machine_weight, _style_fidelity,
+ _reference_attn, _reference_adain, _dtype, batch_size, num_images_per_prompt, device, and _fusion_blocks.
+
+ Args:
+ self: Reference to the instance of the class.
+ mode: The mode of operation for the reference hooks.
+ do_classifier_free_guidance: A boolean flag indicating whether to use classifier-free guidance.
+ _attention_auto_machine_weight: The weight for the attention auto-machine.
+ _gn_auto_machine_weight: The weight for the group normalization auto-machine.
+ _style_fidelity: The style fidelity for the reference hooks.
+ _reference_attn: A boolean flag indicating whether to use reference attention.
+ _reference_adain: A boolean flag indicating whether to use reference AdaIN.
+ _dtype: The data type for the reference hooks.
+ batch_size: The batch size for the reference hooks.
+ num_images_per_prompt: The number of images per prompt for the reference hooks.
+ device: The device for the reference hooks.
+ _fusion_blocks: The fusion blocks for the reference hooks.
+
+ Returns:
+ None
+ """
+ MODE = mode
+ if do_classifier_free_guidance:
+ uc_mask = (
+ torch.Tensor(
+ [1] * batch_size * num_images_per_prompt * 16
+ + [0] * batch_size * num_images_per_prompt * 16
+ )
+ .to(device)
+ .bool()
+ )
+ else:
+ uc_mask = (
+ torch.Tensor([0] * batch_size * num_images_per_prompt * 2)
+ .to(device)
+ .bool()
+ )
+
+ def hacked_basic_transformer_inner_forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ timestep: Optional[torch.LongTensor] = None,
+ cross_attention_kwargs: Dict[str, Any] = None,
+ class_labels: Optional[torch.LongTensor] = None,
+ video_length=None,
+ ):
+ gate_msa = None
+ shift_mlp = None
+ scale_mlp = None
+ gate_mlp = None
+
+ if self.use_ada_layer_norm: # False
+ norm_hidden_states = self.norm1(hidden_states, timestep)
+ elif self.use_ada_layer_norm_zero:
+ (
+ norm_hidden_states,
+ gate_msa,
+ shift_mlp,
+ scale_mlp,
+ gate_mlp,
+ ) = self.norm1(
+ hidden_states,
+ timestep,
+ class_labels,
+ hidden_dtype=hidden_states.dtype,
+ )
+ else:
+ norm_hidden_states = self.norm1(hidden_states)
+
+ # 1. Self-Attention
+ # self.only_cross_attention = False
+ cross_attention_kwargs = (
+ cross_attention_kwargs if cross_attention_kwargs is not None else {}
+ )
+ if self.only_cross_attention:
+ attn_output = self.attn1(
+ norm_hidden_states,
+ encoder_hidden_states=(
+ encoder_hidden_states if self.only_cross_attention else None
+ ),
+ attention_mask=attention_mask,
+ **cross_attention_kwargs,
+ )
+ else:
+ if MODE == "write":
+ self.bank.append(norm_hidden_states.clone())
+ attn_output = self.attn1(
+ norm_hidden_states,
+ encoder_hidden_states=(
+ encoder_hidden_states if self.only_cross_attention else None
+ ),
+ attention_mask=attention_mask,
+ **cross_attention_kwargs,
+ )
+ if MODE == "read":
+
+ bank_fea = [
+ rearrange(
+ rearrange(
+ d,
+ "(b s) l c -> b s l c",
+ b=norm_hidden_states.shape[0] // video_length,
+ )[:, 0, :, :]
+ # .unsqueeze(1)
+ .repeat(1, video_length, 1, 1),
+ "b t l c -> (b t) l c",
+ )
+ for d in self.bank
+ ]
+ motion_frames_fea = [rearrange(
+ d,
+ "(b s) l c -> b s l c",
+ b=norm_hidden_states.shape[0] // video_length,
+ )[:, 1:, :, :] for d in self.bank]
+ modify_norm_hidden_states = torch.cat(
+ [norm_hidden_states] + bank_fea, dim=1
+ )
+ hidden_states_uc = (
+ self.attn1(
+ norm_hidden_states,
+ encoder_hidden_states=modify_norm_hidden_states,
+ attention_mask=attention_mask,
+ )
+ + hidden_states
+ )
+ if do_classifier_free_guidance:
+ hidden_states_c = hidden_states_uc.clone()
+ _uc_mask = uc_mask.clone()
+ if hidden_states.shape[0] != _uc_mask.shape[0]:
+ _uc_mask = (
+ torch.Tensor(
+ [1] * (hidden_states.shape[0] // 2)
+ + [0] * (hidden_states.shape[0] // 2)
+ )
+ .to(device)
+ .bool()
+ )
+ hidden_states_c[_uc_mask] = (
+ self.attn1(
+ norm_hidden_states[_uc_mask],
+ encoder_hidden_states=norm_hidden_states[_uc_mask],
+ attention_mask=attention_mask,
+ )
+ + hidden_states[_uc_mask]
+ )
+ hidden_states = hidden_states_c.clone()
+ else:
+ hidden_states = hidden_states_uc
+
+ # self.bank.clear()
+ if self.attn2 is not None:
+ # Cross-Attention
+ norm_hidden_states = (
+ self.norm2(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm2(hidden_states)
+ )
+ hidden_states = (
+ self.attn2(
+ norm_hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ )
+ + hidden_states
+ )
+
+ # Feed-forward
+ hidden_states = self.ff(self.norm3(
+ hidden_states)) + hidden_states
+
+ # Temporal-Attention
+ if self.unet_use_temporal_attention:
+ d = hidden_states.shape[1]
+ hidden_states = rearrange(
+ hidden_states, "(b f) d c -> (b d) f c", f=video_length
+ )
+ norm_hidden_states = (
+ self.norm_temp(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm_temp(hidden_states)
+ )
+ hidden_states = (
+ self.attn_temp(norm_hidden_states) + hidden_states
+ )
+ hidden_states = rearrange(
+ hidden_states, "(b d) f c -> (b f) d c", d=d
+ )
+
+ return hidden_states, motion_frames_fea
+
+ if self.use_ada_layer_norm_zero:
+ attn_output = gate_msa.unsqueeze(1) * attn_output
+ hidden_states = attn_output + hidden_states
+
+ if self.attn2 is not None:
+ norm_hidden_states = (
+ self.norm2(hidden_states, timestep)
+ if self.use_ada_layer_norm
+ else self.norm2(hidden_states)
+ )
+
+ # 2. Cross-Attention
+ tmp = norm_hidden_states.shape[0] // encoder_hidden_states.shape[0]
+ attn_output = self.attn2(
+ norm_hidden_states,
+ # TODO: repeat这个地方需要斟酌一下
+ encoder_hidden_states=encoder_hidden_states.repeat(
+ tmp, 1, 1),
+ attention_mask=encoder_attention_mask,
+ **cross_attention_kwargs,
+ )
+ hidden_states = attn_output + hidden_states
+
+ # 3. Feed-forward
+ norm_hidden_states = self.norm3(hidden_states)
+
+ if self.use_ada_layer_norm_zero:
+ norm_hidden_states = (
+ norm_hidden_states *
+ (1 + scale_mlp[:, None]) + shift_mlp[:, None]
+ )
+
+ ff_output = self.ff(norm_hidden_states)
+
+ if self.use_ada_layer_norm_zero:
+ ff_output = gate_mlp.unsqueeze(1) * ff_output
+
+ hidden_states = ff_output + hidden_states
+
+ return hidden_states
+
+ if self.reference_attn:
+ if self.fusion_blocks == "midup":
+ attn_modules = [
+ module
+ for module in (
+ torch_dfs(self.unet.mid_block) +
+ torch_dfs(self.unet.up_blocks)
+ )
+ if isinstance(module, (BasicTransformerBlock, TemporalBasicTransformerBlock))
+ ]
+ elif self.fusion_blocks == "full":
+ attn_modules = [
+ module
+ for module in torch_dfs(self.unet)
+ if isinstance(module, (BasicTransformerBlock, TemporalBasicTransformerBlock))
+ ]
+ attn_modules = sorted(
+ attn_modules, key=lambda x: -x.norm1.normalized_shape[0]
+ )
+
+ for i, module in enumerate(attn_modules):
+ module._original_inner_forward = module.forward
+ if isinstance(module, BasicTransformerBlock):
+ module.forward = hacked_basic_transformer_inner_forward.__get__(
+ module,
+ BasicTransformerBlock)
+ if isinstance(module, TemporalBasicTransformerBlock):
+ module.forward = hacked_basic_transformer_inner_forward.__get__(
+ module,
+ TemporalBasicTransformerBlock)
+
+ module.bank = []
+ module.attn_weight = float(i) / float(len(attn_modules))
+
+ def update(self, writer, dtype=torch.float16):
+ """
+ Update the model's parameters.
+
+ Args:
+ writer (torch.nn.Module): The model's writer object.
+ dtype (torch.dtype, optional): The data type to be used for the update. Defaults to torch.float16.
+
+ Returns:
+ None.
+ """
+ if self.reference_attn:
+ if self.fusion_blocks == "midup":
+ reader_attn_modules = [
+ module
+ for module in (
+ torch_dfs(self.unet.mid_block) +
+ torch_dfs(self.unet.up_blocks)
+ )
+ if isinstance(module, TemporalBasicTransformerBlock)
+ ]
+ writer_attn_modules = [
+ module
+ for module in (
+ torch_dfs(writer.unet.mid_block)
+ + torch_dfs(writer.unet.up_blocks)
+ )
+ if isinstance(module, BasicTransformerBlock)
+ ]
+ elif self.fusion_blocks == "full":
+ reader_attn_modules = [
+ module
+ for module in torch_dfs(self.unet)
+ if isinstance(module, TemporalBasicTransformerBlock)
+ ]
+ writer_attn_modules = [
+ module
+ for module in torch_dfs(writer.unet)
+ if isinstance(module, BasicTransformerBlock)
+ ]
+
+ assert len(reader_attn_modules) == len(writer_attn_modules)
+ reader_attn_modules = sorted(
+ reader_attn_modules, key=lambda x: -x.norm1.normalized_shape[0]
+ )
+ writer_attn_modules = sorted(
+ writer_attn_modules, key=lambda x: -x.norm1.normalized_shape[0]
+ )
+ for r, w in zip(reader_attn_modules, writer_attn_modules):
+ r.bank = [v.clone().to(dtype) for v in w.bank]
+
+
+ def clear(self):
+ """
+ Clears the attention bank of all reader attention modules.
+
+ This method is used when the `reference_attn` attribute is set to `True`.
+ It clears the attention bank of all reader attention modules inside the UNet
+ model based on the selected `fusion_blocks` mode.
+
+ If `fusion_blocks` is set to "midup", it searches for reader attention modules
+ in both the mid block and up blocks of the UNet model. If `fusion_blocks` is set
+ to "full", it searches for reader attention modules in the entire UNet model.
+
+ It sorts the reader attention modules by the number of neurons in their
+ `norm1.normalized_shape[0]` attribute in descending order. This sorting ensures
+ that the modules with more neurons are cleared first.
+
+ Finally, it iterates through the sorted list of reader attention modules and
+ calls the `clear()` method on each module's `bank` attribute to clear the
+ attention bank.
+ """
+ if self.reference_attn:
+ if self.fusion_blocks == "midup":
+ reader_attn_modules = [
+ module
+ for module in (
+ torch_dfs(self.unet.mid_block) +
+ torch_dfs(self.unet.up_blocks)
+ )
+ if isinstance(module, (BasicTransformerBlock, TemporalBasicTransformerBlock))
+ ]
+ elif self.fusion_blocks == "full":
+ reader_attn_modules = [
+ module
+ for module in torch_dfs(self.unet)
+ if isinstance(module, (BasicTransformerBlock, TemporalBasicTransformerBlock))
+ ]
+ reader_attn_modules = sorted(
+ reader_attn_modules, key=lambda x: -x.norm1.normalized_shape[0]
+ )
+ for r in reader_attn_modules:
+ r.bank.clear()
diff --git a/animation/hallo-83dd4eb/hallo/models/resnet.py b/animation/hallo-83dd4eb/hallo/models/resnet.py
new file mode 100644
index 0000000..5593db7
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/resnet.py
@@ -0,0 +1,435 @@
+# pylint: disable=E1120
+# pylint: disable=E1102
+# pylint: disable=W0237
+
+# src/models/resnet.py
+
+"""
+This module defines various components used in the ResNet model, such as InflatedConv3D, InflatedGroupNorm,
+Upsample3D, Downsample3D, ResnetBlock3D, and Mish activation function. These components are used to construct
+a deep neural network model for image classification or other computer vision tasks.
+
+Classes:
+- InflatedConv3d: An inflated 3D convolutional layer, inheriting from nn.Conv2d.
+- InflatedGroupNorm: An inflated group normalization layer, inheriting from nn.GroupNorm.
+- Upsample3D: A 3D upsampling module, used to increase the resolution of the input tensor.
+- Downsample3D: A 3D downsampling module, used to decrease the resolution of the input tensor.
+- ResnetBlock3D: A 3D residual block, commonly used in ResNet architectures.
+- Mish: A Mish activation function, which is a smooth, non-monotonic activation function.
+
+To use this module, simply import the classes and functions you need and follow the instructions provided in
+the respective class and function docstrings.
+"""
+
+import torch
+import torch.nn.functional as F
+from einops import rearrange
+from torch import nn
+
+
+class InflatedConv3d(nn.Conv2d):
+ """
+ InflatedConv3d is a class that inherits from torch.nn.Conv2d and overrides the forward method.
+
+ This class is used to perform 3D convolution on input tensor x. It is a specialized type of convolutional layer
+ commonly used in deep learning models for computer vision tasks. The main difference between a regular Conv2d and
+ InflatedConv3d is that InflatedConv3d is designed to handle 3D input tensors, which are typically the result of
+ inflating 2D convolutional layers to 3D for use in 3D deep learning tasks.
+
+ Attributes:
+ Same as torch.nn.Conv2d.
+
+ Methods:
+ forward(self, x):
+ Performs 3D convolution on the input tensor x using the InflatedConv3d layer.
+
+ Example:
+ conv_layer = InflatedConv3d(in_channels=3, out_channels=64, kernel_size=3, stride=1, padding=1)
+ output = conv_layer(input_tensor)
+ """
+ def forward(self, x):
+ """
+ Forward pass of the InflatedConv3d layer.
+
+ Args:
+ x (torch.Tensor): Input tensor to the layer.
+
+ Returns:
+ torch.Tensor: Output tensor after applying the InflatedConv3d layer.
+ """
+ video_length = x.shape[2]
+
+ x = rearrange(x, "b c f h w -> (b f) c h w")
+ x = super().forward(x)
+ x = rearrange(x, "(b f) c h w -> b c f h w", f=video_length)
+
+ return x
+
+
+class InflatedGroupNorm(nn.GroupNorm):
+ """
+ InflatedGroupNorm is a custom class that inherits from torch.nn.GroupNorm.
+ It is used to apply group normalization to 3D tensors.
+
+ Args:
+ num_groups (int): The number of groups to divide the channels into.
+ num_channels (int): The number of channels in the input tensor.
+ eps (float, optional): A small constant to add to the variance to avoid division by zero. Defaults to 1e-5.
+ affine (bool, optional): If True, the module has learnable affine parameters. Defaults to True.
+
+ Attributes:
+ weight (torch.Tensor): The learnable weight tensor for scale.
+ bias (torch.Tensor): The learnable bias tensor for shift.
+
+ Forward method:
+ x (torch.Tensor): Input tensor to be normalized.
+ return (torch.Tensor): Normalized tensor.
+ """
+ def forward(self, x):
+ """
+ Performs a forward pass through the CustomClassName.
+
+ :param x: Input tensor of shape (batch_size, channels, video_length, height, width).
+ :return: Output tensor of shape (batch_size, channels, video_length, height, width).
+ """
+ video_length = x.shape[2]
+
+ x = rearrange(x, "b c f h w -> (b f) c h w")
+ x = super().forward(x)
+ x = rearrange(x, "(b f) c h w -> b c f h w", f=video_length)
+
+ return x
+
+
+class Upsample3D(nn.Module):
+ """
+ Upsample3D is a PyTorch module that upsamples a 3D tensor.
+
+ Args:
+ channels (int): The number of channels in the input tensor.
+ use_conv (bool): Whether to use a convolutional layer for upsampling.
+ use_conv_transpose (bool): Whether to use a transposed convolutional layer for upsampling.
+ out_channels (int): The number of channels in the output tensor.
+ name (str): The name of the convolutional layer.
+ """
+ def __init__(
+ self,
+ channels,
+ use_conv=False,
+ use_conv_transpose=False,
+ out_channels=None,
+ name="conv",
+ ):
+ super().__init__()
+ self.channels = channels
+ self.out_channels = out_channels or channels
+ self.use_conv = use_conv
+ self.use_conv_transpose = use_conv_transpose
+ self.name = name
+
+ if use_conv_transpose:
+ raise NotImplementedError
+ if use_conv:
+ self.conv = InflatedConv3d(self.channels, self.out_channels, 3, padding=1)
+
+ def forward(self, hidden_states, output_size=None):
+ """
+ Forward pass of the Upsample3D class.
+
+ Args:
+ hidden_states (torch.Tensor): Input tensor to be upsampled.
+ output_size (tuple, optional): Desired output size of the upsampled tensor.
+
+ Returns:
+ torch.Tensor: Upsampled tensor.
+
+ Raises:
+ AssertionError: If the number of channels in the input tensor does not match the expected channels.
+ """
+ assert hidden_states.shape[1] == self.channels
+
+ if self.use_conv_transpose:
+ raise NotImplementedError
+
+ # Cast to float32 to as 'upsample_nearest2d_out_frame' op does not support bfloat16
+ dtype = hidden_states.dtype
+ if dtype == torch.bfloat16:
+ hidden_states = hidden_states.to(torch.float32)
+
+ # upsample_nearest_nhwc fails with large batch sizes. see https://github.com/huggingface/diffusers/issues/984
+ if hidden_states.shape[0] >= 64:
+ hidden_states = hidden_states.contiguous()
+
+ # if `output_size` is passed we force the interpolation output
+ # size and do not make use of `scale_factor=2`
+ if output_size is None:
+ hidden_states = F.interpolate(
+ hidden_states, scale_factor=[1.0, 2.0, 2.0], mode="nearest"
+ )
+ else:
+ hidden_states = F.interpolate(
+ hidden_states, size=output_size, mode="nearest"
+ )
+
+ # If the input is bfloat16, we cast back to bfloat16
+ if dtype == torch.bfloat16:
+ hidden_states = hidden_states.to(dtype)
+
+ # if self.use_conv:
+ # if self.name == "conv":
+ # hidden_states = self.conv(hidden_states)
+ # else:
+ # hidden_states = self.Conv2d_0(hidden_states)
+ hidden_states = self.conv(hidden_states)
+
+ return hidden_states
+
+
+class Downsample3D(nn.Module):
+ """
+ The Downsample3D class is a PyTorch module for downsampling a 3D tensor, which is used to
+ reduce the spatial resolution of feature maps, commonly in the encoder part of a neural network.
+
+ Attributes:
+ channels (int): Number of input channels.
+ use_conv (bool): Flag to use a convolutional layer for downsampling.
+ out_channels (int, optional): Number of output channels. Defaults to input channels if None.
+ padding (int): Padding added to the input.
+ name (str): Name of the convolutional layer used for downsampling.
+
+ Methods:
+ forward(self, hidden_states):
+ Downsamples the input tensor hidden_states and returns the downsampled tensor.
+ """
+ def __init__(
+ self, channels, use_conv=False, out_channels=None, padding=1, name="conv"
+ ):
+ """
+ Downsamples the given input in the 3D space.
+
+ Args:
+ channels: The number of input channels.
+ use_conv: Whether to use a convolutional layer for downsampling.
+ out_channels: The number of output channels. If None, the input channels are used.
+ padding: The amount of padding to be added to the input.
+ name: The name of the convolutional layer.
+ """
+ super().__init__()
+ self.channels = channels
+ self.out_channels = out_channels or channels
+ self.use_conv = use_conv
+ self.padding = padding
+ stride = 2
+ self.name = name
+
+ if use_conv:
+ self.conv = InflatedConv3d(
+ self.channels, self.out_channels, 3, stride=stride, padding=padding
+ )
+ else:
+ raise NotImplementedError
+
+ def forward(self, hidden_states):
+ """
+ Forward pass for the Downsample3D class.
+
+ Args:
+ hidden_states (torch.Tensor): Input tensor to be downsampled.
+
+ Returns:
+ torch.Tensor: Downsampled tensor.
+
+ Raises:
+ AssertionError: If the number of channels in the input tensor does not match the expected channels.
+ """
+ assert hidden_states.shape[1] == self.channels
+ if self.use_conv and self.padding == 0:
+ raise NotImplementedError
+
+ assert hidden_states.shape[1] == self.channels
+ hidden_states = self.conv(hidden_states)
+
+ return hidden_states
+
+
+class ResnetBlock3D(nn.Module):
+ """
+ The ResnetBlock3D class defines a 3D residual block, a common building block in ResNet
+ architectures for both image and video modeling tasks.
+
+ Attributes:
+ in_channels (int): Number of input channels.
+ out_channels (int, optional): Number of output channels, defaults to in_channels if None.
+ conv_shortcut (bool): Flag to use a convolutional shortcut.
+ dropout (float): Dropout rate.
+ temb_channels (int): Number of channels in the time embedding tensor.
+ groups (int): Number of groups for the group normalization layers.
+ eps (float): Epsilon value for group normalization.
+ non_linearity (str): Type of nonlinearity to apply after convolutions.
+ time_embedding_norm (str): Type of normalization for the time embedding.
+ output_scale_factor (float): Scaling factor for the output tensor.
+ use_in_shortcut (bool): Flag to include the input tensor in the shortcut connection.
+ use_inflated_groupnorm (bool): Flag to use inflated group normalization layers.
+
+ Methods:
+ forward(self, input_tensor, temb):
+ Passes the input tensor and time embedding through the residual block and
+ returns the output tensor.
+ """
+ def __init__(
+ self,
+ *,
+ in_channels,
+ out_channels=None,
+ conv_shortcut=False,
+ dropout=0.0,
+ temb_channels=512,
+ groups=32,
+ groups_out=None,
+ pre_norm=True,
+ eps=1e-6,
+ non_linearity="swish",
+ time_embedding_norm="default",
+ output_scale_factor=1.0,
+ use_in_shortcut=None,
+ use_inflated_groupnorm=None,
+ ):
+ super().__init__()
+ self.pre_norm = pre_norm
+ self.pre_norm = True
+ self.in_channels = in_channels
+ out_channels = in_channels if out_channels is None else out_channels
+ self.out_channels = out_channels
+ self.use_conv_shortcut = conv_shortcut
+ self.time_embedding_norm = time_embedding_norm
+ self.output_scale_factor = output_scale_factor
+
+ if groups_out is None:
+ groups_out = groups
+
+ assert use_inflated_groupnorm is not None
+ if use_inflated_groupnorm:
+ self.norm1 = InflatedGroupNorm(
+ num_groups=groups, num_channels=in_channels, eps=eps, affine=True
+ )
+ else:
+ self.norm1 = torch.nn.GroupNorm(
+ num_groups=groups, num_channels=in_channels, eps=eps, affine=True
+ )
+
+ self.conv1 = InflatedConv3d(
+ in_channels, out_channels, kernel_size=3, stride=1, padding=1
+ )
+
+ if temb_channels is not None:
+ if self.time_embedding_norm == "default":
+ time_emb_proj_out_channels = out_channels
+ elif self.time_embedding_norm == "scale_shift":
+ time_emb_proj_out_channels = out_channels * 2
+ else:
+ raise ValueError(
+ f"unknown time_embedding_norm : {self.time_embedding_norm} "
+ )
+
+ self.time_emb_proj = torch.nn.Linear(
+ temb_channels, time_emb_proj_out_channels
+ )
+ else:
+ self.time_emb_proj = None
+
+ if use_inflated_groupnorm:
+ self.norm2 = InflatedGroupNorm(
+ num_groups=groups_out, num_channels=out_channels, eps=eps, affine=True
+ )
+ else:
+ self.norm2 = torch.nn.GroupNorm(
+ num_groups=groups_out, num_channels=out_channels, eps=eps, affine=True
+ )
+ self.dropout = torch.nn.Dropout(dropout)
+ self.conv2 = InflatedConv3d(
+ out_channels, out_channels, kernel_size=3, stride=1, padding=1
+ )
+
+ if non_linearity == "swish":
+ self.nonlinearity = F.silu()
+ elif non_linearity == "mish":
+ self.nonlinearity = Mish()
+ elif non_linearity == "silu":
+ self.nonlinearity = nn.SiLU()
+
+ self.use_in_shortcut = (
+ self.in_channels != self.out_channels
+ if use_in_shortcut is None
+ else use_in_shortcut
+ )
+
+ self.conv_shortcut = None
+ if self.use_in_shortcut:
+ self.conv_shortcut = InflatedConv3d(
+ in_channels, out_channels, kernel_size=1, stride=1, padding=0
+ )
+
+ def forward(self, input_tensor, temb):
+ """
+ Forward pass for the ResnetBlock3D class.
+
+ Args:
+ input_tensor (torch.Tensor): Input tensor to the ResnetBlock3D layer.
+ temb (torch.Tensor): Token embedding tensor.
+
+ Returns:
+ torch.Tensor: Output tensor after passing through the ResnetBlock3D layer.
+ """
+ hidden_states = input_tensor
+
+ hidden_states = self.norm1(hidden_states)
+ hidden_states = self.nonlinearity(hidden_states)
+
+ hidden_states = self.conv1(hidden_states)
+
+ if temb is not None:
+ temb = self.time_emb_proj(self.nonlinearity(temb))[:, :, None, None, None]
+
+ if temb is not None and self.time_embedding_norm == "default":
+ hidden_states = hidden_states + temb
+
+ hidden_states = self.norm2(hidden_states)
+
+ if temb is not None and self.time_embedding_norm == "scale_shift":
+ scale, shift = torch.chunk(temb, 2, dim=1)
+ hidden_states = hidden_states * (1 + scale) + shift
+
+ hidden_states = self.nonlinearity(hidden_states)
+
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.conv2(hidden_states)
+
+ if self.conv_shortcut is not None:
+ input_tensor = self.conv_shortcut(input_tensor)
+
+ output_tensor = (input_tensor + hidden_states) / self.output_scale_factor
+
+ return output_tensor
+
+
+class Mish(torch.nn.Module):
+ """
+ The Mish class implements the Mish activation function, a smooth, non-monotonic function
+ that can be used in neural networks as an alternative to traditional activation functions like ReLU.
+
+ Methods:
+ forward(self, hidden_states):
+ Applies the Mish activation function to the input tensor hidden_states and
+ returns the resulting tensor.
+ """
+ def forward(self, hidden_states):
+ """
+ Mish activation function.
+
+ Args:
+ hidden_states (torch.Tensor): The input tensor to apply the Mish activation function to.
+
+ Returns:
+ hidden_states (torch.Tensor): The output tensor after applying the Mish activation function.
+ """
+ return hidden_states * torch.tanh(torch.nn.functional.softplus(hidden_states))
diff --git a/animation/hallo-83dd4eb/hallo/models/transformer_2d.py b/animation/hallo-83dd4eb/hallo/models/transformer_2d.py
new file mode 100644
index 0000000..e9c5bbb
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/transformer_2d.py
@@ -0,0 +1,431 @@
+# pylint: disable=E1101
+# src/models/transformer_2d.py
+
+"""
+This module defines the Transformer2DModel, a PyTorch model that extends ModelMixin and ConfigMixin. It includes
+methods for gradient checkpointing, forward propagation, and various utility functions. The model is designed for
+2D image-related tasks and uses LoRa (Low-Rank All-Attention) compatible layers for efficient attention computation.
+
+The file includes the following import statements:
+
+- From dataclasses import dataclass
+- From typing import Any, Dict, Optional
+- Import torch
+- From diffusers.configuration_utils import ConfigMixin, register_to_config
+- From diffusers.models.lora import LoRACompatibleConv, LoRACompatibleLinear
+- From diffusers.models.modeling_utils import ModelMixin
+- From diffusers.models.normalization import AdaLayerNormSingle
+- From diffusers.utils import (USE_PEFT_BACKEND, BaseOutput, deprecate,
+ is_torch_version)
+- From torch import nn
+- From .attention import BasicTransformerBlock
+
+The file also includes the following classes and functions:
+
+- Transformer2DModel: A model class that extends ModelMixin and ConfigMixin. It includes methods for gradient
+ checkpointing, forward propagation, and various utility functions.
+- _set_gradient_checkpointing: A utility function to set gradient checkpointing for a given module.
+- forward: The forward propagation method for the Transformer2DModel.
+
+To use this module, you can import the Transformer2DModel class and create an instance of the model with the desired
+configuration. Then, you can use the forward method to pass input tensors through the model and get the output tensors.
+"""
+
+from dataclasses import dataclass
+from typing import Any, Dict, Optional
+
+import torch
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+# from diffusers.models.embeddings import CaptionProjection
+from diffusers.models.lora import LoRACompatibleConv, LoRACompatibleLinear
+from diffusers.models.modeling_utils import ModelMixin
+from diffusers.models.normalization import AdaLayerNormSingle
+from diffusers.utils import (USE_PEFT_BACKEND, BaseOutput, deprecate,
+ is_torch_version)
+from torch import nn
+
+from .attention import BasicTransformerBlock
+
+
+@dataclass
+class Transformer2DModelOutput(BaseOutput):
+ """
+ The output of [`Transformer2DModel`].
+
+ Args:
+ sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`
+ or `(batch size, num_vector_embeds - 1, num_latent_pixels)` if [`Transformer2DModel`] is discrete):
+ The hidden states output conditioned on the `encoder_hidden_states` input. If discrete, returns probability
+ distributions for the unnoised latent pixels.
+ """
+
+ sample: torch.FloatTensor
+ ref_feature: torch.FloatTensor
+
+
+class Transformer2DModel(ModelMixin, ConfigMixin):
+ """
+ A 2D Transformer model for image-like data.
+
+ Parameters:
+ num_attention_heads (`int`, *optional*, defaults to 16): The number of heads to use for multi-head attention.
+ attention_head_dim (`int`, *optional*, defaults to 88): The number of channels in each head.
+ in_channels (`int`, *optional*):
+ The number of channels in the input and output (specify if the input is **continuous**).
+ num_layers (`int`, *optional*, defaults to 1): The number of layers of Transformer blocks to use.
+ dropout (`float`, *optional*, defaults to 0.0): The dropout probability to use.
+ cross_attention_dim (`int`, *optional*): The number of `encoder_hidden_states` dimensions to use.
+ sample_size (`int`, *optional*): The width of the latent images (specify if the input is **discrete**).
+ This is fixed during training since it is used to learn a number of position embeddings.
+ num_vector_embeds (`int`, *optional*):
+ The number of classes of the vector embeddings of the latent pixels (specify if the input is **discrete**).
+ Includes the class for the masked latent pixel.
+ activation_fn (`str`, *optional*, defaults to `"geglu"`): Activation function to use in feed-forward.
+ num_embeds_ada_norm ( `int`, *optional*):
+ The number of diffusion steps used during training. Pass if at least one of the norm_layers is
+ `AdaLayerNorm`. This is fixed during training since it is used to learn a number of embeddings that are
+ added to the hidden states.
+
+ During inference, you can denoise for up to but not more steps than `num_embeds_ada_norm`.
+ attention_bias (`bool`, *optional*):
+ Configure if the `TransformerBlocks` attention should contain a bias parameter.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ num_attention_heads: int = 16,
+ attention_head_dim: int = 88,
+ in_channels: Optional[int] = None,
+ out_channels: Optional[int] = None,
+ num_layers: int = 1,
+ dropout: float = 0.0,
+ norm_num_groups: int = 32,
+ cross_attention_dim: Optional[int] = None,
+ attention_bias: bool = False,
+ num_vector_embeds: Optional[int] = None,
+ patch_size: Optional[int] = None,
+ activation_fn: str = "geglu",
+ num_embeds_ada_norm: Optional[int] = None,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ double_self_attention: bool = False,
+ upcast_attention: bool = False,
+ norm_type: str = "layer_norm",
+ norm_elementwise_affine: bool = True,
+ norm_eps: float = 1e-5,
+ attention_type: str = "default",
+ ):
+ super().__init__()
+ self.use_linear_projection = use_linear_projection
+ self.num_attention_heads = num_attention_heads
+ self.attention_head_dim = attention_head_dim
+ inner_dim = num_attention_heads * attention_head_dim
+
+ conv_cls = nn.Conv2d if USE_PEFT_BACKEND else LoRACompatibleConv
+ linear_cls = nn.Linear if USE_PEFT_BACKEND else LoRACompatibleLinear
+
+ # 1. Transformer2DModel can process both standard continuous images of
+ # shape `(batch_size, num_channels, width, height)` as well as quantized image embeddings of
+ # shape `(batch_size, num_image_vectors)`
+ # Define whether input is continuous or discrete depending on configuration
+ self.is_input_continuous = (in_channels is not None) and (patch_size is None)
+ self.is_input_vectorized = num_vector_embeds is not None
+ self.is_input_patches = in_channels is not None and patch_size is not None
+
+ if norm_type == "layer_norm" and num_embeds_ada_norm is not None:
+ deprecation_message = (
+ f"The configuration file of this model: {self.__class__} is outdated. `norm_type` is either not set or"
+ " incorrectly set to `'layer_norm'`.Make sure to set `norm_type` to `'ada_norm'` in the config."
+ " Please make sure to update the config accordingly as leaving `norm_type` might led to incorrect"
+ " results in future versions. If you have downloaded this checkpoint from the Hugging Face Hub, it"
+ " would be very nice if you could open a Pull request for the `transformer/config.json` file"
+ )
+ deprecate(
+ "norm_type!=num_embeds_ada_norm",
+ "1.0.0",
+ deprecation_message,
+ standard_warn=False,
+ )
+ norm_type = "ada_norm"
+
+ if self.is_input_continuous and self.is_input_vectorized:
+ raise ValueError(
+ f"Cannot define both `in_channels`: {in_channels} and `num_vector_embeds`: {num_vector_embeds}. Make"
+ " sure that either `in_channels` or `num_vector_embeds` is None."
+ )
+
+ if self.is_input_vectorized and self.is_input_patches:
+ raise ValueError(
+ f"Cannot define both `num_vector_embeds`: {num_vector_embeds} and `patch_size`: {patch_size}. Make"
+ " sure that either `num_vector_embeds` or `num_patches` is None."
+ )
+
+ if (
+ not self.is_input_continuous
+ and not self.is_input_vectorized
+ and not self.is_input_patches
+ ):
+ raise ValueError(
+ f"Has to define `in_channels`: {in_channels}, `num_vector_embeds`: {num_vector_embeds}, or patch_size:"
+ f" {patch_size}. Make sure that `in_channels`, `num_vector_embeds` or `num_patches` is not None."
+ )
+
+ # 2. Define input layers
+ self.in_channels = in_channels
+
+ self.norm = torch.nn.GroupNorm(
+ num_groups=norm_num_groups,
+ num_channels=in_channels,
+ eps=1e-6,
+ affine=True,
+ )
+ if use_linear_projection:
+ self.proj_in = linear_cls(in_channels, inner_dim)
+ else:
+ self.proj_in = conv_cls(
+ in_channels, inner_dim, kernel_size=1, stride=1, padding=0
+ )
+
+ # 3. Define transformers blocks
+ self.transformer_blocks = nn.ModuleList(
+ [
+ BasicTransformerBlock(
+ inner_dim,
+ num_attention_heads,
+ attention_head_dim,
+ dropout=dropout,
+ cross_attention_dim=cross_attention_dim,
+ activation_fn=activation_fn,
+ num_embeds_ada_norm=num_embeds_ada_norm,
+ attention_bias=attention_bias,
+ only_cross_attention=only_cross_attention,
+ double_self_attention=double_self_attention,
+ upcast_attention=upcast_attention,
+ norm_type=norm_type,
+ norm_elementwise_affine=norm_elementwise_affine,
+ norm_eps=norm_eps,
+ attention_type=attention_type,
+ )
+ for d in range(num_layers)
+ ]
+ )
+
+ # 4. Define output layers
+ self.out_channels = in_channels if out_channels is None else out_channels
+ # TODO: should use out_channels for continuous projections
+ if use_linear_projection:
+ self.proj_out = linear_cls(inner_dim, in_channels)
+ else:
+ self.proj_out = conv_cls(
+ inner_dim, in_channels, kernel_size=1, stride=1, padding=0
+ )
+
+ # 5. PixArt-Alpha blocks.
+ self.adaln_single = None
+ self.use_additional_conditions = False
+ if norm_type == "ada_norm_single":
+ self.use_additional_conditions = self.config.sample_size == 128
+ # TODO(Sayak, PVP) clean this, for now we use sample size to determine whether to use
+ # additional conditions until we find better name
+ self.adaln_single = AdaLayerNormSingle(
+ inner_dim, use_additional_conditions=self.use_additional_conditions
+ )
+
+ self.caption_projection = None
+
+ self.gradient_checkpointing = False
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ if hasattr(module, "gradient_checkpointing"):
+ module.gradient_checkpointing = value
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ encoder_hidden_states: Optional[torch.Tensor] = None,
+ timestep: Optional[torch.LongTensor] = None,
+ _added_cond_kwargs: Dict[str, torch.Tensor] = None,
+ class_labels: Optional[torch.LongTensor] = None,
+ cross_attention_kwargs: Dict[str, Any] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ return_dict: bool = True,
+ ):
+ """
+ The [`Transformer2DModel`] forward method.
+
+ Args:
+ hidden_states (`torch.LongTensor` of shape `(batch size, num latent pixels)` if discrete,
+ `torch.FloatTensor` of shape `(batch size, channel, height, width)` if continuous):
+ Input `hidden_states`.
+ encoder_hidden_states ( `torch.FloatTensor` of shape `(batch size, sequence len, embed dims)`, *optional*):
+ Conditional embeddings for cross attention layer. If not given, cross-attention defaults to
+ self-attention.
+ timestep ( `torch.LongTensor`, *optional*):
+ Used to indicate denoising step. Optional timestep to be applied as an embedding in `AdaLayerNorm`.
+ class_labels ( `torch.LongTensor` of shape `(batch size, num classes)`, *optional*):
+ Used to indicate class labels conditioning. Optional class labels to be applied as an embedding in
+ `AdaLayerZeroNorm`.
+ cross_attention_kwargs ( `Dict[str, Any]`, *optional*):
+ A kwargs dictionary that if specified is passed along to the `AttentionProcessor` as defined under
+ `self.processor` in
+ [diffusers.models.attention_processor]
+ (https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py).
+ attention_mask ( `torch.Tensor`, *optional*):
+ An attention mask of shape `(batch, key_tokens)` is applied to `encoder_hidden_states`. If `1` the mask
+ is kept, otherwise if `0` it is discarded. Mask will be converted into a bias, which adds large
+ negative values to the attention scores corresponding to "discard" tokens.
+ encoder_attention_mask ( `torch.Tensor`, *optional*):
+ Cross-attention mask applied to `encoder_hidden_states`. Two formats supported:
+
+ * Mask `(batch, sequence_length)` True = keep, False = discard.
+ * Bias `(batch, 1, sequence_length)` 0 = keep, -10000 = discard.
+
+ If `ndim == 2`: will be interpreted as a mask, then converted into a bias consistent with the format
+ above. This bias will be added to the cross-attention scores.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~models.unet_2d_condition.UNet2DConditionOutput`] instead of a plain
+ tuple.
+
+ Returns:
+ If `return_dict` is True, an [`~models.transformer_2d.Transformer2DModelOutput`] is returned, otherwise a
+ `tuple` where the first element is the sample tensor.
+ """
+ # ensure attention_mask is a bias, and give it a singleton query_tokens dimension.
+ # we may have done this conversion already, e.g. if we came here via UNet2DConditionModel#forward.
+ # we can tell by counting dims; if ndim == 2: it's a mask rather than a bias.
+ # expects mask of shape:
+ # [batch, key_tokens]
+ # adds singleton query_tokens dimension:
+ # [batch, 1, key_tokens]
+ # this helps to broadcast it as a bias over attention scores, which will be in one of the following shapes:
+ # [batch, heads, query_tokens, key_tokens] (e.g. torch sdp attn)
+ # [batch * heads, query_tokens, key_tokens] (e.g. xformers or classic attn)
+ if attention_mask is not None and attention_mask.ndim == 2:
+ # assume that mask is expressed as:
+ # (1 = keep, 0 = discard)
+ # convert mask into a bias that can be added to attention scores:
+ # (keep = +0, discard = -10000.0)
+ attention_mask = (1 - attention_mask.to(hidden_states.dtype)) * -10000.0
+ attention_mask = attention_mask.unsqueeze(1)
+
+ # convert encoder_attention_mask to a bias the same way we do for attention_mask
+ if encoder_attention_mask is not None and encoder_attention_mask.ndim == 2:
+ encoder_attention_mask = (
+ 1 - encoder_attention_mask.to(hidden_states.dtype)
+ ) * -10000.0
+ encoder_attention_mask = encoder_attention_mask.unsqueeze(1)
+
+ # Retrieve lora scale.
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+
+ # 1. Input
+ batch, _, height, width = hidden_states.shape
+ residual = hidden_states
+
+ hidden_states = self.norm(hidden_states)
+ if not self.use_linear_projection:
+ hidden_states = (
+ self.proj_in(hidden_states, scale=lora_scale)
+ if not USE_PEFT_BACKEND
+ else self.proj_in(hidden_states)
+ )
+ inner_dim = hidden_states.shape[1]
+ hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(
+ batch, height * width, inner_dim
+ )
+ else:
+ inner_dim = hidden_states.shape[1]
+ hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(
+ batch, height * width, inner_dim
+ )
+ hidden_states = (
+ self.proj_in(hidden_states, scale=lora_scale)
+ if not USE_PEFT_BACKEND
+ else self.proj_in(hidden_states)
+ )
+
+ # 2. Blocks
+ if self.caption_projection is not None:
+ batch_size = hidden_states.shape[0]
+ encoder_hidden_states = self.caption_projection(encoder_hidden_states)
+ encoder_hidden_states = encoder_hidden_states.view(
+ batch_size, -1, hidden_states.shape[-1]
+ )
+
+ ref_feature = hidden_states.reshape(batch, height, width, inner_dim)
+ for block in self.transformer_blocks:
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ ckpt_kwargs: Dict[str, Any] = (
+ {"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
+ )
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(block),
+ hidden_states,
+ attention_mask,
+ encoder_hidden_states,
+ encoder_attention_mask,
+ timestep,
+ cross_attention_kwargs,
+ class_labels,
+ **ckpt_kwargs,
+ )
+ else:
+ hidden_states = block(
+ hidden_states, # shape [5, 4096, 320]
+ attention_mask=attention_mask,
+ encoder_hidden_states=encoder_hidden_states, # shape [1,4,768]
+ encoder_attention_mask=encoder_attention_mask,
+ timestep=timestep,
+ cross_attention_kwargs=cross_attention_kwargs,
+ class_labels=class_labels,
+ )
+
+ # 3. Output
+ output = None
+ if self.is_input_continuous:
+ if not self.use_linear_projection:
+ hidden_states = (
+ hidden_states.reshape(batch, height, width, inner_dim)
+ .permute(0, 3, 1, 2)
+ .contiguous()
+ )
+ hidden_states = (
+ self.proj_out(hidden_states, scale=lora_scale)
+ if not USE_PEFT_BACKEND
+ else self.proj_out(hidden_states)
+ )
+ else:
+ hidden_states = (
+ self.proj_out(hidden_states, scale=lora_scale)
+ if not USE_PEFT_BACKEND
+ else self.proj_out(hidden_states)
+ )
+ hidden_states = (
+ hidden_states.reshape(batch, height, width, inner_dim)
+ .permute(0, 3, 1, 2)
+ .contiguous()
+ )
+
+ output = hidden_states + residual
+ if not return_dict:
+ return (output, ref_feature)
+
+ return Transformer2DModelOutput(sample=output, ref_feature=ref_feature)
diff --git a/animation/hallo-83dd4eb/hallo/models/transformer_3d.py b/animation/hallo-83dd4eb/hallo/models/transformer_3d.py
new file mode 100644
index 0000000..f2899a3
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/transformer_3d.py
@@ -0,0 +1,257 @@
+# pylint: disable=R0801
+"""
+This module implements the Transformer3DModel, a PyTorch model designed for processing
+3D data such as videos. It extends ModelMixin and ConfigMixin to provide a transformer
+model with support for gradient checkpointing and various types of attention mechanisms.
+The model can be configured with different parameters such as the number of attention heads,
+attention head dimension, and the number of layers. It also supports the use of audio modules
+for enhanced feature extraction from video data.
+"""
+
+from dataclasses import dataclass
+from typing import Optional
+
+import torch
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+from diffusers.models import ModelMixin
+from diffusers.utils import BaseOutput
+from einops import rearrange, repeat
+from torch import nn
+
+from .attention import (AudioTemporalBasicTransformerBlock,
+ TemporalBasicTransformerBlock)
+
+
+@dataclass
+class Transformer3DModelOutput(BaseOutput):
+ """
+ The output of the [`Transformer3DModel`].
+
+ Attributes:
+ sample (`torch.FloatTensor`):
+ The output tensor from the transformer model, which is the result of processing the input
+ hidden states through the transformer blocks and any subsequent layers.
+ """
+ sample: torch.FloatTensor
+
+
+class Transformer3DModel(ModelMixin, ConfigMixin):
+ """
+ Transformer3DModel is a PyTorch model that extends `ModelMixin` and `ConfigMixin` to create a 3D transformer model.
+ It implements the forward pass for processing input hidden states, encoder hidden states, and various types of attention masks.
+ The model supports gradient checkpointing, which can be enabled by calling the `enable_gradient_checkpointing()` method.
+ """
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ num_attention_heads: int = 16,
+ attention_head_dim: int = 88,
+ in_channels: Optional[int] = None,
+ num_layers: int = 1,
+ dropout: float = 0.0,
+ norm_num_groups: int = 32,
+ cross_attention_dim: Optional[int] = None,
+ attention_bias: bool = False,
+ activation_fn: str = "geglu",
+ num_embeds_ada_norm: Optional[int] = None,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_audio_module=False,
+ depth=0,
+ unet_block_name=None,
+ stack_enable_blocks_name = None,
+ stack_enable_blocks_depth = None,
+ ):
+ super().__init__()
+ self.use_linear_projection = use_linear_projection
+ self.num_attention_heads = num_attention_heads
+ self.attention_head_dim = attention_head_dim
+ inner_dim = num_attention_heads * attention_head_dim
+ self.use_audio_module = use_audio_module
+ # Define input layers
+ self.in_channels = in_channels
+
+ self.norm = torch.nn.GroupNorm(
+ num_groups=norm_num_groups, num_channels=in_channels, eps=1e-6, affine=True
+ )
+ if use_linear_projection:
+ self.proj_in = nn.Linear(in_channels, inner_dim)
+ else:
+ self.proj_in = nn.Conv2d(
+ in_channels, inner_dim, kernel_size=1, stride=1, padding=0
+ )
+
+ if use_audio_module:
+ self.transformer_blocks = nn.ModuleList(
+ [
+ AudioTemporalBasicTransformerBlock(
+ inner_dim,
+ num_attention_heads,
+ attention_head_dim,
+ dropout=dropout,
+ cross_attention_dim=cross_attention_dim,
+ activation_fn=activation_fn,
+ num_embeds_ada_norm=num_embeds_ada_norm,
+ attention_bias=attention_bias,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ depth=depth,
+ unet_block_name=unet_block_name,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ for d in range(num_layers)
+ ]
+ )
+ else:
+ # Define transformers blocks
+ self.transformer_blocks = nn.ModuleList(
+ [
+ TemporalBasicTransformerBlock(
+ inner_dim,
+ num_attention_heads,
+ attention_head_dim,
+ dropout=dropout,
+ cross_attention_dim=cross_attention_dim,
+ activation_fn=activation_fn,
+ num_embeds_ada_norm=num_embeds_ada_norm,
+ attention_bias=attention_bias,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ )
+ for d in range(num_layers)
+ ]
+ )
+
+ # 4. Define output layers
+ if use_linear_projection:
+ self.proj_out = nn.Linear(in_channels, inner_dim)
+ else:
+ self.proj_out = nn.Conv2d(
+ inner_dim, in_channels, kernel_size=1, stride=1, padding=0
+ )
+
+ self.gradient_checkpointing = False
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ if hasattr(module, "gradient_checkpointing"):
+ module.gradient_checkpointing = value
+
+ def forward(
+ self,
+ hidden_states,
+ encoder_hidden_states=None,
+ attention_mask=None,
+ full_mask=None,
+ face_mask=None,
+ lip_mask=None,
+ motion_scale=None,
+ timestep=None,
+ return_dict: bool = True,
+ ):
+ """
+ Forward pass for the Transformer3DModel.
+
+ Args:
+ hidden_states (torch.Tensor): The input hidden states.
+ encoder_hidden_states (torch.Tensor, optional): The input encoder hidden states.
+ attention_mask (torch.Tensor, optional): The attention mask.
+ full_mask (torch.Tensor, optional): The full mask.
+ face_mask (torch.Tensor, optional): The face mask.
+ lip_mask (torch.Tensor, optional): The lip mask.
+ timestep (int, optional): The current timestep.
+ return_dict (bool, optional): Whether to return a dictionary or a tuple.
+
+ Returns:
+ output (Union[Tuple, BaseOutput]): The output of the Transformer3DModel.
+ """
+ # Input
+ assert (
+ hidden_states.dim() == 5
+ ), f"Expected hidden_states to have ndim=5, but got ndim={hidden_states.dim()}."
+ video_length = hidden_states.shape[2]
+ hidden_states = rearrange(hidden_states, "b c f h w -> (b f) c h w")
+
+ # TODO
+ if self.use_audio_module:
+ encoder_hidden_states = rearrange(
+ encoder_hidden_states,
+ "bs f margin dim -> (bs f) margin dim",
+ )
+ else:
+ if encoder_hidden_states.shape[0] != hidden_states.shape[0]:
+ encoder_hidden_states = repeat(
+ encoder_hidden_states, "b n c -> (b f) n c", f=video_length
+ )
+
+ batch, _, height, weight = hidden_states.shape
+ residual = hidden_states
+
+ hidden_states = self.norm(hidden_states)
+ if not self.use_linear_projection:
+ hidden_states = self.proj_in(hidden_states)
+ inner_dim = hidden_states.shape[1]
+ hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(
+ batch, height * weight, inner_dim
+ )
+ else:
+ inner_dim = hidden_states.shape[1]
+ hidden_states = hidden_states.permute(0, 2, 3, 1).reshape(
+ batch, height * weight, inner_dim
+ )
+ hidden_states = self.proj_in(hidden_states)
+
+ # Blocks
+ motion_frames = []
+ for _, block in enumerate(self.transformer_blocks):
+ if isinstance(block, TemporalBasicTransformerBlock):
+ hidden_states, motion_frame_fea = block(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ timestep=timestep,
+ video_length=video_length,
+ )
+ motion_frames.append(motion_frame_fea)
+ else:
+ hidden_states = block(
+ hidden_states, # shape [2, 4096, 320]
+ encoder_hidden_states=encoder_hidden_states, # shape [2, 20, 640]
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ timestep=timestep,
+ video_length=video_length,
+ motion_scale=motion_scale,
+ )
+
+ # Output
+ if not self.use_linear_projection:
+ hidden_states = (
+ hidden_states.reshape(batch, height, weight, inner_dim)
+ .permute(0, 3, 1, 2)
+ .contiguous()
+ )
+ hidden_states = self.proj_out(hidden_states)
+ else:
+ hidden_states = self.proj_out(hidden_states)
+ hidden_states = (
+ hidden_states.reshape(batch, height, weight, inner_dim)
+ .permute(0, 3, 1, 2)
+ .contiguous()
+ )
+
+ output = hidden_states + residual
+
+ output = rearrange(output, "(b f) c h w -> b c f h w", f=video_length)
+ if not return_dict:
+ return (output, motion_frames)
+
+ return Transformer3DModelOutput(sample=output)
diff --git a/animation/hallo-83dd4eb/hallo/models/unet_2d_blocks.py b/animation/hallo-83dd4eb/hallo/models/unet_2d_blocks.py
new file mode 100644
index 0000000..09883d5
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/unet_2d_blocks.py
@@ -0,0 +1,1343 @@
+# pylint: disable=R0801
+# pylint: disable=W1203
+
+"""
+This file defines the 2D blocks for the UNet model in a PyTorch implementation.
+The UNet model is a popular architecture for image segmentation tasks,
+which consists of an encoder, a decoder, and a skip connection mechanism.
+The 2D blocks in this file include various types of layers, such as ResNet blocks,
+Transformer blocks, and cross-attention blocks,
+which are used to build the encoder and decoder parts of the UNet model.
+The AutoencoderTinyBlock class is a simple autoencoder block for tiny models,
+and the UNetMidBlock2D and CrossAttnDownBlock2D, DownBlock2D, CrossAttnUpBlock2D,
+and UpBlock2D classes are used for the middle and decoder parts of the UNet model.
+The classes and functions in this file provide a flexible and modular way
+to construct the UNet model for different image segmentation tasks.
+"""
+
+from typing import Any, Dict, Optional, Tuple, Union
+
+import torch
+from diffusers.models.activations import get_activation
+from diffusers.models.attention_processor import Attention
+from diffusers.models.resnet import Downsample2D, ResnetBlock2D, Upsample2D
+from diffusers.models.transformers.dual_transformer_2d import \
+ DualTransformer2DModel
+from diffusers.utils import is_torch_version, logging
+from diffusers.utils.torch_utils import apply_freeu
+from torch import nn
+
+from .transformer_2d import Transformer2DModel
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+def get_down_block(
+ down_block_type: str,
+ num_layers: int,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ add_downsample: bool,
+ resnet_eps: float,
+ resnet_act_fn: str,
+ transformer_layers_per_block: int = 1,
+ num_attention_heads: Optional[int] = None,
+ resnet_groups: Optional[int] = None,
+ cross_attention_dim: Optional[int] = None,
+ downsample_padding: Optional[int] = None,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ resnet_time_scale_shift: str = "default",
+ attention_type: str = "default",
+ attention_head_dim: Optional[int] = None,
+ dropout: float = 0.0,
+):
+ """ This function creates and returns a UpBlock2D or CrossAttnUpBlock2D object based on the given up_block_type.
+
+ Args:
+ up_block_type (str): The type of up block to create. Must be either "UpBlock2D" or "CrossAttnUpBlock2D".
+ num_layers (int): The number of layers in the ResNet block.
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels.
+ prev_output_channel (int): The number of channels in the previous output.
+ temb_channels (int): The number of channels in the token embedding.
+ add_upsample (bool): Whether to add an upsample layer after the ResNet block. Defaults to True.
+ resnet_eps (float): The epsilon value for the ResNet block. Defaults to 1e-6.
+ resnet_act_fn (str): The activation function to use in the ResNet block. Defaults to "swish".
+ resnet_groups (int): The number of groups in the ResNet block. Defaults to 32.
+ resnet_pre_norm (bool): Whether to use pre-normalization in the ResNet block. Defaults to True.
+ output_scale_factor (float): The scale factor to apply to the output. Defaults to 1.0.
+
+ Returns:
+ nn.Module: The created UpBlock2D or CrossAttnUpBlock2D object.
+ """
+ # If attn head dim is not defined, we default it to the number of heads
+ if attention_head_dim is None:
+ logger.warning("It is recommended to provide `attention_head_dim` when calling `get_down_block`.")
+ logger.warning(f"Defaulting `attention_head_dim` to {num_attention_heads}.")
+ attention_head_dim = num_attention_heads
+
+ down_block_type = (
+ down_block_type[7:]
+ if down_block_type.startswith("UNetRes")
+ else down_block_type
+ )
+ if down_block_type == "DownBlock2D":
+ return DownBlock2D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ dropout=dropout,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+
+ if down_block_type == "CrossAttnDownBlock2D":
+ if cross_attention_dim is None:
+ raise ValueError(
+ "cross_attention_dim must be specified for CrossAttnDownBlock2D"
+ )
+ return CrossAttnDownBlock2D(
+ num_layers=num_layers,
+ transformer_layers_per_block=transformer_layers_per_block,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ dropout=dropout,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ cross_attention_dim=cross_attention_dim,
+ num_attention_heads=num_attention_heads,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ attention_type=attention_type,
+ )
+ raise ValueError(f"{down_block_type} does not exist.")
+
+
+def get_up_block(
+ up_block_type: str,
+ num_layers: int,
+ in_channels: int,
+ out_channels: int,
+ prev_output_channel: int,
+ temb_channels: int,
+ add_upsample: bool,
+ resnet_eps: float,
+ resnet_act_fn: str,
+ resolution_idx: Optional[int] = None,
+ transformer_layers_per_block: int = 1,
+ num_attention_heads: Optional[int] = None,
+ resnet_groups: Optional[int] = None,
+ cross_attention_dim: Optional[int] = None,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ resnet_time_scale_shift: str = "default",
+ attention_type: str = "default",
+ attention_head_dim: Optional[int] = None,
+ dropout: float = 0.0,
+) -> nn.Module:
+ """ This function ...
+ Args:
+ Returns:
+ """
+ # If attn head dim is not defined, we default it to the number of heads
+ if attention_head_dim is None:
+ logger.warning("It is recommended to provide `attention_head_dim` when calling `get_up_block`.")
+ logger.warning(f"Defaulting `attention_head_dim` to {num_attention_heads}.")
+ attention_head_dim = num_attention_heads
+
+ up_block_type = (
+ up_block_type[7:] if up_block_type.startswith("UNetRes") else up_block_type
+ )
+ if up_block_type == "UpBlock2D":
+ return UpBlock2D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ resolution_idx=resolution_idx,
+ dropout=dropout,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ )
+ if up_block_type == "CrossAttnUpBlock2D":
+ if cross_attention_dim is None:
+ raise ValueError(
+ "cross_attention_dim must be specified for CrossAttnUpBlock2D"
+ )
+ return CrossAttnUpBlock2D(
+ num_layers=num_layers,
+ transformer_layers_per_block=transformer_layers_per_block,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ resolution_idx=resolution_idx,
+ dropout=dropout,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ cross_attention_dim=cross_attention_dim,
+ num_attention_heads=num_attention_heads,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ attention_type=attention_type,
+ )
+
+ raise ValueError(f"{up_block_type} does not exist.")
+
+
+class AutoencoderTinyBlock(nn.Module):
+ """
+ Tiny Autoencoder block used in [`AutoencoderTiny`]. It is a mini residual module consisting of plain conv + ReLU
+ blocks.
+
+ Args:
+ in_channels (`int`): The number of input channels.
+ out_channels (`int`): The number of output channels.
+ act_fn (`str`):
+ ` The activation function to use. Supported values are `"swish"`, `"mish"`, `"gelu"`, and `"relu"`.
+
+ Returns:
+ `torch.FloatTensor`: A tensor with the same shape as the input tensor, but with the number of channels equal to
+ `out_channels`.
+ """
+
+ def __init__(self, in_channels: int, out_channels: int, act_fn: str):
+ super().__init__()
+ act_fn = get_activation(act_fn)
+ self.conv = nn.Sequential(
+ nn.Conv2d(in_channels, out_channels, kernel_size=3, padding=1),
+ act_fn,
+ nn.Conv2d(out_channels, out_channels, kernel_size=3, padding=1),
+ act_fn,
+ nn.Conv2d(out_channels, out_channels, kernel_size=3, padding=1),
+ )
+ self.skip = (
+ nn.Conv2d(in_channels, out_channels, kernel_size=1, bias=False)
+ if in_channels != out_channels
+ else nn.Identity()
+ )
+ self.fuse = nn.ReLU()
+
+ def forward(self, x: torch.FloatTensor) -> torch.FloatTensor:
+ """
+ Forward pass of the AutoencoderTinyBlock class.
+
+ Parameters:
+ x (torch.FloatTensor): The input tensor to the AutoencoderTinyBlock.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the AutoencoderTinyBlock.
+ """
+ return self.fuse(self.conv(x) + self.skip(x))
+
+
+class UNetMidBlock2D(nn.Module):
+ """
+ A 2D UNet mid-block [`UNetMidBlock2D`] with multiple residual blocks and optional attention blocks.
+
+ Args:
+ in_channels (`int`): The number of input channels.
+ temb_channels (`int`): The number of temporal embedding channels.
+ dropout (`float`, *optional*, defaults to 0.0): The dropout rate.
+ num_layers (`int`, *optional*, defaults to 1): The number of residual blocks.
+ resnet_eps (`float`, *optional*, 1e-6 ): The epsilon value for the resnet blocks.
+ resnet_time_scale_shift (`str`, *optional*, defaults to `default`):
+ The type of normalization to apply to the time embeddings. This can help to improve the performance of the
+ model on tasks with long-range temporal dependencies.
+ resnet_act_fn (`str`, *optional*, defaults to `swish`): The activation function for the resnet blocks.
+ resnet_groups (`int`, *optional*, defaults to 32):
+ The number of groups to use in the group normalization layers of the resnet blocks.
+ attn_groups (`Optional[int]`, *optional*, defaults to None): The number of groups for the attention blocks.
+ resnet_pre_norm (`bool`, *optional*, defaults to `True`):
+ Whether to use pre-normalization for the resnet blocks.
+ add_attention (`bool`, *optional*, defaults to `True`): Whether to add attention blocks.
+ attention_head_dim (`int`, *optional*, defaults to 1):
+ Dimension of a single attention head. The number of attention heads is determined based on this value and
+ the number of input channels.
+ output_scale_factor (`float`, *optional*, defaults to 1.0): The output scale factor.
+
+ Returns:
+ `torch.FloatTensor`: The output of the last residual block, which is a tensor of shape `(batch_size,
+ in_channels, height, width)`.
+
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default", # default, spatial
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ attn_groups: Optional[int] = None,
+ resnet_pre_norm: bool = True,
+ add_attention: bool = True,
+ attention_head_dim: int = 1,
+ output_scale_factor: float = 1.0,
+ ):
+ super().__init__()
+ resnet_groups = (
+ resnet_groups if resnet_groups is not None else min(in_channels // 4, 32)
+ )
+ self.add_attention = add_attention
+
+ if attn_groups is None:
+ attn_groups = (
+ resnet_groups if resnet_time_scale_shift == "default" else None
+ )
+
+ # there is always at least one resnet
+ resnets = [
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ ]
+ attentions = []
+
+ if attention_head_dim is None:
+ logger.warning(
+ f"It is not recommend to pass `attention_head_dim=None`. Defaulting `attention_head_dim` to `in_channels`: {in_channels}."
+ )
+ attention_head_dim = in_channels
+
+ for _ in range(num_layers):
+ if self.add_attention:
+ attentions.append(
+ Attention(
+ in_channels,
+ heads=in_channels // attention_head_dim,
+ dim_head=attention_head_dim,
+ rescale_output_factor=output_scale_factor,
+ eps=resnet_eps,
+ norm_num_groups=attn_groups,
+ spatial_norm_dim=(
+ temb_channels
+ if resnet_time_scale_shift == "spatial"
+ else None
+ ),
+ residual_connection=True,
+ bias=True,
+ upcast_softmax=True,
+ _from_deprecated_attn_block=True,
+ )
+ )
+ else:
+ attentions.append(None)
+
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ def forward(
+ self, hidden_states: torch.FloatTensor, temb: Optional[torch.FloatTensor] = None
+ ) -> torch.FloatTensor:
+ """
+ Forward pass of the UNetMidBlock2D class.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input tensor to the UNetMidBlock2D.
+ temb (Optional[torch.FloatTensor], optional): The token embedding tensor. Defaults to None.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the UNetMidBlock2D.
+ """
+ # Your implementation here
+ hidden_states = self.resnets[0](hidden_states, temb)
+ for attn, resnet in zip(self.attentions, self.resnets[1:]):
+ if attn is not None:
+ hidden_states = attn(hidden_states, temb=temb)
+ hidden_states = resnet(hidden_states, temb)
+
+ return hidden_states
+
+
+class UNetMidBlock2DCrossAttn(nn.Module):
+ """
+ UNetMidBlock2DCrossAttn is a class that represents a mid-block 2D UNet with cross-attention.
+
+ This block is responsible for processing the input tensor with a series of residual blocks,
+ and applying cross-attention mechanism to attend to the global information in the encoder.
+
+ Args:
+ in_channels (int): The number of input channels.
+ temb_channels (int): The number of channels for the token embedding.
+ dropout (float, optional): The dropout rate. Defaults to 0.0.
+ num_layers (int, optional): The number of layers in the residual blocks. Defaults to 1.
+ resnet_eps (float, optional): The epsilon value for the residual blocks. Defaults to 1e-6.
+ resnet_time_scale_shift (str, optional): The time scale shift type for the residual blocks. Defaults to "default".
+ resnet_act_fn (str, optional): The activation function for the residual blocks. Defaults to "swish".
+ resnet_groups (int, optional): The number of groups for the residual blocks. Defaults to 32.
+ resnet_pre_norm (bool, optional): Whether to apply pre-normalization for the residual blocks. Defaults to True.
+ num_attention_heads (int, optional): The number of attention heads for cross-attention. Defaults to 1.
+ cross_attention_dim (int, optional): The dimension of the cross-attention. Defaults to 1280.
+ output_scale_factor (float, optional): The scale factor for the output tensor. Defaults to 1.0.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: Union[int, Tuple[int]] = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads: int = 1,
+ output_scale_factor: float = 1.0,
+ cross_attention_dim: int = 1280,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ upcast_attention: bool = False,
+ attention_type: str = "default",
+ ):
+ super().__init__()
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+ resnet_groups = (
+ resnet_groups if resnet_groups is not None else min(in_channels // 4, 32)
+ )
+
+ # support for variable transformer layers per block
+ if isinstance(transformer_layers_per_block, int):
+ transformer_layers_per_block = [transformer_layers_per_block] * num_layers
+
+ # there is always at least one resnet
+ resnets = [
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ ]
+ attentions = []
+
+ for i in range(num_layers):
+ if not dual_cross_attention:
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ in_channels // num_attention_heads,
+ in_channels=in_channels,
+ num_layers=transformer_layers_per_block[i],
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ attention_type=attention_type,
+ )
+ )
+ else:
+ attentions.append(
+ DualTransformer2DModel(
+ num_attention_heads,
+ in_channels // num_attention_heads,
+ in_channels=in_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ )
+ )
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ temb: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ cross_attention_kwargs: Optional[Dict[str, Any]] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Forward pass for the UNetMidBlock2DCrossAttn class.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input hidden states tensor.
+ temb (Optional[torch.FloatTensor], optional): The optional tensor for time embeddings.
+ encoder_hidden_states (Optional[torch.FloatTensor], optional): The optional encoder hidden states tensor.
+ attention_mask (Optional[torch.FloatTensor], optional): The optional attention mask tensor.
+ cross_attention_kwargs (Optional[Dict[str, Any]], optional): The optional cross-attention kwargs tensor.
+ encoder_attention_mask (Optional[torch.FloatTensor], optional): The optional encoder attention mask tensor.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the UNetMidBlock2DCrossAttn layers.
+ """
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+ hidden_states = self.resnets[0](hidden_states, temb, scale=lora_scale)
+ for attn, resnet in zip(self.attentions, self.resnets[1:]):
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ ckpt_kwargs: Dict[str, Any] = (
+ {"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
+ )
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet),
+ hidden_states,
+ temb,
+ **ckpt_kwargs,
+ )
+ else:
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+ hidden_states = resnet(hidden_states, temb, scale=lora_scale)
+
+ return hidden_states
+
+
+class CrossAttnDownBlock2D(nn.Module):
+ """
+ CrossAttnDownBlock2D is a class that represents a 2D cross-attention downsampling block.
+
+ This block is used in the UNet model and consists of a series of ResNet blocks and Transformer layers.
+ It takes input hidden states, a tensor embedding, and optional encoder hidden states, attention mask,
+ and cross-attention kwargs. The block performs a series of operations including downsampling, cross-attention,
+ and residual connections.
+
+ Attributes:
+ in_channels (int): The number of input channels.
+ out_channels (int): The number of output channels.
+ temb_channels (int): The number of tensor embedding channels.
+ dropout (float): The dropout rate.
+ num_layers (int): The number of ResNet layers.
+ transformer_layers_per_block (Union[int, Tuple[int]]): The number of Transformer layers per block.
+ resnet_eps (float): The ResNet epsilon value.
+ resnet_time_scale_shift (str): The ResNet time scale shift type.
+ resnet_act_fn (str): The ResNet activation function.
+ resnet_groups (int): The ResNet group size.
+ resnet_pre_norm (bool): Whether to use ResNet pre-normalization.
+ num_attention_heads (int): The number of attention heads.
+ cross_attention_dim (int): The cross-attention dimension.
+ output_scale_factor (float): The output scale factor.
+ downsample_padding (int): The downsampling padding.
+ add_downsample (bool): Whether to add downsampling.
+ dual_cross_attention (bool): Whether to use dual cross-attention.
+ use_linear_projection (bool): Whether to use linear projection.
+ only_cross_attention (bool): Whether to use only cross-attention.
+ upcast_attention (bool): Whether to upcast attention.
+ attention_type (str): The attention type.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: Union[int, Tuple[int]] = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads: int = 1,
+ cross_attention_dim: int = 1280,
+ output_scale_factor: float = 1.0,
+ downsample_padding: int = 1,
+ add_downsample: bool = True,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ attention_type: str = "default",
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+ if isinstance(transformer_layers_per_block, int):
+ transformer_layers_per_block = [transformer_layers_per_block] * num_layers
+
+ for i in range(num_layers):
+ in_channels = in_channels if i == 0 else out_channels
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+ if not dual_cross_attention:
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=transformer_layers_per_block[i],
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ attention_type=attention_type,
+ )
+ )
+ else:
+ attentions.append(
+ DualTransformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ )
+ )
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ Downsample2D(
+ out_channels,
+ use_conv=True,
+ out_channels=out_channels,
+ padding=downsample_padding,
+ name="op",
+ )
+ ]
+ )
+ else:
+ self.downsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ temb: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ cross_attention_kwargs: Optional[Dict[str, Any]] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ additional_residuals: Optional[torch.FloatTensor] = None,
+ ) -> Tuple[torch.FloatTensor, Tuple[torch.FloatTensor, ...]]:
+ """
+ Forward pass for the CrossAttnDownBlock2D class.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input hidden states.
+ temb (Optional[torch.FloatTensor], optional): The token embeddings. Defaults to None.
+ encoder_hidden_states (Optional[torch.FloatTensor], optional): The encoder hidden states. Defaults to None.
+ attention_mask (Optional[torch.FloatTensor], optional): The attention mask. Defaults to None.
+ cross_attention_kwargs (Optional[Dict[str, Any]], optional): The cross-attention kwargs. Defaults to None.
+ encoder_attention_mask (Optional[torch.FloatTensor], optional): The encoder attention mask. Defaults to None.
+ additional_residuals (Optional[torch.FloatTensor], optional): The additional residuals. Defaults to None.
+
+ Returns:
+ Tuple[torch.FloatTensor, Tuple[torch.FloatTensor, ...]]: The output hidden states and residuals.
+ """
+ output_states = ()
+
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+
+ blocks = list(zip(self.resnets, self.attentions))
+
+ for i, (resnet, attn) in enumerate(blocks):
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ ckpt_kwargs: Dict[str, Any] = (
+ {"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
+ )
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet),
+ hidden_states,
+ temb,
+ **ckpt_kwargs,
+ )
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, scale=lora_scale)
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+
+ # apply additional residuals to the output of the last pair of resnet and attention blocks
+ if i == len(blocks) - 1 and additional_residuals is not None:
+ hidden_states = hidden_states + additional_residuals
+
+ output_states = output_states + (hidden_states,)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states, scale=lora_scale)
+
+ output_states = output_states + (hidden_states,)
+
+ return hidden_states, output_states
+
+
+class DownBlock2D(nn.Module):
+ """
+ DownBlock2D is a class that represents a 2D downsampling block in a neural network.
+
+ It takes the following parameters:
+ - in_channels (int): The number of input channels in the block.
+ - out_channels (int): The number of output channels in the block.
+ - temb_channels (int): The number of channels in the token embedding.
+ - dropout (float): The dropout rate for the block.
+ - num_layers (int): The number of layers in the block.
+ - resnet_eps (float): The epsilon value for the ResNet layer.
+ - resnet_time_scale_shift (str): The type of activation function for the ResNet layer.
+ - resnet_act_fn (str): The activation function for the ResNet layer.
+ - resnet_groups (int): The number of groups in the ResNet layer.
+ - resnet_pre_norm (bool): Whether to apply layer normalization before the ResNet layer.
+ - output_scale_factor (float): The scale factor for the output.
+ - add_downsample (bool): Whether to add a downsampling layer.
+ - downsample_padding (int): The padding value for the downsampling layer.
+
+ The DownBlock2D class inherits from the nn.Module class and defines the following methods:
+ - __init__: Initializes the DownBlock2D class with the given parameters.
+ - forward: Forward pass of the DownBlock2D class.
+
+ The forward method takes the following parameters:
+ - hidden_states (torch.FloatTensor): The input tensor to the block.
+ - temb (Optional[torch.FloatTensor]): The token embedding tensor.
+ - scale (float): The scale factor for the input tensor.
+
+ The forward method returns a tuple containing the output tensor and a tuple of hidden states.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ output_scale_factor: float = 1.0,
+ add_downsample: bool = True,
+ downsample_padding: int = 1,
+ ):
+ super().__init__()
+ resnets = []
+
+ for i in range(num_layers):
+ in_channels = in_channels if i == 0 else out_channels
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ Downsample2D(
+ out_channels,
+ use_conv=True,
+ out_channels=out_channels,
+ padding=downsample_padding,
+ name="op",
+ )
+ ]
+ )
+ else:
+ self.downsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ temb: Optional[torch.FloatTensor] = None,
+ scale: float = 1.0,
+ ) -> Tuple[torch.FloatTensor, Tuple[torch.FloatTensor, ...]]:
+ """
+ Forward pass of the DownBlock2D class.
+
+ Args:
+ hidden_states (torch.FloatTensor): The input tensor to the DownBlock2D layer.
+ temb (Optional[torch.FloatTensor], optional): The token embedding tensor. Defaults to None.
+ scale (float, optional): The scale factor for the input tensor. Defaults to 1.0.
+
+ Returns:
+ Tuple[torch.FloatTensor, Tuple[torch.FloatTensor, ...]]: The output tensor and any additional hidden states.
+ """
+ output_states = ()
+
+ for resnet in self.resnets:
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ if is_torch_version(">=", "1.11.0"):
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet),
+ hidden_states,
+ temb,
+ use_reentrant=False,
+ )
+ else:
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, scale=scale)
+
+ output_states = output_states + (hidden_states,)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states, scale=scale)
+
+ output_states = output_states + (hidden_states,)
+
+ return hidden_states, output_states
+
+
+class CrossAttnUpBlock2D(nn.Module):
+ """
+ CrossAttnUpBlock2D is a class that represents a cross-attention UpBlock in a 2D UNet architecture.
+
+ This block is responsible for upsampling the input tensor and performing cross-attention with the encoder's hidden states.
+
+ Args:
+ in_channels (int): The number of input channels in the tensor.
+ out_channels (int): The number of output channels in the tensor.
+ prev_output_channel (int): The number of channels in the previous output tensor.
+ temb_channels (int): The number of channels in the token embedding tensor.
+ resolution_idx (Optional[int]): The index of the resolution in the model.
+ dropout (float): The dropout rate for the layer.
+ num_layers (int): The number of layers in the ResNet block.
+ transformer_layers_per_block (Union[int, Tuple[int]]): The number of transformer layers per block.
+ resnet_eps (float): The epsilon value for the ResNet layer.
+ resnet_time_scale_shift (str): The type of time scale shift to be applied in the ResNet layer.
+ resnet_act_fn (str): The activation function to be used in the ResNet layer.
+ resnet_groups (int): The number of groups in the ResNet layer.
+ resnet_pre_norm (bool): Whether to use pre-normalization in the ResNet layer.
+ num_attention_heads (int): The number of attention heads in the cross-attention layer.
+ cross_attention_dim (int): The dimension of the cross-attention layer.
+ output_scale_factor (float): The scale factor for the output tensor.
+ add_upsample (bool): Whether to add upsampling to the block.
+ dual_cross_attention (bool): Whether to use dual cross-attention.
+ use_linear_projection (bool): Whether to use linear projection in the cross-attention layer.
+ only_cross_attention (bool): Whether to only use cross-attention and no self-attention.
+ upcast_attention (bool): Whether to upcast the attention weights.
+ attention_type (str): The type of attention to be used in the cross-attention layer.
+
+ Attributes:
+ up_block (nn.Module): The UpBlock module responsible for upsampling the input tensor.
+ cross_attn (nn.Module): The cross-attention module that performs attention between
+ the decoder's hidden states and the encoder's hidden states.
+ resnet_blocks (nn.ModuleList): A list of ResNet blocks that make up the ResNet portion of the block.
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ prev_output_channel: int,
+ temb_channels: int,
+ resolution_idx: Optional[int] = None,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ transformer_layers_per_block: Union[int, Tuple[int]] = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ num_attention_heads: int = 1,
+ cross_attention_dim: int = 1280,
+ output_scale_factor: float = 1.0,
+ add_upsample: bool = True,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ only_cross_attention: bool = False,
+ upcast_attention: bool = False,
+ attention_type: str = "default",
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+
+ self.has_cross_attention = True
+ self.num_attention_heads = num_attention_heads
+
+ if isinstance(transformer_layers_per_block, int):
+ transformer_layers_per_block = [transformer_layers_per_block] * num_layers
+
+ for i in range(num_layers):
+ res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
+ resnet_in_channels = prev_output_channel if i == 0 else out_channels
+
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=resnet_in_channels + res_skip_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+ if not dual_cross_attention:
+ attentions.append(
+ Transformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=transformer_layers_per_block[i],
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ attention_type=attention_type,
+ )
+ )
+ else:
+ attentions.append(
+ DualTransformer2DModel(
+ num_attention_heads,
+ out_channels // num_attention_heads,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ )
+ )
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList(
+ [Upsample2D(out_channels, use_conv=True, out_channels=out_channels)]
+ )
+ else:
+ self.upsamplers = None
+
+ self.gradient_checkpointing = False
+ self.resolution_idx = resolution_idx
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ res_hidden_states_tuple: Tuple[torch.FloatTensor, ...],
+ temb: Optional[torch.FloatTensor] = None,
+ encoder_hidden_states: Optional[torch.FloatTensor] = None,
+ cross_attention_kwargs: Optional[Dict[str, Any]] = None,
+ upsample_size: Optional[int] = None,
+ attention_mask: Optional[torch.FloatTensor] = None,
+ encoder_attention_mask: Optional[torch.FloatTensor] = None,
+ ) -> torch.FloatTensor:
+ """
+ Forward pass for the CrossAttnUpBlock2D class.
+
+ Args:
+ self (CrossAttnUpBlock2D): An instance of the CrossAttnUpBlock2D class.
+ hidden_states (torch.FloatTensor): The input hidden states tensor.
+ res_hidden_states_tuple (Tuple[torch.FloatTensor, ...]): A tuple of residual hidden states tensors.
+ temb (Optional[torch.FloatTensor], optional): The token embeddings tensor. Defaults to None.
+ encoder_hidden_states (Optional[torch.FloatTensor], optional): The encoder hidden states tensor. Defaults to None.
+ cross_attention_kwargs (Optional[Dict[str, Any]], optional): Additional keyword arguments for cross attention. Defaults to None.
+ upsample_size (Optional[int], optional): The upsample size. Defaults to None.
+ attention_mask (Optional[torch.FloatTensor], optional): The attention mask tensor. Defaults to None.
+ encoder_attention_mask (Optional[torch.FloatTensor], optional): The encoder attention mask tensor. Defaults to None.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the block.
+ """
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+ is_freeu_enabled = (
+ getattr(self, "s1", None)
+ and getattr(self, "s2", None)
+ and getattr(self, "b1", None)
+ and getattr(self, "b2", None)
+ )
+
+ for resnet, attn in zip(self.resnets, self.attentions):
+ # pop res hidden states
+ res_hidden_states = res_hidden_states_tuple[-1]
+ res_hidden_states_tuple = res_hidden_states_tuple[:-1]
+
+ # FreeU: Only operate on the first two stages
+ if is_freeu_enabled:
+ hidden_states, res_hidden_states = apply_freeu(
+ self.resolution_idx,
+ hidden_states,
+ res_hidden_states,
+ s1=self.s1,
+ s2=self.s2,
+ b1=self.b1,
+ b2=self.b2,
+ )
+
+ hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
+
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ ckpt_kwargs: Dict[str, Any] = (
+ {"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
+ )
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet),
+ hidden_states,
+ temb,
+ **ckpt_kwargs,
+ )
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, scale=lora_scale)
+ hidden_states, _ref_feature = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ return_dict=False,
+ )
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(
+ hidden_states, upsample_size, scale=lora_scale
+ )
+
+ return hidden_states
+
+
+class UpBlock2D(nn.Module):
+ """
+ UpBlock2D is a class that represents a 2D upsampling block in a neural network.
+
+ This block is used for upsampling the input tensor by a factor of 2 in both dimensions.
+ It takes the previous output channel, input channels, and output channels as input
+ and applies a series of convolutional layers, batch normalization, and activation
+ functions to produce the upsampled tensor.
+
+ Args:
+ in_channels (int): The number of input channels in the tensor.
+ prev_output_channel (int): The number of channels in the previous output tensor.
+ out_channels (int): The number of output channels in the tensor.
+ temb_channels (int): The number of channels in the time embedding tensor.
+ resolution_idx (Optional[int], optional): The index of the resolution in the sequence of resolutions. Defaults to None.
+ dropout (float, optional): The dropout rate to be applied to the convolutional layers. Defaults to 0.0.
+ num_layers (int, optional): The number of convolutional layers in the block. Defaults to 1.
+ resnet_eps (float, optional): The epsilon value used in the batch normalization layer. Defaults to 1e-6.
+ resnet_time_scale_shift (str, optional): The type of activation function to be applied after the convolutional layers. Defaults to "default".
+ resnet_act_fn (str, optional): The activation function to be applied after the batch normalization layer. Defaults to "swish".
+ resnet_groups (int, optional): The number of groups in the group normalization layer. Defaults to 32.
+ resnet_pre_norm (bool, optional): A flag indicating whether to apply layer normalization before the activation function. Defaults to True.
+ output_scale_factor (float, optional): The scale factor to be applied to the output tensor. Defaults to 1.0.
+ add_upsample (bool, optional): A flag indicating whether to add an upsampling layer to the block. Defaults to True.
+
+ Attributes:
+ layers (nn.ModuleList): A list of nn.Module objects representing the convolutional layers in the block.
+ upsample (nn.Module): The upsampling layer in the block, if add_upsample is True.
+
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ prev_output_channel: int,
+ out_channels: int,
+ temb_channels: int,
+ resolution_idx: Optional[int] = None,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ output_scale_factor: float = 1.0,
+ add_upsample: bool = True,
+ ):
+ super().__init__()
+ resnets = []
+
+ for i in range(num_layers):
+ res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
+ resnet_in_channels = prev_output_channel if i == 0 else out_channels
+
+ resnets.append(
+ ResnetBlock2D(
+ in_channels=resnet_in_channels + res_skip_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ )
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList(
+ [Upsample2D(out_channels, use_conv=True, out_channels=out_channels)]
+ )
+ else:
+ self.upsamplers = None
+
+ self.gradient_checkpointing = False
+ self.resolution_idx = resolution_idx
+
+ def forward(
+ self,
+ hidden_states: torch.FloatTensor,
+ res_hidden_states_tuple: Tuple[torch.FloatTensor, ...],
+ temb: Optional[torch.FloatTensor] = None,
+ upsample_size: Optional[int] = None,
+ scale: float = 1.0,
+ ) -> torch.FloatTensor:
+
+ """
+ Forward pass for the UpBlock2D class.
+
+ Args:
+ self (UpBlock2D): An instance of the UpBlock2D class.
+ hidden_states (torch.FloatTensor): The input tensor to the block.
+ res_hidden_states_tuple (Tuple[torch.FloatTensor, ...]): A tuple of residual hidden states.
+ temb (Optional[torch.FloatTensor], optional): The token embeddings. Defaults to None.
+ upsample_size (Optional[int], optional): The size to upsample the input tensor to. Defaults to None.
+ scale (float, optional): The scale factor to apply to the input tensor. Defaults to 1.0.
+
+ Returns:
+ torch.FloatTensor: The output tensor after passing through the block.
+ """
+ is_freeu_enabled = (
+ getattr(self, "s1", None)
+ and getattr(self, "s2", None)
+ and getattr(self, "b1", None)
+ and getattr(self, "b2", None)
+ )
+
+ for resnet in self.resnets:
+ # pop res hidden states
+ res_hidden_states = res_hidden_states_tuple[-1]
+ res_hidden_states_tuple = res_hidden_states_tuple[:-1]
+
+ # FreeU: Only operate on the first two stages
+ if is_freeu_enabled:
+ hidden_states, res_hidden_states = apply_freeu(
+ self.resolution_idx,
+ hidden_states,
+ res_hidden_states,
+ s1=self.s1,
+ s2=self.s2,
+ b1=self.b1,
+ b2=self.b2,
+ )
+
+ hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
+
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ if is_torch_version(">=", "1.11.0"):
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet),
+ hidden_states,
+ temb,
+ use_reentrant=False,
+ )
+ else:
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, scale=scale)
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(hidden_states, upsample_size, scale=scale)
+
+ return hidden_states
diff --git a/animation/hallo-83dd4eb/hallo/models/unet_2d_condition.py b/animation/hallo-83dd4eb/hallo/models/unet_2d_condition.py
new file mode 100644
index 0000000..590e8db
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/unet_2d_condition.py
@@ -0,0 +1,1432 @@
+# pylint: disable=R0801
+# pylint: disable=E1101
+# pylint: disable=W1203
+
+"""
+This module implements the `UNet2DConditionModel`,
+a variant of the 2D U-Net architecture designed for conditional image generation tasks.
+The model is capable of taking a noisy input sample and conditioning it based on additional information such as class labels,
+time steps, and encoder hidden states to produce a denoised output.
+
+The `UNet2DConditionModel` leverages various components such as time embeddings,
+class embeddings, and cross-attention mechanisms to integrate the conditioning information effectively.
+It is built upon several sub-blocks including down-blocks, a middle block, and up-blocks,
+each responsible for different stages of the U-Net's downsampling and upsampling process.
+
+Key Features:
+- Support for multiple types of down and up blocks, including those with cross-attention capabilities.
+- Flexible configuration of the model's layers, including the number of layers per block and the output channels for each block.
+- Integration of time embeddings and class embeddings to condition the model's output on additional information.
+- Implementation of cross-attention to leverage encoder hidden states for conditional generation.
+- The model supports gradient checkpointing to reduce memory usage during training.
+
+The module also includes utility functions and classes such as `UNet2DConditionOutput` for structured output
+and `load_change_cross_attention_dim` for loading and modifying pre-trained models.
+
+Example Usage:
+>>> import torch
+>>> from unet_2d_condition_model import UNet2DConditionModel
+>>> model = UNet2DConditionModel(
+... sample_size=(64, 64),
+... in_channels=3,
+... out_channels=3,
+... encoder_hid_dim=512,
+... cross_attention_dim=1024,
+... )
+>>> # Prepare input tensors
+>>> sample = torch.randn(1, 3, 64, 64)
+>>> timestep = 0
+>>> encoder_hidden_states = torch.randn(1, 14, 512)
+>>> # Forward pass through the model
+>>> output = model(sample, timestep, encoder_hidden_states)
+
+This module is part of a larger ecosystem of diffusion models and can be used for various conditional image generation tasks.
+"""
+
+from dataclasses import dataclass
+from os import PathLike
+from pathlib import Path
+from typing import Any, Dict, List, Optional, Tuple, Union
+
+import torch
+import torch.utils.checkpoint
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+from diffusers.loaders import UNet2DConditionLoadersMixin
+from diffusers.models.activations import get_activation
+from diffusers.models.attention_processor import (
+ ADDED_KV_ATTENTION_PROCESSORS, CROSS_ATTENTION_PROCESSORS,
+ AttentionProcessor, AttnAddedKVProcessor, AttnProcessor)
+from diffusers.models.embeddings import (GaussianFourierProjection,
+ GLIGENTextBoundingboxProjection,
+ ImageHintTimeEmbedding,
+ ImageProjection, ImageTimeEmbedding,
+ TextImageProjection,
+ TextImageTimeEmbedding,
+ TextTimeEmbedding, TimestepEmbedding,
+ Timesteps)
+from diffusers.models.modeling_utils import ModelMixin
+from diffusers.utils import (SAFETENSORS_WEIGHTS_NAME, USE_PEFT_BACKEND,
+ WEIGHTS_NAME, BaseOutput, deprecate, logging,
+ scale_lora_layers, unscale_lora_layers)
+from safetensors.torch import load_file
+from torch import nn
+
+from .unet_2d_blocks import (UNetMidBlock2D, UNetMidBlock2DCrossAttn,
+ get_down_block, get_up_block)
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+@dataclass
+class UNet2DConditionOutput(BaseOutput):
+ """
+ The output of [`UNet2DConditionModel`].
+
+ Args:
+ sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)`):
+ The hidden states output conditioned on `encoder_hidden_states` input. Output of last layer of model.
+ """
+
+ sample: torch.FloatTensor = None
+ ref_features: Tuple[torch.FloatTensor] = None
+
+
+class UNet2DConditionModel(ModelMixin, ConfigMixin, UNet2DConditionLoadersMixin):
+ r"""
+ A conditional 2D UNet model that takes a noisy sample, conditional state, and a timestep and returns a sample
+ shaped output.
+
+ This model inherits from [`ModelMixin`]. Check the superclass documentation for it's generic methods implemented
+ for all models (such as downloading or saving).
+
+ Parameters:
+ sample_size (`int` or `Tuple[int, int]`, *optional*, defaults to `None`):
+ Height and width of input/output sample.
+ in_channels (`int`, *optional*, defaults to 4): Number of channels in the input sample.
+ out_channels (`int`, *optional*, defaults to 4): Number of channels in the output.
+ center_input_sample (`bool`, *optional*, defaults to `False`): Whether to center the input sample.
+ flip_sin_to_cos (`bool`, *optional*, defaults to `False`):
+ Whether to flip the sin to cos in the time embedding.
+ freq_shift (`int`, *optional*, defaults to 0): The frequency shift to apply to the time embedding.
+ down_block_types (`Tuple[str]`, *optional*, defaults to
+ `("CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "CrossAttnDownBlock2D", "DownBlock2D")`):
+ The tuple of downsample blocks to use.
+ mid_block_type (`str`, *optional*, defaults to `"UNetMidBlock2DCrossAttn"`):
+ Block type for middle of UNet, it can be one of `UNetMidBlock2DCrossAttn`, `UNetMidBlock2D`, or
+ `UNetMidBlock2DSimpleCrossAttn`. If `None`, the mid block layer is skipped.
+ up_block_types (`Tuple[str]`, *optional*, defaults to `("UpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D", "CrossAttnUpBlock2D")`):
+ The tuple of upsample blocks to use.
+ only_cross_attention(`bool` or `Tuple[bool]`, *optional*, default to `False`):
+ Whether to include self-attention in the basic transformer blocks, see
+ [`~models.attention.BasicTransformerBlock`].
+ block_out_channels (`Tuple[int]`, *optional*, defaults to `(320, 640, 1280, 1280)`):
+ The tuple of output channels for each block.
+ layers_per_block (`int`, *optional*, defaults to 2): The number of layers per block.
+ downsample_padding (`int`, *optional*, defaults to 1): The padding to use for the downsampling convolution.
+ mid_block_scale_factor (`float`, *optional*, defaults to 1.0): The scale factor to use for the mid block.
+ dropout (`float`, *optional*, defaults to 0.0): The dropout probability to use.
+ act_fn (`str`, *optional*, defaults to `"silu"`): The activation function to use.
+ norm_num_groups (`int`, *optional*, defaults to 32): The number of groups to use for the normalization.
+ If `None`, normalization and activation layers is skipped in post-processing.
+ norm_eps (`float`, *optional*, defaults to 1e-5): The epsilon to use for the normalization.
+ cross_attention_dim (`int` or `Tuple[int]`, *optional*, defaults to 1280):
+ The dimension of the cross attention features.
+ transformer_layers_per_block (`int`, `Tuple[int]`, or `Tuple[Tuple]` , *optional*, defaults to 1):
+ The number of transformer blocks of type [`~models.attention.BasicTransformerBlock`]. Only relevant for
+ [`~models.unet_2d_blocks.CrossAttnDownBlock2D`], [`~models.unet_2d_blocks.CrossAttnUpBlock2D`],
+ [`~models.unet_2d_blocks.UNetMidBlock2DCrossAttn`].
+ reverse_transformer_layers_per_block : (`Tuple[Tuple]`, *optional*, defaults to None):
+ The number of transformer blocks of type [`~models.attention.BasicTransformerBlock`], in the upsampling
+ blocks of the U-Net. Only relevant if `transformer_layers_per_block` is of type `Tuple[Tuple]` and for
+ [`~models.unet_2d_blocks.CrossAttnDownBlock2D`], [`~models.unet_2d_blocks.CrossAttnUpBlock2D`],
+ [`~models.unet_2d_blocks.UNetMidBlock2DCrossAttn`].
+ encoder_hid_dim (`int`, *optional*, defaults to None):
+ If `encoder_hid_dim_type` is defined, `encoder_hidden_states` will be projected from `encoder_hid_dim`
+ dimension to `cross_attention_dim`.
+ encoder_hid_dim_type (`str`, *optional*, defaults to `None`):
+ If given, the `encoder_hidden_states` and potentially other embeddings are down-projected to text
+ embeddings of dimension `cross_attention` according to `encoder_hid_dim_type`.
+ attention_head_dim (`int`, *optional*, defaults to 8): The dimension of the attention heads.
+ num_attention_heads (`int`, *optional*):
+ The number of attention heads. If not defined, defaults to `attention_head_dim`
+ resnet_time_scale_shift (`str`, *optional*, defaults to `"default"`): Time scale shift config
+ for ResNet blocks (see [`~models.resnet.ResnetBlock2D`]). Choose from `default` or `scale_shift`.
+ class_embed_type (`str`, *optional*, defaults to `None`):
+ The type of class embedding to use which is ultimately summed with the time embeddings. Choose from `None`,
+ `"timestep"`, `"identity"`, `"projection"`, or `"simple_projection"`.
+ addition_embed_type (`str`, *optional*, defaults to `None`):
+ Configures an optional embedding which will be summed with the time embeddings. Choose from `None` or
+ "text". "text" will use the `TextTimeEmbedding` layer.
+ addition_time_embed_dim: (`int`, *optional*, defaults to `None`):
+ Dimension for the timestep embeddings.
+ num_class_embeds (`int`, *optional*, defaults to `None`):
+ Input dimension of the learnable embedding matrix to be projected to `time_embed_dim`, when performing
+ class conditioning with `class_embed_type` equal to `None`.
+ time_embedding_type (`str`, *optional*, defaults to `positional`):
+ The type of position embedding to use for timesteps. Choose from `positional` or `fourier`.
+ time_embedding_dim (`int`, *optional*, defaults to `None`):
+ An optional override for the dimension of the projected time embedding.
+ time_embedding_act_fn (`str`, *optional*, defaults to `None`):
+ Optional activation function to use only once on the time embeddings before they are passed to the rest of
+ the UNet. Choose from `silu`, `mish`, `gelu`, and `swish`.
+ timestep_post_act (`str`, *optional*, defaults to `None`):
+ The second activation function to use in timestep embedding. Choose from `silu`, `mish` and `gelu`.
+ time_cond_proj_dim (`int`, *optional*, defaults to `None`):
+ The dimension of `cond_proj` layer in the timestep embedding.
+ conv_in_kernel (`int`, *optional*, default to `3`): The kernel size of `conv_in` layer. conv_out_kernel (`int`,
+ *optional*, default to `3`): The kernel size of `conv_out` layer. projection_class_embeddings_input_dim (`int`,
+ *optional*): The dimension of the `class_labels` input when
+ `class_embed_type="projection"`. Required when `class_embed_type="projection"`.
+ class_embeddings_concat (`bool`, *optional*, defaults to `False`): Whether to concatenate the time
+ embeddings with the class embeddings.
+ mid_block_only_cross_attention (`bool`, *optional*, defaults to `None`):
+ Whether to use cross attention with the mid block when using the `UNetMidBlock2DSimpleCrossAttn`. If
+ `only_cross_attention` is given as a single boolean and `mid_block_only_cross_attention` is `None`, the
+ `only_cross_attention` value is used as the value for `mid_block_only_cross_attention`. Default to `False`
+ otherwise.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ sample_size: Optional[int] = None,
+ in_channels: int = 4,
+ _out_channels: int = 4,
+ _center_input_sample: bool = False,
+ flip_sin_to_cos: bool = True,
+ freq_shift: int = 0,
+ down_block_types: Tuple[str] = (
+ "CrossAttnDownBlock2D",
+ "CrossAttnDownBlock2D",
+ "CrossAttnDownBlock2D",
+ "DownBlock2D",
+ ),
+ mid_block_type: Optional[str] = "UNetMidBlock2DCrossAttn",
+ up_block_types: Tuple[str] = (
+ "UpBlock2D",
+ "CrossAttnUpBlock2D",
+ "CrossAttnUpBlock2D",
+ "CrossAttnUpBlock2D",
+ ),
+ only_cross_attention: Union[bool, Tuple[bool]] = False,
+ block_out_channels: Tuple[int] = (320, 640, 1280, 1280),
+ layers_per_block: Union[int, Tuple[int]] = 2,
+ downsample_padding: int = 1,
+ mid_block_scale_factor: float = 1,
+ dropout: float = 0.0,
+ act_fn: str = "silu",
+ norm_num_groups: Optional[int] = 32,
+ norm_eps: float = 1e-5,
+ cross_attention_dim: Union[int, Tuple[int]] = 1280,
+ transformer_layers_per_block: Union[int, Tuple[int], Tuple[Tuple]] = 1,
+ reverse_transformer_layers_per_block: Optional[Tuple[Tuple[int]]] = None,
+ encoder_hid_dim: Optional[int] = None,
+ encoder_hid_dim_type: Optional[str] = None,
+ attention_head_dim: Union[int, Tuple[int]] = 8,
+ num_attention_heads: Optional[Union[int, Tuple[int]]] = None,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ class_embed_type: Optional[str] = None,
+ addition_embed_type: Optional[str] = None,
+ addition_time_embed_dim: Optional[int] = None,
+ num_class_embeds: Optional[int] = None,
+ upcast_attention: bool = False,
+ resnet_time_scale_shift: str = "default",
+ time_embedding_type: str = "positional",
+ time_embedding_dim: Optional[int] = None,
+ time_embedding_act_fn: Optional[str] = None,
+ timestep_post_act: Optional[str] = None,
+ time_cond_proj_dim: Optional[int] = None,
+ conv_in_kernel: int = 3,
+ projection_class_embeddings_input_dim: Optional[int] = None,
+ attention_type: str = "default",
+ class_embeddings_concat: bool = False,
+ mid_block_only_cross_attention: Optional[bool] = None,
+ addition_embed_type_num_heads=64,
+ _landmark_net=False,
+ ):
+ super().__init__()
+
+ self.sample_size = sample_size
+
+ if num_attention_heads is not None:
+ raise ValueError(
+ "At the moment it is not possible to define the number of attention heads via `num_attention_heads`"
+ "because of a naming issue as described in https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131."
+ "Passing `num_attention_heads` will only be supported in diffusers v0.19."
+ )
+
+ # If `num_attention_heads` is not defined (which is the case for most models)
+ # it will default to `attention_head_dim`. This looks weird upon first reading it and it is.
+ # The reason for this behavior is to correct for incorrectly named variables that were introduced
+ # when this library was created. The incorrect naming was only discovered much later in
+ # https://github.com/huggingface/diffusers/issues/2011#issuecomment-1547958131
+ # Changing `attention_head_dim` to `num_attention_heads` for 40,000+ configurations is too backwards breaking
+ # which is why we correct for the naming here.
+ num_attention_heads = num_attention_heads or attention_head_dim
+
+ # Check inputs
+ if len(down_block_types) != len(up_block_types):
+ raise ValueError(
+ "Must provide the same number of `down_block_types` as `up_block_types`."
+ f"`down_block_types`: {down_block_types}. `up_block_types`: {up_block_types}."
+ )
+
+ if len(block_out_channels) != len(down_block_types):
+ raise ValueError(
+ "Must provide the same number of `block_out_channels` as `down_block_types`."
+ f"`block_out_channels`: {block_out_channels}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(only_cross_attention, bool) and len(
+ only_cross_attention
+ ) != len(down_block_types):
+ raise ValueError(
+ "Must provide the same number of `only_cross_attention` as `down_block_types`."
+ f"`only_cross_attention`: {only_cross_attention}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(num_attention_heads, int) and len(num_attention_heads) != len(
+ down_block_types
+ ):
+ raise ValueError(
+ "Must provide the same number of `num_attention_heads` as `down_block_types`."
+ f"`num_attention_heads`: {num_attention_heads}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(attention_head_dim, int) and len(attention_head_dim) != len(
+ down_block_types
+ ):
+ raise ValueError(
+ "Must provide the same number of `attention_head_dim` as `down_block_types`."
+ f"`attention_head_dim`: {attention_head_dim}. `down_block_types`: {down_block_types}."
+ )
+
+ if isinstance(cross_attention_dim, list) and len(cross_attention_dim) != len(
+ down_block_types
+ ):
+ raise ValueError(
+ "Must provide the same number of `cross_attention_dim` as `down_block_types`."
+ f"`cross_attention_dim`: {cross_attention_dim}. `down_block_types`: {down_block_types}."
+ )
+
+ if not isinstance(layers_per_block, int) and len(layers_per_block) != len(
+ down_block_types
+ ):
+ raise ValueError(
+ "Must provide the same number of `layers_per_block` as `down_block_types`."
+ f"`layers_per_block`: {layers_per_block}. `down_block_types`: {down_block_types}."
+ )
+ if (
+ isinstance(transformer_layers_per_block, list)
+ and reverse_transformer_layers_per_block is None
+ ):
+ for layer_number_per_block in transformer_layers_per_block:
+ if isinstance(layer_number_per_block, list):
+ raise ValueError(
+ "Must provide 'reverse_transformer_layers_per_block` if using asymmetrical UNet."
+ )
+
+ # input
+ conv_in_padding = (conv_in_kernel - 1) // 2
+ self.conv_in = nn.Conv2d(
+ in_channels,
+ block_out_channels[0],
+ kernel_size=conv_in_kernel,
+ padding=conv_in_padding,
+ )
+
+ # time
+ if time_embedding_type == "fourier":
+ time_embed_dim = time_embedding_dim or block_out_channels[0] * 2
+ if time_embed_dim % 2 != 0:
+ raise ValueError(
+ f"`time_embed_dim` should be divisible by 2, but is {time_embed_dim}."
+ )
+ self.time_proj = GaussianFourierProjection(
+ time_embed_dim // 2,
+ set_W_to_weight=False,
+ log=False,
+ flip_sin_to_cos=flip_sin_to_cos,
+ )
+ timestep_input_dim = time_embed_dim
+ elif time_embedding_type == "positional":
+ time_embed_dim = time_embedding_dim or block_out_channels[0] * 4
+
+ self.time_proj = Timesteps(
+ block_out_channels[0], flip_sin_to_cos, freq_shift
+ )
+ timestep_input_dim = block_out_channels[0]
+ else:
+ raise ValueError(
+ f"{time_embedding_type} does not exist. Please make sure to use one of `fourier` or `positional`."
+ )
+
+ self.time_embedding = TimestepEmbedding(
+ timestep_input_dim,
+ time_embed_dim,
+ act_fn=act_fn,
+ post_act_fn=timestep_post_act,
+ cond_proj_dim=time_cond_proj_dim,
+ )
+
+ if encoder_hid_dim_type is None and encoder_hid_dim is not None:
+ encoder_hid_dim_type = "text_proj"
+ self.register_to_config(encoder_hid_dim_type=encoder_hid_dim_type)
+ logger.info(
+ "encoder_hid_dim_type defaults to 'text_proj' as `encoder_hid_dim` is defined."
+ )
+
+ if encoder_hid_dim is None and encoder_hid_dim_type is not None:
+ raise ValueError(
+ f"`encoder_hid_dim` has to be defined when `encoder_hid_dim_type` is set to {encoder_hid_dim_type}."
+ )
+
+ if encoder_hid_dim_type == "text_proj":
+ self.encoder_hid_proj = nn.Linear(
+ encoder_hid_dim, cross_attention_dim)
+ elif encoder_hid_dim_type == "text_image_proj":
+ # image_embed_dim DOESN'T have to be `cross_attention_dim`. To not clutter the __init__ too much
+ # they are set to `cross_attention_dim` here as this is exactly the required dimension for the currently only use
+ # case when `addition_embed_type == "text_image_proj"` (Kadinsky 2.1)`
+ self.encoder_hid_proj = TextImageProjection(
+ text_embed_dim=encoder_hid_dim,
+ image_embed_dim=cross_attention_dim,
+ cross_attention_dim=cross_attention_dim,
+ )
+ elif encoder_hid_dim_type == "image_proj":
+ # Kandinsky 2.2
+ self.encoder_hid_proj = ImageProjection(
+ image_embed_dim=encoder_hid_dim,
+ cross_attention_dim=cross_attention_dim,
+ )
+ elif encoder_hid_dim_type is not None:
+ raise ValueError(
+ f"encoder_hid_dim_type: {encoder_hid_dim_type} must be None, 'text_proj' or 'text_image_proj'."
+ )
+ else:
+ self.encoder_hid_proj = None
+
+ # class embedding
+ if class_embed_type is None and num_class_embeds is not None:
+ self.class_embedding = nn.Embedding(
+ num_class_embeds, time_embed_dim)
+ elif class_embed_type == "timestep":
+ self.class_embedding = TimestepEmbedding(
+ timestep_input_dim, time_embed_dim, act_fn=act_fn
+ )
+ elif class_embed_type == "identity":
+ self.class_embedding = nn.Identity(time_embed_dim, time_embed_dim)
+ elif class_embed_type == "projection":
+ if projection_class_embeddings_input_dim is None:
+ raise ValueError(
+ "`class_embed_type`: 'projection' requires `projection_class_embeddings_input_dim` be set"
+ )
+ # The projection `class_embed_type` is the same as the timestep `class_embed_type` except
+ # 1. the `class_labels` inputs are not first converted to sinusoidal embeddings
+ # 2. it projects from an arbitrary input dimension.
+ #
+ # Note that `TimestepEmbedding` is quite general, being mainly linear layers and activations.
+ # When used for embedding actual timesteps, the timesteps are first converted to sinusoidal embeddings.
+ # As a result, `TimestepEmbedding` can be passed arbitrary vectors.
+ self.class_embedding = TimestepEmbedding(
+ projection_class_embeddings_input_dim, time_embed_dim
+ )
+ elif class_embed_type == "simple_projection":
+ if projection_class_embeddings_input_dim is None:
+ raise ValueError(
+ "`class_embed_type`: 'simple_projection' requires `projection_class_embeddings_input_dim` be set"
+ )
+ self.class_embedding = nn.Linear(
+ projection_class_embeddings_input_dim, time_embed_dim
+ )
+ else:
+ self.class_embedding = None
+
+ if addition_embed_type == "text":
+ if encoder_hid_dim is not None:
+ text_time_embedding_from_dim = encoder_hid_dim
+ else:
+ text_time_embedding_from_dim = cross_attention_dim
+
+ self.add_embedding = TextTimeEmbedding(
+ text_time_embedding_from_dim,
+ time_embed_dim,
+ num_heads=addition_embed_type_num_heads,
+ )
+ elif addition_embed_type == "text_image":
+ # text_embed_dim and image_embed_dim DON'T have to be `cross_attention_dim`. To not clutter the __init__ too much
+ # they are set to `cross_attention_dim` here as this is exactly the required dimension for the currently only use
+ # case when `addition_embed_type == "text_image"` (Kadinsky 2.1)`
+ self.add_embedding = TextImageTimeEmbedding(
+ text_embed_dim=cross_attention_dim,
+ image_embed_dim=cross_attention_dim,
+ time_embed_dim=time_embed_dim,
+ )
+ elif addition_embed_type == "text_time":
+ self.add_time_proj = Timesteps(
+ addition_time_embed_dim, flip_sin_to_cos, freq_shift
+ )
+ self.add_embedding = TimestepEmbedding(
+ projection_class_embeddings_input_dim, time_embed_dim
+ )
+ elif addition_embed_type == "image":
+ # Kandinsky 2.2
+ self.add_embedding = ImageTimeEmbedding(
+ image_embed_dim=encoder_hid_dim, time_embed_dim=time_embed_dim
+ )
+ elif addition_embed_type == "image_hint":
+ # Kandinsky 2.2 ControlNet
+ self.add_embedding = ImageHintTimeEmbedding(
+ image_embed_dim=encoder_hid_dim, time_embed_dim=time_embed_dim
+ )
+ elif addition_embed_type is not None:
+ raise ValueError(
+ f"addition_embed_type: {addition_embed_type} must be None, 'text' or 'text_image'."
+ )
+
+ if time_embedding_act_fn is None:
+ self.time_embed_act = None
+ else:
+ self.time_embed_act = get_activation(time_embedding_act_fn)
+
+ self.down_blocks = nn.ModuleList([])
+ self.up_blocks = nn.ModuleList([])
+
+ if isinstance(only_cross_attention, bool):
+ if mid_block_only_cross_attention is None:
+ mid_block_only_cross_attention = only_cross_attention
+
+ only_cross_attention = [
+ only_cross_attention] * len(down_block_types)
+
+ if mid_block_only_cross_attention is None:
+ mid_block_only_cross_attention = False
+
+ if isinstance(num_attention_heads, int):
+ num_attention_heads = (num_attention_heads,) * \
+ len(down_block_types)
+
+ if isinstance(attention_head_dim, int):
+ attention_head_dim = (attention_head_dim,) * len(down_block_types)
+
+ if isinstance(cross_attention_dim, int):
+ cross_attention_dim = (cross_attention_dim,) * \
+ len(down_block_types)
+
+ if isinstance(layers_per_block, int):
+ layers_per_block = [layers_per_block] * len(down_block_types)
+
+ if isinstance(transformer_layers_per_block, int):
+ transformer_layers_per_block = [transformer_layers_per_block] * len(
+ down_block_types
+ )
+
+ if class_embeddings_concat:
+ # The time embeddings are concatenated with the class embeddings. The dimension of the
+ # time embeddings passed to the down, middle, and up blocks is twice the dimension of the
+ # regular time embeddings
+ blocks_time_embed_dim = time_embed_dim * 2
+ else:
+ blocks_time_embed_dim = time_embed_dim
+
+ # down
+ output_channel = block_out_channels[0]
+ for i, down_block_type in enumerate(down_block_types):
+ input_channel = output_channel
+ output_channel = block_out_channels[i]
+ is_final_block = i == len(block_out_channels) - 1
+
+ down_block = get_down_block(
+ down_block_type,
+ num_layers=layers_per_block[i],
+ transformer_layers_per_block=transformer_layers_per_block[i],
+ in_channels=input_channel,
+ out_channels=output_channel,
+ temb_channels=blocks_time_embed_dim,
+ add_downsample=not is_final_block,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=cross_attention_dim[i],
+ num_attention_heads=num_attention_heads[i],
+ downsample_padding=downsample_padding,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ attention_type=attention_type,
+ attention_head_dim=(
+ attention_head_dim[i]
+ if attention_head_dim[i] is not None
+ else output_channel
+ ),
+ dropout=dropout,
+ )
+ self.down_blocks.append(down_block)
+
+ # mid
+ if mid_block_type == "UNetMidBlock2DCrossAttn":
+ self.mid_block = UNetMidBlock2DCrossAttn(
+ transformer_layers_per_block=transformer_layers_per_block[-1],
+ in_channels=block_out_channels[-1],
+ temb_channels=blocks_time_embed_dim,
+ dropout=dropout,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ output_scale_factor=mid_block_scale_factor,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ cross_attention_dim=cross_attention_dim[-1],
+ num_attention_heads=num_attention_heads[-1],
+ resnet_groups=norm_num_groups,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ attention_type=attention_type,
+ )
+ elif mid_block_type == "UNetMidBlock2DSimpleCrossAttn":
+ raise NotImplementedError(
+ f"Unsupport mid_block_type: {mid_block_type}")
+ elif mid_block_type == "UNetMidBlock2D":
+ self.mid_block = UNetMidBlock2D(
+ in_channels=block_out_channels[-1],
+ temb_channels=blocks_time_embed_dim,
+ dropout=dropout,
+ num_layers=0,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ output_scale_factor=mid_block_scale_factor,
+ resnet_groups=norm_num_groups,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ add_attention=False,
+ )
+ elif mid_block_type is None:
+ self.mid_block = None
+ else:
+ raise ValueError(f"unknown mid_block_type : {mid_block_type}")
+
+ # count how many layers upsample the images
+ self.num_upsamplers = 0
+
+ # up
+ reversed_block_out_channels = list(reversed(block_out_channels))
+ reversed_num_attention_heads = list(reversed(num_attention_heads))
+ reversed_layers_per_block = list(reversed(layers_per_block))
+ reversed_cross_attention_dim = list(reversed(cross_attention_dim))
+ reversed_transformer_layers_per_block = (
+ list(reversed(transformer_layers_per_block))
+ if reverse_transformer_layers_per_block is None
+ else reverse_transformer_layers_per_block
+ )
+ only_cross_attention = list(reversed(only_cross_attention))
+
+ output_channel = reversed_block_out_channels[0]
+ for i, up_block_type in enumerate(up_block_types):
+ is_final_block = i == len(block_out_channels) - 1
+
+ prev_output_channel = output_channel
+ output_channel = reversed_block_out_channels[i]
+ input_channel = reversed_block_out_channels[
+ min(i + 1, len(block_out_channels) - 1)
+ ]
+
+ # add upsample block for all BUT final layer
+ if not is_final_block:
+ add_upsample = True
+ self.num_upsamplers += 1
+ else:
+ add_upsample = False
+
+ up_block = get_up_block(
+ up_block_type,
+ num_layers=reversed_layers_per_block[i] + 1,
+ transformer_layers_per_block=reversed_transformer_layers_per_block[i],
+ in_channels=input_channel,
+ out_channels=output_channel,
+ prev_output_channel=prev_output_channel,
+ temb_channels=blocks_time_embed_dim,
+ add_upsample=add_upsample,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resolution_idx=i,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=reversed_cross_attention_dim[i],
+ num_attention_heads=reversed_num_attention_heads[i],
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ attention_type=attention_type,
+ attention_head_dim=(
+ attention_head_dim[i]
+ if attention_head_dim[i] is not None
+ else output_channel
+ ),
+ dropout=dropout,
+ )
+ self.up_blocks.append(up_block)
+ prev_output_channel = output_channel
+
+ # out
+ if norm_num_groups is not None:
+ self.conv_norm_out = nn.GroupNorm(
+ num_channels=block_out_channels[0],
+ num_groups=norm_num_groups,
+ eps=norm_eps,
+ )
+
+ self.conv_act = get_activation(act_fn)
+
+ else:
+ self.conv_norm_out = None
+ self.conv_act = None
+ self.conv_norm_out = None
+
+ if attention_type in ["gated", "gated-text-image"]:
+ positive_len = 768
+ if isinstance(cross_attention_dim, int):
+ positive_len = cross_attention_dim
+ elif isinstance(cross_attention_dim, (tuple, list)):
+ positive_len = cross_attention_dim[0]
+
+ feature_type = "text-only" if attention_type == "gated" else "text-image"
+ self.position_net = GLIGENTextBoundingboxProjection(
+ positive_len=positive_len,
+ out_dim=cross_attention_dim,
+ feature_type=feature_type,
+ )
+
+ @property
+ def attn_processors(self) -> Dict[str, AttentionProcessor]:
+ r"""
+ Returns:
+ `dict` of attention processors: A dictionary containing all attention processors used in the model with
+ indexed by its weight name.
+ """
+ # set recursively
+ processors = {}
+
+ def fn_recursive_add_processors(
+ name: str,
+ module: torch.nn.Module,
+ processors: Dict[str, AttentionProcessor],
+ ):
+ if hasattr(module, "get_processor"):
+ processors[f"{name}.processor"] = module.get_processor(
+ return_deprecated_lora=True
+ )
+
+ for sub_name, child in module.named_children():
+ fn_recursive_add_processors(
+ f"{name}.{sub_name}", child, processors)
+
+ return processors
+
+ for name, module in self.named_children():
+ fn_recursive_add_processors(name, module, processors)
+
+ return processors
+
+ def set_attn_processor(
+ self,
+ processor: Union[AttentionProcessor, Dict[str, AttentionProcessor]],
+ _remove_lora=False,
+ ):
+ r"""
+ Sets the attention processor to use to compute attention.
+
+ Parameters:
+ processor (`dict` of `AttentionProcessor` or only `AttentionProcessor`):
+ The instantiated processor class or a dictionary of processor classes that will be set as the processor
+ for **all** `Attention` layers.
+
+ If `processor` is a dict, the key needs to define the path to the corresponding cross attention
+ processor. This is strongly recommended when setting trainable attention processors.
+
+ """
+ count = len(self.attn_processors.keys())
+
+ if isinstance(processor, dict) and len(processor) != count:
+ raise ValueError(
+ f"A dict of processors was passed, but the number of processors {len(processor)} does not match the"
+ f" number of attention layers: {count}. Please make sure to pass {count} processor classes."
+ )
+
+ def fn_recursive_attn_processor(name: str, module: torch.nn.Module, processor):
+ if hasattr(module, "set_processor"):
+ if not isinstance(processor, dict):
+ module.set_processor(processor, _remove_lora=_remove_lora)
+ else:
+ module.set_processor(
+ processor.pop(f"{name}.processor"), _remove_lora=_remove_lora
+ )
+
+ for sub_name, child in module.named_children():
+ fn_recursive_attn_processor(
+ f"{name}.{sub_name}", child, processor)
+
+ for name, module in self.named_children():
+ fn_recursive_attn_processor(name, module, processor)
+
+ def set_default_attn_processor(self):
+ """
+ Disables custom attention processors and sets the default attention implementation.
+ """
+ if all(
+ proc.__class__ in ADDED_KV_ATTENTION_PROCESSORS
+ for proc in self.attn_processors.values()
+ ):
+ processor = AttnAddedKVProcessor()
+ elif all(
+ proc.__class__ in CROSS_ATTENTION_PROCESSORS
+ for proc in self.attn_processors.values()
+ ):
+ processor = AttnProcessor()
+ else:
+ raise ValueError(
+ f"Cannot call `set_default_attn_processor` when attention processors are of type {next(iter(self.attn_processors.values()))}"
+ )
+
+ self.set_attn_processor(processor, _remove_lora=True)
+
+ def set_attention_slice(self, slice_size):
+ r"""
+ Enable sliced attention computation.
+
+ When this option is enabled, the attention module splits the input tensor in slices to compute attention in
+ several steps. This is useful for saving some memory in exchange for a small decrease in speed.
+
+ Args:
+ slice_size (`str` or `int` or `list(int)`, *optional*, defaults to `"auto"`):
+ When `"auto"`, input to the attention heads is halved, so attention is computed in two steps. If
+ `"max"`, maximum amount of memory is saved by running only one slice at a time. If a number is
+ provided, uses as many slices as `attention_head_dim // slice_size`. In this case, `attention_head_dim`
+ must be a multiple of `slice_size`.
+ """
+ sliceable_head_dims = []
+
+ def fn_recursive_retrieve_sliceable_dims(module: torch.nn.Module):
+ if hasattr(module, "set_attention_slice"):
+ sliceable_head_dims.append(module.sliceable_head_dim)
+
+ for child in module.children():
+ fn_recursive_retrieve_sliceable_dims(child)
+
+ # retrieve number of attention layers
+ for module in self.children():
+ fn_recursive_retrieve_sliceable_dims(module)
+
+ num_sliceable_layers = len(sliceable_head_dims)
+
+ if slice_size == "auto":
+ # half the attention head size is usually a good trade-off between
+ # speed and memory
+ slice_size = [dim // 2 for dim in sliceable_head_dims]
+ elif slice_size == "max":
+ # make smallest slice possible
+ slice_size = num_sliceable_layers * [1]
+
+ slice_size = (
+ num_sliceable_layers * [slice_size]
+ if not isinstance(slice_size, list)
+ else slice_size
+ )
+
+ if len(slice_size) != len(sliceable_head_dims):
+ raise ValueError(
+ f"You have provided {len(slice_size)}, but {self.config} has {len(sliceable_head_dims)} different"
+ f" attention layers. Make sure to match `len(slice_size)` to be {len(sliceable_head_dims)}."
+ )
+
+ for i, size in enumerate(slice_size):
+ dim = sliceable_head_dims[i]
+ if size is not None and size > dim:
+ raise ValueError(
+ f"size {size} has to be smaller or equal to {dim}.")
+
+ # Recursively walk through all the children.
+ # Any children which exposes the set_attention_slice method
+ # gets the message
+ def fn_recursive_set_attention_slice(
+ module: torch.nn.Module, slice_size: List[int]
+ ):
+ if hasattr(module, "set_attention_slice"):
+ module.set_attention_slice(slice_size.pop())
+
+ for child in module.children():
+ fn_recursive_set_attention_slice(child, slice_size)
+
+ reversed_slice_size = list(reversed(slice_size))
+ for module in self.children():
+ fn_recursive_set_attention_slice(module, reversed_slice_size)
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ if hasattr(module, "gradient_checkpointing"):
+ module.gradient_checkpointing = value
+
+ def enable_freeu(self, s1, s2, b1, b2):
+ r"""Enables the FreeU mechanism from https://arxiv.org/abs/2309.11497.
+
+ The suffixes after the scaling factors represent the stage blocks where they are being applied.
+
+ Please refer to the [official repository](https://github.com/ChenyangSi/FreeU) for combinations of values that
+ are known to work well for different pipelines such as Stable Diffusion v1, v2, and Stable Diffusion XL.
+
+ Args:
+ s1 (`float`):
+ Scaling factor for stage 1 to attenuate the contributions of the skip features. This is done to
+ mitigate the "oversmoothing effect" in the enhanced denoising process.
+ s2 (`float`):
+ Scaling factor for stage 2 to attenuate the contributions of the skip features. This is done to
+ mitigate the "oversmoothing effect" in the enhanced denoising process.
+ b1 (`float`): Scaling factor for stage 1 to amplify the contributions of backbone features.
+ b2 (`float`): Scaling factor for stage 2 to amplify the contributions of backbone features.
+ """
+ for _, upsample_block in enumerate(self.up_blocks):
+ setattr(upsample_block, "s1", s1)
+ setattr(upsample_block, "s2", s2)
+ setattr(upsample_block, "b1", b1)
+ setattr(upsample_block, "b2", b2)
+
+ def disable_freeu(self):
+ """Disables the FreeU mechanism."""
+ freeu_keys = {"s1", "s2", "b1", "b2"}
+ for _, upsample_block in enumerate(self.up_blocks):
+ for k in freeu_keys:
+ if (
+ hasattr(upsample_block, k)
+ or getattr(upsample_block, k, None) is not None
+ ):
+ setattr(upsample_block, k, None)
+
+ def forward(
+ self,
+ sample: torch.FloatTensor,
+ timestep: Union[torch.Tensor, float, int],
+ encoder_hidden_states: torch.Tensor,
+ cond_tensor: torch.FloatTensor=None,
+ class_labels: Optional[torch.Tensor] = None,
+ timestep_cond: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ cross_attention_kwargs: Optional[Dict[str, Any]] = None,
+ added_cond_kwargs: Optional[Dict[str, torch.Tensor]] = None,
+ down_block_additional_residuals: Optional[Tuple[torch.Tensor]] = None,
+ mid_block_additional_residual: Optional[torch.Tensor] = None,
+ down_intrablock_additional_residuals: Optional[Tuple[torch.Tensor]] = None,
+ encoder_attention_mask: Optional[torch.Tensor] = None,
+ return_dict: bool = True,
+ post_process: bool = False,
+ ) -> Union[UNet2DConditionOutput, Tuple]:
+ r"""
+ The [`UNet2DConditionModel`] forward method.
+
+ Args:
+ sample (`torch.FloatTensor`):
+ The noisy input tensor with the following shape `(batch, channel, height, width)`.
+ timestep (`torch.FloatTensor` or `float` or `int`): The number of timesteps to denoise an input.
+ encoder_hidden_states (`torch.FloatTensor`):
+ The encoder hidden states with shape `(batch, sequence_length, feature_dim)`.
+ class_labels (`torch.Tensor`, *optional*, defaults to `None`):
+ Optional class labels for conditioning. Their embeddings will be summed with the timestep embeddings.
+ timestep_cond: (`torch.Tensor`, *optional*, defaults to `None`):
+ Conditional embeddings for timestep. If provided, the embeddings will be summed with the samples passed
+ through the `self.time_embedding` layer to obtain the timestep embeddings.
+ attention_mask (`torch.Tensor`, *optional*, defaults to `None`):
+ An attention mask of shape `(batch, key_tokens)` is applied to `encoder_hidden_states`. If `1` the mask
+ is kept, otherwise if `0` it is discarded. Mask will be converted into a bias, which adds large
+ negative values to the attention scores corresponding to "discard" tokens.
+ cross_attention_kwargs (`dict`, *optional*):
+ A kwargs dictionary that if specified is passed along to the `AttentionProcessor` as defined under
+ `self.processor` in
+ [diffusers.models.attention_processor]
+ (https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py).
+ added_cond_kwargs: (`dict`, *optional*):
+ A kwargs dictionary containing additional embeddings that if specified are added to the embeddings that
+ are passed along to the UNet blocks.
+ down_block_additional_residuals: (`tuple` of `torch.Tensor`, *optional*):
+ A tuple of tensors that if specified are added to the residuals of down unet blocks.
+ mid_block_additional_residual: (`torch.Tensor`, *optional*):
+ A tensor that if specified is added to the residual of the middle unet block.
+ encoder_attention_mask (`torch.Tensor`):
+ A cross-attention mask of shape `(batch, sequence_length)` is applied to `encoder_hidden_states`. If
+ `True` the mask is kept, otherwise if `False` it is discarded. Mask will be converted into a bias,
+ which adds large negative values to the attention scores corresponding to "discard" tokens.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~models.unet_2d_condition.UNet2DConditionOutput`] instead of a plain
+ tuple.
+ cross_attention_kwargs (`dict`, *optional*):
+ A kwargs dictionary that if specified is passed along to the [`AttnProcessor`].
+ added_cond_kwargs: (`dict`, *optional*):
+ A kwargs dictionary containin additional embeddings that if specified are added to the embeddings that
+ are passed along to the UNet blocks.
+ down_block_additional_residuals (`tuple` of `torch.Tensor`, *optional*):
+ additional residuals to be added to UNet long skip connections from down blocks to up blocks for
+ example from ControlNet side model(s)
+ mid_block_additional_residual (`torch.Tensor`, *optional*):
+ additional residual to be added to UNet mid block output, for example from ControlNet side model
+ down_intrablock_additional_residuals (`tuple` of `torch.Tensor`, *optional*):
+ additional residuals to be added within UNet down blocks, for example from T2I-Adapter side model(s)
+
+ Returns:
+ [`~models.unet_2d_condition.UNet2DConditionOutput`] or `tuple`:
+ If `return_dict` is True, an [`~models.unet_2d_condition.UNet2DConditionOutput`] is returned, otherwise
+ a `tuple` is returned where the first element is the sample tensor.
+ """
+ # By default samples have to be AT least a multiple of the overall upsampling factor.
+ # The overall upsampling factor is equal to 2 ** (# num of upsampling layers).
+ # However, the upsampling interpolation output size can be forced to fit any upsampling size
+ # on the fly if necessary.
+ default_overall_up_factor = 2**self.num_upsamplers
+
+ # upsample size should be forwarded when sample is not a multiple of `default_overall_up_factor`
+ forward_upsample_size = False
+ upsample_size = None
+
+ for dim in sample.shape[-2:]:
+ if dim % default_overall_up_factor != 0:
+ # Forward upsample size to force interpolation output size.
+ forward_upsample_size = True
+ break
+
+ # ensure attention_mask is a bias, and give it a singleton query_tokens dimension
+ # expects mask of shape:
+ # [batch, key_tokens]
+ # adds singleton query_tokens dimension:
+ # [batch, 1, key_tokens]
+ # this helps to broadcast it as a bias over attention scores, which will be in one of the following shapes:
+ # [batch, heads, query_tokens, key_tokens] (e.g. torch sdp attn)
+ # [batch * heads, query_tokens, key_tokens] (e.g. xformers or classic attn)
+ if attention_mask is not None:
+ # assume that mask is expressed as:
+ # (1 = keep, 0 = discard)
+ # convert mask into a bias that can be added to attention scores:
+ # (keep = +0, discard = -10000.0)
+ attention_mask = (1 - attention_mask.to(sample.dtype)) * -10000.0
+ attention_mask = attention_mask.unsqueeze(1)
+
+ # convert encoder_attention_mask to a bias the same way we do for attention_mask
+ if encoder_attention_mask is not None:
+ encoder_attention_mask = (
+ 1 - encoder_attention_mask.to(sample.dtype)
+ ) * -10000.0
+ encoder_attention_mask = encoder_attention_mask.unsqueeze(1)
+
+ # 0. center input if necessary
+ if self.config.center_input_sample:
+ sample = 2 * sample - 1.0
+
+ # 1. time
+ timesteps = timestep
+ if not torch.is_tensor(timesteps):
+ # TODO: this requires sync between CPU and GPU. So try to pass timesteps as tensors if you can
+ # This would be a good case for the `match` statement (Python 3.10+)
+ is_mps = sample.device.type == "mps"
+ if isinstance(timestep, float):
+ dtype = torch.float32 if is_mps else torch.float64
+ else:
+ dtype = torch.int32 if is_mps else torch.int64
+ timesteps = torch.tensor(
+ [timesteps], dtype=dtype, device=sample.device)
+ elif len(timesteps.shape) == 0:
+ timesteps = timesteps[None].to(sample.device)
+
+ # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
+ timesteps = timesteps.expand(sample.shape[0])
+
+ t_emb = self.time_proj(timesteps)
+
+ # `Timesteps` does not contain any weights and will always return f32 tensors
+ # but time_embedding might actually be running in fp16. so we need to cast here.
+ # there might be better ways to encapsulate this.
+ t_emb = t_emb.to(dtype=sample.dtype)
+
+ emb = self.time_embedding(t_emb, timestep_cond)
+ aug_emb = None
+
+ if self.class_embedding is not None:
+ if class_labels is None:
+ raise ValueError(
+ "class_labels should be provided when num_class_embeds > 0"
+ )
+
+ if self.config.class_embed_type == "timestep":
+ class_labels = self.time_proj(class_labels)
+
+ # `Timesteps` does not contain any weights and will always return f32 tensors
+ # there might be better ways to encapsulate this.
+ class_labels = class_labels.to(dtype=sample.dtype)
+
+ class_emb = self.class_embedding(
+ class_labels).to(dtype=sample.dtype)
+
+ if self.config.class_embeddings_concat:
+ emb = torch.cat([emb, class_emb], dim=-1)
+ else:
+ emb = emb + class_emb
+
+ if self.config.addition_embed_type == "text":
+ aug_emb = self.add_embedding(encoder_hidden_states)
+ elif self.config.addition_embed_type == "text_image":
+ # Kandinsky 2.1 - style
+ if "image_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `addition_embed_type` set to 'text_image'"
+ "which requires the keyword argument `image_embeds` to be passed in `added_cond_kwargs`"
+ )
+
+ image_embs = added_cond_kwargs.get("image_embeds")
+ text_embs = added_cond_kwargs.get(
+ "text_embeds", encoder_hidden_states)
+ aug_emb = self.add_embedding(text_embs, image_embs)
+ elif self.config.addition_embed_type == "text_time":
+ # SDXL - style
+ if "text_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `addition_embed_type` set to 'text_time'"
+ "which requires the keyword argument `text_embeds` to be passed in `added_cond_kwargs`"
+ )
+ text_embeds = added_cond_kwargs.get("text_embeds")
+ if "time_ids" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `addition_embed_type` set to 'text_time'"
+ "which requires the keyword argument `time_ids` to be passed in `added_cond_kwargs`"
+ )
+ time_ids = added_cond_kwargs.get("time_ids")
+ time_embeds = self.add_time_proj(time_ids.flatten())
+ time_embeds = time_embeds.reshape((text_embeds.shape[0], -1))
+ add_embeds = torch.concat([text_embeds, time_embeds], dim=-1)
+ add_embeds = add_embeds.to(emb.dtype)
+ aug_emb = self.add_embedding(add_embeds)
+ elif self.config.addition_embed_type == "image":
+ # Kandinsky 2.2 - style
+ if "image_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `addition_embed_type` set to 'image'"
+ "which requires the keyword argument `image_embeds` to be passed in `added_cond_kwargs`"
+ )
+ image_embs = added_cond_kwargs.get("image_embeds")
+ aug_emb = self.add_embedding(image_embs)
+ elif self.config.addition_embed_type == "image_hint":
+ # Kandinsky 2.2 - style
+ if (
+ "image_embeds" not in added_cond_kwargs
+ or "hint" not in added_cond_kwargs
+ ):
+ raise ValueError(
+ f"{self.__class__} has the config param `addition_embed_type` set to 'image_hint'"
+ "which requires the keyword arguments `image_embeds` and `hint` to be passed in `added_cond_kwargs`"
+ )
+ image_embs = added_cond_kwargs.get("image_embeds")
+ hint = added_cond_kwargs.get("hint")
+ aug_emb, hint = self.add_embedding(image_embs, hint)
+ sample = torch.cat([sample, hint], dim=1)
+
+ emb = emb + aug_emb if aug_emb is not None else emb
+
+ if self.time_embed_act is not None:
+ emb = self.time_embed_act(emb)
+
+ if (
+ self.encoder_hid_proj is not None
+ and self.config.encoder_hid_dim_type == "text_proj"
+ ):
+ encoder_hidden_states = self.encoder_hid_proj(
+ encoder_hidden_states)
+ elif (
+ self.encoder_hid_proj is not None
+ and self.config.encoder_hid_dim_type == "text_image_proj"
+ ):
+ # Kadinsky 2.1 - style
+ if "image_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `encoder_hid_dim_type` set to 'text_image_proj'"
+ "which requires the keyword argument `image_embeds` to be passed in `added_conditions`"
+ )
+
+ image_embeds = added_cond_kwargs.get("image_embeds")
+ encoder_hidden_states = self.encoder_hid_proj(
+ encoder_hidden_states, image_embeds
+ )
+ elif (
+ self.encoder_hid_proj is not None
+ and self.config.encoder_hid_dim_type == "image_proj"
+ ):
+ # Kandinsky 2.2 - style
+ if "image_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `encoder_hid_dim_type` set to 'image_proj'"
+ "which requires the keyword argument `image_embeds` to be passed in `added_conditions`"
+ )
+ image_embeds = added_cond_kwargs.get("image_embeds")
+ encoder_hidden_states = self.encoder_hid_proj(image_embeds)
+ elif (
+ self.encoder_hid_proj is not None
+ and self.config.encoder_hid_dim_type == "ip_image_proj"
+ ):
+ if "image_embeds" not in added_cond_kwargs:
+ raise ValueError(
+ f"{self.__class__} has the config param `encoder_hid_dim_type` set to 'ip_image_proj'"
+ "which requires the keyword argument `image_embeds` to be passed in `added_conditions`"
+ )
+ image_embeds = added_cond_kwargs.get("image_embeds")
+ image_embeds = self.encoder_hid_proj(image_embeds).to(
+ encoder_hidden_states.dtype
+ )
+ encoder_hidden_states = torch.cat(
+ [encoder_hidden_states, image_embeds], dim=1
+ )
+
+ # 2. pre-process
+ sample = self.conv_in(sample)
+ if cond_tensor is not None:
+ sample = sample + cond_tensor
+
+ # 2.5 GLIGEN position net
+ if (
+ cross_attention_kwargs is not None
+ and cross_attention_kwargs.get("gligen", None) is not None
+ ):
+ cross_attention_kwargs = cross_attention_kwargs.copy()
+ gligen_args = cross_attention_kwargs.pop("gligen")
+ cross_attention_kwargs["gligen"] = {
+ "objs": self.position_net(**gligen_args)
+ }
+
+ # 3. down
+ lora_scale = (
+ cross_attention_kwargs.get("scale", 1.0)
+ if cross_attention_kwargs is not None
+ else 1.0
+ )
+ if USE_PEFT_BACKEND:
+ # weight the lora layers by setting `lora_scale` for each PEFT layer
+ scale_lora_layers(self, lora_scale)
+
+ is_controlnet = (
+ mid_block_additional_residual is not None
+ and down_block_additional_residuals is not None
+ )
+ # using new arg down_intrablock_additional_residuals for T2I-Adapters, to distinguish from controlnets
+ is_adapter = down_intrablock_additional_residuals is not None
+ # maintain backward compatibility for legacy usage, where
+ # T2I-Adapter and ControlNet both use down_block_additional_residuals arg
+ # but can only use one or the other
+ if (
+ not is_adapter
+ and mid_block_additional_residual is None
+ and down_block_additional_residuals is not None
+ ):
+ deprecate(
+ "T2I should not use down_block_additional_residuals",
+ "1.3.0",
+ "Passing intrablock residual connections with `down_block_additional_residuals` is deprecated \
+ and will be removed in diffusers 1.3.0. `down_block_additional_residuals` should only be used \
+ for ControlNet. Please make sure use `down_intrablock_additional_residuals` instead. ",
+ standard_warn=False,
+ )
+ down_intrablock_additional_residuals = down_block_additional_residuals
+ is_adapter = True
+
+ down_block_res_samples = (sample,)
+ for downsample_block in self.down_blocks:
+ if (
+ hasattr(downsample_block, "has_cross_attention")
+ and downsample_block.has_cross_attention
+ ):
+ # For t2i-adapter CrossAttnDownBlock2D
+ additional_residuals = {}
+ if is_adapter and len(down_intrablock_additional_residuals) > 0:
+ additional_residuals["additional_residuals"] = (
+ down_intrablock_additional_residuals.pop(0)
+ )
+
+ sample, res_samples = downsample_block(
+ hidden_states=sample,
+ temb=emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ cross_attention_kwargs=cross_attention_kwargs,
+ encoder_attention_mask=encoder_attention_mask,
+ **additional_residuals,
+ )
+ else:
+ sample, res_samples = downsample_block(
+ hidden_states=sample, temb=emb, scale=lora_scale
+ )
+ if is_adapter and len(down_intrablock_additional_residuals) > 0:
+ sample += down_intrablock_additional_residuals.pop(0)
+
+ down_block_res_samples += res_samples
+
+ if is_controlnet:
+ new_down_block_res_samples = ()
+
+ for down_block_res_sample, down_block_additional_residual in zip(
+ down_block_res_samples, down_block_additional_residuals
+ ):
+ down_block_res_sample = (
+ down_block_res_sample + down_block_additional_residual
+ )
+ new_down_block_res_samples = new_down_block_res_samples + (
+ down_block_res_sample,
+ )
+
+ down_block_res_samples = new_down_block_res_samples
+
+ # 4. mid
+ if self.mid_block is not None:
+ if (
+ hasattr(self.mid_block, "has_cross_attention")
+ and self.mid_block.has_cross_attention
+ ):
+ sample = self.mid_block(
+ sample,
+ emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ cross_attention_kwargs=cross_attention_kwargs,
+ encoder_attention_mask=encoder_attention_mask,
+ )
+ else:
+ sample = self.mid_block(sample, emb)
+
+ # To support T2I-Adapter-XL
+ if (
+ is_adapter
+ and len(down_intrablock_additional_residuals) > 0
+ and sample.shape == down_intrablock_additional_residuals[0].shape
+ ):
+ sample += down_intrablock_additional_residuals.pop(0)
+
+ if is_controlnet:
+ sample = sample + mid_block_additional_residual
+
+ # 5. up
+ for i, upsample_block in enumerate(self.up_blocks):
+ is_final_block = i == len(self.up_blocks) - 1
+
+ res_samples = down_block_res_samples[-len(upsample_block.resnets):]
+ down_block_res_samples = down_block_res_samples[
+ : -len(upsample_block.resnets)
+ ]
+
+ # if we have not reached the final block and need to forward the
+ # upsample size, we do it here
+ if not is_final_block and forward_upsample_size:
+ upsample_size = down_block_res_samples[-1].shape[2:]
+
+ if (
+ hasattr(upsample_block, "has_cross_attention")
+ and upsample_block.has_cross_attention
+ ):
+ sample = upsample_block(
+ hidden_states=sample,
+ temb=emb,
+ res_hidden_states_tuple=res_samples,
+ encoder_hidden_states=encoder_hidden_states,
+ cross_attention_kwargs=cross_attention_kwargs,
+ upsample_size=upsample_size,
+ attention_mask=attention_mask,
+ encoder_attention_mask=encoder_attention_mask,
+ )
+ else:
+ sample = upsample_block(
+ hidden_states=sample,
+ temb=emb,
+ res_hidden_states_tuple=res_samples,
+ upsample_size=upsample_size,
+ scale=lora_scale,
+ )
+
+ # 6. post-process
+ if post_process:
+ if self.conv_norm_out:
+ sample = self.conv_norm_out(sample)
+ sample = self.conv_act(sample)
+ sample = self.conv_out(sample)
+
+ if USE_PEFT_BACKEND:
+ # remove `lora_scale` from each PEFT layer
+ unscale_lora_layers(self, lora_scale)
+
+ if not return_dict:
+ return (sample,)
+
+ return UNet2DConditionOutput(sample=sample)
+
+ @classmethod
+ def load_change_cross_attention_dim(
+ cls,
+ pretrained_model_path: PathLike,
+ subfolder=None,
+ # unet_additional_kwargs=None,
+ ):
+ """
+ Load or change the cross-attention dimension of a pre-trained model.
+
+ Parameters:
+ pretrained_model_name_or_path (:class:`~typing.Union[str, :class:`~pathlib.Path`]`):
+ The identifier of the pre-trained model or the path to the local folder containing the model.
+ force_download (:class:`~bool`):
+ If True, re-download the model even if it is already cached.
+ resume_download (:class:`~bool`):
+ If True, resume the download of the model if partially downloaded.
+ proxies (:class:`~dict`):
+ A dictionary of proxy servers to use for downloading the model.
+ cache_dir (:class:`~Optional[str]`):
+ The path to the cache directory for storing downloaded models.
+ use_auth_token (:class:`~bool`):
+ If True, use the authentication token for private models.
+ revision (:class:`~str`):
+ The specific model version to use.
+ use_safetensors (:class:`~bool`):
+ If True, use the SafeTensors format for loading the model weights.
+ **kwargs (:class:`~dict`):
+ Additional keyword arguments passed to the model.
+
+ """
+ pretrained_model_path = Path(pretrained_model_path)
+ if subfolder is not None:
+ pretrained_model_path = pretrained_model_path.joinpath(subfolder)
+ config_file = pretrained_model_path / "config.json"
+ if not (config_file.exists() and config_file.is_file()):
+ raise RuntimeError(
+ f"{config_file} does not exist or is not a file")
+
+ unet_config = cls.load_config(config_file)
+ unet_config["cross_attention_dim"] = 1024
+
+ model = cls.from_config(unet_config)
+ # load the vanilla weights
+ if pretrained_model_path.joinpath(SAFETENSORS_WEIGHTS_NAME).exists():
+ logger.debug(
+ f"loading safeTensors weights from {pretrained_model_path} ..."
+ )
+ state_dict = load_file(
+ pretrained_model_path.joinpath(SAFETENSORS_WEIGHTS_NAME), device="cpu"
+ )
+
+ elif pretrained_model_path.joinpath(WEIGHTS_NAME).exists():
+ logger.debug(f"loading weights from {pretrained_model_path} ...")
+ state_dict = torch.load(
+ pretrained_model_path.joinpath(WEIGHTS_NAME),
+ map_location="cpu",
+ weights_only=True,
+ )
+ else:
+ raise FileNotFoundError(
+ f"no weights file found in {pretrained_model_path}")
+
+ model_state_dict = model.state_dict()
+ for k in state_dict:
+ if k in model_state_dict:
+ if state_dict[k].shape != model_state_dict[k].shape:
+ state_dict[k] = model_state_dict[k]
+ # load the weights into the model
+ m, u = model.load_state_dict(state_dict, strict=False)
+ print(m, u)
+
+ return model
diff --git a/animation/hallo-83dd4eb/hallo/models/unet_3d.py b/animation/hallo-83dd4eb/hallo/models/unet_3d.py
new file mode 100644
index 0000000..8a3fdb4
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/unet_3d.py
@@ -0,0 +1,839 @@
+# pylint: disable=R0801
+# pylint: disable=E1101
+# pylint: disable=R0402
+# pylint: disable=W1203
+
+"""
+This is the main file for the UNet3DConditionModel, which defines the UNet3D model architecture.
+
+The UNet3D model is a 3D convolutional neural network designed for image segmentation and
+other computer vision tasks. It consists of an encoder, a decoder, and skip connections between
+the corresponding layers of the encoder and decoder. The model can handle 3D data and
+performs well on tasks such as image segmentation, object detection, and video analysis.
+
+This file contains the necessary imports, the main UNet3DConditionModel class, and its
+methods for setting attention slice, setting gradient checkpointing, setting attention
+processor, and the forward method for model inference.
+
+The module provides a comprehensive solution for 3D image segmentation tasks and can be
+easily extended for other computer vision tasks as well.
+"""
+
+from collections import OrderedDict
+from dataclasses import dataclass
+from os import PathLike
+from pathlib import Path
+from typing import Dict, List, Optional, Tuple, Union
+
+import torch
+import torch.nn as nn
+import torch.utils.checkpoint
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+from diffusers.models.attention_processor import AttentionProcessor
+from diffusers.models.embeddings import TimestepEmbedding, Timesteps
+from diffusers.models.modeling_utils import ModelMixin
+from diffusers.utils import (SAFETENSORS_WEIGHTS_NAME, WEIGHTS_NAME,
+ BaseOutput, logging)
+from safetensors.torch import load_file
+
+from .resnet import InflatedConv3d, InflatedGroupNorm
+from .unet_3d_blocks import (UNetMidBlock3DCrossAttn, get_down_block,
+ get_up_block)
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+@dataclass
+class UNet3DConditionOutput(BaseOutput):
+ """
+ Data class that serves as the output of the UNet3DConditionModel.
+
+ Attributes:
+ sample (`torch.FloatTensor`):
+ A tensor representing the processed sample. The shape and nature of this tensor will depend on the
+ specific configuration of the model and the input data.
+ """
+ sample: torch.FloatTensor
+
+
+class UNet3DConditionModel(ModelMixin, ConfigMixin):
+ """
+ A 3D UNet model designed to handle conditional image and video generation tasks. This model is particularly
+ suited for tasks that require the generation of 3D data, such as volumetric medical imaging or 3D video
+ generation, while incorporating additional conditioning information.
+
+ The model consists of an encoder-decoder structure with skip connections. It utilizes a series of downsampling
+ and upsampling blocks, with a middle block for further processing. Each block can be customized with different
+ types of layers and attention mechanisms.
+
+ Parameters:
+ sample_size (`int`, optional): The size of the input sample.
+ in_channels (`int`, defaults to 8): The number of input channels.
+ out_channels (`int`, defaults to 8): The number of output channels.
+ center_input_sample (`bool`, defaults to False): Whether to center the input sample.
+ flip_sin_to_cos (`bool`, defaults to True): Whether to flip the sine to cosine in the time embedding.
+ freq_shift (`int`, defaults to 0): The frequency shift for the time embedding.
+ down_block_types (`Tuple[str]`): A tuple of strings specifying the types of downsampling blocks.
+ mid_block_type (`str`): The type of middle block.
+ up_block_types (`Tuple[str]`): A tuple of strings specifying the types of upsampling blocks.
+ only_cross_attention (`Union[bool, Tuple[bool]]`): Whether to use only cross-attention.
+ block_out_channels (`Tuple[int]`): A tuple of integers specifying the output channels for each block.
+ layers_per_block (`int`, defaults to 2): The number of layers per block.
+ downsample_padding (`int`, defaults to 1): The padding used in downsampling.
+ mid_block_scale_factor (`float`, defaults to 1): The scale factor for the middle block.
+ act_fn (`str`, defaults to 'silu'): The activation function to be used.
+ norm_num_groups (`int`, defaults to 32): The number of groups for normalization.
+ norm_eps (`float`, defaults to 1e-5): The epsilon for normalization.
+ cross_attention_dim (`int`, defaults to 1280): The dimension for cross-attention.
+ attention_head_dim (`Union[int, Tuple[int]]`): The dimension for attention heads.
+ dual_cross_attention (`bool`, defaults to False): Whether to use dual cross-attention.
+ use_linear_projection (`bool`, defaults to False): Whether to use linear projection.
+ class_embed_type (`str`, optional): The type of class embedding.
+ num_class_embeds (`int`, optional): The number of class embeddings.
+ upcast_attention (`bool`, defaults to False): Whether to upcast attention.
+ resnet_time_scale_shift (`str`, defaults to 'default'): The time scale shift for the ResNet.
+ use_inflated_groupnorm (`bool`, defaults to False): Whether to use inflated group normalization.
+ use_motion_module (`bool`, defaults to False): Whether to use a motion module.
+ motion_module_resolutions (`Tuple[int]`): A tuple of resolutions for the motion module.
+ motion_module_mid_block (`bool`, defaults to False): Whether to use a motion module in the middle block.
+ motion_module_decoder_only (`bool`, defaults to False): Whether to use the motion module only in the decoder.
+ motion_module_type (`str`, optional): The type of motion module.
+ motion_module_kwargs (`dict`): Keyword arguments for the motion module.
+ unet_use_cross_frame_attention (`bool`, optional): Whether to use cross-frame attention in the UNet.
+ unet_use_temporal_attention (`bool`, optional): Whether to use temporal attention in the UNet.
+ use_audio_module (`bool`, defaults to False): Whether to use an audio module.
+ audio_attention_dim (`int`, defaults to 768): The dimension for audio attention.
+
+ The model supports various features such as gradient checkpointing, attention processors, and sliced attention
+ computation, making it flexible and efficient for different computational requirements and use cases.
+
+ The forward method of the model accepts a sample, timestep, and encoder hidden states as input, and it returns
+ the processed sample as output. The method also supports additional conditioning information such as class
+ labels, audio embeddings, and masks for specialized tasks.
+
+ The from_pretrained_2d class method allows loading a pre-trained 2D UNet model and adapting it for 3D tasks by
+ incorporating motion modules and other 3D specific features.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ sample_size: Optional[int] = None,
+ in_channels: int = 8,
+ out_channels: int = 8,
+ flip_sin_to_cos: bool = True,
+ freq_shift: int = 0,
+ down_block_types: Tuple[str] = (
+ "CrossAttnDownBlock3D",
+ "CrossAttnDownBlock3D",
+ "CrossAttnDownBlock3D",
+ "DownBlock3D",
+ ),
+ mid_block_type: str = "UNetMidBlock3DCrossAttn",
+ up_block_types: Tuple[str] = (
+ "UpBlock3D",
+ "CrossAttnUpBlock3D",
+ "CrossAttnUpBlock3D",
+ "CrossAttnUpBlock3D",
+ ),
+ only_cross_attention: Union[bool, Tuple[bool]] = False,
+ block_out_channels: Tuple[int] = (320, 640, 1280, 1280),
+ layers_per_block: int = 2,
+ downsample_padding: int = 1,
+ mid_block_scale_factor: float = 1,
+ act_fn: str = "silu",
+ norm_num_groups: int = 32,
+ norm_eps: float = 1e-5,
+ cross_attention_dim: int = 1280,
+ attention_head_dim: Union[int, Tuple[int]] = 8,
+ dual_cross_attention: bool = False,
+ use_linear_projection: bool = False,
+ class_embed_type: Optional[str] = None,
+ num_class_embeds: Optional[int] = None,
+ upcast_attention: bool = False,
+ resnet_time_scale_shift: str = "default",
+ use_inflated_groupnorm=False,
+ # Additional
+ use_motion_module=False,
+ motion_module_resolutions=(1, 2, 4, 8),
+ motion_module_mid_block=False,
+ motion_module_decoder_only=False,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ # audio
+ use_audio_module=False,
+ audio_attention_dim=768,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+ ):
+ super().__init__()
+
+ self.sample_size = sample_size
+ time_embed_dim = block_out_channels[0] * 4
+
+ # input
+ self.conv_in = InflatedConv3d(
+ in_channels, block_out_channels[0], kernel_size=3, padding=(1, 1)
+ )
+
+ # time
+ self.time_proj = Timesteps(
+ block_out_channels[0], flip_sin_to_cos, freq_shift)
+ timestep_input_dim = block_out_channels[0]
+
+ self.time_embedding = TimestepEmbedding(
+ timestep_input_dim, time_embed_dim)
+
+ # class embedding
+ if class_embed_type is None and num_class_embeds is not None:
+ self.class_embedding = nn.Embedding(
+ num_class_embeds, time_embed_dim)
+ elif class_embed_type == "timestep":
+ self.class_embedding = TimestepEmbedding(
+ timestep_input_dim, time_embed_dim)
+ elif class_embed_type == "identity":
+ self.class_embedding = nn.Identity(time_embed_dim, time_embed_dim)
+ else:
+ self.class_embedding = None
+
+ self.down_blocks = nn.ModuleList([])
+ self.mid_block = None
+ self.up_blocks = nn.ModuleList([])
+
+ if isinstance(only_cross_attention, bool):
+ only_cross_attention = [
+ only_cross_attention] * len(down_block_types)
+
+ if isinstance(attention_head_dim, int):
+ attention_head_dim = (attention_head_dim,) * len(down_block_types)
+
+ # down
+ output_channel = block_out_channels[0]
+ for i, down_block_type in enumerate(down_block_types):
+ res = 2**i
+ input_channel = output_channel
+ output_channel = block_out_channels[i]
+ is_final_block = i == len(block_out_channels) - 1
+
+ down_block = get_down_block(
+ down_block_type,
+ num_layers=layers_per_block,
+ in_channels=input_channel,
+ out_channels=output_channel,
+ temb_channels=time_embed_dim,
+ add_downsample=not is_final_block,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=cross_attention_dim,
+ attn_num_head_channels=attention_head_dim[i],
+ downsample_padding=downsample_padding,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module
+ and (res in motion_module_resolutions)
+ and (not motion_module_decoder_only),
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ use_audio_module=use_audio_module,
+ audio_attention_dim=audio_attention_dim,
+ depth=i,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ self.down_blocks.append(down_block)
+
+ # mid
+ if mid_block_type == "UNetMidBlock3DCrossAttn":
+ self.mid_block = UNetMidBlock3DCrossAttn(
+ in_channels=block_out_channels[-1],
+ temb_channels=time_embed_dim,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ output_scale_factor=mid_block_scale_factor,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ cross_attention_dim=cross_attention_dim,
+ attn_num_head_channels=attention_head_dim[-1],
+ resnet_groups=norm_num_groups,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module and motion_module_mid_block,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ use_audio_module=use_audio_module,
+ audio_attention_dim=audio_attention_dim,
+ depth=3,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ else:
+ raise ValueError(f"unknown mid_block_type : {mid_block_type}")
+
+ # count how many layers upsample the videos
+ self.num_upsamplers = 0
+
+ # up
+ reversed_block_out_channels = list(reversed(block_out_channels))
+ reversed_attention_head_dim = list(reversed(attention_head_dim))
+ only_cross_attention = list(reversed(only_cross_attention))
+ output_channel = reversed_block_out_channels[0]
+ for i, up_block_type in enumerate(up_block_types):
+ res = 2 ** (3 - i)
+ is_final_block = i == len(block_out_channels) - 1
+
+ prev_output_channel = output_channel
+ output_channel = reversed_block_out_channels[i]
+ input_channel = reversed_block_out_channels[
+ min(i + 1, len(block_out_channels) - 1)
+ ]
+
+ # add upsample block for all BUT final layer
+ if not is_final_block:
+ add_upsample = True
+ self.num_upsamplers += 1
+ else:
+ add_upsample = False
+
+ up_block = get_up_block(
+ up_block_type,
+ num_layers=layers_per_block + 1,
+ in_channels=input_channel,
+ out_channels=output_channel,
+ prev_output_channel=prev_output_channel,
+ temb_channels=time_embed_dim,
+ add_upsample=add_upsample,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ cross_attention_dim=cross_attention_dim,
+ attn_num_head_channels=reversed_attention_head_dim[i],
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention[i],
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module
+ and (res in motion_module_resolutions),
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ use_audio_module=use_audio_module,
+ audio_attention_dim=audio_attention_dim,
+ depth=3-i,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ self.up_blocks.append(up_block)
+ prev_output_channel = output_channel
+
+ # out
+ if use_inflated_groupnorm:
+ self.conv_norm_out = InflatedGroupNorm(
+ num_channels=block_out_channels[0],
+ num_groups=norm_num_groups,
+ eps=norm_eps,
+ )
+ else:
+ self.conv_norm_out = nn.GroupNorm(
+ num_channels=block_out_channels[0],
+ num_groups=norm_num_groups,
+ eps=norm_eps,
+ )
+ self.conv_act = nn.SiLU()
+ self.conv_out = InflatedConv3d(
+ block_out_channels[0], out_channels, kernel_size=3, padding=1
+ )
+
+ @property
+ # Copied from diffusers.models.unet_2d_condition.UNet2DConditionModel.attn_processors
+ def attn_processors(self) -> Dict[str, AttentionProcessor]:
+ r"""
+ Returns:
+ `dict` of attention processors: A dictionary containing all attention processors used in the model with
+ indexed by its weight name.
+ """
+ # set recursively
+ processors = {}
+
+ def fn_recursive_add_processors(
+ name: str,
+ module: torch.nn.Module,
+ processors: Dict[str, AttentionProcessor],
+ ):
+ if hasattr(module, "set_processor"):
+ processors[f"{name}.processor"] = module.processor
+
+ for sub_name, child in module.named_children():
+ if "temporal_transformer" not in sub_name:
+ fn_recursive_add_processors(
+ f"{name}.{sub_name}", child, processors)
+
+ return processors
+
+ for name, module in self.named_children():
+ if "temporal_transformer" not in name:
+ fn_recursive_add_processors(name, module, processors)
+
+ return processors
+
+ def set_attention_slice(self, slice_size):
+ r"""
+ Enable sliced attention computation.
+
+ When this option is enabled, the attention module will split the input tensor in slices, to compute attention
+ in several steps. This is useful to save some memory in exchange for a small speed decrease.
+
+ Args:
+ slice_size (`str` or `int` or `list(int)`, *optional*, defaults to `"auto"`):
+ When `"auto"`, halves the input to the attention heads, so attention will be computed in two steps. If
+ `"max"`, maxium amount of memory will be saved by running only one slice at a time. If a number is
+ provided, uses as many slices as `attention_head_dim // slice_size`. In this case, `attention_head_dim`
+ must be a multiple of `slice_size`.
+ """
+ sliceable_head_dims = []
+
+ def fn_recursive_retrieve_slicable_dims(module: torch.nn.Module):
+ if hasattr(module, "set_attention_slice"):
+ sliceable_head_dims.append(module.sliceable_head_dim)
+
+ for child in module.children():
+ fn_recursive_retrieve_slicable_dims(child)
+
+ # retrieve number of attention layers
+ for module in self.children():
+ fn_recursive_retrieve_slicable_dims(module)
+
+ num_slicable_layers = len(sliceable_head_dims)
+
+ if slice_size == "auto":
+ # half the attention head size is usually a good trade-off between
+ # speed and memory
+ slice_size = [dim // 2 for dim in sliceable_head_dims]
+ elif slice_size == "max":
+ # make smallest slice possible
+ slice_size = num_slicable_layers * [1]
+
+ slice_size = (
+ num_slicable_layers * [slice_size]
+ if not isinstance(slice_size, list)
+ else slice_size
+ )
+
+ if len(slice_size) != len(sliceable_head_dims):
+ raise ValueError(
+ f"You have provided {len(slice_size)}, but {self.config} has {len(sliceable_head_dims)} different"
+ f" attention layers. Make sure to match `len(slice_size)` to be {len(sliceable_head_dims)}."
+ )
+
+ for i, size in enumerate(slice_size):
+ dim = sliceable_head_dims[i]
+ if size is not None and size > dim:
+ raise ValueError(
+ f"size {size} has to be smaller or equal to {dim}.")
+
+ # Recursively walk through all the children.
+ # Any children which exposes the set_attention_slice method
+ # gets the message
+ def fn_recursive_set_attention_slice(
+ module: torch.nn.Module, slice_size: List[int]
+ ):
+ if hasattr(module, "set_attention_slice"):
+ module.set_attention_slice(slice_size.pop())
+
+ for child in module.children():
+ fn_recursive_set_attention_slice(child, slice_size)
+
+ reversed_slice_size = list(reversed(slice_size))
+ for module in self.children():
+ fn_recursive_set_attention_slice(module, reversed_slice_size)
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ if hasattr(module, "gradient_checkpointing"):
+ module.gradient_checkpointing = value
+
+ # Copied from diffusers.models.unet_2d_condition.UNet2DConditionModel.set_attn_processor
+ def set_attn_processor(
+ self, processor: Union[AttentionProcessor, Dict[str, AttentionProcessor]]
+ ):
+ r"""
+ Sets the attention processor to use to compute attention.
+
+ Parameters:
+ processor (`dict` of `AttentionProcessor` or only `AttentionProcessor`):
+ The instantiated processor class or a dictionary of processor classes that will be set as the processor
+ for **all** `Attention` layers.
+
+ If `processor` is a dict, the key needs to define the path to the corresponding cross attention
+ processor. This is strongly recommended when setting trainable attention processors.
+
+ """
+ count = len(self.attn_processors.keys())
+
+ if isinstance(processor, dict) and len(processor) != count:
+ raise ValueError(
+ f"A dict of processors was passed, but the number of processors {len(processor)} does not match the"
+ f" number of attention layers: {count}. Please make sure to pass {count} processor classes."
+ )
+
+ def fn_recursive_attn_processor(name: str, module: torch.nn.Module, processor):
+ if hasattr(module, "set_processor"):
+ if not isinstance(processor, dict):
+ module.set_processor(processor)
+ else:
+ module.set_processor(processor.pop(f"{name}.processor"))
+
+ for sub_name, child in module.named_children():
+ if "temporal_transformer" not in sub_name:
+ fn_recursive_attn_processor(
+ f"{name}.{sub_name}", child, processor)
+
+ for name, module in self.named_children():
+ if "temporal_transformer" not in name:
+ fn_recursive_attn_processor(name, module, processor)
+
+ def forward(
+ self,
+ sample: torch.FloatTensor,
+ timestep: Union[torch.Tensor, float, int],
+ encoder_hidden_states: torch.Tensor,
+ audio_embedding: Optional[torch.Tensor] = None,
+ class_labels: Optional[torch.Tensor] = None,
+ mask_cond_fea: Optional[torch.Tensor] = None,
+ attention_mask: Optional[torch.Tensor] = None,
+ full_mask: Optional[torch.Tensor] = None,
+ face_mask: Optional[torch.Tensor] = None,
+ lip_mask: Optional[torch.Tensor] = None,
+ motion_scale: Optional[torch.Tensor] = None,
+ down_block_additional_residuals: Optional[Tuple[torch.Tensor]] = None,
+ mid_block_additional_residual: Optional[torch.Tensor] = None,
+ return_dict: bool = True,
+ # start: bool = False,
+ ) -> Union[UNet3DConditionOutput, Tuple]:
+ r"""
+ Args:
+ sample (`torch.FloatTensor`): (batch, channel, height, width) noisy inputs tensor
+ timestep (`torch.FloatTensor` or `float` or `int`): (batch) timesteps
+ encoder_hidden_states (`torch.FloatTensor`): (batch, sequence_length, feature_dim) encoder hidden states
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`models.unet_2d_condition.UNet2DConditionOutput`] instead of a plain tuple.
+
+ Returns:
+ [`~models.unet_2d_condition.UNet2DConditionOutput`] or `tuple`:
+ [`~models.unet_2d_condition.UNet2DConditionOutput`] if `return_dict` is True, otherwise a `tuple`. When
+ returning a tuple, the first element is the sample tensor.
+ """
+ # By default samples have to be AT least a multiple of the overall upsampling factor.
+ # The overall upsampling factor is equal to 2 ** (# num of upsampling layears).
+ # However, the upsampling interpolation output size can be forced to fit any upsampling size
+ # on the fly if necessary.
+ default_overall_up_factor = 2**self.num_upsamplers
+
+ # upsample size should be forwarded when sample is not a multiple of `default_overall_up_factor`
+ forward_upsample_size = False
+ upsample_size = None
+
+ if any(s % default_overall_up_factor != 0 for s in sample.shape[-2:]):
+ logger.info(
+ "Forward upsample size to force interpolation output size.")
+ forward_upsample_size = True
+
+ # prepare attention_mask
+ if attention_mask is not None:
+ attention_mask = (1 - attention_mask.to(sample.dtype)) * -10000.0
+ attention_mask = attention_mask.unsqueeze(1)
+
+ # center input if necessary
+ if self.config.center_input_sample:
+ sample = 2 * sample - 1.0
+
+ # time
+ timesteps = timestep
+ if not torch.is_tensor(timesteps):
+ # This would be a good case for the `match` statement (Python 3.10+)
+ is_mps = sample.device.type == "mps"
+ if isinstance(timestep, float):
+ dtype = torch.float32 if is_mps else torch.float64
+ else:
+ dtype = torch.int32 if is_mps else torch.int64
+ timesteps = torch.tensor(
+ [timesteps], dtype=dtype, device=sample.device)
+ elif len(timesteps.shape) == 0:
+ timesteps = timesteps[None].to(sample.device)
+
+ # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
+ timesteps = timesteps.expand(sample.shape[0])
+
+ t_emb = self.time_proj(timesteps)
+
+ # timesteps does not contain any weights and will always return f32 tensors
+ # but time_embedding might actually be running in fp16. so we need to cast here.
+ # there might be better ways to encapsulate this.
+ t_emb = t_emb.to(dtype=self.dtype)
+ emb = self.time_embedding(t_emb)
+
+ if self.class_embedding is not None:
+ if class_labels is None:
+ raise ValueError(
+ "class_labels should be provided when num_class_embeds > 0"
+ )
+
+ if self.config.class_embed_type == "timestep":
+ class_labels = self.time_proj(class_labels)
+
+ class_emb = self.class_embedding(class_labels).to(dtype=self.dtype)
+ emb = emb + class_emb
+
+ # pre-process
+ sample = self.conv_in(sample)
+ if mask_cond_fea is not None:
+ sample = sample + mask_cond_fea
+
+ # down
+ down_block_res_samples = (sample,)
+ for downsample_block in self.down_blocks:
+ if (
+ hasattr(downsample_block, "has_cross_attention")
+ and downsample_block.has_cross_attention
+ ):
+ sample, res_samples = downsample_block(
+ hidden_states=sample,
+ temb=emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ audio_embedding=audio_embedding,
+ motion_scale=motion_scale,
+ )
+ # print("")
+ else:
+ sample, res_samples = downsample_block(
+ hidden_states=sample,
+ temb=emb,
+ encoder_hidden_states=encoder_hidden_states,
+ # audio_embedding=audio_embedding,
+ )
+ # print("")
+
+ down_block_res_samples += res_samples
+
+ if down_block_additional_residuals is not None:
+ new_down_block_res_samples = ()
+
+ for down_block_res_sample, down_block_additional_residual in zip(
+ down_block_res_samples, down_block_additional_residuals
+ ):
+ down_block_res_sample = (
+ down_block_res_sample + down_block_additional_residual
+ )
+ new_down_block_res_samples += (down_block_res_sample,)
+
+ down_block_res_samples = new_down_block_res_samples
+
+ # mid
+ sample = self.mid_block(
+ sample,
+ emb,
+ encoder_hidden_states=encoder_hidden_states,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ audio_embedding=audio_embedding,
+ motion_scale=motion_scale,
+ )
+
+ if mid_block_additional_residual is not None:
+ sample = sample + mid_block_additional_residual
+
+ # up
+ for i, upsample_block in enumerate(self.up_blocks):
+ is_final_block = i == len(self.up_blocks) - 1
+
+ res_samples = down_block_res_samples[-len(upsample_block.resnets):]
+ down_block_res_samples = down_block_res_samples[
+ : -len(upsample_block.resnets)
+ ]
+
+ # if we have not reached the final block and need to forward the
+ # upsample size, we do it here
+ if not is_final_block and forward_upsample_size:
+ upsample_size = down_block_res_samples[-1].shape[2:]
+
+ if (
+ hasattr(upsample_block, "has_cross_attention")
+ and upsample_block.has_cross_attention
+ ):
+ sample = upsample_block(
+ hidden_states=sample,
+ temb=emb,
+ res_hidden_states_tuple=res_samples,
+ encoder_hidden_states=encoder_hidden_states,
+ upsample_size=upsample_size,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ audio_embedding=audio_embedding,
+ motion_scale=motion_scale,
+ )
+ else:
+ sample = upsample_block(
+ hidden_states=sample,
+ temb=emb,
+ res_hidden_states_tuple=res_samples,
+ upsample_size=upsample_size,
+ encoder_hidden_states=encoder_hidden_states,
+ # audio_embedding=audio_embedding,
+ )
+
+ # post-process
+ sample = self.conv_norm_out(sample)
+ sample = self.conv_act(sample)
+ sample = self.conv_out(sample)
+
+ if not return_dict:
+ return (sample,)
+
+ return UNet3DConditionOutput(sample=sample)
+
+ @classmethod
+ def from_pretrained_2d(
+ cls,
+ pretrained_model_path: PathLike,
+ motion_module_path: PathLike,
+ subfolder=None,
+ unet_additional_kwargs=None,
+ mm_zero_proj_out=False,
+ use_landmark=True,
+ ):
+ """
+ Load a pre-trained 2D UNet model from a given directory.
+
+ Parameters:
+ pretrained_model_path (`str` or `PathLike`):
+ Path to the directory containing a pre-trained 2D UNet model.
+ dtype (`torch.dtype`, *optional*):
+ The data type of the loaded model. If not provided, the default data type is used.
+ device (`torch.device`, *optional*):
+ The device on which the loaded model will be placed. If not provided, the default device is used.
+ **kwargs (`Any`):
+ Additional keyword arguments passed to the model.
+
+ Returns:
+ `UNet3DConditionModel`:
+ The loaded 2D UNet model.
+ """
+ pretrained_model_path = Path(pretrained_model_path)
+ motion_module_path = Path(motion_module_path)
+ if subfolder is not None:
+ pretrained_model_path = pretrained_model_path.joinpath(subfolder)
+ logger.info(
+ f"loaded temporal unet's pretrained weights from {pretrained_model_path} ..."
+ )
+
+ config_file = pretrained_model_path / "config.json"
+ if not (config_file.exists() and config_file.is_file()):
+ raise RuntimeError(
+ f"{config_file} does not exist or is not a file")
+
+ unet_config = cls.load_config(config_file)
+ unet_config["_class_name"] = cls.__name__
+ unet_config["down_block_types"] = [
+ "CrossAttnDownBlock3D",
+ "CrossAttnDownBlock3D",
+ "CrossAttnDownBlock3D",
+ "DownBlock3D",
+ ]
+ unet_config["up_block_types"] = [
+ "UpBlock3D",
+ "CrossAttnUpBlock3D",
+ "CrossAttnUpBlock3D",
+ "CrossAttnUpBlock3D",
+ ]
+ unet_config["mid_block_type"] = "UNetMidBlock3DCrossAttn"
+ if use_landmark:
+ unet_config["in_channels"] = 8
+ unet_config["out_channels"] = 8
+
+ model = cls.from_config(unet_config, **unet_additional_kwargs)
+ # load the vanilla weights
+ if pretrained_model_path.joinpath(SAFETENSORS_WEIGHTS_NAME).exists():
+ logger.debug(
+ f"loading safeTensors weights from {pretrained_model_path} ..."
+ )
+ state_dict = load_file(
+ pretrained_model_path.joinpath(SAFETENSORS_WEIGHTS_NAME), device="cpu"
+ )
+
+ elif pretrained_model_path.joinpath(WEIGHTS_NAME).exists():
+ logger.debug(f"loading weights from {pretrained_model_path} ...")
+ state_dict = torch.load(
+ pretrained_model_path.joinpath(WEIGHTS_NAME),
+ map_location="cpu",
+ weights_only=True,
+ )
+ else:
+ raise FileNotFoundError(
+ f"no weights file found in {pretrained_model_path}")
+
+ # load the motion module weights
+ if motion_module_path.exists() and motion_module_path.is_file():
+ if motion_module_path.suffix.lower() in [".pth", ".pt", ".ckpt"]:
+ print(
+ f"Load motion module params from {motion_module_path}")
+ motion_state_dict = torch.load(
+ motion_module_path, map_location="cpu", weights_only=True
+ )
+ elif motion_module_path.suffix.lower() == ".safetensors":
+ motion_state_dict = load_file(motion_module_path, device="cpu")
+ else:
+ raise RuntimeError(
+ f"unknown file format for motion module weights: {motion_module_path.suffix}"
+ )
+ if mm_zero_proj_out:
+ logger.info(
+ "Zero initialize proj_out layers in motion module...")
+ new_motion_state_dict = OrderedDict()
+ for k in motion_state_dict:
+ if "proj_out" in k:
+ continue
+ new_motion_state_dict[k] = motion_state_dict[k]
+ motion_state_dict = new_motion_state_dict
+
+ # merge the state dicts
+ state_dict.update(motion_state_dict)
+
+ model_state_dict = model.state_dict()
+ for k in state_dict:
+ if k in model_state_dict:
+ if state_dict[k].shape != model_state_dict[k].shape:
+ state_dict[k] = model_state_dict[k]
+ # load the weights into the model
+ m, u = model.load_state_dict(state_dict, strict=False)
+ logger.debug(
+ f"### missing keys: {len(m)}; \n### unexpected keys: {len(u)};")
+
+ params = [
+ p.numel() if "temporal" in n else 0 for n, p in model.named_parameters()
+ ]
+ logger.info(f"Loaded {sum(params) / 1e6}M-parameter motion module")
+
+ return model
diff --git a/animation/hallo-83dd4eb/hallo/models/unet_3d_blocks.py b/animation/hallo-83dd4eb/hallo/models/unet_3d_blocks.py
new file mode 100644
index 0000000..d940294
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/unet_3d_blocks.py
@@ -0,0 +1,1401 @@
+# pylint: disable=R0801
+# src/models/unet_3d_blocks.py
+
+"""
+This module defines various 3D UNet blocks used in the video model.
+
+The blocks include:
+- UNetMidBlock3DCrossAttn: The middle block of the UNet with cross attention.
+- CrossAttnDownBlock3D: The downsampling block with cross attention.
+- DownBlock3D: The standard downsampling block without cross attention.
+- CrossAttnUpBlock3D: The upsampling block with cross attention.
+- UpBlock3D: The standard upsampling block without cross attention.
+
+These blocks are used to construct the 3D UNet architecture for video-related tasks.
+"""
+
+import torch
+from einops import rearrange
+from torch import nn
+
+from .motion_module import get_motion_module
+from .resnet import Downsample3D, ResnetBlock3D, Upsample3D
+from .transformer_3d import Transformer3DModel
+
+
+def get_down_block(
+ down_block_type,
+ num_layers,
+ in_channels,
+ out_channels,
+ temb_channels,
+ add_downsample,
+ resnet_eps,
+ resnet_act_fn,
+ attn_num_head_channels,
+ resnet_groups=None,
+ cross_attention_dim=None,
+ audio_attention_dim=None,
+ downsample_padding=None,
+ dual_cross_attention=False,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ resnet_time_scale_shift="default",
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ use_audio_module=None,
+ depth=0,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+):
+ """
+ Factory function to instantiate a down-block module for the 3D UNet architecture.
+
+ Down blocks are used in the downsampling part of the U-Net to reduce the spatial dimensions
+ of the feature maps while increasing the depth. This function can create blocks with or without
+ cross attention based on the specified parameters.
+
+ Parameters:
+ - down_block_type (str): The type of down block to instantiate.
+ - num_layers (int): The number of layers in the block.
+ - in_channels (int): The number of input channels.
+ - out_channels (int): The number of output channels.
+ - temb_channels (int): The number of token embedding channels.
+ - add_downsample (bool): Flag to add a downsampling layer.
+ - resnet_eps (float): Epsilon for residual block stability.
+ - resnet_act_fn (callable): Activation function for the residual block.
+ - ... (remaining parameters): Additional parameters for configuring the block.
+
+ Returns:
+ - nn.Module: An instance of a down-sampling block module.
+ """
+ down_block_type = (
+ down_block_type[7:]
+ if down_block_type.startswith("UNetRes")
+ else down_block_type
+ )
+ if down_block_type == "DownBlock3D":
+ return DownBlock3D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+
+ if down_block_type == "CrossAttnDownBlock3D":
+ if cross_attention_dim is None:
+ raise ValueError(
+ "cross_attention_dim must be specified for CrossAttnDownBlock3D"
+ )
+ return CrossAttnDownBlock3D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ add_downsample=add_downsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ downsample_padding=downsample_padding,
+ cross_attention_dim=cross_attention_dim,
+ audio_attention_dim=audio_attention_dim,
+ attn_num_head_channels=attn_num_head_channels,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ use_audio_module=use_audio_module,
+ depth=depth,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ raise ValueError(f"{down_block_type} does not exist.")
+
+
+def get_up_block(
+ up_block_type,
+ num_layers,
+ in_channels,
+ out_channels,
+ prev_output_channel,
+ temb_channels,
+ add_upsample,
+ resnet_eps,
+ resnet_act_fn,
+ attn_num_head_channels,
+ resnet_groups=None,
+ cross_attention_dim=None,
+ audio_attention_dim=None,
+ dual_cross_attention=False,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ resnet_time_scale_shift="default",
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ use_audio_module=None,
+ depth=0,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+):
+ """
+ Factory function to instantiate an up-block module for the 3D UNet architecture.
+
+ Up blocks are used in the upsampling part of the U-Net to increase the spatial dimensions
+ of the feature maps while decreasing the depth. This function can create blocks with or without
+ cross attention based on the specified parameters.
+
+ Parameters:
+ - up_block_type (str): The type of up block to instantiate.
+ - num_layers (int): The number of layers in the block.
+ - in_channels (int): The number of input channels.
+ - out_channels (int): The number of output channels.
+ - prev_output_channel (int): The number of channels from the previous layer's output.
+ - temb_channels (int): The number of token embedding channels.
+ - add_upsample (bool): Flag to add an upsampling layer.
+ - resnet_eps (float): Epsilon for residual block stability.
+ - resnet_act_fn (callable): Activation function for the residual block.
+ - ... (remaining parameters): Additional parameters for configuring the block.
+
+ Returns:
+ - nn.Module: An instance of an up-sampling block module.
+ """
+ up_block_type = (
+ up_block_type[7:] if up_block_type.startswith("UNetRes") else up_block_type
+ )
+ if up_block_type == "UpBlock3D":
+ return UpBlock3D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+
+ if up_block_type == "CrossAttnUpBlock3D":
+ if cross_attention_dim is None:
+ raise ValueError(
+ "cross_attention_dim must be specified for CrossAttnUpBlock3D"
+ )
+ return CrossAttnUpBlock3D(
+ num_layers=num_layers,
+ in_channels=in_channels,
+ out_channels=out_channels,
+ prev_output_channel=prev_output_channel,
+ temb_channels=temb_channels,
+ add_upsample=add_upsample,
+ resnet_eps=resnet_eps,
+ resnet_act_fn=resnet_act_fn,
+ resnet_groups=resnet_groups,
+ cross_attention_dim=cross_attention_dim,
+ audio_attention_dim=audio_attention_dim,
+ attn_num_head_channels=attn_num_head_channels,
+ dual_cross_attention=dual_cross_attention,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ resnet_time_scale_shift=resnet_time_scale_shift,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ use_motion_module=use_motion_module,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ use_audio_module=use_audio_module,
+ depth=depth,
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ raise ValueError(f"{up_block_type} does not exist.")
+
+
+class UNetMidBlock3DCrossAttn(nn.Module):
+ """
+ A 3D UNet middle block with cross attention mechanism. This block is part of the U-Net architecture
+ and is used for feature extraction in the middle of the downsampling path.
+
+ Parameters:
+ - in_channels (int): Number of input channels.
+ - temb_channels (int): Number of token embedding channels.
+ - dropout (float): Dropout rate.
+ - num_layers (int): Number of layers in the block.
+ - resnet_eps (float): Epsilon for residual block.
+ - resnet_time_scale_shift (str): Time scale shift for time embedding normalization.
+ - resnet_act_fn (str): Activation function for the residual block.
+ - resnet_groups (int): Number of groups for the convolutions in the residual block.
+ - resnet_pre_norm (bool): Whether to use pre-normalization in the residual block.
+ - attn_num_head_channels (int): Number of attention heads.
+ - cross_attention_dim (int): Dimensionality of the cross attention layers.
+ - audio_attention_dim (int): Dimensionality of the audio attention layers.
+ - dual_cross_attention (bool): Whether to use dual cross attention.
+ - use_linear_projection (bool): Whether to use linear projection in attention.
+ - upcast_attention (bool): Whether to upcast attention to the original input dimension.
+ - unet_use_cross_frame_attention (bool): Whether to use cross frame attention in U-Net.
+ - unet_use_temporal_attention (bool): Whether to use temporal attention in U-Net.
+ - use_inflated_groupnorm (bool): Whether to use inflated group normalization.
+ - use_motion_module (bool): Whether to use motion module.
+ - motion_module_type (str): Type of motion module.
+ - motion_module_kwargs (dict): Keyword arguments for the motion module.
+ - use_audio_module (bool): Whether to use audio module.
+ - depth (int): Depth of the block in the network.
+ - stack_enable_blocks_name (str): Name of the stack enable blocks.
+ - stack_enable_blocks_depth (int): Depth of the stack enable blocks.
+
+ Forward method:
+ The forward method applies the residual blocks, cross attention, and optional motion and audio modules
+ to the input hidden states. It returns the transformed hidden states.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ attn_num_head_channels=1,
+ output_scale_factor=1.0,
+ cross_attention_dim=1280,
+ audio_attention_dim=1024,
+ dual_cross_attention=False,
+ use_linear_projection=False,
+ upcast_attention=False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ use_audio_module=None,
+ depth=0,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+ ):
+ super().__init__()
+
+ self.has_cross_attention = True
+ self.attn_num_head_channels = attn_num_head_channels
+ resnet_groups = (
+ resnet_groups if resnet_groups is not None else min(in_channels // 4, 32)
+ )
+
+ # there is always at least one resnet
+ resnets = [
+ ResnetBlock3D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ ]
+ attentions = []
+ motion_modules = []
+ audio_modules = []
+
+ for _ in range(num_layers):
+ if dual_cross_attention:
+ raise NotImplementedError
+ attentions.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ in_channels // attn_num_head_channels,
+ in_channels=in_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ )
+ )
+ audio_modules.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ in_channels // attn_num_head_channels,
+ in_channels=in_channels,
+ num_layers=1,
+ cross_attention_dim=audio_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ upcast_attention=upcast_attention,
+ use_audio_module=use_audio_module,
+ depth=depth,
+ unet_block_name="mid",
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ if use_audio_module
+ else None
+ )
+
+ motion_modules.append(
+ get_motion_module(
+ in_channels=in_channels,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+ if use_motion_module
+ else None
+ )
+ resnets.append(
+ ResnetBlock3D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+ self.audio_modules = nn.ModuleList(audio_modules)
+ self.motion_modules = nn.ModuleList(motion_modules)
+
+ def forward(
+ self,
+ hidden_states,
+ temb=None,
+ encoder_hidden_states=None,
+ attention_mask=None,
+ full_mask=None,
+ face_mask=None,
+ lip_mask=None,
+ audio_embedding=None,
+ motion_scale=None,
+ ):
+ """
+ Forward pass for the UNetMidBlock3DCrossAttn class.
+
+ Args:
+ self (UNetMidBlock3DCrossAttn): An instance of the UNetMidBlock3DCrossAttn class.
+ hidden_states (Tensor): The input hidden states tensor.
+ temb (Tensor, optional): The input temporal embedding tensor. Defaults to None.
+ encoder_hidden_states (Tensor, optional): The encoder hidden states tensor. Defaults to None.
+ attention_mask (Tensor, optional): The attention mask tensor. Defaults to None.
+ full_mask (Tensor, optional): The full mask tensor. Defaults to None.
+ face_mask (Tensor, optional): The face mask tensor. Defaults to None.
+ lip_mask (Tensor, optional): The lip mask tensor. Defaults to None.
+ audio_embedding (Tensor, optional): The audio embedding tensor. Defaults to None.
+
+ Returns:
+ Tensor: The output tensor after passing through the UNetMidBlock3DCrossAttn layers.
+ """
+ hidden_states = self.resnets[0](hidden_states, temb)
+ for attn, resnet, audio_module, motion_module in zip(
+ self.attentions, self.resnets[1:], self.audio_modules, self.motion_modules
+ ):
+ hidden_states, motion_frame = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ return_dict=False,
+ ) # .sample
+ if len(motion_frame[0]) > 0:
+ # if motion_frame[0][0].numel() > 0:
+ motion_frames = motion_frame[0][0]
+ motion_frames = rearrange(
+ motion_frames,
+ "b f (d1 d2) c -> b c f d1 d2",
+ d1=hidden_states.size(-1),
+ )
+
+ else:
+ motion_frames = torch.zeros(
+ hidden_states.shape[0],
+ hidden_states.shape[1],
+ 4,
+ hidden_states.shape[3],
+ hidden_states.shape[4],
+ )
+
+ n_motion_frames = motion_frames.size(2)
+ if audio_module is not None:
+ hidden_states = (
+ audio_module(
+ hidden_states,
+ encoder_hidden_states=audio_embedding,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ motion_scale=motion_scale,
+ return_dict=False,
+ )
+ )[0] # .sample
+ if motion_module is not None:
+ motion_frames = motion_frames.to(
+ device=hidden_states.device, dtype=hidden_states.dtype
+ )
+
+ _hidden_states = (
+ torch.cat([motion_frames, hidden_states], dim=2)
+ if n_motion_frames > 0
+ else hidden_states
+ )
+ hidden_states = motion_module(
+ _hidden_states, encoder_hidden_states=encoder_hidden_states
+ )
+ hidden_states = hidden_states[:, :, n_motion_frames:]
+
+ hidden_states = resnet(hidden_states, temb)
+
+ return hidden_states
+
+
+class CrossAttnDownBlock3D(nn.Module):
+ """
+ A 3D downsampling block with cross attention for the U-Net architecture.
+
+ Parameters:
+ - (same as above, refer to the constructor for details)
+
+ Forward method:
+ The forward method downsamples the input hidden states using residual blocks and cross attention.
+ It also applies optional motion and audio modules. The method supports gradient checkpointing
+ to save memory during training.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ attn_num_head_channels=1,
+ cross_attention_dim=1280,
+ audio_attention_dim=1024,
+ output_scale_factor=1.0,
+ downsample_padding=1,
+ add_downsample=True,
+ dual_cross_attention=False,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ use_audio_module=None,
+ depth=0,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+ audio_modules = []
+ motion_modules = []
+
+ self.has_cross_attention = True
+ self.attn_num_head_channels = attn_num_head_channels
+
+ for i in range(num_layers):
+ in_channels = in_channels if i == 0 else out_channels
+ resnets.append(
+ ResnetBlock3D(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ )
+ if dual_cross_attention:
+ raise NotImplementedError
+ attentions.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ out_channels // attn_num_head_channels,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ )
+ )
+ # TODO:检查维度
+ audio_modules.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ in_channels // attn_num_head_channels,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=audio_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ use_audio_module=use_audio_module,
+ depth=depth,
+ unet_block_name="down",
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ if use_audio_module
+ else None
+ )
+ motion_modules.append(
+ get_motion_module(
+ in_channels=out_channels,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+ if use_motion_module
+ else None
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+ self.audio_modules = nn.ModuleList(audio_modules)
+ self.motion_modules = nn.ModuleList(motion_modules)
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ Downsample3D(
+ out_channels,
+ use_conv=True,
+ out_channels=out_channels,
+ padding=downsample_padding,
+ name="op",
+ )
+ ]
+ )
+ else:
+ self.downsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ temb=None,
+ encoder_hidden_states=None,
+ attention_mask=None,
+ full_mask=None,
+ face_mask=None,
+ lip_mask=None,
+ audio_embedding=None,
+ motion_scale=None,
+ ):
+ """
+ Defines the forward pass for the CrossAttnDownBlock3D class.
+
+ Parameters:
+ - hidden_states : torch.Tensor
+ The input tensor to the block.
+ temb : torch.Tensor, optional
+ The token embeddings from the previous block.
+ encoder_hidden_states : torch.Tensor, optional
+ The hidden states from the encoder.
+ attention_mask : torch.Tensor, optional
+ The attention mask for the cross-attention mechanism.
+ full_mask : torch.Tensor, optional
+ The full mask for the cross-attention mechanism.
+ face_mask : torch.Tensor, optional
+ The face mask for the cross-attention mechanism.
+ lip_mask : torch.Tensor, optional
+ The lip mask for the cross-attention mechanism.
+ audio_embedding : torch.Tensor, optional
+ The audio embedding for the cross-attention mechanism.
+
+ Returns:
+ -- torch.Tensor
+ The output tensor from the block.
+ """
+ output_states = ()
+
+ for _, (resnet, attn, audio_module, motion_module) in enumerate(
+ zip(self.resnets, self.attentions, self.audio_modules, self.motion_modules)
+ ):
+ # self.gradient_checkpointing = False
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+
+ motion_frames = []
+ hidden_states, motion_frame = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(attn, return_dict=False),
+ hidden_states,
+ encoder_hidden_states,
+ )
+ if len(motion_frame[0]) > 0:
+ motion_frames = motion_frame[0][0]
+ # motion_frames = torch.cat(motion_frames, dim=0)
+ motion_frames = rearrange(
+ motion_frames,
+ "b f (d1 d2) c -> b c f d1 d2",
+ d1=hidden_states.size(-1),
+ )
+
+ else:
+ motion_frames = torch.zeros(
+ hidden_states.shape[0],
+ hidden_states.shape[1],
+ 4,
+ hidden_states.shape[3],
+ hidden_states.shape[4],
+ )
+
+ n_motion_frames = motion_frames.size(2)
+
+ if audio_module is not None:
+ # audio_embedding = audio_embedding
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(audio_module, return_dict=False),
+ hidden_states,
+ audio_embedding,
+ attention_mask,
+ full_mask,
+ face_mask,
+ lip_mask,
+ motion_scale,
+ )[0]
+
+ # add motion module
+ if motion_module is not None:
+ motion_frames = motion_frames.to(
+ device=hidden_states.device, dtype=hidden_states.dtype
+ )
+ _hidden_states = torch.cat(
+ [motion_frames, hidden_states], dim=2
+ ) # if n_motion_frames > 0 else hidden_states
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(motion_module),
+ _hidden_states,
+ encoder_hidden_states,
+ )
+ hidden_states = hidden_states[:, :, n_motion_frames:]
+
+ else:
+ hidden_states = resnet(hidden_states, temb)
+ hidden_states = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ ).sample
+ if audio_module is not None:
+ hidden_states = audio_module(
+ hidden_states,
+ audio_embedding,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ return_dict=False,
+ )[0]
+ # add motion module
+ if motion_module is not None:
+ hidden_states = motion_module(
+ hidden_states, encoder_hidden_states=encoder_hidden_states
+ )
+
+ output_states += (hidden_states,)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states)
+
+ output_states += (hidden_states,)
+
+ return hidden_states, output_states
+
+
+class DownBlock3D(nn.Module):
+ """
+ A 3D downsampling block for the U-Net architecture. This block performs downsampling operations
+ using residual blocks and an optional motion module.
+
+ Parameters:
+ - in_channels (int): Number of input channels.
+ - out_channels (int): Number of output channels.
+ - temb_channels (int): Number of token embedding channels.
+ - dropout (float): Dropout rate for the block.
+ - num_layers (int): Number of layers in the block.
+ - resnet_eps (float): Epsilon for residual block stability.
+ - resnet_time_scale_shift (str): Time scale shift for the residual block's time embedding.
+ - resnet_act_fn (str): Activation function used in the residual block.
+ - resnet_groups (int): Number of groups for the convolutions in the residual block.
+ - resnet_pre_norm (bool): Whether to use pre-normalization in the residual block.
+ - output_scale_factor (float): Scaling factor for the block's output.
+ - add_downsample (bool): Whether to add a downsampling layer.
+ - downsample_padding (int): Padding for the downsampling layer.
+ - use_inflated_groupnorm (bool): Whether to use inflated group normalization.
+ - use_motion_module (bool): Whether to include a motion module.
+ - motion_module_type (str): Type of motion module to use.
+ - motion_module_kwargs (dict): Keyword arguments for the motion module.
+
+ Forward method:
+ The forward method processes the input hidden states through the residual blocks and optional
+ motion modules, followed by an optional downsampling step. It supports gradient checkpointing
+ during training to reduce memory usage.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ output_scale_factor=1.0,
+ add_downsample=True,
+ downsample_padding=1,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ ):
+ super().__init__()
+ resnets = []
+ motion_modules = []
+
+ # use_motion_module = False
+ for i in range(num_layers):
+ in_channels = in_channels if i == 0 else out_channels
+ resnets.append(
+ ResnetBlock3D(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ )
+ motion_modules.append(
+ get_motion_module(
+ in_channels=out_channels,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+ if use_motion_module
+ else None
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+ self.motion_modules = nn.ModuleList(motion_modules)
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ Downsample3D(
+ out_channels,
+ use_conv=True,
+ out_channels=out_channels,
+ padding=downsample_padding,
+ name="op",
+ )
+ ]
+ )
+ else:
+ self.downsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ temb=None,
+ encoder_hidden_states=None,
+ ):
+ """
+ forward method for the DownBlock3D class.
+
+ Args:
+ hidden_states (Tensor): The input tensor to the DownBlock3D layer.
+ temb (Tensor, optional): The token embeddings, if using transformer.
+ encoder_hidden_states (Tensor, optional): The hidden states from the encoder.
+
+ Returns:
+ Tensor: The output tensor after passing through the DownBlock3D layer.
+ """
+ output_states = ()
+
+ for resnet, motion_module in zip(self.resnets, self.motion_modules):
+ # print(f"DownBlock3D {self.gradient_checkpointing = }")
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+
+ else:
+ hidden_states = resnet(hidden_states, temb)
+
+ # add motion module
+ hidden_states = (
+ motion_module(
+ hidden_states, encoder_hidden_states=encoder_hidden_states
+ )
+ if motion_module is not None
+ else hidden_states
+ )
+
+ output_states += (hidden_states,)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states)
+
+ output_states += (hidden_states,)
+
+ return hidden_states, output_states
+
+
+class CrossAttnUpBlock3D(nn.Module):
+ """
+ Standard 3D downsampling block for the U-Net architecture. This block performs downsampling
+ operations in the U-Net using residual blocks and an optional motion module.
+
+ Parameters:
+ - in_channels (int): Number of input channels.
+ - out_channels (int): Number of output channels.
+ - temb_channels (int): Number of channels for the temporal embedding.
+ - dropout (float): Dropout rate for the block.
+ - num_layers (int): Number of layers in the block.
+ - resnet_eps (float): Epsilon for residual block stability.
+ - resnet_time_scale_shift (str): Time scale shift for the residual block's time embedding.
+ - resnet_act_fn (str): Activation function used in the residual block.
+ - resnet_groups (int): Number of groups for the convolutions in the residual block.
+ - resnet_pre_norm (bool): Whether to use pre-normalization in the residual block.
+ - output_scale_factor (float): Scaling factor for the block's output.
+ - add_downsample (bool): Whether to add a downsampling layer.
+ - downsample_padding (int): Padding for the downsampling layer.
+ - use_inflated_groupnorm (bool): Whether to use inflated group normalization.
+ - use_motion_module (bool): Whether to include a motion module.
+ - motion_module_type (str): Type of motion module to use.
+ - motion_module_kwargs (dict): Keyword arguments for the motion module.
+
+ Forward method:
+ The forward method processes the input hidden states through the residual blocks and optional
+ motion modules, followed by an optional downsampling step. It supports gradient checkpointing
+ during training to reduce memory usage.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ prev_output_channel: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ attn_num_head_channels=1,
+ cross_attention_dim=1280,
+ audio_attention_dim=1024,
+ output_scale_factor=1.0,
+ add_upsample=True,
+ dual_cross_attention=False,
+ use_linear_projection=False,
+ only_cross_attention=False,
+ upcast_attention=False,
+ unet_use_cross_frame_attention=None,
+ unet_use_temporal_attention=None,
+ use_motion_module=None,
+ use_inflated_groupnorm=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ use_audio_module=None,
+ depth=0,
+ stack_enable_blocks_name=None,
+ stack_enable_blocks_depth=None,
+ ):
+ super().__init__()
+ resnets = []
+ attentions = []
+ audio_modules = []
+ motion_modules = []
+
+ self.has_cross_attention = True
+ self.attn_num_head_channels = attn_num_head_channels
+
+ for i in range(num_layers):
+ res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
+ resnet_in_channels = prev_output_channel if i == 0 else out_channels
+
+ resnets.append(
+ ResnetBlock3D(
+ in_channels=resnet_in_channels + res_skip_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ )
+
+ if dual_cross_attention:
+ raise NotImplementedError
+ attentions.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ out_channels // attn_num_head_channels,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=cross_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ unet_use_cross_frame_attention=unet_use_cross_frame_attention,
+ unet_use_temporal_attention=unet_use_temporal_attention,
+ )
+ )
+ audio_modules.append(
+ Transformer3DModel(
+ attn_num_head_channels,
+ in_channels // attn_num_head_channels,
+ in_channels=out_channels,
+ num_layers=1,
+ cross_attention_dim=audio_attention_dim,
+ norm_num_groups=resnet_groups,
+ use_linear_projection=use_linear_projection,
+ only_cross_attention=only_cross_attention,
+ upcast_attention=upcast_attention,
+ use_audio_module=use_audio_module,
+ depth=depth,
+ unet_block_name="up",
+ stack_enable_blocks_name=stack_enable_blocks_name,
+ stack_enable_blocks_depth=stack_enable_blocks_depth,
+ )
+ if use_audio_module
+ else None
+ )
+ motion_modules.append(
+ get_motion_module(
+ in_channels=out_channels,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+ if use_motion_module
+ else None
+ )
+
+ self.attentions = nn.ModuleList(attentions)
+ self.resnets = nn.ModuleList(resnets)
+ self.audio_modules = nn.ModuleList(audio_modules)
+ self.motion_modules = nn.ModuleList(motion_modules)
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList(
+ [Upsample3D(out_channels, use_conv=True, out_channels=out_channels)]
+ )
+ else:
+ self.upsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ res_hidden_states_tuple,
+ temb=None,
+ encoder_hidden_states=None,
+ upsample_size=None,
+ attention_mask=None,
+ full_mask=None,
+ face_mask=None,
+ lip_mask=None,
+ audio_embedding=None,
+ motion_scale=None,
+ ):
+ """
+ Forward pass for the CrossAttnUpBlock3D class.
+
+ Args:
+ self (CrossAttnUpBlock3D): An instance of the CrossAttnUpBlock3D class.
+ hidden_states (Tensor): The input hidden states tensor.
+ res_hidden_states_tuple (Tuple[Tensor]): A tuple of residual hidden states tensors.
+ temb (Tensor, optional): The token embeddings tensor. Defaults to None.
+ encoder_hidden_states (Tensor, optional): The encoder hidden states tensor. Defaults to None.
+ upsample_size (int, optional): The upsample size. Defaults to None.
+ attention_mask (Tensor, optional): The attention mask tensor. Defaults to None.
+ full_mask (Tensor, optional): The full mask tensor. Defaults to None.
+ face_mask (Tensor, optional): The face mask tensor. Defaults to None.
+ lip_mask (Tensor, optional): The lip mask tensor. Defaults to None.
+ audio_embedding (Tensor, optional): The audio embedding tensor. Defaults to None.
+
+ Returns:
+ Tensor: The output tensor after passing through the CrossAttnUpBlock3D.
+ """
+ for _, (resnet, attn, audio_module, motion_module) in enumerate(
+ zip(self.resnets, self.attentions, self.audio_modules, self.motion_modules)
+ ):
+ # pop res hidden states
+ res_hidden_states = res_hidden_states_tuple[-1]
+ res_hidden_states_tuple = res_hidden_states_tuple[:-1]
+ hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
+
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module, return_dict=None):
+ def custom_forward(*inputs):
+ if return_dict is not None:
+ return module(*inputs, return_dict=return_dict)
+
+ return module(*inputs)
+
+ return custom_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+
+ motion_frames = []
+ hidden_states, motion_frame = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(attn, return_dict=False),
+ hidden_states,
+ encoder_hidden_states,
+ )
+ if len(motion_frame[0]) > 0:
+ motion_frames = motion_frame[0][0]
+ # motion_frames = torch.cat(motion_frames, dim=0)
+ motion_frames = rearrange(
+ motion_frames,
+ "b f (d1 d2) c -> b c f d1 d2",
+ d1=hidden_states.size(-1),
+ )
+ else:
+ motion_frames = torch.zeros(
+ hidden_states.shape[0],
+ hidden_states.shape[1],
+ 4,
+ hidden_states.shape[3],
+ hidden_states.shape[4],
+ )
+
+ n_motion_frames = motion_frames.size(2)
+
+ if audio_module is not None:
+ # audio_embedding = audio_embedding
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(audio_module, return_dict=False),
+ hidden_states,
+ audio_embedding,
+ attention_mask,
+ full_mask,
+ face_mask,
+ lip_mask,
+ motion_scale,
+ )[0]
+
+ # add motion module
+ if motion_module is not None:
+ motion_frames = motion_frames.to(
+ device=hidden_states.device, dtype=hidden_states.dtype
+ )
+
+ _hidden_states = (
+ torch.cat([motion_frames, hidden_states], dim=2)
+ if n_motion_frames > 0
+ else hidden_states
+ )
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(motion_module),
+ _hidden_states,
+ encoder_hidden_states,
+ )
+ hidden_states = hidden_states[:, :, n_motion_frames:]
+ else:
+ hidden_states = resnet(hidden_states, temb)
+ hidden_states = attn(
+ hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ ).sample
+
+ if audio_module is not None:
+
+ hidden_states = (
+ audio_module(
+ hidden_states,
+ encoder_hidden_states=audio_embedding,
+ attention_mask=attention_mask,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask,
+ )
+ ).sample
+ # add motion module
+ hidden_states = (
+ motion_module(
+ hidden_states, encoder_hidden_states=encoder_hidden_states
+ )
+ if motion_module is not None
+ else hidden_states
+ )
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(hidden_states, upsample_size)
+
+ return hidden_states
+
+
+class UpBlock3D(nn.Module):
+ """
+ 3D upsampling block with cross attention for the U-Net architecture. This block performs
+ upsampling operations and incorporates cross attention mechanisms, which allow the model to
+ focus on different parts of the input when upscaling.
+
+ Parameters:
+ - in_channels (int): Number of input channels.
+ - out_channels (int): Number of output channels.
+ - prev_output_channel (int): Number of channels from the previous layer's output.
+ - temb_channels (int): Number of channels for the temporal embedding.
+ - dropout (float): Dropout rate for the block.
+ - num_layers (int): Number of layers in the block.
+ - resnet_eps (float): Epsilon for residual block stability.
+ - resnet_time_scale_shift (str): Time scale shift for the residual block's time embedding.
+ - resnet_act_fn (str): Activation function used in the residual block.
+ - resnet_groups (int): Number of groups for the convolutions in the residual block.
+ - resnet_pre_norm (bool): Whether to use pre-normalization in the residual block.
+ - attn_num_head_channels (int): Number of attention heads for the cross attention mechanism.
+ - cross_attention_dim (int): Dimensionality of the cross attention layers.
+ - audio_attention_dim (int): Dimensionality of the audio attention layers.
+ - output_scale_factor (float): Scaling factor for the block's output.
+ - add_upsample (bool): Whether to add an upsampling layer.
+ - dual_cross_attention (bool): Whether to use dual cross attention (not implemented).
+ - use_linear_projection (bool): Whether to use linear projection in the cross attention.
+ - only_cross_attention (bool): Whether to use only cross attention (no self-attention).
+ - upcast_attention (bool): Whether to upcast attention to the original input dimension.
+ - unet_use_cross_frame_attention (bool): Whether to use cross frame attention in U-Net.
+ - unet_use_temporal_attention (bool): Whether to use temporal attention in U-Net.
+ - use_motion_module (bool): Whether to include a motion module.
+ - use_inflated_groupnorm (bool): Whether to use inflated group normalization.
+ - motion_module_type (str): Type of motion module to use.
+ - motion_module_kwargs (dict): Keyword arguments for the motion module.
+ - use_audio_module (bool): Whether to include an audio module.
+ - depth (int): Depth of the block in the network.
+ - stack_enable_blocks_name (str): Name of the stack enable blocks.
+ - stack_enable_blocks_depth (int): Depth of the stack enable blocks.
+
+ Forward method:
+ The forward method upsamples the input hidden states and residual hidden states, processes
+ them through the residual and cross attention blocks, and optional motion and audio modules.
+ It supports gradient checkpointing during training.
+ """
+ def __init__(
+ self,
+ in_channels: int,
+ prev_output_channel: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_time_scale_shift: str = "default",
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ resnet_pre_norm: bool = True,
+ output_scale_factor=1.0,
+ add_upsample=True,
+ use_inflated_groupnorm=None,
+ use_motion_module=None,
+ motion_module_type=None,
+ motion_module_kwargs=None,
+ ):
+ super().__init__()
+ resnets = []
+ motion_modules = []
+
+ # use_motion_module = False
+ for i in range(num_layers):
+ res_skip_channels = in_channels if (i == num_layers - 1) else out_channels
+ resnet_in_channels = prev_output_channel if i == 0 else out_channels
+
+ resnets.append(
+ ResnetBlock3D(
+ in_channels=resnet_in_channels + res_skip_channels,
+ out_channels=out_channels,
+ temb_channels=temb_channels,
+ eps=resnet_eps,
+ groups=resnet_groups,
+ dropout=dropout,
+ time_embedding_norm=resnet_time_scale_shift,
+ non_linearity=resnet_act_fn,
+ output_scale_factor=output_scale_factor,
+ pre_norm=resnet_pre_norm,
+ use_inflated_groupnorm=use_inflated_groupnorm,
+ )
+ )
+ motion_modules.append(
+ get_motion_module(
+ in_channels=out_channels,
+ motion_module_type=motion_module_type,
+ motion_module_kwargs=motion_module_kwargs,
+ )
+ if use_motion_module
+ else None
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+ self.motion_modules = nn.ModuleList(motion_modules)
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList(
+ [Upsample3D(out_channels, use_conv=True, out_channels=out_channels)]
+ )
+ else:
+ self.upsamplers = None
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states,
+ res_hidden_states_tuple,
+ temb=None,
+ upsample_size=None,
+ encoder_hidden_states=None,
+ ):
+ """
+ Forward pass for the UpBlock3D class.
+
+ Args:
+ self (UpBlock3D): An instance of the UpBlock3D class.
+ hidden_states (Tensor): The input hidden states tensor.
+ res_hidden_states_tuple (Tuple[Tensor]): A tuple of residual hidden states tensors.
+ temb (Tensor, optional): The token embeddings tensor. Defaults to None.
+ upsample_size (int, optional): The upsample size. Defaults to None.
+ encoder_hidden_states (Tensor, optional): The encoder hidden states tensor. Defaults to None.
+
+ Returns:
+ Tensor: The output tensor after passing through the UpBlock3D layers.
+ """
+ for resnet, motion_module in zip(self.resnets, self.motion_modules):
+ # pop res hidden states
+ res_hidden_states = res_hidden_states_tuple[-1]
+ res_hidden_states_tuple = res_hidden_states_tuple[:-1]
+ hidden_states = torch.cat([hidden_states, res_hidden_states], dim=1)
+
+ # print(f"UpBlock3D {self.gradient_checkpointing = }")
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb)
+ hidden_states = (
+ motion_module(
+ hidden_states, encoder_hidden_states=encoder_hidden_states
+ )
+ if motion_module is not None
+ else hidden_states
+ )
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(hidden_states, upsample_size)
+
+ return hidden_states
diff --git a/animation/hallo-83dd4eb/hallo/models/wav2vec.py b/animation/hallo-83dd4eb/hallo/models/wav2vec.py
new file mode 100644
index 0000000..cd0d002
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/models/wav2vec.py
@@ -0,0 +1,209 @@
+# pylint: disable=R0901
+# src/models/wav2vec.py
+
+"""
+This module defines the Wav2Vec model, which is a pre-trained model for speech recognition and understanding.
+It inherits from the Wav2Vec2Model class in the transformers library and provides additional functionalities
+such as feature extraction and encoding.
+
+Classes:
+ Wav2VecModel: Inherits from Wav2Vec2Model and adds additional methods for feature extraction and encoding.
+
+Functions:
+ linear_interpolation: Interpolates the features based on the sequence length.
+"""
+
+import torch.nn.functional as F
+from transformers import Wav2Vec2Model
+from transformers.modeling_outputs import BaseModelOutput
+
+
+class Wav2VecModel(Wav2Vec2Model):
+ """
+ Wav2VecModel is a custom model class that extends the Wav2Vec2Model class from the transformers library.
+ It inherits all the functionality of the Wav2Vec2Model and adds additional methods for feature extraction and encoding.
+ ...
+
+ Attributes:
+ base_model (Wav2Vec2Model): The base Wav2Vec2Model object.
+
+ Methods:
+ forward(input_values, seq_len, attention_mask=None, mask_time_indices=None
+ , output_attentions=None, output_hidden_states=None, return_dict=None):
+ Forward pass of the Wav2VecModel.
+ It takes input_values, seq_len, and other optional parameters as input and returns the output of the base model.
+
+ feature_extract(input_values, seq_len):
+ Extracts features from the input_values using the base model.
+
+ encode(extract_features, attention_mask=None, mask_time_indices=None, output_attentions=None, output_hidden_states=None, return_dict=None):
+ Encodes the extracted features using the base model and returns the encoded features.
+ """
+ def forward(
+ self,
+ input_values,
+ seq_len,
+ attention_mask=None,
+ mask_time_indices=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ """
+ Forward pass of the Wav2Vec model.
+
+ Args:
+ self: The instance of the model.
+ input_values: The input values (waveform) to the model.
+ seq_len: The sequence length of the input values.
+ attention_mask: Attention mask to be used for the model.
+ mask_time_indices: Mask indices to be used for the model.
+ output_attentions: If set to True, returns attentions.
+ output_hidden_states: If set to True, returns hidden states.
+ return_dict: If set to True, returns a BaseModelOutput instead of a tuple.
+
+ Returns:
+ The output of the Wav2Vec model.
+ """
+ self.config.output_attentions = True
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+ extract_features = linear_interpolation(extract_features, seq_len=seq_len)
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, ) + encoder_outputs[1:]
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+ def feature_extract(
+ self,
+ input_values,
+ seq_len,
+ ):
+ """
+ Extracts features from the input values and returns the extracted features.
+
+ Parameters:
+ input_values (torch.Tensor): The input values to be processed.
+ seq_len (torch.Tensor): The sequence lengths of the input values.
+
+ Returns:
+ extracted_features (torch.Tensor): The extracted features from the input values.
+ """
+ extract_features = self.feature_extractor(input_values)
+ extract_features = extract_features.transpose(1, 2)
+ extract_features = linear_interpolation(extract_features, seq_len=seq_len)
+
+ return extract_features
+
+ def encode(
+ self,
+ extract_features,
+ attention_mask=None,
+ mask_time_indices=None,
+ output_attentions=None,
+ output_hidden_states=None,
+ return_dict=None,
+ ):
+ """
+ Encodes the input features into the output space.
+
+ Args:
+ extract_features (torch.Tensor): The extracted features from the audio signal.
+ attention_mask (torch.Tensor, optional): Attention mask to be used for padding.
+ mask_time_indices (torch.Tensor, optional): Masked indices for the time dimension.
+ output_attentions (bool, optional): If set to True, returns the attention weights.
+ output_hidden_states (bool, optional): If set to True, returns all hidden states.
+ return_dict (bool, optional): If set to True, returns a BaseModelOutput instead of the tuple.
+
+ Returns:
+ The encoded output features.
+ """
+ self.config.output_attentions = True
+
+ output_hidden_states = (
+ output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
+ )
+ return_dict = return_dict if return_dict is not None else self.config.use_return_dict
+
+ if attention_mask is not None:
+ # compute reduced attention_mask corresponding to feature vectors
+ attention_mask = self._get_feature_vector_attention_mask(
+ extract_features.shape[1], attention_mask, add_adapter=False
+ )
+
+ hidden_states, extract_features = self.feature_projection(extract_features)
+ hidden_states = self._mask_hidden_states(
+ hidden_states, mask_time_indices=mask_time_indices, attention_mask=attention_mask
+ )
+
+ encoder_outputs = self.encoder(
+ hidden_states,
+ attention_mask=attention_mask,
+ output_attentions=output_attentions,
+ output_hidden_states=output_hidden_states,
+ return_dict=return_dict,
+ )
+
+ hidden_states = encoder_outputs[0]
+
+ if self.adapter is not None:
+ hidden_states = self.adapter(hidden_states)
+
+ if not return_dict:
+ return (hidden_states, ) + encoder_outputs[1:]
+ return BaseModelOutput(
+ last_hidden_state=hidden_states,
+ hidden_states=encoder_outputs.hidden_states,
+ attentions=encoder_outputs.attentions,
+ )
+
+
+def linear_interpolation(features, seq_len):
+ """
+ Transpose the features to interpolate linearly.
+
+ Args:
+ features (torch.Tensor): The extracted features to be interpolated.
+ seq_len (torch.Tensor): The sequence lengths of the features.
+
+ Returns:
+ torch.Tensor: The interpolated features.
+ """
+ features = features.transpose(1, 2)
+ output_features = F.interpolate(features, size=seq_len, align_corners=True, mode='linear')
+ return output_features.transpose(1, 2)
diff --git a/animation/hallo-83dd4eb/hallo/utils/__init__.py b/animation/hallo-83dd4eb/hallo/utils/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/animation/hallo-83dd4eb/hallo/utils/config.py b/animation/hallo-83dd4eb/hallo/utils/config.py
new file mode 100644
index 0000000..69854b6
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/utils/config.py
@@ -0,0 +1,25 @@
+"""
+This module provides utility functions for configuration manipulation.
+"""
+
+from typing import Dict
+
+
+def filter_non_none(dict_obj: Dict):
+ """
+ Filters out key-value pairs from the given dictionary where the value is None.
+
+ Args:
+ dict_obj (Dict): The dictionary to be filtered.
+
+ Returns:
+ Dict: The dictionary with key-value pairs removed where the value was None.
+
+ This function creates a new dictionary containing only the key-value pairs from
+ the original dictionary where the value is not None. It then clears the original
+ dictionary and updates it with the filtered key-value pairs.
+ """
+ non_none_filter = { k: v for k, v in dict_obj.items() if v is not None }
+ dict_obj.clear()
+ dict_obj.update(non_none_filter)
+ return dict_obj
diff --git a/animation/hallo-83dd4eb/hallo/utils/util.py b/animation/hallo-83dd4eb/hallo/utils/util.py
new file mode 100644
index 0000000..9fe2917
--- /dev/null
+++ b/animation/hallo-83dd4eb/hallo/utils/util.py
@@ -0,0 +1,980 @@
+# pylint: disable=C0116
+# pylint: disable=W0718
+# pylint: disable=R1732
+# pylint: disable=R0801
+"""
+utils.py
+
+This module provides utility functions for various tasks such as setting random seeds,
+importing modules from files, managing checkpoint files, and saving video files from
+sequences of PIL images.
+
+Functions:
+ seed_everything(seed)
+ import_filename(filename)
+ delete_additional_ckpt(base_path, num_keep)
+ save_videos_from_pil(pil_images, path, fps=8)
+
+Dependencies:
+ importlib
+ os
+ os.path as osp
+ random
+ shutil
+ sys
+ pathlib.Path
+ av
+ cv2
+ mediapipe as mp
+ numpy as np
+ torch
+ torchvision
+ einops.rearrange
+ moviepy.editor.AudioFileClip, VideoClip
+ PIL.Image
+
+Examples:
+ seed_everything(42)
+ imported_module = import_filename('path/to/your/module.py')
+ delete_additional_ckpt('path/to/checkpoints', 1)
+ save_videos_from_pil(pil_images, 'output/video.mp4', fps=12)
+
+The functions in this module ensure reproducibility of experiments by seeding random number
+generators, allow dynamic importing of modules, manage checkpoint files by deleting extra ones,
+and provide a way to save sequences of images as video files.
+
+Function Details:
+ seed_everything(seed)
+ Seeds all random number generators to ensure reproducibility.
+
+ import_filename(filename)
+ Imports a module from a given file location.
+
+ delete_additional_ckpt(base_path, num_keep)
+ Deletes additional checkpoint files in the given directory.
+
+ save_videos_from_pil(pil_images, path, fps=8)
+ Saves a sequence of images as a video using the Pillow library.
+
+Attributes:
+ _ (str): Placeholder for static type checking
+"""
+
+import importlib
+import os
+import os.path as osp
+import random
+import shutil
+import subprocess
+import sys
+from pathlib import Path
+from typing import List
+
+import av
+import cv2
+import mediapipe as mp
+import numpy as np
+import torch
+import torchvision
+from einops import rearrange
+from moviepy.editor import AudioFileClip, VideoClip
+from PIL import Image
+
+
+def seed_everything(seed):
+ """
+ Seeds all random number generators to ensure reproducibility.
+
+ Args:
+ seed (int): The seed value to set for all random number generators.
+ """
+ torch.manual_seed(seed)
+ torch.cuda.manual_seed_all(seed)
+ np.random.seed(seed % (2**32))
+ random.seed(seed)
+
+
+def import_filename(filename):
+ """
+ Import a module from a given file location.
+
+ Args:
+ filename (str): The path to the file containing the module to be imported.
+
+ Returns:
+ module: The imported module.
+
+ Raises:
+ ImportError: If the module cannot be imported.
+
+ Example:
+ >>> imported_module = import_filename('path/to/your/module.py')
+ """
+ spec = importlib.util.spec_from_file_location("mymodule", filename)
+ module = importlib.util.module_from_spec(spec)
+ sys.modules[spec.name] = module
+ spec.loader.exec_module(module)
+ return module
+
+
+def delete_additional_ckpt(base_path, num_keep):
+ """
+ Deletes additional checkpoint files in the given directory.
+
+ Args:
+ base_path (str): The path to the directory containing the checkpoint files.
+ num_keep (int): The number of most recent checkpoint files to keep.
+
+ Returns:
+ None
+
+ Raises:
+ FileNotFoundError: If the base_path does not exist.
+
+ Example:
+ >>> delete_additional_ckpt('path/to/checkpoints', 1)
+ # This will delete all but the most recent checkpoint file in 'path/to/checkpoints'.
+ """
+ dirs = []
+ for d in os.listdir(base_path):
+ if d.startswith("checkpoint-"):
+ dirs.append(d)
+ num_tot = len(dirs)
+ if num_tot <= num_keep:
+ return
+ # ensure ckpt is sorted and delete the ealier!
+ del_dirs = sorted(dirs, key=lambda x: int(
+ x.split("-")[-1]))[: num_tot - num_keep]
+ for d in del_dirs:
+ path_to_dir = osp.join(base_path, d)
+ if osp.exists(path_to_dir):
+ shutil.rmtree(path_to_dir)
+
+
+def save_videos_from_pil(pil_images, path, fps=8):
+ """
+ Save a sequence of images as a video using the Pillow library.
+
+ Args:
+ pil_images (List[PIL.Image]): A list of PIL.Image objects representing the frames of the video.
+ path (str): The output file path for the video.
+ fps (int, optional): The frames per second rate of the video. Defaults to 8.
+
+ Returns:
+ None
+
+ Raises:
+ ValueError: If the save format is not supported.
+
+ This function takes a list of PIL.Image objects and saves them as a video file with a specified frame rate.
+ The output file format is determined by the file extension of the provided path. Supported formats include
+ .mp4, .avi, and .mkv. The function uses the Pillow library to handle the image processing and video
+ creation.
+ """
+ save_fmt = Path(path).suffix
+ os.makedirs(os.path.dirname(path), exist_ok=True)
+ width, height = pil_images[0].size
+
+ if save_fmt == ".mp4":
+ codec = "libx264"
+ container = av.open(path, "w")
+ stream = container.add_stream(codec, rate=fps)
+
+ stream.width = width
+ stream.height = height
+
+ for pil_image in pil_images:
+ # pil_image = Image.fromarray(image_arr).convert("RGB")
+ av_frame = av.VideoFrame.from_image(pil_image)
+ container.mux(stream.encode(av_frame))
+ container.mux(stream.encode())
+ container.close()
+
+ elif save_fmt == ".gif":
+ pil_images[0].save(
+ fp=path,
+ format="GIF",
+ append_images=pil_images[1:],
+ save_all=True,
+ duration=(1 / fps * 1000),
+ loop=0,
+ )
+ else:
+ raise ValueError("Unsupported file type. Use .mp4 or .gif.")
+
+
+def save_videos_grid(videos: torch.Tensor, path: str, rescale=False, n_rows=6, fps=8):
+ """
+ Save a grid of videos as an animation or video.
+
+ Args:
+ videos (torch.Tensor): A tensor of shape (batch_size, channels, time, height, width)
+ containing the videos to save.
+ path (str): The path to save the video grid. Supported formats are .mp4, .avi, and .gif.
+ rescale (bool, optional): If True, rescale the video to the original resolution.
+ Defaults to False.
+ n_rows (int, optional): The number of rows in the video grid. Defaults to 6.
+ fps (int, optional): The frame rate of the saved video. Defaults to 8.
+
+ Raises:
+ ValueError: If the video format is not supported.
+
+ Returns:
+ None
+ """
+ videos = rearrange(videos, "b c t h w -> t b c h w")
+ # height, width = videos.shape[-2:]
+ outputs = []
+
+ for x in videos:
+ x = torchvision.utils.make_grid(x, nrow=n_rows) # (c h w)
+ x = x.transpose(0, 1).transpose(1, 2).squeeze(-1) # (h w c)
+ if rescale:
+ x = (x + 1.0) / 2.0 # -1,1 -> 0,1
+ x = (x * 255).numpy().astype(np.uint8)
+ x = Image.fromarray(x)
+
+ outputs.append(x)
+
+ os.makedirs(os.path.dirname(path), exist_ok=True)
+
+ save_videos_from_pil(outputs, path, fps)
+
+
+def read_frames(video_path):
+ """
+ Reads video frames from a given video file.
+
+ Args:
+ video_path (str): The path to the video file.
+
+ Returns:
+ container (av.container.InputContainer): The input container object
+ containing the video stream.
+
+ Raises:
+ FileNotFoundError: If the video file is not found.
+ RuntimeError: If there is an error in reading the video stream.
+
+ The function reads the video frames from the specified video file using the
+ Python AV library (av). It returns an input container object that contains
+ the video stream. If the video file is not found, it raises a FileNotFoundError,
+ and if there is an error in reading the video stream, it raises a RuntimeError.
+ """
+ container = av.open(video_path)
+
+ video_stream = next(s for s in container.streams if s.type == "video")
+ frames = []
+ for packet in container.demux(video_stream):
+ for frame in packet.decode():
+ image = Image.frombytes(
+ "RGB",
+ (frame.width, frame.height),
+ frame.to_rgb().to_ndarray(),
+ )
+ frames.append(image)
+
+ return frames
+
+
+def get_fps(video_path):
+ """
+ Get the frame rate (FPS) of a video file.
+
+ Args:
+ video_path (str): The path to the video file.
+
+ Returns:
+ int: The frame rate (FPS) of the video file.
+ """
+ container = av.open(video_path)
+ video_stream = next(s for s in container.streams if s.type == "video")
+ fps = video_stream.average_rate
+ container.close()
+ return fps
+
+
+def tensor_to_video(tensor, output_video_file, audio_source, fps=25):
+ """
+ Converts a Tensor with shape [c, f, h, w] into a video and adds an audio track from the specified audio file.
+
+ Args:
+ tensor (Tensor): The Tensor to be converted, shaped [c, f, h, w].
+ output_video_file (str): The file path where the output video will be saved.
+ audio_source (str): The path to the audio file (WAV file) that contains the audio track to be added.
+ fps (int): The frame rate of the output video. Default is 25 fps.
+ """
+ tensor = tensor.permute(1, 2, 3, 0).cpu(
+ ).numpy() # convert to [f, h, w, c]
+ tensor = np.clip(tensor * 255, 0, 255).astype(
+ np.uint8
+ ) # to [0, 255]
+
+ def make_frame(t):
+ # get index
+ frame_index = min(int(t * fps), tensor.shape[0] - 1)
+ return tensor[frame_index]
+ new_video_clip = VideoClip(make_frame, duration=tensor.shape[0] / fps)
+ audio_clip = AudioFileClip(audio_source).subclip(0, tensor.shape[0] / fps)
+ new_video_clip = new_video_clip.set_audio(audio_clip)
+ new_video_clip.write_videofile(output_video_file, fps=fps, audio_codec='aac')
+
+
+silhouette_ids = [
+ 10, 338, 297, 332, 284, 251, 389, 356, 454, 323, 361, 288,
+ 397, 365, 379, 378, 400, 377, 152, 148, 176, 149, 150, 136,
+ 172, 58, 132, 93, 234, 127, 162, 21, 54, 103, 67, 109
+]
+lip_ids = [61, 185, 40, 39, 37, 0, 267, 269, 270, 409, 291,
+ 146, 91, 181, 84, 17, 314, 405, 321, 375]
+
+
+def compute_face_landmarks(detection_result, h, w):
+ """
+ Compute face landmarks from a detection result.
+
+ Args:
+ detection_result (mediapipe.solutions.face_mesh.FaceMesh): The detection result containing face landmarks.
+ h (int): The height of the video frame.
+ w (int): The width of the video frame.
+
+ Returns:
+ face_landmarks_list (list): A list of face landmarks.
+ """
+ face_landmarks_list = detection_result.face_landmarks
+ if len(face_landmarks_list) != 1:
+ print("#face is invalid:", len(face_landmarks_list))
+ return []
+ return [[p.x * w, p.y * h] for p in face_landmarks_list[0]]
+
+
+def get_landmark(file):
+ """
+ This function takes a file as input and returns the facial landmarks detected in the file.
+
+ Args:
+ file (str): The path to the file containing the video or image to be processed.
+
+ Returns:
+ Tuple[List[float], List[float]]: A tuple containing two lists of floats representing the x and y coordinates of the facial landmarks.
+ """
+ model_path = "pretrained_models/face_analysis/models/face_landmarker_v2_with_blendshapes.task"
+ BaseOptions = mp.tasks.BaseOptions
+ FaceLandmarker = mp.tasks.vision.FaceLandmarker
+ FaceLandmarkerOptions = mp.tasks.vision.FaceLandmarkerOptions
+ VisionRunningMode = mp.tasks.vision.RunningMode
+ # Create a face landmarker instance with the video mode:
+ options = FaceLandmarkerOptions(
+ base_options=BaseOptions(model_asset_path=model_path),
+ running_mode=VisionRunningMode.IMAGE,
+ )
+
+ with FaceLandmarker.create_from_options(options) as landmarker:
+ image = mp.Image.create_from_file(str(file))
+ height, width = image.height, image.width
+ face_landmarker_result = landmarker.detect(image)
+ face_landmark = compute_face_landmarks(
+ face_landmarker_result, height, width)
+
+ return np.array(face_landmark), height, width
+
+
+def get_landmark_overframes(landmark_model, frames_path):
+ """
+ This function iterate frames and returns the facial landmarks detected in each frame.
+
+ Args:
+ landmark_model: mediapipe landmark model instance
+ frames_path (str): The path to the video frames.
+
+ Returns:
+ List[List[float], float, float]: A List containing two lists of floats representing the x and y coordinates of the facial landmarks.
+ """
+
+ face_landmarks = []
+
+ for file in sorted(os.listdir(frames_path)):
+ image = mp.Image.create_from_file(os.path.join(frames_path, file))
+ height, width = image.height, image.width
+ landmarker_result = landmark_model.detect(image)
+ frame_landmark = compute_face_landmarks(
+ landmarker_result, height, width)
+ face_landmarks.append(frame_landmark)
+
+ return face_landmarks, height, width
+
+
+def get_lip_mask(landmarks, height, width, out_path=None, expand_ratio=2.0):
+ """
+ Extracts the lip region from the given landmarks and saves it as an image.
+
+ Parameters:
+ landmarks (numpy.ndarray): Array of facial landmarks.
+ height (int): Height of the output lip mask image.
+ width (int): Width of the output lip mask image.
+ out_path (pathlib.Path): Path to save the lip mask image.
+ expand_ratio (float): Expand ratio of mask.
+ """
+ lip_landmarks = np.take(landmarks, lip_ids, 0)
+ min_xy_lip = np.round(np.min(lip_landmarks, 0))
+ max_xy_lip = np.round(np.max(lip_landmarks, 0))
+ min_xy_lip[0], max_xy_lip[0], min_xy_lip[1], max_xy_lip[1] = expand_region(
+ [min_xy_lip[0], max_xy_lip[0], min_xy_lip[1], max_xy_lip[1]], width, height, expand_ratio)
+ lip_mask = np.zeros((height, width), dtype=np.uint8)
+ lip_mask[round(min_xy_lip[1]):round(max_xy_lip[1]),
+ round(min_xy_lip[0]):round(max_xy_lip[0])] = 255
+ if out_path:
+ cv2.imwrite(str(out_path), lip_mask)
+ return None
+
+ return lip_mask
+
+
+def get_union_lip_mask(landmarks, height, width, expand_ratio=1):
+ """
+ Extracts the lip region from the given landmarks and saves it as an image.
+
+ Parameters:
+ landmarks (numpy.ndarray): Array of facial landmarks.
+ height (int): Height of the output lip mask image.
+ width (int): Width of the output lip mask image.
+ expand_ratio (float): Expand ratio of mask.
+ """
+ lip_masks = []
+ for landmark in landmarks:
+ lip_masks.append(get_lip_mask(landmarks=landmark, height=height,
+ width=width, expand_ratio=expand_ratio))
+ union_mask = get_union_mask(lip_masks)
+ return union_mask
+
+
+def get_face_mask(landmarks, height, width, out_path=None, expand_ratio=1.2):
+ """
+ Generate a face mask based on the given landmarks.
+
+ Args:
+ landmarks (numpy.ndarray): The landmarks of the face.
+ height (int): The height of the output face mask image.
+ width (int): The width of the output face mask image.
+ out_path (pathlib.Path): The path to save the face mask image.
+ expand_ratio (float): Expand ratio of mask.
+ Returns:
+ None. The face mask image is saved at the specified path.
+ """
+ face_landmarks = np.take(landmarks, silhouette_ids, 0)
+ min_xy_face = np.round(np.min(face_landmarks, 0))
+ max_xy_face = np.round(np.max(face_landmarks, 0))
+ min_xy_face[0], max_xy_face[0], min_xy_face[1], max_xy_face[1] = expand_region(
+ [min_xy_face[0], max_xy_face[0], min_xy_face[1], max_xy_face[1]], width, height, expand_ratio)
+ face_mask = np.zeros((height, width), dtype=np.uint8)
+ face_mask[round(min_xy_face[1]):round(max_xy_face[1]),
+ round(min_xy_face[0]):round(max_xy_face[0])] = 255
+ if out_path:
+ cv2.imwrite(str(out_path), face_mask)
+ return None
+
+ return face_mask
+
+
+def get_union_face_mask(landmarks, height, width, expand_ratio=1):
+ """
+ Generate a face mask based on the given landmarks.
+
+ Args:
+ landmarks (numpy.ndarray): The landmarks of the face.
+ height (int): The height of the output face mask image.
+ width (int): The width of the output face mask image.
+ expand_ratio (float): Expand ratio of mask.
+ Returns:
+ None. The face mask image is saved at the specified path.
+ """
+ face_masks = []
+ for landmark in landmarks:
+ face_masks.append(get_face_mask(landmarks=landmark,height=height,width=width,expand_ratio=expand_ratio))
+ union_mask = get_union_mask(face_masks)
+ return union_mask
+
+def get_mask(file, cache_dir, face_expand_raio):
+ """
+ Generate a face mask based on the given landmarks and save it to the specified cache directory.
+
+ Args:
+ file (str): The path to the file containing the landmarks.
+ cache_dir (str): The directory to save the generated face mask.
+
+ Returns:
+ None
+ """
+ landmarks, height, width = get_landmark(file)
+ file_name = os.path.basename(file).split(".")[0]
+ get_lip_mask(landmarks, height, width, os.path.join(
+ cache_dir, f"{file_name}_lip_mask.png"))
+ get_face_mask(landmarks, height, width, os.path.join(
+ cache_dir, f"{file_name}_face_mask.png"), face_expand_raio)
+ get_blur_mask(os.path.join(
+ cache_dir, f"{file_name}_face_mask.png"), os.path.join(
+ cache_dir, f"{file_name}_face_mask_blur.png"), kernel_size=(51, 51))
+ get_blur_mask(os.path.join(
+ cache_dir, f"{file_name}_lip_mask.png"), os.path.join(
+ cache_dir, f"{file_name}_sep_lip.png"), kernel_size=(31, 31))
+ get_background_mask(os.path.join(
+ cache_dir, f"{file_name}_face_mask_blur.png"), os.path.join(
+ cache_dir, f"{file_name}_sep_background.png"))
+ get_sep_face_mask(os.path.join(
+ cache_dir, f"{file_name}_face_mask_blur.png"), os.path.join(
+ cache_dir, f"{file_name}_sep_lip.png"), os.path.join(
+ cache_dir, f"{file_name}_sep_face.png"))
+
+
+def expand_region(region, image_w, image_h, expand_ratio=1.0):
+ """
+ Expand the given region by a specified ratio.
+ Args:
+ region (tuple): A tuple containing the coordinates (min_x, max_x, min_y, max_y) of the region.
+ image_w (int): The width of the image.
+ image_h (int): The height of the image.
+ expand_ratio (float, optional): The ratio by which the region should be expanded. Defaults to 1.0.
+
+ Returns:
+ tuple: A tuple containing the expanded coordinates (min_x, max_x, min_y, max_y) of the region.
+ """
+
+ min_x, max_x, min_y, max_y = region
+ mid_x = (max_x + min_x) // 2
+ side_len_x = (max_x - min_x) * expand_ratio
+ mid_y = (max_y + min_y) // 2
+ side_len_y = (max_y - min_y) * expand_ratio
+ min_x = mid_x - side_len_x // 2
+ max_x = mid_x + side_len_x // 2
+ min_y = mid_y - side_len_y // 2
+ max_y = mid_y + side_len_y // 2
+ if min_x < 0:
+ max_x -= min_x
+ min_x = 0
+ if max_x > image_w:
+ min_x -= max_x - image_w
+ max_x = image_w
+ if min_y < 0:
+ max_y -= min_y
+ min_y = 0
+ if max_y > image_h:
+ min_y -= max_y - image_h
+ max_y = image_h
+
+ return round(min_x), round(max_x), round(min_y), round(max_y)
+
+
+def get_blur_mask(file_path, output_file_path, resize_dim=(64, 64), kernel_size=(101, 101)):
+ """
+ Read, resize, blur, normalize, and save an image.
+
+ Parameters:
+ file_path (str): Path to the input image file.
+ output_dir (str): Path to the output directory to save blurred images.
+ resize_dim (tuple): Dimensions to resize the images to.
+ kernel_size (tuple): Size of the kernel to use for Gaussian blur.
+ """
+ # Read the mask image
+ mask = cv2.imread(file_path, cv2.IMREAD_GRAYSCALE)
+
+ # Check if the image is loaded successfully
+ if mask is not None:
+ normalized_mask = blur_mask(mask,resize_dim=resize_dim,kernel_size=kernel_size)
+ # Save the normalized mask image
+ cv2.imwrite(output_file_path, normalized_mask)
+ return f"Processed, normalized, and saved: {output_file_path}"
+ return f"Failed to load image: {file_path}"
+
+
+def blur_mask(mask, resize_dim=(64, 64), kernel_size=(51, 51)):
+ """
+ Read, resize, blur, normalize, and save an image.
+
+ Parameters:
+ file_path (str): Path to the input image file.
+ resize_dim (tuple): Dimensions to resize the images to.
+ kernel_size (tuple): Size of the kernel to use for Gaussian blur.
+ """
+ # Check if the image is loaded successfully
+ normalized_mask = None
+ if mask is not None:
+ # Resize the mask image
+ resized_mask = cv2.resize(mask, resize_dim)
+ # Apply Gaussian blur to the resized mask image
+ blurred_mask = cv2.GaussianBlur(resized_mask, kernel_size, 0)
+ # Normalize the blurred image
+ normalized_mask = cv2.normalize(
+ blurred_mask, None, 0, 255, cv2.NORM_MINMAX)
+ # Save the normalized mask image
+ return normalized_mask
+
+def get_background_mask(file_path, output_file_path):
+ """
+ Read an image, invert its values, and save the result.
+
+ Parameters:
+ file_path (str): Path to the input image file.
+ output_dir (str): Path to the output directory to save the inverted image.
+ """
+ # Read the image
+ image = cv2.imread(file_path, cv2.IMREAD_GRAYSCALE)
+
+ if image is None:
+ print(f"Failed to load image: {file_path}")
+ return
+
+ # Invert the image
+ inverted_image = 1.0 - (
+ image / 255.0
+ ) # Assuming the image values are in [0, 255] range
+ # Convert back to uint8
+ inverted_image = (inverted_image * 255).astype(np.uint8)
+
+ # Save the inverted image
+ cv2.imwrite(output_file_path, inverted_image)
+ print(f"Processed and saved: {output_file_path}")
+
+
+def get_sep_face_mask(file_path1, file_path2, output_file_path):
+ """
+ Read two images, subtract the second one from the first, and save the result.
+
+ Parameters:
+ output_dir (str): Path to the output directory to save the subtracted image.
+ """
+
+ # Read the images
+ mask1 = cv2.imread(file_path1, cv2.IMREAD_GRAYSCALE)
+ mask2 = cv2.imread(file_path2, cv2.IMREAD_GRAYSCALE)
+
+ if mask1 is None or mask2 is None:
+ print(f"Failed to load images: {file_path1}")
+ return
+
+ # Ensure the images are the same size
+ if mask1.shape != mask2.shape:
+ print(
+ f"Image shapes do not match for {file_path1}: {mask1.shape} vs {mask2.shape}"
+ )
+ return
+
+ # Subtract the second mask from the first
+ result_mask = cv2.subtract(mask1, mask2)
+
+ # Save the result mask image
+ cv2.imwrite(output_file_path, result_mask)
+ print(f"Processed and saved: {output_file_path}")
+
+def resample_audio(input_audio_file: str, output_audio_file: str, sample_rate: int):
+ p = subprocess.Popen([
+ "ffmpeg", "-y", "-v", "error", "-i", input_audio_file, "-ar", str(sample_rate), output_audio_file
+ ])
+ ret = p.wait()
+ assert ret == 0, "Resample audio failed!"
+ return output_audio_file
+
+def get_face_region(image_path: str, detector):
+ try:
+ image = cv2.imread(image_path)
+ if image is None:
+ print(f"Failed to open image: {image_path}. Skipping...")
+ return None, None
+
+ mp_image = mp.Image(image_format=mp.ImageFormat.SRGB, data=image)
+ detection_result = detector.detect(mp_image)
+
+ # Adjust mask creation for the three-channel image
+ mask = np.zeros_like(image, dtype=np.uint8)
+
+ for detection in detection_result.detections:
+ bbox = detection.bounding_box
+ start_point = (int(bbox.origin_x), int(bbox.origin_y))
+ end_point = (int(bbox.origin_x + bbox.width),
+ int(bbox.origin_y + bbox.height))
+ cv2.rectangle(mask, start_point, end_point,
+ (255, 255, 255), thickness=-1)
+
+ save_path = image_path.replace("images", "face_masks")
+ os.makedirs(os.path.dirname(save_path), exist_ok=True)
+ cv2.imwrite(save_path, mask)
+ # print(f"Processed and saved {save_path}")
+ return image_path, mask
+ except Exception as e:
+ print(f"Error processing image {image_path}: {e}")
+ return None, None
+
+
+def save_checkpoint(model: torch.nn.Module, save_dir: str, prefix: str, ckpt_num: int, total_limit: int = -1) -> None:
+ """
+ Save the model's state_dict to a checkpoint file.
+
+ If `total_limit` is provided, this function will remove the oldest checkpoints
+ until the total number of checkpoints is less than the specified limit.
+
+ Args:
+ model (nn.Module): The model whose state_dict is to be saved.
+ save_dir (str): The directory where the checkpoint will be saved.
+ prefix (str): The prefix for the checkpoint file name.
+ ckpt_num (int): The checkpoint number to be saved.
+ total_limit (int, optional): The maximum number of checkpoints to keep.
+ Defaults to None, in which case no checkpoints will be removed.
+
+ Raises:
+ FileNotFoundError: If the save directory does not exist.
+ ValueError: If the checkpoint number is negative.
+ OSError: If there is an error saving the checkpoint.
+ """
+
+ if not osp.exists(save_dir):
+ raise FileNotFoundError(
+ f"The save directory {save_dir} does not exist.")
+
+ if ckpt_num < 0:
+ raise ValueError(f"Checkpoint number {ckpt_num} must be non-negative.")
+
+ save_path = osp.join(save_dir, f"{prefix}-{ckpt_num}.pth")
+
+ if total_limit > 0:
+ checkpoints = os.listdir(save_dir)
+ checkpoints = [d for d in checkpoints if d.startswith(prefix)]
+ checkpoints = sorted(
+ checkpoints, key=lambda x: int(x.split("-")[1].split(".")[0])
+ )
+
+ if len(checkpoints) >= total_limit:
+ num_to_remove = len(checkpoints) - total_limit + 1
+ removing_checkpoints = checkpoints[0:num_to_remove]
+ print(
+ f"{len(checkpoints)} checkpoints already exist, removing {len(removing_checkpoints)} checkpoints"
+ )
+ print(
+ f"Removing checkpoints: {', '.join(removing_checkpoints)}"
+ )
+
+ for removing_checkpoint in removing_checkpoints:
+ removing_checkpoint_path = osp.join(
+ save_dir, removing_checkpoint)
+ try:
+ os.remove(removing_checkpoint_path)
+ except OSError as e:
+ print(
+ f"Error removing checkpoint {removing_checkpoint_path}: {e}")
+
+ state_dict = model.state_dict()
+ try:
+ torch.save(state_dict, save_path)
+ print(f"Checkpoint saved at {save_path}")
+ except OSError as e:
+ raise OSError(f"Error saving checkpoint at {save_path}: {e}") from e
+
+
+def init_output_dir(dir_list: List[str]):
+ """
+ Initialize the output directories.
+
+ This function creates the directories specified in the `dir_list`. If a directory already exists, it does nothing.
+
+ Args:
+ dir_list (List[str]): List of directory paths to create.
+ """
+ for path in dir_list:
+ os.makedirs(path, exist_ok=True)
+
+
+def load_checkpoint(cfg, save_dir, accelerator):
+ """
+ Load the most recent checkpoint from the specified directory.
+
+ This function loads the latest checkpoint from the `save_dir` if the `resume_from_checkpoint` parameter is set to "latest".
+ If a specific checkpoint is provided in `resume_from_checkpoint`, it loads that checkpoint. If no checkpoint is found,
+ it starts training from scratch.
+
+ Args:
+ cfg: The configuration object containing training parameters.
+ save_dir (str): The directory where checkpoints are saved.
+ accelerator: The accelerator object for distributed training.
+
+ Returns:
+ int: The global step at which to resume training.
+ """
+ if cfg.resume_from_checkpoint != "latest":
+ resume_dir = cfg.resume_from_checkpoint
+ else:
+ resume_dir = save_dir
+ # Get the most recent checkpoint
+ dirs = os.listdir(resume_dir)
+
+ dirs = [d for d in dirs if d.startswith("checkpoint")]
+ if len(dirs) > 0:
+ dirs = sorted(dirs, key=lambda x: int(x.split("-")[1]))
+ path = dirs[-1]
+ accelerator.load_state(os.path.join(resume_dir, path))
+ accelerator.print(f"Resuming from checkpoint {path}")
+ global_step = int(path.split("-")[1])
+ else:
+ accelerator.print(
+ f"Could not find checkpoint under {resume_dir}, start training from scratch")
+ global_step = 0
+
+ return global_step
+
+
+def compute_snr(noise_scheduler, timesteps):
+ """
+ Computes SNR as per
+ https://github.com/TiankaiHang/Min-SNR-Diffusion-Training/blob/
+ 521b624bd70c67cee4bdf49225915f5945a872e3/guided_diffusion/gaussian_diffusion.py#L847-L849
+ """
+ alphas_cumprod = noise_scheduler.alphas_cumprod
+ sqrt_alphas_cumprod = alphas_cumprod**0.5
+ sqrt_one_minus_alphas_cumprod = (1.0 - alphas_cumprod) ** 0.5
+
+ # Expand the tensors.
+ # Adapted from https://github.com/TiankaiHang/Min-SNR-Diffusion-Training/blob/
+ # 521b624bd70c67cee4bdf49225915f5945a872e3/guided_diffusion/gaussian_diffusion.py#L1026
+ sqrt_alphas_cumprod = sqrt_alphas_cumprod.to(device=timesteps.device)[
+ timesteps
+ ].float()
+ while len(sqrt_alphas_cumprod.shape) < len(timesteps.shape):
+ sqrt_alphas_cumprod = sqrt_alphas_cumprod[..., None]
+ alpha = sqrt_alphas_cumprod.expand(timesteps.shape)
+
+ sqrt_one_minus_alphas_cumprod = sqrt_one_minus_alphas_cumprod.to(
+ device=timesteps.device
+ )[timesteps].float()
+ while len(sqrt_one_minus_alphas_cumprod.shape) < len(timesteps.shape):
+ sqrt_one_minus_alphas_cumprod = sqrt_one_minus_alphas_cumprod[..., None]
+ sigma = sqrt_one_minus_alphas_cumprod.expand(timesteps.shape)
+
+ # Compute SNR.
+ snr = (alpha / sigma) ** 2
+ return snr
+
+
+def extract_audio_from_videos(video_path: Path, audio_output_path: Path) -> Path:
+ """
+ Extract audio from a video file and save it as a WAV file.
+
+ This function uses ffmpeg to extract the audio stream from a given video file and saves it as a WAV file
+ in the specified output directory.
+
+ Args:
+ video_path (Path): The path to the input video file.
+ output_dir (Path): The directory where the extracted audio file will be saved.
+
+ Returns:
+ Path: The path to the extracted audio file.
+
+ Raises:
+ subprocess.CalledProcessError: If the ffmpeg command fails to execute.
+ """
+ ffmpeg_command = [
+ 'ffmpeg', '-y',
+ '-i', str(video_path),
+ '-vn', '-acodec',
+ "pcm_s16le", '-ar', '16000', '-ac', '2',
+ str(audio_output_path)
+ ]
+
+ try:
+ print(f"Running command: {' '.join(ffmpeg_command)}")
+ subprocess.run(ffmpeg_command, check=True)
+ except subprocess.CalledProcessError as e:
+ print(f"Error extracting audio from video: {e}")
+ raise
+
+ return audio_output_path
+
+
+def convert_video_to_images(video_path: Path, output_dir: Path) -> Path:
+ """
+ Convert a video file into a sequence of images.
+
+ This function uses ffmpeg to convert each frame of the given video file into an image. The images are saved
+ in a directory named after the video file stem under the specified output directory.
+
+ Args:
+ video_path (Path): The path to the input video file.
+ output_dir (Path): The directory where the extracted images will be saved.
+
+ Returns:
+ Path: The path to the directory containing the extracted images.
+
+ Raises:
+ subprocess.CalledProcessError: If the ffmpeg command fails to execute.
+ """
+ ffmpeg_command = [
+ 'ffmpeg',
+ '-i', str(video_path),
+ '-vf', 'fps=25',
+ str(output_dir / '%04d.png')
+ ]
+
+ try:
+ print(f"Running command: {' '.join(ffmpeg_command)}")
+ subprocess.run(ffmpeg_command, check=True)
+ except subprocess.CalledProcessError as e:
+ print(f"Error converting video to images: {e}")
+ raise
+
+ return output_dir
+
+
+def get_union_mask(masks):
+ """
+ Compute the union of a list of masks.
+
+ This function takes a list of masks and computes their union by taking the maximum value at each pixel location.
+ Additionally, it finds the bounding box of the non-zero regions in the mask and sets the bounding box area to white.
+
+ Args:
+ masks (list of np.ndarray): List of masks to be combined.
+
+ Returns:
+ np.ndarray: The union of the input masks.
+ """
+ union_mask = None
+ for mask in masks:
+ if union_mask is None:
+ union_mask = mask
+ else:
+ union_mask = np.maximum(union_mask, mask)
+
+ if union_mask is not None:
+ # Find the bounding box of the non-zero regions in the mask
+ rows = np.any(union_mask, axis=1)
+ cols = np.any(union_mask, axis=0)
+ try:
+ ymin, ymax = np.where(rows)[0][[0, -1]]
+ xmin, xmax = np.where(cols)[0][[0, -1]]
+ except Exception as e:
+ print(str(e))
+ return 0.0
+
+ # Set bounding box area to white
+ union_mask[ymin: ymax + 1, xmin: xmax + 1] = np.max(union_mask)
+
+ return union_mask
+
+
+def move_final_checkpoint(save_dir, module_dir, prefix):
+ """
+ Move the final checkpoint file to the save directory.
+
+ This function identifies the latest checkpoint file based on the given prefix and moves it to the specified save directory.
+
+ Args:
+ save_dir (str): The directory where the final checkpoint file should be saved.
+ module_dir (str): The directory containing the checkpoint files.
+ prefix (str): The prefix used to identify checkpoint files.
+
+ Raises:
+ ValueError: If no checkpoint files are found with the specified prefix.
+ """
+ checkpoints = os.listdir(module_dir)
+ checkpoints = [d for d in checkpoints if d.startswith(prefix)]
+ checkpoints = sorted(
+ checkpoints, key=lambda x: int(x.split("-")[1].split(".")[0])
+ )
+ shutil.copy2(os.path.join(
+ module_dir, checkpoints[-1]), os.path.join(save_dir, prefix + '.pth'))
diff --git a/animation/hallo-83dd4eb/requirements.txt b/animation/hallo-83dd4eb/requirements.txt
new file mode 100644
index 0000000..5c4a9a5
--- /dev/null
+++ b/animation/hallo-83dd4eb/requirements.txt
@@ -0,0 +1,33 @@
+--find-links https://download.pytorch.org/whl/torch_stable.html
+
+accelerate==0.28.0
+audio-separator==0.17.2
+av==12.1.0
+bitsandbytes==0.43.1
+decord==0.6.0
+diffusers==0.27.2
+einops==0.8.0
+insightface==0.7.3
+librosa==0.10.2.post1
+mediapipe[vision]==0.10.14
+mlflow==2.13.1
+moviepy==1.0.3
+numpy==1.26.4
+omegaconf==2.3.0
+onnx2torch==1.5.14
+onnx==1.16.1
+onnxruntime-gpu==1.18.0
+opencv-contrib-python==4.9.0.80
+opencv-python-headless==4.9.0.80
+opencv-python==4.9.0.80
+pillow==10.3.0
+setuptools==70.0.0
+torch==2.2.2+cu121
+torchvision==0.17.2+cu121
+tqdm==4.66.4
+transformers==4.39.2
+xformers==0.0.25.post1
+isort==5.13.2
+pylint==3.2.2
+pre-commit==3.7.1
+gradio==4.36.1
diff --git a/animation/hallo-83dd4eb/scripts/app.py b/animation/hallo-83dd4eb/scripts/app.py
new file mode 100644
index 0000000..770ffcb
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/app.py
@@ -0,0 +1,51 @@
+"""
+This script is a gradio web ui.
+
+The script takes an image and an audio clip, and lets you configure all the
+variables such as cfg_scale, pose_weight, face_weight, lip_weight, etc.
+
+Usage:
+This script can be run from the command line with the following command:
+
+python scripts/app.py
+"""
+import argparse
+
+import gradio as gr
+from inference import inference_process
+
+
+def predict(image, audio, pose_weight, face_weight, lip_weight, face_expand_ratio, progress=gr.Progress(track_tqdm=True)):
+ """
+ Create a gradio interface with the configs.
+ """
+ _ = progress
+ config = {
+ 'source_image': image,
+ 'driving_audio': audio,
+ 'pose_weight': pose_weight,
+ 'face_weight': face_weight,
+ 'lip_weight': lip_weight,
+ 'face_expand_ratio': face_expand_ratio,
+ 'config': 'configs/inference/default.yaml',
+ 'checkpoint': None,
+ 'output': ".cache/output.mp4"
+ }
+ args = argparse.Namespace()
+ for key, value in config.items():
+ setattr(args, key, value)
+ return inference_process(args)
+
+app = gr.Interface(
+ fn=predict,
+ inputs=[
+ gr.Image(label="source image (no webp)", type="filepath", format="jpeg"),
+ gr.Audio(label="source audio", type="filepath"),
+ gr.Number(label="pose weight", value=1.0),
+ gr.Number(label="face weight", value=1.0),
+ gr.Number(label="lip weight", value=1.0),
+ gr.Number(label="face expand ratio", value=1.2),
+ ],
+ outputs=[gr.Video()],
+)
+app.launch()
diff --git a/animation/hallo-83dd4eb/scripts/data_preprocess.py b/animation/hallo-83dd4eb/scripts/data_preprocess.py
new file mode 100644
index 0000000..92efc2f
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/data_preprocess.py
@@ -0,0 +1,191 @@
+# pylint: disable=W1203,W0718
+"""
+This module is used to process videos to prepare data for training. It utilizes various libraries and models
+to perform tasks such as video frame extraction, audio extraction, face mask generation, and face embedding extraction.
+The script takes in command-line arguments to specify the input and output directories, GPU status, level of parallelism,
+and rank for distributed processing.
+
+Usage:
+ python -m scripts.data_preprocess --input_dir /path/to/video_dir --dataset_name dataset_name --gpu_status --parallelism 4 --rank 0
+
+Example:
+ python -m scripts.data_preprocess -i data/videos -o data/output -g -p 4 -r 0
+"""
+import argparse
+import logging
+import os
+from pathlib import Path
+from typing import List
+
+import cv2
+import torch
+from tqdm import tqdm
+
+from hallo.datasets.audio_processor import AudioProcessor
+from hallo.datasets.image_processor import ImageProcessorForDataProcessing
+from hallo.utils.util import convert_video_to_images, extract_audio_from_videos
+
+# Configure logging
+logging.basicConfig(level=logging.INFO,
+ format='%(asctime)s - %(levelname)s - %(message)s')
+
+
+def setup_directories(video_path: Path) -> dict:
+ """
+ Setup directories for storing processed files.
+
+ Args:
+ video_path (Path): Path to the video file.
+
+ Returns:
+ dict: A dictionary containing paths for various directories.
+ """
+ base_dir = video_path.parent.parent
+ dirs = {
+ "face_mask": base_dir / "face_mask",
+ "sep_pose_mask": base_dir / "sep_pose_mask",
+ "sep_face_mask": base_dir / "sep_face_mask",
+ "sep_lip_mask": base_dir / "sep_lip_mask",
+ "face_emb": base_dir / "face_emb",
+ "audio_emb": base_dir / "audio_emb"
+ }
+
+ for path in dirs.values():
+ path.mkdir(parents=True, exist_ok=True)
+
+ return dirs
+
+
+def process_single_video(video_path: Path,
+ output_dir: Path,
+ image_processor: ImageProcessorForDataProcessing,
+ audio_processor: AudioProcessor,
+ step: int) -> None:
+ """
+ Process a single video file.
+
+ Args:
+ video_path (Path): Path to the video file.
+ output_dir (Path): Directory to save the output.
+ image_processor (ImageProcessorForDataProcessing): Image processor object.
+ audio_processor (AudioProcessor): Audio processor object.
+ gpu_status (bool): Whether to use GPU for processing.
+ """
+ assert video_path.exists(), f"Video path {video_path} does not exist"
+ dirs = setup_directories(video_path)
+ logging.info(f"Processing video: {video_path}")
+
+ try:
+ if step == 1:
+ images_output_dir = output_dir / 'images' / video_path.stem
+ images_output_dir.mkdir(parents=True, exist_ok=True)
+ images_output_dir = convert_video_to_images(
+ video_path, images_output_dir)
+ logging.info(f"Images saved to: {images_output_dir}")
+
+ audio_output_dir = output_dir / 'audios'
+ audio_output_dir.mkdir(parents=True, exist_ok=True)
+ audio_output_path = audio_output_dir / f'{video_path.stem}.wav'
+ audio_output_path = extract_audio_from_videos(
+ video_path, audio_output_path)
+ logging.info(f"Audio extracted to: {audio_output_path}")
+
+ face_mask, _, sep_pose_mask, sep_face_mask, sep_lip_mask = image_processor.preprocess(
+ images_output_dir)
+ cv2.imwrite(
+ str(dirs["face_mask"] / f"{video_path.stem}.png"), face_mask)
+ cv2.imwrite(str(dirs["sep_pose_mask"] /
+ f"{video_path.stem}.png"), sep_pose_mask)
+ cv2.imwrite(str(dirs["sep_face_mask"] /
+ f"{video_path.stem}.png"), sep_face_mask)
+ cv2.imwrite(str(dirs["sep_lip_mask"] /
+ f"{video_path.stem}.png"), sep_lip_mask)
+ else:
+ images_dir = output_dir / "images" / video_path.stem
+ audio_path = output_dir / "audios" / f"{video_path.stem}.wav"
+ _, face_emb, _, _, _ = image_processor.preprocess(images_dir)
+ torch.save(face_emb, str(
+ dirs["face_emb"] / f"{video_path.stem}.pt"))
+ audio_emb, _ = audio_processor.preprocess(audio_path)
+ torch.save(audio_emb, str(
+ dirs["audio_emb"] / f"{video_path.stem}.pt"))
+ except Exception as e:
+ logging.error(f"Failed to process video {video_path}: {e}")
+
+
+def process_all_videos(input_video_list: List[Path], output_dir: Path, step: int) -> None:
+ """
+ Process all videos in the input list.
+
+ Args:
+ input_video_list (List[Path]): List of video paths to process.
+ output_dir (Path): Directory to save the output.
+ gpu_status (bool): Whether to use GPU for processing.
+ """
+ face_analysis_model_path = "pretrained_models/face_analysis"
+ landmark_model_path = "pretrained_models/face_analysis/models/face_landmarker_v2_with_blendshapes.task"
+ audio_separator_model_file = "pretrained_models/audio_separator/Kim_Vocal_2.onnx"
+ wav2vec_model_path = 'pretrained_models/wav2vec/wav2vec2-base-960h'
+
+ audio_processor = AudioProcessor(
+ 16000,
+ 25,
+ wav2vec_model_path,
+ False,
+ os.path.dirname(audio_separator_model_file),
+ os.path.basename(audio_separator_model_file),
+ os.path.join(output_dir, "vocals"),
+ ) if step==2 else None
+
+ image_processor = ImageProcessorForDataProcessing(
+ face_analysis_model_path, landmark_model_path, step)
+
+ for video_path in tqdm(input_video_list, desc="Processing videos"):
+ process_single_video(video_path, output_dir,
+ image_processor, audio_processor, step)
+
+
+def get_video_paths(source_dir: Path, parallelism: int, rank: int) -> List[Path]:
+ """
+ Get paths of videos to process, partitioned for parallel processing.
+
+ Args:
+ source_dir (Path): Source directory containing videos.
+ parallelism (int): Level of parallelism.
+ rank (int): Rank for distributed processing.
+
+ Returns:
+ List[Path]: List of video paths to process.
+ """
+ video_paths = [item for item in sorted(
+ source_dir.iterdir()) if item.is_file() and item.suffix == '.mp4']
+ return [video_paths[i] for i in range(len(video_paths)) if i % parallelism == rank]
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser(
+ description="Process videos to prepare data for training. Run this script twice with different GPU status parameters."
+ )
+ parser.add_argument("-i", "--input_dir", type=Path,
+ required=True, help="Directory containing videos")
+ parser.add_argument("-o", "--output_dir", type=Path,
+ help="Directory to save results, default is parent dir of input dir")
+ parser.add_argument("-s", "--step", type=int, default=1,
+ help="Specify data processing step 1 or 2, you should run 1 and 2 sequently")
+ parser.add_argument("-p", "--parallelism", default=1,
+ type=int, help="Level of parallelism")
+ parser.add_argument("-r", "--rank", default=0, type=int,
+ help="Rank for distributed processing")
+
+ args = parser.parse_args()
+
+ if args.output_dir is None:
+ args.output_dir = args.input_dir.parent
+
+ video_path_list = get_video_paths(
+ args.input_dir, args.parallelism, args.rank)
+
+ if not video_path_list:
+ logging.warning("No videos to process.")
+ else:
+ process_all_videos(video_path_list, args.output_dir, args.step)
diff --git a/animation/hallo-83dd4eb/scripts/extract_meta_info_stage1.py b/animation/hallo-83dd4eb/scripts/extract_meta_info_stage1.py
new file mode 100644
index 0000000..936cb06
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/extract_meta_info_stage1.py
@@ -0,0 +1,106 @@
+# pylint: disable=R0801
+"""
+This module is used to extract meta information from video directories.
+
+It takes in two command-line arguments: `root_path` and `dataset_name`. The `root_path`
+specifies the path to the video directory, while the `dataset_name` specifies the name
+of the dataset. The module then collects all the video folder paths, and for each video
+folder, it checks if a mask path and a face embedding path exist. If they do, it appends
+a dictionary containing the image path, mask path, and face embedding path to a list.
+
+Finally, the module writes the list of dictionaries to a JSON file with the filename
+constructed using the `dataset_name`.
+
+Usage:
+ python tools/extract_meta_info_stage1.py --root_path /path/to/video_dir --dataset_name hdtf
+
+"""
+
+import argparse
+import json
+import os
+from pathlib import Path
+
+import torch
+
+
+def collect_video_folder_paths(root_path: Path) -> list:
+ """
+ Collect all video folder paths from the root path.
+
+ Args:
+ root_path (Path): The root directory containing video folders.
+
+ Returns:
+ list: List of video folder paths.
+ """
+ return [frames_dir.resolve() for frames_dir in root_path.iterdir() if frames_dir.is_dir()]
+
+
+def construct_meta_info(frames_dir_path: Path) -> dict:
+ """
+ Construct meta information for a given frames directory.
+
+ Args:
+ frames_dir_path (Path): The path to the frames directory.
+
+ Returns:
+ dict: A dictionary containing the meta information for the frames directory, or None if the required files do not exist.
+ """
+ mask_path = str(frames_dir_path).replace("images", "face_mask") + ".png"
+ face_emb_path = str(frames_dir_path).replace("images", "face_emb") + ".pt"
+
+ if not os.path.exists(mask_path):
+ print(f"Mask path not found: {mask_path}")
+ return None
+
+ if torch.load(face_emb_path) is None:
+ print(f"Face emb is None: {face_emb_path}")
+ return None
+
+ return {
+ "image_path": str(frames_dir_path),
+ "mask_path": mask_path,
+ "face_emb": face_emb_path,
+ }
+
+
+def main():
+ """
+ Main function to extract meta info for training.
+ """
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-r", "--root_path", type=str,
+ required=True, help="Root path of the video directories")
+ parser.add_argument("-n", "--dataset_name", type=str,
+ required=True, help="Name of the dataset")
+ parser.add_argument("--meta_info_name", type=str,
+ help="Name of the meta information file")
+
+ args = parser.parse_args()
+
+ if args.meta_info_name is None:
+ args.meta_info_name = args.dataset_name
+
+ image_dir = Path(args.root_path) / "images"
+ output_dir = Path("./data")
+ output_dir.mkdir(exist_ok=True)
+
+ # Collect all video folder paths
+ frames_dir_paths = collect_video_folder_paths(image_dir)
+
+ meta_infos = []
+ for frames_dir_path in frames_dir_paths:
+ meta_info = construct_meta_info(frames_dir_path)
+ if meta_info:
+ meta_infos.append(meta_info)
+
+ output_file = output_dir / f"{args.meta_info_name}_stage1.json"
+ with output_file.open("w", encoding="utf-8") as f:
+ json.dump(meta_infos, f, indent=4)
+
+ print(f"Final data count: {len(meta_infos)}")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/animation/hallo-83dd4eb/scripts/extract_meta_info_stage2.py b/animation/hallo-83dd4eb/scripts/extract_meta_info_stage2.py
new file mode 100644
index 0000000..e2d9301
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/extract_meta_info_stage2.py
@@ -0,0 +1,192 @@
+# pylint: disable=R0801
+"""
+This module is used to extract meta information from video files and store them in a JSON file.
+
+The script takes in command line arguments to specify the root path of the video files,
+the dataset name, and the name of the meta information file. It then generates a list of
+dictionaries containing the meta information for each video file and writes it to a JSON
+file with the specified name.
+
+The meta information includes the path to the video file, the mask path, the face mask
+path, the face mask union path, the face mask gaussian path, the lip mask path, the lip
+mask union path, the lip mask gaussian path, the separate mask border, the separate mask
+face, the separate mask lip, the face embedding path, the audio path, the vocals embedding
+base last path, the vocals embedding base all path, the vocals embedding base average
+path, the vocals embedding large last path, the vocals embedding large all path, and the
+vocals embedding large average path.
+
+The script checks if the mask path exists before adding the information to the list.
+
+Usage:
+ python tools/extract_meta_info_stage2.py --root_path --dataset_name --meta_info_name
+
+Example:
+ python tools/extract_meta_info_stage2.py --root_path data/videos_25fps --dataset_name my_dataset --meta_info_name my_meta_info
+"""
+
+import argparse
+import json
+import os
+from pathlib import Path
+
+import torch
+from decord import VideoReader, cpu
+from tqdm import tqdm
+
+
+def get_video_paths(root_path: Path, extensions: list) -> list:
+ """
+ Get a list of video paths from the root path with the specified extensions.
+
+ Args:
+ root_path (Path): The root directory containing video files.
+ extensions (list): List of file extensions to include.
+
+ Returns:
+ list: List of video file paths.
+ """
+ return [str(path.resolve()) for path in root_path.iterdir() if path.suffix in extensions]
+
+
+def file_exists(file_path: str) -> bool:
+ """
+ Check if a file exists.
+
+ Args:
+ file_path (str): The path to the file.
+
+ Returns:
+ bool: True if the file exists, False otherwise.
+ """
+ return os.path.exists(file_path)
+
+
+def construct_paths(video_path: str, base_dir: str, new_dir: str, new_ext: str) -> str:
+ """
+ Construct a new path by replacing the base directory and extension in the original path.
+
+ Args:
+ video_path (str): The original video path.
+ base_dir (str): The base directory to be replaced.
+ new_dir (str): The new directory to replace the base directory.
+ new_ext (str): The new file extension.
+
+ Returns:
+ str: The constructed path.
+ """
+ return str(video_path).replace(base_dir, new_dir).replace(".mp4", new_ext)
+
+
+def extract_meta_info(video_path: str) -> dict:
+ """
+ Extract meta information for a given video file.
+
+ Args:
+ video_path (str): The path to the video file.
+
+ Returns:
+ dict: A dictionary containing the meta information for the video.
+ """
+ mask_path = construct_paths(
+ video_path, "videos", "face_mask", ".png")
+ sep_mask_border = construct_paths(
+ video_path, "videos", "sep_pose_mask", ".png")
+ sep_mask_face = construct_paths(
+ video_path, "videos", "sep_face_mask", ".png")
+ sep_mask_lip = construct_paths(
+ video_path, "videos", "sep_lip_mask", ".png")
+ face_emb_path = construct_paths(
+ video_path, "videos", "face_emb", ".pt")
+ audio_path = construct_paths(video_path, "videos", "audios", ".wav")
+ vocal_emb_base_all = construct_paths(
+ video_path, "videos", "audio_emb", ".pt")
+
+ assert_flag = True
+
+ if not file_exists(mask_path):
+ print(f"Mask path not found: {mask_path}")
+ assert_flag = False
+ if not file_exists(sep_mask_border):
+ print(f"Separate mask border not found: {sep_mask_border}")
+ assert_flag = False
+ if not file_exists(sep_mask_face):
+ print(f"Separate mask face not found: {sep_mask_face}")
+ assert_flag = False
+ if not file_exists(sep_mask_lip):
+ print(f"Separate mask lip not found: {sep_mask_lip}")
+ assert_flag = False
+ if not file_exists(face_emb_path):
+ print(f"Face embedding path not found: {face_emb_path}")
+ assert_flag = False
+ if not file_exists(audio_path):
+ print(f"Audio path not found: {audio_path}")
+ assert_flag = False
+ if not file_exists(vocal_emb_base_all):
+ print(f"Vocal embedding base all not found: {vocal_emb_base_all}")
+ assert_flag = False
+
+ video_frames = VideoReader(video_path, ctx=cpu(0))
+ audio_emb = torch.load(vocal_emb_base_all)
+ if abs(len(video_frames) - audio_emb.shape[0]) > 3:
+ print(f"Frame count mismatch for video: {video_path}")
+ assert_flag = False
+
+ face_emb = torch.load(face_emb_path)
+ if face_emb is None:
+ print(f"Face embedding is None for video: {video_path}")
+ assert_flag = False
+
+ del video_frames, audio_emb
+
+ if assert_flag:
+ return {
+ "video_path": str(video_path),
+ "mask_path": mask_path,
+ "sep_mask_border": sep_mask_border,
+ "sep_mask_face": sep_mask_face,
+ "sep_mask_lip": sep_mask_lip,
+ "face_emb_path": face_emb_path,
+ "audio_path": audio_path,
+ "vocals_emb_base_all": vocal_emb_base_all,
+ }
+ return None
+
+
+def main():
+ """
+ Main function to extract meta info for training.
+ """
+ parser = argparse.ArgumentParser()
+ parser.add_argument("-r", "--root_path", type=str,
+ required=True, help="Root path of the video files")
+ parser.add_argument("-n", "--dataset_name", type=str,
+ required=True, help="Name of the dataset")
+ parser.add_argument("--meta_info_name", type=str,
+ help="Name of the meta information file")
+
+ args = parser.parse_args()
+
+ if args.meta_info_name is None:
+ args.meta_info_name = args.dataset_name
+
+ video_dir = Path(args.root_path) / "videos"
+ video_paths = get_video_paths(video_dir, [".mp4"])
+
+ meta_infos = []
+
+ for video_path in tqdm(video_paths, desc="Extracting meta info"):
+ meta_info = extract_meta_info(video_path)
+ if meta_info:
+ meta_infos.append(meta_info)
+
+ print(f"Final data count: {len(meta_infos)}")
+
+ output_file = Path(f"./data/{args.meta_info_name}_stage2.json")
+ output_file.parent.mkdir(parents=True, exist_ok=True)
+
+ with output_file.open("w", encoding="utf-8") as f:
+ json.dump(meta_infos, f, indent=4)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/animation/hallo-83dd4eb/scripts/inference.py b/animation/hallo-83dd4eb/scripts/inference.py
new file mode 100644
index 0000000..5b780b1
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/inference.py
@@ -0,0 +1,376 @@
+# pylint: disable=E1101
+# scripts/inference.py
+
+"""
+This script contains the main inference pipeline for processing audio and image inputs to generate a video output.
+
+The script imports necessary packages and classes, defines a neural network model,
+and contains functions for processing audio embeddings and performing inference.
+
+The main inference process is outlined in the following steps:
+1. Initialize the configuration.
+2. Set up runtime variables.
+3. Prepare the input data for inference (source image, face mask, and face embeddings).
+4. Process the audio embeddings.
+5. Build and freeze the model and scheduler.
+6. Run the inference loop and save the result.
+
+Usage:
+This script can be run from the command line with the following arguments:
+- audio_path: Path to the audio file.
+- image_path: Path to the source image.
+- face_mask_path: Path to the face mask image.
+- face_emb_path: Path to the face embeddings file.
+- output_path: Path to save the output video.
+
+Example:
+python scripts/inference.py --audio_path audio.wav --image_path image.jpg
+ --face_mask_path face_mask.png --face_emb_path face_emb.pt --output_path output.mp4
+"""
+
+import argparse
+import os
+
+import torch
+from diffusers import AutoencoderKL, DDIMScheduler
+from omegaconf import OmegaConf
+from torch import nn
+
+from hallo.animate.face_animate import FaceAnimatePipeline
+from hallo.datasets.audio_processor import AudioProcessor
+from hallo.datasets.image_processor import ImageProcessor
+from hallo.models.audio_proj import AudioProjModel
+from hallo.models.face_locator import FaceLocator
+from hallo.models.image_proj import ImageProjModel
+from hallo.models.unet_2d_condition import UNet2DConditionModel
+from hallo.models.unet_3d import UNet3DConditionModel
+from hallo.utils.config import filter_non_none
+from hallo.utils.util import tensor_to_video
+
+
+class Net(nn.Module):
+ """
+ The Net class combines all the necessary modules for the inference process.
+
+ Args:
+ reference_unet (UNet2DConditionModel): The UNet2DConditionModel used as a reference for inference.
+ denoising_unet (UNet3DConditionModel): The UNet3DConditionModel used for denoising the input audio.
+ face_locator (FaceLocator): The FaceLocator model used to locate the face in the input image.
+ imageproj (nn.Module): The ImageProjector model used to project the source image onto the face.
+ audioproj (nn.Module): The AudioProjector model used to project the audio embeddings onto the face.
+ """
+ def __init__(
+ self,
+ reference_unet: UNet2DConditionModel,
+ denoising_unet: UNet3DConditionModel,
+ face_locator: FaceLocator,
+ imageproj,
+ audioproj,
+ ):
+ super().__init__()
+ self.reference_unet = reference_unet
+ self.denoising_unet = denoising_unet
+ self.face_locator = face_locator
+ self.imageproj = imageproj
+ self.audioproj = audioproj
+
+ def forward(self,):
+ """
+ empty function to override abstract function of nn Module
+ """
+
+ def get_modules(self):
+ """
+ Simple method to avoid too-few-public-methods pylint error
+ """
+ return {
+ "reference_unet": self.reference_unet,
+ "denoising_unet": self.denoising_unet,
+ "face_locator": self.face_locator,
+ "imageproj": self.imageproj,
+ "audioproj": self.audioproj,
+ }
+
+
+def process_audio_emb(audio_emb):
+ """
+ Process the audio embedding to concatenate with other tensors.
+
+ Parameters:
+ audio_emb (torch.Tensor): The audio embedding tensor to process.
+
+ Returns:
+ concatenated_tensors (List[torch.Tensor]): The concatenated tensor list.
+ """
+ concatenated_tensors = []
+
+ for i in range(audio_emb.shape[0]):
+ vectors_to_concat = [
+ audio_emb[max(min(i + j, audio_emb.shape[0]-1), 0)]for j in range(-2, 3)]
+ concatenated_tensors.append(torch.stack(vectors_to_concat, dim=0))
+
+ audio_emb = torch.stack(concatenated_tensors, dim=0)
+
+ return audio_emb
+
+
+
+def inference_process(args: argparse.Namespace):
+ """
+ Perform inference processing.
+
+ Args:
+ args (argparse.Namespace): Command-line arguments.
+
+ This function initializes the configuration for the inference process. It sets up the necessary
+ modules and variables to prepare for the upcoming inference steps.
+ """
+ # 1. init config
+ cli_args = filter_non_none(vars(args))
+ config = OmegaConf.load(args.config)
+ config = OmegaConf.merge(config, cli_args)
+ source_image_path = config.source_image
+ driving_audio_path = config.driving_audio
+ save_path = config.save_path
+ if not os.path.exists(save_path):
+ os.makedirs(save_path)
+ motion_scale = [config.pose_weight, config.face_weight, config.lip_weight]
+
+ # 2. runtime variables
+ device = torch.device(
+ "cuda") if torch.cuda.is_available() else torch.device("cpu")
+ if config.weight_dtype == "fp16":
+ weight_dtype = torch.float16
+ elif config.weight_dtype == "bf16":
+ weight_dtype = torch.bfloat16
+ elif config.weight_dtype == "fp32":
+ weight_dtype = torch.float32
+ else:
+ weight_dtype = torch.float32
+
+ # 3. prepare inference data
+ # 3.1 prepare source image, face mask, face embeddings
+ img_size = (config.data.source_image.width,
+ config.data.source_image.height)
+ clip_length = config.data.n_sample_frames
+ face_analysis_model_path = config.face_analysis.model_path
+ with ImageProcessor(img_size, face_analysis_model_path) as image_processor:
+ source_image_pixels, \
+ source_image_face_region, \
+ source_image_face_emb, \
+ source_image_full_mask, \
+ source_image_face_mask, \
+ source_image_lip_mask = image_processor.preprocess(
+ source_image_path, save_path, config.face_expand_ratio)
+
+ # 3.2 prepare audio embeddings
+ sample_rate = config.data.driving_audio.sample_rate
+ assert sample_rate == 16000, "audio sample rate must be 16000"
+ fps = config.data.export_video.fps
+ wav2vec_model_path = config.wav2vec.model_path
+ wav2vec_only_last_features = config.wav2vec.features == "last"
+ audio_separator_model_file = config.audio_separator.model_path
+ with AudioProcessor(
+ sample_rate,
+ fps,
+ wav2vec_model_path,
+ wav2vec_only_last_features,
+ os.path.dirname(audio_separator_model_file),
+ os.path.basename(audio_separator_model_file),
+ os.path.join(save_path, "audio_preprocess")
+ ) as audio_processor:
+ audio_emb, audio_length = audio_processor.preprocess(driving_audio_path, clip_length)
+
+ # 4. build modules
+ sched_kwargs = OmegaConf.to_container(config.noise_scheduler_kwargs)
+ if config.enable_zero_snr:
+ sched_kwargs.update(
+ rescale_betas_zero_snr=True,
+ timestep_spacing="trailing",
+ prediction_type="v_prediction",
+ )
+ val_noise_scheduler = DDIMScheduler(**sched_kwargs)
+ sched_kwargs.update({"beta_schedule": "scaled_linear"})
+
+ vae = AutoencoderKL.from_pretrained(config.vae.model_path)
+ reference_unet = UNet2DConditionModel.from_pretrained(
+ config.base_model_path, subfolder="unet")
+ denoising_unet = UNet3DConditionModel.from_pretrained_2d(
+ config.base_model_path,
+ config.motion_module_path,
+ subfolder="unet",
+ unet_additional_kwargs=OmegaConf.to_container(
+ config.unet_additional_kwargs),
+ use_landmark=False,
+ )
+ face_locator = FaceLocator(conditioning_embedding_channels=320)
+ image_proj = ImageProjModel(
+ cross_attention_dim=denoising_unet.config.cross_attention_dim,
+ clip_embeddings_dim=512,
+ clip_extra_context_tokens=4,
+ )
+
+ audio_proj = AudioProjModel(
+ seq_len=5,
+ blocks=12, # use 12 layers' hidden states of wav2vec
+ channels=768, # audio embedding channel
+ intermediate_dim=512,
+ output_dim=768,
+ context_tokens=32,
+ ).to(device=device, dtype=weight_dtype)
+
+ audio_ckpt_dir = config.audio_ckpt_dir
+
+
+ # Freeze
+ vae.requires_grad_(False)
+ image_proj.requires_grad_(False)
+ reference_unet.requires_grad_(False)
+ denoising_unet.requires_grad_(False)
+ face_locator.requires_grad_(False)
+ audio_proj.requires_grad_(False)
+
+ reference_unet.enable_gradient_checkpointing()
+ denoising_unet.enable_gradient_checkpointing()
+
+ net = Net(
+ reference_unet,
+ denoising_unet,
+ face_locator,
+ image_proj,
+ audio_proj,
+ )
+
+ m,u = net.load_state_dict(
+ torch.load(
+ os.path.join(audio_ckpt_dir, "net.pth"),
+ map_location="cpu",
+ ),
+ )
+ assert len(m) == 0 and len(u) == 0, "Fail to load correct checkpoint."
+ print("loaded weight from ", os.path.join(audio_ckpt_dir, "net.pth"))
+
+ # 5. inference
+ pipeline = FaceAnimatePipeline(
+ vae=vae,
+ reference_unet=net.reference_unet,
+ denoising_unet=net.denoising_unet,
+ face_locator=net.face_locator,
+ scheduler=val_noise_scheduler,
+ image_proj=net.imageproj,
+ )
+ pipeline.to(device=device, dtype=weight_dtype)
+
+ audio_emb = process_audio_emb(audio_emb)
+
+ source_image_pixels = source_image_pixels.unsqueeze(0)
+ source_image_face_region = source_image_face_region.unsqueeze(0)
+ source_image_face_emb = source_image_face_emb.reshape(1, -1)
+ source_image_face_emb = torch.tensor(source_image_face_emb)
+
+ source_image_full_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_full_mask
+ ]
+ source_image_face_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_face_mask
+ ]
+ source_image_lip_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_lip_mask
+ ]
+
+
+ times = audio_emb.shape[0] // clip_length
+
+ tensor_result = []
+
+ generator = torch.manual_seed(42)
+
+ for t in range(times):
+ print(f"[{t+1}/{times}]")
+
+ if len(tensor_result) == 0:
+ # The first iteration
+ motion_zeros = source_image_pixels.repeat(
+ config.data.n_motion_frames, 1, 1, 1)
+ motion_zeros = motion_zeros.to(
+ dtype=source_image_pixels.dtype, device=source_image_pixels.device)
+ pixel_values_ref_img = torch.cat(
+ [source_image_pixels, motion_zeros], dim=0) # concat the ref image and the first motion frames
+ else:
+ motion_frames = tensor_result[-1][0]
+ motion_frames = motion_frames.permute(1, 0, 2, 3)
+ motion_frames = motion_frames[0-config.data.n_motion_frames:]
+ motion_frames = motion_frames * 2.0 - 1.0
+ motion_frames = motion_frames.to(
+ dtype=source_image_pixels.dtype, device=source_image_pixels.device)
+ pixel_values_ref_img = torch.cat(
+ [source_image_pixels, motion_frames], dim=0) # concat the ref image and the motion frames
+
+ pixel_values_ref_img = pixel_values_ref_img.unsqueeze(0)
+
+ audio_tensor = audio_emb[
+ t * clip_length: min((t + 1) * clip_length, audio_emb.shape[0])
+ ]
+ audio_tensor = audio_tensor.unsqueeze(0)
+ audio_tensor = audio_tensor.to(
+ device=net.audioproj.device, dtype=net.audioproj.dtype)
+ audio_tensor = net.audioproj(audio_tensor)
+
+ pipeline_output = pipeline(
+ ref_image=pixel_values_ref_img,
+ audio_tensor=audio_tensor,
+ face_emb=source_image_face_emb,
+ face_mask=source_image_face_region,
+ pixel_values_full_mask=source_image_full_mask,
+ pixel_values_face_mask=source_image_face_mask,
+ pixel_values_lip_mask=source_image_lip_mask,
+ width=img_size[0],
+ height=img_size[1],
+ video_length=clip_length,
+ num_inference_steps=config.inference_steps,
+ guidance_scale=config.cfg_scale,
+ generator=generator,
+ motion_scale=motion_scale,
+ )
+
+ tensor_result.append(pipeline_output.videos)
+
+ tensor_result = torch.cat(tensor_result, dim=2)
+ tensor_result = tensor_result.squeeze(0)
+ tensor_result = tensor_result[:, :audio_length]
+
+ output_file = config.output
+ # save the result after all iteration
+ tensor_to_video(tensor_result, output_file, driving_audio_path)
+ return output_file
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+
+ parser.add_argument(
+ "-c", "--config", default="configs/inference/default.yaml")
+ parser.add_argument("--source_image", type=str, required=False,
+ help="source image")
+ parser.add_argument("--driving_audio", type=str, required=False,
+ help="driving audio")
+ parser.add_argument(
+ "--output", type=str, help="output video file name", default=".cache/output.mp4")
+ parser.add_argument(
+ "--pose_weight", type=float, help="weight of pose", required=False)
+ parser.add_argument(
+ "--face_weight", type=float, help="weight of face", required=False)
+ parser.add_argument(
+ "--lip_weight", type=float, help="weight of lip", required=False)
+ parser.add_argument(
+ "--face_expand_ratio", type=float, help="face region", required=False)
+ parser.add_argument(
+ "--audio_ckpt_dir", "--checkpoint", type=str, help="specific checkpoint dir", required=False)
+
+
+ command_line_args = parser.parse_args()
+
+ inference_process(command_line_args)
diff --git a/animation/hallo-83dd4eb/scripts/train_stage1.py b/animation/hallo-83dd4eb/scripts/train_stage1.py
new file mode 100644
index 0000000..e9e7e84
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/train_stage1.py
@@ -0,0 +1,793 @@
+# pylint: disable=E1101,C0415,W0718,R0801
+# scripts/train_stage1.py
+"""
+This is the main training script for stage 1 of the project.
+It imports necessary packages, defines necessary classes and functions, and trains the model using the provided configuration.
+
+The script includes the following classes and functions:
+
+1. Net: A PyTorch model that takes noisy latents, timesteps, reference image latents, face embeddings,
+ and face masks as input and returns the denoised latents.
+3. log_validation: A function that logs the validation information using the given VAE, image encoder,
+ network, scheduler, accelerator, width, height, and configuration.
+4. train_stage1_process: A function that processes the training stage 1 using the given configuration.
+
+The script also includes the necessary imports and a brief description of the purpose of the file.
+"""
+
+import argparse
+import copy
+import logging
+import math
+import os
+import random
+import warnings
+from datetime import datetime
+
+import cv2
+import diffusers
+import mlflow
+import numpy as np
+import torch
+import torch.nn.functional as F
+import torch.utils.checkpoint
+import transformers
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import DistributedDataParallelKwargs
+from diffusers import AutoencoderKL, DDIMScheduler
+from diffusers.optimization import get_scheduler
+from diffusers.utils import check_min_version
+from diffusers.utils.import_utils import is_xformers_available
+from insightface.app import FaceAnalysis
+from omegaconf import OmegaConf
+from PIL import Image
+from torch import nn
+from tqdm.auto import tqdm
+
+from hallo.animate.face_animate_static import StaticPipeline
+from hallo.datasets.mask_image import FaceMaskDataset
+from hallo.models.face_locator import FaceLocator
+from hallo.models.image_proj import ImageProjModel
+from hallo.models.mutual_self_attention import ReferenceAttentionControl
+from hallo.models.unet_2d_condition import UNet2DConditionModel
+from hallo.models.unet_3d import UNet3DConditionModel
+from hallo.utils.util import (compute_snr, delete_additional_ckpt,
+ import_filename, init_output_dir,
+ load_checkpoint, move_final_checkpoint,
+ save_checkpoint, seed_everything)
+
+warnings.filterwarnings("ignore")
+
+# Will error if the minimal version of diffusers is not installed. Remove at your own risks.
+check_min_version("0.10.0.dev0")
+
+logger = get_logger(__name__, log_level="INFO")
+
+
+class Net(nn.Module):
+ """
+ The Net class defines a neural network model that combines a reference UNet2DConditionModel,
+ a denoising UNet3DConditionModel, a face locator, and other components to animate a face in a static image.
+
+ Args:
+ reference_unet (UNet2DConditionModel): The reference UNet2DConditionModel used for face animation.
+ denoising_unet (UNet3DConditionModel): The denoising UNet3DConditionModel used for face animation.
+ face_locator (FaceLocator): The face locator model used for face animation.
+ reference_control_writer: The reference control writer component.
+ reference_control_reader: The reference control reader component.
+ imageproj: The image projection model.
+
+ Forward method:
+ noisy_latents (torch.Tensor): The noisy latents tensor.
+ timesteps (torch.Tensor): The timesteps tensor.
+ ref_image_latents (torch.Tensor): The reference image latents tensor.
+ face_emb (torch.Tensor): The face embeddings tensor.
+ face_mask (torch.Tensor): The face mask tensor.
+ uncond_fwd (bool): A flag indicating whether to perform unconditional forward pass.
+
+ Returns:
+ torch.Tensor: The output tensor of the neural network model.
+ """
+
+ def __init__(
+ self,
+ reference_unet: UNet2DConditionModel,
+ denoising_unet: UNet3DConditionModel,
+ face_locator: FaceLocator,
+ reference_control_writer: ReferenceAttentionControl,
+ reference_control_reader: ReferenceAttentionControl,
+ imageproj: ImageProjModel,
+ ):
+ super().__init__()
+ self.reference_unet = reference_unet
+ self.denoising_unet = denoising_unet
+ self.face_locator = face_locator
+ self.reference_control_writer = reference_control_writer
+ self.reference_control_reader = reference_control_reader
+ self.imageproj = imageproj
+
+ def forward(
+ self,
+ noisy_latents,
+ timesteps,
+ ref_image_latents,
+ face_emb,
+ face_mask,
+ uncond_fwd: bool = False,
+ ):
+ """
+ Forward pass of the model.
+ Args:
+ self (Net): The model instance.
+ noisy_latents (torch.Tensor): Noisy latents.
+ timesteps (torch.Tensor): Timesteps.
+ ref_image_latents (torch.Tensor): Reference image latents.
+ face_emb (torch.Tensor): Face embedding.
+ face_mask (torch.Tensor): Face mask.
+ uncond_fwd (bool, optional): Unconditional forward pass. Defaults to False.
+
+ Returns:
+ torch.Tensor: Model prediction.
+ """
+
+ face_emb = self.imageproj(face_emb)
+ face_mask = face_mask.to(device="cuda")
+ face_mask_feature = self.face_locator(face_mask)
+
+ if not uncond_fwd:
+ ref_timesteps = torch.zeros_like(timesteps)
+ self.reference_unet(
+ ref_image_latents,
+ ref_timesteps,
+ encoder_hidden_states=face_emb,
+ return_dict=False,
+ )
+ self.reference_control_reader.update(self.reference_control_writer)
+ model_pred = self.denoising_unet(
+ noisy_latents,
+ timesteps,
+ mask_cond_fea=face_mask_feature,
+ encoder_hidden_states=face_emb,
+ ).sample
+
+ return model_pred
+
+
+def get_noise_scheduler(cfg: argparse.Namespace):
+ """
+ Create noise scheduler for training
+
+ Args:
+ cfg (omegaconf.dictconfig.DictConfig): Configuration object.
+
+ Returns:
+ train noise scheduler and val noise scheduler
+ """
+ sched_kwargs = OmegaConf.to_container(cfg.noise_scheduler_kwargs)
+ if cfg.enable_zero_snr:
+ sched_kwargs.update(
+ rescale_betas_zero_snr=True,
+ timestep_spacing="trailing",
+ prediction_type="v_prediction",
+ )
+ val_noise_scheduler = DDIMScheduler(**sched_kwargs)
+ sched_kwargs.update({"beta_schedule": "scaled_linear"})
+ train_noise_scheduler = DDIMScheduler(**sched_kwargs)
+
+ return train_noise_scheduler, val_noise_scheduler
+
+
+def log_validation(
+ vae,
+ net,
+ scheduler,
+ accelerator,
+ width,
+ height,
+ imageproj,
+ cfg,
+ save_dir,
+ global_step,
+ face_analysis_model_path,
+):
+ """
+ Log validation generation image.
+
+ Args:
+ vae (nn.Module): Variational Autoencoder model.
+ net (Net): Main model.
+ scheduler (diffusers.SchedulerMixin): Noise scheduler.
+ accelerator (accelerate.Accelerator): Accelerator for training.
+ width (int): Width of the input images.
+ height (int): Height of the input images.
+ imageproj (nn.Module): Image projection model.
+ cfg (omegaconf.dictconfig.DictConfig): Configuration object.
+ save_dir (str): directory path to save log result.
+ global_step (int): Global step number.
+
+ Returns:
+ None
+ """
+ logger.info("Running validation... ")
+
+ ori_net = accelerator.unwrap_model(net)
+ ori_net = copy.deepcopy(ori_net)
+ reference_unet = ori_net.reference_unet
+ denoising_unet = ori_net.denoising_unet
+ face_locator = ori_net.face_locator
+
+ generator = torch.manual_seed(42)
+ image_enc = FaceAnalysis(
+ name="",
+ root=face_analysis_model_path,
+ providers=["CUDAExecutionProvider", "CPUExecutionProvider"],
+ )
+ image_enc.prepare(ctx_id=0, det_size=(640, 640))
+
+ pipe = StaticPipeline(
+ vae=vae,
+ reference_unet=reference_unet,
+ denoising_unet=denoising_unet,
+ face_locator=face_locator,
+ scheduler=scheduler,
+ imageproj=imageproj,
+ )
+
+ pil_images = []
+ for ref_image_path, mask_image_path in zip(cfg.ref_image_paths, cfg.mask_image_paths):
+ # for mask_image_path in mask_image_paths:
+ mask_name = os.path.splitext(
+ os.path.basename(mask_image_path))[0]
+ ref_name = os.path.splitext(
+ os.path.basename(ref_image_path))[0]
+ ref_image_pil = Image.open(ref_image_path).convert("RGB")
+ mask_image_pil = Image.open(mask_image_path).convert("RGB")
+
+ # Prepare face embeds
+ face_info = image_enc.get(
+ cv2.cvtColor(np.array(ref_image_pil), cv2.COLOR_RGB2BGR))
+ face_info = sorted(face_info, key=lambda x: (x['bbox'][2] - x['bbox'][0]) * (
+ x['bbox'][3] - x['bbox'][1]))[-1] # only use the maximum face
+ face_emb = torch.tensor(face_info['embedding'])
+ face_emb = face_emb.to(
+ imageproj.device, imageproj.dtype)
+
+ image = pipe(
+ ref_image_pil,
+ mask_image_pil,
+ width,
+ height,
+ 20,
+ 3.5,
+ face_emb,
+ generator=generator,
+ ).images
+ image = image[0, :, 0].permute(1, 2, 0).cpu().numpy() # (3, 512, 512)
+ res_image_pil = Image.fromarray((image * 255).astype(np.uint8))
+ # Save ref_image, src_image and the generated_image
+ w, h = res_image_pil.size
+ canvas = Image.new("RGB", (w * 3, h), "white")
+ ref_image_pil = ref_image_pil.resize((w, h))
+ mask_image_pil = mask_image_pil.resize((w, h))
+ canvas.paste(ref_image_pil, (0, 0))
+ canvas.paste(mask_image_pil, (w, 0))
+ canvas.paste(res_image_pil, (w * 2, 0))
+
+ out_file = os.path.join(
+ save_dir, f"{global_step:06d}-{ref_name}_{mask_name}.jpg"
+ )
+ canvas.save(out_file)
+
+ del pipe
+ del ori_net
+ torch.cuda.empty_cache()
+
+ return pil_images
+
+
+def train_stage1_process(cfg: argparse.Namespace) -> None:
+ """
+ Trains the model using the given configuration (cfg).
+
+ Args:
+ cfg (dict): The configuration dictionary containing the parameters for training.
+
+ Notes:
+ - This function trains the model using the given configuration.
+ - It initializes the necessary components for training, such as the pipeline, optimizer, and scheduler.
+ - The training progress is logged and tracked using the accelerator.
+ - The trained model is saved after the training is completed.
+ """
+ kwargs = DistributedDataParallelKwargs(find_unused_parameters=True)
+ accelerator = Accelerator(
+ gradient_accumulation_steps=cfg.solver.gradient_accumulation_steps,
+ mixed_precision=cfg.solver.mixed_precision,
+ log_with="mlflow",
+ project_dir="./mlruns",
+ kwargs_handlers=[kwargs],
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ transformers.utils.logging.set_verbosity_warning()
+ diffusers.utils.logging.set_verbosity_info()
+ else:
+ transformers.utils.logging.set_verbosity_error()
+ diffusers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if cfg.seed is not None:
+ seed_everything(cfg.seed)
+
+ # create output dir for training
+ exp_name = cfg.exp_name
+ save_dir = f"{cfg.output_dir}/{exp_name}"
+ checkpoint_dir = os.path.join(save_dir, "checkpoints")
+ module_dir = os.path.join(save_dir, "modules")
+ validation_dir = os.path.join(save_dir, "validation")
+
+ if accelerator.is_main_process:
+ init_output_dir([save_dir, checkpoint_dir, module_dir, validation_dir])
+
+ accelerator.wait_for_everyone()
+
+ # create model
+ if cfg.weight_dtype == "fp16":
+ weight_dtype = torch.float16
+ elif cfg.weight_dtype == "bf16":
+ weight_dtype = torch.bfloat16
+ elif cfg.weight_dtype == "fp32":
+ weight_dtype = torch.float32
+ else:
+ raise ValueError(
+ f"Do not support weight dtype: {cfg.weight_dtype} during training"
+ )
+
+ # create model
+ vae = AutoencoderKL.from_pretrained(cfg.vae_model_path).to(
+ "cuda", dtype=weight_dtype
+ )
+ reference_unet = UNet2DConditionModel.from_pretrained(
+ cfg.base_model_path,
+ subfolder="unet",
+ ).to(device="cuda", dtype=weight_dtype)
+ denoising_unet = UNet3DConditionModel.from_pretrained_2d(
+ cfg.base_model_path,
+ "",
+ subfolder="unet",
+ unet_additional_kwargs={
+ "use_motion_module": False,
+ "unet_use_temporal_attention": False,
+ },
+ use_landmark=False
+ ).to(device="cuda", dtype=weight_dtype)
+ imageproj = ImageProjModel(
+ cross_attention_dim=denoising_unet.config.cross_attention_dim,
+ clip_embeddings_dim=512,
+ clip_extra_context_tokens=4,
+ ).to(device="cuda", dtype=weight_dtype)
+
+ if cfg.face_locator_pretrained:
+ face_locator = FaceLocator(
+ conditioning_embedding_channels=320, block_out_channels=(16, 32, 96, 256)
+ ).to(device="cuda", dtype=weight_dtype)
+ miss, _ = face_locator.load_state_dict(
+ cfg.face_state_dict_path, strict=False)
+ logger.info(f"Missing key for face locator: {len(miss)}")
+ else:
+ face_locator = FaceLocator(
+ conditioning_embedding_channels=320,
+ ).to(device="cuda", dtype=weight_dtype)
+ # Freeze
+ vae.requires_grad_(False)
+ denoising_unet.requires_grad_(True)
+ reference_unet.requires_grad_(True)
+ imageproj.requires_grad_(True)
+ face_locator.requires_grad_(True)
+
+ reference_control_writer = ReferenceAttentionControl(
+ reference_unet,
+ do_classifier_free_guidance=False,
+ mode="write",
+ fusion_blocks="full",
+ )
+ reference_control_reader = ReferenceAttentionControl(
+ denoising_unet,
+ do_classifier_free_guidance=False,
+ mode="read",
+ fusion_blocks="full",
+ )
+
+ net = Net(
+ reference_unet,
+ denoising_unet,
+ face_locator,
+ reference_control_writer,
+ reference_control_reader,
+ imageproj,
+ ).to(dtype=weight_dtype)
+
+ # get noise scheduler
+ train_noise_scheduler, val_noise_scheduler = get_noise_scheduler(cfg)
+
+ # init optimizer
+ if cfg.solver.enable_xformers_memory_efficient_attention:
+ if is_xformers_available():
+ reference_unet.enable_xformers_memory_efficient_attention()
+ denoising_unet.enable_xformers_memory_efficient_attention()
+ else:
+ raise ValueError(
+ "xformers is not available. Make sure it is installed correctly"
+ )
+
+ if cfg.solver.gradient_checkpointing:
+ reference_unet.enable_gradient_checkpointing()
+ denoising_unet.enable_gradient_checkpointing()
+
+ if cfg.solver.scale_lr:
+ learning_rate = (
+ cfg.solver.learning_rate
+ * cfg.solver.gradient_accumulation_steps
+ * cfg.data.train_bs
+ * accelerator.num_processes
+ )
+ else:
+ learning_rate = cfg.solver.learning_rate
+
+ # Initialize the optimizer
+ if cfg.solver.use_8bit_adam:
+ try:
+ import bitsandbytes as bnb
+ except ImportError as exc:
+ raise ImportError(
+ "Please install bitsandbytes to use 8-bit Adam. You can do so by running `pip install bitsandbytes`"
+ ) from exc
+
+ optimizer_cls = bnb.optim.AdamW8bit
+ else:
+ optimizer_cls = torch.optim.AdamW
+
+ trainable_params = list(
+ filter(lambda p: p.requires_grad, net.parameters()))
+ optimizer = optimizer_cls(
+ trainable_params,
+ lr=learning_rate,
+ betas=(cfg.solver.adam_beta1, cfg.solver.adam_beta2),
+ weight_decay=cfg.solver.adam_weight_decay,
+ eps=cfg.solver.adam_epsilon,
+ )
+
+ # init scheduler
+ lr_scheduler = get_scheduler(
+ cfg.solver.lr_scheduler,
+ optimizer=optimizer,
+ num_warmup_steps=cfg.solver.lr_warmup_steps
+ * cfg.solver.gradient_accumulation_steps,
+ num_training_steps=cfg.solver.max_train_steps
+ * cfg.solver.gradient_accumulation_steps,
+ )
+
+ # get data loader
+ train_dataset = FaceMaskDataset(
+ img_size=(cfg.data.train_width, cfg.data.train_height),
+ data_meta_paths=cfg.data.meta_paths,
+ sample_margin=cfg.data.sample_margin,
+ )
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset, batch_size=cfg.data.train_bs, shuffle=True, num_workers=4
+ )
+
+ # Prepare everything with our `accelerator`.
+ (
+ net,
+ optimizer,
+ train_dataloader,
+ lr_scheduler,
+ ) = accelerator.prepare(
+ net,
+ optimizer,
+ train_dataloader,
+ lr_scheduler,
+ )
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(
+ len(train_dataloader) / cfg.solver.gradient_accumulation_steps
+ )
+ # Afterwards we recalculate our number of training epochs
+ num_train_epochs = math.ceil(
+ cfg.solver.max_train_steps / num_update_steps_per_epoch
+ )
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if accelerator.is_main_process:
+ run_time = datetime.now().strftime("%Y%m%d-%H%M")
+ accelerator.init_trackers(
+ cfg.exp_name,
+ init_kwargs={"mlflow": {"run_name": run_time}},
+ )
+ # dump config file
+ mlflow.log_dict(OmegaConf.to_container(cfg), "config.yaml")
+
+ logger.info(f"save config to {save_dir}")
+ OmegaConf.save(
+ cfg, os.path.join(save_dir, "config.yaml")
+ )
+ # Train!
+ total_batch_size = (
+ cfg.data.train_bs
+ * accelerator.num_processes
+ * cfg.solver.gradient_accumulation_steps
+ )
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {cfg.data.train_bs}")
+ logger.info(
+ f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}"
+ )
+ logger.info(
+ f" Gradient Accumulation steps = {cfg.solver.gradient_accumulation_steps}"
+ )
+ logger.info(f" Total optimization steps = {cfg.solver.max_train_steps}")
+ global_step = 0
+ first_epoch = 0
+
+ # load checkpoint
+ # Potentially load in the weights and states from a previous save
+ if cfg.resume_from_checkpoint:
+ logger.info(f"Loading checkpoint from {checkpoint_dir}")
+ global_step = load_checkpoint(cfg, checkpoint_dir, accelerator)
+ first_epoch = global_step // num_update_steps_per_epoch
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(
+ range(global_step, cfg.solver.max_train_steps),
+ disable=not accelerator.is_main_process,
+ )
+ progress_bar.set_description("Steps")
+ net.train()
+ for _ in range(first_epoch, num_train_epochs):
+ train_loss = 0.0
+ for _, batch in enumerate(train_dataloader):
+ with accelerator.accumulate(net):
+ # Convert videos to latent space
+ pixel_values = batch["img"].to(weight_dtype)
+ with torch.no_grad():
+ latents = vae.encode(pixel_values).latent_dist.sample()
+ latents = latents.unsqueeze(2) # (b, c, 1, h, w)
+ latents = latents * 0.18215
+
+ noise = torch.randn_like(latents)
+ if cfg.noise_offset > 0.0:
+ noise += cfg.noise_offset * torch.randn(
+ (noise.shape[0], noise.shape[1], 1, 1, 1),
+ device=noise.device,
+ )
+
+ bsz = latents.shape[0]
+ # Sample a random timestep for each video
+ timesteps = torch.randint(
+ 0,
+ train_noise_scheduler.num_train_timesteps,
+ (bsz,),
+ device=latents.device,
+ )
+ timesteps = timesteps.long()
+
+ face_mask_img = batch["tgt_mask"]
+ face_mask_img = face_mask_img.unsqueeze(
+ 2)
+ face_mask_img = face_mask_img.to(weight_dtype)
+
+ uncond_fwd = random.random() < cfg.uncond_ratio
+ face_emb_list = []
+ ref_image_list = []
+ for _, (ref_img, face_emb) in enumerate(
+ zip(batch["ref_img"], batch["face_emb"])
+ ):
+ if uncond_fwd:
+ face_emb_list.append(torch.zeros_like(face_emb))
+ else:
+ face_emb_list.append(face_emb)
+ ref_image_list.append(ref_img)
+
+ with torch.no_grad():
+ ref_img = torch.stack(ref_image_list, dim=0).to(
+ dtype=vae.dtype, device=vae.device
+ )
+ ref_image_latents = vae.encode(
+ ref_img
+ ).latent_dist.sample()
+ ref_image_latents = ref_image_latents * 0.18215
+
+ face_emb = torch.stack(face_emb_list, dim=0).to(
+ dtype=imageproj.dtype, device=imageproj.device
+ )
+
+ # add noise
+ noisy_latents = train_noise_scheduler.add_noise(
+ latents, noise, timesteps
+ )
+
+ # Get the target for loss depending on the prediction type
+ if train_noise_scheduler.prediction_type == "epsilon":
+ target = noise
+ elif train_noise_scheduler.prediction_type == "v_prediction":
+ target = train_noise_scheduler.get_velocity(
+ latents, noise, timesteps
+ )
+ else:
+ raise ValueError(
+ f"Unknown prediction type {train_noise_scheduler.prediction_type}"
+ )
+ model_pred = net(
+ noisy_latents,
+ timesteps,
+ ref_image_latents,
+ face_emb,
+ face_mask_img,
+ uncond_fwd,
+ )
+
+ if cfg.snr_gamma == 0:
+ loss = F.mse_loss(
+ model_pred.float(), target.float(), reduction="mean"
+ )
+ else:
+ snr = compute_snr(train_noise_scheduler, timesteps)
+ if train_noise_scheduler.config.prediction_type == "v_prediction":
+ # Velocity objective requires that we add one to SNR values before we divide by them.
+ snr = snr + 1
+ mse_loss_weights = (
+ torch.stack(
+ [snr, cfg.snr_gamma * torch.ones_like(timesteps)], dim=1
+ ).min(dim=1)[0]
+ / snr
+ )
+ loss = F.mse_loss(
+ model_pred.float(), target.float(), reduction="none"
+ )
+ loss = (
+ loss.mean(dim=list(range(1, len(loss.shape))))
+ * mse_loss_weights
+ )
+ loss = loss.mean()
+
+ # Gather the losses across all processes for logging (if we use distributed training).
+ avg_loss = accelerator.gather(
+ loss.repeat(cfg.data.train_bs)).mean()
+ train_loss += avg_loss.item() / cfg.solver.gradient_accumulation_steps
+
+ # Backpropagate
+ accelerator.backward(loss)
+ if accelerator.sync_gradients:
+ accelerator.clip_grad_norm_(
+ trainable_params,
+ cfg.solver.max_grad_norm,
+ )
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ if accelerator.sync_gradients:
+ reference_control_reader.clear()
+ reference_control_writer.clear()
+ progress_bar.update(1)
+ global_step += 1
+ accelerator.log({"train_loss": train_loss}, step=global_step)
+ train_loss = 0.0
+ if global_step % cfg.checkpointing_steps == 0 or global_step == cfg.solver.max_train_steps:
+ accelerator.wait_for_everyone()
+ save_path = os.path.join(
+ checkpoint_dir, f"checkpoint-{global_step}")
+ if accelerator.is_main_process:
+ delete_additional_ckpt(checkpoint_dir, 3)
+ accelerator.save_state(save_path)
+ accelerator.wait_for_everyone()
+ unwrap_net = accelerator.unwrap_model(net)
+ if accelerator.is_main_process:
+ save_checkpoint(
+ unwrap_net.reference_unet,
+ module_dir,
+ "reference_unet",
+ global_step,
+ total_limit=3,
+ )
+ save_checkpoint(
+ unwrap_net.imageproj,
+ module_dir,
+ "imageproj",
+ global_step,
+ total_limit=3,
+ )
+ save_checkpoint(
+ unwrap_net.denoising_unet,
+ module_dir,
+ "denoising_unet",
+ global_step,
+ total_limit=3,
+ )
+ save_checkpoint(
+ unwrap_net.face_locator,
+ module_dir,
+ "face_locator",
+ global_step,
+ total_limit=3,
+ )
+
+ if global_step % cfg.val.validation_steps == 0 or global_step == 1:
+ if accelerator.is_main_process:
+ generator = torch.Generator(device=accelerator.device)
+ generator.manual_seed(cfg.seed)
+ log_validation(
+ vae=vae,
+ net=net,
+ scheduler=val_noise_scheduler,
+ accelerator=accelerator,
+ width=cfg.data.train_width,
+ height=cfg.data.train_height,
+ imageproj=imageproj,
+ cfg=cfg,
+ save_dir=validation_dir,
+ global_step=global_step,
+ face_analysis_model_path=cfg.face_analysis_model_path
+ )
+
+ logs = {
+ "step_loss": loss.detach().item(),
+ "lr": lr_scheduler.get_last_lr()[0],
+ }
+ progress_bar.set_postfix(**logs)
+
+ if global_step >= cfg.solver.max_train_steps:
+ # process final module weight for stage2
+ if accelerator.is_main_process:
+ move_final_checkpoint(save_dir, module_dir, "reference_unet")
+ move_final_checkpoint(save_dir, module_dir, "imageproj")
+ move_final_checkpoint(save_dir, module_dir, "denoising_unet")
+ move_final_checkpoint(save_dir, module_dir, "face_locator")
+ break
+
+ accelerator.wait_for_everyone()
+ accelerator.end_training()
+
+
+def load_config(config_path: str) -> dict:
+ """
+ Loads the configuration file.
+
+ Args:
+ config_path (str): Path to the configuration file.
+
+ Returns:
+ dict: The configuration dictionary.
+ """
+
+ if config_path.endswith(".yaml"):
+ return OmegaConf.load(config_path)
+ if config_path.endswith(".py"):
+ return import_filename(config_path).cfg
+ raise ValueError("Unsupported format for config file")
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+ parser.add_argument("--config", type=str,
+ default="./configs/train/stage1.yaml")
+ args = parser.parse_args()
+
+ try:
+ config = load_config(args.config)
+ train_stage1_process(config)
+ except Exception as e:
+ logging.error("Failed to execute the training process: %s", e)
diff --git a/animation/hallo-83dd4eb/scripts/train_stage2.py b/animation/hallo-83dd4eb/scripts/train_stage2.py
new file mode 100644
index 0000000..8cff266
--- /dev/null
+++ b/animation/hallo-83dd4eb/scripts/train_stage2.py
@@ -0,0 +1,991 @@
+# pylint: disable=E1101,C0415,W0718,R0801
+# scripts/train_stage2.py
+"""
+This is the main training script for stage 2 of the project.
+It imports necessary packages, defines necessary classes and functions, and trains the model using the provided configuration.
+
+The script includes the following classes and functions:
+
+1. Net: A PyTorch model that takes noisy latents, timesteps, reference image latents, face embeddings,
+ and face masks as input and returns the denoised latents.
+2. get_attention_mask: A function that rearranges the mask tensors to the required format.
+3. get_noise_scheduler: A function that creates and returns the noise schedulers for training and validation.
+4. process_audio_emb: A function that processes the audio embeddings to concatenate with other tensors.
+5. log_validation: A function that logs the validation information using the given VAE, image encoder,
+ network, scheduler, accelerator, width, height, and configuration.
+6. train_stage2_process: A function that processes the training stage 2 using the given configuration.
+7. load_config: A function that loads the configuration file from the given path.
+
+The script also includes the necessary imports and a brief description of the purpose of the file.
+"""
+
+import argparse
+import copy
+import logging
+import math
+import os
+import random
+import time
+import warnings
+from datetime import datetime
+from typing import List, Tuple
+
+import diffusers
+import mlflow
+import torch
+import torch.nn.functional as F
+import torch.utils.checkpoint
+import transformers
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.utils import DistributedDataParallelKwargs
+from diffusers import AutoencoderKL, DDIMScheduler
+from diffusers.optimization import get_scheduler
+from diffusers.utils import check_min_version
+from diffusers.utils.import_utils import is_xformers_available
+from einops import rearrange, repeat
+from omegaconf import OmegaConf
+from torch import nn
+from tqdm.auto import tqdm
+
+from hallo.animate.face_animate import FaceAnimatePipeline
+from hallo.datasets.audio_processor import AudioProcessor
+from hallo.datasets.image_processor import ImageProcessor
+from hallo.datasets.talk_video import TalkingVideoDataset
+from hallo.models.audio_proj import AudioProjModel
+from hallo.models.face_locator import FaceLocator
+from hallo.models.image_proj import ImageProjModel
+from hallo.models.mutual_self_attention import ReferenceAttentionControl
+from hallo.models.unet_2d_condition import UNet2DConditionModel
+from hallo.models.unet_3d import UNet3DConditionModel
+from hallo.utils.util import (compute_snr, delete_additional_ckpt,
+ import_filename, init_output_dir,
+ load_checkpoint, save_checkpoint,
+ seed_everything, tensor_to_video)
+
+warnings.filterwarnings("ignore")
+
+# Will error if the minimal version of diffusers is not installed. Remove at your own risks.
+check_min_version("0.10.0.dev0")
+
+logger = get_logger(__name__, log_level="INFO")
+
+
+class Net(nn.Module):
+ """
+ The Net class defines a neural network model that combines a reference UNet2DConditionModel,
+ a denoising UNet3DConditionModel, a face locator, and other components to animate a face in a static image.
+
+ Args:
+ reference_unet (UNet2DConditionModel): The reference UNet2DConditionModel used for face animation.
+ denoising_unet (UNet3DConditionModel): The denoising UNet3DConditionModel used for face animation.
+ face_locator (FaceLocator): The face locator model used for face animation.
+ reference_control_writer: The reference control writer component.
+ reference_control_reader: The reference control reader component.
+ imageproj: The image projection model.
+ audioproj: The audio projection model.
+
+ Forward method:
+ noisy_latents (torch.Tensor): The noisy latents tensor.
+ timesteps (torch.Tensor): The timesteps tensor.
+ ref_image_latents (torch.Tensor): The reference image latents tensor.
+ face_emb (torch.Tensor): The face embeddings tensor.
+ audio_emb (torch.Tensor): The audio embeddings tensor.
+ mask (torch.Tensor): Hard face mask for face locator.
+ full_mask (torch.Tensor): Pose Mask.
+ face_mask (torch.Tensor): Face Mask
+ lip_mask (torch.Tensor): Lip Mask
+ uncond_img_fwd (bool): A flag indicating whether to perform reference image unconditional forward pass.
+ uncond_audio_fwd (bool): A flag indicating whether to perform audio unconditional forward pass.
+
+ Returns:
+ torch.Tensor: The output tensor of the neural network model.
+ """
+ def __init__(
+ self,
+ reference_unet: UNet2DConditionModel,
+ denoising_unet: UNet3DConditionModel,
+ face_locator: FaceLocator,
+ reference_control_writer,
+ reference_control_reader,
+ imageproj,
+ audioproj,
+ ):
+ super().__init__()
+ self.reference_unet = reference_unet
+ self.denoising_unet = denoising_unet
+ self.face_locator = face_locator
+ self.reference_control_writer = reference_control_writer
+ self.reference_control_reader = reference_control_reader
+ self.imageproj = imageproj
+ self.audioproj = audioproj
+
+ def forward(
+ self,
+ noisy_latents: torch.Tensor,
+ timesteps: torch.Tensor,
+ ref_image_latents: torch.Tensor,
+ face_emb: torch.Tensor,
+ audio_emb: torch.Tensor,
+ mask: torch.Tensor,
+ full_mask: torch.Tensor,
+ face_mask: torch.Tensor,
+ lip_mask: torch.Tensor,
+ uncond_img_fwd: bool = False,
+ uncond_audio_fwd: bool = False,
+ ):
+ """
+ simple docstring to prevent pylint error
+ """
+ face_emb = self.imageproj(face_emb)
+ mask = mask.to(device="cuda")
+ mask_feature = self.face_locator(mask)
+ audio_emb = audio_emb.to(
+ device=self.audioproj.device, dtype=self.audioproj.dtype)
+ audio_emb = self.audioproj(audio_emb)
+
+ # condition forward
+ if not uncond_img_fwd:
+ ref_timesteps = torch.zeros_like(timesteps)
+ ref_timesteps = repeat(
+ ref_timesteps,
+ "b -> (repeat b)",
+ repeat=ref_image_latents.size(0) // ref_timesteps.size(0),
+ )
+ self.reference_unet(
+ ref_image_latents,
+ ref_timesteps,
+ encoder_hidden_states=face_emb,
+ return_dict=False,
+ )
+ self.reference_control_reader.update(self.reference_control_writer)
+
+ if uncond_audio_fwd:
+ audio_emb = torch.zeros_like(audio_emb).to(
+ device=audio_emb.device, dtype=audio_emb.dtype
+ )
+
+ model_pred = self.denoising_unet(
+ noisy_latents,
+ timesteps,
+ mask_cond_fea=mask_feature,
+ encoder_hidden_states=face_emb,
+ audio_embedding=audio_emb,
+ full_mask=full_mask,
+ face_mask=face_mask,
+ lip_mask=lip_mask
+ ).sample
+
+ return model_pred
+
+
+def get_attention_mask(mask: torch.Tensor, weight_dtype: torch.dtype) -> torch.Tensor:
+ """
+ Rearrange the mask tensors to the required format.
+
+ Args:
+ mask (torch.Tensor): The input mask tensor.
+ weight_dtype (torch.dtype): The data type for the mask tensor.
+
+ Returns:
+ torch.Tensor: The rearranged mask tensor.
+ """
+ if isinstance(mask, List):
+ _mask = []
+ for m in mask:
+ _mask.append(
+ rearrange(m, "b f 1 h w -> (b f) (h w)").to(weight_dtype))
+ return _mask
+ mask = rearrange(mask, "b f 1 h w -> (b f) (h w)").to(weight_dtype)
+ return mask
+
+
+def get_noise_scheduler(cfg: argparse.Namespace) -> Tuple[DDIMScheduler, DDIMScheduler]:
+ """
+ Create noise scheduler for training.
+
+ Args:
+ cfg (argparse.Namespace): Configuration object.
+
+ Returns:
+ Tuple[DDIMScheduler, DDIMScheduler]: Train noise scheduler and validation noise scheduler.
+ """
+
+ sched_kwargs = OmegaConf.to_container(cfg.noise_scheduler_kwargs)
+ if cfg.enable_zero_snr:
+ sched_kwargs.update(
+ rescale_betas_zero_snr=True,
+ timestep_spacing="trailing",
+ prediction_type="v_prediction",
+ )
+ val_noise_scheduler = DDIMScheduler(**sched_kwargs)
+ sched_kwargs.update({"beta_schedule": "scaled_linear"})
+ train_noise_scheduler = DDIMScheduler(**sched_kwargs)
+
+ return train_noise_scheduler, val_noise_scheduler
+
+
+def process_audio_emb(audio_emb: torch.Tensor) -> torch.Tensor:
+ """
+ Process the audio embedding to concatenate with other tensors.
+
+ Parameters:
+ audio_emb (torch.Tensor): The audio embedding tensor to process.
+
+ Returns:
+ concatenated_tensors (List[torch.Tensor]): The concatenated tensor list.
+ """
+ concatenated_tensors = []
+
+ for i in range(audio_emb.shape[0]):
+ vectors_to_concat = [
+ audio_emb[max(min(i + j, audio_emb.shape[0] - 1), 0)]for j in range(-2, 3)]
+ concatenated_tensors.append(torch.stack(vectors_to_concat, dim=0))
+
+ audio_emb = torch.stack(concatenated_tensors, dim=0)
+
+ return audio_emb
+
+
+def log_validation(
+ accelerator: Accelerator,
+ vae: AutoencoderKL,
+ net: Net,
+ scheduler: DDIMScheduler,
+ width: int,
+ height: int,
+ clip_length: int = 24,
+ generator: torch.Generator = None,
+ cfg: dict = None,
+ save_dir: str = None,
+ global_step: int = 0,
+ times: int = None,
+ face_analysis_model_path: str = "",
+) -> None:
+ """
+ Log validation video during the training process.
+
+ Args:
+ accelerator (Accelerator): The accelerator for distributed training.
+ vae (AutoencoderKL): The autoencoder model.
+ net (Net): The main neural network model.
+ scheduler (DDIMScheduler): The scheduler for noise.
+ width (int): The width of the input images.
+ height (int): The height of the input images.
+ clip_length (int): The length of the video clips. Defaults to 24.
+ generator (torch.Generator): The random number generator. Defaults to None.
+ cfg (dict): The configuration dictionary. Defaults to None.
+ save_dir (str): The directory to save validation results. Defaults to None.
+ global_step (int): The current global step in training. Defaults to 0.
+ times (int): The number of inference times. Defaults to None.
+ face_analysis_model_path (str): The path to the face analysis model. Defaults to "".
+
+ Returns:
+ torch.Tensor: The tensor result of the validation.
+ """
+ ori_net = accelerator.unwrap_model(net)
+ reference_unet = ori_net.reference_unet
+ denoising_unet = ori_net.denoising_unet
+ face_locator = ori_net.face_locator
+ imageproj = ori_net.imageproj
+ audioproj = ori_net.audioproj
+
+ generator = torch.manual_seed(42)
+ tmp_denoising_unet = copy.deepcopy(denoising_unet)
+
+ pipeline = FaceAnimatePipeline(
+ vae=vae,
+ reference_unet=reference_unet,
+ denoising_unet=tmp_denoising_unet,
+ face_locator=face_locator,
+ image_proj=imageproj,
+ scheduler=scheduler,
+ )
+ pipeline = pipeline.to("cuda")
+
+ image_processor = ImageProcessor((width, height), face_analysis_model_path)
+ audio_processor = AudioProcessor(
+ cfg.data.sample_rate,
+ cfg.data.fps,
+ cfg.wav2vec_config.model_path,
+ cfg.wav2vec_config.features == "last",
+ os.path.dirname(cfg.audio_separator.model_path),
+ os.path.basename(cfg.audio_separator.model_path),
+ os.path.join(save_dir, '.cache', "audio_preprocess")
+ )
+
+ for idx, ref_img_path in enumerate(cfg.ref_img_path):
+ audio_path = cfg.audio_path[idx]
+ source_image_pixels, \
+ source_image_face_region, \
+ source_image_face_emb, \
+ source_image_full_mask, \
+ source_image_face_mask, \
+ source_image_lip_mask = image_processor.preprocess(
+ ref_img_path, os.path.join(save_dir, '.cache'), cfg.face_expand_ratio)
+ audio_emb, audio_length = audio_processor.preprocess(
+ audio_path, clip_length)
+
+ audio_emb = process_audio_emb(audio_emb)
+
+ source_image_pixels = source_image_pixels.unsqueeze(0)
+ source_image_face_region = source_image_face_region.unsqueeze(0)
+ source_image_face_emb = source_image_face_emb.reshape(1, -1)
+ source_image_face_emb = torch.tensor(source_image_face_emb)
+
+ source_image_full_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_full_mask
+ ]
+ source_image_face_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_face_mask
+ ]
+ source_image_lip_mask = [
+ (mask.repeat(clip_length, 1))
+ for mask in source_image_lip_mask
+ ]
+
+ times = audio_emb.shape[0] // clip_length
+ tensor_result = []
+ generator = torch.manual_seed(42)
+ for t in range(times):
+ print(f"[{t+1}/{times}]")
+
+ if len(tensor_result) == 0:
+ # The first iteration
+ motion_zeros = source_image_pixels.repeat(
+ cfg.data.n_motion_frames, 1, 1, 1)
+ motion_zeros = motion_zeros.to(
+ dtype=source_image_pixels.dtype, device=source_image_pixels.device)
+ pixel_values_ref_img = torch.cat(
+ [source_image_pixels, motion_zeros], dim=0) # concat the ref image and the first motion frames
+ else:
+ motion_frames = tensor_result[-1][0]
+ motion_frames = motion_frames.permute(1, 0, 2, 3)
+ motion_frames = motion_frames[0 - cfg.data.n_motion_frames:]
+ motion_frames = motion_frames * 2.0 - 1.0
+ motion_frames = motion_frames.to(
+ dtype=source_image_pixels.dtype, device=source_image_pixels.device)
+ pixel_values_ref_img = torch.cat(
+ [source_image_pixels, motion_frames], dim=0) # concat the ref image and the motion frames
+
+ pixel_values_ref_img = pixel_values_ref_img.unsqueeze(0)
+
+ audio_tensor = audio_emb[
+ t * clip_length: min((t + 1) * clip_length, audio_emb.shape[0])
+ ]
+ audio_tensor = audio_tensor.unsqueeze(0)
+ audio_tensor = audio_tensor.to(
+ device=audioproj.device, dtype=audioproj.dtype)
+ audio_tensor = audioproj(audio_tensor)
+
+ pipeline_output = pipeline(
+ ref_image=pixel_values_ref_img,
+ audio_tensor=audio_tensor,
+ face_emb=source_image_face_emb,
+ face_mask=source_image_face_region,
+ pixel_values_full_mask=source_image_full_mask,
+ pixel_values_face_mask=source_image_face_mask,
+ pixel_values_lip_mask=source_image_lip_mask,
+ width=cfg.data.train_width,
+ height=cfg.data.train_height,
+ video_length=clip_length,
+ num_inference_steps=cfg.inference_steps,
+ guidance_scale=cfg.cfg_scale,
+ generator=generator,
+ )
+
+ tensor_result.append(pipeline_output.videos)
+
+ tensor_result = torch.cat(tensor_result, dim=2)
+ tensor_result = tensor_result.squeeze(0)
+ tensor_result = tensor_result[:, :audio_length]
+ audio_name = os.path.basename(audio_path).split('.')[0]
+ ref_name = os.path.basename(ref_img_path).split('.')[0]
+ output_file = os.path.join(save_dir,f"{global_step}_{ref_name}_{audio_name}.mp4")
+ # save the result after all iteration
+ tensor_to_video(tensor_result, output_file, audio_path)
+
+
+ # clean up
+ del tmp_denoising_unet
+ del pipeline
+ del image_processor
+ del audio_processor
+ torch.cuda.empty_cache()
+
+ return tensor_result
+
+
+def train_stage2_process(cfg: argparse.Namespace) -> None:
+ """
+ Trains the model using the given configuration (cfg).
+
+ Args:
+ cfg (dict): The configuration dictionary containing the parameters for training.
+
+ Notes:
+ - This function trains the model using the given configuration.
+ - It initializes the necessary components for training, such as the pipeline, optimizer, and scheduler.
+ - The training progress is logged and tracked using the accelerator.
+ - The trained model is saved after the training is completed.
+ """
+ kwargs = DistributedDataParallelKwargs(find_unused_parameters=False)
+ accelerator = Accelerator(
+ gradient_accumulation_steps=cfg.solver.gradient_accumulation_steps,
+ mixed_precision=cfg.solver.mixed_precision,
+ log_with="mlflow",
+ project_dir="./mlruns",
+ kwargs_handlers=[kwargs],
+ )
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ transformers.utils.logging.set_verbosity_warning()
+ diffusers.utils.logging.set_verbosity_info()
+ else:
+ transformers.utils.logging.set_verbosity_error()
+ diffusers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if cfg.seed is not None:
+ seed_everything(cfg.seed)
+
+ # create output dir for training
+ exp_name = cfg.exp_name
+ save_dir = f"{cfg.output_dir}/{exp_name}"
+ checkpoint_dir = os.path.join(save_dir, "checkpoints")
+ module_dir = os.path.join(save_dir, "modules")
+ validation_dir = os.path.join(save_dir, "validation")
+ if accelerator.is_main_process:
+ init_output_dir([save_dir, checkpoint_dir, module_dir, validation_dir])
+
+ accelerator.wait_for_everyone()
+
+ if cfg.weight_dtype == "fp16":
+ weight_dtype = torch.float16
+ elif cfg.weight_dtype == "bf16":
+ weight_dtype = torch.bfloat16
+ elif cfg.weight_dtype == "fp32":
+ weight_dtype = torch.float32
+ else:
+ raise ValueError(
+ f"Do not support weight dtype: {cfg.weight_dtype} during training"
+ )
+
+ # Create Models
+ vae = AutoencoderKL.from_pretrained(cfg.vae_model_path).to(
+ "cuda", dtype=weight_dtype
+ )
+ reference_unet = UNet2DConditionModel.from_pretrained(
+ cfg.base_model_path,
+ subfolder="unet",
+ ).to(device="cuda", dtype=weight_dtype)
+ denoising_unet = UNet3DConditionModel.from_pretrained_2d(
+ cfg.base_model_path,
+ cfg.mm_path,
+ subfolder="unet",
+ unet_additional_kwargs=OmegaConf.to_container(
+ cfg.unet_additional_kwargs),
+ use_landmark=False
+ ).to(device="cuda", dtype=weight_dtype)
+ imageproj = ImageProjModel(
+ cross_attention_dim=denoising_unet.config.cross_attention_dim,
+ clip_embeddings_dim=512,
+ clip_extra_context_tokens=4,
+ ).to(device="cuda", dtype=weight_dtype)
+ face_locator = FaceLocator(
+ conditioning_embedding_channels=320,
+ ).to(device="cuda", dtype=weight_dtype)
+ audioproj = AudioProjModel(
+ seq_len=5,
+ blocks=12,
+ channels=768,
+ intermediate_dim=512,
+ output_dim=768,
+ context_tokens=32,
+ ).to(device="cuda", dtype=weight_dtype)
+
+ # load module weight from stage 1
+ stage1_ckpt_dir = cfg.stage1_ckpt_dir
+ denoising_unet.load_state_dict(
+ torch.load(
+ os.path.join(stage1_ckpt_dir, "denoising_unet.pth"),
+ map_location="cpu",
+ ),
+ strict=False,
+ )
+ reference_unet.load_state_dict(
+ torch.load(
+ os.path.join(stage1_ckpt_dir, "reference_unet.pth"),
+ map_location="cpu",
+ ),
+ strict=False,
+ )
+ face_locator.load_state_dict(
+ torch.load(
+ os.path.join(stage1_ckpt_dir, "face_locator.pth"),
+ map_location="cpu",
+ ),
+ strict=False,
+ )
+ imageproj.load_state_dict(
+ torch.load(
+ os.path.join(stage1_ckpt_dir, "imageproj.pth"),
+ map_location="cpu",
+ ),
+ strict=False,
+ )
+
+ # Freeze
+ vae.requires_grad_(False)
+ imageproj.requires_grad_(False)
+ reference_unet.requires_grad_(False)
+ denoising_unet.requires_grad_(False)
+ face_locator.requires_grad_(False)
+ audioproj.requires_grad_(True)
+
+ # Set motion module learnable
+ trainable_modules = cfg.trainable_para
+ for name, module in denoising_unet.named_modules():
+ if any(trainable_mod in name for trainable_mod in trainable_modules):
+ for params in module.parameters():
+ params.requires_grad_(True)
+
+ reference_control_writer = ReferenceAttentionControl(
+ reference_unet,
+ do_classifier_free_guidance=False,
+ mode="write",
+ fusion_blocks="full",
+ )
+ reference_control_reader = ReferenceAttentionControl(
+ denoising_unet,
+ do_classifier_free_guidance=False,
+ mode="read",
+ fusion_blocks="full",
+ )
+
+ net = Net(
+ reference_unet,
+ denoising_unet,
+ face_locator,
+ reference_control_writer,
+ reference_control_reader,
+ imageproj,
+ audioproj,
+ ).to(dtype=weight_dtype)
+
+ # get noise scheduler
+ train_noise_scheduler, val_noise_scheduler = get_noise_scheduler(cfg)
+
+ if cfg.solver.enable_xformers_memory_efficient_attention:
+ if is_xformers_available():
+ reference_unet.enable_xformers_memory_efficient_attention()
+ denoising_unet.enable_xformers_memory_efficient_attention()
+
+ else:
+ raise ValueError(
+ "xformers is not available. Make sure it is installed correctly"
+ )
+
+ if cfg.solver.gradient_checkpointing:
+ reference_unet.enable_gradient_checkpointing()
+ denoising_unet.enable_gradient_checkpointing()
+
+ if cfg.solver.scale_lr:
+ learning_rate = (
+ cfg.solver.learning_rate
+ * cfg.solver.gradient_accumulation_steps
+ * cfg.data.train_bs
+ * accelerator.num_processes
+ )
+ else:
+ learning_rate = cfg.solver.learning_rate
+
+ # Initialize the optimizer
+ if cfg.solver.use_8bit_adam:
+ try:
+ import bitsandbytes as bnb
+ except ImportError as exc:
+ raise ImportError(
+ "Please install bitsandbytes to use 8-bit Adam. You can do so by running `pip install bitsandbytes`"
+ ) from exc
+ optimizer_cls = bnb.optim.AdamW8bit
+ else:
+ optimizer_cls = torch.optim.AdamW
+
+ trainable_params = list(
+ filter(lambda p: p.requires_grad, net.parameters()))
+ logger.info(f"Total trainable params {len(trainable_params)}")
+ optimizer = optimizer_cls(
+ trainable_params,
+ lr=learning_rate,
+ betas=(cfg.solver.adam_beta1, cfg.solver.adam_beta2),
+ weight_decay=cfg.solver.adam_weight_decay,
+ eps=cfg.solver.adam_epsilon,
+ )
+
+ # Scheduler
+ lr_scheduler = get_scheduler(
+ cfg.solver.lr_scheduler,
+ optimizer=optimizer,
+ num_warmup_steps=cfg.solver.lr_warmup_steps
+ * cfg.solver.gradient_accumulation_steps,
+ num_training_steps=cfg.solver.max_train_steps
+ * cfg.solver.gradient_accumulation_steps,
+ )
+
+ # get data loader
+ train_dataset = TalkingVideoDataset(
+ img_size=(cfg.data.train_width, cfg.data.train_height),
+ sample_rate=cfg.data.sample_rate,
+ n_sample_frames=cfg.data.n_sample_frames,
+ n_motion_frames=cfg.data.n_motion_frames,
+ audio_margin=cfg.data.audio_margin,
+ data_meta_paths=cfg.data.train_meta_paths,
+ wav2vec_cfg=cfg.wav2vec_config,
+ )
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset, batch_size=cfg.data.train_bs, shuffle=True, num_workers=16
+ )
+
+ # Prepare everything with our `accelerator`.
+ (
+ net,
+ optimizer,
+ train_dataloader,
+ lr_scheduler,
+ ) = accelerator.prepare(
+ net,
+ optimizer,
+ train_dataloader,
+ lr_scheduler,
+ )
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(
+ len(train_dataloader) / cfg.solver.gradient_accumulation_steps
+ )
+ # Afterwards we recalculate our number of training epochs
+ num_train_epochs = math.ceil(
+ cfg.solver.max_train_steps / num_update_steps_per_epoch
+ )
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if accelerator.is_main_process:
+ run_time = datetime.now().strftime("%Y%m%d-%H%M")
+ accelerator.init_trackers(
+ exp_name,
+ init_kwargs={"mlflow": {"run_name": run_time}},
+ )
+ # dump config file
+ mlflow.log_dict(
+ OmegaConf.to_container(
+ cfg), "config.yaml"
+ )
+ logger.info(f"save config to {save_dir}")
+ OmegaConf.save(
+ cfg, os.path.join(save_dir, "config.yaml")
+ )
+
+ # Train!
+ total_batch_size = (
+ cfg.data.train_bs
+ * accelerator.num_processes
+ * cfg.solver.gradient_accumulation_steps
+ )
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {cfg.data.train_bs}")
+ logger.info(
+ f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}"
+ )
+ logger.info(
+ f" Gradient Accumulation steps = {cfg.solver.gradient_accumulation_steps}"
+ )
+ logger.info(f" Total optimization steps = {cfg.solver.max_train_steps}")
+ global_step = 0
+ first_epoch = 0
+
+ # # Potentially load in the weights and states from a previous save
+ if cfg.resume_from_checkpoint:
+ logger.info(f"Loading checkpoint from {checkpoint_dir}")
+ global_step = load_checkpoint(cfg, checkpoint_dir, accelerator)
+ first_epoch = global_step // num_update_steps_per_epoch
+
+ # Only show the progress bar once on each machine.
+ progress_bar = tqdm(
+ range(global_step, cfg.solver.max_train_steps),
+ disable=not accelerator.is_local_main_process,
+ )
+ progress_bar.set_description("Steps")
+
+ for _ in range(first_epoch, num_train_epochs):
+ train_loss = 0.0
+ t_data_start = time.time()
+ for _, batch in enumerate(train_dataloader):
+ t_data = time.time() - t_data_start
+ with accelerator.accumulate(net):
+ # Convert videos to latent space
+ pixel_values_vid = batch["pixel_values_vid"].to(weight_dtype)
+
+ pixel_values_face_mask = batch["pixel_values_face_mask"]
+ pixel_values_face_mask = get_attention_mask(
+ pixel_values_face_mask, weight_dtype
+ )
+ pixel_values_lip_mask = batch["pixel_values_lip_mask"]
+ pixel_values_lip_mask = get_attention_mask(
+ pixel_values_lip_mask, weight_dtype
+ )
+ pixel_values_full_mask = batch["pixel_values_full_mask"]
+ pixel_values_full_mask = get_attention_mask(
+ pixel_values_full_mask, weight_dtype
+ )
+
+ with torch.no_grad():
+ video_length = pixel_values_vid.shape[1]
+ pixel_values_vid = rearrange(
+ pixel_values_vid, "b f c h w -> (b f) c h w"
+ )
+ latents = vae.encode(pixel_values_vid).latent_dist.sample()
+ latents = rearrange(
+ latents, "(b f) c h w -> b c f h w", f=video_length
+ )
+ latents = latents * 0.18215
+
+ noise = torch.randn_like(latents)
+ if cfg.noise_offset > 0:
+ noise += cfg.noise_offset * torch.randn(
+ (latents.shape[0], latents.shape[1], 1, 1, 1),
+ device=latents.device,
+ )
+
+ bsz = latents.shape[0]
+ # Sample a random timestep for each video
+ timesteps = torch.randint(
+ 0,
+ train_noise_scheduler.num_train_timesteps,
+ (bsz,),
+ device=latents.device,
+ )
+ timesteps = timesteps.long()
+
+ # mask for face locator
+ pixel_values_mask = (
+ batch["pixel_values_mask"].unsqueeze(
+ 1).to(dtype=weight_dtype)
+ )
+ pixel_values_mask = repeat(
+ pixel_values_mask,
+ "b f c h w -> b (repeat f) c h w",
+ repeat=video_length,
+ )
+ pixel_values_mask = pixel_values_mask.transpose(
+ 1, 2)
+
+ uncond_img_fwd = random.random() < cfg.uncond_img_ratio
+ uncond_audio_fwd = random.random() < cfg.uncond_audio_ratio
+
+ start_frame = random.random() < cfg.start_ratio
+ pixel_values_ref_img = batch["pixel_values_ref_img"].to(
+ dtype=weight_dtype
+ )
+ # initialize the motion frames as zero maps
+ if start_frame:
+ pixel_values_ref_img[:, 1:] = 0.0
+
+ ref_img_and_motion = rearrange(
+ pixel_values_ref_img, "b f c h w -> (b f) c h w"
+ )
+
+ with torch.no_grad():
+ ref_image_latents = vae.encode(
+ ref_img_and_motion
+ ).latent_dist.sample()
+ ref_image_latents = ref_image_latents * 0.18215
+ image_prompt_embeds = batch["face_emb"].to(
+ dtype=imageproj.dtype, device=imageproj.device
+ )
+
+ # add noise
+ noisy_latents = train_noise_scheduler.add_noise(
+ latents, noise, timesteps
+ )
+
+ # Get the target for loss depending on the prediction type
+ if train_noise_scheduler.prediction_type == "epsilon":
+ target = noise
+ elif train_noise_scheduler.prediction_type == "v_prediction":
+ target = train_noise_scheduler.get_velocity(
+ latents, noise, timesteps
+ )
+ else:
+ raise ValueError(
+ f"Unknown prediction type {train_noise_scheduler.prediction_type}"
+ )
+
+ # ---- Forward!!! -----
+ model_pred = net(
+ noisy_latents=noisy_latents,
+ timesteps=timesteps,
+ ref_image_latents=ref_image_latents,
+ face_emb=image_prompt_embeds,
+ mask=pixel_values_mask,
+ full_mask=pixel_values_full_mask,
+ face_mask=pixel_values_face_mask,
+ lip_mask=pixel_values_lip_mask,
+ audio_emb=batch["audio_tensor"].to(
+ dtype=weight_dtype),
+ uncond_img_fwd=uncond_img_fwd,
+ uncond_audio_fwd=uncond_audio_fwd,
+ )
+
+ if cfg.snr_gamma == 0:
+ loss = F.mse_loss(
+ model_pred.float(),
+ target.float(),
+ reduction="mean",
+ )
+ else:
+ snr = compute_snr(train_noise_scheduler, timesteps)
+ if train_noise_scheduler.config.prediction_type == "v_prediction":
+ # Velocity objective requires that we add one to SNR values before we divide by them.
+ snr = snr + 1
+ mse_loss_weights = (
+ torch.stack(
+ [snr, cfg.snr_gamma * torch.ones_like(timesteps)], dim=1
+ ).min(dim=1)[0]
+ / snr
+ )
+ loss = F.mse_loss(
+ model_pred.float(),
+ target.float(),
+ reduction="mean",
+ )
+ loss = (
+ loss.mean(dim=list(range(1, len(loss.shape))))
+ * mse_loss_weights
+ ).mean()
+
+ # Gather the losses across all processes for logging (if we use distributed training).
+ avg_loss = accelerator.gather(
+ loss.repeat(cfg.data.train_bs)).mean()
+ train_loss += avg_loss.item() / cfg.solver.gradient_accumulation_steps
+
+ # Backpropagate
+ accelerator.backward(loss)
+ if accelerator.sync_gradients:
+ accelerator.clip_grad_norm_(
+ trainable_params,
+ cfg.solver.max_grad_norm,
+ )
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ if accelerator.sync_gradients:
+ reference_control_reader.clear()
+ reference_control_writer.clear()
+ progress_bar.update(1)
+ global_step += 1
+ accelerator.log({"train_loss": train_loss}, step=global_step)
+ train_loss = 0.0
+
+ if global_step % cfg.val.validation_steps == 0 or global_step==1:
+ if accelerator.is_main_process:
+ generator = torch.Generator(device=accelerator.device)
+ generator.manual_seed(cfg.seed)
+
+ log_validation(
+ accelerator=accelerator,
+ vae=vae,
+ net=net,
+ scheduler=val_noise_scheduler,
+ width=cfg.data.train_width,
+ height=cfg.data.train_height,
+ clip_length=cfg.data.n_sample_frames,
+ cfg=cfg,
+ save_dir=validation_dir,
+ global_step=global_step,
+ times=cfg.single_inference_times if cfg.single_inference_times is not None else None,
+ face_analysis_model_path=cfg.face_analysis_model_path
+ )
+
+ logs = {
+ "step_loss": loss.detach().item(),
+ "lr": lr_scheduler.get_last_lr()[0],
+ "td": f"{t_data:.2f}s",
+ }
+ t_data_start = time.time()
+ progress_bar.set_postfix(**logs)
+
+ if (
+ global_step % cfg.checkpointing_steps == 0
+ or global_step == cfg.solver.max_train_steps
+ ):
+ # save model
+ save_path = os.path.join(
+ checkpoint_dir, f"checkpoint-{global_step}")
+ if accelerator.is_main_process:
+ delete_additional_ckpt(checkpoint_dir, 30)
+ accelerator.wait_for_everyone()
+ accelerator.save_state(save_path)
+
+ # save model weight
+ unwrap_net = accelerator.unwrap_model(net)
+ if accelerator.is_main_process:
+ save_checkpoint(
+ unwrap_net,
+ module_dir,
+ "net",
+ global_step,
+ total_limit=30,
+ )
+ if global_step >= cfg.solver.max_train_steps:
+ break
+
+ # Create the pipeline using the trained modules and save it.
+ accelerator.wait_for_everyone()
+ accelerator.end_training()
+
+
+def load_config(config_path: str) -> dict:
+ """
+ Loads the configuration file.
+
+ Args:
+ config_path (str): Path to the configuration file.
+
+ Returns:
+ dict: The configuration dictionary.
+ """
+
+ if config_path.endswith(".yaml"):
+ return OmegaConf.load(config_path)
+ if config_path.endswith(".py"):
+ return import_filename(config_path).cfg
+ raise ValueError("Unsupported format for config file")
+
+
+if __name__ == "__main__":
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ "--config", type=str, default="./configs/train/stage2.yaml"
+ )
+ args = parser.parse_args()
+
+ try:
+ config = load_config(args.config)
+ train_stage2_process(config)
+ except Exception as e:
+ logging.error("Failed to execute the training process: %s", e)
diff --git a/animation/hallo-83dd4eb/setup.py b/animation/hallo-83dd4eb/setup.py
new file mode 100644
index 0000000..92320f1
--- /dev/null
+++ b/animation/hallo-83dd4eb/setup.py
@@ -0,0 +1,55 @@
+"""
+setup.py
+----
+This is the main setup file for the hallo face animation project. It defines the package
+metadata, required dependencies, and provides the entry point for installing the package.
+
+"""
+
+# -*- coding: utf-8 -*-
+from setuptools import setup
+
+packages = \
+ ['hallo', 'hallo.datasets', 'hallo.models', 'hallo.animate', 'hallo.utils']
+
+package_data = \
+{'': ['*']}
+
+install_requires = \
+['accelerate==0.28.0',
+ 'audio-separator>=0.17.2,<0.18.0',
+ 'av==12.1.0',
+ 'bitsandbytes==0.43.1',
+ 'decord==0.6.0',
+ 'diffusers==0.27.2',
+ 'einops>=0.8.0,<0.9.0',
+ 'insightface>=0.7.3,<0.8.0',
+ 'mediapipe[vision]>=0.10.14,<0.11.0',
+ 'mlflow==2.13.1',
+ 'moviepy>=1.0.3,<2.0.0',
+ 'omegaconf>=2.3.0,<3.0.0',
+ 'opencv-python>=4.9.0.80,<5.0.0.0',
+ 'pillow>=10.3.0,<11.0.0',
+ 'torch==2.2.2',
+ 'torchvision==0.17.2',
+ 'transformers==4.39.2',
+ 'xformers==0.0.25.post1']
+
+setup_kwargs = {
+ 'name': 'hallo',
+ 'version': '0.1.0',
+ 'description': '',
+ 'long_description': '# Anna face animation',
+ 'author': 'Your Name',
+ 'author_email': 'you@example.com',
+ 'maintainer': 'None',
+ 'maintainer_email': 'None',
+ 'url': 'None',
+ 'packages': packages,
+ 'package_data': package_data,
+ 'install_requires': install_requires,
+ 'python_requires': '>=3.10,<4.0',
+}
+
+
+setup(**setup_kwargs)
 +
 +
 +
 +
 +
 +
 +