mirror of
https://github.com/storytold/terraform-aws-observability-accelerator.git
synced 2026-10-17 00:23:17 +00:00
Docs (#69)
* working first run

* removing core module dependencies

* adding CW datasource

* alarms MVP

* readmes

* Adding Screenshot

* Adding billing note

* adding billing module

* Revert "adding billing module"

This reverts commit 40d667e37db1036cd71a471ef2fde83ec02aaa13.

reverting

* adding billing module

* Updating Screenshot

* resolving feedback

* removing unused modules

* fmt

* Support for tf 1.3.x

* removing unused variables

* support alarms for multiple workspaces

* Updating Readme

* docs first draft

* indigo nav fix

* Simplify docs

* RUM White Logo

* amp docs

* removing billing docs

* Change docs structure, reword infrastructure monitoring doc

* Pre-commit fixes

* drop dead code

* Add concepts page

* Update contributors

* Update java

* Update docs

* Docs for workloads

* Update docs site

* typos

* pre-commit fixes

* Update pre-commit

* Update pre-commit

Co-authored-by: Rodrigue Koffi <bonclay7@users.noreply.github.com>
This commit is contained in:
 Kevin Lewin
@@ -0,0 +1,197 @@
|
||||
# Monitor Java/JMX applications running on Amazon EKS
|
||||
|
||||
The current example deploys the [java workload module](https://github.com/aws-observability/terraform-aws-observability-accelerator/tree/main/modules/workloads/java),
|
||||
to provide to an existing EKS cluster with an OpenTelemetry collector,
|
||||
curated Grafana dashboards, Prometheus alerting and recording rules with multiple
|
||||
configuration options on the cluster infrastructure.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Make sure to complete the [prerequisites section](/terraform-aws-observability-accelerator/concepts/#prerequisites)
|
||||
before proceeding.
|
||||
|
||||
## Setup
|
||||
|
||||
### 1. Download sources and initialize Terraform
|
||||
|
||||
```bash
|
||||
git clone https://github.com/aws-observability/terraform-aws-observability-accelerator.git
|
||||
cd examples/existing-cluster-java
|
||||
terraform init
|
||||
```
|
||||
|
||||
### 2. AWS Region
|
||||
|
||||
Specify the AWS Region where the resources will be deployed:
|
||||
|
||||
```bash
|
||||
export TF_VAR_aws_region=xxx
|
||||
```
|
||||
|
||||
### 3. Amazon EKS Cluster
|
||||
|
||||
To run this example, you need to provide your EKS cluster name. If you don't
|
||||
have a cluster ready, visit [this example](/terraform-aws-observability-accelerator/helpers/new-eks-cluster.md)
|
||||
first to create a new one.
|
||||
|
||||
Specify your cluster name:
|
||||
|
||||
```bash
|
||||
export TF_VAR_eks_cluster_id=xxx
|
||||
```
|
||||
|
||||
### 4. Amazon Managed Service for Prometheus workspace (optional)
|
||||
|
||||
By default, we create an Amazon Managed Service for Prometheus workspace for you.
|
||||
However, if you have an existing workspace you want to reuse, edit and run:
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_prometheus_workspace_id=ws-xxx
|
||||
```
|
||||
|
||||
To create a workspace outside of Terraform's state, simply run:
|
||||
|
||||
```bash
|
||||
aws amp create-workspace --alias observability-accelerator --query '.workspaceId' --output text
|
||||
```
|
||||
|
||||
### 5. Amazon Managed Grafana workspace
|
||||
|
||||
To run this example you need an Amazon Managed Grafana workspace. If you have an existing workspace, edit and run:
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_grafana_workspace_id=g-xxx
|
||||
```
|
||||
|
||||
To create a new one, within this example's Terraform state (sharing the same lifecycle with all the other resources):
|
||||
|
||||
- Edit main.tf and set `enable_managed_grafana = true`
|
||||
- Run
|
||||
|
||||
```bash
|
||||
terraform init
|
||||
terraform apply -target "module.eks_observability_accelerator.module.managed_grafana[0].aws_grafana_workspace.this[0]"
|
||||
export TF_VAR_managed_grafana_workspace_id=$(terraform output --raw managed_grafana_workspace_id)
|
||||
```
|
||||
|
||||
### 6. Grafana API Key
|
||||
|
||||
Amazon Managed Grafana provides a control plane API for generating Grafana API keys.
|
||||
As a security best practice, we will provide to Terraform a short lived API key to
|
||||
run the `apply` or `destroy` command.
|
||||
|
||||
Ensure you have necessary IAM permissions (`CreateWorkspaceApiKey, DeleteWorkspaceApiKey`)
|
||||
|
||||
```bash
|
||||
export TF_VAR_grafana_api_key=`aws grafana create-workspace-api-key --key-name "observability-accelerator-$(date +%s)" --key-role ADMIN --seconds-to-live 1200 --workspace-id $TF_VAR_managed_grafana_workspace_id --query key --output text`
|
||||
```
|
||||
|
||||
## Deploy
|
||||
|
||||
Simply run this command to deploy.
|
||||
|
||||
```bash
|
||||
terraform apply
|
||||
```
|
||||
|
||||
## Visualization
|
||||
|
||||
1. Prometheus datasource on Grafana
|
||||
|
||||
Open your Grafana workspace and under Configuration -> Data sources, you will see `aws-observability-accelerator`. Open and click `Save & test`. You will then see a notification confirming that the Amazon Managed Service for Prometheus workspace is ready to be used on Grafana.
|
||||
|
||||
2. Grafana dashboards
|
||||
|
||||
Go to the Dashboards panel of your Grafana workspace. There will be a folder called `Observability Accelerator Dashboards`
|
||||
|
||||
<img width="832" alt="image" src="https://user-images.githubusercontent.com/97046295/194903648-57c55d30-6f90-4b03-9eb6-577aaba7dc22.png">
|
||||
|
||||
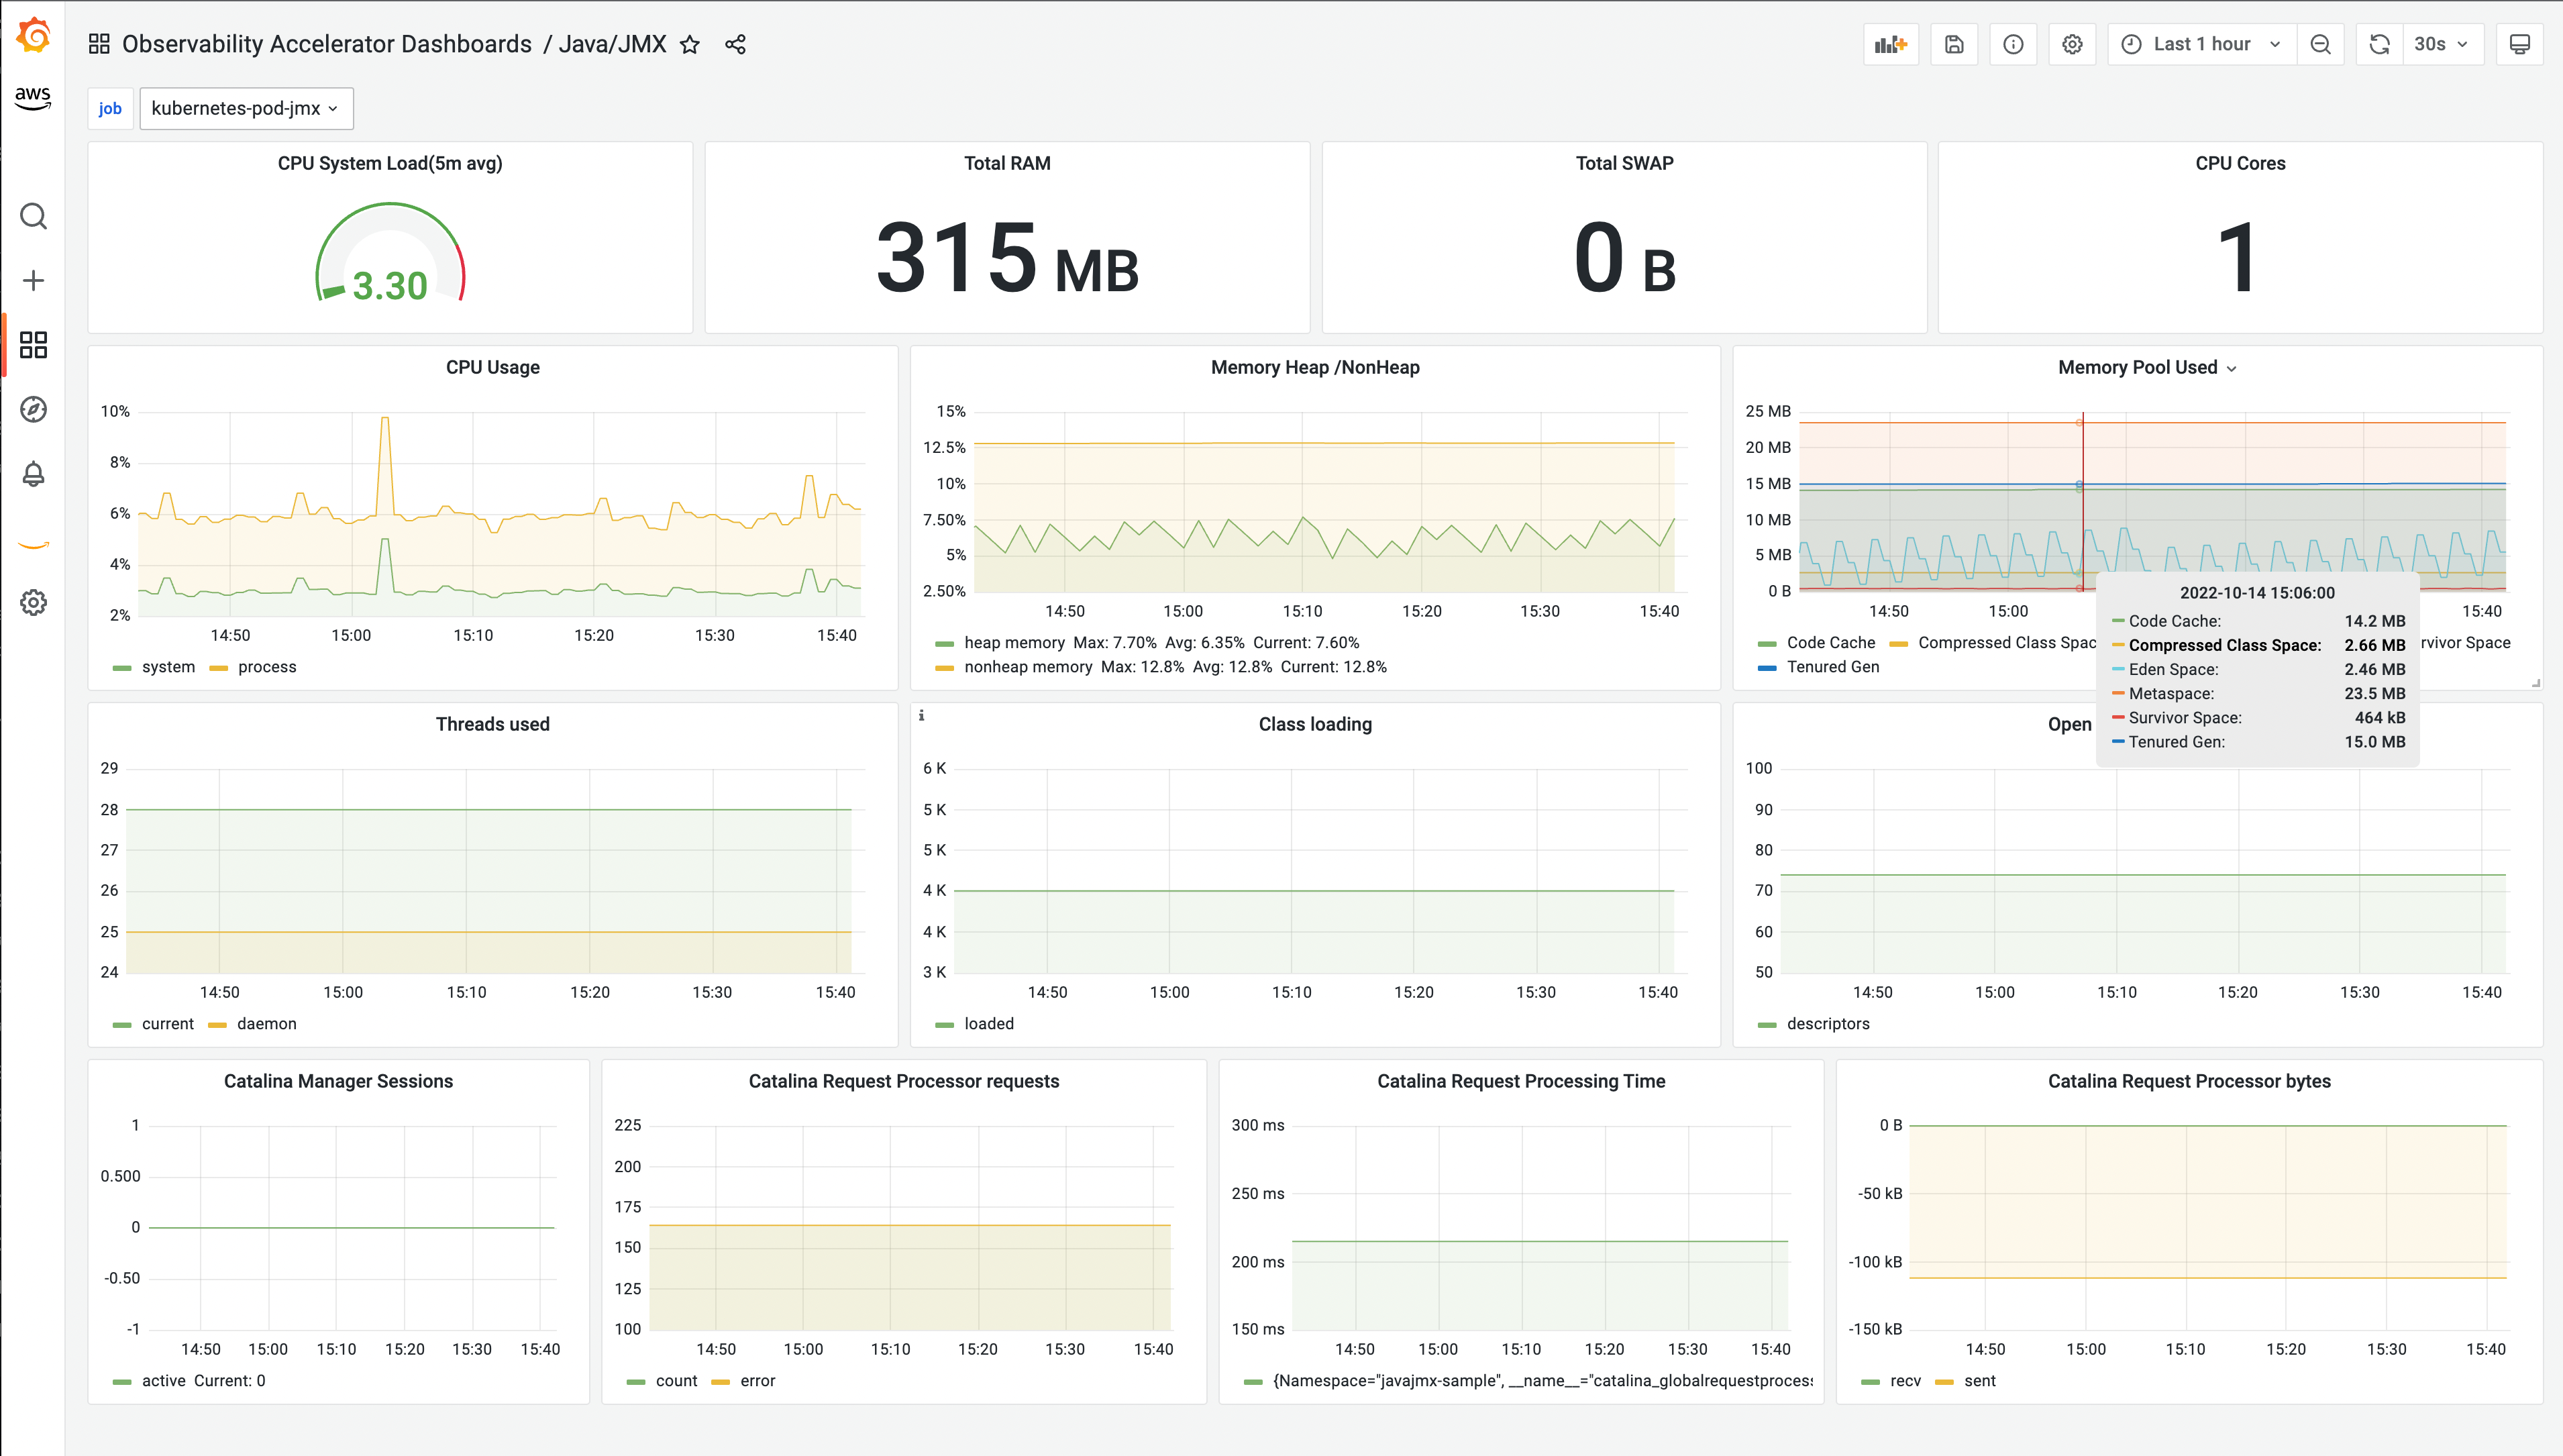
Open the "Java/JMX" dashboard to view its visualization
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
2. Amazon Managed Service for Prometheus rules and alerts
|
||||
|
||||
Open the Amazon Managed Service for Prometheus console and view the details of your workspace. Under the `Rules management` tab, you will find new rules deployed.
|
||||
|
||||
<img width="1314" alt="image" src="https://user-images.githubusercontent.com/97046295/194904104-09a28577-d149-478e-b0a1-dc21cb7effc1.png">
|
||||
|
||||
|
||||
To setup your alert receiver, with Amazon SNS, follow [this documentation](https://docs.aws.amazon.com/prometheus/latest/userguide/AMP-alertmanager-receiver.html)
|
||||
|
||||
|
||||
## Deploy an Example Java Application
|
||||
|
||||
In this section we will reuse an example from the AWS OpenTelemetry collector [repository](https://github.com/aws-observability/aws-otel-collector/blob/main/docs/developers/container-insights-eks-jmx.md). For convenience, the steps can be found below.
|
||||
|
||||
1. Clone [this repository](https://github.com/aws-observability/aws-otel-test-framework) and navigate to the `sample-apps/jmx/` directory.
|
||||
|
||||
2. Authenticate to Amazon ECR
|
||||
|
||||
```sh
|
||||
export AWS_ACCOUNT_ID=`aws sts get-caller-identity --query Account --output text`
|
||||
export AWS_REGION={region}
|
||||
aws ecr get-login-password --region $AWS_REGION | docker login --username AWS --password-stdin $AWS_ACCOUNT_ID.dkr.ecr.$AWS_REGION.amazonaws.com
|
||||
```
|
||||
|
||||
3. Create an Amazon ECR repository
|
||||
|
||||
```sh
|
||||
aws ecr create-repository --repository-name prometheus-sample-tomcat-jmx \
|
||||
--image-scanning-configuration scanOnPush=true \
|
||||
--region $AWS_REGION
|
||||
```
|
||||
|
||||
4. Build Docker image and push to ECR.
|
||||
|
||||
```sh
|
||||
docker build -t $AWS_ACCOUNT_ID.dkr.ecr.$AWS_REGION.amazonaws.com/prometheus-sample-tomcat-jmx:latest .
|
||||
docker push $AWS_ACCOUNT_ID.dkr.ecr.$AWS_REGION.amazonaws.com/prometheus-sample-tomcat-jmx:latest
|
||||
```
|
||||
|
||||
5. Install sample application
|
||||
|
||||
```sh
|
||||
export SAMPLE_TRAFFIC_NAMESPACE=javajmx-sample
|
||||
curl https://raw.githubusercontent.com/aws-observability/aws-otel-test-framework/terraform/sample-apps/jmx/examples/prometheus-metrics-sample.yaml > metrics-sample.yaml
|
||||
sed -i "s/{{aws_account_id}}/$AWS_ACCOUNT_ID/g" metrics-sample.yaml
|
||||
sed -i "s/{{region}}/$AWS_REGION/g" metrics-sample.yaml
|
||||
sed -i "s/{{namespace}}/$SAMPLE_TRAFFIC_NAMESPACE/g" metrics-sample.yaml
|
||||
kubectl apply -f metrics-sample.yaml
|
||||
```
|
||||
|
||||
Verify that the sample application is running:
|
||||
|
||||
```sh
|
||||
kubectl get pods -n $SAMPLE_TRAFFIC_NAMESPACE
|
||||
|
||||
NAME READY STATUS RESTARTS AGE
|
||||
tomcat-bad-traffic-generator 1/1 Running 0 11s
|
||||
tomcat-example-7958666589-2q755 0/1 ContainerCreating 0 11s
|
||||
tomcat-traffic-generator 1/1 Running 0 11s
|
||||
```
|
||||
|
||||
## Destroy resources
|
||||
|
||||
If you leave this stack running, you will continue to incur charges. To remove all resources
|
||||
created by Terraform, [refresh your Grafana API key](#6-grafana-api-key) and run the command below.
|
||||
|
||||
Be careful, this command will removing everything created by Terraform. If you wish
|
||||
to keep your Amazon Managed Grafana or Amazon Managed Service for Prometheus workspaces. Remove them
|
||||
from your terraform state before running the destroy command.
|
||||
|
||||
```bash
|
||||
terraform destroy
|
||||
```
|
||||
|
||||
To remove resources from your Terraform state, run
|
||||
|
||||
```bash
|
||||
# grafana workspace
|
||||
terraform state rm "module.eks_observability_accelerator.module.managed_grafana[0].aws_grafana_workspace.this[0]"
|
||||
|
||||
# prometheus workspace
|
||||
terraform state rm "module.eks_observability_accelerator.aws_prometheus_workspace.this[0]"
|
||||
```
|
||||
@@ -0,0 +1,98 @@
|
||||
# Monitoring Amazon Managed Service for Prometheus workspaces
|
||||
|
||||
This example allows you to monitor your Amazon Managed Service for Prometheus workspaces
|
||||
using Amazon CloudWatch vended metrics and logs. It also creates configurable CloudWatch
|
||||
alarms for service usage limits. Those informations are displayed in a Managed Grafana
|
||||
workspace dashboard.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Make sure to complete the [prerequisites section](/terraform-aws-observability-accelerator/concepts/#prerequisites)
|
||||
before proceeding.
|
||||
|
||||
> This example doesn't require an Amazon EKS cluster and Kubernetes tools (ex. `kubectl`).
|
||||
|
||||
## Setup
|
||||
|
||||
|
||||
### 1. Download sources and initialize Terraform
|
||||
|
||||
```bash
|
||||
git clone https://github.com/aws-observability/terraform-aws-observability-accelerator.git
|
||||
cd examples/managed-prometheus-monitoring
|
||||
terraform init
|
||||
```
|
||||
|
||||
### 2. AWS Region
|
||||
|
||||
Specify the AWS Region where the resources will be deployed:
|
||||
|
||||
```bash
|
||||
export TF_VAR_aws_region=xxx
|
||||
```
|
||||
|
||||
### 3. Amazon Managed Service for Prometheus workspace
|
||||
|
||||
Specify one or more workspaces in the same Region separated with a comma seperated string.
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_prometheus_workspace_id="ws-xxx"
|
||||
```
|
||||
|
||||
You can use the following command to create alarms for all of the workspaces in a region.
|
||||
|
||||
```sh
|
||||
export TF_VAR_managed_prometheus_workspace_id=$(aws amp list-workspaces --query 'workspaces[].workspaceId' --output text | sed -E 's/\t/,/g')
|
||||
```
|
||||
|
||||
### 4. Amazon Managed Grafana workspace
|
||||
|
||||
To run this example you need an Amazon Managed Grafana workspace.
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_grafana_workspace_id=g-xxx
|
||||
```
|
||||
|
||||
### 5. Grafana API Key
|
||||
|
||||
Amazon Managed Grafana provides a control plane API for generating Grafana API keys.
|
||||
As a security best practice, we will provide to Terraform a short lived API key to
|
||||
run the `apply` or `destroy` command.
|
||||
|
||||
Ensure you have necessary IAM permissions (`CreateWorkspaceApiKey, DeleteWorkspaceApiKey`)
|
||||
|
||||
```bash
|
||||
export TF_VAR_grafana_api_key=`aws grafana create-workspace-api-key --key-name "observability-accelerator-$(date +%s)" --key-role ADMIN --seconds-to-live 1200 --workspace-id $TF_VAR_managed_grafana_workspace_id --query key --output text`
|
||||
```
|
||||
|
||||
## Deploy
|
||||
|
||||
Simply run this command to deploy the example
|
||||
|
||||
```sh
|
||||
terraform apply
|
||||
```
|
||||
|
||||
## Visualization
|
||||
|
||||
### 1. Cloudwatch datasource on Grafana
|
||||
|
||||
Open your Grafana workspace and under Configuration -> Data sources, you should see `aws-observability-accelerator-cloudwatch`. Open and click `Save & test`. You should see a notification confirming that the CloudWatch datasource is ready to be used on Grafana.
|
||||
|
||||
### 2. Grafana dashboards
|
||||
|
||||
Go to the Dashboards panel of your Grafana workspace. You should see a list of dashboards under the `AMP Monitoring Dashboards` folder.
|
||||
|
||||
Open the `AMP Accelerator Dashboard` to see a visualization of the AMP workspace.
|
||||
|
||||
<img width="1786" alt="Screen Shot 2022-10-11 at 2 16 17 PM" src="https://user-images.githubusercontent.com/97046295/196742772-fba1a5fb-dd38-445c-88a9-607f38994713.png">
|
||||
|
||||
### 3. Amazon Managed Service for Prometheus CloudWatch Alarms.
|
||||
|
||||
Open the CloudWatch console and click `Alarms` > `All Alarms` to review the service limit alarms.
|
||||
|
||||
<img width="1525" alt="image" src="https://user-images.githubusercontent.com/97046295/196742923-876e3b1c-6f2a-419d-ad39-9c057a0f7650.png">
|
||||
|
||||
In us-east-1 region an alarm is created for billing. This alarm utilizes anomaly detection to detect anomalies in the Estimated Charges billing metric.
|
||||
|
||||
<img width="1346" alt="image" src="https://user-images.githubusercontent.com/97046295/197042518-a98d69df-8f53-4a4a-afb8-f424d91da56f.png">
|
||||
@@ -0,0 +1,197 @@
|
||||
# Monitor Nginx applications running on Amazon EKS
|
||||
|
||||
The current example deploys the [nginx workload module](https://github.com/aws-observability/terraform-aws-observability-accelerator/tree/main/modules/workloads/nginx),
|
||||
to provide an existing EKS cluster with an OpenTelemetry collector,
|
||||
curated Grafana dashboards, Prometheus alerting and recording rules with multiple
|
||||
configuration options on the cluster infrastructure.
|
||||
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Make sure to complete the [prerequisites section](/terraform-aws-observability-accelerator/concepts/#prerequisites)
|
||||
before proceeding.
|
||||
|
||||
## Setup
|
||||
|
||||
|
||||
### 1. Download sources and initialize Terraform
|
||||
|
||||
```bash
|
||||
git clone https://github.com/aws-observability/terraform-aws-observability-accelerator.git
|
||||
cd examples/existing-cluster-nginx
|
||||
terraform init
|
||||
```
|
||||
|
||||
### 2. AWS Region
|
||||
|
||||
Specify the AWS Region where the resources will be deployed:
|
||||
|
||||
```bash
|
||||
export TF_VAR_aws_region=xxx
|
||||
```
|
||||
|
||||
### 3. Amazon EKS Cluster
|
||||
|
||||
To run this example, you need to provide your EKS cluster name. If you don't
|
||||
have a cluster ready, visit [this example](/terraform-aws-observability-accelerator/helpers/new-eks-cluster.md)
|
||||
first to create a new one.
|
||||
|
||||
Specify your cluster name:
|
||||
|
||||
```bash
|
||||
export TF_VAR_eks_cluster_id=xxx
|
||||
```
|
||||
|
||||
### 4. Amazon Managed Service for Prometheus workspace (optional)
|
||||
|
||||
By default, we create an Amazon Managed Service for Prometheus workspace for you.
|
||||
However, if you have an existing workspace you want to reuse, edit and run:
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_prometheus_workspace_id=ws-xxx
|
||||
```
|
||||
|
||||
To create a workspace outside of Terraform's state, simply run:
|
||||
|
||||
```bash
|
||||
aws amp create-workspace --alias observability-accelerator --query '.workspaceId' --output text
|
||||
```
|
||||
|
||||
### 5. Amazon Managed Grafana workspace
|
||||
|
||||
To run this example you need an Amazon Managed Grafana workspace. If you have an existing workspace, edit and run:
|
||||
|
||||
```bash
|
||||
export TF_VAR_managed_grafana_workspace_id=g-xxx
|
||||
```
|
||||
|
||||
To create a new one, within this example's Terraform state (sharing the same lifecycle with all the other resources):
|
||||
|
||||
- Edit main.tf and set `enable_managed_grafana = true`
|
||||
- Run
|
||||
|
||||
```bash
|
||||
terraform init
|
||||
terraform apply -target "module.eks_observability_accelerator.module.managed_grafana[0].aws_grafana_workspace.this[0]"
|
||||
export TF_VAR_managed_grafana_workspace_id=$(terraform output --raw managed_grafana_workspace_id)
|
||||
```
|
||||
|
||||
### 6. Grafana API Key
|
||||
|
||||
Amazon Managed Grafana provides a control plane API for generating Grafana API keys.
|
||||
As a security best practice, we will provide to Terraform a short lived API key to
|
||||
run the `apply` or `destroy` command.
|
||||
|
||||
Ensure you have necessary IAM permissions (`CreateWorkspaceApiKey, DeleteWorkspaceApiKey`)
|
||||
|
||||
```bash
|
||||
export TF_VAR_grafana_api_key=`aws grafana create-workspace-api-key --key-name "observability-accelerator-$(date +%s)" --key-role ADMIN --seconds-to-live 1200 --workspace-id $TF_VAR_managed_grafana_workspace_id --query key --output text`
|
||||
```
|
||||
|
||||
## Deploy
|
||||
|
||||
Simply run this command to deploy.
|
||||
|
||||
```bash
|
||||
terraform apply
|
||||
```
|
||||
|
||||
## Visualization
|
||||
|
||||
### 1. Prometheus datasource on Grafana
|
||||
|
||||
Open your Grafana workspace and under Configuration -> Data sources, you will see `aws-observability-accelerator`. Open and click `Save & test`. You will see a notification confirming that the Amazon Managed Service for Prometheus workspace is ready to be used on Grafana.
|
||||
|
||||
### 2. Grafana dashboards
|
||||
|
||||
Go to the Dashboards panel of your Grafana workspace. You will see a list of dashboards under the `Observability Accelerator Dashboards`
|
||||
|
||||
<img width="1208" alt="image" src="https://user-images.githubusercontent.com/97046295/190665211-60faef71-d83d-4d59-ac80-bf4309d8c082.png">
|
||||
|
||||
Open the NGINX dashboard and you will be able to view its visualization
|
||||
|
||||
<img width="1850" alt="image" src="https://user-images.githubusercontent.com/97046295/196226043-e49afeb9-7828-467f-9199-5707cdc69aa9.png">
|
||||
|
||||
### 3. Amazon Managed Service for Prometheus rules and alerts
|
||||
|
||||
Open the Amazon Managed Service for Prometheus console and view the details of your workspace. Under the `Rules management` tab, you will find new rules deployed.
|
||||
|
||||
<img width="1054" alt="image" src="https://user-images.githubusercontent.com/97046295/190665728-ae8bb709-ad93-4629-b845-85c158dd1925.png">
|
||||
|
||||
|
||||
To setup your alert receiver, with Amazon SNS, follow [this documentation](https://docs.aws.amazon.com/prometheus/latest/userguide/AMP-alertmanager-receiver.html)
|
||||
|
||||
## Deploy an Example Application to Visualize
|
||||
|
||||
In this section we will deploy sample application and extract metrics using AWS OpenTelemetry collector
|
||||
|
||||
### 1. Add the helm incubator repo:
|
||||
|
||||
```sh
|
||||
helm repo add ingress-nginx https://kubernetes.github.io/ingress-nginx
|
||||
```
|
||||
|
||||
### 2. Enter the following command to create a new namespace:
|
||||
|
||||
```sh
|
||||
kubectl create namespace nginx-ingress-sample
|
||||
```
|
||||
|
||||
### 3. Enter the following commands to install NGINX:
|
||||
|
||||
```sh
|
||||
helm install my-nginx ingress-nginx/ingress-nginx \
|
||||
--namespace nginx-ingress-sample \
|
||||
--set controller.metrics.enabled=true \
|
||||
--set-string controller.metrics.service.annotations."prometheus\.io/port"="10254" \
|
||||
--set-string controller.metrics.service.annotations."prometheus\.io/scrape"="true"
|
||||
```
|
||||
|
||||
### 4. Set an EXTERNAL-IP variable to the value of the EXTERNAL-IP column in the row of the NGINX ingress controller.
|
||||
|
||||
```sh
|
||||
EXTERNAL_IP=your-nginx-controller-external-ip
|
||||
```
|
||||
|
||||
### 5. Start some sample NGINX traffic by entering the following command.
|
||||
|
||||
```sh
|
||||
SAMPLE_TRAFFIC_NAMESPACE=nginx-sample-traffic
|
||||
curl https://raw.githubusercontent.com/aws-samples/amazon-cloudwatch-container-insights/master/k8s-deployment-manifest-templates/deployment-mode/service/cwagent-prometheus/sample_traffic/nginx-traffic/nginx-traffic-sample.yaml |
|
||||
sed "s/{{external_ip}}/$EXTERNAL_IP/g" |
|
||||
sed "s/{{namespace}}/$SAMPLE_TRAFFIC_NAMESPACE/g" |
|
||||
kubectl apply -f -
|
||||
```
|
||||
|
||||
### 6. Verify if the application is running
|
||||
|
||||
```sh
|
||||
kubectl get pods -n nginx-ingress-sample
|
||||
```
|
||||
|
||||
### 7. Visualize the Application's dashboard
|
||||
|
||||
Log back into your Managed Grafana Workspace and navigate to the dashboard side panel, click on `Observability Accelerator Dashboards` Folder and open the `NGINX` Dashboard.
|
||||
|
||||
## Destroy resources
|
||||
|
||||
If you leave this stack running, you will continue to incur charges. To remove all resources
|
||||
created by Terraform, [refresh your Grafana API key](#6-grafana-api-key) and run the command below.
|
||||
|
||||
Be careful, this command will removing everything created by Terraform. If you wish
|
||||
to keep your Amazon Managed Grafana or Amazon Managed Service for Prometheus workspaces. Remove them
|
||||
from your terraform state before running the destroy command.
|
||||
|
||||
```bash
|
||||
terraform destroy
|
||||
```
|
||||
|
||||
To remove resources from your Terraform state, run
|
||||
|
||||
```bash
|
||||
# grafana workspace
|
||||
terraform state rm "module.eks_observability_accelerator.module.managed_grafana[0].aws_grafana_workspace.this[0]"
|
||||
|
||||
# prometheus workspace
|
||||
terraform state rm "module.eks_observability_accelerator.aws_prometheus_workspace.this[0]"
|
||||
```
|
||||
Reference in New Issue
Block a user