mirror of
https://github.com/storytold/terraform-aws-observability-accelerator.git
synced 2026-10-09 00:09:43 +00:00
chore: Cleanup docs assets (#227)
* Update eks.md

Move image assets to upstream repo

* Update index.md

Move assets to upstream

* Update eks-apiserver.md

Move assets to upstream
Fix terminology
This commit is contained in:
 Rodrigue Koffi
@@ -7,7 +7,8 @@ The OpenTelemetry collector produces metrics to monitor the entire pipeline. In
|
|||||||
|
|
||||||
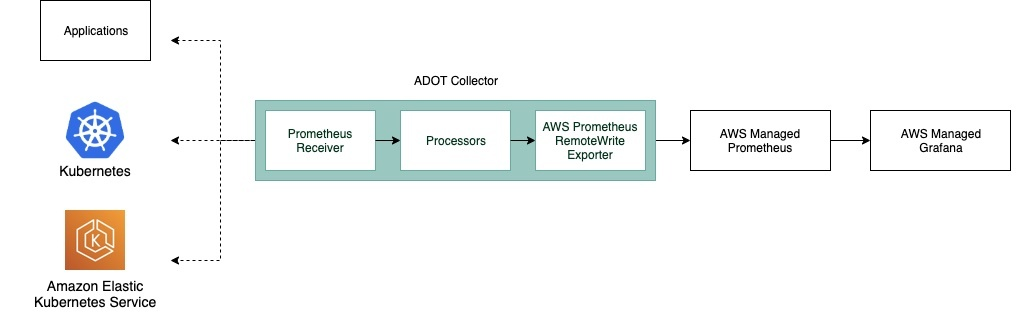
Below diagram shows an example data flow and the components in an ADOT collector:
|
Below diagram shows an example data flow and the components in an ADOT collector:
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
|
|
||||||
In this dashboard, there are five sections. Each section has [metrics](https://aws-observability.github.io/observability-best-practices/guides/operational/adot-at-scale/operating-adot-collector/#collecting-health-metrics-from-the-collector) relevant to the various [components](https://opentelemetry.io/docs/demo/collector-data-flow-dashboard/#data-flow-overview) of the AWS Distro for OpenTelemetry (ADOT) collector :
|
||||||
|
|
||||||
@@ -17,22 +18,24 @@ Shows the receiver’s accepted and refused rate/count of spans and metric point
|
|||||||
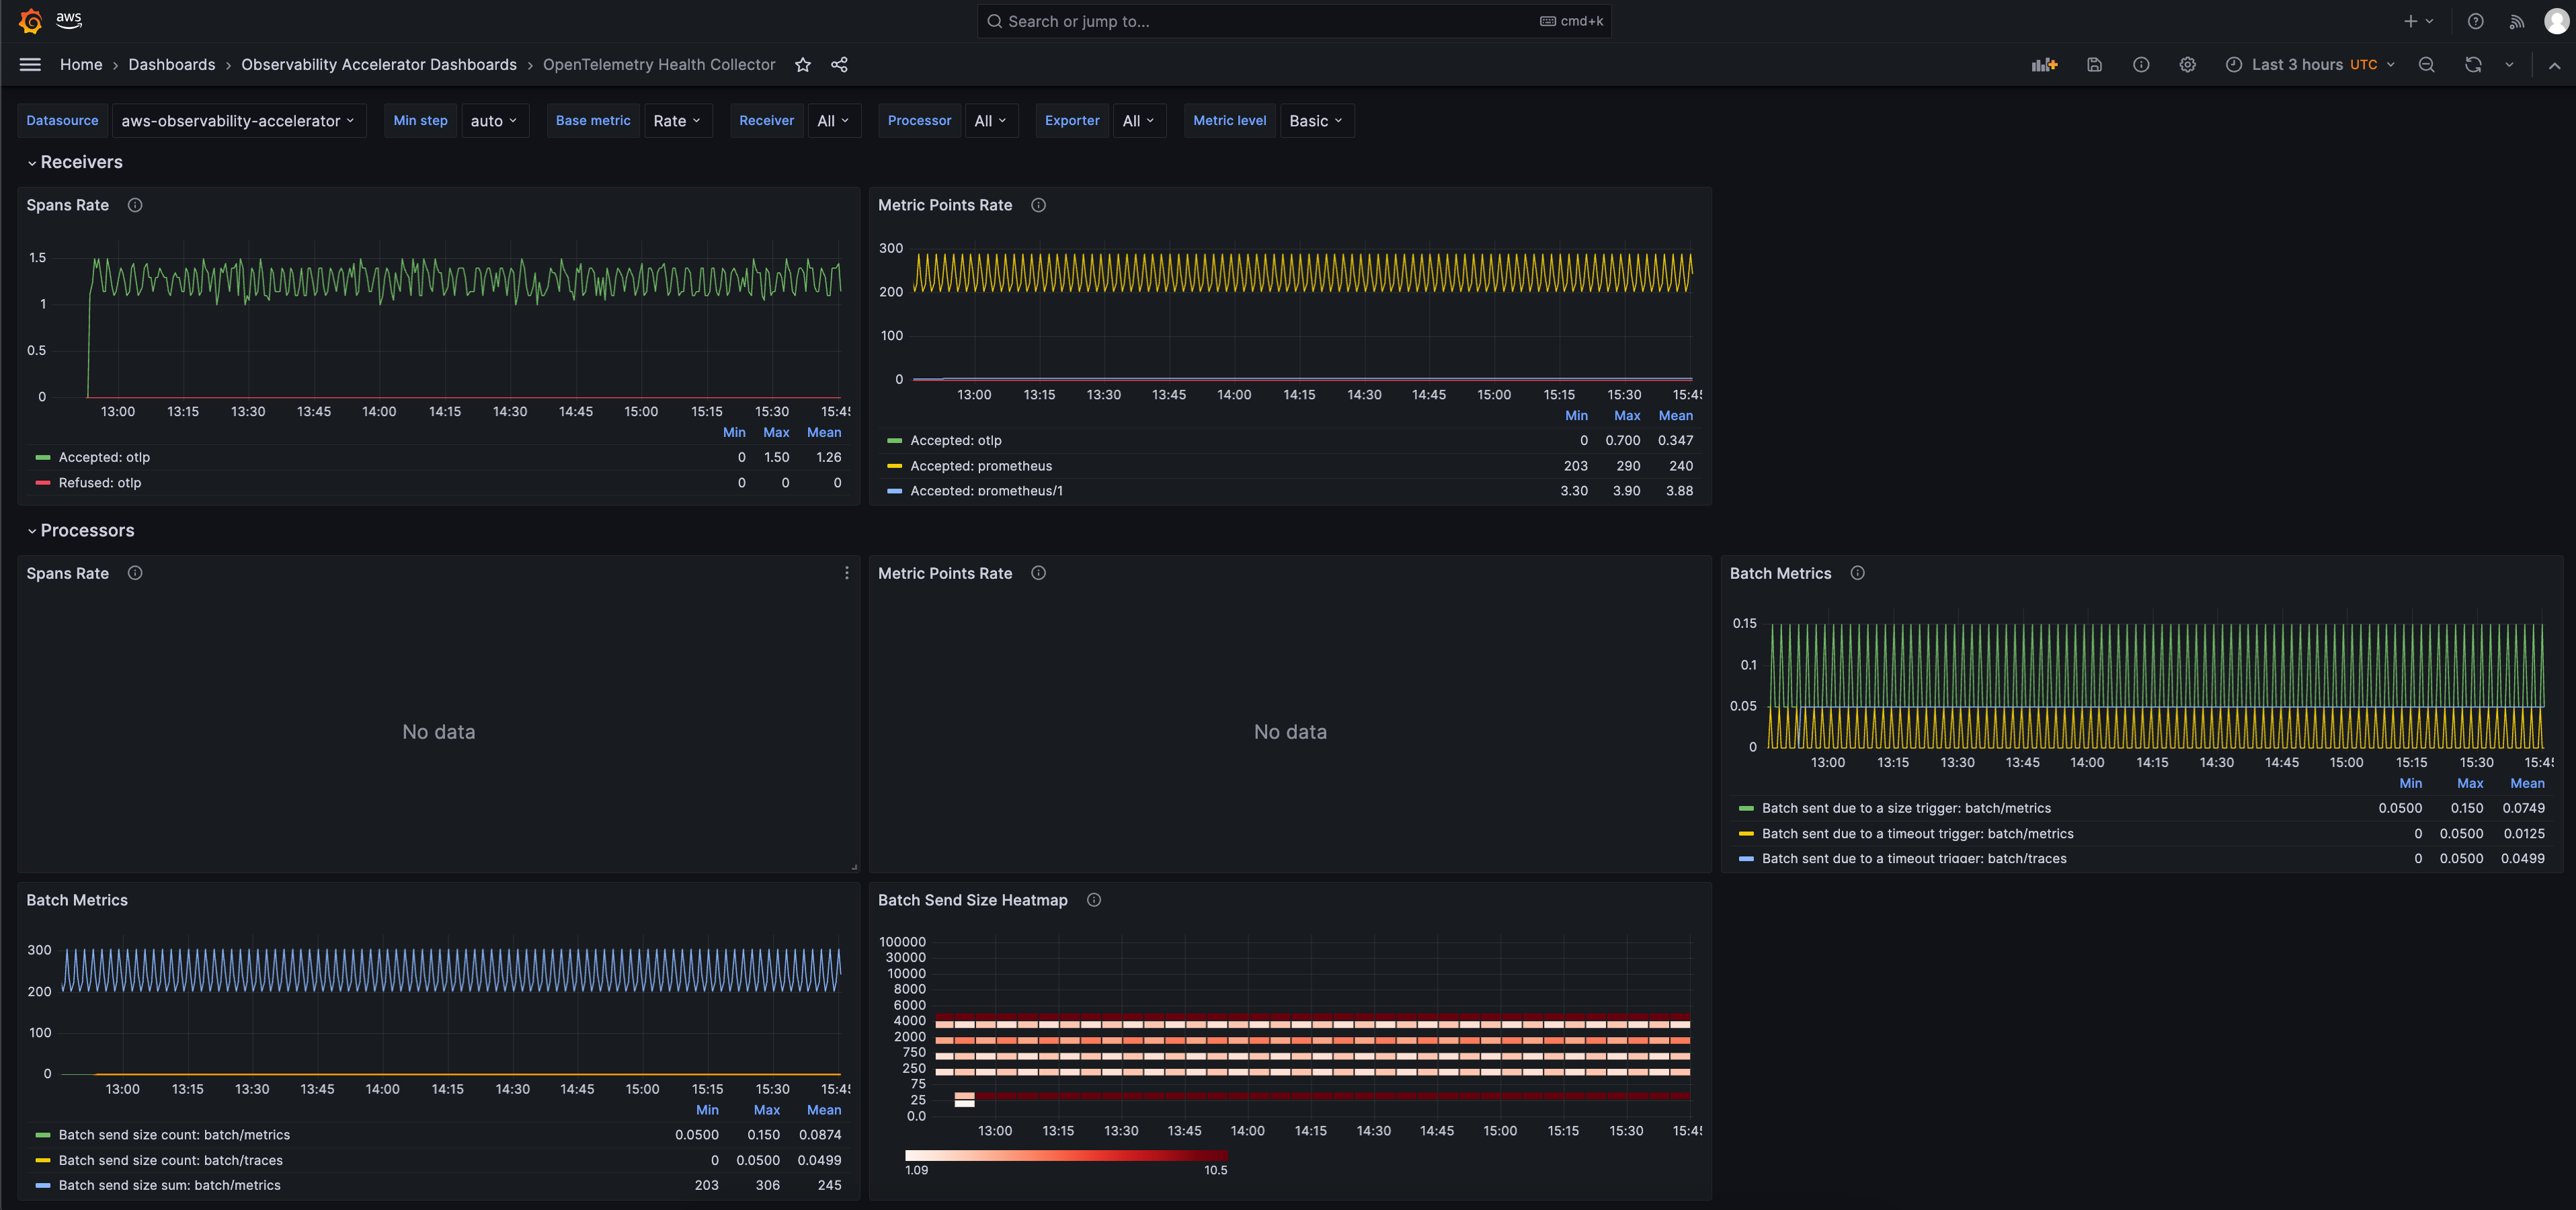
### Processors
|
### Processors
|
||||||
Shows the accepted and refused rate/count of spans and metric points pushed into next component in the pipeline. The batch metrics can help to understand how often metrics are sent to exporter and the batch size.
|
Shows the accepted and refused rate/count of spans and metric points pushed into next component in the pipeline. The batch metrics can help to understand how often metrics are sent to exporter and the batch size.
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
|
|
||||||
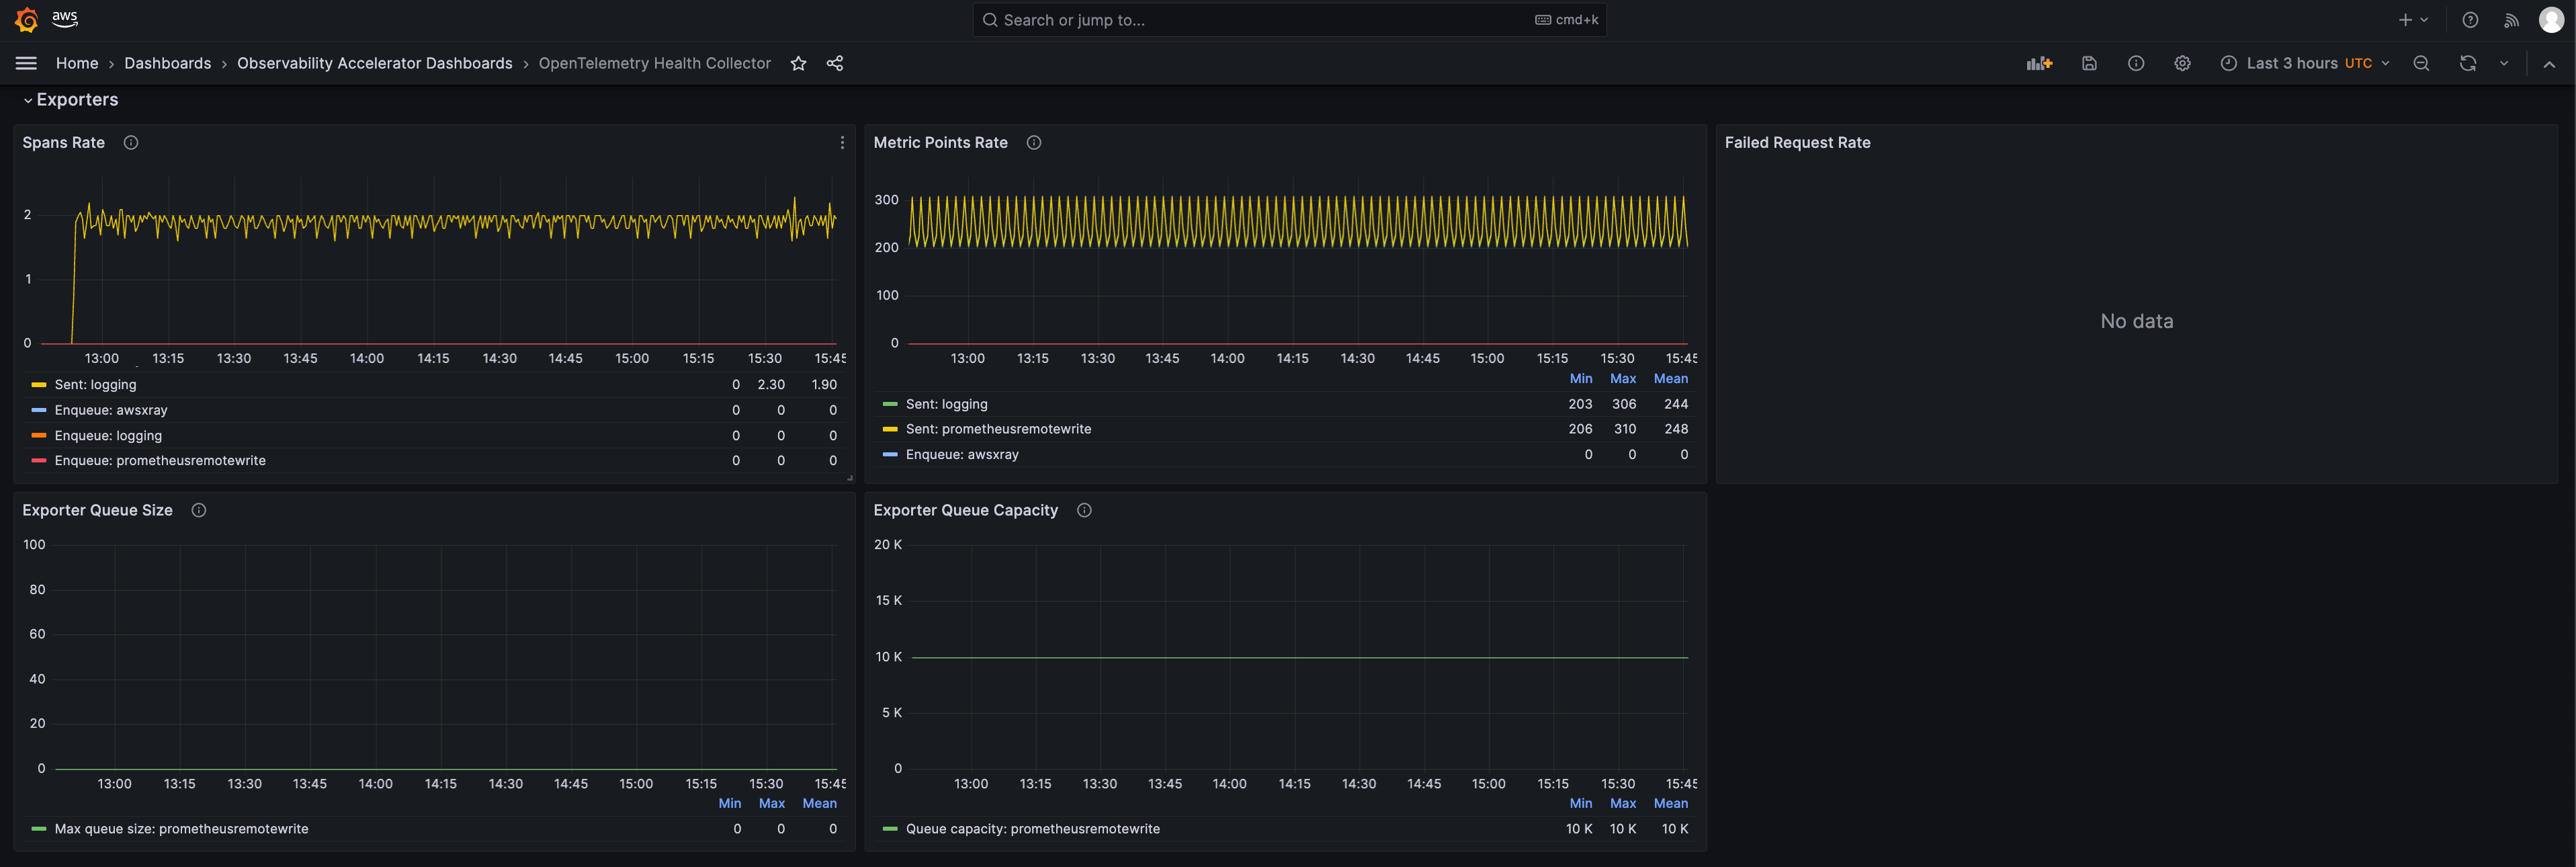
### Exporters
|
### Exporters
|
||||||
Shows the exporter’s accepted and refused rate/count of spans and metric points that are pushed to any of the destinations. It also shows the size and capacity of the retry queue. These metrics can be used to understand if the collector is having issues in sending trace or metric data to the destination configured.
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
|
|
||||||
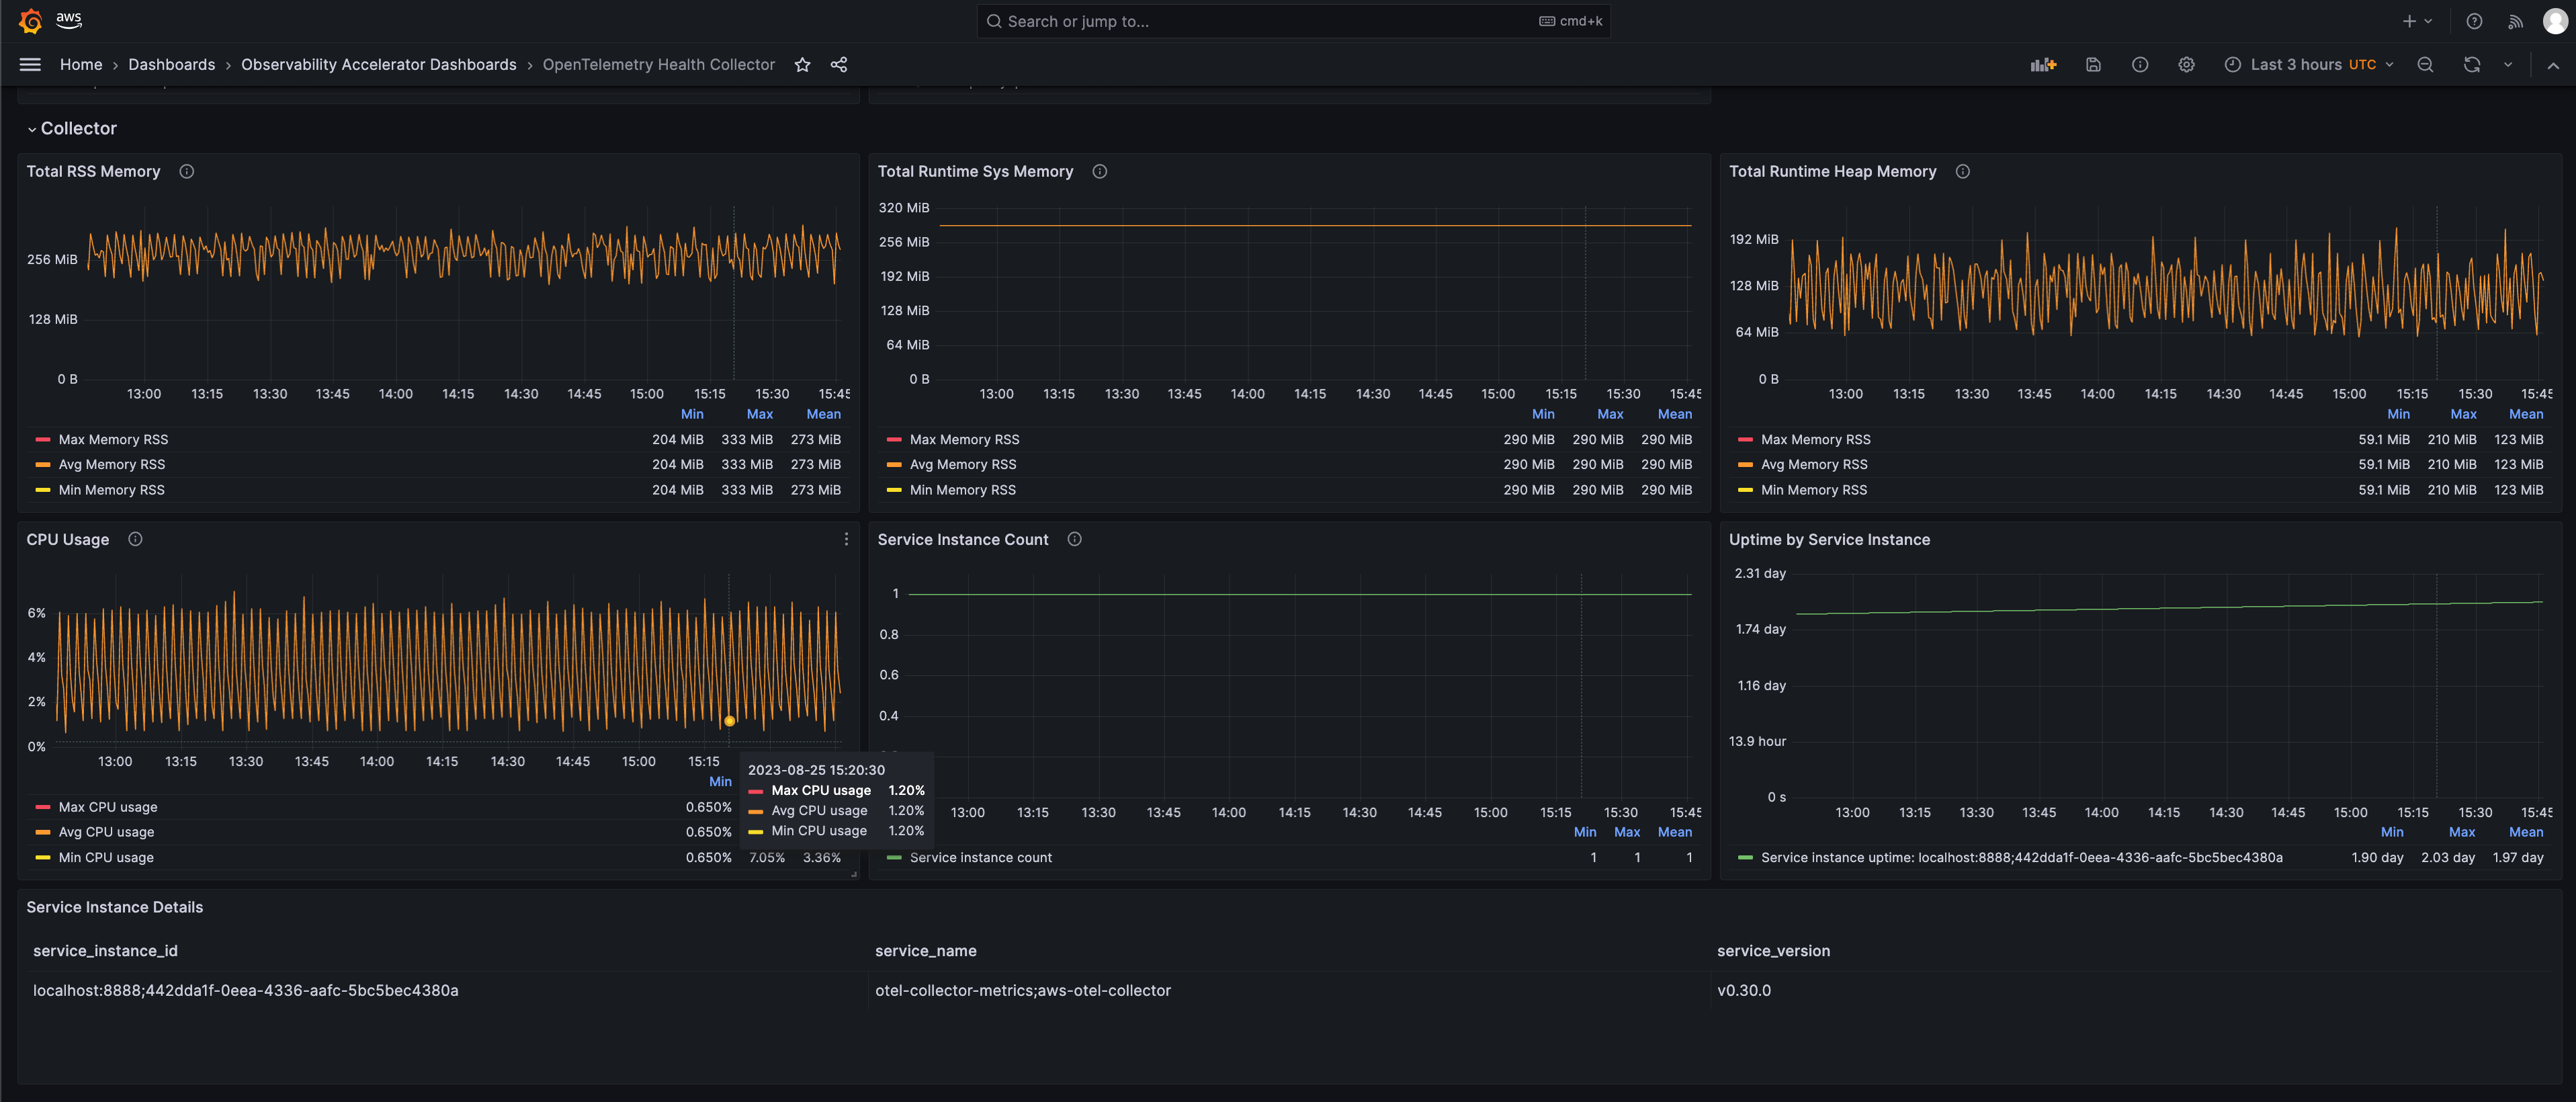
### Collectors
|
### Collectors
|
||||||
Shows the collector’s operational metrics (Memory, CPU, uptime). This can be used to understand how much resources the collector is consuming.
|
Shows the collector’s operational metrics (Memory, CPU, uptime). This can be used to understand how much resources the collector is consuming.
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
### Data Flow
|
### Data Flow
|
||||||
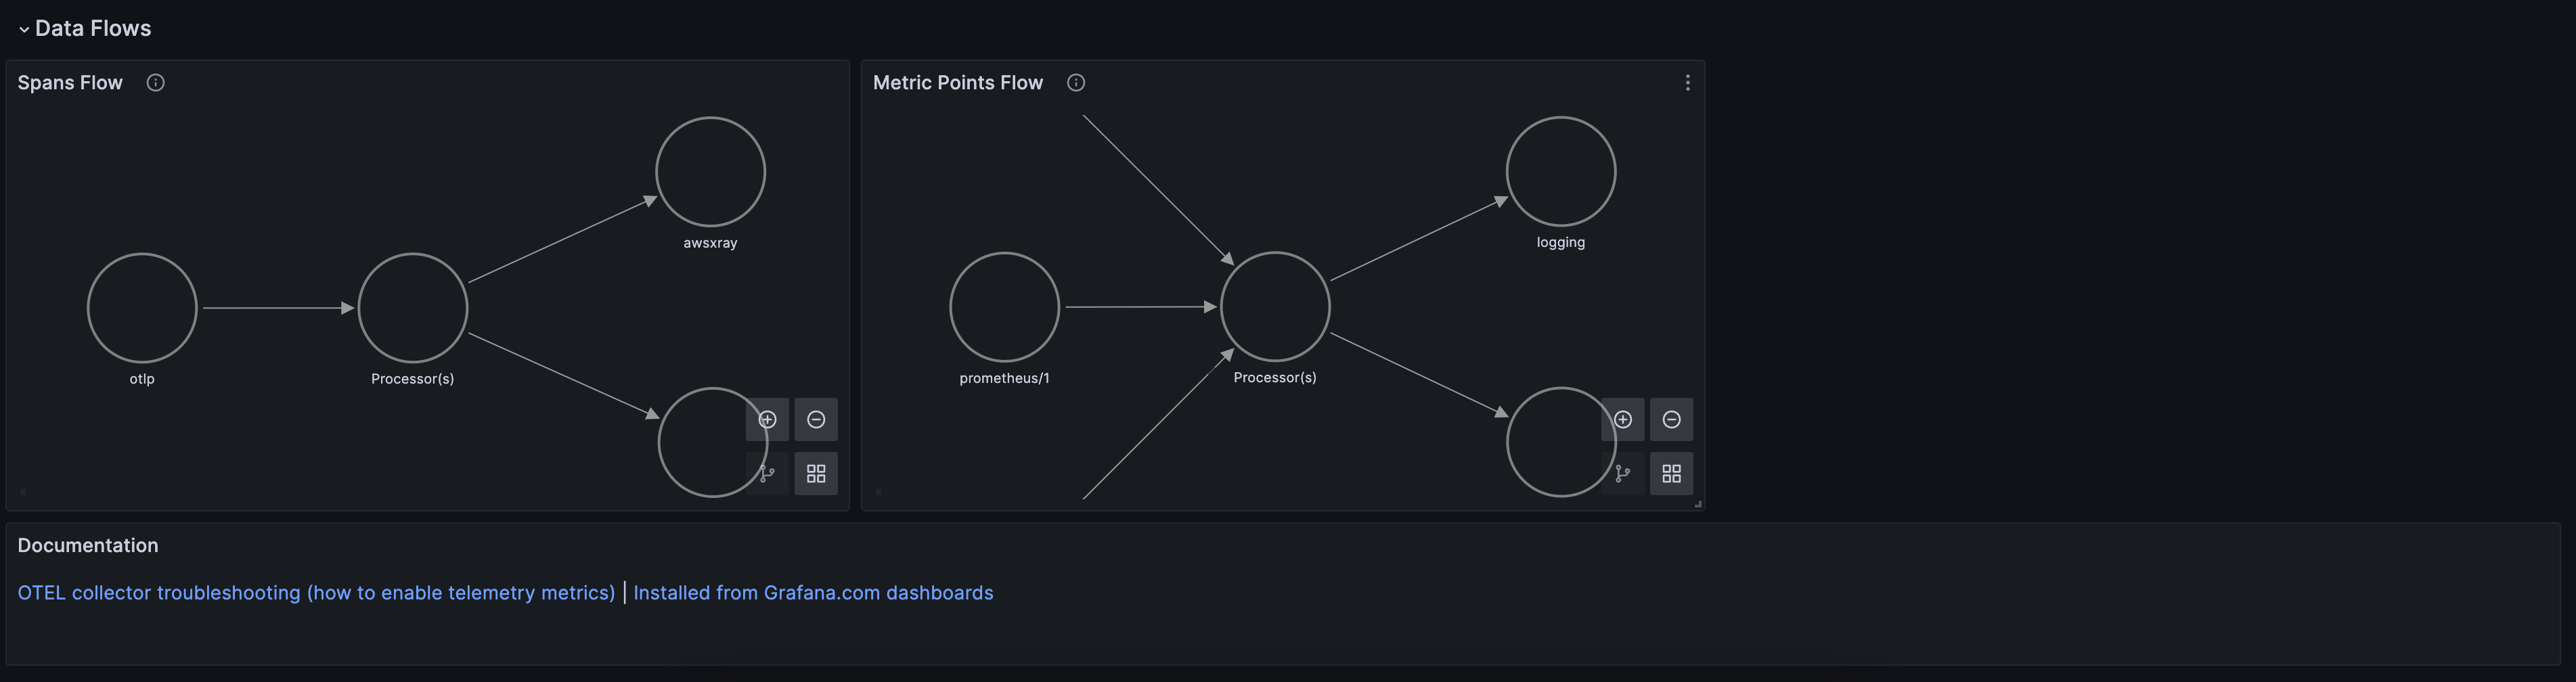
Shows the metrics and spans data flow through the collector’s components.
|
Shows the metrics and spans data flow through the collector’s components.
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
!!!note
|
!!!note
|
||||||
To read more about the metrics and the dashboard used, visit the upstream documentation [here](https://opentelemetry.io/docs/demo/collector-data-flow-dashboard/).
|
To read more about the metrics and the dashboard used, visit the upstream documentation [here](https://opentelemetry.io/docs/demo/collector-data-flow-dashboard/).
|
||||||
|
|||||||
@@ -46,8 +46,7 @@ terraform apply
|
|||||||
|
|
||||||
After apply, open your Amazon CloudWatch console in the same region as your EKS cluster, then from the left hand side choose `Insights -> Container Insights`, there choose the `Performance montoring` from the drop down, choose the `cluster name` and you will see the metrics shown on the dashboard:
|
||||||
|
|
||||||
|

|
||||||
<img width="1423" alt="Screenshot 2023-08-08 at 1.15.14 PM" src="https://github.com/RJrocks/terraform-aws-observability-accelerator/assets/5756583/4c5e4ed3-2e1f-4d41-b568-01976fbfd303">
|
|
||||||
|
|
||||||
|
|
||||||
## Cleanup
|
## Cleanup
|
||||||
|
|||||||
@@ -1,23 +1,25 @@
|
|||||||
# Monitoring EKS API server
|
# Monitoring Amazon EKS API server
|
||||||
|
|
||||||
AWS Distro of OpenTelemetry enables EKS API server monitoring by default and provides three Grafana dashboards:
|
AWS Distro for OpenTelemetry (ADOT) enables Amazon EKS API server monitoring by default and provides three Grafana dashboards:
|
||||||
|
|
||||||
## Kube-apiserver (basic)
|
## Kube-apiserver (basic)
|
||||||
|
|
||||||
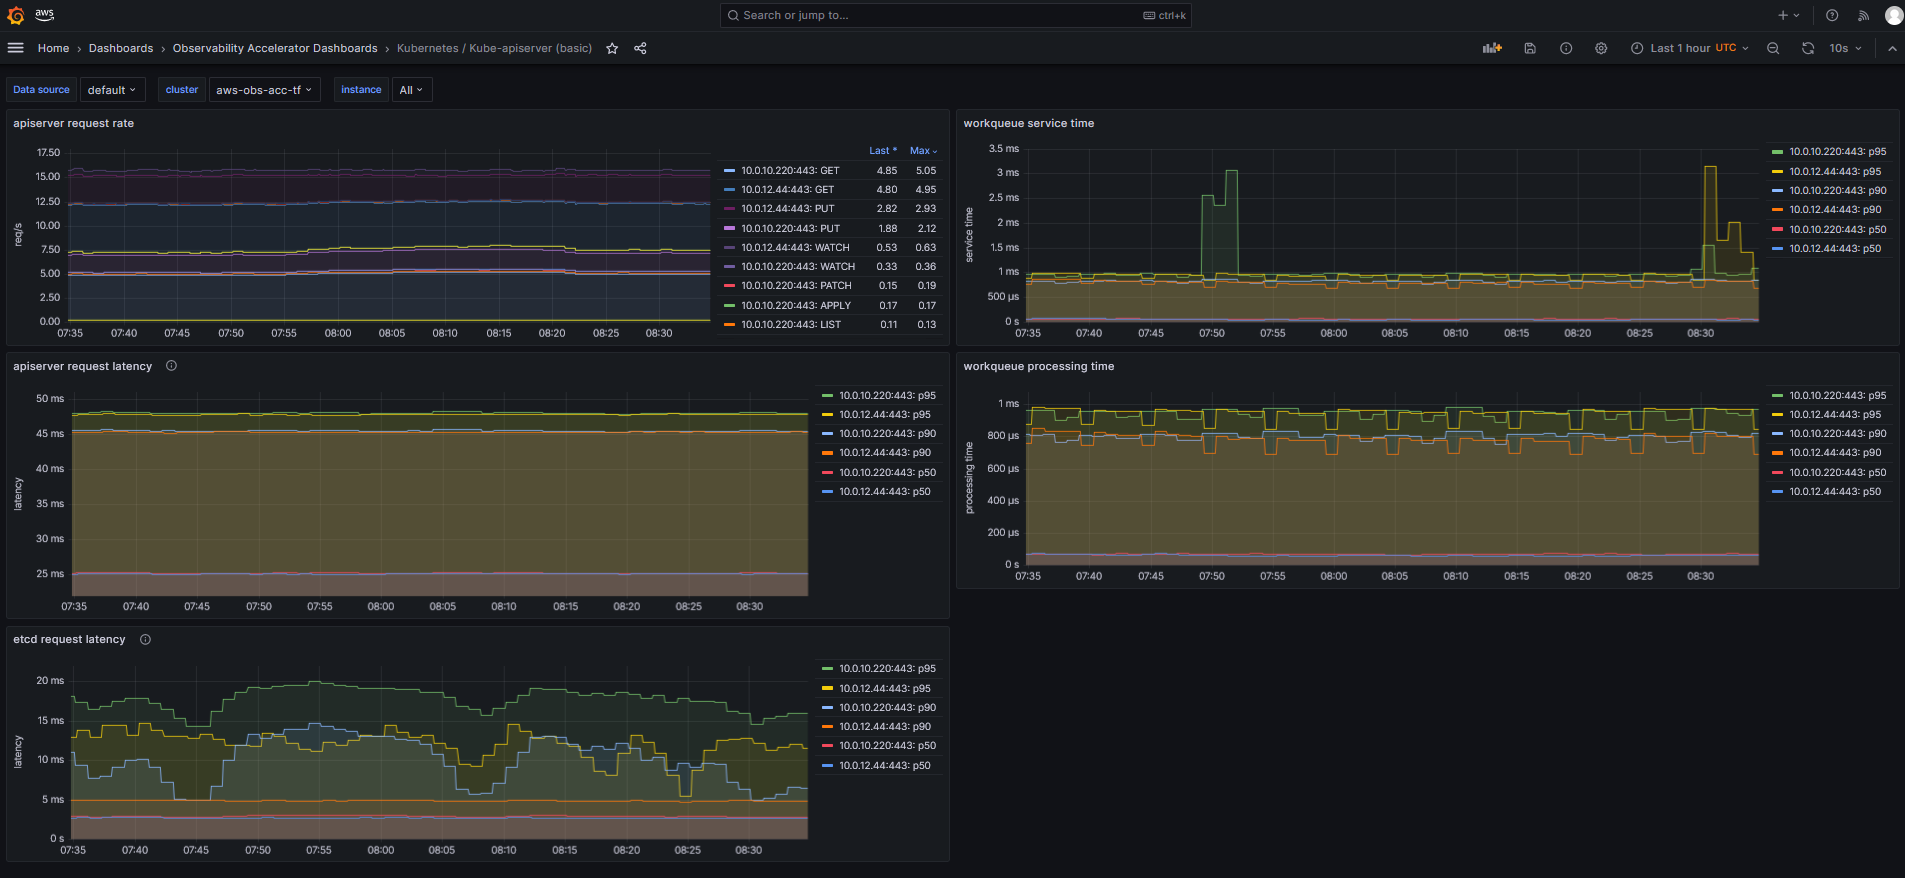
The basic dashboard shows metrics recommended in [EKS Best Practices Guides - Monitor Control Plane Metrics](https://aws.github.io/aws-eks-best-practices/reliability/docs/controlplane/#monitor-control-plane-metrics) and provides request rate and latency for API server, latency for ETCD server and overall workqueue sercice time and latency. It allows a drill-down per API server.
|
The basic dashboard shows metrics recommended in [EKS Best Practices Guides - Monitor Control Plane Metrics](https://aws.github.io/aws-eks-best-practices/reliability/docs/controlplane/#monitor-control-plane-metrics) and provides request rate and latency for API server, latency for ETCD server and overall workqueue service time and latency. It allows a drill-down per API server.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
## Kube-apiserver (advanced)
|
## Kube-apiserver (advanced)
|
||||||
|
|
||||||
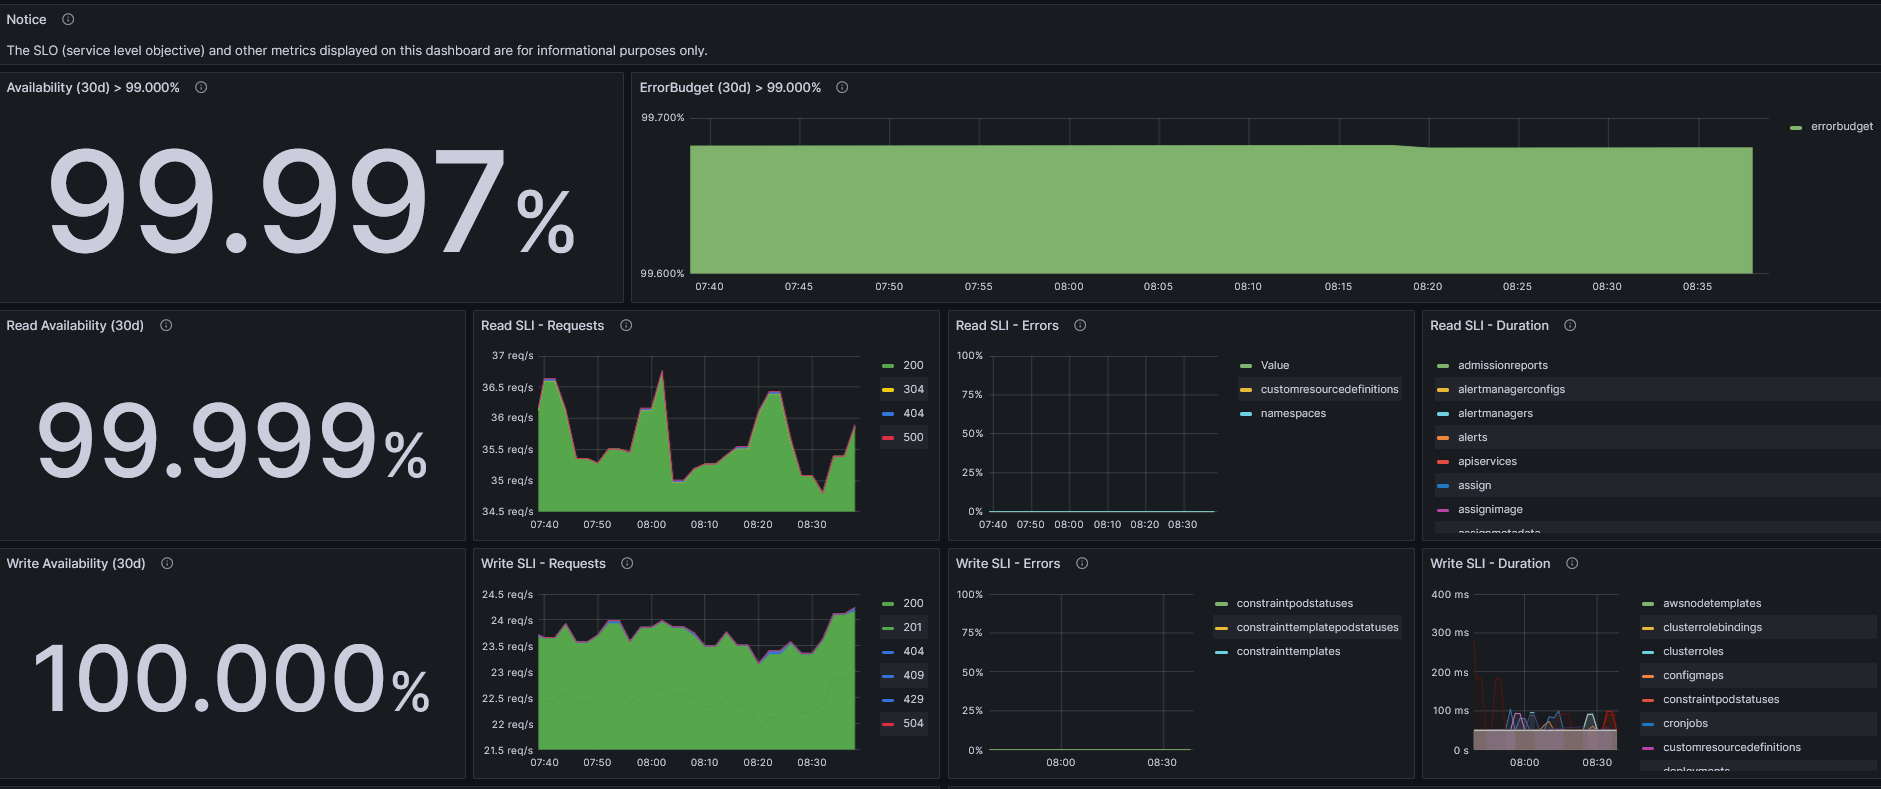
The advanced dashboard is derived from kube-prometheus-stack "Kubernetes / API server" dashboard and provides a detailed metrics drill-down for example per READ and WRITE operations per component (like deployments, configmaps etc.).
|
The advanced dashboard is derived from kube-prometheus-stack `Kubernetes / API server` dashboard and provides a detailed metrics drill-down for example per READ and WRITE operations per component (like deployments, configmaps etc.).
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||

|
|
||||||
|
|
||||||
## Kube-apiserver (troubleshooting)
|
## Kube-apiserver (troubleshooting)
|
||||||
|
|
||||||
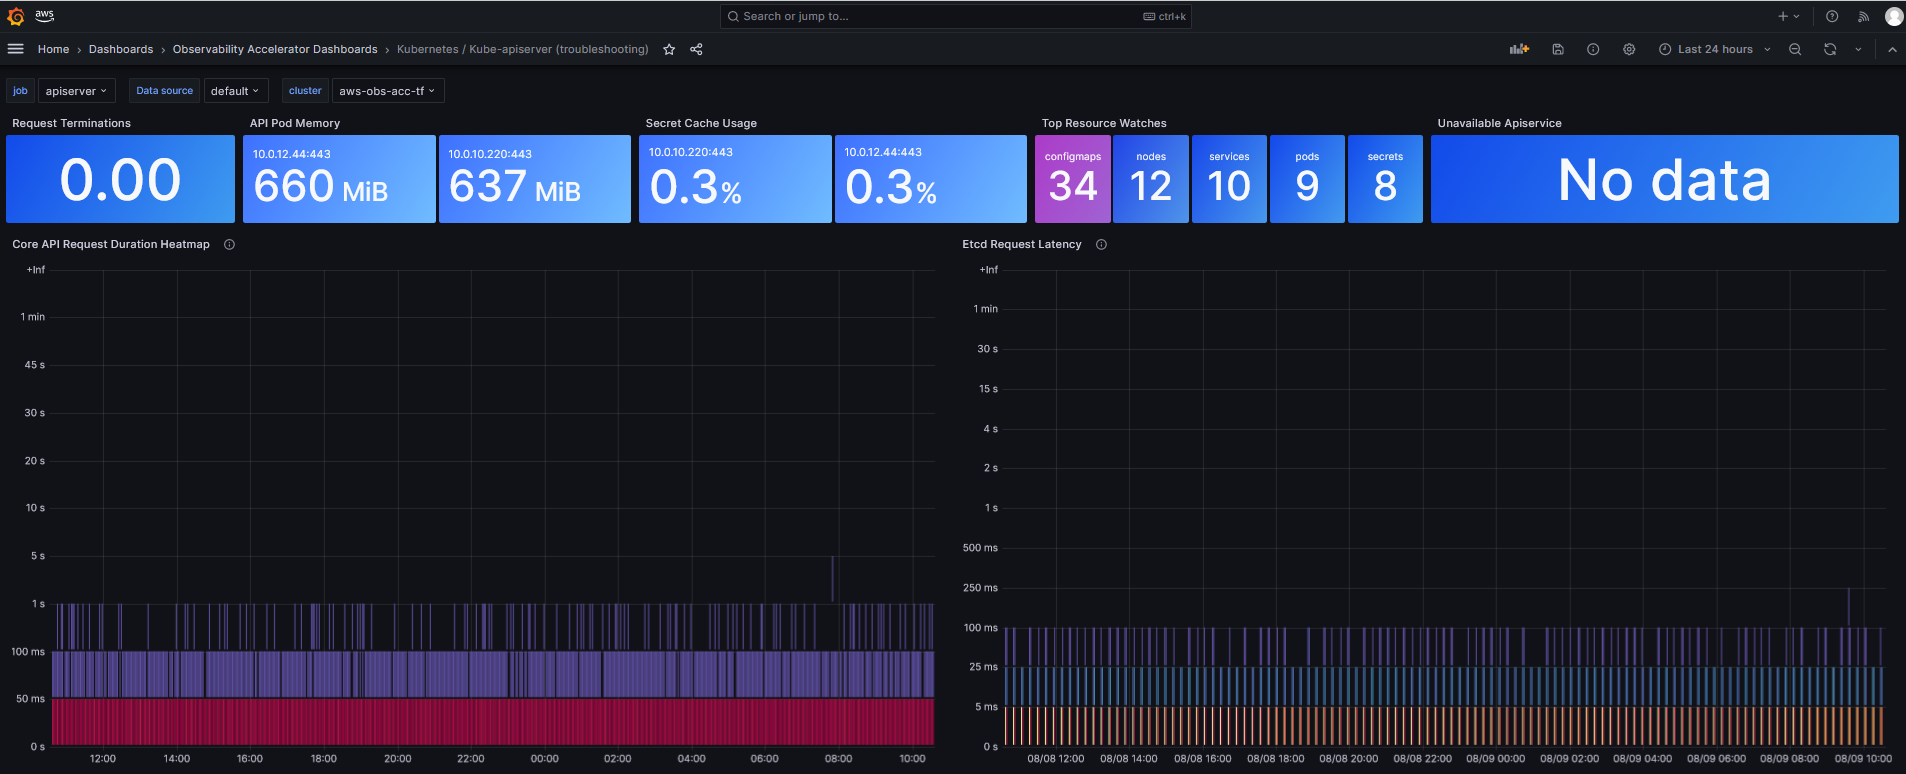
This dashboards can be used to troubleshoot API server problems like latency, errors etc.
|
This dashboard can be used to troubleshoot API server problems like latency, errors etc.
|
||||||
|
|
||||||
A detailed description for usage and background information regarding the dashboard can be found in AWS Containers blog post [Troubleshooting Amazon EKS API servers with Prometheus](https://aws.amazon.com/blogs/containers/troubleshooting-amazon-eks-api-servers-with-prometheus/).
|
A detailed description for usage and background information regarding the dashboard can be found in AWS Containers blog post [Troubleshooting Amazon EKS API servers with Prometheus](https://aws.amazon.com/blogs/containers/troubleshooting-amazon-eks-api-servers-with-prometheus/).
|
||||||
|
|
||||||

|
|
||||||
|
|||||||
Reference in New Issue
Block a user