mirror of
https://github.com/storytold/storyteller-ml.git
synced 2026-10-18 00:33:15 +00:00
update to so-vits-svc-fork repo 81551ce9c6fb7924d184c3c5a4cf9035168b28d2, add Dockerfile, reduce memory usage, remove unnecessary deps, use dio instead of parselmouth or crepe
This commit is contained in:
 Paul Sajna
@@ -1,164 +0,0 @@
|
||||
# Vim
|
||||
*~
|
||||
|
||||
# Model files
|
||||
checkpoint_best_legacy_500.pt
|
||||
logs/44k/
|
||||
|
||||
# Virtual environments
|
||||
python/
|
||||
|
||||
##### BELOW WAS ORIGINAL GITIGNORE #####
|
||||
#
|
||||
# Created by https://www.toptal.com/developers/gitignore/api/python
|
||||
# Edit at https://www.toptal.com/developers/gitignore?templates=python
|
||||
|
||||
### Python ###
|
||||
# Byte-compiled / optimized / DLL files
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
|
||||
# C extensions
|
||||
*.so
|
||||
|
||||
# Distribution / packaging
|
||||
.Python
|
||||
build/
|
||||
develop-eggs/
|
||||
dist/
|
||||
downloads/
|
||||
eggs/
|
||||
.eggs/
|
||||
lib/
|
||||
lib64/
|
||||
parts/
|
||||
sdist/
|
||||
var/
|
||||
wheels/
|
||||
pip-wheel-metadata/
|
||||
share/python-wheels/
|
||||
*.egg-info/
|
||||
.installed.cfg
|
||||
*.egg
|
||||
MANIFEST
|
||||
|
||||
# PyInstaller
|
||||
# Usually these files are written by a python script from a template
|
||||
# before PyInstaller builds the exe, so as to inject date/other infos into it.
|
||||
*.manifest
|
||||
*.spec
|
||||
|
||||
# Installer logs
|
||||
pip-log.txt
|
||||
pip-delete-this-directory.txt
|
||||
|
||||
# Unit test / coverage reports
|
||||
htmlcov/
|
||||
.tox/
|
||||
.nox/
|
||||
.coverage
|
||||
.coverage.*
|
||||
.cache
|
||||
nosetests.xml
|
||||
coverage.xml
|
||||
*.cover
|
||||
*.py,cover
|
||||
.hypothesis/
|
||||
.pytest_cache/
|
||||
pytestdebug.log
|
||||
|
||||
# Translations
|
||||
*.mo
|
||||
*.pot
|
||||
|
||||
# Django stuff:
|
||||
*.log
|
||||
local_settings.py
|
||||
db.sqlite3
|
||||
db.sqlite3-journal
|
||||
|
||||
# Flask stuff:
|
||||
instance/
|
||||
.webassets-cache
|
||||
|
||||
# Scrapy stuff:
|
||||
.scrapy
|
||||
|
||||
# Sphinx documentation
|
||||
docs/_build/
|
||||
doc/_build/
|
||||
|
||||
# PyBuilder
|
||||
target/
|
||||
|
||||
# Jupyter Notebook
|
||||
.ipynb_checkpoints
|
||||
|
||||
# IPython
|
||||
profile_default/
|
||||
ipython_config.py
|
||||
|
||||
# pyenv
|
||||
.python-version
|
||||
|
||||
# pipenv
|
||||
# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
|
||||
# However, in case of collaboration, if having platform-specific dependencies or dependencies
|
||||
# having no cross-platform support, pipenv may install dependencies that don't work, or not
|
||||
# install all needed dependencies.
|
||||
#Pipfile.lock
|
||||
|
||||
# PEP 582; used by e.g. github.com/David-OConnor/pyflow
|
||||
__pypackages__/
|
||||
|
||||
# Celery stuff
|
||||
celerybeat-schedule
|
||||
celerybeat.pid
|
||||
|
||||
# SageMath parsed files
|
||||
*.sage.py
|
||||
|
||||
# Environments
|
||||
.env
|
||||
.venv
|
||||
env/
|
||||
venv/
|
||||
ENV/
|
||||
env.bak/
|
||||
venv.bak/
|
||||
|
||||
# Spyder project settings
|
||||
.spyderproject
|
||||
.spyproject
|
||||
|
||||
# Rope project settings
|
||||
.ropeproject
|
||||
|
||||
# mkdocs documentation
|
||||
/site
|
||||
|
||||
# mypy
|
||||
.mypy_cache/
|
||||
.dmypy.json
|
||||
dmypy.json
|
||||
|
||||
# Pyre type checker
|
||||
.pyre/
|
||||
|
||||
# pytype static type analyzer
|
||||
.pytype/
|
||||
|
||||
# End of https://www.toptal.com/developers/gitignore/api/python
|
||||
|
||||
dataset
|
||||
dataset_raw
|
||||
raw
|
||||
results
|
||||
inference/chunks_temp.json
|
||||
logs
|
||||
hubert/checkpoint_best_legacy_500.pt
|
||||
configs/config.json
|
||||
filelists/test.txt
|
||||
filelists/train.txt
|
||||
filelists/val.txt
|
||||
@@ -0,0 +1,110 @@
|
||||
# Changelog
|
||||
|
||||
<!--next-version-placeholder-->
|
||||
|
||||
## v1.0.2 (2023-03-21)
|
||||
### Fix
|
||||
* **deps:** Update dependency scipy to v1.10.1 ([#35](https://github.com/34j/so-vits-svc-fork/issues/35)) ([`e0253bf`](https://github.com/34j/so-vits-svc-fork/commit/e0253bf1e655f86be605395a18f343763d975101))
|
||||
|
||||
## v1.0.1 (2023-03-20)
|
||||
### Documentation
|
||||
* Add ThrowawayAccount01 as a contributor for bug ([#47](https://github.com/34j/so-vits-svc-fork/issues/47)) ([`15e31fa`](https://github.com/34j/so-vits-svc-fork/commit/15e31fa806249d45235918fa62a48a86c43538cb))
|
||||
* Add BlueAmulet as a contributor for ideas ([#46](https://github.com/34j/so-vits-svc-fork/issues/46)) ([`a3bcb2b`](https://github.com/34j/so-vits-svc-fork/commit/a3bcb2be2992c98bcc2485082c19009c74cb3194))
|
||||
|
||||
### Performance
|
||||
* **inference_main:** Do dummy inference before running vc ([#45](https://github.com/34j/so-vits-svc-fork/issues/45)) ([`4066c43`](https://github.com/34j/so-vits-svc-fork/commit/4066c4334b107062d2daa7c9dc00600a56c6e553))
|
||||
|
||||
## v1.0.0 (2023-03-20)
|
||||
### Fix
|
||||
* Fix default dataset path ([#43](https://github.com/34j/so-vits-svc-fork/issues/43)) ([`ac47fed`](https://github.com/34j/so-vits-svc-fork/commit/ac47fede2581d375c2be9c28102961f19f5a9aa1))
|
||||
|
||||
### Breaking
|
||||
* the behaviour of preprocess_resample changes when there is a folder ./dataset_raw/44k and "44k" is no longer allowed as a speaker name in some conditions ([`ac47fed`](https://github.com/34j/so-vits-svc-fork/commit/ac47fede2581d375c2be9c28102961f19f5a9aa1))
|
||||
|
||||
## v0.8.2 (2023-03-20)
|
||||
### Fix
|
||||
* Fix compute_f0_crepe returning wrong length ([#42](https://github.com/34j/so-vits-svc-fork/issues/42)) ([`afb42b0`](https://github.com/34j/so-vits-svc-fork/commit/afb42b019ccd133876a2c55cf01007950a733d8c))
|
||||
|
||||
## v0.8.1 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency librosa to v0.10.0 ([#40](https://github.com/34j/so-vits-svc-fork/issues/40)) ([`8e92f71`](https://github.com/34j/so-vits-svc-fork/commit/8e92f71b2820628f0f8583e6bc455d8f753f4302))
|
||||
|
||||
## v0.8.0 (2023-03-20)
|
||||
### Feature
|
||||
* Add more f0 calculation methods ([#39](https://github.com/34j/so-vits-svc-fork/issues/39)) ([`6b3b20d`](https://github.com/34j/so-vits-svc-fork/commit/6b3b20dfd609d81cb1184b7c8e8865a58f8d45f9))
|
||||
|
||||
## v0.7.1 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency gradio to v3.22.1 ([#33](https://github.com/34j/so-vits-svc-fork/issues/33)) ([`f09fc23`](https://github.com/34j/so-vits-svc-fork/commit/f09fc23ca82519cc095509d4d4760561424a17ec))
|
||||
|
||||
## v0.7.0 (2023-03-20)
|
||||
### Feature
|
||||
* **preprocessing:** Allow nested dataset ([#19](https://github.com/34j/so-vits-svc-fork/issues/19)) ([`0433151`](https://github.com/34j/so-vits-svc-fork/commit/0433151d94c4da8e84a0183bdd47f1e08ea3c462))
|
||||
|
||||
## v0.6.3 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency torch to v1.13.1 ([#27](https://github.com/34j/so-vits-svc-fork/issues/27)) ([`8826d68`](https://github.com/34j/so-vits-svc-fork/commit/8826d6870e223e7969baa069bf12235e0deec0b7))
|
||||
* **deps:** Update dependency torchaudio to v0.13.1 ([#28](https://github.com/34j/so-vits-svc-fork/issues/28)) ([`989f5d9`](https://github.com/34j/so-vits-svc-fork/commit/989f5d903b47ba9b0ea1d0fe37cbfe76edf0a811))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Update notes about VRAM caps ([#18](https://github.com/34j/so-vits-svc-fork/issues/18)) ([`0a245f4`](https://github.com/34j/so-vits-svc-fork/commit/0a245f4ee69bd0d4371836367becf0fe409431e2))
|
||||
|
||||
## v0.6.2 (2023-03-19)
|
||||
### Fix
|
||||
* Use hubert preprocess force_rebuild argument ([#15](https://github.com/34j/so-vits-svc-fork/issues/15)) ([`87cf807`](https://github.com/34j/so-vits-svc-fork/commit/87cf807496248e2c7b859069f81aa040e86aec59))
|
||||
|
||||
### Documentation
|
||||
* Add GarrettConway as a contributor for bug ([#17](https://github.com/34j/so-vits-svc-fork/issues/17)) ([`31d9671`](https://github.com/34j/so-vits-svc-fork/commit/31d9671207143fd06b8db148802d1e27874151ce))
|
||||
* **notebook:** Launch tensorboard ([#16](https://github.com/34j/so-vits-svc-fork/issues/16)) ([`52229ba`](https://github.com/34j/so-vits-svc-fork/commit/52229ba0fe9458e37b45287c0a716c7cd36adbd6))
|
||||
* Add 34j as a contributor for example, infra, and 6 more ([#14](https://github.com/34j/so-vits-svc-fork/issues/14)) ([`1b90378`](https://github.com/34j/so-vits-svc-fork/commit/1b903783b4b89f2f5a4fc2e1b47f3eade0c0402f))
|
||||
* Add GarrettConway as a contributor for code ([#13](https://github.com/34j/so-vits-svc-fork/issues/13)) ([`716813f`](https://github.com/34j/so-vits-svc-fork/commit/716813fbff85ab4609d8ec3f374b78c6551877e5))
|
||||
|
||||
## v0.6.1 (2023-03-19)
|
||||
### Performance
|
||||
* **preprocessing:** Better performance ([#12](https://github.com/34j/so-vits-svc-fork/issues/12)) ([`668c8e1`](https://github.com/34j/so-vits-svc-fork/commit/668c8e1f18cefb0ebd2fb2f1d6572ce4d37d1102))
|
||||
|
||||
## v0.6.0 (2023-03-18)
|
||||
### Feature
|
||||
* Configurable input and output devices ([#11](https://github.com/34j/so-vits-svc-fork/issues/11)) ([`a822a60`](https://github.com/34j/so-vits-svc-fork/commit/a822a6098d322ff37725eee19d17758f72a6db49))
|
||||
|
||||
### Documentation
|
||||
* **notebook:** Fix notebook ([#9](https://github.com/34j/so-vits-svc-fork/issues/9)) ([`427b4c1`](https://github.com/34j/so-vits-svc-fork/commit/427b4c1c6e0482345b17fedb018f7a18db68ccc5))
|
||||
* Update notebook ([#8](https://github.com/34j/so-vits-svc-fork/issues/8)) ([`ae3e471`](https://github.com/34j/so-vits-svc-fork/commit/ae3e4710aac41555f00ddcdfbcf5a5e925afb718))
|
||||
|
||||
## v0.5.0 (2023-03-18)
|
||||
### Feature
|
||||
* **gui:** Remember last directory (misc) ([`92558da`](https://github.com/34j/so-vits-svc-fork/commit/92558da2f0e4eb24a8de412fb7e22dc3530b648a))
|
||||
* **__main__:** Show defaults ([`3d298df`](https://github.com/34j/so-vits-svc-fork/commit/3d298df91bdfca230959603da74331b5eef4d487))
|
||||
|
||||
### Fix
|
||||
* **__main__:** Fix option names ([`7ff34fe`](https://github.com/34j/so-vits-svc-fork/commit/7ff34fe623dde6b0a684c45cf33dc54118f9a800))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Update README.md ([#6](https://github.com/34j/so-vits-svc-fork/issues/6)) ([`b988101`](https://github.com/34j/so-vits-svc-fork/commit/b98810194703b6bb0ede03a00c460eeecdab5131))
|
||||
|
||||
## v0.4.1 (2023-03-18)
|
||||
### Fix
|
||||
* Call init_logger() ([#5](https://github.com/34j/so-vits-svc-fork/issues/5)) ([`e6378f1`](https://github.com/34j/so-vits-svc-fork/commit/e6378f12e747e618ff90ece1552d09c0d0714d41))
|
||||
|
||||
## v0.4.0 (2023-03-18)
|
||||
### Feature
|
||||
* Enhance realtime algorythm ([#4](https://github.com/34j/so-vits-svc-fork/issues/4)) ([`d789a12`](https://github.com/34j/so-vits-svc-fork/commit/d789a12308784473ae5d09e0b73fa15bf7554de1))
|
||||
|
||||
## v0.3.0 (2023-03-17)
|
||||
### Feature
|
||||
* Add gui ([#3](https://github.com/34j/so-vits-svc-fork/issues/3)) ([`34aec2b`](https://github.com/34j/so-vits-svc-fork/commit/34aec2b98ee4ef82ef488129b61a7952af5226a3))
|
||||
|
||||
### Documentation
|
||||
* Update notebook ([`7b74606`](https://github.com/34j/so-vits-svc-fork/commit/7b74606508cfb7e45224cbd76f3de9c43c8b4309))
|
||||
|
||||
## v0.2.1 (2023-03-17)
|
||||
### Fix
|
||||
* **notebook:** Fix notebook ([`3ed00cc`](https://github.com/34j/so-vits-svc-fork/commit/3ed00cc66d4f66e045f61fc14937cb9160eee556))
|
||||
|
||||
## v0.2.0 (2023-03-17)
|
||||
### Feature
|
||||
* Realtime inference ([#2](https://github.com/34j/so-vits-svc-fork/issues/2)) ([`4dea1ae`](https://github.com/34j/so-vits-svc-fork/commit/4dea1ae51fe2e47a3f41556bdbe3fefd033d729a))
|
||||
|
||||
## v0.1.0 (2023-03-17)
|
||||
### Feature
|
||||
* Main feat ([#1](https://github.com/34j/so-vits-svc-fork/issues/1)) ([`faa990c`](https://github.com/34j/so-vits-svc-fork/commit/faa990ce6411d8b4e8b3d2d48c4b532b76ff7800))
|
||||
@@ -0,0 +1,26 @@
|
||||
FROM nvidia/cuda:12.0.1-runtime-ubuntu22.04
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive
|
||||
RUN apt-get update && apt-get install -y \
|
||||
build-essential \
|
||||
nvidia-driver-515 \
|
||||
python3.10 \
|
||||
python3-pip \
|
||||
python3.10-venv \
|
||||
python3.10-dev \
|
||||
vim \
|
||||
curl \
|
||||
wget \
|
||||
htop \
|
||||
libsndfile1 \
|
||||
--no-install-recommends \
|
||||
&& apt-get clean autoclean && apt-get autoremove -y && rm -rf /var/lib/{apt,dpkg,cache,log}/
|
||||
|
||||
|
||||
|
||||
|
||||
COPY . /models/voice_conversion/so-vits-svc
|
||||
|
||||
WORKDIR /models/voice_conversion/so-vits-svc
|
||||
RUN pip install -e .
|
||||
WORKDIR /
|
||||
@@ -1,5 +1,6 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2023 34j and contributors
|
||||
Copyright (c) 2021 Jingyi Li
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
|
||||
@@ -3,24 +3,44 @@ so-vits-svc
|
||||
|
||||
Original docs are in [README\_ORIGINAL.md](./README_ORIGINAL.md).
|
||||
|
||||
This is a snapshot of `f22819cb8718ead5e50dea4fdbd05195c72fb1a8` (branch `origin/4.0`). It was taken
|
||||
from justinjohn0306's fork at https://github.com/justinjohn0306/so-vits-svc
|
||||
This is a snapshot of `81551ce9c6fb7924d184c3c5a4cf9035168b28d2` (branch `main`). It was taken
|
||||
from 34j's fork at https://github.com/34j/so-vits-svc-fork
|
||||
|
||||
|
||||
Dev Installation
|
||||
----------------
|
||||
|
||||
Use our `requirements.txt` instead of the original `upstream-requirements-but-broken.txt`
|
||||
`pip install -e .`
|
||||
|
||||
Installing this may give you trouble. Brandon had trouble under Python3.10, so downgraded to Python 3.9
|
||||
using the deadsnakes PPA. Furthermore, the version of pyworld originally specified refused to build;
|
||||
upgrading to the latest point release fixed it.
|
||||
There is also a Dockerfile available so if you prefer:
|
||||
```sh
|
||||
docker build -t so-vits-svc .`
|
||||
docker run -it --privileged --gpus 0 so-vits-svc
|
||||
```
|
||||
|
||||
`pyworld==0.2.5` -> `pyworld==0.2.12`
|
||||
|
||||
tl;dr:
|
||||
|
||||
- Python3.9
|
||||
- pyworld 0.2.12
|
||||
Usage
|
||||
-----
|
||||
```
|
||||
$svc infer -h
|
||||
Usage: svc infer [OPTIONS] INPUT_PATH
|
||||
|
||||
Inference
|
||||
|
||||
Options:
|
||||
-o, --output-path PATH path to output dir
|
||||
-s, --speaker TEXT speaker name
|
||||
-m, --model-path PATH path to model [default: logs/44k]
|
||||
-c, --config-path PATH path to config [default: configs/44k/config.json]
|
||||
-k, --cluster-model-path PATH path to cluster model
|
||||
-t, --transpose INTEGER transpose [default: 0]
|
||||
-db, --db-thresh INTEGER threshold (DB) (RELATIVE) [default: -20]
|
||||
-a, --auto-predict-f0 BOOLEAN auto predict f0 [default: True]
|
||||
-r, --cluster-infer-ratio FLOAT
|
||||
cluster infer ratio [default: 0]
|
||||
-n, --noise-scale FLOAT noise scale [default: 0.4]
|
||||
-p, --pad-seconds FLOAT pad seconds [default: 0.5]
|
||||
-d, --device TEXT device [default: cuda]
|
||||
-ch, --chunk-seconds FLOAT chunk seconds [default: 0.5]
|
||||
-ab, --absolute-thresh BOOLEAN absolute thresh [default: False]
|
||||
-h, --help Show this message and exit.
|
||||
```
|
||||
|
||||
@@ -1,138 +1,167 @@
|
||||
# SoftVC VITS Singing Voice Conversion
|
||||
# SoftVC VITS Singing Voice Conversion Fork
|
||||
|
||||
## SoVITS has stopped updating and officially Archived
|
||||
Some other related warehouses for follow-up maintenance and other work:
|
||||
+ [so-vits-svc](https://github.com/svc-develop-team/so-vits-svc): The svc community is ready to take over and maintain sovits. If you have pr and issue, you can submit them here
|
||||
+ [SoftVitsResearch](https://github.com/NaruseMioShirakana/SoftVitsResearch): Used to make some fancy functions (mainly for Onnx-MoesS)
|
||||
<p align="center">
|
||||
<a href="https://github.com/34j/so-vits-svc-fork/actions/workflows/ci.yml?query=branch%3Amain">
|
||||
<img src="https://img.shields.io/github/actions/workflow/status/34j/so-vits-svc-fork/ci.yml?branch=main&label=CI&logo=github&style=flat-square" alt="CI Status" >
|
||||
</a>
|
||||
<a href="https://so-vits-svc-fork.readthedocs.io">
|
||||
<img src="https://img.shields.io/readthedocs/so-vits-svc-fork.svg?logo=read-the-docs&logoColor=fff&style=flat-square" alt="Documentation Status">
|
||||
</a>
|
||||
<a href="https://codecov.io/gh/34j/so-vits-svc-fork">
|
||||
<img src="https://img.shields.io/codecov/c/github/34j/so-vits-svc-fork.svg?logo=codecov&logoColor=fff&style=flat-square" alt="Test coverage percentage">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://python-poetry.org/">
|
||||
<img src="https://img.shields.io/badge/packaging-poetry-299bd7?style=flat-square&logo=data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAA4AAAASCAYAAABrXO8xAAAACXBIWXMAAAsTAAALEwEAmpwYAAAAAXNSR0IArs4c6QAAAARnQU1BAACxjwv8YQUAAAJJSURBVHgBfZLPa1NBEMe/s7tNXoxW1KJQKaUHkXhQvHgW6UHQQ09CBS/6V3hKc/AP8CqCrUcpmop3Cx48eDB4yEECjVQrlZb80CRN8t6OM/teagVxYZi38+Yz853dJbzoMV3MM8cJUcLMSUKIE8AzQ2PieZzFxEJOHMOgMQQ+dUgSAckNXhapU/NMhDSWLs1B24A8sO1xrN4NECkcAC9ASkiIJc6k5TRiUDPhnyMMdhKc+Zx19l6SgyeW76BEONY9exVQMzKExGKwwPsCzza7KGSSWRWEQhyEaDXp6ZHEr416ygbiKYOd7TEWvvcQIeusHYMJGhTwF9y7sGnSwaWyFAiyoxzqW0PM/RjghPxF2pWReAowTEXnDh0xgcLs8l2YQmOrj3N7ByiqEoH0cARs4u78WgAVkoEDIDoOi3AkcLOHU60RIg5wC4ZuTC7FaHKQm8Hq1fQuSOBvX/sodmNJSB5geaF5CPIkUeecdMxieoRO5jz9bheL6/tXjrwCyX/UYBUcjCaWHljx1xiX6z9xEjkYAzbGVnB8pvLmyXm9ep+W8CmsSHQQY77Zx1zboxAV0w7ybMhQmfqdmmw3nEp1I0Z+FGO6M8LZdoyZnuzzBdjISicKRnpxzI9fPb+0oYXsNdyi+d3h9bm9MWYHFtPeIZfLwzmFDKy1ai3p+PDls1Llz4yyFpferxjnyjJDSEy9CaCx5m2cJPerq6Xm34eTrZt3PqxYO1XOwDYZrFlH1fWnpU38Y9HRze3lj0vOujZcXKuuXm3jP+s3KbZVra7y2EAAAAAASUVORK5CYII=" alt="Poetry">
|
||||
</a>
|
||||
<a href="https://github.com/ambv/black">
|
||||
<img src="https://img.shields.io/badge/code%20style-black-000000.svg?style=flat-square" alt="black">
|
||||
</a>
|
||||
<a href="https://github.com/pre-commit/pre-commit">
|
||||
<img src="https://img.shields.io/badge/pre--commit-enabled-brightgreen?logo=pre-commit&logoColor=white&style=flat-square" alt="pre-commit">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://pypi.org/project/so-vits-svc-fork/">
|
||||
<img src="https://img.shields.io/pypi/v/so-vits-svc-fork.svg?logo=python&logoColor=fff&style=flat-square" alt="PyPI Version">
|
||||
</a>
|
||||
<img src="https://img.shields.io/pypi/pyversions/so-vits-svc-fork.svg?style=flat-square&logo=python&logoColor=fff" alt="Supported Python versions">
|
||||
<img src="https://img.shields.io/pypi/l/so-vits-svc-fork.svg?style=flat-square" alt="License">
|
||||
</p>
|
||||
|
||||
## Terms of use
|
||||
1. Please solve the authorization problem of the data set by yourself. Any problems caused by using unauthorized data sets for training, you must bear full responsibility and all consequences, and have nothing to do with sovits!
|
||||
2. Any sovits-based video published to the video platform must clearly indicate in the introduction the input source singing and audio used for voice changer conversion, for example: use the video/audio released by others, and use the separated human voice as input If the source is converted, a clear link to the original video and music must be given; if the input source is converted using your own vocals or voice synthesized by other singing voice synthesis engines, you must also explain it in the introduction.
|
||||
3. Any copyright infringement caused by the input source shall bear full responsibility and all consequences. When using other commercial singing voice synthesis software as the input source, please make sure to abide by the terms of use of the software. Note that the terms of use of many singing voice synthesis engines clearly indicate that they cannot be used for input source conversion!
|
||||
A fork of [`so-vits-svc`](https://github.com/svc-develop-team/so-vits-svc) with **realtime support** and **greatly improved interface**. Based on branch `4.0` (v1) and the models are compatible.
|
||||
|
||||
## update
|
||||
> The 4.0-v2 model has been updated. The entire process is the same as 4.0. Compared with 4.0, there are some improvements in some scenarios, but there are also some cases where there are regressions. In the [4.0-v2 branch](https://github.com/innnky/so -vits-svc/tree/4.0-v2) This is the last update of sovits \
|
||||
## Installation
|
||||
|
||||
## Model Introduction
|
||||
The singing voice conversion model extracts the voice features of the source audio through the SoftVC content encoder, and inputs VITS at the same time as F0 to replace the original text input to achieve the effect of singing voice conversion. At the same time, replace the vocoder with [NSF HiFiGAN](https://github.com/openvpi/DiffSinger/tree/refactor/modules/nsf_hifigan) to solve the staccato problem
|
||||
Install this via pip (or your favourite package manager):
|
||||
|
||||
### 4.0 version update content
|
||||
+ Feature input replaced with [Content Vec](https://github.com/auspicious3000/contentvec)
|
||||
+ The sampling rate is uniformly used at 44100hz
|
||||
+ Due to the change of parameters such as hop size and the simplification of some model structures, the video memory usage required for inference has been greatly reduced**, and the 44khz video memory usage of version 4.0 is even smaller than the 32khz of version 3.0
|
||||
+ Adjusted part of the code structure
|
||||
+ Dataset production and training process are consistent with 3.0, but the model is not universal at all, and the dataset also needs to be re-preprocessed
|
||||
+ Added option 1: vc mode automatically predicts the pitch f0, that is, there is no need to manually input the transposition key when converting the voice, the male and female voices can be automatically converted, but only for voice conversion, the singing voice will be out of tune when converted in this mode
|
||||
+ Added option 2: reduce timbre leakage through the kmeans clustering scheme, that is, make the timbre more like the target timbre
|
||||
|
||||
Online demo: [](https://huggingface.co/spaces/innnky/sovits4)
|
||||
|
||||
## Pre-downloaded model files
|
||||
+ contentvec: [checkpoint_best_legacy_500.pt](https://ibm.box.com/s/z1wgl1stco8ffooyatzdwsqn2psd9lrr)
|
||||
+ placed in the `hubert` directory
|
||||
+ Pre-training base model file: [G_0.pth](https://huggingface.co/justinjohn-03/so-vits-svc-4.0/resolve/main/G_0.pth) and [D_0.pth](https://huggingface.co/justinjohn-03/so-vits-svc-4.0/resolve/main/D_0.pth)
|
||||
+ placed in the `logs/44k` directory
|
||||
+ The pre-trained base model training data set includes Yunhao, Jishuang, Huiyu·Xing AI Paimeng, Lingdi Ningning, covering the common vocal range of male and female girls, which can be considered as a relatively common base model
|
||||
```shell
|
||||
# One-click download
|
||||
# contentvec
|
||||
http://obs.cstcloud.cn/share/obs/sankagenkeshi/checkpoint_best_legacy_500.pt
|
||||
# It can also be manually downloaded and placed in the hubert directory
|
||||
# G and D pre-training model:
|
||||
wget -P logs/44k/ https://huggingface.co/justinjohn-03/so-vits-svc-4.0/resolve/main/G_0.pth
|
||||
wget -P logs/44k/ https://huggingface.co/justinjohn-03/so-vits-svc-4.0/resolve/main/D_0.pth
|
||||
|
||||
pip install -U torch torchaudio --index-url https://download.pytorch.org/whl/cu117
|
||||
pip install so-vits-svc-fork
|
||||
```
|
||||
|
||||
## Colab one-click data set production and training script
|
||||
[](https://colab.research.google.com/github/justinjohn0306/so-vits-svc/blob/4.0/Sovits4_0_training_inference.ipynb)
|
||||
## Features not available in the original repo
|
||||
|
||||
- **Realtime voice conversion** (enhanced in v1.1.0)
|
||||
- More accurate pitch estimation using CREPE
|
||||
- GUI available
|
||||
- Unified command-line interface (no need to run Python scripts)
|
||||
- Ready to use just by installing with `pip`.
|
||||
- Automatically download pretrained base model and HuBERT model
|
||||
- Code completely formatted with black, isort, autoflake etc.
|
||||
- Volume normalization in preprocessing
|
||||
- Other minor differences
|
||||
|
||||
## Usage
|
||||
|
||||
### Inference
|
||||
|
||||
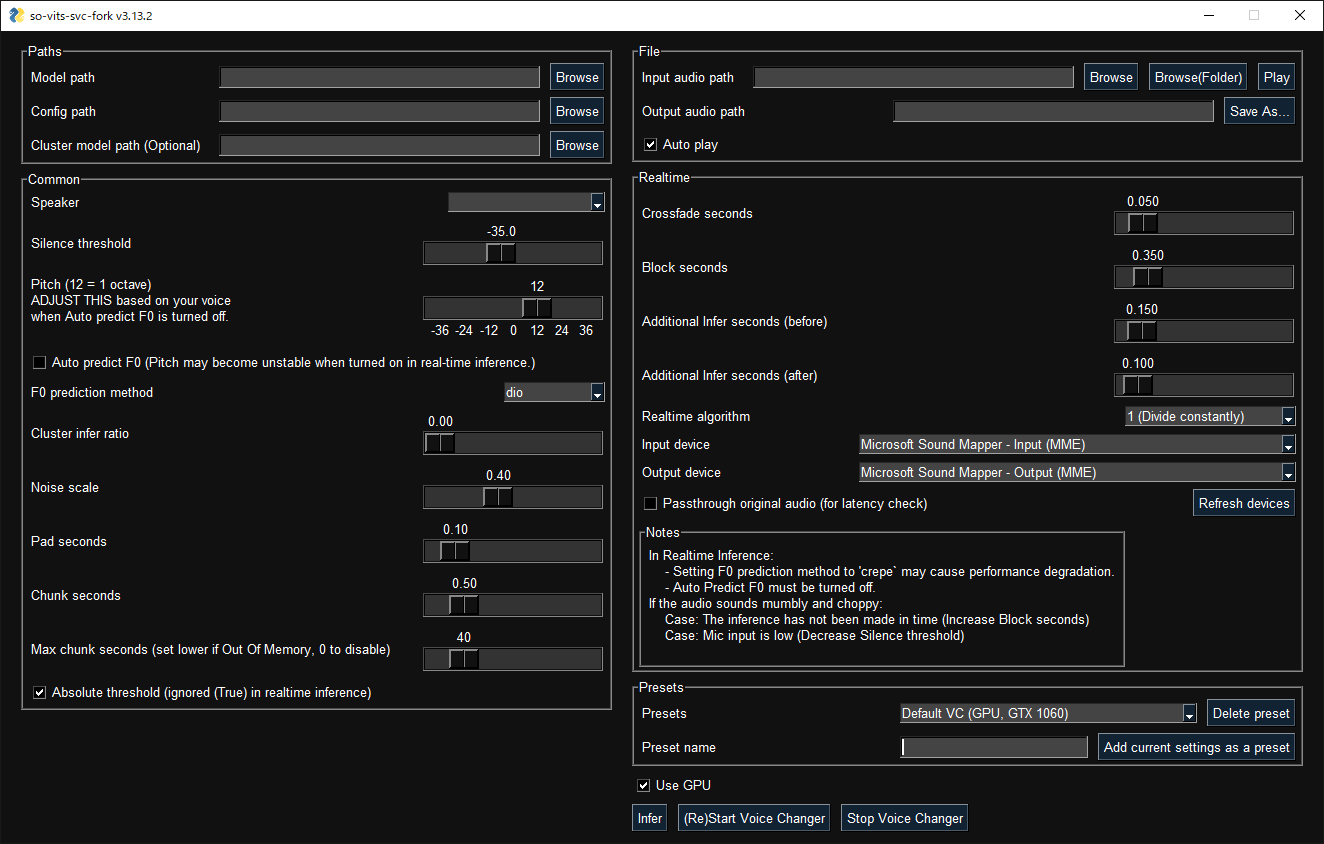
#### GUI
|
||||
|
||||
|
||||
|
||||
GUI launches with the following command:
|
||||
|
||||
## Dataset preparation
|
||||
Just put the dataset into the dataset_raw directory with the following file structure
|
||||
```shell
|
||||
dataset_raw
|
||||
├───speaker0
|
||||
│ ├───xxx1-xxx1.wav
|
||||
│ ├────...
|
||||
│ └───Lxx-0xx8.wav
|
||||
└───speaker1
|
||||
├───xx2-0xxx2.wav
|
||||
├────...
|
||||
└───xxx7-xxx007.wav
|
||||
svcg
|
||||
```
|
||||
|
||||
#### CLI
|
||||
|
||||
## Data preprocessing
|
||||
1. Resample to 44100hz
|
||||
- Realtime (from microphone)
|
||||
|
||||
```shell
|
||||
python resample.py
|
||||
```
|
||||
2. Automatically divide training set, verification set, test set and automatically generate configuration files
|
||||
```shell
|
||||
python preprocess_flist_config.py
|
||||
svc vc --model-path <model-path>
|
||||
```
|
||||
3. Generate hubert and f0
|
||||
```shell
|
||||
python preprocess_hubert_f0.py
|
||||
```
|
||||
After performing the above steps, the dataset directory is the preprocessed data, you can delete the dataset_raw folder
|
||||
|
||||
|
||||
## train
|
||||
```shell
|
||||
python train.py -c configs/config.json -m 44k
|
||||
```
|
||||
Note: The old model will be automatically cleared during training, and only the latest 3 models will be kept. If you want to prevent overfitting, you need to manually back up the model record points, or modify the configuration file keep_ckpts 0 to never clear
|
||||
|
||||
## reasoning
|
||||
Use [inference_main.py](inference_main.py)
|
||||
|
||||
As of now, the 4.0 usage method (training, reasoning) is exactly the same as 3.0, without any changes (command line support is added for reasoning)
|
||||
- File
|
||||
|
||||
```shell
|
||||
# example
|
||||
python inference_main.py -m "logs/44k/G_30400.pth" -c "configs/config.json" -n "君の知らない物语-src.wav" -t 0 -s "nen"
|
||||
svc --model-path <model-path> source.wav
|
||||
```
|
||||
required field
|
||||
+ -m, --model_path: model path.
|
||||
+ -c, --config_path: configuration file path.
|
||||
+ -n, --clean_names: list of wav file names, placed under the raw folder.
|
||||
+ -t, --trans: pitch adjustment, support positive and negative (semitones).
|
||||
+ -s, --spk_list: synthesize target speaker names.
|
||||
|
||||
Optional section: see next section
|
||||
+ -a, --auto_predict_f0: Voice conversion automatically predicts the pitch, do not enable this when converting singing voices, it will seriously go out of tune.
|
||||
+ -cm, --cluster_model_path: The path of the cluster model, if there is no training cluster, just fill it in.
|
||||
+ -cr, --cluster_infer_ratio: Clustering scheme ratio, range 0-1, if no clustering model is trained, fill in 0.
|
||||
#### Notes
|
||||
|
||||
## Optional
|
||||
If the previous effect is satisfactory, or if you don’t understand what is going on below, then the following content can be ignored without affecting the use of the model. (These options have relatively little impact and may have some effect on some specific data, but most of the cases seem to be less obvious),
|
||||
### Automatic f0 prediction
|
||||
The 4.0 model training process will train an f0 predictor. For voice conversion, you can enable automatic pitch prediction. If the effect is not good, you can also use manual, but please do not enable this function when converting singing voices! ! ! It will be seriously out of tune! !
|
||||
+ Set auto_predict_f0 to true in inference_main
|
||||
### Cluster Timbre Leakage Control
|
||||
Introduction: The clustering scheme can reduce the timbre leakage, making the model trained more like the target timbre (but it is not particularly obvious), but the simple clustering scheme will reduce the model's articulation (it will be inarticulate) (this is obvious) , this model adopts the fusion method,
|
||||
You can linearly control the ratio of the clustering scheme and the non-clustering scheme, that is, you can manually adjust the ratio between "like the target tone" and "clear articulation" to find a suitable compromise point.
|
||||
- In real-time inference, if there is noise on the inputs, the HuBERT model will react to those as well. Consider using realtime noise reduction applications such as [RTX Voice](https://www.nvidia.com/en-us/geforce/guides/nvidia-rtx-voice-setup-guide/) in this case.
|
||||
|
||||
Using the existing steps before clustering does not require any changes, only an additional clustering model needs to be trained, although the effect is relatively limited, but the training cost is relatively low
|
||||
+ Training process:
|
||||
+ Use a machine with better CPU performance for training. According to my experience, it takes about 4 minutes to train each speaker on Tencent Cloud 6-core CPU to complete the training
|
||||
+ Execute python cluster/train_cluster.py, the output of the model will be in logs/44k/kmeans_10000.pt
|
||||
+ Reasoning process:
|
||||
+ Specify cluster_model_path in inference_main
|
||||
+ Specify cluster_infer_ratio in inference_main, 0 means no clustering at all, 1 means only clustering, usually set to 0.5
|
||||
### Training
|
||||
|
||||
## Onnx export
|
||||
Use [onnx_export.py](onnx_export.py)
|
||||
+ Create a new folder: `checkpoints` and open it
|
||||
+ Create a new folder in the `checkpoints` folder as the project folder, and the folder name is your project name, such as `aziplayer`
|
||||
+ Rename your model to `model.pth`, rename the configuration file to `config.json`, and place it in the `aziplayer` folder you just created
|
||||
+ Change `"NyaruTaffy"` in `path = "NyaruTaffy"` in [onnx_export.py](onnx_export.py) to your project name, `path = "aziplayer"`
|
||||
+ run [onnx_export.py](onnx_export.py)
|
||||
+ After the execution is completed, a `model.onnx` will be generated in your project folder, which is the exported model
|
||||
### Onnx model supported UI
|
||||
+ [MoeSS](https://github.com/NaruseMioShirakana/MoeSS)
|
||||
+ I removed all the training functions and all complicated transpositions, not a single line, because I think you only know that you are using Onnx if you remove these things
|
||||
+ Note: Please use the model provided by MoesS for the Hubert Onnx model, which cannot be exported at present (Hubert in fairseq has many operators that onnx does not support and things that involve constants, and an error will be reported when exporting or the exported model input and output shape and The results are problematic)
|
||||
[Hubert4.0](https://huggingface.co/NaruseMioShirakana/MoeSS-SUBModel)
|
||||
#### Google Colab
|
||||
|
||||
[](https://colab.research.google.com/github/34j/so-vits-svc-fork/blob/main/notebooks/so-vits-svc-fork-4.0.ipynb)
|
||||
|
||||
#### Local
|
||||
|
||||
Place your dataset like `dataset_raw/{speaker_id}/**/{wav_file}.{any_format}` (subfolders are acceptable) and run:
|
||||
|
||||
```shell
|
||||
svc pre-resample
|
||||
svc pre-config
|
||||
svc pre-hubert
|
||||
svc train
|
||||
```
|
||||
|
||||
#### Notes
|
||||
|
||||
- Dataset audio duration per file should be <~ 10s or VRAM will run out.
|
||||
- It is recommended to change the batch_size in `config.json` before the `train` command to match the VRAM capacity. As tested, the default requires about 14 GB.
|
||||
|
||||
### Further help
|
||||
|
||||
For more details, run `svc -h` or `svc <subcommand> -h`.
|
||||
|
||||
```shell
|
||||
> svc -h
|
||||
Usage: svc [OPTIONS] COMMAND [ARGS]...
|
||||
|
||||
so-vits-svc allows any folder structure for training data.
|
||||
However, the following folder structure is recommended.
|
||||
When training: dataset_raw/{speaker_name}/{wav_name}.wav
|
||||
When inference: configs/44k/config.json, logs/44k/G_XXXX.pth
|
||||
If the folder structure is followed, you DO NOT NEED TO SPECIFY model path, config path, etc.
|
||||
(The latest model will be automatically loaded.)
|
||||
To train a model, run pre-resample, pre-config, pre-hubert, train.
|
||||
To infer a model, run infer.
|
||||
|
||||
Options:
|
||||
-h, --help Show this message and exit.
|
||||
|
||||
Commands:
|
||||
clean Clean up files, only useful if you are using the default file structure
|
||||
infer Inference
|
||||
onnx Export model to onnx
|
||||
pre-config Preprocessing part 2: config
|
||||
pre-hubert Preprocessing part 3: hubert If the HuBERT model is not found, it will be...
|
||||
pre-resample Preprocessing part 1: resample
|
||||
train Train model If D_0.pth or G_0.pth not found, automatically download from hub.
|
||||
train-cluster Train k-means clustering
|
||||
vc Realtime inference from microphone
|
||||
```
|
||||
|
||||
## Contributors ✨
|
||||
|
||||
Thanks goes to these wonderful people ([emoji key](https://allcontributors.org/docs/en/emoji-key)):
|
||||
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- ALL-CONTRIBUTORS-LIST:START - Do not remove or modify this section -->
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- markdownlint-disable -->
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/34j"><img src="https://avatars.githubusercontent.com/u/55338215?v=4?s=80" width="80px;" alt="34j"/><br /><sub><b>34j</b></sub></a><br /><a href="https://github.com/34j/so-vits-svc-fork/commits?author=34j" title="Code">💻</a> <a href="#ideas-34j" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/34j/so-vits-svc-fork/commits?author=34j" title="Documentation">📖</a> <a href="#example-34j" title="Examples">💡</a> <a href="#infra-34j" title="Infrastructure (Hosting, Build-Tools, etc)">🚇</a> <a href="#maintenance-34j" title="Maintenance">🚧</a> <a href="https://github.com/34j/so-vits-svc-fork/pulls?q=is%3Apr+reviewed-by%3A34j" title="Reviewed Pull Requests">👀</a> <a href="https://github.com/34j/so-vits-svc-fork/commits?author=34j" title="Tests">⚠️</a> <a href="#tutorial-34j" title="Tutorials">✅</a> <a href="#promotion-34j" title="Promotion">📣</a> <a href="https://github.com/34j/so-vits-svc-fork/issues?q=author%3A34j" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/GarrettConway"><img src="https://avatars.githubusercontent.com/u/22782004?v=4?s=80" width="80px;" alt="GarrettConway"/><br /><sub><b>GarrettConway</b></sub></a><br /><a href="https://github.com/34j/so-vits-svc-fork/commits?author=GarrettConway" title="Code">💻</a> <a href="https://github.com/34j/so-vits-svc-fork/issues?q=author%3AGarrettConway" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/BlueAmulet"><img src="https://avatars.githubusercontent.com/u/43395286?v=4?s=80" width="80px;" alt="BlueAmulet"/><br /><sub><b>BlueAmulet</b></sub></a><br /><a href="#ideas-BlueAmulet" title="Ideas, Planning, & Feedback">🤔</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ThrowawayAccount01"><img src="https://avatars.githubusercontent.com/u/125531852?v=4?s=80" width="80px;" alt="ThrowawayAccount01"/><br /><sub><b>ThrowawayAccount01</b></sub></a><br /><a href="https://github.com/34j/so-vits-svc-fork/issues?q=author%3AThrowawayAccount01" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
<!-- markdownlint-restore -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:END -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
This project follows the [all-contributors](https://github.com/all-contributors/all-contributors) specification. Contributions of any kind welcome!
|
||||
|
||||
@@ -1,69 +0,0 @@
|
||||
import io
|
||||
import os
|
||||
|
||||
# os.system("wget -P cvec/ https://huggingface.co/spaces/innnky/nanami/resolve/main/checkpoint_best_legacy_500.pt")
|
||||
import gradio as gr
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile
|
||||
from inference.infer_tool import Svc
|
||||
import logging
|
||||
|
||||
logging.getLogger('numba').setLevel(logging.WARNING)
|
||||
logging.getLogger('markdown_it').setLevel(logging.WARNING)
|
||||
logging.getLogger('urllib3').setLevel(logging.WARNING)
|
||||
logging.getLogger('matplotlib').setLevel(logging.WARNING)
|
||||
|
||||
config_path = "configs/config.json"
|
||||
|
||||
model = Svc("logs/44k/G_114400.pth", "configs/config.json", cluster_model_path="logs/44k/kmeans_10000.pt")
|
||||
|
||||
|
||||
|
||||
def vc_fn(sid, input_audio, vc_transform, auto_f0,cluster_ratio, slice_db, noise_scale):
|
||||
if input_audio is None:
|
||||
return "You need to upload an audio", None
|
||||
sampling_rate, audio = input_audio
|
||||
# print(audio.shape,sampling_rate)
|
||||
duration = audio.shape[0] / sampling_rate
|
||||
if duration > 90:
|
||||
return "请上传小于90s的音频,需要转换长音频请本地进行转换", None
|
||||
audio = (audio / np.iinfo(audio.dtype).max).astype(np.float32)
|
||||
if len(audio.shape) > 1:
|
||||
audio = librosa.to_mono(audio.transpose(1, 0))
|
||||
if sampling_rate != 16000:
|
||||
audio = librosa.resample(audio, orig_sr=sampling_rate, target_sr=16000)
|
||||
print(audio.shape)
|
||||
out_wav_path = "temp.wav"
|
||||
soundfile.write(out_wav_path, audio, 16000, format="wav")
|
||||
print( cluster_ratio, auto_f0, noise_scale)
|
||||
_audio = model.slice_inference(out_wav_path, sid, vc_transform, slice_db, cluster_ratio, auto_f0, noise_scale)
|
||||
return "Success", (44100, _audio)
|
||||
|
||||
|
||||
app = gr.Blocks()
|
||||
with app:
|
||||
with gr.Tabs():
|
||||
with gr.TabItem("Basic"):
|
||||
gr.Markdown(value="""
|
||||
sovits4.0 在线demo
|
||||
|
||||
此demo为预训练底模在线demo,使用数据:云灏 即霜 辉宇·星AI 派蒙 绫地宁宁
|
||||
""")
|
||||
spks = list(model.spk2id.keys())
|
||||
sid = gr.Dropdown(label="音色", choices=spks, value=spks[0])
|
||||
vc_input3 = gr.Audio(label="上传音频(长度小于90秒)")
|
||||
vc_transform = gr.Number(label="变调(整数,可以正负,半音数量,升高八度就是12)", value=0)
|
||||
cluster_ratio = gr.Number(label="聚类模型混合比例,0-1之间,默认为0不启用聚类,能提升音色相似度,但会导致咬字下降(如果使用建议0.5左右)", value=0)
|
||||
auto_f0 = gr.Checkbox(label="自动f0预测,配合聚类模型f0预测效果更好,会导致变调功能失效(仅限转换语音,歌声不要勾选此项会究极跑调)", value=False)
|
||||
slice_db = gr.Number(label="切片阈值", value=-40)
|
||||
noise_scale = gr.Number(label="noise_scale 建议不要动,会影响音质,玄学参数", value=0.4)
|
||||
vc_submit = gr.Button("转换", variant="primary")
|
||||
vc_output1 = gr.Textbox(label="Output Message")
|
||||
vc_output2 = gr.Audio(label="Output Audio")
|
||||
vc_submit.click(vc_fn, [sid, vc_input3, vc_transform,auto_f0,cluster_ratio, slice_db, noise_scale], [vc_output1, vc_output2])
|
||||
|
||||
app.launch()
|
||||
|
||||
|
||||
|
||||
@@ -1,89 +0,0 @@
|
||||
import os
|
||||
from glob import glob
|
||||
from pathlib import Path
|
||||
import torch
|
||||
import logging
|
||||
import argparse
|
||||
import torch
|
||||
import numpy as np
|
||||
from sklearn.cluster import KMeans, MiniBatchKMeans
|
||||
import tqdm
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
logger = logging.getLogger(__name__)
|
||||
import time
|
||||
import random
|
||||
|
||||
def train_cluster(in_dir, n_clusters, use_minibatch=True, verbose=False):
|
||||
|
||||
logger.info(f"Loading features from {in_dir}")
|
||||
features = []
|
||||
nums = 0
|
||||
for path in tqdm.tqdm(in_dir.glob("*.soft.pt")):
|
||||
features.append(torch.load(path).squeeze(0).numpy().T)
|
||||
# print(features[-1].shape)
|
||||
features = np.concatenate(features, axis=0)
|
||||
print(nums, features.nbytes/ 1024**2, "MB , shape:",features.shape, features.dtype)
|
||||
features = features.astype(np.float32)
|
||||
logger.info(f"Clustering features of shape: {features.shape}")
|
||||
t = time.time()
|
||||
if use_minibatch:
|
||||
kmeans = MiniBatchKMeans(n_clusters=n_clusters,verbose=verbose, batch_size=4096, max_iter=80).fit(features)
|
||||
else:
|
||||
kmeans = KMeans(n_clusters=n_clusters,verbose=verbose).fit(features)
|
||||
print(time.time()-t, "s")
|
||||
|
||||
x = {
|
||||
"n_features_in_": kmeans.n_features_in_,
|
||||
"_n_threads": kmeans._n_threads,
|
||||
"cluster_centers_": kmeans.cluster_centers_,
|
||||
}
|
||||
print("end")
|
||||
|
||||
return x
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--dataset', type=Path, default="./dataset/44k",
|
||||
help='path of training data directory')
|
||||
parser.add_argument('--output', type=Path, default="logs/44k",
|
||||
help='path of model output directory')
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
checkpoint_dir = args.output
|
||||
dataset = args.dataset
|
||||
n_clusters = 10000
|
||||
|
||||
ckpt = {}
|
||||
for spk in os.listdir(dataset):
|
||||
if os.path.isdir(dataset/spk):
|
||||
print(f"train kmeans for {spk}...")
|
||||
in_dir = dataset/spk
|
||||
x = train_cluster(in_dir, n_clusters, verbose=False)
|
||||
ckpt[spk] = x
|
||||
|
||||
checkpoint_path = checkpoint_dir / f"kmeans_{n_clusters}.pt"
|
||||
checkpoint_path.parent.mkdir(exist_ok=True, parents=True)
|
||||
torch.save(
|
||||
ckpt,
|
||||
checkpoint_path,
|
||||
)
|
||||
|
||||
|
||||
# import cluster
|
||||
# for spk in tqdm.tqdm(os.listdir("dataset")):
|
||||
# if os.path.isdir(f"dataset/{spk}"):
|
||||
# print(f"start kmeans inference for {spk}...")
|
||||
# for feature_path in tqdm.tqdm(glob(f"dataset/{spk}/*.discrete.npy", recursive=True)):
|
||||
# mel_path = feature_path.replace(".discrete.npy",".mel.npy")
|
||||
# mel_spectrogram = np.load(mel_path)
|
||||
# feature_len = mel_spectrogram.shape[-1]
|
||||
# c = np.load(feature_path)
|
||||
# c = utils.tools.repeat_expand_2d(torch.FloatTensor(c), feature_len).numpy()
|
||||
# feature = c.T
|
||||
# feature_class = cluster.get_cluster_result(feature, spk)
|
||||
# np.save(feature_path.replace(".discrete.npy", ".discrete_class.npy"), feature_class)
|
||||
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
# Minimal makefile for Sphinx documentation
|
||||
#
|
||||
|
||||
# You can set these variables from the command line, and also
|
||||
# from the environment for the first two.
|
||||
SPHINXOPTS ?=
|
||||
SPHINXBUILD ?= sphinx-build
|
||||
SOURCEDIR = .
|
||||
BUILDDIR = _build
|
||||
|
||||
# Put it first so that "make" without argument is like "make help".
|
||||
help:
|
||||
@$(SPHINXBUILD) -M help "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
|
||||
|
||||
.PHONY: help Makefile
|
||||
|
||||
# Catch-all target: route all unknown targets to Sphinx using the new
|
||||
# "make mode" option. $(O) is meant as a shortcut for $(SPHINXOPTS).
|
||||
%: Makefile
|
||||
@$(SPHINXBUILD) -M $@ "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 35 KiB |
@@ -0,0 +1,3 @@
|
||||
```{include} ../CHANGELOG.md
|
||||
|
||||
```
|
||||
@@ -0,0 +1,78 @@
|
||||
# Configuration file for the Sphinx documentation builder.
|
||||
#
|
||||
# This file only contains a selection of the most common options. For a full
|
||||
# list see the documentation:
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from sphinx.application import Sphinx
|
||||
from sphinx.ext import apidoc
|
||||
|
||||
# -- Project information -----------------------------------------------------
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html#project-information
|
||||
|
||||
project = "SoftVC VITS Singing Voice Conversion Fork"
|
||||
copyright = "2023, 34j"
|
||||
author = "34j"
|
||||
release = "0.0.0"
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html#general-configuration
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"myst_parser",
|
||||
"sphinx.ext.napoleon",
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.viewcode",
|
||||
]
|
||||
napoleon_google_docstring = False
|
||||
|
||||
# The suffix of source filenames.
|
||||
source_suffix = [".rst", ".md"]
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
# This pattern also affects html_static_path and html_extra_path.
|
||||
exclude_patterns: list[str] = []
|
||||
|
||||
|
||||
# -- Options for HTML output -------------------------------------------------
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
#
|
||||
html_theme = "sphinx_rtd_theme"
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
|
||||
|
||||
# -- Automatically run sphinx-apidoc -----------------------------------------
|
||||
|
||||
|
||||
def run_apidoc(_: Any) -> None:
|
||||
docs_path = Path(__file__).parent
|
||||
module_path = docs_path.parent / "src" / "so_vits_svc_fork"
|
||||
|
||||
apidoc.main(
|
||||
[
|
||||
"--force",
|
||||
"--module-first",
|
||||
"-o",
|
||||
docs_path.as_posix(),
|
||||
module_path.as_posix(),
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
def setup(app: Sphinx) -> None:
|
||||
app.connect("builder-inited", run_apidoc)
|
||||
@@ -0,0 +1,28 @@
|
||||
# Welcome to SoftVC VITS Singing Voice Conversion Fork documentation!
|
||||
|
||||
```{toctree}
|
||||
:caption: Installation & Usage
|
||||
:maxdepth: 2
|
||||
|
||||
installation
|
||||
usage
|
||||
```
|
||||
|
||||
```{toctree}
|
||||
:caption: Project Info
|
||||
:maxdepth: 2
|
||||
|
||||
changelog
|
||||
contributing
|
||||
```
|
||||
|
||||
```{toctree}
|
||||
:caption: API Reference
|
||||
:maxdepth: 2
|
||||
|
||||
so_vits_svc_fork
|
||||
```
|
||||
|
||||
```{include} ../README.md
|
||||
|
||||
```
|
||||
@@ -0,0 +1,7 @@
|
||||
# Installation
|
||||
|
||||
The package is published on [PyPI](https://pypi.org/project/so-vits-svc-fork/) and can be installed with `pip` (or any equivalent):
|
||||
|
||||
```bash
|
||||
pip install so-vits-svc-fork
|
||||
```
|
||||
@@ -0,0 +1,35 @@
|
||||
@ECHO OFF
|
||||
|
||||
pushd %~dp0
|
||||
|
||||
REM Command file for Sphinx documentation
|
||||
|
||||
if "%SPHINXBUILD%" == "" (
|
||||
set SPHINXBUILD=sphinx-build
|
||||
)
|
||||
set SOURCEDIR=.
|
||||
set BUILDDIR=_build
|
||||
|
||||
%SPHINXBUILD% >NUL 2>NUL
|
||||
if errorlevel 9009 (
|
||||
echo.
|
||||
echo.The 'sphinx-build' command was not found. Make sure you have Sphinx
|
||||
echo.installed, then set the SPHINXBUILD environment variable to point
|
||||
echo.to the full path of the 'sphinx-build' executable. Alternatively you
|
||||
echo.may add the Sphinx directory to PATH.
|
||||
echo.
|
||||
echo.If you don't have Sphinx installed, grab it from
|
||||
echo.https://www.sphinx-doc.org/
|
||||
exit /b 1
|
||||
)
|
||||
|
||||
if "%1" == "" goto help
|
||||
|
||||
%SPHINXBUILD% -M %1 %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
|
||||
goto end
|
||||
|
||||
:help
|
||||
%SPHINXBUILD% -M help %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
|
||||
|
||||
:end
|
||||
popd
|
||||
@@ -0,0 +1,9 @@
|
||||
# Usage
|
||||
|
||||
To use this package, import it:
|
||||
|
||||
```python
|
||||
import so_vits_svc_fork
|
||||
```
|
||||
|
||||
TODO: Document usage
|
||||
@@ -1,20 +0,0 @@
|
||||
name: sovits
|
||||
channels:
|
||||
- pytorch
|
||||
- nvidia
|
||||
- conda-forge
|
||||
- fvcore
|
||||
- iopath
|
||||
- bottler
|
||||
- defaults
|
||||
dependencies:
|
||||
- python=3.8
|
||||
- pytorch
|
||||
- torchvision
|
||||
- fvcore
|
||||
- iopath
|
||||
- nvidiacub
|
||||
- pyembree
|
||||
- cupy
|
||||
- cython
|
||||
- pip
|
||||
@@ -1,56 +0,0 @@
|
||||
import io
|
||||
import logging
|
||||
|
||||
import soundfile
|
||||
import torch
|
||||
import torchaudio
|
||||
from flask import Flask, request, send_file
|
||||
from flask_cors import CORS
|
||||
|
||||
from inference.infer_tool import Svc, RealTimeVC
|
||||
|
||||
app = Flask(__name__)
|
||||
|
||||
CORS(app)
|
||||
|
||||
logging.getLogger('numba').setLevel(logging.WARNING)
|
||||
|
||||
|
||||
@app.route("/voiceChangeModel", methods=["POST"])
|
||||
def voice_change_model():
|
||||
request_form = request.form
|
||||
wave_file = request.files.get("sample", None)
|
||||
# 变调信息
|
||||
f_pitch_change = float(request_form.get("fPitchChange", 0))
|
||||
# DAW所需的采样率
|
||||
daw_sample = int(float(request_form.get("sampleRate", 0)))
|
||||
speaker_id = int(float(request_form.get("sSpeakId", 0)))
|
||||
# http获得wav文件并转换
|
||||
input_wav_path = io.BytesIO(wave_file.read())
|
||||
|
||||
# 模型推理
|
||||
if raw_infer:
|
||||
out_audio, out_sr = svc_model.infer(speaker_id, f_pitch_change, input_wav_path)
|
||||
tar_audio = torchaudio.functional.resample(out_audio, svc_model.target_sample, daw_sample)
|
||||
else:
|
||||
out_audio = svc.process(svc_model, speaker_id, f_pitch_change, input_wav_path)
|
||||
tar_audio = torchaudio.functional.resample(torch.from_numpy(out_audio), svc_model.target_sample, daw_sample)
|
||||
# 返回音频
|
||||
out_wav_path = io.BytesIO()
|
||||
soundfile.write(out_wav_path, tar_audio.cpu().numpy(), daw_sample, format="wav")
|
||||
out_wav_path.seek(0)
|
||||
return send_file(out_wav_path, download_name="temp.wav", as_attachment=True)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
# 启用则为直接切片合成,False为交叉淡化方式
|
||||
# vst插件调整0.3-0.5s切片时间可以降低延迟,直接切片方法会有连接处爆音、交叉淡化会有轻微重叠声音
|
||||
# 自行选择能接受的方法,或将vst最大切片时间调整为1s,此处设为Ture,延迟大音质稳定一些
|
||||
raw_infer = True
|
||||
# 每个模型和config是唯一对应的
|
||||
model_name = "logs/32k/G_174000-Copy1.pth"
|
||||
config_name = "configs/config.json"
|
||||
svc_model = Svc(model_name, config_name)
|
||||
svc = RealTimeVC()
|
||||
# 此处与vst插件对应,不建议更改
|
||||
app.run(port=6842, host="0.0.0.0", debug=False, threaded=False)
|
||||
@@ -1,244 +0,0 @@
|
||||
import hashlib
|
||||
import io
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import time
|
||||
from pathlib import Path
|
||||
from inference import slicer
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
# import onnxruntime
|
||||
import parselmouth
|
||||
import soundfile
|
||||
import torch
|
||||
import torchaudio
|
||||
|
||||
import cluster
|
||||
from hubert import hubert_model
|
||||
import utils
|
||||
from models import SynthesizerTrn
|
||||
|
||||
logging.getLogger('matplotlib').setLevel(logging.WARNING)
|
||||
|
||||
|
||||
def read_temp(file_name):
|
||||
if not os.path.exists(file_name):
|
||||
with open(file_name, "w") as f:
|
||||
f.write(json.dumps({"info": "temp_dict"}))
|
||||
return {}
|
||||
else:
|
||||
try:
|
||||
with open(file_name, "r") as f:
|
||||
data = f.read()
|
||||
data_dict = json.loads(data)
|
||||
if os.path.getsize(file_name) > 50 * 1024 * 1024:
|
||||
f_name = file_name.replace("\\", "/").split("/")[-1]
|
||||
print(f"clean {f_name}")
|
||||
for wav_hash in list(data_dict.keys()):
|
||||
if int(time.time()) - int(data_dict[wav_hash]["time"]) > 14 * 24 * 3600:
|
||||
del data_dict[wav_hash]
|
||||
except Exception as e:
|
||||
print(e)
|
||||
print(f"{file_name} error,auto rebuild file")
|
||||
data_dict = {"info": "temp_dict"}
|
||||
return data_dict
|
||||
|
||||
|
||||
def write_temp(file_name, data):
|
||||
with open(file_name, "w") as f:
|
||||
f.write(json.dumps(data))
|
||||
|
||||
|
||||
def timeit(func):
|
||||
def run(*args, **kwargs):
|
||||
t = time.time()
|
||||
res = func(*args, **kwargs)
|
||||
print('executing \'%s\' costed %.3fs' % (func.__name__, time.time() - t))
|
||||
return res
|
||||
|
||||
return run
|
||||
|
||||
|
||||
def format_wav(audio_path):
|
||||
if Path(audio_path).suffix == '.wav':
|
||||
return
|
||||
raw_audio, raw_sample_rate = librosa.load(audio_path, mono=True, sr=None)
|
||||
soundfile.write(Path(audio_path).with_suffix(".wav"), raw_audio, raw_sample_rate)
|
||||
|
||||
|
||||
def get_end_file(dir_path, end):
|
||||
file_lists = []
|
||||
for root, dirs, files in os.walk(dir_path):
|
||||
files = [f for f in files if f[0] != '.']
|
||||
dirs[:] = [d for d in dirs if d[0] != '.']
|
||||
for f_file in files:
|
||||
if f_file.endswith(end):
|
||||
file_lists.append(os.path.join(root, f_file).replace("\\", "/"))
|
||||
return file_lists
|
||||
|
||||
|
||||
def get_md5(content):
|
||||
return hashlib.new("md5", content).hexdigest()
|
||||
|
||||
def fill_a_to_b(a, b):
|
||||
if len(a) < len(b):
|
||||
for _ in range(0, len(b) - len(a)):
|
||||
a.append(a[0])
|
||||
|
||||
def mkdir(paths: list):
|
||||
for path in paths:
|
||||
if not os.path.exists(path):
|
||||
os.mkdir(path)
|
||||
|
||||
def pad_array(arr, target_length):
|
||||
current_length = arr.shape[0]
|
||||
if current_length >= target_length:
|
||||
return arr
|
||||
else:
|
||||
pad_width = target_length - current_length
|
||||
pad_left = pad_width // 2
|
||||
pad_right = pad_width - pad_left
|
||||
padded_arr = np.pad(arr, (pad_left, pad_right), 'constant', constant_values=(0, 0))
|
||||
return padded_arr
|
||||
|
||||
|
||||
class Svc(object):
|
||||
def __init__(self, net_g_path, config_path,
|
||||
device=None,
|
||||
cluster_model_path="logs/44k/kmeans_10000.pt"):
|
||||
self.net_g_path = net_g_path
|
||||
if device is None:
|
||||
self.dev = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
||||
else:
|
||||
self.dev = torch.device(device)
|
||||
self.net_g_ms = None
|
||||
self.hps_ms = utils.get_hparams_from_file(config_path)
|
||||
self.target_sample = self.hps_ms.data.sampling_rate
|
||||
self.hop_size = self.hps_ms.data.hop_length
|
||||
self.spk2id = self.hps_ms.spk
|
||||
# 加载hubert
|
||||
self.hubert_model = utils.get_hubert_model().to(self.dev)
|
||||
self.load_model()
|
||||
if os.path.exists(cluster_model_path):
|
||||
self.cluster_model = cluster.get_cluster_model(cluster_model_path)
|
||||
|
||||
def load_model(self):
|
||||
# 获取模型配置
|
||||
self.net_g_ms = SynthesizerTrn(
|
||||
self.hps_ms.data.filter_length // 2 + 1,
|
||||
self.hps_ms.train.segment_size // self.hps_ms.data.hop_length,
|
||||
**self.hps_ms.model)
|
||||
_ = utils.load_checkpoint(self.net_g_path, self.net_g_ms, None)
|
||||
if "half" in self.net_g_path and torch.cuda.is_available():
|
||||
_ = self.net_g_ms.half().eval().to(self.dev)
|
||||
else:
|
||||
_ = self.net_g_ms.eval().to(self.dev)
|
||||
|
||||
|
||||
|
||||
def get_unit_f0(self, in_path, tran, cluster_infer_ratio, speaker):
|
||||
|
||||
wav, sr = librosa.load(in_path, sr=self.target_sample)
|
||||
|
||||
f0 = utils.compute_f0_parselmouth(wav, sampling_rate=self.target_sample, hop_length=self.hop_size)
|
||||
f0, uv = utils.interpolate_f0(f0)
|
||||
f0 = torch.FloatTensor(f0)
|
||||
uv = torch.FloatTensor(uv)
|
||||
f0 = f0 * 2 ** (tran / 12)
|
||||
f0 = f0.unsqueeze(0).to(self.dev)
|
||||
uv = uv.unsqueeze(0).to(self.dev)
|
||||
|
||||
wav16k = librosa.resample(wav, orig_sr=self.target_sample, target_sr=16000)
|
||||
wav16k = torch.from_numpy(wav16k).to(self.dev)
|
||||
c = utils.get_hubert_content(self.hubert_model, wav_16k_tensor=wav16k)
|
||||
c = utils.repeat_expand_2d(c.squeeze(0), f0.shape[1])
|
||||
|
||||
if cluster_infer_ratio !=0:
|
||||
cluster_c = cluster.get_cluster_center_result(self.cluster_model, c.cpu().numpy().T, speaker).T
|
||||
cluster_c = torch.FloatTensor(cluster_c).to(self.dev)
|
||||
c = cluster_infer_ratio * cluster_c + (1 - cluster_infer_ratio) * c
|
||||
|
||||
c = c.unsqueeze(0)
|
||||
return c, f0, uv
|
||||
|
||||
def infer(self, speaker, tran, raw_path,
|
||||
cluster_infer_ratio=0,
|
||||
auto_predict_f0=False,
|
||||
noice_scale=0.4):
|
||||
speaker_id = self.spk2id[speaker]
|
||||
sid = torch.LongTensor([int(speaker_id)]).to(self.dev).unsqueeze(0)
|
||||
c, f0, uv = self.get_unit_f0(raw_path, tran, cluster_infer_ratio, speaker)
|
||||
if "half" in self.net_g_path and torch.cuda.is_available():
|
||||
c = c.half()
|
||||
with torch.no_grad():
|
||||
start = time.time()
|
||||
audio = self.net_g_ms.infer(c, f0=f0, g=sid, uv=uv, predict_f0=auto_predict_f0, noice_scale=noice_scale)[0,0].data.float()
|
||||
use_time = time.time() - start
|
||||
print("vits use time:{}".format(use_time))
|
||||
return audio, audio.shape[-1]
|
||||
|
||||
def slice_inference(self,raw_audio_path, spk, tran, slice_db,cluster_infer_ratio, auto_predict_f0,noice_scale, pad_seconds=0.5):
|
||||
wav_path = raw_audio_path
|
||||
chunks = slicer.cut(wav_path, db_thresh=slice_db)
|
||||
audio_data, audio_sr = slicer.chunks2audio(wav_path, chunks)
|
||||
|
||||
audio = []
|
||||
for (slice_tag, data) in audio_data:
|
||||
print(f'#=====segment start, {round(len(data) / audio_sr, 3)}s======')
|
||||
# padd
|
||||
pad_len = int(audio_sr * pad_seconds)
|
||||
data = np.concatenate([np.zeros([pad_len]), data, np.zeros([pad_len])])
|
||||
length = int(np.ceil(len(data) / audio_sr * self.target_sample))
|
||||
raw_path = io.BytesIO()
|
||||
soundfile.write(raw_path, data, audio_sr, format="wav")
|
||||
raw_path.seek(0)
|
||||
if slice_tag:
|
||||
print('jump empty segment')
|
||||
_audio = np.zeros(length)
|
||||
else:
|
||||
out_audio, out_sr = self.infer(spk, tran, raw_path,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noice_scale=noice_scale
|
||||
)
|
||||
_audio = out_audio.cpu().numpy()
|
||||
|
||||
pad_len = int(self.target_sample * pad_seconds)
|
||||
_audio = _audio[pad_len:-pad_len]
|
||||
audio.extend(list(_audio))
|
||||
return np.array(audio)
|
||||
|
||||
|
||||
class RealTimeVC:
|
||||
def __init__(self):
|
||||
self.last_chunk = None
|
||||
self.last_o = None
|
||||
self.chunk_len = 16000 # 区块长度
|
||||
self.pre_len = 3840 # 交叉淡化长度,640的倍数
|
||||
|
||||
"""输入输出都是1维numpy 音频波形数组"""
|
||||
|
||||
def process(self, svc_model, speaker_id, f_pitch_change, input_wav_path):
|
||||
import maad
|
||||
audio, sr = torchaudio.load(input_wav_path)
|
||||
audio = audio.cpu().numpy()[0]
|
||||
temp_wav = io.BytesIO()
|
||||
if self.last_chunk is None:
|
||||
input_wav_path.seek(0)
|
||||
audio, sr = svc_model.infer(speaker_id, f_pitch_change, input_wav_path)
|
||||
audio = audio.cpu().numpy()
|
||||
self.last_chunk = audio[-self.pre_len:]
|
||||
self.last_o = audio
|
||||
return audio[-self.chunk_len:]
|
||||
else:
|
||||
audio = np.concatenate([self.last_chunk, audio])
|
||||
soundfile.write(temp_wav, audio, sr, format="wav")
|
||||
temp_wav.seek(0)
|
||||
audio, sr = svc_model.infer(speaker_id, f_pitch_change, temp_wav)
|
||||
audio = audio.cpu().numpy()
|
||||
ret = maad.util.crossfade(self.last_o, audio, self.pre_len)
|
||||
self.last_chunk = audio[-self.pre_len:]
|
||||
self.last_o = audio
|
||||
return ret[self.chunk_len:2 * self.chunk_len]
|
||||
@@ -1,160 +0,0 @@
|
||||
import hashlib
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import time
|
||||
from pathlib import Path
|
||||
import io
|
||||
import librosa
|
||||
import maad
|
||||
import numpy as np
|
||||
from inference import slicer
|
||||
import parselmouth
|
||||
import soundfile
|
||||
import torch
|
||||
import torchaudio
|
||||
|
||||
from hubert import hubert_model
|
||||
import utils
|
||||
from models import SynthesizerTrn
|
||||
logging.getLogger('numba').setLevel(logging.WARNING)
|
||||
logging.getLogger('matplotlib').setLevel(logging.WARNING)
|
||||
|
||||
def resize2d_f0(x, target_len):
|
||||
source = np.array(x)
|
||||
source[source < 0.001] = np.nan
|
||||
target = np.interp(np.arange(0, len(source) * target_len, len(source)) / target_len, np.arange(0, len(source)),
|
||||
source)
|
||||
res = np.nan_to_num(target)
|
||||
return res
|
||||
|
||||
def get_f0(x, p_len,f0_up_key=0):
|
||||
|
||||
time_step = 160 / 16000 * 1000
|
||||
f0_min = 50
|
||||
f0_max = 1100
|
||||
f0_mel_min = 1127 * np.log(1 + f0_min / 700)
|
||||
f0_mel_max = 1127 * np.log(1 + f0_max / 700)
|
||||
|
||||
f0 = parselmouth.Sound(x, 16000).to_pitch_ac(
|
||||
time_step=time_step / 1000, voicing_threshold=0.6,
|
||||
pitch_floor=f0_min, pitch_ceiling=f0_max).selected_array['frequency']
|
||||
|
||||
pad_size=(p_len - len(f0) + 1) // 2
|
||||
if(pad_size>0 or p_len - len(f0) - pad_size>0):
|
||||
f0 = np.pad(f0,[[pad_size,p_len - len(f0) - pad_size]], mode='constant')
|
||||
|
||||
f0 *= pow(2, f0_up_key / 12)
|
||||
f0_mel = 1127 * np.log(1 + f0 / 700)
|
||||
f0_mel[f0_mel > 0] = (f0_mel[f0_mel > 0] - f0_mel_min) * 254 / (f0_mel_max - f0_mel_min) + 1
|
||||
f0_mel[f0_mel <= 1] = 1
|
||||
f0_mel[f0_mel > 255] = 255
|
||||
f0_coarse = np.rint(f0_mel).astype(np.int)
|
||||
return f0_coarse, f0
|
||||
|
||||
def clean_pitch(input_pitch):
|
||||
num_nan = np.sum(input_pitch == 1)
|
||||
if num_nan / len(input_pitch) > 0.9:
|
||||
input_pitch[input_pitch != 1] = 1
|
||||
return input_pitch
|
||||
|
||||
|
||||
def plt_pitch(input_pitch):
|
||||
input_pitch = input_pitch.astype(float)
|
||||
input_pitch[input_pitch == 1] = np.nan
|
||||
return input_pitch
|
||||
|
||||
|
||||
def f0_to_pitch(ff):
|
||||
f0_pitch = 69 + 12 * np.log2(ff / 440)
|
||||
return f0_pitch
|
||||
|
||||
|
||||
def fill_a_to_b(a, b):
|
||||
if len(a) < len(b):
|
||||
for _ in range(0, len(b) - len(a)):
|
||||
a.append(a[0])
|
||||
|
||||
|
||||
def mkdir(paths: list):
|
||||
for path in paths:
|
||||
if not os.path.exists(path):
|
||||
os.mkdir(path)
|
||||
|
||||
|
||||
class VitsSvc(object):
|
||||
def __init__(self):
|
||||
self.device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
||||
self.SVCVITS = None
|
||||
self.hps = None
|
||||
self.speakers = None
|
||||
self.hubert_soft = utils.get_hubert_model()
|
||||
|
||||
def set_device(self, device):
|
||||
self.device = torch.device(device)
|
||||
self.hubert_soft.to(self.device)
|
||||
if self.SVCVITS != None:
|
||||
self.SVCVITS.to(self.device)
|
||||
|
||||
def loadCheckpoint(self, path):
|
||||
self.hps = utils.get_hparams_from_file(f"checkpoints/{path}/config.json")
|
||||
self.SVCVITS = SynthesizerTrn(
|
||||
self.hps.data.filter_length // 2 + 1,
|
||||
self.hps.train.segment_size // self.hps.data.hop_length,
|
||||
**self.hps.model)
|
||||
_ = utils.load_checkpoint(f"checkpoints/{path}/model.pth", self.SVCVITS, None)
|
||||
_ = self.SVCVITS.eval().to(self.device)
|
||||
self.speakers = self.hps.spk
|
||||
|
||||
def get_units(self, source, sr):
|
||||
source = source.unsqueeze(0).to(self.device)
|
||||
with torch.inference_mode():
|
||||
units = self.hubert_soft.units(source)
|
||||
return units
|
||||
|
||||
|
||||
def get_unit_pitch(self, in_path, tran):
|
||||
source, sr = torchaudio.load(in_path)
|
||||
source = torchaudio.functional.resample(source, sr, 16000)
|
||||
if len(source.shape) == 2 and source.shape[1] >= 2:
|
||||
source = torch.mean(source, dim=0).unsqueeze(0)
|
||||
soft = self.get_units(source, sr).squeeze(0).cpu().numpy()
|
||||
f0_coarse, f0 = get_f0(source.cpu().numpy()[0], soft.shape[0]*2, tran)
|
||||
return soft, f0
|
||||
|
||||
def infer(self, speaker_id, tran, raw_path):
|
||||
speaker_id = self.speakers[speaker_id]
|
||||
sid = torch.LongTensor([int(speaker_id)]).to(self.device).unsqueeze(0)
|
||||
soft, pitch = self.get_unit_pitch(raw_path, tran)
|
||||
f0 = torch.FloatTensor(clean_pitch(pitch)).unsqueeze(0).to(self.device)
|
||||
stn_tst = torch.FloatTensor(soft)
|
||||
with torch.no_grad():
|
||||
x_tst = stn_tst.unsqueeze(0).to(self.device)
|
||||
x_tst = torch.repeat_interleave(x_tst, repeats=2, dim=1).transpose(1, 2)
|
||||
audio = self.SVCVITS.infer(x_tst, f0=f0, g=sid)[0,0].data.float()
|
||||
return audio, audio.shape[-1]
|
||||
|
||||
def inference(self,srcaudio,chara,tran,slice_db):
|
||||
sampling_rate, audio = srcaudio
|
||||
audio = (audio / np.iinfo(audio.dtype).max).astype(np.float32)
|
||||
if len(audio.shape) > 1:
|
||||
audio = librosa.to_mono(audio.transpose(1, 0))
|
||||
if sampling_rate != 16000:
|
||||
audio = librosa.resample(audio, orig_sr=sampling_rate, target_sr=16000)
|
||||
soundfile.write("tmpwav.wav", audio, 16000, format="wav")
|
||||
chunks = slicer.cut("tmpwav.wav", db_thresh=slice_db)
|
||||
audio_data, audio_sr = slicer.chunks2audio("tmpwav.wav", chunks)
|
||||
audio = []
|
||||
for (slice_tag, data) in audio_data:
|
||||
length = int(np.ceil(len(data) / audio_sr * self.hps.data.sampling_rate))
|
||||
raw_path = io.BytesIO()
|
||||
soundfile.write(raw_path, data, audio_sr, format="wav")
|
||||
raw_path.seek(0)
|
||||
if slice_tag:
|
||||
_audio = np.zeros(length)
|
||||
else:
|
||||
out_audio, out_sr = self.infer(chara, tran, raw_path)
|
||||
_audio = out_audio.cpu().numpy()
|
||||
audio.extend(list(_audio))
|
||||
audio = (np.array(audio) * 32768.0).astype('int16')
|
||||
return (self.hps.data.sampling_rate,audio)
|
||||
@@ -1,142 +0,0 @@
|
||||
import librosa
|
||||
import torch
|
||||
import torchaudio
|
||||
|
||||
|
||||
class Slicer:
|
||||
def __init__(self,
|
||||
sr: int,
|
||||
threshold: float = -40.,
|
||||
min_length: int = 5000,
|
||||
min_interval: int = 300,
|
||||
hop_size: int = 20,
|
||||
max_sil_kept: int = 5000):
|
||||
if not min_length >= min_interval >= hop_size:
|
||||
raise ValueError('The following condition must be satisfied: min_length >= min_interval >= hop_size')
|
||||
if not max_sil_kept >= hop_size:
|
||||
raise ValueError('The following condition must be satisfied: max_sil_kept >= hop_size')
|
||||
min_interval = sr * min_interval / 1000
|
||||
self.threshold = 10 ** (threshold / 20.)
|
||||
self.hop_size = round(sr * hop_size / 1000)
|
||||
self.win_size = min(round(min_interval), 4 * self.hop_size)
|
||||
self.min_length = round(sr * min_length / 1000 / self.hop_size)
|
||||
self.min_interval = round(min_interval / self.hop_size)
|
||||
self.max_sil_kept = round(sr * max_sil_kept / 1000 / self.hop_size)
|
||||
|
||||
def _apply_slice(self, waveform, begin, end):
|
||||
if len(waveform.shape) > 1:
|
||||
return waveform[:, begin * self.hop_size: min(waveform.shape[1], end * self.hop_size)]
|
||||
else:
|
||||
return waveform[begin * self.hop_size: min(waveform.shape[0], end * self.hop_size)]
|
||||
|
||||
# @timeit
|
||||
def slice(self, waveform):
|
||||
if len(waveform.shape) > 1:
|
||||
samples = librosa.to_mono(waveform)
|
||||
else:
|
||||
samples = waveform
|
||||
if samples.shape[0] <= self.min_length:
|
||||
return {"0": {"slice": False, "split_time": f"0,{len(waveform)}"}}
|
||||
rms_list = librosa.feature.rms(y=samples, frame_length=self.win_size, hop_length=self.hop_size).squeeze(0)
|
||||
sil_tags = []
|
||||
silence_start = None
|
||||
clip_start = 0
|
||||
for i, rms in enumerate(rms_list):
|
||||
# Keep looping while frame is silent.
|
||||
if rms < self.threshold:
|
||||
# Record start of silent frames.
|
||||
if silence_start is None:
|
||||
silence_start = i
|
||||
continue
|
||||
# Keep looping while frame is not silent and silence start has not been recorded.
|
||||
if silence_start is None:
|
||||
continue
|
||||
# Clear recorded silence start if interval is not enough or clip is too short
|
||||
is_leading_silence = silence_start == 0 and i > self.max_sil_kept
|
||||
need_slice_middle = i - silence_start >= self.min_interval and i - clip_start >= self.min_length
|
||||
if not is_leading_silence and not need_slice_middle:
|
||||
silence_start = None
|
||||
continue
|
||||
# Need slicing. Record the range of silent frames to be removed.
|
||||
if i - silence_start <= self.max_sil_kept:
|
||||
pos = rms_list[silence_start: i + 1].argmin() + silence_start
|
||||
if silence_start == 0:
|
||||
sil_tags.append((0, pos))
|
||||
else:
|
||||
sil_tags.append((pos, pos))
|
||||
clip_start = pos
|
||||
elif i - silence_start <= self.max_sil_kept * 2:
|
||||
pos = rms_list[i - self.max_sil_kept: silence_start + self.max_sil_kept + 1].argmin()
|
||||
pos += i - self.max_sil_kept
|
||||
pos_l = rms_list[silence_start: silence_start + self.max_sil_kept + 1].argmin() + silence_start
|
||||
pos_r = rms_list[i - self.max_sil_kept: i + 1].argmin() + i - self.max_sil_kept
|
||||
if silence_start == 0:
|
||||
sil_tags.append((0, pos_r))
|
||||
clip_start = pos_r
|
||||
else:
|
||||
sil_tags.append((min(pos_l, pos), max(pos_r, pos)))
|
||||
clip_start = max(pos_r, pos)
|
||||
else:
|
||||
pos_l = rms_list[silence_start: silence_start + self.max_sil_kept + 1].argmin() + silence_start
|
||||
pos_r = rms_list[i - self.max_sil_kept: i + 1].argmin() + i - self.max_sil_kept
|
||||
if silence_start == 0:
|
||||
sil_tags.append((0, pos_r))
|
||||
else:
|
||||
sil_tags.append((pos_l, pos_r))
|
||||
clip_start = pos_r
|
||||
silence_start = None
|
||||
# Deal with trailing silence.
|
||||
total_frames = rms_list.shape[0]
|
||||
if silence_start is not None and total_frames - silence_start >= self.min_interval:
|
||||
silence_end = min(total_frames, silence_start + self.max_sil_kept)
|
||||
pos = rms_list[silence_start: silence_end + 1].argmin() + silence_start
|
||||
sil_tags.append((pos, total_frames + 1))
|
||||
# Apply and return slices.
|
||||
if len(sil_tags) == 0:
|
||||
return {"0": {"slice": False, "split_time": f"0,{len(waveform)}"}}
|
||||
else:
|
||||
chunks = []
|
||||
# 第一段静音并非从头开始,补上有声片段
|
||||
if sil_tags[0][0]:
|
||||
chunks.append(
|
||||
{"slice": False, "split_time": f"0,{min(waveform.shape[0], sil_tags[0][0] * self.hop_size)}"})
|
||||
for i in range(0, len(sil_tags)):
|
||||
# 标识有声片段(跳过第一段)
|
||||
if i:
|
||||
chunks.append({"slice": False,
|
||||
"split_time": f"{sil_tags[i - 1][1] * self.hop_size},{min(waveform.shape[0], sil_tags[i][0] * self.hop_size)}"})
|
||||
# 标识所有静音片段
|
||||
chunks.append({"slice": True,
|
||||
"split_time": f"{sil_tags[i][0] * self.hop_size},{min(waveform.shape[0], sil_tags[i][1] * self.hop_size)}"})
|
||||
# 最后一段静音并非结尾,补上结尾片段
|
||||
if sil_tags[-1][1] * self.hop_size < len(waveform):
|
||||
chunks.append({"slice": False, "split_time": f"{sil_tags[-1][1] * self.hop_size},{len(waveform)}"})
|
||||
chunk_dict = {}
|
||||
for i in range(len(chunks)):
|
||||
chunk_dict[str(i)] = chunks[i]
|
||||
return chunk_dict
|
||||
|
||||
|
||||
def cut(audio_path, db_thresh=-30, min_len=5000):
|
||||
audio, sr = librosa.load(audio_path, sr=None)
|
||||
slicer = Slicer(
|
||||
sr=sr,
|
||||
threshold=db_thresh,
|
||||
min_length=min_len
|
||||
)
|
||||
chunks = slicer.slice(audio)
|
||||
return chunks
|
||||
|
||||
|
||||
def chunks2audio(audio_path, chunks):
|
||||
chunks = dict(chunks)
|
||||
audio, sr = torchaudio.load(audio_path)
|
||||
if len(audio.shape) == 2 and audio.shape[1] >= 2:
|
||||
audio = torch.mean(audio, dim=0).unsqueeze(0)
|
||||
audio = audio.cpu().numpy()[0]
|
||||
result = []
|
||||
for k, v in chunks.items():
|
||||
tag = v["split_time"].split(",")
|
||||
if tag[0] != tag[1]:
|
||||
result.append((v["slice"], audio[int(tag[0]):int(tag[1])]))
|
||||
return result, sr
|
||||
@@ -1,101 +0,0 @@
|
||||
import io
|
||||
import logging
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import librosa
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
import soundfile
|
||||
|
||||
from inference import infer_tool
|
||||
from inference import slicer
|
||||
from inference.infer_tool import Svc
|
||||
|
||||
logging.getLogger('numba').setLevel(logging.WARNING)
|
||||
chunks_dict = infer_tool.read_temp("inference/chunks_temp.json")
|
||||
|
||||
|
||||
|
||||
def main():
|
||||
import argparse
|
||||
|
||||
parser = argparse.ArgumentParser(description='sovits4 inference')
|
||||
|
||||
# 一定要设置的部分
|
||||
parser.add_argument('-m', '--model_path', type=str, default="logs/44k/G_0.pth", help='模型路径')
|
||||
parser.add_argument('-c', '--config_path', type=str, default="configs/config.json", help='配置文件路径')
|
||||
parser.add_argument('-n', '--clean_names', type=str, nargs='+', default=["君の知らない物語-src.wav"], help='wav文件名列表,放在raw文件夹下')
|
||||
parser.add_argument('-t', '--trans', type=int, nargs='+', default=[0], help='音高调整,支持正负(半音)')
|
||||
parser.add_argument('-s', '--spk_list', type=str, nargs='+', default=['nen'], help='合成目标说话人名称')
|
||||
|
||||
# 可选项部分
|
||||
parser.add_argument('-a', '--auto_predict_f0', action='store_true', default=False,
|
||||
help='语音转换自动预测音高,转换歌声时不要打开这个会严重跑调')
|
||||
parser.add_argument('-cm', '--cluster_model_path', type=str, default="logs/44k/kmeans_10000.pt", help='聚类模型路径,如果没有训练聚类则随便填')
|
||||
parser.add_argument('-cr', '--cluster_infer_ratio', type=float, default=0, help='聚类方案占比,范围0-1,若没有训练聚类模型则填0即可')
|
||||
|
||||
# 不用动的部分
|
||||
parser.add_argument('-sd', '--slice_db', type=int, default=-40, help='默认-40,嘈杂的音频可以-30,干声保留呼吸可以-50')
|
||||
parser.add_argument('-d', '--device', type=str, default=None, help='推理设备,None则为自动选择cpu和gpu')
|
||||
parser.add_argument('-ns', '--noice_scale', type=float, default=0.4, help='噪音级别,会影响咬字和音质,较为玄学')
|
||||
parser.add_argument('-p', '--pad_seconds', type=float, default=0.5, help='推理音频pad秒数,由于未知原因开头结尾会有异响,pad一小段静音段后就不会出现')
|
||||
parser.add_argument('-wf', '--wav_format', type=str, default='flac', help='音频输出格式')
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
svc_model = Svc(args.model_path, args.config_path, args.device, args.cluster_model_path)
|
||||
infer_tool.mkdir(["raw", "results"])
|
||||
clean_names = args.clean_names
|
||||
trans = args.trans
|
||||
spk_list = args.spk_list
|
||||
slice_db = args.slice_db
|
||||
wav_format = args.wav_format
|
||||
auto_predict_f0 = args.auto_predict_f0
|
||||
cluster_infer_ratio = args.cluster_infer_ratio
|
||||
noice_scale = args.noice_scale
|
||||
pad_seconds = args.pad_seconds
|
||||
|
||||
infer_tool.fill_a_to_b(trans, clean_names)
|
||||
for clean_name, tran in zip(clean_names, trans):
|
||||
raw_audio_path = f"raw/{clean_name}"
|
||||
if "." not in raw_audio_path:
|
||||
raw_audio_path += ".wav"
|
||||
infer_tool.format_wav(raw_audio_path)
|
||||
wav_path = Path(raw_audio_path).with_suffix('.wav')
|
||||
chunks = slicer.cut(wav_path, db_thresh=slice_db)
|
||||
audio_data, audio_sr = slicer.chunks2audio(wav_path, chunks)
|
||||
|
||||
for spk in spk_list:
|
||||
audio = []
|
||||
for (slice_tag, data) in audio_data:
|
||||
print(f'#=====segment start, {round(len(data) / audio_sr, 3)}s======')
|
||||
|
||||
length = int(np.ceil(len(data) / audio_sr * svc_model.target_sample))
|
||||
if slice_tag:
|
||||
print('jump empty segment')
|
||||
_audio = np.zeros(length)
|
||||
else:
|
||||
# padd
|
||||
pad_len = int(audio_sr * pad_seconds)
|
||||
data = np.concatenate([np.zeros([pad_len]), data, np.zeros([pad_len])])
|
||||
raw_path = io.BytesIO()
|
||||
soundfile.write(raw_path, data, audio_sr, format="wav")
|
||||
raw_path.seek(0)
|
||||
out_audio, out_sr = svc_model.infer(spk, tran, raw_path,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noice_scale=noice_scale
|
||||
)
|
||||
_audio = out_audio.cpu().numpy()
|
||||
pad_len = int(svc_model.target_sample * pad_seconds)
|
||||
_audio = _audio[pad_len:-pad_len]
|
||||
|
||||
audio.extend(list(infer_tool.pad_array(_audio, length)))
|
||||
key = "auto" if auto_predict_f0 else f"{tran}key"
|
||||
cluster_name = "" if cluster_infer_ratio == 0 else f"_{cluster_infer_ratio}"
|
||||
res_path = f'./results/{clean_name}_{key}_{spk}{cluster_name}.{wav_format}'
|
||||
soundfile.write(res_path, audio, svc_model.target_sample, format=wav_format)
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
@@ -1,420 +0,0 @@
|
||||
import copy
|
||||
import math
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
import modules.attentions as attentions
|
||||
import modules.commons as commons
|
||||
import modules.modules as modules
|
||||
|
||||
from torch.nn import Conv1d, ConvTranspose1d, AvgPool1d, Conv2d
|
||||
from torch.nn.utils import weight_norm, remove_weight_norm, spectral_norm
|
||||
|
||||
import utils
|
||||
from modules.commons import init_weights, get_padding
|
||||
from vdecoder.hifigan.models import Generator
|
||||
from utils import f0_to_coarse
|
||||
|
||||
class ResidualCouplingBlock(nn.Module):
|
||||
def __init__(self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
n_flows=4,
|
||||
gin_channels=0):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.n_flows = n_flows
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.flows = nn.ModuleList()
|
||||
for i in range(n_flows):
|
||||
self.flows.append(modules.ResidualCouplingLayer(channels, hidden_channels, kernel_size, dilation_rate, n_layers, gin_channels=gin_channels, mean_only=True))
|
||||
self.flows.append(modules.Flip())
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
if not reverse:
|
||||
for flow in self.flows:
|
||||
x, _ = flow(x, x_mask, g=g, reverse=reverse)
|
||||
else:
|
||||
for flow in reversed(self.flows):
|
||||
x = flow(x, x_mask, g=g, reverse=reverse)
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.pre = nn.Conv1d(in_channels, hidden_channels, 1)
|
||||
self.enc = modules.WN(hidden_channels, kernel_size, dilation_rate, n_layers, gin_channels=gin_channels)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
|
||||
def forward(self, x, x_lengths, g=None):
|
||||
# print(x.shape,x_lengths.shape)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(x_lengths, x.size(2)), 1).to(x.dtype)
|
||||
x = self.pre(x) * x_mask
|
||||
x = self.enc(x, x_mask, g=g)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs)) * x_mask
|
||||
return z, m, logs, x_mask
|
||||
|
||||
|
||||
class TextEncoder(nn.Module):
|
||||
def __init__(self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
filter_channels=None,
|
||||
n_heads=None,
|
||||
p_dropout=None):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
self.f0_emb = nn.Embedding(256, hidden_channels)
|
||||
|
||||
self.enc_ = attentions.Encoder(
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout)
|
||||
|
||||
def forward(self, x, x_mask, f0=None, noice_scale=1):
|
||||
x = x + self.f0_emb(f0).transpose(1,2)
|
||||
x = self.enc_(x * x_mask, x_mask)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs) * noice_scale) * x_mask
|
||||
|
||||
return z, m, logs, x_mask
|
||||
|
||||
|
||||
|
||||
class DiscriminatorP(torch.nn.Module):
|
||||
def __init__(self, period, kernel_size=5, stride=3, use_spectral_norm=False):
|
||||
super(DiscriminatorP, self).__init__()
|
||||
self.period = period
|
||||
self.use_spectral_norm = use_spectral_norm
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv2d(1, 32, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(32, 128, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(128, 512, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(512, 1024, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(1024, 1024, (kernel_size, 1), 1, padding=(get_padding(kernel_size, 1), 0))),
|
||||
])
|
||||
self.conv_post = norm_f(Conv2d(1024, 1, (3, 1), 1, padding=(1, 0)))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
# 1d to 2d
|
||||
b, c, t = x.shape
|
||||
if t % self.period != 0: # pad first
|
||||
n_pad = self.period - (t % self.period)
|
||||
x = F.pad(x, (0, n_pad), "reflect")
|
||||
t = t + n_pad
|
||||
x = x.view(b, c, t // self.period, self.period)
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class DiscriminatorS(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super(DiscriminatorS, self).__init__()
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv1d(1, 16, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(16, 64, 41, 4, groups=4, padding=20)),
|
||||
norm_f(Conv1d(64, 256, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 1024, 41, 4, groups=64, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 4, groups=256, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
])
|
||||
self.conv_post = norm_f(Conv1d(1024, 1, 3, 1, padding=1))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class MultiPeriodDiscriminator(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super(MultiPeriodDiscriminator, self).__init__()
|
||||
periods = [2,3,5,7,11]
|
||||
|
||||
discs = [DiscriminatorS(use_spectral_norm=use_spectral_norm)]
|
||||
discs = discs + [DiscriminatorP(i, use_spectral_norm=use_spectral_norm) for i in periods]
|
||||
self.discriminators = nn.ModuleList(discs)
|
||||
|
||||
def forward(self, y, y_hat):
|
||||
y_d_rs = []
|
||||
y_d_gs = []
|
||||
fmap_rs = []
|
||||
fmap_gs = []
|
||||
for i, d in enumerate(self.discriminators):
|
||||
y_d_r, fmap_r = d(y)
|
||||
y_d_g, fmap_g = d(y_hat)
|
||||
y_d_rs.append(y_d_r)
|
||||
y_d_gs.append(y_d_g)
|
||||
fmap_rs.append(fmap_r)
|
||||
fmap_gs.append(fmap_g)
|
||||
|
||||
return y_d_rs, y_d_gs, fmap_rs, fmap_gs
|
||||
|
||||
|
||||
class SpeakerEncoder(torch.nn.Module):
|
||||
def __init__(self, mel_n_channels=80, model_num_layers=3, model_hidden_size=256, model_embedding_size=256):
|
||||
super(SpeakerEncoder, self).__init__()
|
||||
self.lstm = nn.LSTM(mel_n_channels, model_hidden_size, model_num_layers, batch_first=True)
|
||||
self.linear = nn.Linear(model_hidden_size, model_embedding_size)
|
||||
self.relu = nn.ReLU()
|
||||
|
||||
def forward(self, mels):
|
||||
self.lstm.flatten_parameters()
|
||||
_, (hidden, _) = self.lstm(mels)
|
||||
embeds_raw = self.relu(self.linear(hidden[-1]))
|
||||
return embeds_raw / torch.norm(embeds_raw, dim=1, keepdim=True)
|
||||
|
||||
def compute_partial_slices(self, total_frames, partial_frames, partial_hop):
|
||||
mel_slices = []
|
||||
for i in range(0, total_frames-partial_frames, partial_hop):
|
||||
mel_range = torch.arange(i, i+partial_frames)
|
||||
mel_slices.append(mel_range)
|
||||
|
||||
return mel_slices
|
||||
|
||||
def embed_utterance(self, mel, partial_frames=128, partial_hop=64):
|
||||
mel_len = mel.size(1)
|
||||
last_mel = mel[:,-partial_frames:]
|
||||
|
||||
if mel_len > partial_frames:
|
||||
mel_slices = self.compute_partial_slices(mel_len, partial_frames, partial_hop)
|
||||
mels = list(mel[:,s] for s in mel_slices)
|
||||
mels.append(last_mel)
|
||||
mels = torch.stack(tuple(mels), 0).squeeze(1)
|
||||
|
||||
with torch.no_grad():
|
||||
partial_embeds = self(mels)
|
||||
embed = torch.mean(partial_embeds, axis=0).unsqueeze(0)
|
||||
#embed = embed / torch.linalg.norm(embed, 2)
|
||||
else:
|
||||
with torch.no_grad():
|
||||
embed = self(last_mel)
|
||||
|
||||
return embed
|
||||
|
||||
class F0Decoder(nn.Module):
|
||||
def __init__(self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=0):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.spk_channels = spk_channels
|
||||
|
||||
self.prenet = nn.Conv1d(hidden_channels, hidden_channels, 3, padding=1)
|
||||
self.decoder = attentions.FFT(
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.f0_prenet = nn.Conv1d(1, hidden_channels , 3, padding=1)
|
||||
self.cond = nn.Conv1d(spk_channels, hidden_channels, 1)
|
||||
|
||||
def forward(self, x, norm_f0, x_mask, spk_emb=None):
|
||||
x = torch.detach(x)
|
||||
if (spk_emb is not None):
|
||||
x = x + self.cond(spk_emb)
|
||||
x += self.f0_prenet(norm_f0)
|
||||
x = self.prenet(x) * x_mask
|
||||
x = self.decoder(x * x_mask, x_mask)
|
||||
x = self.proj(x) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class SynthesizerTrn(nn.Module):
|
||||
"""
|
||||
Synthesizer for Training
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
spec_channels,
|
||||
segment_size,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gin_channels,
|
||||
ssl_dim,
|
||||
n_speakers,
|
||||
sampling_rate=44100,
|
||||
**kwargs):
|
||||
|
||||
super().__init__()
|
||||
self.spec_channels = spec_channels
|
||||
self.inter_channels = inter_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.resblock = resblock
|
||||
self.resblock_kernel_sizes = resblock_kernel_sizes
|
||||
self.resblock_dilation_sizes = resblock_dilation_sizes
|
||||
self.upsample_rates = upsample_rates
|
||||
self.upsample_initial_channel = upsample_initial_channel
|
||||
self.upsample_kernel_sizes = upsample_kernel_sizes
|
||||
self.segment_size = segment_size
|
||||
self.gin_channels = gin_channels
|
||||
self.ssl_dim = ssl_dim
|
||||
self.emb_g = nn.Embedding(n_speakers, gin_channels)
|
||||
|
||||
self.pre = nn.Conv1d(ssl_dim, hidden_channels, kernel_size=5, padding=2)
|
||||
|
||||
self.enc_p = TextEncoder(
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels=filter_channels,
|
||||
n_heads=n_heads,
|
||||
n_layers=n_layers,
|
||||
kernel_size=kernel_size,
|
||||
p_dropout=p_dropout
|
||||
)
|
||||
hps = {
|
||||
"sampling_rate": sampling_rate,
|
||||
"inter_channels": inter_channels,
|
||||
"resblock": resblock,
|
||||
"resblock_kernel_sizes": resblock_kernel_sizes,
|
||||
"resblock_dilation_sizes": resblock_dilation_sizes,
|
||||
"upsample_rates": upsample_rates,
|
||||
"upsample_initial_channel": upsample_initial_channel,
|
||||
"upsample_kernel_sizes": upsample_kernel_sizes,
|
||||
"gin_channels": gin_channels,
|
||||
}
|
||||
self.dec = Generator(h=hps)
|
||||
self.enc_q = Encoder(spec_channels, inter_channels, hidden_channels, 5, 1, 16, gin_channels=gin_channels)
|
||||
self.flow = ResidualCouplingBlock(inter_channels, hidden_channels, 5, 1, 4, gin_channels=gin_channels)
|
||||
self.f0_decoder = F0Decoder(
|
||||
1,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=gin_channels
|
||||
)
|
||||
self.emb_uv = nn.Embedding(2, hidden_channels)
|
||||
|
||||
def forward(self, c, f0, uv, spec, g=None, c_lengths=None, spec_lengths=None):
|
||||
g = self.emb_g(g).transpose(1,2)
|
||||
# ssl prenet
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(c.dtype)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1,2)
|
||||
|
||||
# f0 predict
|
||||
lf0 = 2595. * torch.log10(1. + f0.unsqueeze(1) / 700.) / 500
|
||||
norm_lf0 = utils.normalize_f0(lf0, x_mask, uv)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
|
||||
# encoder
|
||||
z_ptemp, m_p, logs_p, _ = self.enc_p(x, x_mask, f0=f0_to_coarse(f0))
|
||||
z, m_q, logs_q, spec_mask = self.enc_q(spec, spec_lengths, g=g)
|
||||
|
||||
# flow
|
||||
z_p = self.flow(z, spec_mask, g=g)
|
||||
z_slice, pitch_slice, ids_slice = commons.rand_slice_segments_with_pitch(z, f0, spec_lengths, self.segment_size)
|
||||
|
||||
# nsf decoder
|
||||
o = self.dec(z_slice, g=g, f0=pitch_slice)
|
||||
|
||||
return o, ids_slice, spec_mask, (z, z_p, m_p, logs_p, m_q, logs_q), pred_lf0, norm_lf0, lf0
|
||||
|
||||
def infer(self, c, f0, uv, g=None, noice_scale=0.35, predict_f0=False):
|
||||
c_lengths = (torch.ones(c.size(0)) * c.size(-1)).to(c.device)
|
||||
g = self.emb_g(g).transpose(1,2)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(c.dtype)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1,2)
|
||||
|
||||
if predict_f0:
|
||||
lf0 = 2595. * torch.log10(1. + f0.unsqueeze(1) / 700.) / 500
|
||||
norm_lf0 = utils.normalize_f0(lf0, x_mask, uv, random_scale=False)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
f0 = (700 * (torch.pow(10, pred_lf0 * 500 / 2595) - 1)).squeeze(1)
|
||||
|
||||
z_p, m_p, logs_p, c_mask = self.enc_p(x, x_mask, f0=f0_to_coarse(f0), noice_scale=noice_scale)
|
||||
z = self.flow(z_p, c_mask, g=g, reverse=True)
|
||||
o = self.dec(z * c_mask, g=g, f0=f0)
|
||||
return o
|
||||
@@ -1,349 +0,0 @@
|
||||
import copy
|
||||
import math
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
import modules.commons as commons
|
||||
import modules.modules as modules
|
||||
from modules.modules import LayerNorm
|
||||
|
||||
|
||||
class FFT(nn.Module):
|
||||
def __init__(self, hidden_channels, filter_channels, n_heads, n_layers=1, kernel_size=1, p_dropout=0.,
|
||||
proximal_bias=False, proximal_init=True, **kwargs):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(
|
||||
MultiHeadAttention(hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout, proximal_bias=proximal_bias,
|
||||
proximal_init=proximal_init))
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(hidden_channels, hidden_channels, filter_channels, kernel_size, p_dropout=p_dropout, causal=True))
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(device=x.device, dtype=x.dtype)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(self, hidden_channels, filter_channels, n_heads, n_layers, kernel_size=1, p_dropout=0., window_size=4, **kwargs):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.attn_layers.append(MultiHeadAttention(hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout, window_size=window_size))
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(FFN(hidden_channels, hidden_channels, filter_channels, kernel_size, p_dropout=p_dropout))
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
attn_mask = x_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.attn_layers[i](x, x, attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Decoder(nn.Module):
|
||||
def __init__(self, hidden_channels, filter_channels, n_heads, n_layers, kernel_size=1, p_dropout=0., proximal_bias=False, proximal_init=True, **kwargs):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.encdec_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(MultiHeadAttention(hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout, proximal_bias=proximal_bias, proximal_init=proximal_init))
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.encdec_attn_layers.append(MultiHeadAttention(hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout))
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(FFN(hidden_channels, hidden_channels, filter_channels, kernel_size, p_dropout=p_dropout, causal=True))
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask, h, h_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(device=x.device, dtype=x.dtype)
|
||||
encdec_attn_mask = h_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.encdec_attn_layers[i](x, h, encdec_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class MultiHeadAttention(nn.Module):
|
||||
def __init__(self, channels, out_channels, n_heads, p_dropout=0., window_size=None, heads_share=True, block_length=None, proximal_bias=False, proximal_init=False):
|
||||
super().__init__()
|
||||
assert channels % n_heads == 0
|
||||
|
||||
self.channels = channels
|
||||
self.out_channels = out_channels
|
||||
self.n_heads = n_heads
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
self.heads_share = heads_share
|
||||
self.block_length = block_length
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
self.attn = None
|
||||
|
||||
self.k_channels = channels // n_heads
|
||||
self.conv_q = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_k = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_v = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_o = nn.Conv1d(channels, out_channels, 1)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if window_size is not None:
|
||||
n_heads_rel = 1 if heads_share else n_heads
|
||||
rel_stddev = self.k_channels**-0.5
|
||||
self.emb_rel_k = nn.Parameter(torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels) * rel_stddev)
|
||||
self.emb_rel_v = nn.Parameter(torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels) * rel_stddev)
|
||||
|
||||
nn.init.xavier_uniform_(self.conv_q.weight)
|
||||
nn.init.xavier_uniform_(self.conv_k.weight)
|
||||
nn.init.xavier_uniform_(self.conv_v.weight)
|
||||
if proximal_init:
|
||||
with torch.no_grad():
|
||||
self.conv_k.weight.copy_(self.conv_q.weight)
|
||||
self.conv_k.bias.copy_(self.conv_q.bias)
|
||||
|
||||
def forward(self, x, c, attn_mask=None):
|
||||
q = self.conv_q(x)
|
||||
k = self.conv_k(c)
|
||||
v = self.conv_v(c)
|
||||
|
||||
x, self.attn = self.attention(q, k, v, mask=attn_mask)
|
||||
|
||||
x = self.conv_o(x)
|
||||
return x
|
||||
|
||||
def attention(self, query, key, value, mask=None):
|
||||
# reshape [b, d, t] -> [b, n_h, t, d_k]
|
||||
b, d, t_s, t_t = (*key.size(), query.size(2))
|
||||
query = query.view(b, self.n_heads, self.k_channels, t_t).transpose(2, 3)
|
||||
key = key.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
value = value.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
|
||||
scores = torch.matmul(query / math.sqrt(self.k_channels), key.transpose(-2, -1))
|
||||
if self.window_size is not None:
|
||||
assert t_s == t_t, "Relative attention is only available for self-attention."
|
||||
key_relative_embeddings = self._get_relative_embeddings(self.emb_rel_k, t_s)
|
||||
rel_logits = self._matmul_with_relative_keys(query /math.sqrt(self.k_channels), key_relative_embeddings)
|
||||
scores_local = self._relative_position_to_absolute_position(rel_logits)
|
||||
scores = scores + scores_local
|
||||
if self.proximal_bias:
|
||||
assert t_s == t_t, "Proximal bias is only available for self-attention."
|
||||
scores = scores + self._attention_bias_proximal(t_s).to(device=scores.device, dtype=scores.dtype)
|
||||
if mask is not None:
|
||||
scores = scores.masked_fill(mask == 0, -1e4)
|
||||
if self.block_length is not None:
|
||||
assert t_s == t_t, "Local attention is only available for self-attention."
|
||||
block_mask = torch.ones_like(scores).triu(-self.block_length).tril(self.block_length)
|
||||
scores = scores.masked_fill(block_mask == 0, -1e4)
|
||||
p_attn = F.softmax(scores, dim=-1) # [b, n_h, t_t, t_s]
|
||||
p_attn = self.drop(p_attn)
|
||||
output = torch.matmul(p_attn, value)
|
||||
if self.window_size is not None:
|
||||
relative_weights = self._absolute_position_to_relative_position(p_attn)
|
||||
value_relative_embeddings = self._get_relative_embeddings(self.emb_rel_v, t_s)
|
||||
output = output + self._matmul_with_relative_values(relative_weights, value_relative_embeddings)
|
||||
output = output.transpose(2, 3).contiguous().view(b, d, t_t) # [b, n_h, t_t, d_k] -> [b, d, t_t]
|
||||
return output, p_attn
|
||||
|
||||
def _matmul_with_relative_values(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, m]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, d]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0))
|
||||
return ret
|
||||
|
||||
def _matmul_with_relative_keys(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, d]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, m]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0).transpose(-2, -1))
|
||||
return ret
|
||||
|
||||
def _get_relative_embeddings(self, relative_embeddings, length):
|
||||
max_relative_position = 2 * self.window_size + 1
|
||||
# Pad first before slice to avoid using cond ops.
|
||||
pad_length = max(length - (self.window_size + 1), 0)
|
||||
slice_start_position = max((self.window_size + 1) - length, 0)
|
||||
slice_end_position = slice_start_position + 2 * length - 1
|
||||
if pad_length > 0:
|
||||
padded_relative_embeddings = F.pad(
|
||||
relative_embeddings,
|
||||
commons.convert_pad_shape([[0, 0], [pad_length, pad_length], [0, 0]]))
|
||||
else:
|
||||
padded_relative_embeddings = relative_embeddings
|
||||
used_relative_embeddings = padded_relative_embeddings[:,slice_start_position:slice_end_position]
|
||||
return used_relative_embeddings
|
||||
|
||||
def _relative_position_to_absolute_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, 2*l-1]
|
||||
ret: [b, h, l, l]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# Concat columns of pad to shift from relative to absolute indexing.
|
||||
x = F.pad(x, commons.convert_pad_shape([[0,0],[0,0],[0,0],[0,1]]))
|
||||
|
||||
# Concat extra elements so to add up to shape (len+1, 2*len-1).
|
||||
x_flat = x.view([batch, heads, length * 2 * length])
|
||||
x_flat = F.pad(x_flat, commons.convert_pad_shape([[0,0],[0,0],[0,length-1]]))
|
||||
|
||||
# Reshape and slice out the padded elements.
|
||||
x_final = x_flat.view([batch, heads, length+1, 2*length-1])[:, :, :length, length-1:]
|
||||
return x_final
|
||||
|
||||
def _absolute_position_to_relative_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, l]
|
||||
ret: [b, h, l, 2*l-1]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# padd along column
|
||||
x = F.pad(x, commons.convert_pad_shape([[0, 0], [0, 0], [0, 0], [0, length-1]]))
|
||||
x_flat = x.view([batch, heads, length**2 + length*(length -1)])
|
||||
# add 0's in the beginning that will skew the elements after reshape
|
||||
x_flat = F.pad(x_flat, commons.convert_pad_shape([[0, 0], [0, 0], [length, 0]]))
|
||||
x_final = x_flat.view([batch, heads, length, 2*length])[:,:,:,1:]
|
||||
return x_final
|
||||
|
||||
def _attention_bias_proximal(self, length):
|
||||
"""Bias for self-attention to encourage attention to close positions.
|
||||
Args:
|
||||
length: an integer scalar.
|
||||
Returns:
|
||||
a Tensor with shape [1, 1, length, length]
|
||||
"""
|
||||
r = torch.arange(length, dtype=torch.float32)
|
||||
diff = torch.unsqueeze(r, 0) - torch.unsqueeze(r, 1)
|
||||
return torch.unsqueeze(torch.unsqueeze(-torch.log1p(torch.abs(diff)), 0), 0)
|
||||
|
||||
|
||||
class FFN(nn.Module):
|
||||
def __init__(self, in_channels, out_channels, filter_channels, kernel_size, p_dropout=0., activation=None, causal=False):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.activation = activation
|
||||
self.causal = causal
|
||||
|
||||
if causal:
|
||||
self.padding = self._causal_padding
|
||||
else:
|
||||
self.padding = self._same_padding
|
||||
|
||||
self.conv_1 = nn.Conv1d(in_channels, filter_channels, kernel_size)
|
||||
self.conv_2 = nn.Conv1d(filter_channels, out_channels, kernel_size)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x = self.conv_1(self.padding(x * x_mask))
|
||||
if self.activation == "gelu":
|
||||
x = x * torch.sigmoid(1.702 * x)
|
||||
else:
|
||||
x = torch.relu(x)
|
||||
x = self.drop(x)
|
||||
x = self.conv_2(self.padding(x * x_mask))
|
||||
return x * x_mask
|
||||
|
||||
def _causal_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = self.kernel_size - 1
|
||||
pad_r = 0
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
|
||||
def _same_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = (self.kernel_size - 1) // 2
|
||||
pad_r = self.kernel_size // 2
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
@@ -1,188 +0,0 @@
|
||||
import math
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
def slice_pitch_segments(x, ids_str, segment_size=4):
|
||||
ret = torch.zeros_like(x[:, :segment_size])
|
||||
for i in range(x.size(0)):
|
||||
idx_str = ids_str[i]
|
||||
idx_end = idx_str + segment_size
|
||||
ret[i] = x[i, idx_str:idx_end]
|
||||
return ret
|
||||
|
||||
def rand_slice_segments_with_pitch(x, pitch, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size + 1
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
ret_pitch = slice_pitch_segments(pitch, ids_str, segment_size)
|
||||
return ret, ret_pitch, ids_str
|
||||
|
||||
def init_weights(m, mean=0.0, std=0.01):
|
||||
classname = m.__class__.__name__
|
||||
if classname.find("Conv") != -1:
|
||||
m.weight.data.normal_(mean, std)
|
||||
|
||||
|
||||
def get_padding(kernel_size, dilation=1):
|
||||
return int((kernel_size*dilation - dilation)/2)
|
||||
|
||||
|
||||
def convert_pad_shape(pad_shape):
|
||||
l = pad_shape[::-1]
|
||||
pad_shape = [item for sublist in l for item in sublist]
|
||||
return pad_shape
|
||||
|
||||
|
||||
def intersperse(lst, item):
|
||||
result = [item] * (len(lst) * 2 + 1)
|
||||
result[1::2] = lst
|
||||
return result
|
||||
|
||||
|
||||
def kl_divergence(m_p, logs_p, m_q, logs_q):
|
||||
"""KL(P||Q)"""
|
||||
kl = (logs_q - logs_p) - 0.5
|
||||
kl += 0.5 * (torch.exp(2. * logs_p) + ((m_p - m_q)**2)) * torch.exp(-2. * logs_q)
|
||||
return kl
|
||||
|
||||
|
||||
def rand_gumbel(shape):
|
||||
"""Sample from the Gumbel distribution, protect from overflows."""
|
||||
uniform_samples = torch.rand(shape) * 0.99998 + 0.00001
|
||||
return -torch.log(-torch.log(uniform_samples))
|
||||
|
||||
|
||||
def rand_gumbel_like(x):
|
||||
g = rand_gumbel(x.size()).to(dtype=x.dtype, device=x.device)
|
||||
return g
|
||||
|
||||
|
||||
def slice_segments(x, ids_str, segment_size=4):
|
||||
ret = torch.zeros_like(x[:, :, :segment_size])
|
||||
for i in range(x.size(0)):
|
||||
idx_str = ids_str[i]
|
||||
idx_end = idx_str + segment_size
|
||||
ret[i] = x[i, :, idx_str:idx_end]
|
||||
return ret
|
||||
|
||||
|
||||
def rand_slice_segments(x, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size + 1
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
return ret, ids_str
|
||||
|
||||
|
||||
def rand_spec_segments(x, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
return ret, ids_str
|
||||
|
||||
|
||||
def get_timing_signal_1d(
|
||||
length, channels, min_timescale=1.0, max_timescale=1.0e4):
|
||||
position = torch.arange(length, dtype=torch.float)
|
||||
num_timescales = channels // 2
|
||||
log_timescale_increment = (
|
||||
math.log(float(max_timescale) / float(min_timescale)) /
|
||||
(num_timescales - 1))
|
||||
inv_timescales = min_timescale * torch.exp(
|
||||
torch.arange(num_timescales, dtype=torch.float) * -log_timescale_increment)
|
||||
scaled_time = position.unsqueeze(0) * inv_timescales.unsqueeze(1)
|
||||
signal = torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], 0)
|
||||
signal = F.pad(signal, [0, 0, 0, channels % 2])
|
||||
signal = signal.view(1, channels, length)
|
||||
return signal
|
||||
|
||||
|
||||
def add_timing_signal_1d(x, min_timescale=1.0, max_timescale=1.0e4):
|
||||
b, channels, length = x.size()
|
||||
signal = get_timing_signal_1d(length, channels, min_timescale, max_timescale)
|
||||
return x + signal.to(dtype=x.dtype, device=x.device)
|
||||
|
||||
|
||||
def cat_timing_signal_1d(x, min_timescale=1.0, max_timescale=1.0e4, axis=1):
|
||||
b, channels, length = x.size()
|
||||
signal = get_timing_signal_1d(length, channels, min_timescale, max_timescale)
|
||||
return torch.cat([x, signal.to(dtype=x.dtype, device=x.device)], axis)
|
||||
|
||||
|
||||
def subsequent_mask(length):
|
||||
mask = torch.tril(torch.ones(length, length)).unsqueeze(0).unsqueeze(0)
|
||||
return mask
|
||||
|
||||
|
||||
@torch.jit.script
|
||||
def fused_add_tanh_sigmoid_multiply(input_a, input_b, n_channels):
|
||||
n_channels_int = n_channels[0]
|
||||
in_act = input_a + input_b
|
||||
t_act = torch.tanh(in_act[:, :n_channels_int, :])
|
||||
s_act = torch.sigmoid(in_act[:, n_channels_int:, :])
|
||||
acts = t_act * s_act
|
||||
return acts
|
||||
|
||||
|
||||
def convert_pad_shape(pad_shape):
|
||||
l = pad_shape[::-1]
|
||||
pad_shape = [item for sublist in l for item in sublist]
|
||||
return pad_shape
|
||||
|
||||
|
||||
def shift_1d(x):
|
||||
x = F.pad(x, convert_pad_shape([[0, 0], [0, 0], [1, 0]]))[:, :, :-1]
|
||||
return x
|
||||
|
||||
|
||||
def sequence_mask(length, max_length=None):
|
||||
if max_length is None:
|
||||
max_length = length.max()
|
||||
x = torch.arange(max_length, dtype=length.dtype, device=length.device)
|
||||
return x.unsqueeze(0) < length.unsqueeze(1)
|
||||
|
||||
|
||||
def generate_path(duration, mask):
|
||||
"""
|
||||
duration: [b, 1, t_x]
|
||||
mask: [b, 1, t_y, t_x]
|
||||
"""
|
||||
device = duration.device
|
||||
|
||||
b, _, t_y, t_x = mask.shape
|
||||
cum_duration = torch.cumsum(duration, -1)
|
||||
|
||||
cum_duration_flat = cum_duration.view(b * t_x)
|
||||
path = sequence_mask(cum_duration_flat, t_y).to(mask.dtype)
|
||||
path = path.view(b, t_x, t_y)
|
||||
path = path - F.pad(path, convert_pad_shape([[0, 0], [1, 0], [0, 0]]))[:, :-1]
|
||||
path = path.unsqueeze(1).transpose(2,3) * mask
|
||||
return path
|
||||
|
||||
|
||||
def clip_grad_value_(parameters, clip_value, norm_type=2):
|
||||
if isinstance(parameters, torch.Tensor):
|
||||
parameters = [parameters]
|
||||
parameters = list(filter(lambda p: p.grad is not None, parameters))
|
||||
norm_type = float(norm_type)
|
||||
if clip_value is not None:
|
||||
clip_value = float(clip_value)
|
||||
|
||||
total_norm = 0
|
||||
for p in parameters:
|
||||
param_norm = p.grad.data.norm(norm_type)
|
||||
total_norm += param_norm.item() ** norm_type
|
||||
if clip_value is not None:
|
||||
p.grad.data.clamp_(min=-clip_value, max=clip_value)
|
||||
total_norm = total_norm ** (1. / norm_type)
|
||||
return total_norm
|
||||
@@ -1,61 +0,0 @@
|
||||
import torch
|
||||
from torch.nn import functional as F
|
||||
|
||||
import modules.commons as commons
|
||||
|
||||
|
||||
def feature_loss(fmap_r, fmap_g):
|
||||
loss = 0
|
||||
for dr, dg in zip(fmap_r, fmap_g):
|
||||
for rl, gl in zip(dr, dg):
|
||||
rl = rl.float().detach()
|
||||
gl = gl.float()
|
||||
loss += torch.mean(torch.abs(rl - gl))
|
||||
|
||||
return loss * 2
|
||||
|
||||
|
||||
def discriminator_loss(disc_real_outputs, disc_generated_outputs):
|
||||
loss = 0
|
||||
r_losses = []
|
||||
g_losses = []
|
||||
for dr, dg in zip(disc_real_outputs, disc_generated_outputs):
|
||||
dr = dr.float()
|
||||
dg = dg.float()
|
||||
r_loss = torch.mean((1-dr)**2)
|
||||
g_loss = torch.mean(dg**2)
|
||||
loss += (r_loss + g_loss)
|
||||
r_losses.append(r_loss.item())
|
||||
g_losses.append(g_loss.item())
|
||||
|
||||
return loss, r_losses, g_losses
|
||||
|
||||
|
||||
def generator_loss(disc_outputs):
|
||||
loss = 0
|
||||
gen_losses = []
|
||||
for dg in disc_outputs:
|
||||
dg = dg.float()
|
||||
l = torch.mean((1-dg)**2)
|
||||
gen_losses.append(l)
|
||||
loss += l
|
||||
|
||||
return loss, gen_losses
|
||||
|
||||
|
||||
def kl_loss(z_p, logs_q, m_p, logs_p, z_mask):
|
||||
"""
|
||||
z_p, logs_q: [b, h, t_t]
|
||||
m_p, logs_p: [b, h, t_t]
|
||||
"""
|
||||
z_p = z_p.float()
|
||||
logs_q = logs_q.float()
|
||||
m_p = m_p.float()
|
||||
logs_p = logs_p.float()
|
||||
z_mask = z_mask.float()
|
||||
#print(logs_p)
|
||||
kl = logs_p - logs_q - 0.5
|
||||
kl += 0.5 * ((z_p - m_p)**2) * torch.exp(-2. * logs_p)
|
||||
kl = torch.sum(kl * z_mask)
|
||||
l = kl / torch.sum(z_mask)
|
||||
return l
|
||||
@@ -1,112 +0,0 @@
|
||||
import math
|
||||
import os
|
||||
import random
|
||||
import torch
|
||||
from torch import nn
|
||||
import torch.nn.functional as F
|
||||
import torch.utils.data
|
||||
import numpy as np
|
||||
import librosa
|
||||
import librosa.util as librosa_util
|
||||
from librosa.util import normalize, pad_center, tiny
|
||||
from scipy.signal import get_window
|
||||
from scipy.io.wavfile import read
|
||||
from librosa.filters import mel as librosa_mel_fn
|
||||
|
||||
MAX_WAV_VALUE = 32768.0
|
||||
|
||||
|
||||
def dynamic_range_compression_torch(x, C=1, clip_val=1e-5):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor
|
||||
"""
|
||||
return torch.log(torch.clamp(x, min=clip_val) * C)
|
||||
|
||||
|
||||
def dynamic_range_decompression_torch(x, C=1):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor used to compress
|
||||
"""
|
||||
return torch.exp(x) / C
|
||||
|
||||
|
||||
def spectral_normalize_torch(magnitudes):
|
||||
output = dynamic_range_compression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
def spectral_de_normalize_torch(magnitudes):
|
||||
output = dynamic_range_decompression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
mel_basis = {}
|
||||
hann_window = {}
|
||||
|
||||
|
||||
def spectrogram_torch(y, n_fft, sampling_rate, hop_size, win_size, center=False):
|
||||
if torch.min(y) < -1.:
|
||||
print('min value is ', torch.min(y))
|
||||
if torch.max(y) > 1.:
|
||||
print('max value is ', torch.max(y))
|
||||
|
||||
global hann_window
|
||||
dtype_device = str(y.dtype) + '_' + str(y.device)
|
||||
wnsize_dtype_device = str(win_size) + '_' + dtype_device
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(dtype=y.dtype, device=y.device)
|
||||
|
||||
y = torch.nn.functional.pad(y.unsqueeze(1), (int((n_fft-hop_size)/2), int((n_fft-hop_size)/2)), mode='reflect')
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(y, n_fft, hop_length=hop_size, win_length=win_size, window=hann_window[wnsize_dtype_device],
|
||||
center=center, pad_mode='reflect', normalized=False, onesided=True, return_complex=False)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
return spec
|
||||
|
||||
|
||||
def spec_to_mel_torch(spec, n_fft, num_mels, sampling_rate, fmin, fmax):
|
||||
global mel_basis
|
||||
dtype_device = str(spec.dtype) + '_' + str(spec.device)
|
||||
fmax_dtype_device = str(fmax) + '_' + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(dtype=spec.dtype, device=spec.device)
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
return spec
|
||||
|
||||
|
||||
def mel_spectrogram_torch(y, n_fft, num_mels, sampling_rate, hop_size, win_size, fmin, fmax, center=False):
|
||||
if torch.min(y) < -1.:
|
||||
print('min value is ', torch.min(y))
|
||||
if torch.max(y) > 1.:
|
||||
print('max value is ', torch.max(y))
|
||||
|
||||
global mel_basis, hann_window
|
||||
dtype_device = str(y.dtype) + '_' + str(y.device)
|
||||
fmax_dtype_device = str(fmax) + '_' + dtype_device
|
||||
wnsize_dtype_device = str(win_size) + '_' + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(dtype=y.dtype, device=y.device)
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(dtype=y.dtype, device=y.device)
|
||||
|
||||
y = torch.nn.functional.pad(y.unsqueeze(1), (int((n_fft-hop_size)/2), int((n_fft-hop_size)/2)), mode='reflect')
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(y, n_fft, hop_length=hop_size, win_length=win_size, window=hann_window[wnsize_dtype_device],
|
||||
center=center, pad_mode='reflect', normalized=False, onesided=True, return_complex=False)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
|
||||
return spec
|
||||
@@ -1,342 +0,0 @@
|
||||
import copy
|
||||
import math
|
||||
import numpy as np
|
||||
import scipy
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
from torch.nn import Conv1d, ConvTranspose1d, AvgPool1d, Conv2d
|
||||
from torch.nn.utils import weight_norm, remove_weight_norm
|
||||
|
||||
import modules.commons as commons
|
||||
from modules.commons import init_weights, get_padding
|
||||
|
||||
|
||||
LRELU_SLOPE = 0.1
|
||||
|
||||
|
||||
class LayerNorm(nn.Module):
|
||||
def __init__(self, channels, eps=1e-5):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.eps = eps
|
||||
|
||||
self.gamma = nn.Parameter(torch.ones(channels))
|
||||
self.beta = nn.Parameter(torch.zeros(channels))
|
||||
|
||||
def forward(self, x):
|
||||
x = x.transpose(1, -1)
|
||||
x = F.layer_norm(x, (self.channels,), self.gamma, self.beta, self.eps)
|
||||
return x.transpose(1, -1)
|
||||
|
||||
|
||||
class ConvReluNorm(nn.Module):
|
||||
def __init__(self, in_channels, hidden_channels, out_channels, kernel_size, n_layers, p_dropout):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.out_channels = out_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
assert n_layers > 1, "Number of layers should be larger than 0."
|
||||
|
||||
self.conv_layers = nn.ModuleList()
|
||||
self.norm_layers = nn.ModuleList()
|
||||
self.conv_layers.append(nn.Conv1d(in_channels, hidden_channels, kernel_size, padding=kernel_size//2))
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.relu_drop = nn.Sequential(
|
||||
nn.ReLU(),
|
||||
nn.Dropout(p_dropout))
|
||||
for _ in range(n_layers-1):
|
||||
self.conv_layers.append(nn.Conv1d(hidden_channels, hidden_channels, kernel_size, padding=kernel_size//2))
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.proj.weight.data.zero_()
|
||||
self.proj.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x_org = x
|
||||
for i in range(self.n_layers):
|
||||
x = self.conv_layers[i](x * x_mask)
|
||||
x = self.norm_layers[i](x)
|
||||
x = self.relu_drop(x)
|
||||
x = x_org + self.proj(x)
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class DDSConv(nn.Module):
|
||||
"""
|
||||
Dialted and Depth-Separable Convolution
|
||||
"""
|
||||
def __init__(self, channels, kernel_size, n_layers, p_dropout=0.):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.convs_sep = nn.ModuleList()
|
||||
self.convs_1x1 = nn.ModuleList()
|
||||
self.norms_1 = nn.ModuleList()
|
||||
self.norms_2 = nn.ModuleList()
|
||||
for i in range(n_layers):
|
||||
dilation = kernel_size ** i
|
||||
padding = (kernel_size * dilation - dilation) // 2
|
||||
self.convs_sep.append(nn.Conv1d(channels, channels, kernel_size,
|
||||
groups=channels, dilation=dilation, padding=padding
|
||||
))
|
||||
self.convs_1x1.append(nn.Conv1d(channels, channels, 1))
|
||||
self.norms_1.append(LayerNorm(channels))
|
||||
self.norms_2.append(LayerNorm(channels))
|
||||
|
||||
def forward(self, x, x_mask, g=None):
|
||||
if g is not None:
|
||||
x = x + g
|
||||
for i in range(self.n_layers):
|
||||
y = self.convs_sep[i](x * x_mask)
|
||||
y = self.norms_1[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.convs_1x1[i](y)
|
||||
y = self.norms_2[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.drop(y)
|
||||
x = x + y
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class WN(torch.nn.Module):
|
||||
def __init__(self, hidden_channels, kernel_size, dilation_rate, n_layers, gin_channels=0, p_dropout=0):
|
||||
super(WN, self).__init__()
|
||||
assert(kernel_size % 2 == 1)
|
||||
self.hidden_channels =hidden_channels
|
||||
self.kernel_size = kernel_size,
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.in_layers = torch.nn.ModuleList()
|
||||
self.res_skip_layers = torch.nn.ModuleList()
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if gin_channels != 0:
|
||||
cond_layer = torch.nn.Conv1d(gin_channels, 2*hidden_channels*n_layers, 1)
|
||||
self.cond_layer = torch.nn.utils.weight_norm(cond_layer, name='weight')
|
||||
|
||||
for i in range(n_layers):
|
||||
dilation = dilation_rate ** i
|
||||
padding = int((kernel_size * dilation - dilation) / 2)
|
||||
in_layer = torch.nn.Conv1d(hidden_channels, 2*hidden_channels, kernel_size,
|
||||
dilation=dilation, padding=padding)
|
||||
in_layer = torch.nn.utils.weight_norm(in_layer, name='weight')
|
||||
self.in_layers.append(in_layer)
|
||||
|
||||
# last one is not necessary
|
||||
if i < n_layers - 1:
|
||||
res_skip_channels = 2 * hidden_channels
|
||||
else:
|
||||
res_skip_channels = hidden_channels
|
||||
|
||||
res_skip_layer = torch.nn.Conv1d(hidden_channels, res_skip_channels, 1)
|
||||
res_skip_layer = torch.nn.utils.weight_norm(res_skip_layer, name='weight')
|
||||
self.res_skip_layers.append(res_skip_layer)
|
||||
|
||||
def forward(self, x, x_mask, g=None, **kwargs):
|
||||
output = torch.zeros_like(x)
|
||||
n_channels_tensor = torch.IntTensor([self.hidden_channels])
|
||||
|
||||
if g is not None:
|
||||
g = self.cond_layer(g)
|
||||
|
||||
for i in range(self.n_layers):
|
||||
x_in = self.in_layers[i](x)
|
||||
if g is not None:
|
||||
cond_offset = i * 2 * self.hidden_channels
|
||||
g_l = g[:,cond_offset:cond_offset+2*self.hidden_channels,:]
|
||||
else:
|
||||
g_l = torch.zeros_like(x_in)
|
||||
|
||||
acts = commons.fused_add_tanh_sigmoid_multiply(
|
||||
x_in,
|
||||
g_l,
|
||||
n_channels_tensor)
|
||||
acts = self.drop(acts)
|
||||
|
||||
res_skip_acts = self.res_skip_layers[i](acts)
|
||||
if i < self.n_layers - 1:
|
||||
res_acts = res_skip_acts[:,:self.hidden_channels,:]
|
||||
x = (x + res_acts) * x_mask
|
||||
output = output + res_skip_acts[:,self.hidden_channels:,:]
|
||||
else:
|
||||
output = output + res_skip_acts
|
||||
return output * x_mask
|
||||
|
||||
def remove_weight_norm(self):
|
||||
if self.gin_channels != 0:
|
||||
torch.nn.utils.remove_weight_norm(self.cond_layer)
|
||||
for l in self.in_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
for l in self.res_skip_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock1(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5)):
|
||||
super(ResBlock1, self).__init__()
|
||||
self.convs1 = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[2],
|
||||
padding=get_padding(kernel_size, dilation[2])))
|
||||
])
|
||||
self.convs1.apply(init_weights)
|
||||
|
||||
self.convs2 = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1)))
|
||||
])
|
||||
self.convs2.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c1, c2 in zip(self.convs1, self.convs2):
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c1(xt)
|
||||
xt = F.leaky_relu(xt, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c2(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs1:
|
||||
remove_weight_norm(l)
|
||||
for l in self.convs2:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock2(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3)):
|
||||
super(ResBlock2, self).__init__()
|
||||
self.convs = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1])))
|
||||
])
|
||||
self.convs.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c in self.convs:
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class Log(nn.Module):
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = torch.log(torch.clamp_min(x, 1e-5)) * x_mask
|
||||
logdet = torch.sum(-y, [1, 2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = torch.exp(x) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Flip(nn.Module):
|
||||
def forward(self, x, *args, reverse=False, **kwargs):
|
||||
x = torch.flip(x, [1])
|
||||
if not reverse:
|
||||
logdet = torch.zeros(x.size(0)).to(dtype=x.dtype, device=x.device)
|
||||
return x, logdet
|
||||
else:
|
||||
return x
|
||||
|
||||
|
||||
class ElementwiseAffine(nn.Module):
|
||||
def __init__(self, channels):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.m = nn.Parameter(torch.zeros(channels,1))
|
||||
self.logs = nn.Parameter(torch.zeros(channels,1))
|
||||
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = self.m + torch.exp(self.logs) * x
|
||||
y = y * x_mask
|
||||
logdet = torch.sum(self.logs * x_mask, [1,2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = (x - self.m) * torch.exp(-self.logs) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class ResidualCouplingLayer(nn.Module):
|
||||
def __init__(self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
p_dropout=0,
|
||||
gin_channels=0,
|
||||
mean_only=False):
|
||||
assert channels % 2 == 0, "channels should be divisible by 2"
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.half_channels = channels // 2
|
||||
self.mean_only = mean_only
|
||||
|
||||
self.pre = nn.Conv1d(self.half_channels, hidden_channels, 1)
|
||||
self.enc = WN(hidden_channels, kernel_size, dilation_rate, n_layers, p_dropout=p_dropout, gin_channels=gin_channels)
|
||||
self.post = nn.Conv1d(hidden_channels, self.half_channels * (2 - mean_only), 1)
|
||||
self.post.weight.data.zero_()
|
||||
self.post.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
x0, x1 = torch.split(x, [self.half_channels]*2, 1)
|
||||
h = self.pre(x0) * x_mask
|
||||
h = self.enc(h, x_mask, g=g)
|
||||
stats = self.post(h) * x_mask
|
||||
if not self.mean_only:
|
||||
m, logs = torch.split(stats, [self.half_channels]*2, 1)
|
||||
else:
|
||||
m = stats
|
||||
logs = torch.zeros_like(m)
|
||||
|
||||
if not reverse:
|
||||
x1 = m + x1 * torch.exp(logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
logdet = torch.sum(logs, [1,2])
|
||||
return x, logdet
|
||||
else:
|
||||
x1 = (x1 - m) * torch.exp(-logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
return x
|
||||
@@ -0,0 +1,274 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Before training\n",
|
||||
"\n",
|
||||
"This program saves the last 3 generations of models to Google Drive. Since 1 generation of models is >1GB, you should have at least 3GB of free space in Google Drive. If you do not have such free space, it is recommended to create another Google Account.\n",
|
||||
"\n",
|
||||
"Training requires >10GB VRAM. (T4 should be enough) Inference does not require such a lot of VRAM."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Installation"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Check GPU\n",
|
||||
"!nvidia-smi"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Mount Google Drive\n",
|
||||
"from google.colab import drive\n",
|
||||
"drive.mount('/content/drive')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Install dependencies\n",
|
||||
"!python -m pip install -U pip wheel\n",
|
||||
"%pip install -U ipython \n",
|
||||
"\n",
|
||||
"#@markdown Branch (for development)\n",
|
||||
"BRANCH = \"none\" #@param {\"type\": \"string\"}\n",
|
||||
"if BRANCH == \"none\":\n",
|
||||
" %pip install -U so-vits-svc-fork\n",
|
||||
"else:\n",
|
||||
" %pip install -U git+https://github.com/34j/so-vits-svc-fork.git@{BRANCH}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Training"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Make dataset directory\n",
|
||||
"%cd ./content"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!mkdir -p \"dataset_raw\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#!rm -r \"dataset_raw\"\n",
|
||||
"#!rm -r \"dataset/44k\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Copy your dataset\n",
|
||||
"DATASET_NAME = \"kiritan\" #@param {type: \"string\"}\n",
|
||||
"!cp -R /content/drive/MyDrive/so-vits-svc-fork/dataset/{DATASET_NAME}/ -t \"dataset_raw/\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Download dataset (Tsukuyomi-chan JVS)\n",
|
||||
"#@markdown Make sure you agree to the license when using this dataset.\n",
|
||||
"# !wget https://tyc.rei-yumesaki.net/files/sozai-tyc-corpus1.zip\n",
|
||||
"# !unzip sozai-tyc-corpus1.zip\n",
|
||||
"# !mv \"/content/つくよみちゃんコーパス Vol.1 声優統計コーパス(JVSコーパス準拠)/おまけ:WAV(+12dB増幅&高音域削減)/WAV(+12dB増幅&高音域削減)\" \"dataset_raw/tsukuyomi\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Automatic preprocessing\n",
|
||||
"!svc pre-resample"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc pre-config"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Copy configs file\n",
|
||||
"!cp configs/44k/config.json drive/MyDrive/so-vits-svc-fork"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc pre-hubert"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Train\n",
|
||||
"%load_ext tensorboard\n",
|
||||
"%tensorboard --logdir drive/MyDrive/so-vits-svc-fork/logs/44k\n",
|
||||
"!svc train --model-path drive/MyDrive/so-vits-svc-fork/logs/44k"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Inference"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Get the author's voice as a source\n",
|
||||
"import random\n",
|
||||
"NAME = str(random.randint(1, 100))\n",
|
||||
"!wget -N \"https://github.com/34j/34j/raw/main/jvs-parallel100/{NAME}.wav\"\n",
|
||||
"from IPython.display import Audio, display\n",
|
||||
"display(Audio(f\"{NAME}.wav\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Use trained model\n",
|
||||
"!svc infer {NAME}.wav -m drive/MyDrive/so-vits-svc-fork/logs/44k/ -c drive/MyDrive/so-vits-svc-fork/logs/44k/config.json\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"attachments": {},
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Pretrained models"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/tree/main\n",
|
||||
"!wget -N \"https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/resolve/main/riri/G_riri_220.pth\"\n",
|
||||
"!wget -N \"https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/resolve/main/riri/config.json\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc infer {NAME}.wav -c config.json -m G_riri_220.pth\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title https://huggingface.co/therealvul/so-vits-svc-4.0/tree/main\n",
|
||||
"!wget -N \"https://huggingface.co/therealvul/so-vits-svc-4.0/resolve/main/Pinkie%20(speaking%20sep)/G_166400.pth\"\n",
|
||||
"!wget -N \"https://huggingface.co/therealvul/so-vits-svc-4.0/resolve/main/Pinkie%20(speaking%20sep)/config.json\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc infer {NAME}.wav --speaker \"Pinkie {neutral}\" -c config.json -m G_166400.pth\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"provenance": [
|
||||
{
|
||||
"file_id": "https://github.com/34j/so-vits-svc-fork/blob/feat%2Fmain-feat/so-vits-svc-fork-4.0.ipynb",
|
||||
"timestamp": 1678970434570
|
||||
}
|
||||
]
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -1,94 +0,0 @@
|
||||
import torch
|
||||
from torchaudio.models.wav2vec2.utils import import_fairseq_model
|
||||
from fairseq import checkpoint_utils
|
||||
from onnxexport.model_onnx import SynthesizerTrn
|
||||
import utils
|
||||
|
||||
def get_hubert_model():
|
||||
vec_path = "hubert/checkpoint_best_legacy_500.pt"
|
||||
print("load model(s) from {}".format(vec_path))
|
||||
models, saved_cfg, task = checkpoint_utils.load_model_ensemble_and_task(
|
||||
[vec_path],
|
||||
suffix="",
|
||||
)
|
||||
model = models[0]
|
||||
model.eval()
|
||||
return model
|
||||
|
||||
|
||||
def main(HubertExport, NetExport):
|
||||
path = "SoVits4.0"
|
||||
|
||||
'''if HubertExport:
|
||||
device = torch.device("cpu")
|
||||
vec_path = "hubert/checkpoint_best_legacy_500.pt"
|
||||
models, saved_cfg, task = checkpoint_utils.load_model_ensemble_and_task(
|
||||
[vec_path],
|
||||
suffix="",
|
||||
)
|
||||
original = models[0]
|
||||
original.eval()
|
||||
model = original
|
||||
test_input = torch.rand(1, 1, 16000)
|
||||
model(test_input)
|
||||
torch.onnx.export(model,
|
||||
test_input,
|
||||
"hubert4.0.onnx",
|
||||
export_params=True,
|
||||
opset_version=16,
|
||||
do_constant_folding=True,
|
||||
input_names=['source'],
|
||||
output_names=['embed'],
|
||||
dynamic_axes={
|
||||
'source':
|
||||
{
|
||||
2: "sample_length"
|
||||
},
|
||||
}
|
||||
)'''
|
||||
if NetExport:
|
||||
device = torch.device("cpu")
|
||||
hps = utils.get_hparams_from_file(f"checkpoints/{path}/config.json")
|
||||
SVCVITS = SynthesizerTrn(
|
||||
hps.data.filter_length // 2 + 1,
|
||||
hps.train.segment_size // hps.data.hop_length,
|
||||
**hps.model)
|
||||
_ = utils.load_checkpoint(f"checkpoints/{path}/model.pth", SVCVITS, None)
|
||||
_ = SVCVITS.eval().to(device)
|
||||
for i in SVCVITS.parameters():
|
||||
i.requires_grad = False
|
||||
test_hidden_unit = torch.rand(1, 10, 256)
|
||||
test_pitch = torch.rand(1, 10)
|
||||
test_mel2ph = torch.LongTensor([0, 1, 2, 3, 4, 5, 6, 7, 8, 9]).unsqueeze(0)
|
||||
test_uv = torch.ones(1, 10, dtype=torch.float32)
|
||||
test_noise = torch.randn(1, 192, 10)
|
||||
test_sid = torch.LongTensor([0])
|
||||
input_names = ["c", "f0", "mel2ph", "uv", "noise", "sid"]
|
||||
output_names = ["audio", ]
|
||||
SVCVITS.eval()
|
||||
torch.onnx.export(SVCVITS,
|
||||
(
|
||||
test_hidden_unit.to(device),
|
||||
test_pitch.to(device),
|
||||
test_mel2ph.to(device),
|
||||
test_uv.to(device),
|
||||
test_noise.to(device),
|
||||
test_sid.to(device)
|
||||
),
|
||||
f"checkpoints/{path}/model.onnx",
|
||||
dynamic_axes={
|
||||
"c": [0, 1],
|
||||
"f0": [1],
|
||||
"mel2ph": [1],
|
||||
"uv": [1],
|
||||
"noise": [2],
|
||||
},
|
||||
do_constant_folding=False,
|
||||
opset_version=16,
|
||||
verbose=False,
|
||||
input_names=input_names,
|
||||
output_names=output_names)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
main(False, True)
|
||||
Generated
+4897
File diff suppressed because it is too large
Load Diff
@@ -1,83 +0,0 @@
|
||||
import os
|
||||
import argparse
|
||||
import re
|
||||
|
||||
from tqdm import tqdm
|
||||
from random import shuffle
|
||||
import json
|
||||
import wave
|
||||
|
||||
config_template = json.load(open("configs/config.json"))
|
||||
|
||||
pattern = re.compile(r'^[\.a-zA-Z0-9_\/]+$')
|
||||
|
||||
def get_wav_duration(file_path):
|
||||
with wave.open(file_path, 'rb') as wav_file:
|
||||
# 获取音频帧数
|
||||
n_frames = wav_file.getnframes()
|
||||
# 获取采样率
|
||||
framerate = wav_file.getframerate()
|
||||
# 计算时长(秒)
|
||||
duration = n_frames / float(framerate)
|
||||
return duration
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--train_list", type=str, default="./filelists/train.txt", help="path to train list")
|
||||
parser.add_argument("--val_list", type=str, default="./filelists/val.txt", help="path to val list")
|
||||
parser.add_argument("--test_list", type=str, default="./filelists/test.txt", help="path to test list")
|
||||
parser.add_argument("--source_dir", type=str, default="./dataset/44k", help="path to source dir")
|
||||
args = parser.parse_args()
|
||||
|
||||
train = []
|
||||
val = []
|
||||
test = []
|
||||
idx = 0
|
||||
spk_dict = {}
|
||||
spk_id = 0
|
||||
for speaker in tqdm(os.listdir(args.source_dir)):
|
||||
spk_dict[speaker] = spk_id
|
||||
spk_id += 1
|
||||
wavs = ["/".join([args.source_dir, speaker, i]) for i in os.listdir(os.path.join(args.source_dir, speaker))]
|
||||
new_wavs = []
|
||||
for file in wavs:
|
||||
if not file.endswith("wav"):
|
||||
continue
|
||||
if not pattern.match(file):
|
||||
print(f"warning:文件名{file}中包含非字母数字下划线,可能会导致错误。(也可能不会)")
|
||||
if get_wav_duration(file) < 0.3:
|
||||
print("skip too short audio:", file)
|
||||
continue
|
||||
new_wavs.append(file)
|
||||
wavs = new_wavs
|
||||
shuffle(wavs)
|
||||
train += wavs[2:-2]
|
||||
val += wavs[:2]
|
||||
test += wavs[-2:]
|
||||
|
||||
shuffle(train)
|
||||
shuffle(val)
|
||||
shuffle(test)
|
||||
|
||||
print("Writing", args.train_list)
|
||||
with open(args.train_list, "w") as f:
|
||||
for fname in tqdm(train):
|
||||
wavpath = fname
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
print("Writing", args.val_list)
|
||||
with open(args.val_list, "w") as f:
|
||||
for fname in tqdm(val):
|
||||
wavpath = fname
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
print("Writing", args.test_list)
|
||||
with open(args.test_list, "w") as f:
|
||||
for fname in tqdm(test):
|
||||
wavpath = fname
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
config_template["spk"] = spk_dict
|
||||
print("Writing configs/config.json")
|
||||
with open("configs/config.json", "w") as f:
|
||||
json.dump(config_template, f, indent=2)
|
||||
@@ -1,62 +0,0 @@
|
||||
import math
|
||||
import multiprocessing
|
||||
import os
|
||||
import argparse
|
||||
from random import shuffle
|
||||
|
||||
import torch
|
||||
from glob import glob
|
||||
from tqdm import tqdm
|
||||
|
||||
import utils
|
||||
import logging
|
||||
logging.getLogger('numba').setLevel(logging.WARNING)
|
||||
import librosa
|
||||
import numpy as np
|
||||
|
||||
hps = utils.get_hparams_from_file("configs/config.json")
|
||||
sampling_rate = hps.data.sampling_rate
|
||||
hop_length = hps.data.hop_length
|
||||
|
||||
|
||||
def process_one(filename, hmodel):
|
||||
# print(filename)
|
||||
wav, sr = librosa.load(filename, sr=sampling_rate)
|
||||
soft_path = filename + ".soft.pt"
|
||||
if not os.path.exists(soft_path):
|
||||
devive = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
||||
wav16k = librosa.resample(wav, orig_sr=sampling_rate, target_sr=16000)
|
||||
wav16k = torch.from_numpy(wav16k).to(devive)
|
||||
c = utils.get_hubert_content(hmodel, wav_16k_tensor=wav16k)
|
||||
torch.save(c.cpu(), soft_path)
|
||||
f0_path = filename + ".f0.npy"
|
||||
if not os.path.exists(f0_path):
|
||||
f0 = utils.compute_f0_dio(wav, sampling_rate=sampling_rate, hop_length=hop_length)
|
||||
np.save(f0_path, f0)
|
||||
|
||||
|
||||
def process_batch(filenames):
|
||||
print("Loading hubert for content...")
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
hmodel = utils.get_hubert_model().to(device)
|
||||
print("Loaded hubert.")
|
||||
for filename in tqdm(filenames):
|
||||
process_one(filename, hmodel)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--in_dir", type=str, default="dataset/44k", help="path to input dir")
|
||||
|
||||
args = parser.parse_args()
|
||||
filenames = glob(f'{args.in_dir}/*/*.wav', recursive=True) # [:10]
|
||||
shuffle(filenames)
|
||||
multiprocessing.set_start_method('spawn',force=True)
|
||||
|
||||
num_processes = 1
|
||||
chunk_size = int(math.ceil(len(filenames) / num_processes))
|
||||
chunks = [filenames[i:i + chunk_size] for i in range(0, len(filenames), chunk_size)]
|
||||
print([len(c) for c in chunks])
|
||||
processes = [multiprocessing.Process(target=process_batch, args=(chunk,)) for chunk in chunks]
|
||||
for p in processes:
|
||||
p.start()
|
||||
@@ -0,0 +1,113 @@
|
||||
[tool.poetry]
|
||||
name = "so-vits-svc-fork"
|
||||
version = "1.2.3"
|
||||
description = "A fork of so-vits-svc."
|
||||
authors = ["34j <34j.95a2p@simplelogin.com>"]
|
||||
license = "MIT"
|
||||
readme = "README.md"
|
||||
repository = "https://github.com/34j/so-vits-svc-fork"
|
||||
documentation = "https://so-vits-svc-fork.readthedocs.io"
|
||||
classifiers = [
|
||||
"Development Status :: 2 - Pre-Alpha",
|
||||
"Intended Audience :: Developers",
|
||||
"Natural Language :: English",
|
||||
"Operating System :: OS Independent",
|
||||
"Topic :: Software Development :: Libraries",
|
||||
]
|
||||
packages = [
|
||||
{ include = "so_vits_svc_fork", from = "src" },
|
||||
]
|
||||
|
||||
[tool.poetry.scripts]
|
||||
so-vits-svc-fork = "so_vits_svc_fork.__main__:cli"
|
||||
svc = "so_vits_svc_fork.__main__:cli"
|
||||
svcf = "so_vits_svc_fork.__main__:cli"
|
||||
svcg = "so_vits_svc_fork.gui:main"
|
||||
svc-gui = "so_vits_svc_fork.gui:main"
|
||||
svcf-gui = "so_vits_svc_fork.gui:main"
|
||||
|
||||
[tool.poetry.urls]
|
||||
"Bug Tracker" = "https://github.com/34j/so-vits-svc-fork/issues"
|
||||
"Changelog" = "https://github.com/34j/so-vits-svc-fork/blob/main/CHANGELOG.md"
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
attrs="22.2.0"
|
||||
cm_time="0.1.2"
|
||||
fairseq="0.12.2"
|
||||
librosa="0.8.1"
|
||||
matplotlib="3.7.1"
|
||||
numba="0.56.4"
|
||||
numpy="1.23.5"
|
||||
onnx="1.13.1"
|
||||
onnxoptimizer="0.3.10"
|
||||
onnxsim="0.4.19"
|
||||
pyworld="0.2.12"
|
||||
resampy="0.4.2"
|
||||
scikit-learn="1.2.2"
|
||||
scipy="1.8.0"
|
||||
soundfile="0.12.1"
|
||||
tensorboard="2.12.0"
|
||||
torch="1.13.1"
|
||||
torchaudio="0.13.1"
|
||||
tqdm="4.65.0"
|
||||
click="8.1.3"
|
||||
pyinputplus="0.2.12"
|
||||
|
||||
[tool.semantic_release]
|
||||
branch = "main"
|
||||
version_toml = "pyproject.toml:tool.poetry.version"
|
||||
version_variable = "src/so_vits_svc_fork/__init__.py:__version__"
|
||||
build_command = "pip install poetry && poetry build"
|
||||
|
||||
[tool.pytest.ini_options]
|
||||
addopts = "-v -Wdefault --cov=so_vits_svc_fork --cov-report=term-missing:skip-covered"
|
||||
pythonpath = ["src"]
|
||||
|
||||
[tool.coverage.run]
|
||||
branch = true
|
||||
|
||||
[tool.coverage.report]
|
||||
exclude_lines = [
|
||||
"pragma: no cover",
|
||||
"@overload",
|
||||
"if TYPE_CHECKING",
|
||||
"raise NotImplementedError",
|
||||
'if __name__ == "__main__":',
|
||||
]
|
||||
|
||||
[tool.isort]
|
||||
profile = "black"
|
||||
known_first_party = ["so_vits_svc_fork", "tests"]
|
||||
|
||||
[tool.autoflake]
|
||||
remove_all_unused_imports = true
|
||||
|
||||
[tool.mypy]
|
||||
check_untyped_defs = true
|
||||
disallow_any_generics = true
|
||||
disallow_incomplete_defs = true
|
||||
disallow_untyped_defs = true
|
||||
mypy_path = "src/"
|
||||
no_implicit_optional = true
|
||||
show_error_codes = true
|
||||
warn_unreachable = true
|
||||
warn_unused_ignores = true
|
||||
exclude = [
|
||||
'docs/.*',
|
||||
'setup.py',
|
||||
]
|
||||
|
||||
[[tool.mypy.overrides]]
|
||||
module = "tests.*"
|
||||
allow_untyped_defs = true
|
||||
|
||||
[[tool.mypy.overrides]]
|
||||
module = "docs.*"
|
||||
ignore_errors = true
|
||||
|
||||
[tool.bandit]
|
||||
exclude_dirs = ["src"]
|
||||
|
||||
[build-system]
|
||||
requires = ["poetry-core>=1.0.0"]
|
||||
build-backend = "poetry.core.masonry.api"
|
||||
@@ -1,19 +1,21 @@
|
||||
Flask
|
||||
Flask_Cors
|
||||
gradio
|
||||
numpy
|
||||
#pyworld==0.2.5
|
||||
pyworld==0.2.12
|
||||
scipy==1.7.3
|
||||
SoundFile==0.12.1
|
||||
torch==1.13.1
|
||||
torchaudio==0.13.1
|
||||
tqdm
|
||||
scikit-maad
|
||||
praat-parselmouth
|
||||
onnx
|
||||
onnxsim
|
||||
onnxoptimizer
|
||||
cm_time==0.1.2
|
||||
attrs=22.2.0
|
||||
fairseq==0.12.2
|
||||
librosa==0.8.1
|
||||
tensorboard
|
||||
matplotlib==3.7.1
|
||||
numba==0.56.4
|
||||
numpy==1.23.5
|
||||
onnx==1.13.1
|
||||
onnxoptimizer==0.3.10
|
||||
onnxsim==0.4.19
|
||||
pyworld==0.2.12
|
||||
resampy==0.4.2
|
||||
scikit-learn==1.2.2
|
||||
scipy==1.8.0
|
||||
soundfile==0.12.1
|
||||
tensorboard==2.12.0
|
||||
torch==1.13.1
|
||||
torchaudio==0.13.1
|
||||
tqdm==4.65.0
|
||||
click==8.1.3
|
||||
pyinputplus==0.2.12
|
||||
|
||||
@@ -1,9 +0,0 @@
|
||||
numpy==1.20.3
|
||||
pyworld==0.2.5
|
||||
scipy==1.7.3
|
||||
SoundFile==0.12.1
|
||||
tqdm
|
||||
scikit-maad
|
||||
praat-parselmouth
|
||||
fairseq==0.12.2
|
||||
librosa==0.8.1
|
||||
@@ -1,23 +0,0 @@
|
||||
librosa==0.9.2
|
||||
fairseq==0.12.2
|
||||
Flask==2.1.2
|
||||
Flask_Cors==3.0.10
|
||||
gradio==3.4.1
|
||||
numpy==1.20.0
|
||||
playsound==1.3.0
|
||||
PyAudio==0.2.12
|
||||
pydub==0.25.1
|
||||
pyworld==0.3.0
|
||||
requests==2.28.1
|
||||
scipy==1.7.3
|
||||
sounddevice==0.4.5
|
||||
SoundFile==0.10.3.post1
|
||||
starlette==0.19.1
|
||||
torch==1.12.0+cu116
|
||||
torchaudio==0.12.0+cu116
|
||||
tqdm==4.63.0
|
||||
scikit-maad
|
||||
praat-parselmouth
|
||||
onnx
|
||||
onnxsim
|
||||
onnxoptimizer
|
||||
@@ -1,48 +0,0 @@
|
||||
import os
|
||||
import argparse
|
||||
import librosa
|
||||
import numpy as np
|
||||
from multiprocessing import Pool, cpu_count
|
||||
from scipy.io import wavfile
|
||||
from tqdm import tqdm
|
||||
|
||||
|
||||
def process(item):
|
||||
spkdir, wav_name, args = item
|
||||
# speaker 's5', 'p280', 'p315' are excluded,
|
||||
speaker = spkdir.replace("\\", "/").split("/")[-1]
|
||||
wav_path = os.path.join(args.in_dir, speaker, wav_name)
|
||||
if os.path.exists(wav_path) and '.wav' in wav_path:
|
||||
os.makedirs(os.path.join(args.out_dir2, speaker), exist_ok=True)
|
||||
wav, sr = librosa.load(wav_path, sr=None)
|
||||
wav, _ = librosa.effects.trim(wav, top_db=20)
|
||||
peak = np.abs(wav).max()
|
||||
if peak > 1.0:
|
||||
wav = 0.98 * wav / peak
|
||||
wav2 = librosa.resample(wav, orig_sr=sr, target_sr=args.sr2)
|
||||
wav2 /= max(wav2.max(), -wav2.min())
|
||||
save_name = wav_name
|
||||
save_path2 = os.path.join(args.out_dir2, speaker, save_name)
|
||||
wavfile.write(
|
||||
save_path2,
|
||||
args.sr2,
|
||||
(wav2 * np.iinfo(np.int16).max).astype(np.int16)
|
||||
)
|
||||
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--sr2", type=int, default=44100, help="sampling rate")
|
||||
parser.add_argument("--in_dir", type=str, default="./dataset_raw", help="path to source dir")
|
||||
parser.add_argument("--out_dir2", type=str, default="./dataset/44k", help="path to target dir")
|
||||
args = parser.parse_args()
|
||||
processs = cpu_count()-2 if cpu_count() >4 else 1
|
||||
pool = Pool(processes=processs)
|
||||
|
||||
for speaker in os.listdir(args.in_dir):
|
||||
spk_dir = os.path.join(args.in_dir, speaker)
|
||||
if os.path.isdir(spk_dir):
|
||||
print(spk_dir)
|
||||
for _ in tqdm(pool.imap_unordered(process, [(spk_dir, i, args) for i in os.listdir(spk_dir) if i.endswith("wav")])):
|
||||
pass
|
||||
@@ -0,0 +1,9 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
# This is a shim to allow GitHub to detect the package, build is done with poetry
|
||||
# Taken from https://github.com/Textualize/rich
|
||||
|
||||
import setuptools
|
||||
|
||||
if __name__ == "__main__":
|
||||
setuptools.setup(name="so-vits-svc-fork")
|
||||
@@ -0,0 +1 @@
|
||||
__version__ = "1.0.2"
|
||||
@@ -0,0 +1,579 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from logging import (
|
||||
DEBUG,
|
||||
INFO,
|
||||
FileHandler,
|
||||
StreamHandler,
|
||||
basicConfig,
|
||||
captureWarnings,
|
||||
getLogger,
|
||||
)
|
||||
from pathlib import Path
|
||||
from typing import Literal
|
||||
|
||||
import click
|
||||
import pyinputplus as pyip
|
||||
import torch
|
||||
from rich.logging import RichHandler
|
||||
|
||||
|
||||
def init_logger() -> None:
|
||||
IN_COLAB = os.getenv("COLAB_RELEASE_TAG")
|
||||
IS_TEST = "test" in Path(__file__).parent.stem
|
||||
|
||||
basicConfig(
|
||||
level=DEBUG if IS_TEST else INFO,
|
||||
format="%(asctime)s %(message)s",
|
||||
datefmt="[%X]",
|
||||
handlers=[
|
||||
RichHandler() if not IN_COLAB else StreamHandler(),
|
||||
FileHandler(f"{__name__.split('.')[0]}.log"),
|
||||
],
|
||||
)
|
||||
captureWarnings(True)
|
||||
if IS_TEST:
|
||||
LOG.debug("Test mode is on.")
|
||||
|
||||
|
||||
init_logger()
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
class RichHelpFormatter(click.HelpFormatter):
|
||||
def __init__(
|
||||
self,
|
||||
indent_increment: int = 2,
|
||||
width: int | None = None,
|
||||
max_width: int | None = None,
|
||||
) -> None:
|
||||
width = 100
|
||||
super().__init__(indent_increment, width, max_width)
|
||||
|
||||
|
||||
def patch_wrap_text():
|
||||
orig_wrap_text = click.formatting.wrap_text
|
||||
|
||||
def wrap_text(
|
||||
text,
|
||||
width=78,
|
||||
initial_indent="",
|
||||
subsequent_indent="",
|
||||
preserve_paragraphs=False,
|
||||
):
|
||||
return orig_wrap_text(
|
||||
text.replace("\n", "\n\n"),
|
||||
width=width,
|
||||
initial_indent=initial_indent,
|
||||
subsequent_indent=subsequent_indent,
|
||||
preserve_paragraphs=True,
|
||||
).replace("\n\n", "\n")
|
||||
|
||||
click.formatting.wrap_text = wrap_text
|
||||
|
||||
|
||||
patch_wrap_text()
|
||||
|
||||
CONTEXT_SETTINGS = dict(help_option_names=["-h", "--help"], show_default=True)
|
||||
click.Context.formatter_class = RichHelpFormatter
|
||||
|
||||
|
||||
@click.group(context_settings=CONTEXT_SETTINGS)
|
||||
def cli():
|
||||
"""so-vits-svc allows any folder structure for training data.
|
||||
However, the following folder structure is recommended.\n
|
||||
When training: dataset_raw/{speaker_name}/**/{wav_name}.{any_format}\n
|
||||
When inference: configs/44k/config.json, logs/44k/G_XXXX.pth\n
|
||||
If the folder structure is followed, you DO NOT NEED TO SPECIFY model path, config path, etc.
|
||||
(The latest model will be automatically loaded.)\n
|
||||
To train a model, run pre-resample, pre-config, pre-hubert, train.\n
|
||||
To infer a model, run infer.
|
||||
"""
|
||||
init_logger()
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
help="path to config",
|
||||
default=Path("./configs/44k/config.json"),
|
||||
)
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(),
|
||||
help="path to output dir",
|
||||
default=Path("./logs/44k"),
|
||||
)
|
||||
def train(config_path: Path, model_path: Path):
|
||||
"""Train model
|
||||
If D_0.pth or G_0.pth not found, automatically download from hub."""
|
||||
from .train import train
|
||||
|
||||
config_path = Path(config_path)
|
||||
model_path = Path(model_path)
|
||||
train(config_path=config_path, model_path=model_path)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.argument(
|
||||
"input-path",
|
||||
type=click.Path(exists=True),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./logs/44k/"),
|
||||
help="path to model",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-k",
|
||||
"--cluster-model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=None,
|
||||
help="path to cluster model",
|
||||
)
|
||||
@click.option("-t", "--transpose", type=int, default=0, help="transpose")
|
||||
@click.option(
|
||||
"-db", "--db-thresh", type=int, default=-20, help="threshold (DB) (RELATIVE)"
|
||||
)
|
||||
@click.option(
|
||||
"-a", "--auto-predict-f0", type=bool, default=True, help="auto predict f0"
|
||||
)
|
||||
@click.option(
|
||||
"-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
)
|
||||
@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
@click.option("-p", "--pad-seconds", type=float, default=0.5, help="pad seconds")
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default="cuda" if torch.cuda.is_available() else "cpu",
|
||||
help="device",
|
||||
)
|
||||
@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
@click.option(
|
||||
"-ab", "--absolute-thresh", type=bool, default=False, help="absolute thresh"
|
||||
)
|
||||
def infer(
|
||||
input_path: Path,
|
||||
output_path: Path,
|
||||
speaker: str,
|
||||
model_path: Path,
|
||||
config_path: Path,
|
||||
cluster_model_path: Path | None = None,
|
||||
transpose: int = 0,
|
||||
db_thresh: int = -40,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
device: Literal["cpu", "cuda"] = "cuda" if torch.cuda.is_available() else "cpu",
|
||||
):
|
||||
"""Inference"""
|
||||
from .inference_main import infer
|
||||
|
||||
if not auto_predict_f0:
|
||||
LOG.warning(
|
||||
f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please set transpose."
|
||||
"Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
)
|
||||
|
||||
input_path = Path(input_path)
|
||||
if output_path is None:
|
||||
output_path = input_path.parent / f"{input_path.stem}.out{input_path.suffix}"
|
||||
output_path = Path(output_path)
|
||||
model_path = Path(model_path)
|
||||
if model_path.is_dir():
|
||||
model_path = list(sorted(model_path.glob("*.pth")))[-1]
|
||||
LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
config_path = Path(config_path)
|
||||
if cluster_model_path is not None:
|
||||
cluster_model_path = Path(cluster_model_path)
|
||||
infer(
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
speaker=speaker,
|
||||
model_path=model_path,
|
||||
config_path=config_path,
|
||||
cluster_model_path=cluster_model_path,
|
||||
transpose=transpose,
|
||||
db_thresh=db_thresh,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=absolute_thresh,
|
||||
device=device,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./logs/44k/"),
|
||||
help="path to model",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-k",
|
||||
"--cluster-model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=None,
|
||||
help="path to cluster model",
|
||||
)
|
||||
@click.option("-t", "--transpose", type=int, default=12, help="transpose")
|
||||
@click.option(
|
||||
"-a",
|
||||
"--auto-predict-f0",
|
||||
type=bool,
|
||||
default=False,
|
||||
help="auto predict f0 (not recommended for realtime since voice pitch will not be stable)",
|
||||
)
|
||||
@click.option(
|
||||
"-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
)
|
||||
@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
@click.option(
|
||||
"-db", "--db-thresh", type=int, default=-30, help="threshold (DB) (ABSOLUTE)"
|
||||
)
|
||||
@click.option(
|
||||
"-fm",
|
||||
"--f0-method",
|
||||
type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
default="crepe",
|
||||
help="f0 prediction method",
|
||||
)
|
||||
@click.option("-p", "--pad-seconds", type=float, default=0.02, help="pad seconds")
|
||||
@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
@click.option(
|
||||
"-cr",
|
||||
"--crossfade-seconds",
|
||||
type=float,
|
||||
default=0.01,
|
||||
help="crossfade seconds",
|
||||
)
|
||||
@click.option(
|
||||
"-ab",
|
||||
"--additional-infer-before-seconds",
|
||||
type=float,
|
||||
default=0.2,
|
||||
help="additional infer before seconds",
|
||||
)
|
||||
@click.option(
|
||||
"-aa",
|
||||
"--additional-infer-after-seconds",
|
||||
type=float,
|
||||
default=0.1,
|
||||
help="additional infer after seconds",
|
||||
)
|
||||
@click.option("-b", "--block-seconds", type=float, default=0.5, help="block seconds")
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default="cuda" if torch.cuda.is_available() else "cpu",
|
||||
help="device",
|
||||
)
|
||||
@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
@click.option("-v", "--version", type=int, default=2, help="version")
|
||||
@click.option("-i", "--input-device", type=int, default=None, help="input device")
|
||||
@click.option("-o", "--output-device", type=int, default=None, help="output device")
|
||||
@click.option(
|
||||
"-po",
|
||||
"--passthrough-original",
|
||||
type=bool,
|
||||
default=False,
|
||||
is_flag=True,
|
||||
help="passthrough original (for latency check)",
|
||||
)
|
||||
def vc(
|
||||
# paths
|
||||
model_path: Path,
|
||||
config_path: Path,
|
||||
# svc config
|
||||
speaker: str,
|
||||
cluster_model_path: Path | None,
|
||||
transpose: int,
|
||||
auto_predict_f0: bool,
|
||||
cluster_infer_ratio: float,
|
||||
noise_scale: float,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
# slice config
|
||||
db_thresh: int,
|
||||
pad_seconds: float,
|
||||
chunk_seconds: float,
|
||||
# realtime config
|
||||
crossfade_seconds: float,
|
||||
additional_infer_before_seconds: float,
|
||||
additional_infer_after_seconds: float,
|
||||
block_seconds: float,
|
||||
version: int,
|
||||
input_device: int | str | None,
|
||||
output_device: int | str | None,
|
||||
device: Literal["cpu", "cuda"],
|
||||
passthrough_original: bool = False,
|
||||
) -> None:
|
||||
"""Realtime inference from microphone"""
|
||||
from .inference_main import realtime
|
||||
|
||||
if auto_predict_f0:
|
||||
LOG.warning(
|
||||
"auto_predict_f0 = True in realtime inference will cause unstable voice pitch, use with caution"
|
||||
)
|
||||
else:
|
||||
LOG.warning(
|
||||
f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please change the transpose value."
|
||||
"Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
)
|
||||
model_path = Path(model_path)
|
||||
config_path = Path(config_path)
|
||||
if cluster_model_path is not None:
|
||||
cluster_model_path = Path(cluster_model_path)
|
||||
if model_path.is_dir():
|
||||
model_path = list(sorted(model_path.glob("*.pth")))[-1]
|
||||
LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
|
||||
realtime(
|
||||
# paths
|
||||
model_path=model_path,
|
||||
config_path=config_path,
|
||||
# svc config
|
||||
speaker=speaker,
|
||||
cluster_model_path=cluster_model_path,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
# slice config
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
# realtime config
|
||||
crossfade_seconds=crossfade_seconds,
|
||||
additional_infer_before_seconds=additional_infer_before_seconds,
|
||||
additional_infer_after_seconds=additional_infer_after_seconds,
|
||||
block_seconds=block_seconds,
|
||||
version=version,
|
||||
input_device=input_device,
|
||||
output_device=output_device,
|
||||
device=device,
|
||||
passthrough_original=passthrough_original,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset_raw"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-dir",
|
||||
type=click.Path(),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option("-s", "--sampling-rate", type=int, default=44100, help="sampling rate")
|
||||
def pre_resample(input_dir: Path, output_dir: Path, sampling_rate: int) -> None:
|
||||
"""Preprocessing part 1: resample"""
|
||||
from .preprocess_resample import preprocess_resample
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
preprocess_resample(
|
||||
input_dir=input_dir, output_dir=output_dir, sampling_rate=sampling_rate
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-f",
|
||||
"--filelist-path",
|
||||
type=click.Path(),
|
||||
default=Path("./filelists/44k"),
|
||||
help="path to filelist dir",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
def pre_config(
|
||||
input_dir: Path,
|
||||
filelist_path: Path,
|
||||
config_path: Path,
|
||||
):
|
||||
"""Preprocessing part 2: config"""
|
||||
from .preprocess_flist_config import preprocess_config
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
filelist_path = Path(filelist_path)
|
||||
config_path = Path(config_path)
|
||||
preprocess_config(
|
||||
input_dir=input_dir,
|
||||
train_list_path=filelist_path / "train.txt",
|
||||
val_list_path=filelist_path / "val.txt",
|
||||
test_list_path=filelist_path / "test.txt",
|
||||
config_path=config_path,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
help="path to config",
|
||||
default=Path("./configs/44k/config.json"),
|
||||
)
|
||||
@click.option(
|
||||
"-n",
|
||||
"--n_jobs",
|
||||
type=int,
|
||||
default=4,
|
||||
help="number of jobs (optimal value may depend on your VRAM capacity and audio duration per file)",
|
||||
)
|
||||
@click.option(
|
||||
"-f",
|
||||
"--force-rebuild",
|
||||
type=bool,
|
||||
default=True,
|
||||
help="force rebuild existing preprocessed files",
|
||||
)
|
||||
@click.option(
|
||||
"-fm",
|
||||
"--f0-method",
|
||||
type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
default="dio",
|
||||
)
|
||||
def pre_hubert(
|
||||
input_dir: Path,
|
||||
config_path: Path,
|
||||
n_jobs: bool,
|
||||
force_rebuild: bool,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
) -> None:
|
||||
"""Preprocessing part 3: hubert
|
||||
If the HuBERT model is not found, it will be downloaded automatically."""
|
||||
from .preprocess_hubert_f0 import preprocess_hubert_f0
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
config_path = Path(config_path)
|
||||
preprocess_hubert_f0(
|
||||
input_dir=input_dir,
|
||||
config_path=config_path,
|
||||
n_jobs=n_jobs,
|
||||
force_rebuild=force_rebuild,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
|
||||
|
||||
@cli.command
|
||||
def clean():
|
||||
"""Clean up files, only useful if you are using the default file structure"""
|
||||
import shutil
|
||||
|
||||
folders = ["dataset", "filelists", "logs"]
|
||||
if pyip.inputYesNo(f"Are you sure you want to delete files in {folders}?") == "yes":
|
||||
for folder in folders:
|
||||
if Path(folder).exists():
|
||||
shutil.rmtree(folder)
|
||||
LOG.info("Cleaned up files")
|
||||
else:
|
||||
LOG.info("Aborted")
|
||||
|
||||
|
||||
@cli.command
|
||||
@click.option("-i", "--input-path", type=click.Path(exists=True), help="model path")
|
||||
@click.option("-o", "--output-path", type=click.Path(), help="onnx model path to save")
|
||||
@click.option("-c", "--config-path", type=click.Path(), help="config path")
|
||||
@click.option("-d", "--device", type=str, default="cpu", help="torch device")
|
||||
def onnx(input_path: Path, output_path: Path, config_path: Path, device: str) -> None:
|
||||
"""Export model to onnx"""
|
||||
input_path = Path(input_path)
|
||||
output_path = Path(output_path)
|
||||
config_path = Path(config_path)
|
||||
device_ = torch.device(device)
|
||||
from .onnx_export import onnx_export
|
||||
|
||||
onnx_export(
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
config_path=config_path,
|
||||
device=device_,
|
||||
)
|
||||
|
||||
|
||||
@cli.command
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
help="dataset directory",
|
||||
default=Path("./dataset/44k"),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="model path to save",
|
||||
default=Path("./models/44k/kmeans.pt"),
|
||||
)
|
||||
@click.option("-n", "--n-clusters", type=int, help="number of clusters", default=10000)
|
||||
def train_cluster(input_dir: Path, output_path: Path, n_clusters: int) -> None:
|
||||
"""Train k-means clustering"""
|
||||
from .cluster.train_cluster import main
|
||||
|
||||
main(input_dir=input_dir, output_path=output_path, n_clusters=n_clusters)
|
||||
+15
-7
@@ -1,8 +1,13 @@
|
||||
import numpy as np
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
from sklearn.cluster import KMeans
|
||||
|
||||
def get_cluster_model(ckpt_path):
|
||||
|
||||
def get_cluster_model(ckpt_path: Path | str):
|
||||
checkpoint = torch.load(ckpt_path)
|
||||
kmeans_dict = {}
|
||||
for spk, ckpt in checkpoint.items():
|
||||
@@ -13,17 +18,20 @@ def get_cluster_model(ckpt_path):
|
||||
kmeans_dict[spk] = km
|
||||
return kmeans_dict
|
||||
|
||||
def get_cluster_result(model, x, speaker):
|
||||
|
||||
def get_cluster_result(model: Any, x: Any, speaker: Any):
|
||||
"""
|
||||
x: np.array [t, 256]
|
||||
return cluster class result
|
||||
x: np.array [t, 256]
|
||||
return cluster class result
|
||||
"""
|
||||
return model[speaker].predict(x)
|
||||
|
||||
def get_cluster_center_result(model, x,speaker):
|
||||
|
||||
def get_cluster_center_result(model: Any, x: Any, speaker: Any):
|
||||
"""x: np.array [t, 256]"""
|
||||
predict = model[speaker].predict(x)
|
||||
return model[speaker].cluster_centers_[predict]
|
||||
|
||||
def get_center(model, x,speaker):
|
||||
|
||||
def get_center(model: Any, x: Any, speaker: Any):
|
||||
return model[speaker].cluster_centers_[x]
|
||||
@@ -0,0 +1,66 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from cm_time import timer
|
||||
from joblib import Parallel, delayed
|
||||
from sklearn.cluster import KMeans, MiniBatchKMeans
|
||||
from tqdm import tqdm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def train_cluster(
|
||||
input_dir: Path | str,
|
||||
n_clusters: int,
|
||||
use_minibatch: bool = True,
|
||||
verbose: bool = False,
|
||||
) -> dict:
|
||||
input_dir = Path(input_dir)
|
||||
LOG.info(f"Loading features from {input_dir}")
|
||||
features = []
|
||||
nums = 0
|
||||
for path in tqdm(input_dir.glob("*.soft.pt")):
|
||||
features.append(torch.load(path).squeeze(0).numpy().T)
|
||||
features = np.concatenate(features, axis=0).astype(np.float32)
|
||||
LOG.info(
|
||||
f"Nums: {nums}, shape: {features.shape}, size: {features.nbytes/1024**2:.2f} MB, dtype: {features.dtype}"
|
||||
)
|
||||
with timer() as t:
|
||||
if use_minibatch:
|
||||
kmeans = MiniBatchKMeans(
|
||||
n_clusters=n_clusters, verbose=verbose, batch_size=4096, max_iter=80
|
||||
).fit(features)
|
||||
else:
|
||||
kmeans = KMeans(n_clusters=n_clusters, verbose=verbose).fit(features)
|
||||
LOG.info(f"Clustering took {t.elapsed:.2f} seconds")
|
||||
|
||||
x = {
|
||||
"n_features_in_": kmeans.n_features_in_,
|
||||
"_n_threads": kmeans._n_threads,
|
||||
"cluster_centers_": kmeans.cluster_centers_,
|
||||
}
|
||||
return x
|
||||
|
||||
|
||||
def main(
|
||||
input_dir: Path | str, output_path: Path | str, n_clusters: int = 10000
|
||||
) -> None:
|
||||
input_dir = Path(input_dir)
|
||||
output_path = Path(output_path)
|
||||
|
||||
def train_cluster_(input_path: Path, **kwargs: Any) -> tuple[str, dict]:
|
||||
return input_path.stem, train_cluster(input_path, **kwargs)
|
||||
|
||||
parallel_result = Parallel(n_jobs=-1)(
|
||||
delayed(train_cluster_)(input_path_, n_clusters=n_clusters)
|
||||
for input_path_ in input_dir.iterdir()
|
||||
)
|
||||
assert parallel_result is not None
|
||||
checkpoint = dict(parallel_result)
|
||||
output_path.parent.mkdir(exist_ok=True, parents=True)
|
||||
torch.save(checkpoint, output_path)
|
||||
+60
@@ -0,0 +1,60 @@
|
||||
{
|
||||
"train": {
|
||||
"log_interval": 200,
|
||||
"eval_interval": 800,
|
||||
"seed": 1234,
|
||||
"epochs": 10000,
|
||||
"learning_rate": 0.0001,
|
||||
"betas": [0.8, 0.99],
|
||||
"eps": 1e-9,
|
||||
"batch_size": 6,
|
||||
"fp16_run": false,
|
||||
"lr_decay": 0.999875,
|
||||
"segment_size": 10240,
|
||||
"init_lr_ratio": 1,
|
||||
"warmup_epochs": 0,
|
||||
"c_mel": 45,
|
||||
"c_kl": 1.0,
|
||||
"use_sr": true,
|
||||
"max_speclen": 512,
|
||||
"port": "8001",
|
||||
"keep_ckpts": 3
|
||||
},
|
||||
"data": {
|
||||
"training_files": "filelists/44k/train.txt",
|
||||
"validation_files": "filelists/44k/val.txt",
|
||||
"max_wav_value": 32768.0,
|
||||
"sampling_rate": 44100,
|
||||
"filter_length": 2048,
|
||||
"hop_length": 512,
|
||||
"win_length": 2048,
|
||||
"n_mel_channels": 80,
|
||||
"mel_fmin": 0.0,
|
||||
"mel_fmax": 22050
|
||||
},
|
||||
"model": {
|
||||
"inter_channels": 192,
|
||||
"hidden_channels": 192,
|
||||
"filter_channels": 768,
|
||||
"n_heads": 2,
|
||||
"n_layers": 6,
|
||||
"kernel_size": 3,
|
||||
"p_dropout": 0.1,
|
||||
"resblock": "1",
|
||||
"resblock_kernel_sizes": [3, 7, 11],
|
||||
"resblock_dilation_sizes": [
|
||||
[1, 3, 5],
|
||||
[1, 3, 5],
|
||||
[1, 3, 5]
|
||||
],
|
||||
"upsample_rates": [8, 8, 2, 2, 2],
|
||||
"upsample_initial_channel": 512,
|
||||
"upsample_kernel_sizes": [16, 16, 4, 4, 4],
|
||||
"n_layers_q": 3,
|
||||
"use_spectral_norm": false,
|
||||
"gin_channels": 256,
|
||||
"ssl_dim": 256,
|
||||
"n_speakers": 200
|
||||
},
|
||||
"spk": {}
|
||||
}
|
||||
+44
-29
@@ -1,26 +1,25 @@
|
||||
import time
|
||||
import os
|
||||
import random
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.utils.data
|
||||
|
||||
import modules.commons as commons
|
||||
import utils
|
||||
from modules.mel_processing import spectrogram_torch, spec_to_mel_torch
|
||||
from utils import load_wav_to_torch, load_filepaths_and_text
|
||||
from . import utils
|
||||
from .modules.mel_processing import spectrogram_torch
|
||||
from .utils import load_filepaths_and_text, load_wav_to_torch
|
||||
|
||||
# import h5py
|
||||
|
||||
|
||||
"""Multi speaker version"""
|
||||
# Multi speaker version
|
||||
|
||||
|
||||
class TextAudioSpeakerLoader(torch.utils.data.Dataset):
|
||||
"""
|
||||
1) loads audio, speaker_id, text pairs
|
||||
2) normalizes text and converts them to sequences of integers
|
||||
3) computes spectrograms from audio files.
|
||||
1) loads audio, speaker_id, text pairs
|
||||
2) normalizes text and converts them to sequences of integers
|
||||
3) computes spectrograms from audio files.
|
||||
"""
|
||||
|
||||
def __init__(self, audiopaths, hparams):
|
||||
@@ -42,17 +41,25 @@ class TextAudioSpeakerLoader(torch.utils.data.Dataset):
|
||||
filename = filename.replace("\\", "/")
|
||||
audio, sampling_rate = load_wav_to_torch(filename)
|
||||
if sampling_rate != self.sampling_rate:
|
||||
raise ValueError("{} SR doesn't match target {} SR".format(
|
||||
sampling_rate, self.sampling_rate))
|
||||
raise ValueError(
|
||||
"{} SR doesn't match target {} SR".format(
|
||||
sampling_rate, self.sampling_rate
|
||||
)
|
||||
)
|
||||
audio_norm = audio / self.max_wav_value
|
||||
audio_norm = audio_norm.unsqueeze(0)
|
||||
spec_filename = filename.replace(".wav", ".spec.pt")
|
||||
if os.path.exists(spec_filename):
|
||||
spec = torch.load(spec_filename)
|
||||
else:
|
||||
spec = spectrogram_torch(audio_norm, self.filter_length,
|
||||
self.sampling_rate, self.hop_length, self.win_length,
|
||||
center=False)
|
||||
spec = spectrogram_torch(
|
||||
audio_norm,
|
||||
self.filter_length,
|
||||
self.sampling_rate,
|
||||
self.hop_length,
|
||||
self.win_length,
|
||||
center=False,
|
||||
)
|
||||
spec = torch.squeeze(spec, 0)
|
||||
torch.save(spec, spec_filename)
|
||||
|
||||
@@ -64,22 +71,31 @@ class TextAudioSpeakerLoader(torch.utils.data.Dataset):
|
||||
f0 = torch.FloatTensor(f0)
|
||||
uv = torch.FloatTensor(uv)
|
||||
|
||||
c = torch.load(filename+ ".soft.pt")
|
||||
c = torch.load(filename + ".soft.pt")
|
||||
c = utils.repeat_expand_2d(c.squeeze(0), f0.shape[0])
|
||||
|
||||
|
||||
lmin = min(c.size(-1), spec.size(-1))
|
||||
assert abs(c.size(-1) - spec.size(-1)) < 3, (c.size(-1), spec.size(-1), f0.shape, filename)
|
||||
assert abs(audio_norm.shape[1]-lmin * self.hop_length) < 3 * self.hop_length
|
||||
assert abs(c.size(-1) - spec.size(-1)) < 3, (
|
||||
c.size(-1),
|
||||
spec.size(-1),
|
||||
f0.shape,
|
||||
filename,
|
||||
)
|
||||
assert abs(audio_norm.shape[1] - lmin * self.hop_length) < 3 * self.hop_length
|
||||
spec, c, f0, uv = spec[:, :lmin], c[:, :lmin], f0[:lmin], uv[:lmin]
|
||||
audio_norm = audio_norm[:, :lmin * self.hop_length]
|
||||
audio_norm = audio_norm[:, : lmin * self.hop_length]
|
||||
# if spec.shape[1] < 30:
|
||||
# print("skip too short audio:", filename)
|
||||
# return None
|
||||
if spec.shape[1] > 800:
|
||||
start = random.randint(0, spec.shape[1]-800)
|
||||
start = random.randint(0, spec.shape[1] - 800)
|
||||
end = start + 790
|
||||
spec, c, f0, uv = spec[:, start:end], c[:, start:end], f0[start:end], uv[start:end]
|
||||
spec, c, f0, uv = (
|
||||
spec[:, start:end],
|
||||
c[:, start:end],
|
||||
f0[start:end],
|
||||
uv[start:end],
|
||||
)
|
||||
audio_norm = audio_norm[:, start * self.hop_length : end * self.hop_length]
|
||||
|
||||
return c, f0, spec, audio_norm, spk, uv
|
||||
@@ -92,13 +108,12 @@ class TextAudioSpeakerLoader(torch.utils.data.Dataset):
|
||||
|
||||
|
||||
class TextAudioCollate:
|
||||
|
||||
def __call__(self, batch):
|
||||
batch = [b for b in batch if b is not None]
|
||||
|
||||
input_lengths, ids_sorted_decreasing = torch.sort(
|
||||
torch.LongTensor([x[0].shape[1] for x in batch]),
|
||||
dim=0, descending=True)
|
||||
torch.LongTensor([x[0].shape[1] for x in batch]), dim=0, descending=True
|
||||
)
|
||||
|
||||
max_c_len = max([x[0].size(1) for x in batch])
|
||||
max_wav_len = max([x[3].size(1) for x in batch])
|
||||
@@ -122,21 +137,21 @@ class TextAudioCollate:
|
||||
row = batch[ids_sorted_decreasing[i]]
|
||||
|
||||
c = row[0]
|
||||
c_padded[i, :, :c.size(1)] = c
|
||||
c_padded[i, :, : c.size(1)] = c
|
||||
lengths[i] = c.size(1)
|
||||
|
||||
f0 = row[1]
|
||||
f0_padded[i, :f0.size(0)] = f0
|
||||
f0_padded[i, : f0.size(0)] = f0
|
||||
|
||||
spec = row[2]
|
||||
spec_padded[i, :, :spec.size(1)] = spec
|
||||
spec_padded[i, :, : spec.size(1)] = spec
|
||||
|
||||
wav = row[3]
|
||||
wav_padded[i, :, :wav.size(1)] = wav
|
||||
wav_padded[i, :, : wav.size(1)] = wav
|
||||
|
||||
spkids[i, 0] = row[4]
|
||||
|
||||
uv = row[5]
|
||||
uv_padded[i, :uv.size(0)] = uv
|
||||
uv_padded[i, : uv.size(0)] = uv
|
||||
|
||||
return c_padded, f0_padded, spec_padded, wav_padded, spkids, lengths, uv_padded
|
||||
@@ -0,0 +1,441 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import textwrap
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import PySimpleGUI as sg
|
||||
import sounddevice as sd
|
||||
import soundfile as sf
|
||||
from pebble import ProcessPool
|
||||
|
||||
from .__main__ import init_logger
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
init_logger()
|
||||
|
||||
|
||||
def play_audio(path: Path | str):
|
||||
if isinstance(path, Path):
|
||||
path = path.as_posix()
|
||||
data, sr = sf.read(path)
|
||||
sd.play(data, sr)
|
||||
|
||||
|
||||
def main():
|
||||
sg.theme("Dark")
|
||||
model_candidates = list(sorted(Path("./logs/44k/").glob("G_*.pth")))
|
||||
|
||||
devices = sd.query_devices()
|
||||
input_devices = [d["name"] for d in devices if d["max_input_channels"] > 0]
|
||||
output_devices = [d["name"] for d in devices if d["max_output_channels"] > 0]
|
||||
devices[sd.default.device[0]]["name"]
|
||||
devices[sd.default.device[1]]["name"]
|
||||
|
||||
layout = [
|
||||
[
|
||||
sg.Frame(
|
||||
"Paths",
|
||||
[
|
||||
[
|
||||
sg.Text("Model path"),
|
||||
sg.Push(),
|
||||
sg.InputText(
|
||||
key="model_path",
|
||||
default_text=model_candidates[-1].absolute().as_posix()
|
||||
if model_candidates
|
||||
else "",
|
||||
enable_events=True,
|
||||
),
|
||||
sg.FileBrowse(
|
||||
initial_folder=Path("./logs/44k/").absolute
|
||||
if Path("./logs/44k/").exists()
|
||||
else Path(".").absolute().as_posix(),
|
||||
key="model_path_browse",
|
||||
file_types=(("PyTorch", "*.pth"),),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Config path"),
|
||||
sg.Push(),
|
||||
sg.InputText(
|
||||
key="config_path",
|
||||
default_text=Path("./configs/44k/config.json")
|
||||
.absolute()
|
||||
.as_posix()
|
||||
if Path("./configs/44k/config.json").exists()
|
||||
else "",
|
||||
enable_events=True,
|
||||
),
|
||||
sg.FileBrowse(
|
||||
initial_folder=Path("./configs/44k/").as_posix()
|
||||
if Path("./configs/44k/").exists()
|
||||
else Path(".").absolute().as_posix(),
|
||||
key="config_path_browse",
|
||||
file_types=(("JSON", "*.json"),),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Cluster model path"),
|
||||
sg.Push(),
|
||||
sg.InputText(key="cluster_model_path", enable_events=True),
|
||||
sg.FileBrowse(
|
||||
initial_folder="./logs/44k/"
|
||||
if Path("./logs/44k/").exists()
|
||||
else ".",
|
||||
key="cluster_model_path_browse",
|
||||
file_types=(("PyTorch", "*.pth"),),
|
||||
),
|
||||
],
|
||||
],
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Frame(
|
||||
"Common",
|
||||
[
|
||||
[
|
||||
sg.Text("Speaker"),
|
||||
sg.Combo(values=[], key="speaker", size=(20, 1)),
|
||||
],
|
||||
[
|
||||
sg.Text("Silence threshold"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(-60.0, 0),
|
||||
orientation="h",
|
||||
key="silence_threshold",
|
||||
default_value=-30,
|
||||
resolution=0.1,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Pitch"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(-20, 20),
|
||||
orientation="h",
|
||||
key="transpose",
|
||||
default_value=0,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
key="auto_predict_f0",
|
||||
default=True,
|
||||
text="Auto predict F0 (Pitch may become unstable when turned on in real-time inference.)",
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Text("F0 prediction method"),
|
||||
sg.Combo(
|
||||
["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
key="f0_method",
|
||||
default_value="crepe",
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Cluster infer ratio"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 1.0),
|
||||
orientation="h",
|
||||
key="cluster_infer_ratio",
|
||||
default_value=0,
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Noise scale"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 1.0),
|
||||
orientation="h",
|
||||
key="noise_scale",
|
||||
default_value=0.4,
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Pad seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 1.0),
|
||||
orientation="h",
|
||||
key="pad_seconds",
|
||||
default_value=0.1,
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Chunk seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 3.0),
|
||||
orientation="h",
|
||||
key="chunk_seconds",
|
||||
default_value=0.5,
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
key="absolute_thresh",
|
||||
default=False,
|
||||
text="Absolute threshold (ignored (True) in realtime inference)",
|
||||
)
|
||||
],
|
||||
],
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Frame(
|
||||
"File",
|
||||
[
|
||||
[
|
||||
sg.Text("Input audio path"),
|
||||
sg.Push(),
|
||||
sg.InputText(key="input_path"),
|
||||
sg.FileBrowse(initial_folder="."),
|
||||
sg.Button("Play", key="play_input"),
|
||||
],
|
||||
[sg.Checkbox(key="auto_play", default=True, text="Auto play")],
|
||||
],
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Frame(
|
||||
"Realtime",
|
||||
[
|
||||
[
|
||||
sg.Text(
|
||||
"In Realtime Inference:\n"
|
||||
" Setting F0 prediction method to 'crepe` may cause performance degradation.\n"
|
||||
" Auto Predict F0 must be turned off.\n"
|
||||
+ textwrap.fill(
|
||||
"If the audio sounds mumbly and choppy, the inference has not been made in time "
|
||||
"and the below parameters should be adjusted or the microphone input is too low and the "
|
||||
"silence threshold should be increased.",
|
||||
80,
|
||||
)
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Text("Crossfade seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 0.6),
|
||||
orientation="h",
|
||||
key="crossfade_seconds",
|
||||
default_value=0.08,
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Block seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 1.0),
|
||||
orientation="h",
|
||||
key="block_seconds",
|
||||
default_value=0.35,
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Additional Infer seconds (before)"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 1.0),
|
||||
orientation="h",
|
||||
key="additional_infer_before_seconds",
|
||||
default_value=0.2,
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Additional Infer seconds (after)"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 1.0),
|
||||
orientation="h",
|
||||
key="additional_infer_after_seconds",
|
||||
default_value=0.08,
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Realtime algorithm"),
|
||||
sg.Combo(
|
||||
["2 (Divide by speech)", "1 (Divide constantly)"],
|
||||
default_value="1 (Divide constantly)",
|
||||
key="realtime_algorithm",
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Input device"),
|
||||
sg.Combo(
|
||||
key="input_device",
|
||||
values=input_devices,
|
||||
size=(20, 1),
|
||||
default_value=input_devices[0],
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Output device"),
|
||||
sg.Combo(
|
||||
key="output_device",
|
||||
values=output_devices,
|
||||
size=(20, 1),
|
||||
default_value=output_devices[0],
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
"Passthrough original audio (for latency check)",
|
||||
key="passthrough_original",
|
||||
default=False,
|
||||
),
|
||||
],
|
||||
],
|
||||
)
|
||||
],
|
||||
[sg.Checkbox(key="use_gpu", default=True, text="Use GPU")],
|
||||
[
|
||||
sg.Button("Infer", key="infer"),
|
||||
sg.Button("(Re)Start Voice Changer", key="start_vc"),
|
||||
sg.Button("Stop Voice Changer", key="stop_vc"),
|
||||
],
|
||||
]
|
||||
for row in layout:
|
||||
for frame in row:
|
||||
if isinstance(frame, sg.Frame):
|
||||
frame.expand_x = True
|
||||
window = sg.Window(
|
||||
f"{__name__.split('.')[0]}", layout
|
||||
) # , use_custom_titlebar=True)
|
||||
with ProcessPool(max_workers=1) as pool:
|
||||
future = None
|
||||
while True:
|
||||
event, values = window.read(100)
|
||||
if event == sg.WIN_CLOSED:
|
||||
break
|
||||
|
||||
def update_combo() -> None:
|
||||
from . import utils
|
||||
|
||||
config_path = Path(values["config_path"])
|
||||
if config_path.exists() and config_path.is_file():
|
||||
hp = utils.get_hparams_from_file(values["config_path"])
|
||||
LOG.info(f"Loaded config from {values['config_path']}")
|
||||
window["speaker"].update(
|
||||
values=list(hp.__dict__["spk"].keys()), set_to_index=0
|
||||
)
|
||||
|
||||
if not event == sg.EVENT_TIMEOUT:
|
||||
LOG.info(f"Event {event}, values {values}")
|
||||
if values["speaker"] == "":
|
||||
update_combo()
|
||||
if event.endswith("_path"):
|
||||
for name in window.AllKeysDict:
|
||||
if str(name).endswith("_browse"):
|
||||
browser = window[name]
|
||||
if isinstance(browser, sg.Button):
|
||||
LOG.info(
|
||||
f"Updating browser {browser} to {Path(values[event]).parent}"
|
||||
)
|
||||
browser.InitialFolder = Path(values[event]).parent
|
||||
browser.update()
|
||||
else:
|
||||
LOG.warning(f"Browser {browser} is not a FileBrowse")
|
||||
"""browser = window[f"{event}_browse"]
|
||||
if isinstance(browser, sg.Button):
|
||||
LOG.info(
|
||||
f"Updating browser {browser} to {Path(values[event]).parent}"
|
||||
)
|
||||
browser.InitialFolder = Path(values[event]).parent
|
||||
browser.update()
|
||||
else:
|
||||
LOG.warning(f"Browser {browser} is not a FileBrowse")"""
|
||||
if event == "config_path":
|
||||
update_combo()
|
||||
elif event == "infer":
|
||||
from .inference_main import infer
|
||||
|
||||
input_path = Path(values["input_path"])
|
||||
output_path = (
|
||||
input_path.parent / f"{input_path.stem}.out{input_path.suffix}"
|
||||
)
|
||||
if not input_path.exists() or not input_path.is_file():
|
||||
LOG.warning(f"Input path {input_path} does not exist.")
|
||||
continue
|
||||
infer(
|
||||
model_path=Path(values["model_path"]),
|
||||
config_path=Path(values["config_path"]),
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
speaker=values["speaker"],
|
||||
cluster_model_path=Path(values["cluster_model_path"])
|
||||
if values["cluster_model_path"]
|
||||
else None,
|
||||
transpose=values["transpose"],
|
||||
auto_predict_f0=values["auto_predict_f0"],
|
||||
cluster_infer_ratio=values["cluster_infer_ratio"],
|
||||
noise_scale=values["noise_scale"],
|
||||
db_thresh=values["silence_threshold"],
|
||||
pad_seconds=values["pad_seconds"],
|
||||
absolute_thresh=values["absolute_thresh"],
|
||||
chunk_seconds=values["chunk_seconds"],
|
||||
device="cuda" if values["use_gpu"] else "cpu",
|
||||
)
|
||||
if values["auto_play"]:
|
||||
pool.schedule(play_audio, args=[output_path])
|
||||
elif event == "play_input":
|
||||
if Path(values["input_path"]).exists():
|
||||
pool.schedule(play_audio, args=[Path(values["input_path"])])
|
||||
elif event == "start_vc":
|
||||
from .inference_main import realtime
|
||||
|
||||
if future:
|
||||
LOG.info("Canceling previous task")
|
||||
future.cancel()
|
||||
future = pool.schedule(
|
||||
realtime,
|
||||
kwargs=dict(
|
||||
model_path=Path(values["model_path"]),
|
||||
config_path=Path(values["config_path"]),
|
||||
speaker=values["speaker"],
|
||||
cluster_model_path=Path(values["cluster_model_path"])
|
||||
if values["cluster_model_path"]
|
||||
else None,
|
||||
transpose=values["transpose"],
|
||||
auto_predict_f0=values["auto_predict_f0"],
|
||||
cluster_infer_ratio=values["cluster_infer_ratio"],
|
||||
noise_scale=values["noise_scale"],
|
||||
f0_method=values["f0_method"],
|
||||
crossfade_seconds=values["crossfade_seconds"],
|
||||
additional_infer_before_seconds=values[
|
||||
"additional_infer_before_seconds"
|
||||
],
|
||||
additional_infer_after_seconds=values[
|
||||
"additional_infer_after_seconds"
|
||||
],
|
||||
db_thresh=values["silence_threshold"],
|
||||
pad_seconds=values["pad_seconds"],
|
||||
chunk_seconds=values["chunk_seconds"],
|
||||
version=int(values["realtime_algorithm"][0]),
|
||||
device="cuda" if values["use_gpu"] else "cpu",
|
||||
block_seconds=values["block_seconds"],
|
||||
input_device=values["input_device"],
|
||||
output_device=values["output_device"],
|
||||
passthrough_original=values["passthrough_original"],
|
||||
),
|
||||
)
|
||||
elif event == "stop_vc":
|
||||
if future:
|
||||
future.cancel()
|
||||
future = None
|
||||
if future:
|
||||
future.cancel()
|
||||
window.close()
|
||||
+16
-15
@@ -36,7 +36,7 @@ class Hubert(nn.Module):
|
||||
return x, mask
|
||||
|
||||
def encode(
|
||||
self, x: torch.Tensor, layer: Optional[int] = None
|
||||
self, x: torch.Tensor, layer: Optional[int] = None
|
||||
) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
x = self.feature_extractor(x)
|
||||
x = self.feature_projection(x.transpose(1, 2))
|
||||
@@ -129,20 +129,20 @@ class PositionalConvEmbedding(nn.Module):
|
||||
|
||||
class TransformerEncoder(nn.Module):
|
||||
def __init__(
|
||||
self, encoder_layer: nn.TransformerEncoderLayer, num_layers: int
|
||||
self, encoder_layer: nn.TransformerEncoderLayer, num_layers: int
|
||||
) -> None:
|
||||
super(TransformerEncoder, self).__init__()
|
||||
super().__init__()
|
||||
self.layers = nn.ModuleList(
|
||||
[copy.deepcopy(encoder_layer) for _ in range(num_layers)]
|
||||
)
|
||||
self.num_layers = num_layers
|
||||
|
||||
def forward(
|
||||
self,
|
||||
src: torch.Tensor,
|
||||
mask: torch.Tensor = None,
|
||||
src_key_padding_mask: torch.Tensor = None,
|
||||
output_layer: Optional[int] = None,
|
||||
self,
|
||||
src: torch.Tensor,
|
||||
mask: torch.Tensor = None,
|
||||
src_key_padding_mask: torch.Tensor = None,
|
||||
output_layer: Optional[int] = None,
|
||||
) -> torch.Tensor:
|
||||
output = src
|
||||
for layer in self.layers[:output_layer]:
|
||||
@@ -153,11 +153,11 @@ class TransformerEncoder(nn.Module):
|
||||
|
||||
|
||||
def _compute_mask(
|
||||
shape: Tuple[int, int],
|
||||
mask_prob: float,
|
||||
mask_length: int,
|
||||
device: torch.device,
|
||||
min_masks: int = 0,
|
||||
shape: Tuple[int, int],
|
||||
mask_prob: float,
|
||||
mask_length: int,
|
||||
device: torch.device,
|
||||
min_masks: int = 0,
|
||||
) -> torch.Tensor:
|
||||
batch_size, sequence_length = shape
|
||||
|
||||
@@ -166,7 +166,8 @@ def _compute_mask(
|
||||
|
||||
if mask_length > sequence_length:
|
||||
raise ValueError(
|
||||
f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length} and `sequence_length`: {sequence_length}`"
|
||||
"`mask_length` has to be smaller than `sequence_length`, "
|
||||
f"but got `mask_length`: {mask_length} and `sequence_length`: {sequence_length}`"
|
||||
)
|
||||
|
||||
# compute number of masked spans in batch
|
||||
@@ -208,7 +209,7 @@ def _compute_mask(
|
||||
|
||||
|
||||
def hubert_soft(
|
||||
path: str,
|
||||
path: str,
|
||||
) -> HubertSoft:
|
||||
r"""HuBERT-Soft from `"A Comparison of Discrete and Soft Speech Units for Improved Voice Conversion"`.
|
||||
Args:
|
||||
+17
-15
@@ -36,7 +36,7 @@ class Hubert(nn.Module):
|
||||
return x, mask
|
||||
|
||||
def encode(
|
||||
self, x: torch.Tensor, layer: Optional[int] = None
|
||||
self, x: torch.Tensor, layer: Optional[int] = None
|
||||
) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
x = self.feature_extractor(x)
|
||||
x = self.feature_projection(x.transpose(1, 2))
|
||||
@@ -67,6 +67,7 @@ class HubertSoft(Hubert):
|
||||
def forward(self, x):
|
||||
return self.units(x)
|
||||
|
||||
|
||||
class FeatureExtractor(nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
@@ -124,20 +125,20 @@ class PositionalConvEmbedding(nn.Module):
|
||||
|
||||
class TransformerEncoder(nn.Module):
|
||||
def __init__(
|
||||
self, encoder_layer: nn.TransformerEncoderLayer, num_layers: int
|
||||
self, encoder_layer: nn.TransformerEncoderLayer, num_layers: int
|
||||
) -> None:
|
||||
super(TransformerEncoder, self).__init__()
|
||||
super().__init__()
|
||||
self.layers = nn.ModuleList(
|
||||
[copy.deepcopy(encoder_layer) for _ in range(num_layers)]
|
||||
)
|
||||
self.num_layers = num_layers
|
||||
|
||||
def forward(
|
||||
self,
|
||||
src: torch.Tensor,
|
||||
mask: torch.Tensor = None,
|
||||
src_key_padding_mask: torch.Tensor = None,
|
||||
output_layer: Optional[int] = None,
|
||||
self,
|
||||
src: torch.Tensor,
|
||||
mask: torch.Tensor = None,
|
||||
src_key_padding_mask: torch.Tensor = None,
|
||||
output_layer: Optional[int] = None,
|
||||
) -> torch.Tensor:
|
||||
output = src
|
||||
for layer in self.layers[:output_layer]:
|
||||
@@ -148,11 +149,11 @@ class TransformerEncoder(nn.Module):
|
||||
|
||||
|
||||
def _compute_mask(
|
||||
shape: Tuple[int, int],
|
||||
mask_prob: float,
|
||||
mask_length: int,
|
||||
device: torch.device,
|
||||
min_masks: int = 0,
|
||||
shape: Tuple[int, int],
|
||||
mask_prob: float,
|
||||
mask_length: int,
|
||||
device: torch.device,
|
||||
min_masks: int = 0,
|
||||
) -> torch.Tensor:
|
||||
batch_size, sequence_length = shape
|
||||
|
||||
@@ -161,7 +162,8 @@ def _compute_mask(
|
||||
|
||||
if mask_length > sequence_length:
|
||||
raise ValueError(
|
||||
f"`mask_length` has to be smaller than `sequence_length`, but got `mask_length`: {mask_length} and `sequence_length`: {sequence_length}`"
|
||||
"`mask_length` has to be smaller than `sequence_length`, "
|
||||
f"but got `mask_length`: {mask_length} and `sequence_length`: {sequence_length}`"
|
||||
)
|
||||
|
||||
# compute number of masked spans in batch
|
||||
@@ -203,7 +205,7 @@ def _compute_mask(
|
||||
|
||||
|
||||
def hubert_soft(
|
||||
path: str,
|
||||
path: str,
|
||||
) -> HubertSoft:
|
||||
r"""HuBERT-Soft from `"A Comparison of Discrete and Soft Speech Units for Improved Voice Conversion"`.
|
||||
Args:
|
||||
@@ -0,0 +1,635 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from copy import deepcopy
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable, Iterable, Literal
|
||||
|
||||
import attrs
|
||||
import librosa
|
||||
import numpy as np
|
||||
import torch
|
||||
from cm_time import timer
|
||||
from numpy import dtype, float32, ndarray
|
||||
|
||||
from so_vits_svc_fork import cluster, utils
|
||||
from so_vits_svc_fork.models import SynthesizerTrn
|
||||
|
||||
from ..utils import HUBERT_SAMPLING_RATE
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def pad_array(array_, target_length: int):
|
||||
current_length = array_.shape[0]
|
||||
if current_length >= target_length:
|
||||
return array_[
|
||||
(current_length - target_length)
|
||||
// 2 : (current_length - target_length)
|
||||
// 2
|
||||
+ target_length,
|
||||
...,
|
||||
]
|
||||
else:
|
||||
pad_width = target_length - current_length
|
||||
pad_left = pad_width // 2
|
||||
pad_right = pad_width - pad_left
|
||||
padded_arr = np.pad(
|
||||
array_, (pad_left, pad_right), "constant", constant_values=(0, 0)
|
||||
)
|
||||
return padded_arr
|
||||
|
||||
|
||||
@attrs.frozen(kw_only=True)
|
||||
class Chunk:
|
||||
is_speech: bool
|
||||
audio: ndarray[Any, dtype[float32]]
|
||||
start: int
|
||||
end: int
|
||||
|
||||
@property
|
||||
def duration(self) -> float32:
|
||||
# return self.end - self.start
|
||||
return float32(self.audio.shape[0])
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"Chunk(Speech: {self.is_speech}, {self.duration})"
|
||||
|
||||
|
||||
def split_silence(
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
top_db: int = 40,
|
||||
ref: float | Callable[[ndarray[Any, dtype[float32]]], float] = 1,
|
||||
frame_length: int = 2048,
|
||||
hop_length: int = 512,
|
||||
aggregate: Callable[[ndarray[Any, dtype[float32]]], float] = np.mean,
|
||||
chunk_size_max: int = 44100 * 10
|
||||
) -> Iterable[Chunk]:
|
||||
non_silence_indices = librosa.effects.split(
|
||||
audio,
|
||||
top_db=top_db,
|
||||
ref=ref,
|
||||
frame_length=frame_length,
|
||||
hop_length=hop_length,
|
||||
#aggregate=aggregate,
|
||||
)
|
||||
last_end = 0
|
||||
for start, end in non_silence_indices:
|
||||
if start != last_end:
|
||||
yield Chunk(
|
||||
is_speech=False, audio=audio[last_end:start], start=last_end, end=start
|
||||
)
|
||||
if end-start > chunk_size_max:
|
||||
while last_end < end:
|
||||
yield Chunk(is_speech=True, audio=audio[last_end:last_end+chunk_size_max], start=last_end, end=last_end+chunk_size_max)
|
||||
last_end = last_end+chunk_size_max
|
||||
else:
|
||||
yield Chunk(is_speech=True, audio=audio[start:end], start=start, end=end)
|
||||
last_end = end
|
||||
else:
|
||||
yield Chunk(is_speech=True, audio=audio[start:end], start=start, end=end)
|
||||
last_end = end
|
||||
if last_end != len(audio):
|
||||
yield Chunk(
|
||||
is_speech=False, audio=audio[last_end:], start=last_end, end=len(audio)
|
||||
)
|
||||
|
||||
|
||||
class Svc:
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
net_g_path: str,
|
||||
config_path: str,
|
||||
device: torch.device | str | None = None,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
):
|
||||
self.net_g_path = net_g_path
|
||||
if device is None:
|
||||
self.dev = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
||||
else:
|
||||
self.dev = torch.device(device)
|
||||
self.net_g_ms = None
|
||||
self.hps_ms = utils.get_hparams_from_file(config_path)
|
||||
self.target_sample = self.hps_ms.data.sampling_rate
|
||||
self.hop_size = self.hps_ms.data.hop_length
|
||||
self.spk2id = self.hps_ms.spk
|
||||
self.hubert_model = utils.get_hubert_model().to(self.dev)
|
||||
self.load_model()
|
||||
if cluster_model_path is not None and Path(cluster_model_path).exists():
|
||||
self.cluster_model = cluster.get_cluster_model(cluster_model_path)
|
||||
|
||||
def load_model(self):
|
||||
self.net_g_ms = SynthesizerTrn(
|
||||
self.hps_ms.data.filter_length // 2 + 1,
|
||||
self.hps_ms.train.segment_size // self.hps_ms.data.hop_length,
|
||||
**self.hps_ms.model,
|
||||
)
|
||||
_ = utils.load_checkpoint(self.net_g_path, self.net_g_ms, None)
|
||||
if "half" in self.net_g_path and torch.cuda.is_available():
|
||||
_ = self.net_g_ms.half().eval().to(self.dev)
|
||||
else:
|
||||
_ = self.net_g_ms.eval().to(self.dev)
|
||||
|
||||
def get_unit_f0(
|
||||
self,
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
tran: int,
|
||||
cluster_infer_ratio: float,
|
||||
speaker: int | str,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
):
|
||||
f0 = utils.compute_f0(
|
||||
audio,
|
||||
sampling_rate=self.target_sample,
|
||||
hop_length=self.hop_size,
|
||||
method=f0_method,
|
||||
)
|
||||
f0, uv = utils.interpolate_f0(f0)
|
||||
f0 = torch.FloatTensor(f0)
|
||||
uv = torch.FloatTensor(uv)
|
||||
f0 = f0 * 2 ** (tran / 12)
|
||||
f0 = f0.unsqueeze(0).to(self.dev)
|
||||
uv = uv.unsqueeze(0).to(self.dev)
|
||||
|
||||
wav16k = librosa.resample(
|
||||
audio, orig_sr=self.target_sample, target_sr=HUBERT_SAMPLING_RATE
|
||||
)
|
||||
wav16k = torch.from_numpy(wav16k).to(self.dev)
|
||||
c = utils.get_hubert_content(self.hubert_model, wav_16k_tensor=wav16k)
|
||||
c = utils.repeat_expand_2d(c.squeeze(0), f0.shape[1])
|
||||
|
||||
if cluster_infer_ratio != 0:
|
||||
cluster_c = cluster.get_cluster_center_result(
|
||||
self.cluster_model, c.cpu().numpy().T, speaker
|
||||
).T
|
||||
cluster_c = torch.FloatTensor(cluster_c).to(self.dev)
|
||||
c = cluster_infer_ratio * cluster_c + (1 - cluster_infer_ratio) * c
|
||||
|
||||
c = c.unsqueeze(0)
|
||||
return c, f0, uv
|
||||
|
||||
def infer(
|
||||
self,
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
) -> tuple[torch.Tensor, int]:
|
||||
audio = audio.astype(np.float32)
|
||||
# get speaker id
|
||||
if isinstance(speaker, int):
|
||||
if len(self.spk2id.__dict__) >= speaker:
|
||||
speaker_id = speaker
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Speaker id {speaker} >= number of speakers {len(self.spk2id.__dict__)}"
|
||||
)
|
||||
else:
|
||||
if speaker in self.spk2id.__dict__:
|
||||
speaker_id = self.spk2id.__dict__[speaker]
|
||||
else:
|
||||
LOG.warning(f"Speaker {speaker} is not found. Use speaker 0 instead.")
|
||||
speaker_id = 0
|
||||
sid = torch.LongTensor([int(speaker_id)]).to(self.dev).unsqueeze(0)
|
||||
|
||||
# get unit f0
|
||||
c, f0, uv = self.get_unit_f0(
|
||||
audio, transpose, cluster_infer_ratio, speaker, f0_method
|
||||
)
|
||||
if "half" in self.net_g_path and torch.cuda.is_available():
|
||||
c = c.half()
|
||||
|
||||
# inference
|
||||
with torch.no_grad():
|
||||
with timer() as t:
|
||||
audio = self.net_g_ms.infer(
|
||||
c,
|
||||
f0=f0,
|
||||
g=sid,
|
||||
uv=uv,
|
||||
predict_f0=auto_predict_f0,
|
||||
noice_scale=noise_scale,
|
||||
)[0, 0].data.float()
|
||||
realtime_coef = len(audio) / (t.elapsed * self.target_sample)
|
||||
LOG.info(
|
||||
f"Inferece time: {t.elapsed:.2f}s, Realtime coef: {realtime_coef:.2f} "
|
||||
f"Input shape: {audio.shape}, Output shape: {audio.shape}"
|
||||
)
|
||||
return audio, audio.shape[-1]
|
||||
|
||||
def clear_empty(self):
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
def infer_silence(
|
||||
self,
|
||||
audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
*,
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
# fade_seconds: float = 0.0,
|
||||
) -> np.ndarray[Any, np.dtype[np.float32]]:
|
||||
sr = self.target_sample
|
||||
result_audio = np.array([], dtype=np.float32)
|
||||
chunk_length_min = chunk_length_min = (
|
||||
int(
|
||||
min(
|
||||
sr / utils.f0_min * 20 + 1,
|
||||
chunk_seconds * sr,
|
||||
)
|
||||
)
|
||||
// 2
|
||||
)
|
||||
for chunk in split_silence(
|
||||
audio,
|
||||
top_db=-db_thresh,
|
||||
frame_length=chunk_length_min * 2,
|
||||
hop_length=chunk_length_min,
|
||||
ref=1 if absolute_thresh else np.max,
|
||||
):
|
||||
LOG.info(f"Chunk: {chunk}")
|
||||
if not chunk.is_speech:
|
||||
audio_chunk_infer = np.zeros_like(chunk.audio)
|
||||
else:
|
||||
# pad
|
||||
pad_len = int(sr * pad_seconds)
|
||||
audio_chunk_pad = np.concatenate(
|
||||
[
|
||||
np.zeros([pad_len], dtype=np.float32),
|
||||
chunk.audio,
|
||||
np.zeros([pad_len], dtype=np.float32),
|
||||
]
|
||||
)
|
||||
audio_chunk_pad_infer_tensor, _ = self.infer(
|
||||
speaker,
|
||||
transpose,
|
||||
audio_chunk_pad,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
audio_chunk_pad_infer = audio_chunk_pad_infer_tensor.cpu().numpy()
|
||||
pad_len = int(self.target_sample * pad_seconds)
|
||||
cut_len_2 = (len(audio_chunk_pad_infer) - len(chunk.audio)) // 2
|
||||
audio_chunk_infer = audio_chunk_pad_infer[
|
||||
cut_len_2 : cut_len_2 + len(chunk.audio)
|
||||
]
|
||||
|
||||
# add fade
|
||||
# fade_len = int(self.target_sample * fade_seconds)
|
||||
# _audio[:fade_len] = _audio[:fade_len] * np.linspace(0, 1, fade_len)
|
||||
# _audio[-fade_len:] = _audio[-fade_len:] * np.linspace(1, 0, fade_len)
|
||||
result_audio = np.concatenate([result_audio, audio_chunk_infer])
|
||||
result_audio = result_audio[: audio.shape[0]]
|
||||
return result_audio
|
||||
|
||||
|
||||
def linear_crossfade(
|
||||
first: ndarray[Any, dtype[float32]],
|
||||
second: ndarray[Any, dtype[float32]],
|
||||
length: int,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
return np.concatenate(
|
||||
[
|
||||
first[:-length],
|
||||
first[-length:] * np.linspace(1, 0, length)
|
||||
+ second[:length] * np.linspace(0, 1, length),
|
||||
second[length:],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class Crossfader:
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
additional_infer_before_len: int,
|
||||
additional_infer_after_len: int,
|
||||
crossfade_len: int,
|
||||
) -> None:
|
||||
if additional_infer_before_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
if crossfade_len < 0:
|
||||
raise ValueError("crossfade_len must be >= 0")
|
||||
if additional_infer_after_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
if additional_infer_before_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
self.additional_infer_before_len = additional_infer_before_len
|
||||
self.additional_infer_after_len = additional_infer_after_len
|
||||
self.crossfade_len = crossfade_len
|
||||
self.last_input_left = np.zeros(
|
||||
crossfade_len + additional_infer_before_len + additional_infer_after_len,
|
||||
dtype=np.float32,
|
||||
)
|
||||
self.last_infered_left = np.zeros(crossfade_len, dtype=np.float32)
|
||||
|
||||
def process(
|
||||
self, input_audio: ndarray[Any, dtype[float32]], *args, **kwargs: Any
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
"""
|
||||
chunks : ■■■■■■□□□□□□
|
||||
add last input:□■■■■■■
|
||||
■□□□□□□
|
||||
infer :□■■■■■■
|
||||
■□□□□□□
|
||||
crossfade :▲■■■■■
|
||||
▲□□□□□
|
||||
"""
|
||||
# check input
|
||||
if input_audio.ndim != 1:
|
||||
raise ValueError("Input audio must be 1-dimensional.")
|
||||
if (
|
||||
input_audio.shape[0] + self.additional_infer_before_len
|
||||
<= self.crossfade_len
|
||||
):
|
||||
raise ValueError(
|
||||
f"Input audio length ({input_audio.shape[0]}) + additional_infer_len ({self.additional_infer_before_len}) must be greater than crossfade_len ({self.crossfade_len})."
|
||||
)
|
||||
input_audio = input_audio.astype(np.float32)
|
||||
input_audio_len = len(input_audio)
|
||||
|
||||
# concat last input and infer
|
||||
input_audio_concat = np.concatenate([self.last_input_left, input_audio])
|
||||
del input_audio
|
||||
pad_len = 0
|
||||
if pad_len:
|
||||
infer_audio_concat = self.infer(
|
||||
np.pad(input_audio_concat, (pad_len, pad_len), mode="reflect"),
|
||||
*args,
|
||||
**kwargs,
|
||||
)[pad_len:-pad_len]
|
||||
else:
|
||||
infer_audio_concat = self.infer(input_audio_concat, *args, **kwargs)
|
||||
if len(infer_audio_concat) != len(input_audio_concat):
|
||||
raise ValueError(
|
||||
f"Inferred audio length ({len(infer_audio_concat)}) should be equal to input audio length ({len(input_audio_concat)})."
|
||||
)
|
||||
|
||||
infer_audio_to_use = infer_audio_concat[
|
||||
-(
|
||||
self.crossfade_len + input_audio_len + self.additional_infer_after_len
|
||||
) : -(self.crossfade_len + self.additional_infer_after_len)
|
||||
]
|
||||
assert (
|
||||
len(infer_audio_to_use) == input_audio_len
|
||||
), f"{len(infer_audio_to_use)} != {input_audio_len}"
|
||||
result_audio = linear_crossfade(
|
||||
self.last_infered_left, infer_audio_to_use, self.crossfade_len
|
||||
)
|
||||
assert (
|
||||
len(result_audio) == input_audio_len
|
||||
), f"{len(result_audio)} != {input_audio_len}"
|
||||
|
||||
# update last input and inferred
|
||||
self.last_input_left = input_audio_concat[
|
||||
-(
|
||||
self.crossfade_len
|
||||
+ self.additional_infer_before_len
|
||||
+ self.additional_infer_after_len
|
||||
) :
|
||||
]
|
||||
self.last_infered_left = infer_audio_concat[
|
||||
-(
|
||||
self.crossfade_len + self.additional_infer_after_len
|
||||
) : -self.additional_infer_after_len
|
||||
]
|
||||
return result_audio
|
||||
|
||||
def infer(
|
||||
self, input_audio: ndarray[Any, dtype[float32]]
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
return input_audio
|
||||
|
||||
|
||||
class RealtimeVC(Crossfader):
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
svc_model: Svc,
|
||||
crossfade_len: int = 3840,
|
||||
additional_infer_before_len: int = 7680,
|
||||
additional_infer_after_len: int = 7680,
|
||||
split: bool = True,
|
||||
) -> None:
|
||||
self.svc_model = svc_model
|
||||
self.split = split
|
||||
super().__init__(
|
||||
crossfade_len=crossfade_len,
|
||||
additional_infer_before_len=additional_infer_before_len,
|
||||
additional_infer_after_len=additional_infer_after_len,
|
||||
)
|
||||
|
||||
def process(
|
||||
self,
|
||||
input_audio: ndarray[Any, dtype[float32]],
|
||||
*args: Any,
|
||||
**kwargs: Any,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
return super().process(input_audio, *args, **kwargs)
|
||||
|
||||
def infer(
|
||||
self,
|
||||
input_audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
# infer
|
||||
if self.split:
|
||||
return self.svc_model.infer_silence(
|
||||
audio=input_audio,
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=True,
|
||||
)
|
||||
else:
|
||||
rms = np.sqrt(np.mean(input_audio**2))
|
||||
min_rms = 10 ** (db_thresh / 20)
|
||||
if rms < min_rms:
|
||||
LOG.info(f"Skip silence: RMS={rms:.2f} < {min_rms:.2f}")
|
||||
return input_audio.copy()
|
||||
else:
|
||||
LOG.info(f"Start inference: RMS={rms:.2f} >= {min_rms:.2f}")
|
||||
infered_audio_c, _ = self.svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
audio=input_audio,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
return infered_audio_c.cpu().numpy()
|
||||
|
||||
|
||||
class RealtimeVC2:
|
||||
chunk_store: list[Chunk]
|
||||
|
||||
def __init__(self, svc_model: Svc) -> None:
|
||||
self.input_audio_store = np.array([], dtype=np.float32)
|
||||
self.chunk_store = []
|
||||
self.svc_model = svc_model
|
||||
|
||||
def process(
|
||||
self,
|
||||
input_audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
chunk_seconds: float = 0.5,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
def infer(audio: ndarray[Any, dtype[float32]]) -> ndarray[Any, dtype[float32]]:
|
||||
infered_audio_c, _ = self.svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
audio=audio,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
return infered_audio_c.cpu().numpy()
|
||||
|
||||
self.input_audio_store = np.concatenate([self.input_audio_store, input_audio])
|
||||
LOG.info(f"input_audio_store: {self.input_audio_store.shape}")
|
||||
sr = self.svc_model.target_sample
|
||||
chunk_length_min = int(min(sr / utils.f0_min * 20 + 1, chunk_seconds * sr)) // 2
|
||||
LOG.info(f"Chunk length min: {chunk_length_min}")
|
||||
chunk_list = list(
|
||||
split_silence(
|
||||
self.input_audio_store,
|
||||
-db_thresh,
|
||||
frame_length=chunk_length_min * 2,
|
||||
hop_length=chunk_length_min,
|
||||
ref=1, # use absolute threshold
|
||||
)
|
||||
)
|
||||
assert len(chunk_list) > 0
|
||||
LOG.info(f"Chunk list: {chunk_list}")
|
||||
# do not infer LAST incomplete is_speech chunk and save to store
|
||||
if chunk_list[-1].is_speech:
|
||||
self.input_audio_store = chunk_list.pop().audio
|
||||
else:
|
||||
self.input_audio_store = np.array([], dtype=np.float32)
|
||||
|
||||
# infer complete is_speech chunk and save to store
|
||||
self.chunk_store.extend(
|
||||
[
|
||||
attrs.evolve(c, audio=infer(c.audio) if c.is_speech else c.audio)
|
||||
for c in chunk_list
|
||||
]
|
||||
)
|
||||
|
||||
# calculate lengths and determine compress rate
|
||||
total_speech_len = sum(
|
||||
[c.duration if c.is_speech else 0 for c in self.chunk_store]
|
||||
)
|
||||
total_silence_len = sum(
|
||||
[c.duration if not c.is_speech else 0 for c in self.chunk_store]
|
||||
)
|
||||
input_audio_len = input_audio.shape[0]
|
||||
silence_compress_rate = total_silence_len / max(
|
||||
0, input_audio_len - total_speech_len
|
||||
)
|
||||
LOG.info(
|
||||
f"Total speech len: {total_speech_len}, silence len: {total_silence_len}, silence compress rate: {silence_compress_rate}"
|
||||
)
|
||||
|
||||
# generate output audio
|
||||
output_audio = np.array([], dtype=np.float32)
|
||||
break_flag = False
|
||||
LOG.info(f"Chunk store: {self.chunk_store}")
|
||||
for chunk in deepcopy(self.chunk_store):
|
||||
compress_rate = 1 if chunk.is_speech else silence_compress_rate
|
||||
left_len = input_audio_len - output_audio.shape[0]
|
||||
# calculate chunk duration
|
||||
chunk_duration_output = int(min(chunk.duration / compress_rate, left_len))
|
||||
chunk_duration_input = int(min(chunk.duration, left_len * compress_rate))
|
||||
LOG.info(
|
||||
f"Chunk duration output: {chunk_duration_output}, input: {chunk_duration_input}, left len: {left_len}"
|
||||
)
|
||||
|
||||
# remove chunk from store
|
||||
self.chunk_store.pop(0)
|
||||
if chunk.duration > chunk_duration_input:
|
||||
left_chunk = attrs.evolve(
|
||||
chunk, audio=chunk.audio[chunk_duration_input:]
|
||||
)
|
||||
chunk = attrs.evolve(chunk, audio=chunk.audio[:chunk_duration_input])
|
||||
|
||||
self.chunk_store.insert(0, left_chunk)
|
||||
break_flag = True
|
||||
|
||||
if chunk.is_speech:
|
||||
# if is_speech, just concat
|
||||
output_audio = np.concatenate([output_audio, chunk.audio])
|
||||
else:
|
||||
# if is_silence, concat with zeros and compress with silence_compress_rate
|
||||
output_audio = np.concatenate(
|
||||
[
|
||||
output_audio,
|
||||
np.zeros(
|
||||
chunk_duration_output,
|
||||
dtype=np.float32,
|
||||
),
|
||||
]
|
||||
)
|
||||
|
||||
if break_flag:
|
||||
break
|
||||
LOG.info(f"Chunk store: {self.chunk_store}, output_audio: {output_audio.shape}")
|
||||
# make same length (errors)
|
||||
output_audio = output_audio[:input_audio_len]
|
||||
output_audio = np.concatenate(
|
||||
[
|
||||
output_audio,
|
||||
np.zeros(input_audio_len - output_audio.shape[0], dtype=np.float32),
|
||||
]
|
||||
)
|
||||
return output_audio
|
||||
@@ -0,0 +1,226 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Literal
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile
|
||||
import torch
|
||||
from cm_time import timer
|
||||
|
||||
from .inference.infer_tool import RealtimeVC, RealtimeVC2, Svc
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def infer(
|
||||
*,
|
||||
# paths
|
||||
input_path: Path | str,
|
||||
output_path: Path | str,
|
||||
model_path: Path | str,
|
||||
config_path: Path | str,
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
device: Literal["cpu", "cuda"] = "cuda" if torch.cuda.is_available() else "cpu",
|
||||
):
|
||||
model_path = Path(model_path)
|
||||
output_path = Path(output_path)
|
||||
input_path = Path(input_path)
|
||||
config_path = Path(config_path)
|
||||
cluster_model_path = Path(cluster_model_path) if cluster_model_path else None
|
||||
svc_model = Svc(
|
||||
net_g_path=model_path.as_posix(),
|
||||
config_path=config_path.as_posix(),
|
||||
cluster_model_path=cluster_model_path.as_posix()
|
||||
if cluster_model_path
|
||||
else None,
|
||||
device=device,
|
||||
)
|
||||
|
||||
audio, _ = librosa.load(input_path, sr=svc_model.target_sample)
|
||||
audio = svc_model.infer_silence(
|
||||
audio.astype(np.float32),
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=absolute_thresh,
|
||||
)
|
||||
|
||||
soundfile.write(output_path, audio, svc_model.target_sample)
|
||||
|
||||
|
||||
def realtime(
|
||||
*,
|
||||
# paths
|
||||
model_path: Path | str,
|
||||
config_path: Path | str,
|
||||
# svc config
|
||||
speaker: str,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "crepe",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
# realtime config
|
||||
crossfade_seconds: float = 0.05,
|
||||
additional_infer_before_seconds: float = 0.2,
|
||||
additional_infer_after_seconds: float = 0.1,
|
||||
block_seconds: float = 0.5,
|
||||
version: int = 2,
|
||||
input_device: int | str | None = None,
|
||||
output_device: int | str | None = None,
|
||||
device: Literal["cpu", "cuda"] = "cuda" if torch.cuda.is_available() else "cpu",
|
||||
passthrough_original: bool = False,
|
||||
):
|
||||
import sounddevice as sd
|
||||
|
||||
model_path = Path(model_path)
|
||||
config_path = Path(config_path)
|
||||
cluster_model_path = Path(cluster_model_path) if cluster_model_path else None
|
||||
svc_model = Svc(
|
||||
net_g_path=model_path.as_posix(),
|
||||
config_path=config_path.as_posix(),
|
||||
cluster_model_path=cluster_model_path.as_posix()
|
||||
if cluster_model_path
|
||||
else None,
|
||||
device=device,
|
||||
)
|
||||
|
||||
LOG.info("Creating realtime model...")
|
||||
if version == 1:
|
||||
model = RealtimeVC(
|
||||
svc_model=svc_model,
|
||||
crossfade_len=int(crossfade_seconds * svc_model.target_sample),
|
||||
additional_infer_before_len=int(
|
||||
additional_infer_before_seconds * svc_model.target_sample
|
||||
),
|
||||
additional_infer_after_len=int(
|
||||
additional_infer_after_seconds * svc_model.target_sample
|
||||
),
|
||||
)
|
||||
else:
|
||||
model = RealtimeVC2(
|
||||
svc_model=svc_model,
|
||||
)
|
||||
|
||||
# LOG all device info
|
||||
devices = sd.query_devices()
|
||||
LOG.info(f"Device: {devices}")
|
||||
if isinstance(input_device, str):
|
||||
input_device_candidates = [
|
||||
i for i, d in enumerate(devices) if d["name"] == input_device
|
||||
]
|
||||
if len(input_device_candidates) == 0:
|
||||
LOG.warning(f"Input device {input_device} not found, using default")
|
||||
input_device = None
|
||||
else:
|
||||
input_device = input_device_candidates[0]
|
||||
if isinstance(output_device, str):
|
||||
output_device_candidates = [
|
||||
i for i, d in enumerate(devices) if d["name"] == output_device
|
||||
]
|
||||
if len(output_device_candidates) == 0:
|
||||
LOG.warning(f"Output device {output_device} not found, using default")
|
||||
output_device = None
|
||||
else:
|
||||
output_device = output_device_candidates[0]
|
||||
if input_device is None or input_device >= len(devices):
|
||||
input_device = sd.default.device[0]
|
||||
if output_device is None or output_device >= len(devices):
|
||||
output_device = sd.default.device[1]
|
||||
LOG.info(
|
||||
f"Input Device: {devices[input_device]['name']}, Output Device: {devices[output_device]['name']}"
|
||||
)
|
||||
|
||||
# the model realtime coef is somewhat significantly low only in the first inference
|
||||
# there could be no better way to warm up the model than to do a dummy inference
|
||||
# (there are not differences in the behavior of the model between the first and the later inferences)
|
||||
# so we do a dummy inference to warm up the model (1 second of audio)
|
||||
LOG.info("Warming up the model...")
|
||||
svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
audio=np.zeros(svc_model.target_sample, dtype=np.float32),
|
||||
)
|
||||
|
||||
def callback(
|
||||
indata: np.ndarray,
|
||||
outdata: np.ndarray,
|
||||
frames: int,
|
||||
time: int,
|
||||
status: sd.CallbackFlags,
|
||||
) -> None:
|
||||
LOG.debug(
|
||||
f"Frames: {frames}, Status: {status}, Shape: {indata.shape}, Time: {time}"
|
||||
)
|
||||
|
||||
kwargs = dict(
|
||||
input_audio=indata.mean(axis=1).astype(np.float32),
|
||||
# svc config
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
# slice config
|
||||
db_thresh=db_thresh,
|
||||
# pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
)
|
||||
if version == 1:
|
||||
kwargs["pad_seconds"] = pad_seconds
|
||||
with timer() as t:
|
||||
inference = model.process(
|
||||
**kwargs,
|
||||
).reshape(-1, 1)
|
||||
if passthrough_original:
|
||||
outdata[:] = (indata + inference) / 2
|
||||
else:
|
||||
outdata[:] = inference
|
||||
LOG.info(f"True Realtime coef: {block_seconds / t.elapsed:.2f}")
|
||||
|
||||
with sd.Stream(
|
||||
device=(input_device, output_device),
|
||||
channels=1,
|
||||
callback=callback,
|
||||
samplerate=svc_model.target_sample,
|
||||
blocksize=int(block_seconds * svc_model.target_sample),
|
||||
latency="low",
|
||||
) as stream:
|
||||
while True:
|
||||
LOG.info(f"Latency: {stream.latency}")
|
||||
sd.sleep(1000)
|
||||
@@ -0,0 +1,519 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import Conv1d, Conv2d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import spectral_norm, weight_norm
|
||||
|
||||
import so_vits_svc_fork.modules.attentions as attentions
|
||||
import so_vits_svc_fork.modules.commons as commons
|
||||
import so_vits_svc_fork.modules.modules as modules
|
||||
|
||||
from . import utils
|
||||
from .modules.commons import get_padding
|
||||
from .utils import f0_to_coarse
|
||||
from .vdecoder.hifigan.models import Generator
|
||||
|
||||
|
||||
class ResidualCouplingBlock(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
n_flows=4,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.n_flows = n_flows
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.flows = nn.ModuleList()
|
||||
for i in range(n_flows):
|
||||
self.flows.append(
|
||||
modules.ResidualCouplingLayer(
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
mean_only=True,
|
||||
)
|
||||
)
|
||||
self.flows.append(modules.Flip())
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
if not reverse:
|
||||
for flow in self.flows:
|
||||
x, _ = flow(x, x_mask, g=g, reverse=reverse)
|
||||
else:
|
||||
for flow in reversed(self.flows):
|
||||
x = flow(x, x_mask, g=g, reverse=reverse)
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.pre = nn.Conv1d(in_channels, hidden_channels, 1)
|
||||
self.enc = modules.WN(
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
|
||||
def forward(self, x, x_lengths, g=None):
|
||||
# print(x.shape,x_lengths.shape)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(x_lengths, x.size(2)), 1).to(
|
||||
x.dtype
|
||||
)
|
||||
x = self.pre(x) * x_mask
|
||||
x = self.enc(x, x_mask, g=g)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs)) * x_mask
|
||||
return z, m, logs, x_mask
|
||||
|
||||
|
||||
class TextEncoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
filter_channels=None,
|
||||
n_heads=None,
|
||||
p_dropout=None,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
self.f0_emb = nn.Embedding(256, hidden_channels)
|
||||
|
||||
self.enc_ = attentions.Encoder(
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
|
||||
def forward(self, x, x_mask, f0=None, noice_scale=1):
|
||||
x = x + self.f0_emb(f0).transpose(1, 2)
|
||||
x = self.enc_(x * x_mask, x_mask)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs) * noice_scale) * x_mask
|
||||
|
||||
return z, m, logs, x_mask
|
||||
|
||||
|
||||
class DiscriminatorP(torch.nn.Module):
|
||||
def __init__(self, period, kernel_size=5, stride=3, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
self.period = period
|
||||
self.use_spectral_norm = use_spectral_norm
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1,
|
||||
32,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
32,
|
||||
128,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
128,
|
||||
512,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
512,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1024,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
1,
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv2d(1024, 1, (3, 1), 1, padding=(1, 0)))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
# 1d to 2d
|
||||
b, c, t = x.shape
|
||||
if t % self.period != 0: # pad first
|
||||
n_pad = self.period - (t % self.period)
|
||||
x = F.pad(x, (0, n_pad), "reflect")
|
||||
t = t + n_pad
|
||||
x = x.view(b, c, t // self.period, self.period)
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class DiscriminatorS(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(Conv1d(1, 16, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(16, 64, 41, 4, groups=4, padding=20)),
|
||||
norm_f(Conv1d(64, 256, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 1024, 41, 4, groups=64, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 4, groups=256, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv1d(1024, 1, 3, 1, padding=1))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class MultiPeriodDiscriminator(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
periods = [2, 3, 5, 7, 11]
|
||||
|
||||
discs = [DiscriminatorS(use_spectral_norm=use_spectral_norm)]
|
||||
discs = discs + [
|
||||
DiscriminatorP(i, use_spectral_norm=use_spectral_norm) for i in periods
|
||||
]
|
||||
self.discriminators = nn.ModuleList(discs)
|
||||
|
||||
def forward(self, y, y_hat):
|
||||
y_d_rs = []
|
||||
y_d_gs = []
|
||||
fmap_rs = []
|
||||
fmap_gs = []
|
||||
for i, d in enumerate(self.discriminators):
|
||||
y_d_r, fmap_r = d(y)
|
||||
y_d_g, fmap_g = d(y_hat)
|
||||
y_d_rs.append(y_d_r)
|
||||
y_d_gs.append(y_d_g)
|
||||
fmap_rs.append(fmap_r)
|
||||
fmap_gs.append(fmap_g)
|
||||
|
||||
return y_d_rs, y_d_gs, fmap_rs, fmap_gs
|
||||
|
||||
|
||||
class SpeakerEncoder(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
mel_n_channels=80,
|
||||
model_num_layers=3,
|
||||
model_hidden_size=256,
|
||||
model_embedding_size=256,
|
||||
):
|
||||
super().__init__()
|
||||
self.lstm = nn.LSTM(
|
||||
mel_n_channels, model_hidden_size, model_num_layers, batch_first=True
|
||||
)
|
||||
self.linear = nn.Linear(model_hidden_size, model_embedding_size)
|
||||
self.relu = nn.ReLU()
|
||||
|
||||
def forward(self, mels):
|
||||
self.lstm.flatten_parameters()
|
||||
_, (hidden, _) = self.lstm(mels)
|
||||
embeds_raw = self.relu(self.linear(hidden[-1]))
|
||||
return embeds_raw / torch.norm(embeds_raw, dim=1, keepdim=True)
|
||||
|
||||
def compute_partial_slices(self, total_frames, partial_frames, partial_hop):
|
||||
mel_slices = []
|
||||
for i in range(0, total_frames - partial_frames, partial_hop):
|
||||
mel_range = torch.arange(i, i + partial_frames)
|
||||
mel_slices.append(mel_range)
|
||||
|
||||
return mel_slices
|
||||
|
||||
def embed_utterance(self, mel, partial_frames=128, partial_hop=64):
|
||||
mel_len = mel.size(1)
|
||||
last_mel = mel[:, -partial_frames:]
|
||||
|
||||
if mel_len > partial_frames:
|
||||
mel_slices = self.compute_partial_slices(
|
||||
mel_len, partial_frames, partial_hop
|
||||
)
|
||||
mels = list(mel[:, s] for s in mel_slices)
|
||||
mels.append(last_mel)
|
||||
mels = torch.stack(tuple(mels), 0).squeeze(1)
|
||||
|
||||
with torch.no_grad():
|
||||
partial_embeds = self(mels)
|
||||
embed = torch.mean(partial_embeds, axis=0).unsqueeze(0)
|
||||
# embed = embed / torch.linalg.norm(embed, 2)
|
||||
else:
|
||||
with torch.no_grad():
|
||||
embed = self(last_mel)
|
||||
|
||||
return embed
|
||||
|
||||
|
||||
class F0Decoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.spk_channels = spk_channels
|
||||
|
||||
self.prenet = nn.Conv1d(hidden_channels, hidden_channels, 3, padding=1)
|
||||
self.decoder = attentions.FFT(
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.f0_prenet = nn.Conv1d(1, hidden_channels, 3, padding=1)
|
||||
self.cond = nn.Conv1d(spk_channels, hidden_channels, 1)
|
||||
|
||||
def forward(self, x, norm_f0, x_mask, spk_emb=None):
|
||||
x = torch.detach(x)
|
||||
if spk_emb is not None:
|
||||
x = x + self.cond(spk_emb)
|
||||
x += self.f0_prenet(norm_f0)
|
||||
x = self.prenet(x) * x_mask
|
||||
x = self.decoder(x * x_mask, x_mask)
|
||||
x = self.proj(x) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class SynthesizerTrn(nn.Module):
|
||||
"""
|
||||
Synthesizer for Training
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
spec_channels,
|
||||
segment_size,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gin_channels,
|
||||
ssl_dim,
|
||||
n_speakers,
|
||||
sampling_rate=44100,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.spec_channels = spec_channels
|
||||
self.inter_channels = inter_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.resblock = resblock
|
||||
self.resblock_kernel_sizes = resblock_kernel_sizes
|
||||
self.resblock_dilation_sizes = resblock_dilation_sizes
|
||||
self.upsample_rates = upsample_rates
|
||||
self.upsample_initial_channel = upsample_initial_channel
|
||||
self.upsample_kernel_sizes = upsample_kernel_sizes
|
||||
self.segment_size = segment_size
|
||||
self.gin_channels = gin_channels
|
||||
self.ssl_dim = ssl_dim
|
||||
self.emb_g = nn.Embedding(n_speakers, gin_channels)
|
||||
|
||||
self.pre = nn.Conv1d(ssl_dim, hidden_channels, kernel_size=5, padding=2)
|
||||
|
||||
self.enc_p = TextEncoder(
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels=filter_channels,
|
||||
n_heads=n_heads,
|
||||
n_layers=n_layers,
|
||||
kernel_size=kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
)
|
||||
hps = {
|
||||
"sampling_rate": sampling_rate,
|
||||
"inter_channels": inter_channels,
|
||||
"resblock": resblock,
|
||||
"resblock_kernel_sizes": resblock_kernel_sizes,
|
||||
"resblock_dilation_sizes": resblock_dilation_sizes,
|
||||
"upsample_rates": upsample_rates,
|
||||
"upsample_initial_channel": upsample_initial_channel,
|
||||
"upsample_kernel_sizes": upsample_kernel_sizes,
|
||||
"gin_channels": gin_channels,
|
||||
}
|
||||
self.dec = Generator(h=hps)
|
||||
self.enc_q = Encoder(
|
||||
spec_channels,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
5,
|
||||
1,
|
||||
16,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.flow = ResidualCouplingBlock(
|
||||
inter_channels, hidden_channels, 5, 1, 4, gin_channels=gin_channels
|
||||
)
|
||||
self.f0_decoder = F0Decoder(
|
||||
1,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=gin_channels,
|
||||
)
|
||||
self.emb_uv = nn.Embedding(2, hidden_channels)
|
||||
|
||||
def forward(self, c, f0, uv, spec, g=None, c_lengths=None, spec_lengths=None):
|
||||
g = self.emb_g(g).transpose(1, 2)
|
||||
# ssl prenet
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(
|
||||
c.dtype
|
||||
)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1, 2)
|
||||
|
||||
# f0 predict
|
||||
lf0 = 2595.0 * torch.log10(1.0 + f0.unsqueeze(1) / 700.0) / 500
|
||||
norm_lf0 = utils.normalize_f0(lf0, x_mask, uv)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
|
||||
# encoder
|
||||
z_ptemp, m_p, logs_p, _ = self.enc_p(x, x_mask, f0=f0_to_coarse(f0))
|
||||
z, m_q, logs_q, spec_mask = self.enc_q(spec, spec_lengths, g=g)
|
||||
|
||||
# flow
|
||||
z_p = self.flow(z, spec_mask, g=g)
|
||||
z_slice, pitch_slice, ids_slice = commons.rand_slice_segments_with_pitch(
|
||||
z, f0, spec_lengths, self.segment_size
|
||||
)
|
||||
|
||||
# nsf decoder
|
||||
o = self.dec(z_slice, g=g, f0=pitch_slice)
|
||||
|
||||
return (
|
||||
o,
|
||||
ids_slice,
|
||||
spec_mask,
|
||||
(z, z_p, m_p, logs_p, m_q, logs_q),
|
||||
pred_lf0,
|
||||
norm_lf0,
|
||||
lf0,
|
||||
)
|
||||
|
||||
def infer(self, c, f0, uv, g=None, noice_scale=0.35, predict_f0=False):
|
||||
c_lengths = (torch.ones(c.size(0)) * c.size(-1)).to(c.device)
|
||||
g = self.emb_g(g).transpose(1, 2)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(
|
||||
c.dtype
|
||||
)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1, 2)
|
||||
|
||||
if predict_f0:
|
||||
lf0 = 2595.0 * torch.log10(1.0 + f0.unsqueeze(1) / 700.0) / 500
|
||||
norm_lf0 = utils.normalize_f0(lf0, x_mask, uv, random_scale=False)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
f0 = (700 * (torch.pow(10, pred_lf0 * 500 / 2595) - 1)).squeeze(1)
|
||||
|
||||
z_p, m_p, logs_p, c_mask = self.enc_p(
|
||||
x, x_mask, f0=f0_to_coarse(f0), noice_scale=noice_scale
|
||||
)
|
||||
z = self.flow(z_p, c_mask, g=g, reverse=True)
|
||||
o = self.dec(z * c_mask, g=g, f0=f0)
|
||||
return o
|
||||
@@ -0,0 +1,488 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
from so_vits_svc_fork.modules import commons
|
||||
from so_vits_svc_fork.modules.modules import LayerNorm
|
||||
|
||||
|
||||
class FFT(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers=1,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
proximal_bias=False,
|
||||
proximal_init=True,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
proximal_bias=proximal_bias,
|
||||
proximal_init=proximal_init,
|
||||
)
|
||||
)
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
causal=True,
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(
|
||||
device=x.device, dtype=x.dtype
|
||||
)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
window_size=4,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
window_size=window_size,
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
)
|
||||
)
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
attn_mask = x_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.attn_layers[i](x, x, attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Decoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
proximal_bias=False,
|
||||
proximal_init=True,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.encdec_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
proximal_bias=proximal_bias,
|
||||
proximal_init=proximal_init,
|
||||
)
|
||||
)
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.encdec_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
causal=True,
|
||||
)
|
||||
)
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask, h, h_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(
|
||||
device=x.device, dtype=x.dtype
|
||||
)
|
||||
encdec_attn_mask = h_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.encdec_attn_layers[i](x, h, encdec_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class MultiHeadAttention(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
out_channels,
|
||||
n_heads,
|
||||
p_dropout=0.0,
|
||||
window_size=None,
|
||||
heads_share=True,
|
||||
block_length=None,
|
||||
proximal_bias=False,
|
||||
proximal_init=False,
|
||||
):
|
||||
super().__init__()
|
||||
assert channels % n_heads == 0
|
||||
|
||||
self.channels = channels
|
||||
self.out_channels = out_channels
|
||||
self.n_heads = n_heads
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
self.heads_share = heads_share
|
||||
self.block_length = block_length
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
self.attn = None
|
||||
|
||||
self.k_channels = channels // n_heads
|
||||
self.conv_q = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_k = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_v = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_o = nn.Conv1d(channels, out_channels, 1)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if window_size is not None:
|
||||
n_heads_rel = 1 if heads_share else n_heads
|
||||
rel_stddev = self.k_channels**-0.5
|
||||
self.emb_rel_k = nn.Parameter(
|
||||
torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels)
|
||||
* rel_stddev
|
||||
)
|
||||
self.emb_rel_v = nn.Parameter(
|
||||
torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels)
|
||||
* rel_stddev
|
||||
)
|
||||
|
||||
nn.init.xavier_uniform_(self.conv_q.weight)
|
||||
nn.init.xavier_uniform_(self.conv_k.weight)
|
||||
nn.init.xavier_uniform_(self.conv_v.weight)
|
||||
if proximal_init:
|
||||
with torch.no_grad():
|
||||
self.conv_k.weight.copy_(self.conv_q.weight)
|
||||
self.conv_k.bias.copy_(self.conv_q.bias)
|
||||
|
||||
def forward(self, x, c, attn_mask=None):
|
||||
q = self.conv_q(x)
|
||||
k = self.conv_k(c)
|
||||
v = self.conv_v(c)
|
||||
|
||||
x, self.attn = self.attention(q, k, v, mask=attn_mask)
|
||||
|
||||
x = self.conv_o(x)
|
||||
return x
|
||||
|
||||
def attention(self, query, key, value, mask=None):
|
||||
# reshape [b, d, t] -> [b, n_h, t, d_k]
|
||||
b, d, t_s, t_t = (*key.size(), query.size(2))
|
||||
query = query.view(b, self.n_heads, self.k_channels, t_t).transpose(2, 3)
|
||||
key = key.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
value = value.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
|
||||
scores = torch.matmul(query / math.sqrt(self.k_channels), key.transpose(-2, -1))
|
||||
if self.window_size is not None:
|
||||
assert (
|
||||
t_s == t_t
|
||||
), "Relative attention is only available for self-attention."
|
||||
key_relative_embeddings = self._get_relative_embeddings(self.emb_rel_k, t_s)
|
||||
rel_logits = self._matmul_with_relative_keys(
|
||||
query / math.sqrt(self.k_channels), key_relative_embeddings
|
||||
)
|
||||
scores_local = self._relative_position_to_absolute_position(rel_logits)
|
||||
scores = scores + scores_local
|
||||
if self.proximal_bias:
|
||||
assert t_s == t_t, "Proximal bias is only available for self-attention."
|
||||
scores = scores + self._attention_bias_proximal(t_s).to(
|
||||
device=scores.device, dtype=scores.dtype
|
||||
)
|
||||
if mask is not None:
|
||||
scores = scores.masked_fill(mask == 0, -1e4)
|
||||
if self.block_length is not None:
|
||||
assert (
|
||||
t_s == t_t
|
||||
), "Local attention is only available for self-attention."
|
||||
block_mask = (
|
||||
torch.ones_like(scores)
|
||||
.triu(-self.block_length)
|
||||
.tril(self.block_length)
|
||||
)
|
||||
scores = scores.masked_fill(block_mask == 0, -1e4)
|
||||
p_attn = F.softmax(scores, dim=-1) # [b, n_h, t_t, t_s]
|
||||
p_attn = self.drop(p_attn)
|
||||
output = torch.matmul(p_attn, value)
|
||||
if self.window_size is not None:
|
||||
relative_weights = self._absolute_position_to_relative_position(p_attn)
|
||||
value_relative_embeddings = self._get_relative_embeddings(
|
||||
self.emb_rel_v, t_s
|
||||
)
|
||||
output = output + self._matmul_with_relative_values(
|
||||
relative_weights, value_relative_embeddings
|
||||
)
|
||||
output = (
|
||||
output.transpose(2, 3).contiguous().view(b, d, t_t)
|
||||
) # [b, n_h, t_t, d_k] -> [b, d, t_t]
|
||||
return output, p_attn
|
||||
|
||||
def _matmul_with_relative_values(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, m]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, d]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0))
|
||||
return ret
|
||||
|
||||
def _matmul_with_relative_keys(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, d]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, m]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0).transpose(-2, -1))
|
||||
return ret
|
||||
|
||||
def _get_relative_embeddings(self, relative_embeddings, length):
|
||||
2 * self.window_size + 1
|
||||
# Pad first before slice to avoid using cond ops.
|
||||
pad_length = max(length - (self.window_size + 1), 0)
|
||||
slice_start_position = max((self.window_size + 1) - length, 0)
|
||||
slice_end_position = slice_start_position + 2 * length - 1
|
||||
if pad_length > 0:
|
||||
padded_relative_embeddings = F.pad(
|
||||
relative_embeddings,
|
||||
commons.convert_pad_shape([[0, 0], [pad_length, pad_length], [0, 0]]),
|
||||
)
|
||||
else:
|
||||
padded_relative_embeddings = relative_embeddings
|
||||
used_relative_embeddings = padded_relative_embeddings[
|
||||
:, slice_start_position:slice_end_position
|
||||
]
|
||||
return used_relative_embeddings
|
||||
|
||||
def _relative_position_to_absolute_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, 2*l-1]
|
||||
ret: [b, h, l, l]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# Concat columns of pad to shift from relative to absolute indexing.
|
||||
x = F.pad(x, commons.convert_pad_shape([[0, 0], [0, 0], [0, 0], [0, 1]]))
|
||||
|
||||
# Concat extra elements so to add up to shape (len+1, 2*len-1).
|
||||
x_flat = x.view([batch, heads, length * 2 * length])
|
||||
x_flat = F.pad(
|
||||
x_flat, commons.convert_pad_shape([[0, 0], [0, 0], [0, length - 1]])
|
||||
)
|
||||
|
||||
# Reshape and slice out the padded elements.
|
||||
x_final = x_flat.view([batch, heads, length + 1, 2 * length - 1])[
|
||||
:, :, :length, length - 1 :
|
||||
]
|
||||
return x_final
|
||||
|
||||
def _absolute_position_to_relative_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, l]
|
||||
ret: [b, h, l, 2*l-1]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# pad along column
|
||||
x = F.pad(
|
||||
x, commons.convert_pad_shape([[0, 0], [0, 0], [0, 0], [0, length - 1]])
|
||||
)
|
||||
x_flat = x.view([batch, heads, length**2 + length * (length - 1)])
|
||||
# add 0's in the beginning that will skew the elements after reshape
|
||||
x_flat = F.pad(x_flat, commons.convert_pad_shape([[0, 0], [0, 0], [length, 0]]))
|
||||
x_final = x_flat.view([batch, heads, length, 2 * length])[:, :, :, 1:]
|
||||
return x_final
|
||||
|
||||
def _attention_bias_proximal(self, length):
|
||||
"""Bias for self-attention to encourage attention to close positions.
|
||||
Args:
|
||||
length: an integer scalar.
|
||||
Returns:
|
||||
a Tensor with shape [1, 1, length, length]
|
||||
"""
|
||||
r = torch.arange(length, dtype=torch.float32)
|
||||
diff = torch.unsqueeze(r, 0) - torch.unsqueeze(r, 1)
|
||||
return torch.unsqueeze(torch.unsqueeze(-torch.log1p(torch.abs(diff)), 0), 0)
|
||||
|
||||
|
||||
class FFN(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=0.0,
|
||||
activation=None,
|
||||
causal=False,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.activation = activation
|
||||
self.causal = causal
|
||||
|
||||
if causal:
|
||||
self.padding = self._causal_padding
|
||||
else:
|
||||
self.padding = self._same_padding
|
||||
|
||||
self.conv_1 = nn.Conv1d(in_channels, filter_channels, kernel_size)
|
||||
self.conv_2 = nn.Conv1d(filter_channels, out_channels, kernel_size)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x = self.conv_1(self.padding(x * x_mask))
|
||||
if self.activation == "gelu":
|
||||
x = x * torch.sigmoid(1.702 * x)
|
||||
else:
|
||||
x = torch.relu(x)
|
||||
x = self.drop(x)
|
||||
x = self.conv_2(self.padding(x * x_mask))
|
||||
return x * x_mask
|
||||
|
||||
def _causal_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = self.kernel_size - 1
|
||||
pad_r = 0
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
|
||||
def _same_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = (self.kernel_size - 1) // 2
|
||||
pad_r = self.kernel_size // 2
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
@@ -0,0 +1,186 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
from torch.nn import functional as F
|
||||
|
||||
|
||||
def slice_pitch_segments(x, ids_str, segment_size=4):
|
||||
ret = torch.zeros_like(x[:, :segment_size])
|
||||
for i in range(x.size(0)):
|
||||
idx_str = ids_str[i]
|
||||
idx_end = idx_str + segment_size
|
||||
ret[i] = x[i, idx_str:idx_end]
|
||||
return ret
|
||||
|
||||
|
||||
def rand_slice_segments_with_pitch(x, pitch, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size + 1
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
ret_pitch = slice_pitch_segments(pitch, ids_str, segment_size)
|
||||
return ret, ret_pitch, ids_str
|
||||
|
||||
|
||||
def init_weights(m, mean=0.0, std=0.01):
|
||||
classname = m.__class__.__name__
|
||||
if classname.find("Conv") != -1:
|
||||
m.weight.data.normal_(mean, std)
|
||||
|
||||
|
||||
def get_padding(kernel_size, dilation=1):
|
||||
return int((kernel_size * dilation - dilation) / 2)
|
||||
|
||||
|
||||
def convert_pad_shape(pad_shape):
|
||||
l = pad_shape[::-1]
|
||||
pad_shape = [item for sublist in l for item in sublist]
|
||||
return pad_shape
|
||||
|
||||
|
||||
def intersperse(lst, item):
|
||||
result = [item] * (len(lst) * 2 + 1)
|
||||
result[1::2] = lst
|
||||
return result
|
||||
|
||||
|
||||
def kl_divergence(m_p, logs_p, m_q, logs_q):
|
||||
"""KL(P||Q)"""
|
||||
kl = (logs_q - logs_p) - 0.5
|
||||
kl += (
|
||||
0.5 * (torch.exp(2.0 * logs_p) + ((m_p - m_q) ** 2)) * torch.exp(-2.0 * logs_q)
|
||||
)
|
||||
return kl
|
||||
|
||||
|
||||
def rand_gumbel(shape):
|
||||
"""Sample from the Gumbel distribution, protect from overflows."""
|
||||
uniform_samples = torch.rand(shape) * 0.99998 + 0.00001
|
||||
return -torch.log(-torch.log(uniform_samples))
|
||||
|
||||
|
||||
def rand_gumbel_like(x):
|
||||
g = rand_gumbel(x.size()).to(dtype=x.dtype, device=x.device)
|
||||
return g
|
||||
|
||||
|
||||
def slice_segments(x, ids_str, segment_size=4):
|
||||
ret = torch.zeros_like(x[:, :, :segment_size])
|
||||
for i in range(x.size(0)):
|
||||
idx_str = ids_str[i]
|
||||
idx_end = idx_str + segment_size
|
||||
ret[i] = x[i, :, idx_str:idx_end]
|
||||
return ret
|
||||
|
||||
|
||||
def rand_slice_segments(x, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size + 1
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
return ret, ids_str
|
||||
|
||||
|
||||
def rand_spec_segments(x, x_lengths=None, segment_size=4):
|
||||
b, d, t = x.size()
|
||||
if x_lengths is None:
|
||||
x_lengths = t
|
||||
ids_str_max = x_lengths - segment_size
|
||||
ids_str = (torch.rand([b]).to(device=x.device) * ids_str_max).to(dtype=torch.long)
|
||||
ret = slice_segments(x, ids_str, segment_size)
|
||||
return ret, ids_str
|
||||
|
||||
|
||||
def get_timing_signal_1d(length, channels, min_timescale=1.0, max_timescale=1.0e4):
|
||||
position = torch.arange(length, dtype=torch.float)
|
||||
num_timescales = channels // 2
|
||||
log_timescale_increment = math.log(float(max_timescale) / float(min_timescale)) / (
|
||||
num_timescales - 1
|
||||
)
|
||||
inv_timescales = min_timescale * torch.exp(
|
||||
torch.arange(num_timescales, dtype=torch.float) * -log_timescale_increment
|
||||
)
|
||||
scaled_time = position.unsqueeze(0) * inv_timescales.unsqueeze(1)
|
||||
signal = torch.cat([torch.sin(scaled_time), torch.cos(scaled_time)], 0)
|
||||
signal = F.pad(signal, [0, 0, 0, channels % 2])
|
||||
signal = signal.view(1, channels, length)
|
||||
return signal
|
||||
|
||||
|
||||
def add_timing_signal_1d(x, min_timescale=1.0, max_timescale=1.0e4):
|
||||
b, channels, length = x.size()
|
||||
signal = get_timing_signal_1d(length, channels, min_timescale, max_timescale)
|
||||
return x + signal.to(dtype=x.dtype, device=x.device)
|
||||
|
||||
|
||||
def cat_timing_signal_1d(x, min_timescale=1.0, max_timescale=1.0e4, axis=1):
|
||||
b, channels, length = x.size()
|
||||
signal = get_timing_signal_1d(length, channels, min_timescale, max_timescale)
|
||||
return torch.cat([x, signal.to(dtype=x.dtype, device=x.device)], axis)
|
||||
|
||||
|
||||
def subsequent_mask(length):
|
||||
mask = torch.tril(torch.ones(length, length)).unsqueeze(0).unsqueeze(0)
|
||||
return mask
|
||||
|
||||
|
||||
@torch.jit.script
|
||||
def fused_add_tanh_sigmoid_multiply(input_a, input_b, n_channels):
|
||||
n_channels_int = n_channels[0]
|
||||
in_act = input_a + input_b
|
||||
t_act = torch.tanh(in_act[:, :n_channels_int, :])
|
||||
s_act = torch.sigmoid(in_act[:, n_channels_int:, :])
|
||||
acts = t_act * s_act
|
||||
return acts
|
||||
|
||||
|
||||
def shift_1d(x):
|
||||
x = F.pad(x, convert_pad_shape([[0, 0], [0, 0], [1, 0]]))[:, :, :-1]
|
||||
return x
|
||||
|
||||
|
||||
def sequence_mask(length, max_length=None):
|
||||
if max_length is None:
|
||||
max_length = length.max()
|
||||
x = torch.arange(max_length, dtype=length.dtype, device=length.device)
|
||||
return x.unsqueeze(0) < length.unsqueeze(1)
|
||||
|
||||
|
||||
def generate_path(duration, mask):
|
||||
"""
|
||||
duration: [b, 1, t_x]
|
||||
mask: [b, 1, t_y, t_x]
|
||||
"""
|
||||
duration.device
|
||||
|
||||
b, _, t_y, t_x = mask.shape
|
||||
cum_duration = torch.cumsum(duration, -1)
|
||||
|
||||
cum_duration_flat = cum_duration.view(b * t_x)
|
||||
path = sequence_mask(cum_duration_flat, t_y).to(mask.dtype)
|
||||
path = path.view(b, t_x, t_y)
|
||||
path = path - F.pad(path, convert_pad_shape([[0, 0], [1, 0], [0, 0]]))[:, :-1]
|
||||
path = path.unsqueeze(1).transpose(2, 3) * mask
|
||||
return path
|
||||
|
||||
|
||||
def clip_grad_value_(parameters, clip_value, norm_type=2):
|
||||
if isinstance(parameters, torch.Tensor):
|
||||
parameters = [parameters]
|
||||
parameters = list(filter(lambda p: p.grad is not None, parameters))
|
||||
norm_type = float(norm_type)
|
||||
if clip_value is not None:
|
||||
clip_value = float(clip_value)
|
||||
|
||||
total_norm = 0
|
||||
for p in parameters:
|
||||
param_norm = p.grad.data.norm(norm_type)
|
||||
total_norm += param_norm.item() ** norm_type
|
||||
if clip_value is not None:
|
||||
p.grad.data.clamp_(min=-clip_value, max=clip_value)
|
||||
total_norm = total_norm ** (1.0 / norm_type)
|
||||
return total_norm
|
||||
@@ -0,0 +1,58 @@
|
||||
import torch
|
||||
|
||||
|
||||
def feature_loss(fmap_r, fmap_g):
|
||||
loss = 0
|
||||
for dr, dg in zip(fmap_r, fmap_g):
|
||||
for rl, gl in zip(dr, dg):
|
||||
rl = rl.float().detach()
|
||||
gl = gl.float()
|
||||
loss += torch.mean(torch.abs(rl - gl))
|
||||
|
||||
return loss * 2
|
||||
|
||||
|
||||
def discriminator_loss(disc_real_outputs, disc_generated_outputs):
|
||||
loss = 0
|
||||
r_losses = []
|
||||
g_losses = []
|
||||
for dr, dg in zip(disc_real_outputs, disc_generated_outputs):
|
||||
dr = dr.float()
|
||||
dg = dg.float()
|
||||
r_loss = torch.mean((1 - dr) ** 2)
|
||||
g_loss = torch.mean(dg**2)
|
||||
loss += r_loss + g_loss
|
||||
r_losses.append(r_loss.item())
|
||||
g_losses.append(g_loss.item())
|
||||
|
||||
return loss, r_losses, g_losses
|
||||
|
||||
|
||||
def generator_loss(disc_outputs):
|
||||
loss = 0
|
||||
gen_losses = []
|
||||
for dg in disc_outputs:
|
||||
dg = dg.float()
|
||||
l = torch.mean((1 - dg) ** 2)
|
||||
gen_losses.append(l)
|
||||
loss += l
|
||||
|
||||
return loss, gen_losses
|
||||
|
||||
|
||||
def kl_loss(z_p, logs_q, m_p, logs_p, z_mask):
|
||||
"""
|
||||
z_p, logs_q: [b, h, t_t]
|
||||
m_p, logs_p: [b, h, t_t]
|
||||
"""
|
||||
z_p = z_p.float()
|
||||
logs_q = logs_q.float()
|
||||
m_p = m_p.float()
|
||||
logs_p = logs_p.float()
|
||||
z_mask = z_mask.float()
|
||||
# print(logs_p)
|
||||
kl = logs_p - logs_q - 0.5
|
||||
kl += 0.5 * ((z_p - m_p) ** 2) * torch.exp(-2.0 * logs_p)
|
||||
kl = torch.sum(kl * z_mask)
|
||||
l = kl / torch.sum(z_mask)
|
||||
return l
|
||||
@@ -0,0 +1,147 @@
|
||||
from logging import getLogger
|
||||
|
||||
import torch
|
||||
import torch.utils.data
|
||||
from librosa.filters import mel as librosa_mel_fn
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
MAX_WAV_VALUE = 32768.0
|
||||
|
||||
|
||||
def dynamic_range_compression_torch(x, C=1, clip_val=1e-5):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor
|
||||
"""
|
||||
return torch.log(torch.clamp(x, min=clip_val) * C)
|
||||
|
||||
|
||||
def dynamic_range_decompression_torch(x, C=1):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor used to compress
|
||||
"""
|
||||
return torch.exp(x) / C
|
||||
|
||||
|
||||
def spectral_normalize_torch(magnitudes):
|
||||
output = dynamic_range_compression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
def spectral_de_normalize_torch(magnitudes):
|
||||
output = dynamic_range_decompression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
mel_basis = {}
|
||||
hann_window = {}
|
||||
|
||||
|
||||
def spectrogram_torch(y, n_fft, sampling_rate, hop_size, win_size, center=False):
|
||||
if torch.min(y) < -1.0:
|
||||
LOG.info("min value is ", torch.min(y))
|
||||
if torch.max(y) > 1.0:
|
||||
LOG.info("max value is ", torch.max(y))
|
||||
|
||||
global hann_window
|
||||
dtype_device = str(y.dtype) + "_" + str(y.device)
|
||||
wnsize_dtype_device = str(win_size) + "_" + dtype_device
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
|
||||
y = torch.nn.functional.pad(
|
||||
y.unsqueeze(1),
|
||||
(int((n_fft - hop_size) / 2), int((n_fft - hop_size) / 2)),
|
||||
mode="reflect",
|
||||
)
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(
|
||||
y,
|
||||
n_fft,
|
||||
hop_length=hop_size,
|
||||
win_length=win_size,
|
||||
window=hann_window[wnsize_dtype_device],
|
||||
center=center,
|
||||
pad_mode="reflect",
|
||||
normalized=False,
|
||||
onesided=True,
|
||||
return_complex=False,
|
||||
)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
return spec
|
||||
|
||||
|
||||
def spec_to_mel_torch(spec, n_fft, num_mels, sampling_rate, fmin, fmax):
|
||||
global mel_basis
|
||||
dtype_device = str(spec.dtype) + "_" + str(spec.device)
|
||||
fmax_dtype_device = str(fmax) + "_" + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(
|
||||
sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax
|
||||
)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(
|
||||
dtype=spec.dtype, device=spec.device
|
||||
)
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
return spec
|
||||
|
||||
|
||||
def mel_spectrogram_torch(
|
||||
y, n_fft, num_mels, sampling_rate, hop_size, win_size, fmin, fmax, center=False
|
||||
):
|
||||
if torch.min(y) < -1.0:
|
||||
LOG.info("min value is ", torch.min(y))
|
||||
if torch.max(y) > 1.0:
|
||||
LOG.info("max value is ", torch.max(y))
|
||||
|
||||
global mel_basis, hann_window
|
||||
dtype_device = str(y.dtype) + "_" + str(y.device)
|
||||
fmax_dtype_device = str(fmax) + "_" + dtype_device
|
||||
wnsize_dtype_device = str(win_size) + "_" + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(
|
||||
sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax
|
||||
)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
|
||||
y = torch.nn.functional.pad(
|
||||
y.unsqueeze(1),
|
||||
(int((n_fft - hop_size) / 2), int((n_fft - hop_size) / 2)),
|
||||
mode="reflect",
|
||||
)
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(
|
||||
y,
|
||||
n_fft,
|
||||
hop_length=hop_size,
|
||||
win_length=win_size,
|
||||
window=hann_window[wnsize_dtype_device],
|
||||
center=center,
|
||||
pad_mode="reflect",
|
||||
normalized=False,
|
||||
onesided=True,
|
||||
return_complex=False,
|
||||
)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
|
||||
return spec
|
||||
@@ -0,0 +1,452 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import Conv1d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import remove_weight_norm, weight_norm
|
||||
|
||||
from so_vits_svc_fork.modules import commons
|
||||
from so_vits_svc_fork.modules.commons import get_padding, init_weights
|
||||
|
||||
LRELU_SLOPE = 0.1
|
||||
|
||||
|
||||
class LayerNorm(nn.Module):
|
||||
def __init__(self, channels, eps=1e-5):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.eps = eps
|
||||
|
||||
self.gamma = nn.Parameter(torch.ones(channels))
|
||||
self.beta = nn.Parameter(torch.zeros(channels))
|
||||
|
||||
def forward(self, x):
|
||||
x = x.transpose(1, -1)
|
||||
x = F.layer_norm(x, (self.channels,), self.gamma, self.beta, self.eps)
|
||||
return x.transpose(1, -1)
|
||||
|
||||
|
||||
class ConvReluNorm(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
hidden_channels,
|
||||
out_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
p_dropout,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.out_channels = out_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
assert n_layers > 1, "Number of layers should be larger than 0."
|
||||
|
||||
self.conv_layers = nn.ModuleList()
|
||||
self.norm_layers = nn.ModuleList()
|
||||
self.conv_layers.append(
|
||||
nn.Conv1d(
|
||||
in_channels, hidden_channels, kernel_size, padding=kernel_size // 2
|
||||
)
|
||||
)
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.relu_drop = nn.Sequential(nn.ReLU(), nn.Dropout(p_dropout))
|
||||
for _ in range(n_layers - 1):
|
||||
self.conv_layers.append(
|
||||
nn.Conv1d(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
padding=kernel_size // 2,
|
||||
)
|
||||
)
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.proj.weight.data.zero_()
|
||||
self.proj.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x_org = x
|
||||
for i in range(self.n_layers):
|
||||
x = self.conv_layers[i](x * x_mask)
|
||||
x = self.norm_layers[i](x)
|
||||
x = self.relu_drop(x)
|
||||
x = x_org + self.proj(x)
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class DDSConv(nn.Module):
|
||||
"""
|
||||
Dialted and Depth-Separable Convolution
|
||||
"""
|
||||
|
||||
def __init__(self, channels, kernel_size, n_layers, p_dropout=0.0):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.convs_sep = nn.ModuleList()
|
||||
self.convs_1x1 = nn.ModuleList()
|
||||
self.norms_1 = nn.ModuleList()
|
||||
self.norms_2 = nn.ModuleList()
|
||||
for i in range(n_layers):
|
||||
dilation = kernel_size**i
|
||||
padding = (kernel_size * dilation - dilation) // 2
|
||||
self.convs_sep.append(
|
||||
nn.Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
groups=channels,
|
||||
dilation=dilation,
|
||||
padding=padding,
|
||||
)
|
||||
)
|
||||
self.convs_1x1.append(nn.Conv1d(channels, channels, 1))
|
||||
self.norms_1.append(LayerNorm(channels))
|
||||
self.norms_2.append(LayerNorm(channels))
|
||||
|
||||
def forward(self, x, x_mask, g=None):
|
||||
if g is not None:
|
||||
x = x + g
|
||||
for i in range(self.n_layers):
|
||||
y = self.convs_sep[i](x * x_mask)
|
||||
y = self.norms_1[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.convs_1x1[i](y)
|
||||
y = self.norms_2[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.drop(y)
|
||||
x = x + y
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class WN(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
p_dropout=0,
|
||||
):
|
||||
super().__init__()
|
||||
assert kernel_size % 2 == 1
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = (kernel_size,)
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.in_layers = torch.nn.ModuleList()
|
||||
self.res_skip_layers = torch.nn.ModuleList()
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if gin_channels != 0:
|
||||
cond_layer = torch.nn.Conv1d(
|
||||
gin_channels, 2 * hidden_channels * n_layers, 1
|
||||
)
|
||||
self.cond_layer = torch.nn.utils.weight_norm(cond_layer, name="weight")
|
||||
|
||||
for i in range(n_layers):
|
||||
dilation = dilation_rate**i
|
||||
padding = int((kernel_size * dilation - dilation) / 2)
|
||||
in_layer = torch.nn.Conv1d(
|
||||
hidden_channels,
|
||||
2 * hidden_channels,
|
||||
kernel_size,
|
||||
dilation=dilation,
|
||||
padding=padding,
|
||||
)
|
||||
in_layer = torch.nn.utils.weight_norm(in_layer, name="weight")
|
||||
self.in_layers.append(in_layer)
|
||||
|
||||
# last one is not necessary
|
||||
if i < n_layers - 1:
|
||||
res_skip_channels = 2 * hidden_channels
|
||||
else:
|
||||
res_skip_channels = hidden_channels
|
||||
|
||||
res_skip_layer = torch.nn.Conv1d(hidden_channels, res_skip_channels, 1)
|
||||
res_skip_layer = torch.nn.utils.weight_norm(res_skip_layer, name="weight")
|
||||
self.res_skip_layers.append(res_skip_layer)
|
||||
|
||||
def forward(self, x, x_mask, g=None, **kwargs):
|
||||
output = torch.zeros_like(x)
|
||||
n_channels_tensor = torch.IntTensor([self.hidden_channels])
|
||||
|
||||
if g is not None:
|
||||
g = self.cond_layer(g)
|
||||
|
||||
for i in range(self.n_layers):
|
||||
x_in = self.in_layers[i](x)
|
||||
if g is not None:
|
||||
cond_offset = i * 2 * self.hidden_channels
|
||||
g_l = g[:, cond_offset : cond_offset + 2 * self.hidden_channels, :]
|
||||
else:
|
||||
g_l = torch.zeros_like(x_in)
|
||||
|
||||
acts = commons.fused_add_tanh_sigmoid_multiply(x_in, g_l, n_channels_tensor)
|
||||
acts = self.drop(acts)
|
||||
|
||||
res_skip_acts = self.res_skip_layers[i](acts)
|
||||
if i < self.n_layers - 1:
|
||||
res_acts = res_skip_acts[:, : self.hidden_channels, :]
|
||||
x = (x + res_acts) * x_mask
|
||||
output = output + res_skip_acts[:, self.hidden_channels :, :]
|
||||
else:
|
||||
output = output + res_skip_acts
|
||||
return output * x_mask
|
||||
|
||||
def remove_weight_norm(self):
|
||||
if self.gin_channels != 0:
|
||||
torch.nn.utils.remove_weight_norm(self.cond_layer)
|
||||
for l in self.in_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
for l in self.res_skip_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock1(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5)):
|
||||
super().__init__()
|
||||
self.convs1 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[2],
|
||||
padding=get_padding(kernel_size, dilation[2]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs1.apply(init_weights)
|
||||
|
||||
self.convs2 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs2.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c1, c2 in zip(self.convs1, self.convs2):
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c1(xt)
|
||||
xt = F.leaky_relu(xt, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c2(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs1:
|
||||
remove_weight_norm(l)
|
||||
for l in self.convs2:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock2(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3)):
|
||||
super().__init__()
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c in self.convs:
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class Log(nn.Module):
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = torch.log(torch.clamp_min(x, 1e-5)) * x_mask
|
||||
logdet = torch.sum(-y, [1, 2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = torch.exp(x) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Flip(nn.Module):
|
||||
def forward(self, x, *args, reverse=False, **kwargs):
|
||||
x = torch.flip(x, [1])
|
||||
if not reverse:
|
||||
logdet = torch.zeros(x.size(0)).to(dtype=x.dtype, device=x.device)
|
||||
return x, logdet
|
||||
else:
|
||||
return x
|
||||
|
||||
|
||||
class ElementwiseAffine(nn.Module):
|
||||
def __init__(self, channels):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.m = nn.Parameter(torch.zeros(channels, 1))
|
||||
self.logs = nn.Parameter(torch.zeros(channels, 1))
|
||||
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = self.m + torch.exp(self.logs) * x
|
||||
y = y * x_mask
|
||||
logdet = torch.sum(self.logs * x_mask, [1, 2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = (x - self.m) * torch.exp(-self.logs) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class ResidualCouplingLayer(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
p_dropout=0,
|
||||
gin_channels=0,
|
||||
mean_only=False,
|
||||
):
|
||||
assert channels % 2 == 0, "channels should be divisible by 2"
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.half_channels = channels // 2
|
||||
self.mean_only = mean_only
|
||||
|
||||
self.pre = nn.Conv1d(self.half_channels, hidden_channels, 1)
|
||||
self.enc = WN(
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
p_dropout=p_dropout,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.post = nn.Conv1d(hidden_channels, self.half_channels * (2 - mean_only), 1)
|
||||
self.post.weight.data.zero_()
|
||||
self.post.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
x0, x1 = torch.split(x, [self.half_channels] * 2, 1)
|
||||
h = self.pre(x0) * x_mask
|
||||
h = self.enc(h, x_mask, g=g)
|
||||
stats = self.post(h) * x_mask
|
||||
if not self.mean_only:
|
||||
m, logs = torch.split(stats, [self.half_channels] * 2, 1)
|
||||
else:
|
||||
m = stats
|
||||
logs = torch.zeros_like(m)
|
||||
|
||||
if not reverse:
|
||||
x1 = m + x1 * torch.exp(logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
logdet = torch.sum(logs, [1, 2])
|
||||
return x, logdet
|
||||
else:
|
||||
x1 = (x1 - m) * torch.exp(-logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
return x
|
||||
@@ -0,0 +1,65 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import torch
|
||||
|
||||
from . import utils
|
||||
from .onnxexport.model_onnx import SynthesizerTrn
|
||||
|
||||
|
||||
def onnx_export(
|
||||
input_path: Path | str,
|
||||
output_path: Path | str,
|
||||
config_path: Path | str,
|
||||
device: str | torch.device = "cpu",
|
||||
):
|
||||
input_path = Path(input_path)
|
||||
output_path = Path(output_path)
|
||||
config_path = Path(config_path)
|
||||
hps = utils.get_hparams_from_file(config_path.as_posix())
|
||||
SVCVITS = SynthesizerTrn(
|
||||
hps.data.filter_length // 2 + 1,
|
||||
hps.train.segment_size // hps.data.hop_length,
|
||||
**hps.model,
|
||||
)
|
||||
_ = utils.load_checkpoint(input_path.as_posix(), SVCVITS, None)
|
||||
_ = SVCVITS.eval().to(device)
|
||||
for i in SVCVITS.parameters():
|
||||
i.requires_grad = False
|
||||
|
||||
test_hidden_unit = torch.rand(1, 10, 256)
|
||||
test_pitch = torch.rand(1, 10)
|
||||
test_mel2ph = torch.LongTensor([0, 1, 2, 3, 4, 5, 6, 7, 8, 9]).unsqueeze(0)
|
||||
test_uv = torch.ones(1, 10, dtype=torch.float32)
|
||||
test_noise = torch.randn(1, 192, 10)
|
||||
test_sid = torch.LongTensor([0])
|
||||
input_names = ["c", "f0", "mel2ph", "uv", "noise", "sid"]
|
||||
output_names = [
|
||||
"audio",
|
||||
]
|
||||
|
||||
torch.onnx.export(
|
||||
SVCVITS,
|
||||
(
|
||||
test_hidden_unit.to(device),
|
||||
test_pitch.to(device),
|
||||
test_mel2ph.to(device),
|
||||
test_uv.to(device),
|
||||
test_noise.to(device),
|
||||
test_sid.to(device),
|
||||
),
|
||||
output_path.as_posix(),
|
||||
dynamic_axes={
|
||||
"c": [0, 1],
|
||||
"f0": [1],
|
||||
"mel2ph": [1],
|
||||
"uv": [1],
|
||||
"noise": [2],
|
||||
},
|
||||
do_constant_folding=False,
|
||||
opset_version=16,
|
||||
verbose=False,
|
||||
input_names=input_names,
|
||||
output_names=output_names,
|
||||
)
|
||||
+179
-108
@@ -1,29 +1,29 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import Conv1d, Conv2d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import spectral_norm, weight_norm
|
||||
|
||||
import modules.attentions as attentions
|
||||
import modules.commons as commons
|
||||
import modules.modules as modules
|
||||
|
||||
from torch.nn import Conv1d, ConvTranspose1d, AvgPool1d, Conv2d
|
||||
from torch.nn.utils import weight_norm, remove_weight_norm, spectral_norm
|
||||
|
||||
import utils
|
||||
from modules.commons import init_weights, get_padding
|
||||
from vdecoder.hifigan.models import Generator
|
||||
from utils import f0_to_coarse
|
||||
from so_vits_svc_fork import modules as attentions
|
||||
from so_vits_svc_fork import modules as commons
|
||||
from so_vits_svc_fork import modules as modules
|
||||
from so_vits_svc_fork import utils
|
||||
from so_vits_svc_fork.modules.commons import get_padding
|
||||
from so_vits_svc_fork.utils import f0_to_coarse
|
||||
from so_vits_svc_fork.vdecoder.hifigan.models import Generator
|
||||
|
||||
|
||||
class ResidualCouplingBlock(nn.Module):
|
||||
def __init__(self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
n_flows=4,
|
||||
gin_channels=0):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
n_flows=4,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
@@ -36,8 +36,16 @@ class ResidualCouplingBlock(nn.Module):
|
||||
self.flows = nn.ModuleList()
|
||||
for i in range(n_flows):
|
||||
self.flows.append(
|
||||
modules.ResidualCouplingLayer(channels, hidden_channels, kernel_size, dilation_rate, n_layers,
|
||||
gin_channels=gin_channels, mean_only=True))
|
||||
modules.ResidualCouplingLayer(
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
mean_only=True,
|
||||
)
|
||||
)
|
||||
self.flows.append(modules.Flip())
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
@@ -51,14 +59,16 @@ class ResidualCouplingBlock(nn.Module):
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
@@ -69,12 +79,20 @@ class Encoder(nn.Module):
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.pre = nn.Conv1d(in_channels, hidden_channels, 1)
|
||||
self.enc = modules.WN(hidden_channels, kernel_size, dilation_rate, n_layers, gin_channels=gin_channels)
|
||||
self.enc = modules.WN(
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
|
||||
def forward(self, x, x_lengths, g=None):
|
||||
# print(x.shape,x_lengths.shape)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(x_lengths, x.size(2)), 1).to(x.dtype)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(x_lengths, x.size(2)), 1).to(
|
||||
x.dtype
|
||||
)
|
||||
x = self.pre(x) * x_mask
|
||||
x = self.enc(x, x_mask, g=g)
|
||||
stats = self.proj(x) * x_mask
|
||||
@@ -84,15 +102,17 @@ class Encoder(nn.Module):
|
||||
|
||||
|
||||
class TextEncoder(nn.Module):
|
||||
def __init__(self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
filter_channels=None,
|
||||
n_heads=None,
|
||||
p_dropout=None):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
filter_channels=None,
|
||||
n_heads=None,
|
||||
p_dropout=None,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
@@ -103,12 +123,8 @@ class TextEncoder(nn.Module):
|
||||
self.f0_emb = nn.Embedding(256, hidden_channels)
|
||||
|
||||
self.enc_ = attentions.Encoder(
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout)
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
|
||||
def forward(self, x, x_mask, f0=None, z=None):
|
||||
x = x + self.f0_emb(f0).transpose(1, 2)
|
||||
@@ -121,17 +137,59 @@ class TextEncoder(nn.Module):
|
||||
|
||||
class DiscriminatorP(torch.nn.Module):
|
||||
def __init__(self, period, kernel_size=5, stride=3, use_spectral_norm=False):
|
||||
super(DiscriminatorP, self).__init__()
|
||||
super().__init__()
|
||||
self.period = period
|
||||
self.use_spectral_norm = use_spectral_norm
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv2d(1, 32, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(32, 128, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(128, 512, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(512, 1024, (kernel_size, 1), (stride, 1), padding=(get_padding(kernel_size, 1), 0))),
|
||||
norm_f(Conv2d(1024, 1024, (kernel_size, 1), 1, padding=(get_padding(kernel_size, 1), 0))),
|
||||
])
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1,
|
||||
32,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
32,
|
||||
128,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
128,
|
||||
512,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
512,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1024,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
1,
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv2d(1024, 1, (3, 1), 1, padding=(1, 0)))
|
||||
|
||||
def forward(self, x):
|
||||
@@ -158,16 +216,18 @@ class DiscriminatorP(torch.nn.Module):
|
||||
|
||||
class DiscriminatorS(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super(DiscriminatorS, self).__init__()
|
||||
super().__init__()
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv1d(1, 16, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(16, 64, 41, 4, groups=4, padding=20)),
|
||||
norm_f(Conv1d(64, 256, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 1024, 41, 4, groups=64, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 4, groups=256, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
])
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(Conv1d(1, 16, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(16, 64, 41, 4, groups=4, padding=20)),
|
||||
norm_f(Conv1d(64, 256, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 1024, 41, 4, groups=64, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 4, groups=256, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv1d(1024, 1, 3, 1, padding=1))
|
||||
|
||||
def forward(self, x):
|
||||
@@ -185,15 +245,17 @@ class DiscriminatorS(torch.nn.Module):
|
||||
|
||||
|
||||
class F0Decoder(nn.Module):
|
||||
def __init__(self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=0):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
@@ -206,12 +268,8 @@ class F0Decoder(nn.Module):
|
||||
|
||||
self.prenet = nn.Conv1d(hidden_channels, hidden_channels, 3, padding=1)
|
||||
self.decoder = attentions.FFT(
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout)
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.f0_prenet = nn.Conv1d(1, hidden_channels, 3, padding=1)
|
||||
self.cond = nn.Conv1d(spk_channels, hidden_channels, 1)
|
||||
@@ -229,30 +287,32 @@ class F0Decoder(nn.Module):
|
||||
|
||||
class SynthesizerTrn(nn.Module):
|
||||
"""
|
||||
Synthesizer for Training
|
||||
"""
|
||||
Synthesizer for Training
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
spec_channels,
|
||||
segment_size,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gin_channels,
|
||||
ssl_dim,
|
||||
n_speakers,
|
||||
sampling_rate=44100,
|
||||
**kwargs):
|
||||
def __init__(
|
||||
self,
|
||||
spec_channels,
|
||||
segment_size,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gin_channels,
|
||||
ssl_dim,
|
||||
n_speakers,
|
||||
sampling_rate=44100,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.spec_channels = spec_channels
|
||||
self.inter_channels = inter_channels
|
||||
@@ -282,7 +342,7 @@ class SynthesizerTrn(nn.Module):
|
||||
n_heads=n_heads,
|
||||
n_layers=n_layers,
|
||||
kernel_size=kernel_size,
|
||||
p_dropout=p_dropout
|
||||
p_dropout=p_dropout,
|
||||
)
|
||||
hps = {
|
||||
"sampling_rate": sampling_rate,
|
||||
@@ -296,8 +356,18 @@ class SynthesizerTrn(nn.Module):
|
||||
"gin_channels": gin_channels,
|
||||
}
|
||||
self.dec = Generator(h=hps)
|
||||
self.enc_q = Encoder(spec_channels, inter_channels, hidden_channels, 5, 1, 16, gin_channels=gin_channels)
|
||||
self.flow = ResidualCouplingBlock(inter_channels, hidden_channels, 5, 1, 4, gin_channels=gin_channels)
|
||||
self.enc_q = Encoder(
|
||||
spec_channels,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
5,
|
||||
1,
|
||||
16,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.flow = ResidualCouplingBlock(
|
||||
inter_channels, hidden_channels, 5, 1, 4, gin_channels=gin_channels
|
||||
)
|
||||
self.f0_decoder = F0Decoder(
|
||||
1,
|
||||
hidden_channels,
|
||||
@@ -306,13 +376,12 @@ class SynthesizerTrn(nn.Module):
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=gin_channels
|
||||
spk_channels=gin_channels,
|
||||
)
|
||||
self.emb_uv = nn.Embedding(2, hidden_channels)
|
||||
self.predict_f0 = False
|
||||
|
||||
def forward(self, c, f0, mel2ph, uv, noise=None, g=None):
|
||||
|
||||
decoder_inp = F.pad(c, [0, 0, 1, 0])
|
||||
mel2ph_ = mel2ph.unsqueeze(2).repeat([1, 1, c.shape[-1]])
|
||||
c = torch.gather(decoder_inp, 1, mel2ph_).transpose(1, 2) # [B, T, H]
|
||||
@@ -320,11 +389,13 @@ class SynthesizerTrn(nn.Module):
|
||||
c_lengths = (torch.ones(c.size(0)) * c.size(-1)).to(c.device)
|
||||
g = g.unsqueeze(0)
|
||||
g = self.emb_g(g).transpose(1, 2)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(c.dtype)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(
|
||||
c.dtype
|
||||
)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1, 2)
|
||||
|
||||
if self.predict_f0:
|
||||
lf0 = 2595. * torch.log10(1. + f0.unsqueeze(1) / 700.) / 500
|
||||
lf0 = 2595.0 * torch.log10(1.0 + f0.unsqueeze(1) / 700.0) / 500
|
||||
norm_lf0 = utils.normalize_f0(lf0, x_mask, uv, random_scale=False)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
f0 = (700 * (torch.pow(10, pred_lf0 * 500 / 2595) - 1)).squeeze(1)
|
||||
@@ -0,0 +1,98 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
import re
|
||||
import wave
|
||||
from copy import deepcopy
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from random import shuffle
|
||||
|
||||
from tqdm import tqdm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def _get_wav_duration(filepath: Path):
|
||||
with open(filepath, "rb") as f:
|
||||
with wave.open(f) as wav_file:
|
||||
n_frames = wav_file.getnframes()
|
||||
framerate = wav_file.getframerate()
|
||||
duration = n_frames / float(framerate)
|
||||
return duration
|
||||
|
||||
|
||||
def preprocess_config(
|
||||
input_dir: Path | str,
|
||||
train_list_path: Path | str,
|
||||
val_list_path: Path | str,
|
||||
test_list_path: Path | str,
|
||||
config_path: Path | str,
|
||||
):
|
||||
input_dir = Path(input_dir)
|
||||
train_list_path = Path(train_list_path)
|
||||
val_list_path = Path(val_list_path)
|
||||
test_list_path = Path(test_list_path)
|
||||
config_path = Path(config_path)
|
||||
train = []
|
||||
val = []
|
||||
test = []
|
||||
spk_dict = {}
|
||||
spk_id = 0
|
||||
for speaker in os.listdir(input_dir):
|
||||
spk_dict[speaker] = spk_id
|
||||
spk_id += 1
|
||||
paths = []
|
||||
for path in tqdm(list((input_dir / speaker).glob("**/*.wav"))):
|
||||
pattern = re.compile(r"^[\.a-zA-Z0-9_\/]+$")
|
||||
if not pattern.match(path.name):
|
||||
LOG.warning(f"file name {path} contains non-alphanumeric characters.")
|
||||
if _get_wav_duration(path) < 0.3:
|
||||
LOG.warning(f"skip {path} because it is too short.")
|
||||
continue
|
||||
paths.append(path)
|
||||
shuffle(paths)
|
||||
if len(paths) <= 4:
|
||||
raise ValueError(
|
||||
f"too few files in {input_dir / speaker} (expected at least 5)."
|
||||
)
|
||||
train += paths[2:-2]
|
||||
val += paths[:2]
|
||||
test += paths[-2:]
|
||||
|
||||
LOG.info(f"Writing {train_list_path}")
|
||||
train_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with train_list_path.open("w") as f:
|
||||
for fname in train:
|
||||
wavpath = fname.as_posix()
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
LOG.info(f"Writing {val_list_path}")
|
||||
val_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with val_list_path.open("w") as f:
|
||||
for fname in val:
|
||||
wavpath = fname.as_posix()
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
LOG.info(f"Writing {test_list_path}")
|
||||
test_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with test_list_path.open("w") as f:
|
||||
for fname in test:
|
||||
wavpath = fname.as_posix()
|
||||
f.write(wavpath + "\n")
|
||||
|
||||
config = deepcopy(
|
||||
json.loads(
|
||||
(
|
||||
Path(__file__).parent / "configs_template" / "config_template.json"
|
||||
).read_text()
|
||||
)
|
||||
)
|
||||
config["spk"] = spk_dict
|
||||
config["data"]["training_files"] = train_list_path.as_posix()
|
||||
config["data"]["validation_files"] = val_list_path.as_posix()
|
||||
LOG.info(f"Writing {config_path}")
|
||||
config_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with config_path.open("w") as f:
|
||||
json.dump(config, f, indent=2)
|
||||
@@ -0,0 +1,107 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from random import shuffle
|
||||
from typing import Iterable, Literal
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import torch
|
||||
from joblib import Parallel, cpu_count, delayed
|
||||
from tqdm import tqdm
|
||||
|
||||
from . import utils
|
||||
from .utils import HUBERT_SAMPLING_RATE
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def _process_one(
|
||||
filepath: Path,
|
||||
hubert_model,
|
||||
sampling_rate: int,
|
||||
hop_length: int,
|
||||
device: Literal["cuda", "cpu"] = "cuda",
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "crepe",
|
||||
force_rebuild: bool = False,
|
||||
):
|
||||
wav, sr = librosa.load(filepath, sr=sampling_rate)
|
||||
|
||||
# Compute HuBERT content
|
||||
soft_path = filepath.parent / (filepath.name + ".soft.pt")
|
||||
if not soft_path.exists() or force_rebuild:
|
||||
wav16k = librosa.resample(
|
||||
wav, orig_sr=sampling_rate, target_sr=HUBERT_SAMPLING_RATE
|
||||
)
|
||||
wav16k = torch.from_numpy(wav16k).to(device)
|
||||
c = utils.get_hubert_content(hubert_model, wav_16k_tensor=wav16k)
|
||||
torch.save(c.cpu(), soft_path)
|
||||
else:
|
||||
LOG.info(f"Skip {filepath} because {soft_path} exists.")
|
||||
|
||||
# Compute f0
|
||||
f0_path = filepath.parent / (filepath.name + ".f0.npy")
|
||||
if not f0_path.exists() or force_rebuild:
|
||||
f0 = utils.compute_f0(
|
||||
wav, sampling_rate=sampling_rate, hop_length=hop_length, method=f0_method
|
||||
)
|
||||
np.save(f0_path, f0)
|
||||
else:
|
||||
LOG.info(f"Skip {filepath} because {f0_path} exists.")
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
|
||||
def _process_batch(
|
||||
filepaths: Iterable[Path],
|
||||
sampling_rate: int,
|
||||
hop_length: int,
|
||||
pbar_position: int,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "crepe",
|
||||
force_rebuild: bool = False,
|
||||
):
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
hubert_model = utils.get_hubert_model().to(device)
|
||||
|
||||
for filepath in tqdm(filepaths, position=pbar_position):
|
||||
_process_one(
|
||||
filepath,
|
||||
hubert_model,
|
||||
sampling_rate,
|
||||
hop_length,
|
||||
device,
|
||||
f0_method,
|
||||
force_rebuild,
|
||||
)
|
||||
|
||||
|
||||
def preprocess_hubert_f0(
|
||||
input_dir: Path | str,
|
||||
config_path: Path | str,
|
||||
n_jobs: int = 4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "crepe",
|
||||
force_rebuild: bool = False,
|
||||
):
|
||||
input_dir = Path(input_dir)
|
||||
config_path = Path(config_path)
|
||||
utils.ensure_hubert_model()
|
||||
hps = utils.get_hparams_from_file(config_path)
|
||||
sampling_rate = hps.data.sampling_rate
|
||||
hop_length = hps.data.hop_length
|
||||
|
||||
filepaths = list(input_dir.rglob("*.wav"))
|
||||
n_jobs = min(cpu_count(), len(filepaths) // 32 + 1, n_jobs)
|
||||
shuffle(filepaths)
|
||||
filepath_chunks = np.array_split(filepaths, n_jobs)
|
||||
Parallel(n_jobs=n_jobs)(
|
||||
delayed(_process_batch)(
|
||||
chunk, sampling_rate, hop_length, pbar_position, f0_method, force_rebuild
|
||||
)
|
||||
for (pbar_position, chunk) in enumerate(filepath_chunks)
|
||||
)
|
||||
@@ -0,0 +1,110 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Iterable
|
||||
|
||||
import audioread.exceptions
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile
|
||||
from joblib import Parallel, delayed
|
||||
from tqdm_joblib import tqdm_joblib
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
# input_dir and output_dir exists.
|
||||
# write code to convert input dir audio files to output dir audio files,
|
||||
# without changing folder structure. Use joblib to parallelize.
|
||||
# Converting audio files includes:
|
||||
# - resampling to specified sampling rate
|
||||
# - trim silence
|
||||
# - adjust volume in a smart way
|
||||
# - save as 16-bit wav file
|
||||
|
||||
|
||||
def _get_unique_filename(path: Path, existing_paths: Iterable[Path]) -> Path:
|
||||
"""Return a unique path by appending a number to the original path."""
|
||||
if path not in existing_paths:
|
||||
return path
|
||||
i = 1
|
||||
while True:
|
||||
new_path = path.parent / f"{path.stem}_{i}{path.suffix}"
|
||||
if new_path not in existing_paths:
|
||||
return new_path
|
||||
i += 1
|
||||
|
||||
|
||||
def is_relative_to(path: Path, *other):
|
||||
"""Return True if the path is relative to another path or False.
|
||||
Python 3.9+ has Path.is_relative_to() method, but we need to support Python 3.8.
|
||||
"""
|
||||
try:
|
||||
path.relative_to(*other)
|
||||
return True
|
||||
except ValueError:
|
||||
return False
|
||||
|
||||
|
||||
def preprocess_resample(
|
||||
input_dir: Path | str, output_dir: Path | str, sampling_rate: int
|
||||
) -> None:
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
"""Preprocess audio files in input_dir and save them to output_dir."""
|
||||
|
||||
def preprocess_one(input_path: Path, output_path: Path) -> None:
|
||||
"""Preprocess one audio file."""
|
||||
|
||||
try:
|
||||
audio, sr = librosa.load(input_path)
|
||||
|
||||
# Audioread is the last backend it will attempt, so this is the exception thrown on failure
|
||||
except audioread.exceptions.NoBackendError as e:
|
||||
# Failure due to attempting to load a file that is not audio, so return early
|
||||
LOG.warning(f"Failed to load {input_path} due to {e}")
|
||||
return
|
||||
|
||||
# Trim silence
|
||||
audio, _ = librosa.effects.trim(audio, top_db=20)
|
||||
|
||||
# Adjust volume
|
||||
peak = np.abs(audio).max()
|
||||
if peak > 1.0:
|
||||
audio = 0.98 * audio / peak
|
||||
|
||||
# Resample
|
||||
audio = librosa.resample(audio, orig_sr=sr, target_sr=sampling_rate)
|
||||
audio /= max(audio.max(), -audio.min())
|
||||
soundfile.write(output_path, audio, samplerate=sampling_rate, subtype="PCM_16")
|
||||
|
||||
in_paths = []
|
||||
out_paths = []
|
||||
for in_path in input_dir.rglob("*.*"):
|
||||
in_path_relative = in_path.relative_to(input_dir)
|
||||
if not in_path.is_absolute() and is_relative_to(
|
||||
in_path, Path("dataset_raw") / "44k"
|
||||
):
|
||||
new_in_path_relative = in_path_relative.relative_to("44k")
|
||||
warnings.warn(
|
||||
f"Recommended folder structure has changed since v1.0.0. "
|
||||
"Please move your dataset directly under dataset_raw folder. "
|
||||
f"Recoginzed {in_path_relative} as {new_in_path_relative}"
|
||||
)
|
||||
in_path_relative = new_in_path_relative
|
||||
|
||||
if len(in_path_relative.parts) < 2:
|
||||
continue
|
||||
speaker_name = in_path_relative.parts[0]
|
||||
file_name = in_path_relative.with_suffix(".wav").name
|
||||
out_path = output_dir / speaker_name / file_name
|
||||
out_path = _get_unique_filename(out_path, out_paths)
|
||||
out_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
in_paths.append(in_path)
|
||||
out_paths.append(out_path)
|
||||
|
||||
in_and_out_paths = list(zip(in_paths, out_paths))
|
||||
|
||||
with tqdm_joblib(desc="Preprocessing", total=len(in_and_out_paths)):
|
||||
Parallel(n_jobs=-1)(delayed(preprocess_one)(*args) for args in in_and_out_paths)
|
||||
+6
-5
@@ -1,11 +1,12 @@
|
||||
from data_utils import TextAudioSpeakerLoader
|
||||
import json
|
||||
|
||||
from tqdm import tqdm
|
||||
|
||||
from utils import HParams
|
||||
from .data_utils import TextAudioSpeakerLoader
|
||||
from .utils import HParams
|
||||
|
||||
config_path = 'configs/config.json'
|
||||
with open(config_path, "r") as f:
|
||||
config_path = "configs/config.json"
|
||||
with open(config_path) as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
hps = HParams(**config)
|
||||
@@ -19,4 +20,4 @@ for _ in tqdm(train_dataset):
|
||||
for _ in tqdm(eval_dataset):
|
||||
pass
|
||||
for _ in tqdm(test_dataset):
|
||||
pass
|
||||
pass
|
||||
@@ -0,0 +1,420 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import multiprocessing
|
||||
import os
|
||||
import time
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
import torch.multiprocessing as mp
|
||||
from torch.cuda.amp import GradScaler, autocast
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.parallel import DistributedDataParallel as DDP
|
||||
from torch.utils.data import DataLoader
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from tqdm import trange
|
||||
|
||||
import so_vits_svc_fork.modules.commons as commons
|
||||
|
||||
from . import utils
|
||||
from .data_utils import TextAudioCollate, TextAudioSpeakerLoader
|
||||
from .models import MultiPeriodDiscriminator, SynthesizerTrn
|
||||
from .modules.losses import discriminator_loss, feature_loss, generator_loss, kl_loss
|
||||
from .modules.mel_processing import mel_spectrogram_torch, spec_to_mel_torch
|
||||
|
||||
# os.environ['TORCH_DISTRIBUTED_DEBUG'] = 'INFO'
|
||||
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
torch.backends.cudnn.benchmark = True
|
||||
global_step = 0
|
||||
start_time = time.time()
|
||||
|
||||
|
||||
def train(config_path: Path | str, model_path: Path | str):
|
||||
"""Assume Single Node Multi GPUs Training Only"""
|
||||
config_path = Path(config_path)
|
||||
model_path = Path(model_path)
|
||||
if not torch.cuda.is_available():
|
||||
raise RuntimeError("CUDA is not available.")
|
||||
utils.ensure_pretrained_model(model_path)
|
||||
hps = utils.get_hparams(config_path, model_path)
|
||||
|
||||
n_gpus = torch.cuda.device_count()
|
||||
os.environ["MASTER_ADDR"] = "localhost"
|
||||
os.environ["MASTER_PORT"] = hps.train.port
|
||||
|
||||
mp.spawn(
|
||||
run,
|
||||
nprocs=n_gpus,
|
||||
args=(
|
||||
n_gpus,
|
||||
hps,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def run(rank, n_gpus, hps):
|
||||
global global_step
|
||||
if rank == 0:
|
||||
LOG.info(hps)
|
||||
# utils.check_git_hash(hps.model_dir)
|
||||
writer = SummaryWriter(log_dir=hps.model_dir)
|
||||
writer_eval = SummaryWriter(log_dir=Path(hps.model_dir) / "eval")
|
||||
|
||||
# for pytorch on win, backend use gloo
|
||||
dist.init_process_group(
|
||||
backend="gloo" if os.name == "nt" else "nccl",
|
||||
init_method="env://",
|
||||
world_size=n_gpus,
|
||||
rank=rank,
|
||||
)
|
||||
torch.manual_seed(hps.train.seed)
|
||||
torch.cuda.set_device(rank)
|
||||
collate_fn = TextAudioCollate()
|
||||
train_dataset = TextAudioSpeakerLoader(hps.data.training_files, hps)
|
||||
num_workers = 5 if multiprocessing.cpu_count() > 4 else multiprocessing.cpu_count()
|
||||
train_loader = DataLoader(
|
||||
train_dataset,
|
||||
num_workers=num_workers,
|
||||
shuffle=False,
|
||||
pin_memory=True,
|
||||
batch_size=hps.train.batch_size,
|
||||
collate_fn=collate_fn,
|
||||
)
|
||||
if rank == 0:
|
||||
eval_dataset = TextAudioSpeakerLoader(hps.data.validation_files, hps)
|
||||
eval_loader = DataLoader(
|
||||
eval_dataset,
|
||||
num_workers=1,
|
||||
shuffle=False,
|
||||
batch_size=1,
|
||||
pin_memory=False,
|
||||
drop_last=False,
|
||||
collate_fn=collate_fn,
|
||||
)
|
||||
|
||||
net_g = SynthesizerTrn(
|
||||
hps.data.filter_length // 2 + 1,
|
||||
hps.train.segment_size // hps.data.hop_length,
|
||||
**hps.model,
|
||||
).cuda(rank)
|
||||
net_d = MultiPeriodDiscriminator(hps.model.use_spectral_norm).cuda(rank)
|
||||
optim_g = torch.optim.AdamW(
|
||||
net_g.parameters(),
|
||||
hps.train.learning_rate,
|
||||
betas=hps.train.betas,
|
||||
eps=hps.train.eps,
|
||||
)
|
||||
optim_d = torch.optim.AdamW(
|
||||
net_d.parameters(),
|
||||
hps.train.learning_rate,
|
||||
betas=hps.train.betas,
|
||||
eps=hps.train.eps,
|
||||
)
|
||||
net_g = DDP(net_g, device_ids=[rank]) # , find_unused_parameters=True)
|
||||
net_d = DDP(net_d, device_ids=[rank])
|
||||
|
||||
skip_optimizer = False
|
||||
try:
|
||||
_, _, _, epoch_str = utils.load_checkpoint(
|
||||
utils.latest_checkpoint_path(hps.model_dir, "G_*.pth"),
|
||||
net_g,
|
||||
optim_g,
|
||||
skip_optimizer,
|
||||
)
|
||||
_, _, _, epoch_str = utils.load_checkpoint(
|
||||
utils.latest_checkpoint_path(hps.model_dir, "D_*.pth"),
|
||||
net_d,
|
||||
optim_d,
|
||||
skip_optimizer,
|
||||
)
|
||||
epoch_str = max(epoch_str, 1)
|
||||
global_step = (epoch_str - 1) * len(train_loader)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
LOG.info("No checkpoint found, start from scratch")
|
||||
epoch_str = 1
|
||||
global_step = 0
|
||||
if skip_optimizer:
|
||||
epoch_str = 1
|
||||
global_step = 0
|
||||
|
||||
scheduler_g = torch.optim.lr_scheduler.ExponentialLR(
|
||||
optim_g, gamma=hps.train.lr_decay, last_epoch=epoch_str - 2
|
||||
)
|
||||
scheduler_d = torch.optim.lr_scheduler.ExponentialLR(
|
||||
optim_d, gamma=hps.train.lr_decay, last_epoch=epoch_str - 2
|
||||
)
|
||||
|
||||
scaler = GradScaler(enabled=hps.train.fp16_run)
|
||||
|
||||
LOG.info("Start training")
|
||||
|
||||
for epoch in trange(epoch_str, hps.train.epochs + 1):
|
||||
if rank == 0:
|
||||
train_and_evaluate(
|
||||
rank,
|
||||
epoch,
|
||||
hps,
|
||||
[net_g, net_d],
|
||||
[optim_g, optim_d],
|
||||
[scheduler_g, scheduler_d],
|
||||
scaler,
|
||||
[train_loader, eval_loader],
|
||||
[writer, writer_eval],
|
||||
)
|
||||
else:
|
||||
train_and_evaluate(
|
||||
rank,
|
||||
epoch,
|
||||
hps,
|
||||
[net_g, net_d],
|
||||
[optim_g, optim_d],
|
||||
[scheduler_g, scheduler_d],
|
||||
scaler,
|
||||
[train_loader, None],
|
||||
None,
|
||||
)
|
||||
scheduler_g.step()
|
||||
scheduler_d.step()
|
||||
|
||||
|
||||
def train_and_evaluate(
|
||||
rank, epoch, hps, nets, optims, schedulers, scaler, loaders, writers
|
||||
):
|
||||
net_g, net_d = nets
|
||||
optim_g, optim_d = optims
|
||||
scheduler_g, scheduler_d = schedulers
|
||||
train_loader, eval_loader = loaders
|
||||
if writers is not None:
|
||||
writer, writer_eval = writers
|
||||
|
||||
# train_loader.batch_sampler.set_epoch(epoch)
|
||||
global global_step
|
||||
|
||||
net_g.train()
|
||||
net_d.train()
|
||||
for batch_idx, items in enumerate(train_loader):
|
||||
c, f0, spec, y, spk, lengths, uv = items
|
||||
g = spk.cuda(rank, non_blocking=True)
|
||||
spec, y = spec.cuda(rank, non_blocking=True), y.cuda(rank, non_blocking=True)
|
||||
c = c.cuda(rank, non_blocking=True)
|
||||
f0 = f0.cuda(rank, non_blocking=True)
|
||||
uv = uv.cuda(rank, non_blocking=True)
|
||||
lengths = lengths.cuda(rank, non_blocking=True)
|
||||
mel = spec_to_mel_torch(
|
||||
spec,
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax,
|
||||
)
|
||||
|
||||
with autocast(enabled=hps.train.fp16_run):
|
||||
(
|
||||
y_hat,
|
||||
ids_slice,
|
||||
z_mask,
|
||||
(z, z_p, m_p, logs_p, m_q, logs_q),
|
||||
pred_lf0,
|
||||
norm_lf0,
|
||||
lf0,
|
||||
) = net_g(c, f0, uv, spec, g=g, c_lengths=lengths, spec_lengths=lengths)
|
||||
|
||||
y_mel = commons.slice_segments(
|
||||
mel, ids_slice, hps.train.segment_size // hps.data.hop_length
|
||||
)
|
||||
y_hat_mel = mel_spectrogram_torch(
|
||||
y_hat.squeeze(1),
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.hop_length,
|
||||
hps.data.win_length,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax,
|
||||
)
|
||||
y = commons.slice_segments(
|
||||
y, ids_slice * hps.data.hop_length, hps.train.segment_size
|
||||
) # slice
|
||||
|
||||
# Discriminator
|
||||
y_d_hat_r, y_d_hat_g, _, _ = net_d(y, y_hat.detach())
|
||||
|
||||
with autocast(enabled=False):
|
||||
loss_disc, losses_disc_r, losses_disc_g = discriminator_loss(
|
||||
y_d_hat_r, y_d_hat_g
|
||||
)
|
||||
loss_disc_all = loss_disc
|
||||
|
||||
optim_d.zero_grad()
|
||||
scaler.scale(loss_disc_all).backward()
|
||||
scaler.unscale_(optim_d)
|
||||
grad_norm_d = commons.clip_grad_value_(net_d.parameters(), None)
|
||||
scaler.step(optim_d)
|
||||
|
||||
with autocast(enabled=hps.train.fp16_run):
|
||||
# Generator
|
||||
y_d_hat_r, y_d_hat_g, fmap_r, fmap_g = net_d(y, y_hat)
|
||||
with autocast(enabled=False):
|
||||
loss_mel = F.l1_loss(y_mel, y_hat_mel) * hps.train.c_mel
|
||||
loss_kl = kl_loss(z_p, logs_q, m_p, logs_p, z_mask) * hps.train.c_kl
|
||||
loss_fm = feature_loss(fmap_r, fmap_g)
|
||||
loss_gen, losses_gen = generator_loss(y_d_hat_g)
|
||||
loss_lf0 = F.mse_loss(pred_lf0, lf0)
|
||||
loss_gen_all = loss_gen + loss_fm + loss_mel + loss_kl + loss_lf0
|
||||
optim_g.zero_grad()
|
||||
scaler.scale(loss_gen_all).backward()
|
||||
scaler.unscale_(optim_g)
|
||||
grad_norm_g = commons.clip_grad_value_(net_g.parameters(), None)
|
||||
scaler.step(optim_g)
|
||||
scaler.update()
|
||||
|
||||
if rank == 0:
|
||||
if global_step % hps.train.log_interval == 0:
|
||||
lr = optim_g.param_groups[0]["lr"]
|
||||
losses = [loss_disc, loss_gen, loss_fm, loss_mel, loss_kl]
|
||||
LOG.info(
|
||||
"Train Epoch: {} [{:.0f}%]".format(
|
||||
epoch, 100.0 * batch_idx / len(train_loader)
|
||||
)
|
||||
)
|
||||
LOG.info(
|
||||
f"Losses: {[x.item() for x in losses]}, step: {global_step}, lr: {lr}"
|
||||
)
|
||||
|
||||
scalar_dict = {
|
||||
"loss/g/total": loss_gen_all,
|
||||
"loss/d/total": loss_disc_all,
|
||||
"learning_rate": lr,
|
||||
"grad_norm_d": grad_norm_d,
|
||||
"grad_norm_g": grad_norm_g,
|
||||
}
|
||||
scalar_dict.update(
|
||||
{
|
||||
"loss/g/fm": loss_fm,
|
||||
"loss/g/mel": loss_mel,
|
||||
"loss/g/kl": loss_kl,
|
||||
"loss/g/lf0": loss_lf0,
|
||||
}
|
||||
)
|
||||
|
||||
# scalar_dict.update({"loss/g/{}".format(i): v for i, v in enumerate(losses_gen)})
|
||||
# scalar_dict.update({"loss/d_r/{}".format(i): v for i, v in enumerate(losses_disc_r)})
|
||||
# scalar_dict.update({"loss/d_g/{}".format(i): v for i, v in enumerate(losses_disc_g)})
|
||||
image_dict = {
|
||||
"slice/mel_org": utils.plot_spectrogram_to_numpy(
|
||||
y_mel[0].data.cpu().numpy()
|
||||
),
|
||||
"slice/mel_gen": utils.plot_spectrogram_to_numpy(
|
||||
y_hat_mel[0].data.cpu().numpy()
|
||||
),
|
||||
"all/mel": utils.plot_spectrogram_to_numpy(
|
||||
mel[0].data.cpu().numpy()
|
||||
),
|
||||
"all/lf0": utils.plot_data_to_numpy(
|
||||
lf0[0, 0, :].cpu().numpy(),
|
||||
pred_lf0[0, 0, :].detach().cpu().numpy(),
|
||||
),
|
||||
"all/norm_lf0": utils.plot_data_to_numpy(
|
||||
lf0[0, 0, :].cpu().numpy(),
|
||||
norm_lf0[0, 0, :].detach().cpu().numpy(),
|
||||
),
|
||||
}
|
||||
|
||||
utils.summarize(
|
||||
writer=writer,
|
||||
global_step=global_step,
|
||||
images=image_dict,
|
||||
scalars=scalar_dict,
|
||||
)
|
||||
|
||||
if global_step % hps.train.eval_interval == 0:
|
||||
LOG.info("Saving checkpoints...")
|
||||
evaluate(hps, net_g, eval_loader, writer_eval)
|
||||
utils.save_checkpoint(
|
||||
net_g,
|
||||
optim_g,
|
||||
hps.train.learning_rate,
|
||||
epoch,
|
||||
Path(hps.model_dir) / f"G_{global_step}.pth",
|
||||
)
|
||||
utils.save_checkpoint(
|
||||
net_d,
|
||||
optim_d,
|
||||
hps.train.learning_rate,
|
||||
epoch,
|
||||
Path(hps.model_dir) / f"D_{global_step}.pth",
|
||||
)
|
||||
keep_ckpts = getattr(hps.train, "keep_ckpts", 0)
|
||||
if keep_ckpts > 0:
|
||||
utils.clean_checkpoints(
|
||||
path_to_models=hps.model_dir,
|
||||
n_ckpts_to_keep=keep_ckpts,
|
||||
sort_by_time=True,
|
||||
)
|
||||
|
||||
global_step += 1
|
||||
|
||||
if rank == 0:
|
||||
global start_time
|
||||
now = time.time()
|
||||
durtaion = format(now - start_time, ".2f")
|
||||
LOG.info(f"====> Epoch: {epoch}, cost {durtaion} s")
|
||||
start_time = now
|
||||
|
||||
|
||||
def evaluate(hps, generator, eval_loader, writer_eval):
|
||||
generator.eval()
|
||||
image_dict = {}
|
||||
audio_dict = {}
|
||||
with torch.no_grad():
|
||||
for batch_idx, items in enumerate(eval_loader):
|
||||
c, f0, spec, y, spk, _, uv = items
|
||||
g = spk[:1].cuda(0)
|
||||
spec, y = spec[:1].cuda(0), y[:1].cuda(0)
|
||||
c = c[:1].cuda(0)
|
||||
f0 = f0[:1].cuda(0)
|
||||
uv = uv[:1].cuda(0)
|
||||
mel = spec_to_mel_torch(
|
||||
spec,
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax,
|
||||
)
|
||||
y_hat = generator.module.infer(c, f0, uv, g=g)
|
||||
|
||||
y_hat_mel = mel_spectrogram_torch(
|
||||
y_hat.squeeze(1).float(),
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.hop_length,
|
||||
hps.data.win_length,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax,
|
||||
)
|
||||
|
||||
audio_dict.update(
|
||||
{f"gen/audio_{batch_idx}": y_hat[0], f"gt/audio_{batch_idx}": y[0]}
|
||||
)
|
||||
image_dict.update(
|
||||
{
|
||||
"gen/mel": utils.plot_spectrogram_to_numpy(y_hat_mel[0].cpu().numpy()),
|
||||
"gt/mel": utils.plot_spectrogram_to_numpy(mel[0].cpu().numpy()),
|
||||
}
|
||||
)
|
||||
utils.summarize(
|
||||
writer=writer_eval,
|
||||
global_step=global_step,
|
||||
images=image_dict,
|
||||
audios=audio_dict,
|
||||
audio_sampling_rate=hps.data.sampling_rate,
|
||||
)
|
||||
generator.train()
|
||||
@@ -0,0 +1,589 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import re
|
||||
from itertools import groupby
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any, Literal
|
||||
|
||||
import numpy as np
|
||||
import requests
|
||||
import torch
|
||||
#import torchcrepe
|
||||
from numpy import dtype, float32, ndarray
|
||||
from scipy.io.wavfile import read
|
||||
from torch import FloatTensor, Tensor
|
||||
from tqdm import tqdm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
MATPLOTLIB_FLAG = False
|
||||
f0_bin = 256
|
||||
f0_max = 1100.0
|
||||
f0_min = 50.0
|
||||
f0_mel_min = 1127 * np.log(1 + f0_min / 700)
|
||||
f0_mel_max = 1127 * np.log(1 + f0_max / 700)
|
||||
HUBERT_SAMPLING_RATE = 16000
|
||||
|
||||
|
||||
# def normalize_f0(f0, random_scale=True):
|
||||
# f0_norm = f0.clone() # create a copy of the input Tensor
|
||||
# batch_size, _, frame_length = f0_norm.shape
|
||||
# for i in range(batch_size):
|
||||
# means = torch.mean(f0_norm[i, 0, :])
|
||||
# if random_scale:
|
||||
# factor = random.uniform(0.8, 1.2)
|
||||
# else:
|
||||
# factor = 1
|
||||
# f0_norm[i, 0, :] = (f0_norm[i, 0, :] - means) * factor
|
||||
# return f0_norm
|
||||
# def normalize_f0(f0, random_scale=True):
|
||||
# means = torch.mean(f0[:, 0, :], dim=1, keepdim=True)
|
||||
# if random_scale:
|
||||
# factor = torch.Tensor(f0.shape[0],1).uniform_(0.8, 1.2).to(f0.device)
|
||||
# else:
|
||||
# factor = torch.ones(f0.shape[0], 1, 1).to(f0.device)
|
||||
# f0_norm = (f0 - means.unsqueeze(-1)) * factor.unsqueeze(-1)
|
||||
# return f0_norm
|
||||
def normalize_f0(
|
||||
f0: FloatTensor, x_mask: FloatTensor, uv: FloatTensor, random_scale=True
|
||||
) -> FloatTensor:
|
||||
# calculate means based on x_mask
|
||||
uv_sum = torch.sum(uv, dim=1, keepdim=True)
|
||||
uv_sum[uv_sum == 0] = 9999
|
||||
means = torch.sum(f0[:, 0, :] * uv, dim=1, keepdim=True) / uv_sum
|
||||
|
||||
if random_scale:
|
||||
factor = torch.Tensor(f0.shape[0], 1).uniform_(0.8, 1.2).to(f0.device)
|
||||
else:
|
||||
factor = torch.ones(f0.shape[0], 1).to(f0.device)
|
||||
# normalize f0 based on means and factor
|
||||
f0_norm = (f0 - means.unsqueeze(-1)) * factor.unsqueeze(-1)
|
||||
if torch.isnan(f0_norm).any():
|
||||
exit(0)
|
||||
return f0_norm * x_mask
|
||||
|
||||
|
||||
def plot_data_to_numpy(x: ndarray, y: ndarray) -> ndarray:
|
||||
global MATPLOTLIB_FLAG
|
||||
if not MATPLOTLIB_FLAG:
|
||||
import matplotlib
|
||||
|
||||
matplotlib.use("Agg")
|
||||
MATPLOTLIB_FLAG = True
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
plt.plot(x)
|
||||
plt.plot(y)
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep="")
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def interpolate_f0(
|
||||
f0: ndarray[Any, dtype[float32]]
|
||||
) -> tuple[ndarray[Any, dtype[float32]], ndarray[Any, dtype[float32]]]:
|
||||
data = np.reshape(f0, (f0.size, 1))
|
||||
|
||||
vuv_vector = np.zeros((data.size, 1), dtype=np.float32)
|
||||
vuv_vector[data > 0.0] = 1.0
|
||||
vuv_vector[data <= 0.0] = 0.0
|
||||
|
||||
ip_data = data
|
||||
|
||||
frame_number = data.size
|
||||
last_value = 0.0
|
||||
for i in range(frame_number):
|
||||
if data[i] <= 0.0:
|
||||
j = i + 1
|
||||
for j in range(i + 1, frame_number):
|
||||
if data[j] > 0.0:
|
||||
break
|
||||
if j < frame_number - 1:
|
||||
if last_value > 0.0:
|
||||
step = (data[j] - data[i - 1]) / float(j - i)
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[i - 1] + step * (k - i + 1)
|
||||
else:
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[j]
|
||||
else:
|
||||
for k in range(i, frame_number):
|
||||
ip_data[k] = last_value
|
||||
else:
|
||||
ip_data[i] = data[i]
|
||||
last_value = data[i]
|
||||
|
||||
return ip_data[:, 0], vuv_vector[:, 0]
|
||||
|
||||
|
||||
def compute_f0_parselmouth(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
):
|
||||
import parselmouth
|
||||
|
||||
x = wav_numpy
|
||||
if p_len is None:
|
||||
p_len = x.shape[0] // hop_length
|
||||
else:
|
||||
assert abs(p_len - x.shape[0] // hop_length) < 4, "pad length error"
|
||||
time_step = hop_length / sampling_rate * 1000
|
||||
f0_min = 50
|
||||
f0_max = 1100
|
||||
f0 = (
|
||||
parselmouth.Sound(x, sampling_rate)
|
||||
.to_pitch_ac(
|
||||
time_step=time_step / 1000,
|
||||
voicing_threshold=0.6,
|
||||
pitch_floor=f0_min,
|
||||
pitch_ceiling=f0_max,
|
||||
)
|
||||
.selected_array["frequency"]
|
||||
)
|
||||
|
||||
pad_size = (p_len - len(f0) + 1) // 2
|
||||
if pad_size > 0 or p_len - len(f0) - pad_size > 0:
|
||||
f0 = np.pad(f0, [[pad_size, p_len - len(f0) - pad_size]], mode="constant")
|
||||
return f0
|
||||
|
||||
|
||||
def _resize_f0(
|
||||
x: ndarray[Any, dtype[float32]], target_len: int
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
source = np.array(x)
|
||||
source[source < 0.001] = np.nan
|
||||
target = np.interp(
|
||||
np.arange(0, len(source) * target_len, len(source)) / target_len,
|
||||
np.arange(0, len(source)),
|
||||
source,
|
||||
)
|
||||
res = np.nan_to_num(target)
|
||||
return res
|
||||
|
||||
|
||||
def compute_f0_pyworld(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
type_: Literal["dio", "harvest"] = "dio",
|
||||
):
|
||||
import pyworld
|
||||
|
||||
if p_len is None:
|
||||
p_len = wav_numpy.shape[0] // hop_length
|
||||
#if type_ == "dio":
|
||||
f0, t = pyworld.dio(
|
||||
wav_numpy.astype(np.double),
|
||||
fs=sampling_rate,
|
||||
f0_ceil=f0_max,
|
||||
f0_floor=f0_min,
|
||||
frame_period=1000 * hop_length / sampling_rate,
|
||||
)
|
||||
#elif type_ == "harvest":
|
||||
# f0, t = pyworld.harvest(
|
||||
# wav_numpy.astype(np.double),
|
||||
# fs=sampling_rate,
|
||||
# f0_ceil=f0_max,
|
||||
# f0_floor=f0_min,
|
||||
# frame_period=1000 * hop_length / sampling_rate,
|
||||
# )
|
||||
f0 = pyworld.stonemask(wav_numpy.astype(np.double), f0, t, sampling_rate)
|
||||
for index, pitch in enumerate(f0):
|
||||
f0[index] = round(pitch, 1)
|
||||
return _resize_f0(f0, p_len)
|
||||
|
||||
|
||||
def compute_f0_crepe(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
device: str = "cuda" if torch.cuda.is_available() else "cpu",
|
||||
model: Literal["full", "tiny"] = "full",
|
||||
):
|
||||
audio = torch.from_numpy(wav_numpy).to(device, copy=True)
|
||||
audio = torch.unsqueeze(audio, dim=0)
|
||||
|
||||
if audio.ndim == 2 and audio.shape[0] > 1:
|
||||
audio = torch.mean(audio, dim=0, keepdim=True).detach()
|
||||
# (T) -> (1, T)
|
||||
audio = audio.detach()
|
||||
|
||||
pitch: Tensor = torchcrepe.predict(
|
||||
audio,
|
||||
sampling_rate,
|
||||
hop_length,
|
||||
f0_min,
|
||||
f0_max,
|
||||
model,
|
||||
batch_size=hop_length * 2,
|
||||
device=device,
|
||||
pad=True,
|
||||
)
|
||||
|
||||
f0 = pitch.squeeze(0).cpu().numpy()
|
||||
p_len = p_len or wav_numpy.shape[0] // hop_length
|
||||
f0 = _resize_f0(f0, p_len)
|
||||
return f0
|
||||
|
||||
|
||||
def compute_f0(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
**kwargs,
|
||||
):
|
||||
wav_numpy = wav_numpy.astype(np.float32)
|
||||
wav_numpy /= np.quantile(np.abs(wav_numpy), 0.999)
|
||||
#if method in ["dio", "harvest"]:
|
||||
return compute_f0_pyworld(wav_numpy, p_len, sampling_rate, hop_length, method)
|
||||
#elif method == "crepe":
|
||||
# return compute_f0_crepe(wav_numpy, p_len, sampling_rate, hop_length, **kwargs)
|
||||
#elif method == "crepe-tiny":
|
||||
# return compute_f0_crepe(
|
||||
# wav_numpy, p_len, sampling_rate, hop_length, model="tiny", **kwargs
|
||||
# )
|
||||
#elif method == "parselmouth":
|
||||
# return compute_f0_parselmouth(wav_numpy, p_len, sampling_rate, hop_length)
|
||||
#else:
|
||||
# raise ValueError("type must be dio, crepe, harvest or parselmouth")
|
||||
|
||||
|
||||
def f0_to_coarse(f0: torch.Tensor | float):
|
||||
is_torch = isinstance(f0, torch.Tensor)
|
||||
f0_mel = 1127 * (1 + f0 / 700).log() if is_torch else 1127 * np.log(1 + f0 / 700)
|
||||
f0_mel[f0_mel > 0] = (f0_mel[f0_mel > 0] - f0_mel_min) * (f0_bin - 2) / (
|
||||
f0_mel_max - f0_mel_min
|
||||
) + 1
|
||||
|
||||
f0_mel[f0_mel <= 1] = 1
|
||||
f0_mel[f0_mel > f0_bin - 1] = f0_bin - 1
|
||||
f0_coarse = (f0_mel + 0.5).long() if is_torch else np.rint(f0_mel).astype(np.int)
|
||||
assert f0_coarse.max() <= 255 and f0_coarse.min() >= 1, (
|
||||
f0_coarse.max(),
|
||||
f0_coarse.min(),
|
||||
)
|
||||
return f0_coarse
|
||||
|
||||
|
||||
def download_file(url: str, filepath: Path | str, chunk_size: int = 4 * 1024, **kwargs):
|
||||
filepath = Path(filepath)
|
||||
filepath.parent.mkdir(parents=True, exist_ok=True)
|
||||
temppath = filepath.parent / f"{filepath.name}.download"
|
||||
if filepath.exists():
|
||||
raise FileExistsError(f"{filepath} already exists")
|
||||
temppath.unlink(missing_ok=True)
|
||||
resp = requests.get(url, stream=True)
|
||||
total = int(resp.headers.get("content-length", 0))
|
||||
with temppath.open("wb") as f, tqdm(
|
||||
total=total,
|
||||
unit="iB",
|
||||
unit_scale=True,
|
||||
unit_divisor=1024,
|
||||
**kwargs,
|
||||
) as pbar:
|
||||
for data in resp.iter_content(chunk_size=chunk_size):
|
||||
size = f.write(data)
|
||||
pbar.update(size)
|
||||
temppath.rename(filepath)
|
||||
|
||||
|
||||
def ensure_pretrained_model(folder_path: Path) -> None:
|
||||
model_urls = [
|
||||
# "https://huggingface.co/innnky/sovits_pretrained/resolve/main/sovits4/G_0.pth",
|
||||
"https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/D_0.pth",
|
||||
# "https://huggingface.co/innnky/sovits_pretrained/resolve/main/sovits4/D_0.pth",
|
||||
"https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/G_0.pth",
|
||||
]
|
||||
for model_url in model_urls:
|
||||
model_path = folder_path / model_url.split("/")[-1]
|
||||
if not model_path.exists():
|
||||
download_file(model_url, model_path, desc=f"Downloading {model_path.name}")
|
||||
|
||||
|
||||
def ensure_hubert_model() -> Path:
|
||||
vec_path = Path("checkpoint_best_legacy_500.pt")
|
||||
vec_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
if not vec_path.exists():
|
||||
# url = "http://obs.cstcloud.cn/share/obs/sankagenkeshi/checkpoint_best_legacy_500.pt"
|
||||
# url = "https://huggingface.co/innnky/contentvec/resolve/main/checkpoint_best_legacy_500.pt"
|
||||
url = "https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/checkpoint_best_legacy_500.pt"
|
||||
download_file(url, vec_path, desc="Downloading Hubert model")
|
||||
return vec_path
|
||||
|
||||
|
||||
def get_hubert_model():
|
||||
vec_path = ensure_hubert_model()
|
||||
from fairseq import checkpoint_utils
|
||||
|
||||
models, saved_cfg, task = checkpoint_utils.load_model_ensemble_and_task(
|
||||
[vec_path.as_posix()],
|
||||
suffix="",
|
||||
)
|
||||
model = models[0]
|
||||
model.eval()
|
||||
return model
|
||||
|
||||
|
||||
def get_hubert_content(hmodel, wav_16k_tensor):
|
||||
feats = wav_16k_tensor
|
||||
if feats.dim() == 2: # double channels
|
||||
feats = feats.mean(-1)
|
||||
assert feats.dim() == 1, feats.dim()
|
||||
feats = feats.view(1, -1)
|
||||
padding_mask = torch.BoolTensor(feats.shape).fill_(False)
|
||||
inputs = {
|
||||
"source": feats.to(wav_16k_tensor.device),
|
||||
"padding_mask": padding_mask.to(wav_16k_tensor.device),
|
||||
"output_layer": 9, # layer 9
|
||||
}
|
||||
with torch.no_grad():
|
||||
logits = hmodel.extract_features(**inputs)
|
||||
feats = hmodel.final_proj(logits[0])
|
||||
return feats.transpose(1, 2)
|
||||
|
||||
|
||||
def get_content(cmodel: Any, y: ndarray) -> ndarray:
|
||||
with torch.no_grad():
|
||||
c = cmodel.extract_features(y.squeeze(1))[0]
|
||||
c = c.transpose(1, 2)
|
||||
return c
|
||||
|
||||
|
||||
def load_checkpoint(
|
||||
checkpoint_path: Any,
|
||||
model: Any,
|
||||
optimizer: Any = None,
|
||||
skip_optimizer: bool = False,
|
||||
):
|
||||
if not Path(checkpoint_path).is_file():
|
||||
raise FileNotFoundError(f"File {checkpoint_path} not found")
|
||||
checkpoint_dict = torch.load(checkpoint_path, map_location="cpu")
|
||||
iteration = checkpoint_dict["iteration"]
|
||||
learning_rate = checkpoint_dict["learning_rate"]
|
||||
if (
|
||||
optimizer is not None
|
||||
and not skip_optimizer
|
||||
and checkpoint_dict["optimizer"] is not None
|
||||
):
|
||||
optimizer.load_state_dict(checkpoint_dict["optimizer"])
|
||||
saved_state_dict = checkpoint_dict["model"]
|
||||
if hasattr(model, "module"):
|
||||
state_dict = model.module.state_dict()
|
||||
else:
|
||||
state_dict = model.state_dict()
|
||||
new_state_dict = {}
|
||||
for k, v in state_dict.items():
|
||||
try:
|
||||
# assert "dec" in k or "disc" in k
|
||||
# print("load", k)
|
||||
new_state_dict[k] = saved_state_dict[k]
|
||||
assert saved_state_dict[k].shape == v.shape, (
|
||||
saved_state_dict[k].shape,
|
||||
v.shape,
|
||||
)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
LOG.error("%s is not in the checkpoint" % k)
|
||||
new_state_dict[k] = v
|
||||
if hasattr(model, "module"):
|
||||
model.module.load_state_dict(new_state_dict)
|
||||
else:
|
||||
model.load_state_dict(new_state_dict)
|
||||
LOG.info(f"Loaded checkpoint '{checkpoint_path}' (iteration {iteration})")
|
||||
return model, optimizer, learning_rate, iteration
|
||||
|
||||
|
||||
def save_checkpoint(
|
||||
model, optimizer, learning_rate, iteration, checkpoint_path
|
||||
) -> None:
|
||||
LOG.info(
|
||||
"Saving model and optimizer state at iteration {} to {}".format(
|
||||
iteration, checkpoint_path
|
||||
)
|
||||
)
|
||||
if hasattr(model, "module"):
|
||||
state_dict = model.module.state_dict()
|
||||
else:
|
||||
state_dict = model.state_dict()
|
||||
torch.save(
|
||||
{
|
||||
"model": state_dict,
|
||||
"iteration": iteration,
|
||||
"optimizer": optimizer.state_dict(),
|
||||
"learning_rate": learning_rate,
|
||||
},
|
||||
checkpoint_path,
|
||||
)
|
||||
|
||||
|
||||
def clean_checkpoints(
|
||||
path_to_models: Path | str, n_ckpts_to_keep: int = 2, sort_by_time: bool = True
|
||||
):
|
||||
"""Freeing up space by deleting saved ckpts
|
||||
|
||||
Arguments:
|
||||
path_to_models -- Path to the model directory
|
||||
n_ckpts_to_keep -- Number of ckpts to keep, excluding G_0.pth and D_0.pth
|
||||
sort_by_time -- True -> chronologically delete ckpts
|
||||
False -> lexicographically delete ckpts
|
||||
"""
|
||||
path_to_models = Path(path_to_models)
|
||||
name_key = lambda p: int(re.match(r"._(\d+)\.pth", p.name).group(1))
|
||||
time_key = lambda p: p.stat().st_mtime
|
||||
models_sorted = sorted(
|
||||
path_to_models.glob(r"._(\d+).pth"), key=time_key if sort_by_time else name_key
|
||||
)
|
||||
models_sorted_grouped = groupby(models_sorted, lambda p: p.name[0])
|
||||
for k, g in models_sorted_grouped:
|
||||
to_dels = list(g)[n_ckpts_to_keep:]
|
||||
for to_del in to_dels:
|
||||
if to_del.stem.endswith("_0"):
|
||||
continue
|
||||
LOG.warning(f"Removing {to_del}")
|
||||
to_del.unlink()
|
||||
|
||||
|
||||
def summarize(
|
||||
writer,
|
||||
global_step,
|
||||
scalars={},
|
||||
histograms={},
|
||||
images={},
|
||||
audios={},
|
||||
audio_sampling_rate=22050,
|
||||
):
|
||||
for k, v in scalars.items():
|
||||
writer.add_scalar(k, v, global_step)
|
||||
for k, v in histograms.items():
|
||||
writer.add_histogram(k, v, global_step)
|
||||
for k, v in images.items():
|
||||
writer.add_image(k, v, global_step, dataformats="HWC")
|
||||
for k, v in audios.items():
|
||||
writer.add_audio(k, v, global_step, audio_sampling_rate)
|
||||
|
||||
|
||||
def latest_checkpoint_path(dir_path: Path | str, regex: str = "G_*.pth"):
|
||||
return list(sorted(Path(dir_path).glob(regex)))[-1]
|
||||
|
||||
|
||||
def plot_spectrogram_to_numpy(spectrogram):
|
||||
global MATPLOTLIB_FLAG
|
||||
if not MATPLOTLIB_FLAG:
|
||||
import matplotlib
|
||||
|
||||
matplotlib.use("Agg")
|
||||
MATPLOTLIB_FLAG = True
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
im = ax.imshow(spectrogram, aspect="auto", origin="lower", interpolation="none")
|
||||
plt.colorbar(im, ax=ax)
|
||||
plt.xlabel("Frames")
|
||||
plt.ylabel("Channels")
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep="")
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def load_wav_to_torch(full_path: Path | str):
|
||||
sampling_rate, data = read(full_path)
|
||||
return torch.FloatTensor(data.astype(np.float32)), sampling_rate
|
||||
|
||||
|
||||
def load_filepaths_and_text(filename: Path | str, split="|"):
|
||||
with open(filename, encoding="utf-8") as f:
|
||||
filepaths_and_text = [line.strip().split(split) for line in f]
|
||||
return filepaths_and_text
|
||||
|
||||
|
||||
def get_hparams(config_path: Path, model_path: Path, init: bool = True) -> HParams:
|
||||
model_path.mkdir(parents=True, exist_ok=True)
|
||||
config_save_path = model_path / "config.json"
|
||||
if init:
|
||||
with config_path.open() as f:
|
||||
data = f.read()
|
||||
with config_save_path.open("w") as f:
|
||||
f.write(data)
|
||||
else:
|
||||
with config_save_path.open() as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
|
||||
hparams = HParams(**config)
|
||||
hparams.model_dir = model_path.as_posix()
|
||||
return hparams
|
||||
|
||||
|
||||
def get_hparams_from_file(config_path: Path | str) -> HParams:
|
||||
config = json.loads(Path(config_path).read_text())
|
||||
hparams = HParams(**config)
|
||||
return hparams
|
||||
|
||||
|
||||
def repeat_expand_2d(content: ndarray, target_len: int) -> ndarray:
|
||||
# content : [h, t]
|
||||
|
||||
src_len = content.shape[-1]
|
||||
target = torch.zeros([content.shape[0], target_len], dtype=torch.float).to(
|
||||
content.device
|
||||
)
|
||||
temp = torch.arange(src_len + 1) * target_len / src_len
|
||||
current_pos = 0
|
||||
for i in range(target_len):
|
||||
if i < temp[current_pos + 1]:
|
||||
target[:, i] = content[:, current_pos]
|
||||
else:
|
||||
current_pos += 1
|
||||
target[:, i] = content[:, current_pos]
|
||||
|
||||
return target
|
||||
|
||||
|
||||
class HParams:
|
||||
def __init__(self, **kwargs):
|
||||
for k, v in kwargs.items():
|
||||
if type(v) == dict:
|
||||
v = HParams(**v)
|
||||
self[k] = v
|
||||
|
||||
def keys(self):
|
||||
return self.__dict__.keys()
|
||||
|
||||
def items(self):
|
||||
return self.__dict__.items()
|
||||
|
||||
def values(self):
|
||||
return self.__dict__.values()
|
||||
|
||||
def __len__(self):
|
||||
return len(self.__dict__)
|
||||
|
||||
def __getitem__(self, key):
|
||||
return getattr(self, key)
|
||||
|
||||
def __setitem__(self, key, value):
|
||||
return setattr(self, key, value)
|
||||
|
||||
def __contains__(self, key):
|
||||
return key in self.__dict__
|
||||
|
||||
def __repr__(self):
|
||||
return self.__dict__.__repr__()
|
||||
+1
-1
@@ -4,7 +4,7 @@ import shutil
|
||||
|
||||
class AttrDict(dict):
|
||||
def __init__(self, *args, **kwargs):
|
||||
super(AttrDict, self).__init__(*args, **kwargs)
|
||||
super().__init__(*args, **kwargs)
|
||||
self.__dict__ = self
|
||||
|
||||
|
||||
+260
-109
@@ -1,19 +1,24 @@
|
||||
import os
|
||||
import json
|
||||
from .env import AttrDict
|
||||
import os
|
||||
from logging import getLogger
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import torch.nn as nn
|
||||
from torch.nn import Conv1d, ConvTranspose1d, AvgPool1d, Conv2d
|
||||
from torch.nn.utils import weight_norm, remove_weight_norm, spectral_norm
|
||||
from .utils import init_weights, get_padding
|
||||
import torch.nn.functional as F
|
||||
from torch.nn import AvgPool1d, Conv1d, Conv2d, ConvTranspose1d
|
||||
from torch.nn.utils import remove_weight_norm, spectral_norm, weight_norm
|
||||
|
||||
from .env import AttrDict
|
||||
from .utils import get_padding, init_weights
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
LRELU_SLOPE = 0.1
|
||||
|
||||
|
||||
def load_model(model_path, device='cuda'):
|
||||
config_file = os.path.join(os.path.split(model_path)[0], 'config.json')
|
||||
def load_model(model_path, device="cuda"):
|
||||
config_file = os.path.join(os.path.split(model_path)[0], "config.json")
|
||||
with open(config_file) as f:
|
||||
data = f.read()
|
||||
|
||||
@@ -24,7 +29,7 @@ def load_model(model_path, device='cuda'):
|
||||
generator = Generator(h).to(device)
|
||||
|
||||
cp_dict = torch.load(model_path)
|
||||
generator.load_state_dict(cp_dict['generator'])
|
||||
generator.load_state_dict(cp_dict["generator"])
|
||||
generator.eval()
|
||||
generator.remove_weight_norm()
|
||||
del cp_dict
|
||||
@@ -33,26 +38,78 @@ def load_model(model_path, device='cuda'):
|
||||
|
||||
class ResBlock1(torch.nn.Module):
|
||||
def __init__(self, h, channels, kernel_size=3, dilation=(1, 3, 5)):
|
||||
super(ResBlock1, self).__init__()
|
||||
super().__init__()
|
||||
self.h = h
|
||||
self.convs1 = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[2],
|
||||
padding=get_padding(kernel_size, dilation[2])))
|
||||
])
|
||||
self.convs1 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[2],
|
||||
padding=get_padding(kernel_size, dilation[2]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs1.apply(init_weights)
|
||||
|
||||
self.convs2 = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=1,
|
||||
padding=get_padding(kernel_size, 1)))
|
||||
])
|
||||
self.convs2 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs2.apply(init_weights)
|
||||
|
||||
def forward(self, x):
|
||||
@@ -73,14 +130,32 @@ class ResBlock1(torch.nn.Module):
|
||||
|
||||
class ResBlock2(torch.nn.Module):
|
||||
def __init__(self, h, channels, kernel_size=3, dilation=(1, 3)):
|
||||
super(ResBlock2, self).__init__()
|
||||
super().__init__()
|
||||
self.h = h
|
||||
self.convs = nn.ModuleList([
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]))),
|
||||
weight_norm(Conv1d(channels, channels, kernel_size, 1, dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1])))
|
||||
])
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs.apply(init_weights)
|
||||
|
||||
def forward(self, x):
|
||||
@@ -96,10 +171,13 @@ class ResBlock2(torch.nn.Module):
|
||||
|
||||
|
||||
def padDiff(x):
|
||||
return F.pad(F.pad(x, (0,0,-1,1), 'constant', 0) - x, (0,0,0,-1), 'constant', 0)
|
||||
return F.pad(
|
||||
F.pad(x, (0, 0, -1, 1), "constant", 0) - x, (0, 0, 0, -1), "constant", 0
|
||||
)
|
||||
|
||||
|
||||
class SineGen(torch.nn.Module):
|
||||
""" Definition of sine generator
|
||||
"""Definition of sine generator
|
||||
SineGen(samp_rate, harmonic_num = 0,
|
||||
sine_amp = 0.1, noise_std = 0.003,
|
||||
voiced_threshold = 0,
|
||||
@@ -114,11 +192,16 @@ class SineGen(torch.nn.Module):
|
||||
segment is always sin(np.pi) or cos(0)
|
||||
"""
|
||||
|
||||
def __init__(self, samp_rate, harmonic_num=0,
|
||||
sine_amp=0.1, noise_std=0.003,
|
||||
voiced_threshold=0,
|
||||
flag_for_pulse=False):
|
||||
super(SineGen, self).__init__()
|
||||
def __init__(
|
||||
self,
|
||||
samp_rate,
|
||||
harmonic_num=0,
|
||||
sine_amp=0.1,
|
||||
noise_std=0.003,
|
||||
voiced_threshold=0,
|
||||
flag_for_pulse=False,
|
||||
):
|
||||
super().__init__()
|
||||
self.sine_amp = sine_amp
|
||||
self.noise_std = noise_std
|
||||
self.harmonic_num = harmonic_num
|
||||
@@ -133,16 +216,17 @@ class SineGen(torch.nn.Module):
|
||||
return uv
|
||||
|
||||
def _f02sine(self, f0_values):
|
||||
""" f0_values: (batchsize, length, dim)
|
||||
where dim indicates fundamental tone and overtones
|
||||
"""f0_values: (batchsize, length, dim)
|
||||
where dim indicates fundamental tone and overtones
|
||||
"""
|
||||
# convert to F0 in rad. The interger part n can be ignored
|
||||
# convert to F0 in rad. The integer part n can be ignored
|
||||
# because 2 * np.pi * n doesn't affect phase
|
||||
rad_values = (f0_values / self.sampling_rate) % 1
|
||||
|
||||
# initial phase noise (no noise for fundamental component)
|
||||
rand_ini = torch.rand(f0_values.shape[0], f0_values.shape[2], \
|
||||
device=f0_values.device)
|
||||
rand_ini = torch.rand(
|
||||
f0_values.shape[0], f0_values.shape[2], device=f0_values.device
|
||||
)
|
||||
rand_ini[:, 0] = 0
|
||||
rad_values[:, 0, :] = rad_values[:, 0, :] + rand_ini
|
||||
|
||||
@@ -159,8 +243,9 @@ class SineGen(torch.nn.Module):
|
||||
cumsum_shift = torch.zeros_like(rad_values)
|
||||
cumsum_shift[:, 1:, :] = tmp_over_one_idx * -1.0
|
||||
|
||||
sines = torch.sin(torch.cumsum(rad_values + cumsum_shift, dim=1)
|
||||
* 2 * np.pi)
|
||||
sines = torch.sin(
|
||||
torch.cumsum(rad_values + cumsum_shift, dim=1) * 2 * np.pi
|
||||
)
|
||||
else:
|
||||
# If necessary, make sure that the first time step of every
|
||||
# voiced segments is sin(pi) or cos(0)
|
||||
@@ -192,17 +277,18 @@ class SineGen(torch.nn.Module):
|
||||
return sines
|
||||
|
||||
def forward(self, f0):
|
||||
""" sine_tensor, uv = forward(f0)
|
||||
"""sine_tensor, uv = forward(f0)
|
||||
input F0: tensor(batchsize=1, length, dim=1)
|
||||
f0 for unvoiced steps should be 0
|
||||
output sine_tensor: tensor(batchsize=1, length, dim)
|
||||
output uv: tensor(batchsize=1, length, 1)
|
||||
"""
|
||||
with torch.no_grad():
|
||||
f0_buf = torch.zeros(f0.shape[0], f0.shape[1], self.dim,
|
||||
device=f0.device)
|
||||
# f0_buf = torch.zeros(f0.shape[0], f0.shape[1], self.dim, device=f0.device)
|
||||
# fundamental component
|
||||
fn = torch.multiply(f0, torch.FloatTensor([[range(1, self.harmonic_num + 2)]]).to(f0.device))
|
||||
fn = torch.multiply(
|
||||
f0, torch.FloatTensor([[range(1, self.harmonic_num + 2)]]).to(f0.device)
|
||||
)
|
||||
|
||||
# generate sine waveforms
|
||||
sine_waves = self._f02sine(fn) * self.sine_amp
|
||||
@@ -225,7 +311,7 @@ class SineGen(torch.nn.Module):
|
||||
|
||||
|
||||
class SourceModuleHnNSF(torch.nn.Module):
|
||||
""" SourceModule for hn-nsf
|
||||
"""SourceModule for hn-nsf
|
||||
SourceModule(sampling_rate, harmonic_num=0, sine_amp=0.1,
|
||||
add_noise_std=0.003, voiced_threshod=0)
|
||||
sampling_rate: sampling_rate in Hz
|
||||
@@ -234,7 +320,7 @@ class SourceModuleHnNSF(torch.nn.Module):
|
||||
add_noise_std: std of additive Gaussian noise (default: 0.003)
|
||||
note that amplitude of noise in unvoiced is decided
|
||||
by sine_amp
|
||||
voiced_threshold: threhold to set U/V given F0 (default: 0)
|
||||
voiced_threshold: threshold to set U/V given F0 (default: 0)
|
||||
Sine_source, noise_source = SourceModuleHnNSF(F0_sampled)
|
||||
F0_sampled (batchsize, length, 1)
|
||||
Sine_source (batchsize, length, 1)
|
||||
@@ -242,16 +328,23 @@ class SourceModuleHnNSF(torch.nn.Module):
|
||||
uv (batchsize, length, 1)
|
||||
"""
|
||||
|
||||
def __init__(self, sampling_rate, harmonic_num=0, sine_amp=0.1,
|
||||
add_noise_std=0.003, voiced_threshod=0):
|
||||
super(SourceModuleHnNSF, self).__init__()
|
||||
def __init__(
|
||||
self,
|
||||
sampling_rate,
|
||||
harmonic_num=0,
|
||||
sine_amp=0.1,
|
||||
add_noise_std=0.003,
|
||||
voiced_threshod=0,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.sine_amp = sine_amp
|
||||
self.noise_std = add_noise_std
|
||||
|
||||
# to produce sine waveforms
|
||||
self.l_sin_gen = SineGen(sampling_rate, harmonic_num,
|
||||
sine_amp, add_noise_std, voiced_threshod)
|
||||
self.l_sin_gen = SineGen(
|
||||
sampling_rate, harmonic_num, sine_amp, add_noise_std, voiced_threshod
|
||||
)
|
||||
|
||||
# to merge source harmonics into a single excitation
|
||||
self.l_linear = torch.nn.Linear(harmonic_num + 1, 1)
|
||||
@@ -275,56 +368,77 @@ class SourceModuleHnNSF(torch.nn.Module):
|
||||
|
||||
class Generator(torch.nn.Module):
|
||||
def __init__(self, h):
|
||||
super(Generator, self).__init__()
|
||||
super().__init__()
|
||||
self.h = h
|
||||
|
||||
self.num_kernels = len(h["resblock_kernel_sizes"])
|
||||
self.num_upsamples = len(h["upsample_rates"])
|
||||
self.f0_upsamp = torch.nn.Upsample(scale_factor=np.prod(h["upsample_rates"]))
|
||||
self.m_source = SourceModuleHnNSF(
|
||||
sampling_rate=h["sampling_rate"],
|
||||
harmonic_num=8)
|
||||
sampling_rate=h["sampling_rate"], harmonic_num=8
|
||||
)
|
||||
self.noise_convs = nn.ModuleList()
|
||||
self.conv_pre = weight_norm(Conv1d(h["inter_channels"], h["upsample_initial_channel"], 7, 1, padding=3))
|
||||
resblock = ResBlock1 if h["resblock"] == '1' else ResBlock2
|
||||
self.conv_pre = weight_norm(
|
||||
Conv1d(h["inter_channels"], h["upsample_initial_channel"], 7, 1, padding=3)
|
||||
)
|
||||
resblock = ResBlock1 if h["resblock"] == "1" else ResBlock2
|
||||
self.ups = nn.ModuleList()
|
||||
for i, (u, k) in enumerate(zip(h["upsample_rates"], h["upsample_kernel_sizes"])):
|
||||
for i, (u, k) in enumerate(
|
||||
zip(h["upsample_rates"], h["upsample_kernel_sizes"])
|
||||
):
|
||||
c_cur = h["upsample_initial_channel"] // (2 ** (i + 1))
|
||||
self.ups.append(weight_norm(
|
||||
ConvTranspose1d(h["upsample_initial_channel"] // (2 ** i), h["upsample_initial_channel"] // (2 ** (i + 1)),
|
||||
k, u, padding=(k - u) // 2)))
|
||||
self.ups.append(
|
||||
weight_norm(
|
||||
ConvTranspose1d(
|
||||
h["upsample_initial_channel"] // (2**i),
|
||||
h["upsample_initial_channel"] // (2 ** (i + 1)),
|
||||
k,
|
||||
u,
|
||||
padding=(k - u) // 2,
|
||||
)
|
||||
)
|
||||
)
|
||||
if i + 1 < len(h["upsample_rates"]): #
|
||||
stride_f0 = np.prod(h["upsample_rates"][i + 1:])
|
||||
self.noise_convs.append(Conv1d(
|
||||
1, c_cur, kernel_size=stride_f0 * 2, stride=stride_f0, padding=stride_f0 // 2))
|
||||
stride_f0 = np.prod(h["upsample_rates"][i + 1 :])
|
||||
self.noise_convs.append(
|
||||
Conv1d(
|
||||
1,
|
||||
c_cur,
|
||||
kernel_size=stride_f0 * 2,
|
||||
stride=stride_f0,
|
||||
padding=stride_f0 // 2,
|
||||
)
|
||||
)
|
||||
else:
|
||||
self.noise_convs.append(Conv1d(1, c_cur, kernel_size=1))
|
||||
self.resblocks = nn.ModuleList()
|
||||
for i in range(len(self.ups)):
|
||||
ch = h["upsample_initial_channel"] // (2 ** (i + 1))
|
||||
for j, (k, d) in enumerate(zip(h["resblock_kernel_sizes"], h["resblock_dilation_sizes"])):
|
||||
for j, (k, d) in enumerate(
|
||||
zip(h["resblock_kernel_sizes"], h["resblock_dilation_sizes"])
|
||||
):
|
||||
self.resblocks.append(resblock(h, ch, k, d))
|
||||
|
||||
self.conv_post = weight_norm(Conv1d(ch, 1, 7, 1, padding=3))
|
||||
self.ups.apply(init_weights)
|
||||
self.conv_post.apply(init_weights)
|
||||
self.cond = nn.Conv1d(h['gin_channels'], h['upsample_initial_channel'], 1)
|
||||
self.cond = nn.Conv1d(h["gin_channels"], h["upsample_initial_channel"], 1)
|
||||
|
||||
def forward(self, x, f0, g=None):
|
||||
# print(1,x.shape,f0.shape,f0[:, None].shape)
|
||||
# LOG.info(1,x.shape,f0.shape,f0[:, None].shape)
|
||||
f0 = self.f0_upsamp(f0[:, None]).transpose(1, 2) # bs,n,t
|
||||
# print(2,f0.shape)
|
||||
# LOG.info(2,f0.shape)
|
||||
har_source, noi_source, uv = self.m_source(f0)
|
||||
har_source = har_source.transpose(1, 2)
|
||||
x = self.conv_pre(x)
|
||||
x = x + self.cond(g)
|
||||
# print(124,x.shape,har_source.shape)
|
||||
# LOG.info(124,x.shape,har_source.shape)
|
||||
for i in range(self.num_upsamples):
|
||||
x = F.leaky_relu(x, LRELU_SLOPE)
|
||||
# print(3,x.shape)
|
||||
# LOG.info(3,x.shape)
|
||||
x = self.ups[i](x)
|
||||
x_source = self.noise_convs[i](har_source)
|
||||
# print(4,x_source.shape,har_source.shape,x.shape)
|
||||
# LOG.info(4,x_source.shape,har_source.shape,x.shape)
|
||||
x = x + x_source
|
||||
xs = None
|
||||
for j in range(self.num_kernels):
|
||||
@@ -340,7 +454,7 @@ class Generator(torch.nn.Module):
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
print('Removing weight norm...')
|
||||
LOG.info("Removing weight norm...")
|
||||
for l in self.ups:
|
||||
remove_weight_norm(l)
|
||||
for l in self.resblocks:
|
||||
@@ -351,16 +465,50 @@ class Generator(torch.nn.Module):
|
||||
|
||||
class DiscriminatorP(torch.nn.Module):
|
||||
def __init__(self, period, kernel_size=5, stride=3, use_spectral_norm=False):
|
||||
super(DiscriminatorP, self).__init__()
|
||||
super().__init__()
|
||||
self.period = period
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv2d(1, 32, (kernel_size, 1), (stride, 1), padding=(get_padding(5, 1), 0))),
|
||||
norm_f(Conv2d(32, 128, (kernel_size, 1), (stride, 1), padding=(get_padding(5, 1), 0))),
|
||||
norm_f(Conv2d(128, 512, (kernel_size, 1), (stride, 1), padding=(get_padding(5, 1), 0))),
|
||||
norm_f(Conv2d(512, 1024, (kernel_size, 1), (stride, 1), padding=(get_padding(5, 1), 0))),
|
||||
norm_f(Conv2d(1024, 1024, (kernel_size, 1), 1, padding=(2, 0))),
|
||||
])
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1,
|
||||
32,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(5, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
32,
|
||||
128,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(5, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
128,
|
||||
512,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(5, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
512,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(5, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(Conv2d(1024, 1024, (kernel_size, 1), 1, padding=(2, 0))),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv2d(1024, 1, (3, 1), 1, padding=(1, 0)))
|
||||
|
||||
def forward(self, x):
|
||||
@@ -387,7 +535,7 @@ class DiscriminatorP(torch.nn.Module):
|
||||
|
||||
class MultiPeriodDiscriminator(torch.nn.Module):
|
||||
def __init__(self, periods=None):
|
||||
super(MultiPeriodDiscriminator, self).__init__()
|
||||
super().__init__()
|
||||
self.periods = periods if periods is not None else [2, 3, 5, 7, 11]
|
||||
self.discriminators = nn.ModuleList()
|
||||
for period in self.periods:
|
||||
@@ -411,17 +559,19 @@ class MultiPeriodDiscriminator(torch.nn.Module):
|
||||
|
||||
class DiscriminatorS(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super(DiscriminatorS, self).__init__()
|
||||
super().__init__()
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList([
|
||||
norm_f(Conv1d(1, 128, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(128, 128, 41, 2, groups=4, padding=20)),
|
||||
norm_f(Conv1d(128, 256, 41, 2, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 512, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(512, 1024, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 1, groups=16, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
])
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(Conv1d(1, 128, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(128, 128, 41, 2, groups=4, padding=20)),
|
||||
norm_f(Conv1d(128, 256, 41, 2, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 512, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(512, 1024, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 1, groups=16, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv1d(1024, 1, 3, 1, padding=1))
|
||||
|
||||
def forward(self, x):
|
||||
@@ -439,16 +589,17 @@ class DiscriminatorS(torch.nn.Module):
|
||||
|
||||
class MultiScaleDiscriminator(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(MultiScaleDiscriminator, self).__init__()
|
||||
self.discriminators = nn.ModuleList([
|
||||
DiscriminatorS(use_spectral_norm=True),
|
||||
DiscriminatorS(),
|
||||
DiscriminatorS(),
|
||||
])
|
||||
self.meanpools = nn.ModuleList([
|
||||
AvgPool1d(4, 2, padding=2),
|
||||
AvgPool1d(4, 2, padding=2)
|
||||
])
|
||||
super().__init__()
|
||||
self.discriminators = nn.ModuleList(
|
||||
[
|
||||
DiscriminatorS(use_spectral_norm=True),
|
||||
DiscriminatorS(),
|
||||
DiscriminatorS(),
|
||||
]
|
||||
)
|
||||
self.meanpools = nn.ModuleList(
|
||||
[AvgPool1d(4, 2, padding=2), AvgPool1d(4, 2, padding=2)]
|
||||
)
|
||||
|
||||
def forward(self, y, y_hat):
|
||||
y_d_rs = []
|
||||
@@ -484,8 +635,8 @@ def discriminator_loss(disc_real_outputs, disc_generated_outputs):
|
||||
g_losses = []
|
||||
for dr, dg in zip(disc_real_outputs, disc_generated_outputs):
|
||||
r_loss = torch.mean((1 - dr) ** 2)
|
||||
g_loss = torch.mean(dg ** 2)
|
||||
loss += (r_loss + g_loss)
|
||||
g_loss = torch.mean(dg**2)
|
||||
loss += r_loss + g_loss
|
||||
r_losses.append(r_loss.item())
|
||||
g_losses.append(g_loss.item())
|
||||
|
||||
@@ -0,0 +1,162 @@
|
||||
import os
|
||||
|
||||
os.environ["LRU_CACHE_CAPACITY"] = "3"
|
||||
from logging import getLogger
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile as sf
|
||||
import torch
|
||||
import torch.utils.data
|
||||
from librosa.filters import mel as librosa_mel_fn
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def load_wav_to_torch(full_path, target_sr=None, return_empty_on_exception=False):
|
||||
sampling_rate = None
|
||||
try:
|
||||
data, sampling_rate = sf.read(full_path, always_2d=True) # than soundfile.
|
||||
except Exception as ex:
|
||||
LOG.info(f"'{full_path}' failed to load.\nException:")
|
||||
LOG.info(ex)
|
||||
if return_empty_on_exception:
|
||||
return [], sampling_rate or target_sr or 32000
|
||||
else:
|
||||
raise Exception(ex)
|
||||
|
||||
if len(data.shape) > 1:
|
||||
data = data[:, 0]
|
||||
assert (
|
||||
len(data) > 2
|
||||
) # check duration of audio file is > 2 samples (because otherwise the slice operation was on the wrong dimension)
|
||||
|
||||
if np.issubdtype(data.dtype, np.integer): # if audio data is type int
|
||||
max_mag = -np.iinfo(
|
||||
data.dtype
|
||||
).min # maximum magnitude = min possible value of intXX
|
||||
else: # if audio data is type fp32
|
||||
max_mag = max(np.amax(data), -np.amin(data))
|
||||
max_mag = (
|
||||
(2**31) + 1
|
||||
if max_mag > (2**15)
|
||||
else ((2**15) + 1 if max_mag > 1.01 else 1.0)
|
||||
) # data should be either 16-bit INT, 32-bit INT or [-1 to 1] float32
|
||||
|
||||
data = torch.FloatTensor(data.astype(np.float32)) / max_mag
|
||||
|
||||
if (
|
||||
torch.isinf(data) | torch.isnan(data)
|
||||
).any() and return_empty_on_exception: # resample will crash with inf/NaN inputs. return_empty_on_exception will return empty arr instead of except
|
||||
return [], sampling_rate or target_sr or 32000
|
||||
if target_sr is not None and sampling_rate != target_sr:
|
||||
data = torch.from_numpy(
|
||||
librosa.core.resample(
|
||||
data.numpy(), orig_sr=sampling_rate, target_sr=target_sr
|
||||
)
|
||||
)
|
||||
sampling_rate = target_sr
|
||||
|
||||
return data, sampling_rate
|
||||
|
||||
|
||||
def dynamic_range_compression(x, C=1, clip_val=1e-5):
|
||||
return np.log(np.clip(x, a_min=clip_val, a_max=None) * C)
|
||||
|
||||
|
||||
def dynamic_range_decompression(x, C=1):
|
||||
return np.exp(x) / C
|
||||
|
||||
|
||||
def dynamic_range_compression_torch(x, C=1, clip_val=1e-5):
|
||||
return torch.log(torch.clamp(x, min=clip_val) * C)
|
||||
|
||||
|
||||
def dynamic_range_decompression_torch(x, C=1):
|
||||
return torch.exp(x) / C
|
||||
|
||||
|
||||
class STFT:
|
||||
def __init__(
|
||||
self,
|
||||
sr=22050,
|
||||
n_mels=80,
|
||||
n_fft=1024,
|
||||
win_size=1024,
|
||||
hop_length=256,
|
||||
fmin=20,
|
||||
fmax=11025,
|
||||
clip_val=1e-5,
|
||||
):
|
||||
self.target_sr = sr
|
||||
|
||||
self.n_mels = n_mels
|
||||
self.n_fft = n_fft
|
||||
self.win_size = win_size
|
||||
self.hop_length = hop_length
|
||||
self.fmin = fmin
|
||||
self.fmax = fmax
|
||||
self.clip_val = clip_val
|
||||
self.mel_basis = {}
|
||||
self.hann_window = {}
|
||||
|
||||
def get_mel(self, y, center=False):
|
||||
sampling_rate = self.target_sr
|
||||
n_mels = self.n_mels
|
||||
n_fft = self.n_fft
|
||||
win_size = self.win_size
|
||||
hop_length = self.hop_length
|
||||
fmin = self.fmin
|
||||
fmax = self.fmax
|
||||
clip_val = self.clip_val
|
||||
|
||||
if torch.min(y) < -1.0:
|
||||
LOG.info("min value is ", torch.min(y))
|
||||
if torch.max(y) > 1.0:
|
||||
LOG.info("max value is ", torch.max(y))
|
||||
|
||||
if fmax not in self.mel_basis:
|
||||
mel = librosa_mel_fn(
|
||||
sr=sampling_rate, n_fft=n_fft, n_mels=n_mels, fmin=fmin, fmax=fmax
|
||||
)
|
||||
self.mel_basis[str(fmax) + "_" + str(y.device)] = (
|
||||
torch.from_numpy(mel).float().to(y.device)
|
||||
)
|
||||
self.hann_window[str(y.device)] = torch.hann_window(self.win_size).to(
|
||||
y.device
|
||||
)
|
||||
|
||||
y = torch.nn.functional.pad(
|
||||
y.unsqueeze(1),
|
||||
(int((n_fft - hop_length) / 2), int((n_fft - hop_length) / 2)),
|
||||
mode="reflect",
|
||||
)
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(
|
||||
y,
|
||||
n_fft,
|
||||
hop_length=hop_length,
|
||||
win_length=win_size,
|
||||
window=self.hann_window[str(y.device)],
|
||||
center=center,
|
||||
pad_mode="reflect",
|
||||
normalized=False,
|
||||
onesided=True,
|
||||
)
|
||||
# LOG.info(111,spec)
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + (1e-9))
|
||||
# LOG.info(222,spec)
|
||||
spec = torch.matmul(self.mel_basis[str(fmax) + "_" + str(y.device)], spec)
|
||||
# LOG.info(333,spec)
|
||||
spec = dynamic_range_compression_torch(spec, clip_val=clip_val)
|
||||
# LOG.info(444,spec)
|
||||
return spec
|
||||
|
||||
def __call__(self, audiopath):
|
||||
audio, sr = load_wav_to_torch(audiopath, target_sr=self.target_sr)
|
||||
spect = self.get_mel(audio.unsqueeze(0)).squeeze(0)
|
||||
return spect
|
||||
|
||||
|
||||
stft = STFT()
|
||||
+22
-19
@@ -1,16 +1,18 @@
|
||||
import glob
|
||||
import os
|
||||
import matplotlib
|
||||
import torch
|
||||
from torch.nn.utils import weight_norm
|
||||
from logging import getLogger
|
||||
|
||||
# matplotlib.use("Agg")
|
||||
import matplotlib.pylab as plt
|
||||
import torch
|
||||
from torch.nn.utils import weight_norm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def plot_spectrogram(spectrogram):
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
im = ax.imshow(spectrogram, aspect="auto", origin="lower",
|
||||
interpolation='none')
|
||||
im = ax.imshow(spectrogram, aspect="auto", origin="lower", interpolation="none")
|
||||
plt.colorbar(im, ax=ax)
|
||||
|
||||
fig.canvas.draw()
|
||||
@@ -32,37 +34,38 @@ def apply_weight_norm(m):
|
||||
|
||||
|
||||
def get_padding(kernel_size, dilation=1):
|
||||
return int((kernel_size*dilation - dilation)/2)
|
||||
return int((kernel_size * dilation - dilation) / 2)
|
||||
|
||||
|
||||
def load_checkpoint(filepath, device):
|
||||
assert os.path.isfile(filepath)
|
||||
print("Loading '{}'".format(filepath))
|
||||
LOG.info(f"Loading '{filepath}'")
|
||||
checkpoint_dict = torch.load(filepath, map_location=device)
|
||||
print("Complete.")
|
||||
LOG.info("Complete.")
|
||||
return checkpoint_dict
|
||||
|
||||
|
||||
def save_checkpoint(filepath, obj):
|
||||
print("Saving checkpoint to {}".format(filepath))
|
||||
LOG.info(f"Saving checkpoint to {filepath}")
|
||||
torch.save(obj, filepath)
|
||||
print("Complete.")
|
||||
LOG.info("Complete.")
|
||||
|
||||
|
||||
def del_old_checkpoints(cp_dir, prefix, n_models=2):
|
||||
pattern = os.path.join(cp_dir, prefix + '????????')
|
||||
cp_list = glob.glob(pattern) # get checkpoint paths
|
||||
cp_list = sorted(cp_list)# sort by iter
|
||||
if len(cp_list) > n_models: # if more than n_models models are found
|
||||
for cp in cp_list[:-n_models]:# delete the oldest models other than lastest n_models
|
||||
open(cp, 'w').close()# empty file contents
|
||||
os.unlink(cp)# delete file (move to trash when using Colab)
|
||||
pattern = os.path.join(cp_dir, prefix + "????????")
|
||||
cp_list = glob.glob(pattern) # get checkpoint paths
|
||||
cp_list = sorted(cp_list) # sort by iter
|
||||
if len(cp_list) > n_models: # if more than n_models models are found
|
||||
for cp in cp_list[
|
||||
:-n_models
|
||||
]: # delete the oldest models other than last n_models
|
||||
open(cp, "w").close() # empty file contents
|
||||
os.unlink(cp) # delete file (move to trash when using Colab)
|
||||
|
||||
|
||||
def scan_checkpoint(cp_dir, prefix):
|
||||
pattern = os.path.join(cp_dir, prefix + '????????')
|
||||
pattern = os.path.join(cp_dir, prefix + "????????")
|
||||
cp_list = glob.glob(pattern)
|
||||
if len(cp_list) == 0:
|
||||
return None
|
||||
return sorted(cp_list)[-1]
|
||||
|
||||
@@ -1,310 +0,0 @@
|
||||
import logging
|
||||
import multiprocessing
|
||||
import time
|
||||
|
||||
logging.getLogger('matplotlib').setLevel(logging.WARNING)
|
||||
import os
|
||||
import json
|
||||
import argparse
|
||||
import itertools
|
||||
import math
|
||||
import torch
|
||||
from torch import nn, optim
|
||||
from torch.nn import functional as F
|
||||
from torch.utils.data import DataLoader
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
import torch.multiprocessing as mp
|
||||
import torch.distributed as dist
|
||||
from torch.nn.parallel import DistributedDataParallel as DDP
|
||||
from torch.cuda.amp import autocast, GradScaler
|
||||
|
||||
import modules.commons as commons
|
||||
import utils
|
||||
from data_utils import TextAudioSpeakerLoader, TextAudioCollate
|
||||
from models import (
|
||||
SynthesizerTrn,
|
||||
MultiPeriodDiscriminator,
|
||||
)
|
||||
from modules.losses import (
|
||||
kl_loss,
|
||||
generator_loss, discriminator_loss, feature_loss
|
||||
)
|
||||
|
||||
from modules.mel_processing import mel_spectrogram_torch, spec_to_mel_torch
|
||||
|
||||
torch.backends.cudnn.benchmark = True
|
||||
global_step = 0
|
||||
start_time = time.time()
|
||||
|
||||
# os.environ['TORCH_DISTRIBUTED_DEBUG'] = 'INFO'
|
||||
|
||||
|
||||
def main():
|
||||
"""Assume Single Node Multi GPUs Training Only"""
|
||||
assert torch.cuda.is_available(), "CPU training is not allowed."
|
||||
hps = utils.get_hparams()
|
||||
|
||||
n_gpus = torch.cuda.device_count()
|
||||
os.environ['MASTER_ADDR'] = 'localhost'
|
||||
os.environ['MASTER_PORT'] = hps.train.port
|
||||
|
||||
mp.spawn(run, nprocs=n_gpus, args=(n_gpus, hps,))
|
||||
|
||||
|
||||
def run(rank, n_gpus, hps):
|
||||
global global_step
|
||||
if rank == 0:
|
||||
logger = utils.get_logger(hps.model_dir)
|
||||
logger.info(hps)
|
||||
utils.check_git_hash(hps.model_dir)
|
||||
writer = SummaryWriter(log_dir=hps.model_dir)
|
||||
writer_eval = SummaryWriter(log_dir=os.path.join(hps.model_dir, "eval"))
|
||||
|
||||
# for pytorch on win, backend use gloo
|
||||
dist.init_process_group(backend= 'gloo' if os.name == 'nt' else 'nccl', init_method='env://', world_size=n_gpus, rank=rank)
|
||||
torch.manual_seed(hps.train.seed)
|
||||
torch.cuda.set_device(rank)
|
||||
collate_fn = TextAudioCollate()
|
||||
train_dataset = TextAudioSpeakerLoader(hps.data.training_files, hps)
|
||||
num_workers = 5 if multiprocessing.cpu_count() > 4 else multiprocessing.cpu_count()
|
||||
train_loader = DataLoader(train_dataset, num_workers=num_workers, shuffle=False, pin_memory=True,
|
||||
batch_size=hps.train.batch_size, collate_fn=collate_fn)
|
||||
if rank == 0:
|
||||
eval_dataset = TextAudioSpeakerLoader(hps.data.validation_files, hps)
|
||||
eval_loader = DataLoader(eval_dataset, num_workers=1, shuffle=False,
|
||||
batch_size=1, pin_memory=False,
|
||||
drop_last=False, collate_fn=collate_fn)
|
||||
|
||||
net_g = SynthesizerTrn(
|
||||
hps.data.filter_length // 2 + 1,
|
||||
hps.train.segment_size // hps.data.hop_length,
|
||||
**hps.model).cuda(rank)
|
||||
net_d = MultiPeriodDiscriminator(hps.model.use_spectral_norm).cuda(rank)
|
||||
optim_g = torch.optim.AdamW(
|
||||
net_g.parameters(),
|
||||
hps.train.learning_rate,
|
||||
betas=hps.train.betas,
|
||||
eps=hps.train.eps)
|
||||
optim_d = torch.optim.AdamW(
|
||||
net_d.parameters(),
|
||||
hps.train.learning_rate,
|
||||
betas=hps.train.betas,
|
||||
eps=hps.train.eps)
|
||||
net_g = DDP(net_g, device_ids=[rank]) # , find_unused_parameters=True)
|
||||
net_d = DDP(net_d, device_ids=[rank])
|
||||
|
||||
skip_optimizer = False
|
||||
try:
|
||||
_, _, _, epoch_str = utils.load_checkpoint(utils.latest_checkpoint_path(hps.model_dir, "G_*.pth"), net_g,
|
||||
optim_g, skip_optimizer)
|
||||
_, _, _, epoch_str = utils.load_checkpoint(utils.latest_checkpoint_path(hps.model_dir, "D_*.pth"), net_d,
|
||||
optim_d, skip_optimizer)
|
||||
epoch_str = max(epoch_str, 1)
|
||||
global_step = (epoch_str - 1) * len(train_loader)
|
||||
except:
|
||||
print("load old checkpoint failed...")
|
||||
epoch_str = 1
|
||||
global_step = 0
|
||||
if skip_optimizer:
|
||||
epoch_str = 1
|
||||
global_step = 0
|
||||
|
||||
scheduler_g = torch.optim.lr_scheduler.ExponentialLR(optim_g, gamma=hps.train.lr_decay, last_epoch=epoch_str - 2)
|
||||
scheduler_d = torch.optim.lr_scheduler.ExponentialLR(optim_d, gamma=hps.train.lr_decay, last_epoch=epoch_str - 2)
|
||||
|
||||
scaler = GradScaler(enabled=hps.train.fp16_run)
|
||||
|
||||
for epoch in range(epoch_str, hps.train.epochs + 1):
|
||||
if rank == 0:
|
||||
train_and_evaluate(rank, epoch, hps, [net_g, net_d], [optim_g, optim_d], [scheduler_g, scheduler_d], scaler,
|
||||
[train_loader, eval_loader], logger, [writer, writer_eval])
|
||||
else:
|
||||
train_and_evaluate(rank, epoch, hps, [net_g, net_d], [optim_g, optim_d], [scheduler_g, scheduler_d], scaler,
|
||||
[train_loader, None], None, None)
|
||||
scheduler_g.step()
|
||||
scheduler_d.step()
|
||||
|
||||
|
||||
def train_and_evaluate(rank, epoch, hps, nets, optims, schedulers, scaler, loaders, logger, writers):
|
||||
net_g, net_d = nets
|
||||
optim_g, optim_d = optims
|
||||
scheduler_g, scheduler_d = schedulers
|
||||
train_loader, eval_loader = loaders
|
||||
if writers is not None:
|
||||
writer, writer_eval = writers
|
||||
|
||||
# train_loader.batch_sampler.set_epoch(epoch)
|
||||
global global_step
|
||||
|
||||
net_g.train()
|
||||
net_d.train()
|
||||
for batch_idx, items in enumerate(train_loader):
|
||||
c, f0, spec, y, spk, lengths, uv = items
|
||||
g = spk.cuda(rank, non_blocking=True)
|
||||
spec, y = spec.cuda(rank, non_blocking=True), y.cuda(rank, non_blocking=True)
|
||||
c = c.cuda(rank, non_blocking=True)
|
||||
f0 = f0.cuda(rank, non_blocking=True)
|
||||
uv = uv.cuda(rank, non_blocking=True)
|
||||
lengths = lengths.cuda(rank, non_blocking=True)
|
||||
mel = spec_to_mel_torch(
|
||||
spec,
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax)
|
||||
|
||||
with autocast(enabled=hps.train.fp16_run):
|
||||
y_hat, ids_slice, z_mask, \
|
||||
(z, z_p, m_p, logs_p, m_q, logs_q), pred_lf0, norm_lf0, lf0 = net_g(c, f0, uv, spec, g=g, c_lengths=lengths,
|
||||
spec_lengths=lengths)
|
||||
|
||||
y_mel = commons.slice_segments(mel, ids_slice, hps.train.segment_size // hps.data.hop_length)
|
||||
y_hat_mel = mel_spectrogram_torch(
|
||||
y_hat.squeeze(1),
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.hop_length,
|
||||
hps.data.win_length,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax
|
||||
)
|
||||
y = commons.slice_segments(y, ids_slice * hps.data.hop_length, hps.train.segment_size) # slice
|
||||
|
||||
# Discriminator
|
||||
y_d_hat_r, y_d_hat_g, _, _ = net_d(y, y_hat.detach())
|
||||
|
||||
with autocast(enabled=False):
|
||||
loss_disc, losses_disc_r, losses_disc_g = discriminator_loss(y_d_hat_r, y_d_hat_g)
|
||||
loss_disc_all = loss_disc
|
||||
|
||||
optim_d.zero_grad()
|
||||
scaler.scale(loss_disc_all).backward()
|
||||
scaler.unscale_(optim_d)
|
||||
grad_norm_d = commons.clip_grad_value_(net_d.parameters(), None)
|
||||
scaler.step(optim_d)
|
||||
|
||||
with autocast(enabled=hps.train.fp16_run):
|
||||
# Generator
|
||||
y_d_hat_r, y_d_hat_g, fmap_r, fmap_g = net_d(y, y_hat)
|
||||
with autocast(enabled=False):
|
||||
loss_mel = F.l1_loss(y_mel, y_hat_mel) * hps.train.c_mel
|
||||
loss_kl = kl_loss(z_p, logs_q, m_p, logs_p, z_mask) * hps.train.c_kl
|
||||
loss_fm = feature_loss(fmap_r, fmap_g)
|
||||
loss_gen, losses_gen = generator_loss(y_d_hat_g)
|
||||
loss_lf0 = F.mse_loss(pred_lf0, lf0)
|
||||
loss_gen_all = loss_gen + loss_fm + loss_mel + loss_kl + loss_lf0
|
||||
optim_g.zero_grad()
|
||||
scaler.scale(loss_gen_all).backward()
|
||||
scaler.unscale_(optim_g)
|
||||
grad_norm_g = commons.clip_grad_value_(net_g.parameters(), None)
|
||||
scaler.step(optim_g)
|
||||
scaler.update()
|
||||
|
||||
if rank == 0:
|
||||
if global_step % hps.train.log_interval == 0:
|
||||
lr = optim_g.param_groups[0]['lr']
|
||||
losses = [loss_disc, loss_gen, loss_fm, loss_mel, loss_kl]
|
||||
logger.info('Train Epoch: {} [{:.0f}%]'.format(
|
||||
epoch,
|
||||
100. * batch_idx / len(train_loader)))
|
||||
logger.info(f"Losses: {[x.item() for x in losses]}, step: {global_step}, lr: {lr}")
|
||||
|
||||
scalar_dict = {"loss/g/total": loss_gen_all, "loss/d/total": loss_disc_all, "learning_rate": lr,
|
||||
"grad_norm_d": grad_norm_d, "grad_norm_g": grad_norm_g}
|
||||
scalar_dict.update({"loss/g/fm": loss_fm, "loss/g/mel": loss_mel, "loss/g/kl": loss_kl,
|
||||
"loss/g/lf0": loss_lf0})
|
||||
|
||||
# scalar_dict.update({"loss/g/{}".format(i): v for i, v in enumerate(losses_gen)})
|
||||
# scalar_dict.update({"loss/d_r/{}".format(i): v for i, v in enumerate(losses_disc_r)})
|
||||
# scalar_dict.update({"loss/d_g/{}".format(i): v for i, v in enumerate(losses_disc_g)})
|
||||
image_dict = {
|
||||
"slice/mel_org": utils.plot_spectrogram_to_numpy(y_mel[0].data.cpu().numpy()),
|
||||
"slice/mel_gen": utils.plot_spectrogram_to_numpy(y_hat_mel[0].data.cpu().numpy()),
|
||||
"all/mel": utils.plot_spectrogram_to_numpy(mel[0].data.cpu().numpy()),
|
||||
"all/lf0": utils.plot_data_to_numpy(lf0[0, 0, :].cpu().numpy(),
|
||||
pred_lf0[0, 0, :].detach().cpu().numpy()),
|
||||
"all/norm_lf0": utils.plot_data_to_numpy(lf0[0, 0, :].cpu().numpy(),
|
||||
norm_lf0[0, 0, :].detach().cpu().numpy())
|
||||
}
|
||||
|
||||
utils.summarize(
|
||||
writer=writer,
|
||||
global_step=global_step,
|
||||
images=image_dict,
|
||||
scalars=scalar_dict
|
||||
)
|
||||
|
||||
if global_step % hps.train.eval_interval == 0:
|
||||
evaluate(hps, net_g, eval_loader, writer_eval)
|
||||
utils.save_checkpoint(net_g, optim_g, hps.train.learning_rate, epoch,
|
||||
os.path.join(hps.model_dir, "G_{}.pth".format(global_step)))
|
||||
utils.save_checkpoint(net_d, optim_d, hps.train.learning_rate, epoch,
|
||||
os.path.join(hps.model_dir, "D_{}.pth".format(global_step)))
|
||||
keep_ckpts = getattr(hps.train, 'keep_ckpts', 0)
|
||||
if keep_ckpts > 0:
|
||||
utils.clean_checkpoints(path_to_models=hps.model_dir, n_ckpts_to_keep=keep_ckpts, sort_by_time=True)
|
||||
|
||||
global_step += 1
|
||||
|
||||
if rank == 0:
|
||||
global start_time
|
||||
now = time.time()
|
||||
durtaion = format(now - start_time, '.2f')
|
||||
logger.info(f'====> Epoch: {epoch}, cost {durtaion} s')
|
||||
start_time = now
|
||||
|
||||
|
||||
def evaluate(hps, generator, eval_loader, writer_eval):
|
||||
generator.eval()
|
||||
image_dict = {}
|
||||
audio_dict = {}
|
||||
with torch.no_grad():
|
||||
for batch_idx, items in enumerate(eval_loader):
|
||||
c, f0, spec, y, spk, _, uv = items
|
||||
g = spk[:1].cuda(0)
|
||||
spec, y = spec[:1].cuda(0), y[:1].cuda(0)
|
||||
c = c[:1].cuda(0)
|
||||
f0 = f0[:1].cuda(0)
|
||||
uv= uv[:1].cuda(0)
|
||||
mel = spec_to_mel_torch(
|
||||
spec,
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax)
|
||||
y_hat = generator.module.infer(c, f0, uv, g=g)
|
||||
|
||||
y_hat_mel = mel_spectrogram_torch(
|
||||
y_hat.squeeze(1).float(),
|
||||
hps.data.filter_length,
|
||||
hps.data.n_mel_channels,
|
||||
hps.data.sampling_rate,
|
||||
hps.data.hop_length,
|
||||
hps.data.win_length,
|
||||
hps.data.mel_fmin,
|
||||
hps.data.mel_fmax
|
||||
)
|
||||
|
||||
audio_dict.update({
|
||||
f"gen/audio_{batch_idx}": y_hat[0],
|
||||
f"gt/audio_{batch_idx}": y[0]
|
||||
})
|
||||
image_dict.update({
|
||||
f"gen/mel": utils.plot_spectrogram_to_numpy(y_hat_mel[0].cpu().numpy()),
|
||||
"gt/mel": utils.plot_spectrogram_to_numpy(mel[0].cpu().numpy())
|
||||
})
|
||||
utils.summarize(
|
||||
writer=writer_eval,
|
||||
global_step=global_step,
|
||||
images=image_dict,
|
||||
audios=audio_dict,
|
||||
audio_sampling_rate=hps.data.sampling_rate
|
||||
)
|
||||
generator.train()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,18 +0,0 @@
|
||||
Flask
|
||||
Flask_Cors
|
||||
gradio
|
||||
numpy==1.20.3
|
||||
pyworld==0.2.5
|
||||
scipy==1.7.3
|
||||
SoundFile==0.12.1
|
||||
torch==1.13.1
|
||||
torchaudio==0.13.1
|
||||
tqdm
|
||||
scikit-maad
|
||||
praat-parselmouth
|
||||
onnx
|
||||
onnxsim
|
||||
onnxoptimizer
|
||||
fairseq==0.12.2
|
||||
librosa==0.8.1
|
||||
tensorboard
|
||||
@@ -1,502 +0,0 @@
|
||||
import os
|
||||
import glob
|
||||
import re
|
||||
import sys
|
||||
import argparse
|
||||
import logging
|
||||
import json
|
||||
import subprocess
|
||||
import random
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
from scipy.io.wavfile import read
|
||||
import torch
|
||||
from torch.nn import functional as F
|
||||
from modules.commons import sequence_mask
|
||||
from hubert import hubert_model
|
||||
MATPLOTLIB_FLAG = False
|
||||
|
||||
logging.basicConfig(stream=sys.stdout, level=logging.DEBUG)
|
||||
logger = logging
|
||||
|
||||
f0_bin = 256
|
||||
f0_max = 1100.0
|
||||
f0_min = 50.0
|
||||
f0_mel_min = 1127 * np.log(1 + f0_min / 700)
|
||||
f0_mel_max = 1127 * np.log(1 + f0_max / 700)
|
||||
|
||||
|
||||
# def normalize_f0(f0, random_scale=True):
|
||||
# f0_norm = f0.clone() # create a copy of the input Tensor
|
||||
# batch_size, _, frame_length = f0_norm.shape
|
||||
# for i in range(batch_size):
|
||||
# means = torch.mean(f0_norm[i, 0, :])
|
||||
# if random_scale:
|
||||
# factor = random.uniform(0.8, 1.2)
|
||||
# else:
|
||||
# factor = 1
|
||||
# f0_norm[i, 0, :] = (f0_norm[i, 0, :] - means) * factor
|
||||
# return f0_norm
|
||||
# def normalize_f0(f0, random_scale=True):
|
||||
# means = torch.mean(f0[:, 0, :], dim=1, keepdim=True)
|
||||
# if random_scale:
|
||||
# factor = torch.Tensor(f0.shape[0],1).uniform_(0.8, 1.2).to(f0.device)
|
||||
# else:
|
||||
# factor = torch.ones(f0.shape[0], 1, 1).to(f0.device)
|
||||
# f0_norm = (f0 - means.unsqueeze(-1)) * factor.unsqueeze(-1)
|
||||
# return f0_norm
|
||||
def normalize_f0(f0, x_mask, uv, random_scale=True):
|
||||
# calculate means based on x_mask
|
||||
uv_sum = torch.sum(uv, dim=1, keepdim=True)
|
||||
uv_sum[uv_sum == 0] = 9999
|
||||
means = torch.sum(f0[:, 0, :] * uv, dim=1, keepdim=True) / uv_sum
|
||||
|
||||
if random_scale:
|
||||
factor = torch.Tensor(f0.shape[0], 1).uniform_(0.8, 1.2).to(f0.device)
|
||||
else:
|
||||
factor = torch.ones(f0.shape[0], 1).to(f0.device)
|
||||
# normalize f0 based on means and factor
|
||||
f0_norm = (f0 - means.unsqueeze(-1)) * factor.unsqueeze(-1)
|
||||
if torch.isnan(f0_norm).any():
|
||||
exit(0)
|
||||
return f0_norm * x_mask
|
||||
|
||||
|
||||
def plot_data_to_numpy(x, y):
|
||||
global MATPLOTLIB_FLAG
|
||||
if not MATPLOTLIB_FLAG:
|
||||
import matplotlib
|
||||
matplotlib.use("Agg")
|
||||
MATPLOTLIB_FLAG = True
|
||||
mpl_logger = logging.getLogger('matplotlib')
|
||||
mpl_logger.setLevel(logging.WARNING)
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
plt.plot(x)
|
||||
plt.plot(y)
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep='')
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
|
||||
def interpolate_f0(f0):
|
||||
'''
|
||||
对F0进行插值处理
|
||||
'''
|
||||
|
||||
data = np.reshape(f0, (f0.size, 1))
|
||||
|
||||
vuv_vector = np.zeros((data.size, 1), dtype=np.float32)
|
||||
vuv_vector[data > 0.0] = 1.0
|
||||
vuv_vector[data <= 0.0] = 0.0
|
||||
|
||||
ip_data = data
|
||||
|
||||
frame_number = data.size
|
||||
last_value = 0.0
|
||||
for i in range(frame_number):
|
||||
if data[i] <= 0.0:
|
||||
j = i + 1
|
||||
for j in range(i + 1, frame_number):
|
||||
if data[j] > 0.0:
|
||||
break
|
||||
if j < frame_number - 1:
|
||||
if last_value > 0.0:
|
||||
step = (data[j] - data[i - 1]) / float(j - i)
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[i - 1] + step * (k - i + 1)
|
||||
else:
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[j]
|
||||
else:
|
||||
for k in range(i, frame_number):
|
||||
ip_data[k] = last_value
|
||||
else:
|
||||
ip_data[i] = data[i]
|
||||
last_value = data[i]
|
||||
|
||||
return ip_data[:,0], vuv_vector[:,0]
|
||||
|
||||
|
||||
def compute_f0_parselmouth(wav_numpy, p_len=None, sampling_rate=44100, hop_length=512):
|
||||
import parselmouth
|
||||
x = wav_numpy
|
||||
if p_len is None:
|
||||
p_len = x.shape[0]//hop_length
|
||||
else:
|
||||
assert abs(p_len-x.shape[0]//hop_length) < 4, "pad length error"
|
||||
time_step = hop_length / sampling_rate * 1000
|
||||
f0_min = 50
|
||||
f0_max = 1100
|
||||
f0 = parselmouth.Sound(x, sampling_rate).to_pitch_ac(
|
||||
time_step=time_step / 1000, voicing_threshold=0.6,
|
||||
pitch_floor=f0_min, pitch_ceiling=f0_max).selected_array['frequency']
|
||||
|
||||
pad_size=(p_len - len(f0) + 1) // 2
|
||||
if(pad_size>0 or p_len - len(f0) - pad_size>0):
|
||||
f0 = np.pad(f0,[[pad_size,p_len - len(f0) - pad_size]], mode='constant')
|
||||
return f0
|
||||
|
||||
def resize_f0(x, target_len):
|
||||
source = np.array(x)
|
||||
source[source<0.001] = np.nan
|
||||
target = np.interp(np.arange(0, len(source)*target_len, len(source))/ target_len, np.arange(0, len(source)), source)
|
||||
res = np.nan_to_num(target)
|
||||
return res
|
||||
|
||||
def compute_f0_dio(wav_numpy, p_len=None, sampling_rate=44100, hop_length=512):
|
||||
import pyworld
|
||||
if p_len is None:
|
||||
p_len = wav_numpy.shape[0]//hop_length
|
||||
f0, t = pyworld.dio(
|
||||
wav_numpy.astype(np.double),
|
||||
fs=sampling_rate,
|
||||
f0_ceil=800,
|
||||
frame_period=1000 * hop_length / sampling_rate,
|
||||
)
|
||||
f0 = pyworld.stonemask(wav_numpy.astype(np.double), f0, t, sampling_rate)
|
||||
for index, pitch in enumerate(f0):
|
||||
f0[index] = round(pitch, 1)
|
||||
return resize_f0(f0, p_len)
|
||||
|
||||
def f0_to_coarse(f0):
|
||||
is_torch = isinstance(f0, torch.Tensor)
|
||||
f0_mel = 1127 * (1 + f0 / 700).log() if is_torch else 1127 * np.log(1 + f0 / 700)
|
||||
f0_mel[f0_mel > 0] = (f0_mel[f0_mel > 0] - f0_mel_min) * (f0_bin - 2) / (f0_mel_max - f0_mel_min) + 1
|
||||
|
||||
f0_mel[f0_mel <= 1] = 1
|
||||
f0_mel[f0_mel > f0_bin - 1] = f0_bin - 1
|
||||
f0_coarse = (f0_mel + 0.5).long() if is_torch else np.rint(f0_mel).astype(np.int)
|
||||
assert f0_coarse.max() <= 255 and f0_coarse.min() >= 1, (f0_coarse.max(), f0_coarse.min())
|
||||
return f0_coarse
|
||||
|
||||
|
||||
def get_hubert_model():
|
||||
vec_path = "hubert/checkpoint_best_legacy_500.pt"
|
||||
print("load model(s) from {}".format(vec_path))
|
||||
from fairseq import checkpoint_utils
|
||||
models, saved_cfg, task = checkpoint_utils.load_model_ensemble_and_task(
|
||||
[vec_path],
|
||||
suffix="",
|
||||
)
|
||||
model = models[0]
|
||||
model.eval()
|
||||
return model
|
||||
|
||||
def get_hubert_content(hmodel, wav_16k_tensor):
|
||||
feats = wav_16k_tensor
|
||||
if feats.dim() == 2: # double channels
|
||||
feats = feats.mean(-1)
|
||||
assert feats.dim() == 1, feats.dim()
|
||||
feats = feats.view(1, -1)
|
||||
padding_mask = torch.BoolTensor(feats.shape).fill_(False)
|
||||
inputs = {
|
||||
"source": feats.to(wav_16k_tensor.device),
|
||||
"padding_mask": padding_mask.to(wav_16k_tensor.device),
|
||||
"output_layer": 9, # layer 9
|
||||
}
|
||||
with torch.no_grad():
|
||||
logits = hmodel.extract_features(**inputs)
|
||||
feats = hmodel.final_proj(logits[0])
|
||||
return feats.transpose(1, 2)
|
||||
|
||||
|
||||
def get_content(cmodel, y):
|
||||
with torch.no_grad():
|
||||
c = cmodel.extract_features(y.squeeze(1))[0]
|
||||
c = c.transpose(1, 2)
|
||||
return c
|
||||
|
||||
|
||||
|
||||
def load_checkpoint(checkpoint_path, model, optimizer=None, skip_optimizer=False):
|
||||
assert os.path.isfile(checkpoint_path)
|
||||
checkpoint_dict = torch.load(checkpoint_path, map_location='cpu')
|
||||
iteration = checkpoint_dict['iteration']
|
||||
learning_rate = checkpoint_dict['learning_rate']
|
||||
if optimizer is not None and not skip_optimizer and checkpoint_dict['optimizer'] is not None:
|
||||
optimizer.load_state_dict(checkpoint_dict['optimizer'])
|
||||
saved_state_dict = checkpoint_dict['model']
|
||||
if hasattr(model, 'module'):
|
||||
state_dict = model.module.state_dict()
|
||||
else:
|
||||
state_dict = model.state_dict()
|
||||
new_state_dict = {}
|
||||
for k, v in state_dict.items():
|
||||
try:
|
||||
# assert "dec" in k or "disc" in k
|
||||
# print("load", k)
|
||||
new_state_dict[k] = saved_state_dict[k]
|
||||
assert saved_state_dict[k].shape == v.shape, (saved_state_dict[k].shape, v.shape)
|
||||
except:
|
||||
print("error, %s is not in the checkpoint" % k)
|
||||
logger.info("%s is not in the checkpoint" % k)
|
||||
new_state_dict[k] = v
|
||||
if hasattr(model, 'module'):
|
||||
model.module.load_state_dict(new_state_dict)
|
||||
else:
|
||||
model.load_state_dict(new_state_dict)
|
||||
print("load ")
|
||||
logger.info("Loaded checkpoint '{}' (iteration {})".format(
|
||||
checkpoint_path, iteration))
|
||||
return model, optimizer, learning_rate, iteration
|
||||
|
||||
|
||||
def save_checkpoint(model, optimizer, learning_rate, iteration, checkpoint_path):
|
||||
logger.info("Saving model and optimizer state at iteration {} to {}".format(
|
||||
iteration, checkpoint_path))
|
||||
if hasattr(model, 'module'):
|
||||
state_dict = model.module.state_dict()
|
||||
else:
|
||||
state_dict = model.state_dict()
|
||||
torch.save({'model': state_dict,
|
||||
'iteration': iteration,
|
||||
'optimizer': optimizer.state_dict(),
|
||||
'learning_rate': learning_rate}, checkpoint_path)
|
||||
|
||||
def clean_checkpoints(path_to_models='logs/44k/', n_ckpts_to_keep=2, sort_by_time=True):
|
||||
"""Freeing up space by deleting saved ckpts
|
||||
|
||||
Arguments:
|
||||
path_to_models -- Path to the model directory
|
||||
n_ckpts_to_keep -- Number of ckpts to keep, excluding G_0.pth and D_0.pth
|
||||
sort_by_time -- True -> chronologically delete ckpts
|
||||
False -> lexicographically delete ckpts
|
||||
"""
|
||||
ckpts_files = [f for f in os.listdir(path_to_models) if os.path.isfile(os.path.join(path_to_models, f))]
|
||||
name_key = (lambda _f: int(re.compile('._(\d+)\.pth').match(_f).group(1)))
|
||||
time_key = (lambda _f: os.path.getmtime(os.path.join(path_to_models, _f)))
|
||||
sort_key = time_key if sort_by_time else name_key
|
||||
x_sorted = lambda _x: sorted([f for f in ckpts_files if f.startswith(_x) and not f.endswith('_0.pth')], key=sort_key)
|
||||
to_del = [os.path.join(path_to_models, fn) for fn in
|
||||
(x_sorted('G')[:-n_ckpts_to_keep] + x_sorted('D')[:-n_ckpts_to_keep])]
|
||||
del_info = lambda fn: logger.info(f".. Free up space by deleting ckpt {fn}")
|
||||
del_routine = lambda x: [os.remove(x), del_info(x)]
|
||||
rs = [del_routine(fn) for fn in to_del]
|
||||
|
||||
def summarize(writer, global_step, scalars={}, histograms={}, images={}, audios={}, audio_sampling_rate=22050):
|
||||
for k, v in scalars.items():
|
||||
writer.add_scalar(k, v, global_step)
|
||||
for k, v in histograms.items():
|
||||
writer.add_histogram(k, v, global_step)
|
||||
for k, v in images.items():
|
||||
writer.add_image(k, v, global_step, dataformats='HWC')
|
||||
for k, v in audios.items():
|
||||
writer.add_audio(k, v, global_step, audio_sampling_rate)
|
||||
|
||||
|
||||
def latest_checkpoint_path(dir_path, regex="G_*.pth"):
|
||||
f_list = glob.glob(os.path.join(dir_path, regex))
|
||||
f_list.sort(key=lambda f: int("".join(filter(str.isdigit, f))))
|
||||
x = f_list[-1]
|
||||
print(x)
|
||||
return x
|
||||
|
||||
|
||||
def plot_spectrogram_to_numpy(spectrogram):
|
||||
global MATPLOTLIB_FLAG
|
||||
if not MATPLOTLIB_FLAG:
|
||||
import matplotlib
|
||||
matplotlib.use("Agg")
|
||||
MATPLOTLIB_FLAG = True
|
||||
mpl_logger = logging.getLogger('matplotlib')
|
||||
mpl_logger.setLevel(logging.WARNING)
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
|
||||
fig, ax = plt.subplots(figsize=(10,2))
|
||||
im = ax.imshow(spectrogram, aspect="auto", origin="lower",
|
||||
interpolation='none')
|
||||
plt.colorbar(im, ax=ax)
|
||||
plt.xlabel("Frames")
|
||||
plt.ylabel("Channels")
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep='')
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def plot_alignment_to_numpy(alignment, info=None):
|
||||
global MATPLOTLIB_FLAG
|
||||
if not MATPLOTLIB_FLAG:
|
||||
import matplotlib
|
||||
matplotlib.use("Agg")
|
||||
MATPLOTLIB_FLAG = True
|
||||
mpl_logger = logging.getLogger('matplotlib')
|
||||
mpl_logger.setLevel(logging.WARNING)
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
|
||||
fig, ax = plt.subplots(figsize=(6, 4))
|
||||
im = ax.imshow(alignment.transpose(), aspect='auto', origin='lower',
|
||||
interpolation='none')
|
||||
fig.colorbar(im, ax=ax)
|
||||
xlabel = 'Decoder timestep'
|
||||
if info is not None:
|
||||
xlabel += '\n\n' + info
|
||||
plt.xlabel(xlabel)
|
||||
plt.ylabel('Encoder timestep')
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep='')
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def load_wav_to_torch(full_path):
|
||||
sampling_rate, data = read(full_path)
|
||||
return torch.FloatTensor(data.astype(np.float32)), sampling_rate
|
||||
|
||||
|
||||
def load_filepaths_and_text(filename, split="|"):
|
||||
with open(filename, encoding='utf-8') as f:
|
||||
filepaths_and_text = [line.strip().split(split) for line in f]
|
||||
return filepaths_and_text
|
||||
|
||||
|
||||
def get_hparams(init=True):
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('-c', '--config', type=str, default="./configs/base.json",
|
||||
help='JSON file for configuration')
|
||||
parser.add_argument('-m', '--model', type=str, required=True,
|
||||
help='Model name')
|
||||
|
||||
args = parser.parse_args()
|
||||
model_dir = os.path.join("./logs", args.model)
|
||||
|
||||
if not os.path.exists(model_dir):
|
||||
os.makedirs(model_dir)
|
||||
|
||||
config_path = args.config
|
||||
config_save_path = os.path.join(model_dir, "config.json")
|
||||
if init:
|
||||
with open(config_path, "r") as f:
|
||||
data = f.read()
|
||||
with open(config_save_path, "w") as f:
|
||||
f.write(data)
|
||||
else:
|
||||
with open(config_save_path, "r") as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
|
||||
hparams = HParams(**config)
|
||||
hparams.model_dir = model_dir
|
||||
return hparams
|
||||
|
||||
|
||||
def get_hparams_from_dir(model_dir):
|
||||
config_save_path = os.path.join(model_dir, "config.json")
|
||||
with open(config_save_path, "r") as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
|
||||
hparams =HParams(**config)
|
||||
hparams.model_dir = model_dir
|
||||
return hparams
|
||||
|
||||
|
||||
def get_hparams_from_file(config_path):
|
||||
with open(config_path, "r") as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
|
||||
hparams =HParams(**config)
|
||||
return hparams
|
||||
|
||||
|
||||
def check_git_hash(model_dir):
|
||||
source_dir = os.path.dirname(os.path.realpath(__file__))
|
||||
if not os.path.exists(os.path.join(source_dir, ".git")):
|
||||
logger.warn("{} is not a git repository, therefore hash value comparison will be ignored.".format(
|
||||
source_dir
|
||||
))
|
||||
return
|
||||
|
||||
cur_hash = subprocess.getoutput("git rev-parse HEAD")
|
||||
|
||||
path = os.path.join(model_dir, "githash")
|
||||
if os.path.exists(path):
|
||||
saved_hash = open(path).read()
|
||||
if saved_hash != cur_hash:
|
||||
logger.warn("git hash values are different. {}(saved) != {}(current)".format(
|
||||
saved_hash[:8], cur_hash[:8]))
|
||||
else:
|
||||
open(path, "w").write(cur_hash)
|
||||
|
||||
|
||||
def get_logger(model_dir, filename="train.log"):
|
||||
global logger
|
||||
logger = logging.getLogger(os.path.basename(model_dir))
|
||||
logger.setLevel(logging.DEBUG)
|
||||
|
||||
formatter = logging.Formatter("%(asctime)s\t%(name)s\t%(levelname)s\t%(message)s")
|
||||
if not os.path.exists(model_dir):
|
||||
os.makedirs(model_dir)
|
||||
h = logging.FileHandler(os.path.join(model_dir, filename))
|
||||
h.setLevel(logging.DEBUG)
|
||||
h.setFormatter(formatter)
|
||||
logger.addHandler(h)
|
||||
return logger
|
||||
|
||||
|
||||
def repeat_expand_2d(content, target_len):
|
||||
# content : [h, t]
|
||||
|
||||
src_len = content.shape[-1]
|
||||
target = torch.zeros([content.shape[0], target_len], dtype=torch.float).to(content.device)
|
||||
temp = torch.arange(src_len+1) * target_len / src_len
|
||||
current_pos = 0
|
||||
for i in range(target_len):
|
||||
if i < temp[current_pos+1]:
|
||||
target[:, i] = content[:, current_pos]
|
||||
else:
|
||||
current_pos += 1
|
||||
target[:, i] = content[:, current_pos]
|
||||
|
||||
return target
|
||||
|
||||
|
||||
class HParams():
|
||||
def __init__(self, **kwargs):
|
||||
for k, v in kwargs.items():
|
||||
if type(v) == dict:
|
||||
v = HParams(**v)
|
||||
self[k] = v
|
||||
|
||||
def keys(self):
|
||||
return self.__dict__.keys()
|
||||
|
||||
def items(self):
|
||||
return self.__dict__.items()
|
||||
|
||||
def values(self):
|
||||
return self.__dict__.values()
|
||||
|
||||
def __len__(self):
|
||||
return len(self.__dict__)
|
||||
|
||||
def __getitem__(self, key):
|
||||
return getattr(self, key)
|
||||
|
||||
def __setitem__(self, key, value):
|
||||
return setattr(self, key, value)
|
||||
|
||||
def __contains__(self, key):
|
||||
return key in self.__dict__
|
||||
|
||||
def __repr__(self):
|
||||
return self.__dict__.__repr__()
|
||||
|
||||
@@ -1,111 +0,0 @@
|
||||
import math
|
||||
import os
|
||||
os.environ["LRU_CACHE_CAPACITY"] = "3"
|
||||
import random
|
||||
import torch
|
||||
import torch.utils.data
|
||||
import numpy as np
|
||||
import librosa
|
||||
from librosa.util import normalize
|
||||
from librosa.filters import mel as librosa_mel_fn
|
||||
from scipy.io.wavfile import read
|
||||
import soundfile as sf
|
||||
|
||||
def load_wav_to_torch(full_path, target_sr=None, return_empty_on_exception=False):
|
||||
sampling_rate = None
|
||||
try:
|
||||
data, sampling_rate = sf.read(full_path, always_2d=True)# than soundfile.
|
||||
except Exception as ex:
|
||||
print(f"'{full_path}' failed to load.\nException:")
|
||||
print(ex)
|
||||
if return_empty_on_exception:
|
||||
return [], sampling_rate or target_sr or 32000
|
||||
else:
|
||||
raise Exception(ex)
|
||||
|
||||
if len(data.shape) > 1:
|
||||
data = data[:, 0]
|
||||
assert len(data) > 2# check duration of audio file is > 2 samples (because otherwise the slice operation was on the wrong dimension)
|
||||
|
||||
if np.issubdtype(data.dtype, np.integer): # if audio data is type int
|
||||
max_mag = -np.iinfo(data.dtype).min # maximum magnitude = min possible value of intXX
|
||||
else: # if audio data is type fp32
|
||||
max_mag = max(np.amax(data), -np.amin(data))
|
||||
max_mag = (2**31)+1 if max_mag > (2**15) else ((2**15)+1 if max_mag > 1.01 else 1.0) # data should be either 16-bit INT, 32-bit INT or [-1 to 1] float32
|
||||
|
||||
data = torch.FloatTensor(data.astype(np.float32))/max_mag
|
||||
|
||||
if (torch.isinf(data) | torch.isnan(data)).any() and return_empty_on_exception:# resample will crash with inf/NaN inputs. return_empty_on_exception will return empty arr instead of except
|
||||
return [], sampling_rate or target_sr or 32000
|
||||
if target_sr is not None and sampling_rate != target_sr:
|
||||
data = torch.from_numpy(librosa.core.resample(data.numpy(), orig_sr=sampling_rate, target_sr=target_sr))
|
||||
sampling_rate = target_sr
|
||||
|
||||
return data, sampling_rate
|
||||
|
||||
def dynamic_range_compression(x, C=1, clip_val=1e-5):
|
||||
return np.log(np.clip(x, a_min=clip_val, a_max=None) * C)
|
||||
|
||||
def dynamic_range_decompression(x, C=1):
|
||||
return np.exp(x) / C
|
||||
|
||||
def dynamic_range_compression_torch(x, C=1, clip_val=1e-5):
|
||||
return torch.log(torch.clamp(x, min=clip_val) * C)
|
||||
|
||||
def dynamic_range_decompression_torch(x, C=1):
|
||||
return torch.exp(x) / C
|
||||
|
||||
class STFT():
|
||||
def __init__(self, sr=22050, n_mels=80, n_fft=1024, win_size=1024, hop_length=256, fmin=20, fmax=11025, clip_val=1e-5):
|
||||
self.target_sr = sr
|
||||
|
||||
self.n_mels = n_mels
|
||||
self.n_fft = n_fft
|
||||
self.win_size = win_size
|
||||
self.hop_length = hop_length
|
||||
self.fmin = fmin
|
||||
self.fmax = fmax
|
||||
self.clip_val = clip_val
|
||||
self.mel_basis = {}
|
||||
self.hann_window = {}
|
||||
|
||||
def get_mel(self, y, center=False):
|
||||
sampling_rate = self.target_sr
|
||||
n_mels = self.n_mels
|
||||
n_fft = self.n_fft
|
||||
win_size = self.win_size
|
||||
hop_length = self.hop_length
|
||||
fmin = self.fmin
|
||||
fmax = self.fmax
|
||||
clip_val = self.clip_val
|
||||
|
||||
if torch.min(y) < -1.:
|
||||
print('min value is ', torch.min(y))
|
||||
if torch.max(y) > 1.:
|
||||
print('max value is ', torch.max(y))
|
||||
|
||||
if fmax not in self.mel_basis:
|
||||
mel = librosa_mel_fn(sr=sampling_rate, n_fft=n_fft, n_mels=n_mels, fmin=fmin, fmax=fmax)
|
||||
self.mel_basis[str(fmax)+'_'+str(y.device)] = torch.from_numpy(mel).float().to(y.device)
|
||||
self.hann_window[str(y.device)] = torch.hann_window(self.win_size).to(y.device)
|
||||
|
||||
y = torch.nn.functional.pad(y.unsqueeze(1), (int((n_fft-hop_length)/2), int((n_fft-hop_length)/2)), mode='reflect')
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(y, n_fft, hop_length=hop_length, win_length=win_size, window=self.hann_window[str(y.device)],
|
||||
center=center, pad_mode='reflect', normalized=False, onesided=True)
|
||||
# print(111,spec)
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1)+(1e-9))
|
||||
# print(222,spec)
|
||||
spec = torch.matmul(self.mel_basis[str(fmax)+'_'+str(y.device)], spec)
|
||||
# print(333,spec)
|
||||
spec = dynamic_range_compression_torch(spec, clip_val=clip_val)
|
||||
# print(444,spec)
|
||||
return spec
|
||||
|
||||
def __call__(self, audiopath):
|
||||
audio, sr = load_wav_to_torch(audiopath, target_sr=self.target_sr)
|
||||
spect = self.get_mel(audio.unsqueeze(0)).squeeze(0)
|
||||
return spect
|
||||
|
||||
stft = STFT()
|
||||
Reference in New Issue
Block a user