mirror of
https://github.com/storytold/storyteller-ml.git
synced 2026-10-15 00:03:06 +00:00
so-vits-svc-paul-v2
This commit is contained in:
 Paul Sajna
@@ -0,0 +1,361 @@
|
||||
{
|
||||
"projectName": "so-vits-svc-fork",
|
||||
"projectOwner": "voicepaw",
|
||||
"repoType": "github",
|
||||
"repoHost": "https://github.com",
|
||||
"files": [
|
||||
"README.md"
|
||||
],
|
||||
"imageSize": 80,
|
||||
"commit": true,
|
||||
"commitConvention": "angular",
|
||||
"contributors": [
|
||||
{
|
||||
"login": "34j",
|
||||
"name": "34j",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/55338215?v=4",
|
||||
"profile": "https://github.com/34j",
|
||||
"contributions": [
|
||||
"code",
|
||||
"ideas",
|
||||
"doc",
|
||||
"example",
|
||||
"infra",
|
||||
"maintenance",
|
||||
"review",
|
||||
"test",
|
||||
"tutorial",
|
||||
"promotion",
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "GarrettConway",
|
||||
"name": "GarrettConway",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/22782004?v=4",
|
||||
"profile": "https://github.com/GarrettConway",
|
||||
"contributions": [
|
||||
"code",
|
||||
"bug",
|
||||
"doc",
|
||||
"review"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "BlueAmulet",
|
||||
"name": "BlueAmulet",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/43395286?v=4",
|
||||
"profile": "https://github.com/BlueAmulet",
|
||||
"contributions": [
|
||||
"ideas",
|
||||
"question",
|
||||
"code",
|
||||
"maintenance"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "ThrowawayAccount01",
|
||||
"name": "ThrowawayAccount01",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/125531852?v=4",
|
||||
"profile": "https://github.com/ThrowawayAccount01",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "MashiroSA",
|
||||
"name": "緋",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/40637516?v=4",
|
||||
"profile": "https://github.com/MashiroSA",
|
||||
"contributions": [
|
||||
"doc",
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Lordmau5",
|
||||
"name": "Lordmau5",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/1345036?v=4",
|
||||
"profile": "https://github.com/Lordmau5",
|
||||
"contributions": [
|
||||
"bug",
|
||||
"code",
|
||||
"ideas",
|
||||
"maintenance",
|
||||
"question",
|
||||
"userTesting"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "DL909",
|
||||
"name": "DL909",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/71912115?v=4",
|
||||
"profile": "https://github.com/DL909",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Satisfy256",
|
||||
"name": "Satisfy256",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/101394399?v=4",
|
||||
"profile": "https://github.com/Satisfy256",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "pierluigizagaria",
|
||||
"name": "Pierluigi Zagaria",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/57801386?v=4",
|
||||
"profile": "https://github.com/pierluigizagaria",
|
||||
"contributions": [
|
||||
"userTesting"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "ruckusmattster",
|
||||
"name": "ruckusmattster",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/77196088?v=4",
|
||||
"profile": "https://github.com/ruckusmattster",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Desuka-art",
|
||||
"name": "Desuka-art",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/111822082?v=4",
|
||||
"profile": "https://github.com/Desuka-art",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "heyfixit",
|
||||
"name": "heyfixit",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/41658450?v=4",
|
||||
"profile": "https://github.com/heyfixit",
|
||||
"contributions": [
|
||||
"doc"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "nerdyrodent",
|
||||
"name": "Nerdy Rodent",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/74688049?v=4",
|
||||
"profile": "https://www.youtube.com/c/NerdyRodent",
|
||||
"contributions": [
|
||||
"video"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "xieyumc",
|
||||
"name": "谢宇",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/47858007?v=4",
|
||||
"profile": "https://github.com/xieyumc",
|
||||
"contributions": [
|
||||
"doc"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "ColdCawfee",
|
||||
"name": "ColdCawfee",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/79474598?v=4",
|
||||
"profile": "https://github.com/ColdCawfee",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "sbersier",
|
||||
"name": "sbersier",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/34165937?v=4",
|
||||
"profile": "https://github.com/sbersier",
|
||||
"contributions": [
|
||||
"ideas",
|
||||
"userTesting",
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Meldoner",
|
||||
"name": "Meldoner",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/43951115?v=4",
|
||||
"profile": "https://github.com/Meldoner",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "mmodeusher",
|
||||
"name": "mmodeusher",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/46575920?v=4",
|
||||
"profile": "https://github.com/mmodeusher",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "AlonDan",
|
||||
"name": "AlonDan",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/21152334?v=4",
|
||||
"profile": "https://github.com/AlonDan",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Likkkez",
|
||||
"name": "Likkkez",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/44336181?v=4",
|
||||
"profile": "https://github.com/Likkkez",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "DuctTapeGames",
|
||||
"name": "Duct Tape Games",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/84365142?v=4",
|
||||
"profile": "https://github.com/DuctTapeGames",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "hxl9654",
|
||||
"name": "Xianglong He",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/6624983?v=4",
|
||||
"profile": "https://tec.hxlxz.com/",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "75aosu",
|
||||
"name": "75aosu",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/79185331?v=4",
|
||||
"profile": "https://github.com/75aosu",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "tonyco82",
|
||||
"name": "tonyco82",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/56610534?v=4",
|
||||
"profile": "https://github.com/tonyco82",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "yxlllc",
|
||||
"name": "yxlllc",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/33565655?v=4",
|
||||
"profile": "https://github.com/yxlllc",
|
||||
"contributions": [
|
||||
"ideas",
|
||||
"code"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "outhipped",
|
||||
"name": "outhipped",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/116147475?v=4",
|
||||
"profile": "https://github.com/outhipped",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "escoolioinglesias",
|
||||
"name": "escoolioinglesias",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/73505402?v=4",
|
||||
"profile": "https://github.com/escoolioinglesias",
|
||||
"contributions": [
|
||||
"bug",
|
||||
"userTesting",
|
||||
"video"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Blacksingh",
|
||||
"name": "Blacksingh",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/130872856?v=4",
|
||||
"profile": "https://github.com/Blacksingh",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "tybantarnusa",
|
||||
"name": "Mgs. M. Thoyib Antarnusa",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/9532857?v=4",
|
||||
"profile": "http://tybantarnusa.com",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "ZeroHackz",
|
||||
"name": "Exosfeer",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/15729496?v=4",
|
||||
"profile": "https://github.com/ZeroHackz",
|
||||
"contributions": [
|
||||
"bug",
|
||||
"code"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "guranon",
|
||||
"name": "guranon",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/130421189?v=4",
|
||||
"profile": "https://github.com/guranon",
|
||||
"contributions": [
|
||||
"bug",
|
||||
"ideas",
|
||||
"code"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "alexanderkoumis",
|
||||
"name": "Alexander Koumis",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/5108856?v=4",
|
||||
"profile": "https://github.com/alexanderkoumis",
|
||||
"contributions": [
|
||||
"code"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "acekagami",
|
||||
"name": "acekagami",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/127201056?v=4",
|
||||
"profile": "https://github.com/acekagami",
|
||||
"contributions": [
|
||||
"translation"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Highupech",
|
||||
"name": "Highupech",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/114140670?v=4",
|
||||
"profile": "https://github.com/Highupech",
|
||||
"contributions": [
|
||||
"bug"
|
||||
]
|
||||
},
|
||||
{
|
||||
"login": "Scorpi",
|
||||
"name": "Scorpi",
|
||||
"avatar_url": "https://avatars.githubusercontent.com/u/969654?v=4",
|
||||
"profile": "https://github.com/Scorpi",
|
||||
"contributions": [
|
||||
"code"
|
||||
]
|
||||
}
|
||||
],
|
||||
"contributorsPerLine": 7,
|
||||
"skipCi": true
|
||||
}
|
||||
@@ -0,0 +1,21 @@
|
||||
# http://editorconfig.org
|
||||
|
||||
root = true
|
||||
|
||||
[*]
|
||||
indent_style = space
|
||||
indent_size = 4
|
||||
trim_trailing_whitespace = true
|
||||
insert_final_newline = true
|
||||
charset = utf-8
|
||||
end_of_line = lf
|
||||
|
||||
[*.bat]
|
||||
indent_style = tab
|
||||
end_of_line = crlf
|
||||
|
||||
[LICENSE]
|
||||
insert_final_newline = false
|
||||
|
||||
[Makefile]
|
||||
indent_style = tab
|
||||
@@ -0,0 +1,4 @@
|
||||
[flake8]
|
||||
exclude = docs
|
||||
max-line-length = 88
|
||||
ignore = E203, E501, E741, E402, E712, W503, E731, E711
|
||||
@@ -0,0 +1,158 @@
|
||||
# Created by .ignore support plugin (hsz.mobi)
|
||||
### Python template
|
||||
# Byte-compiled / optimized / DLL files
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
|
||||
# C extensions
|
||||
*.so
|
||||
|
||||
# Distribution / packaging
|
||||
.Python
|
||||
build/
|
||||
develop-eggs/
|
||||
dist/
|
||||
downloads/
|
||||
eggs/
|
||||
.eggs/
|
||||
lib/
|
||||
lib64/
|
||||
parts/
|
||||
sdist/
|
||||
var/
|
||||
wheels/
|
||||
share/python-wheels/
|
||||
*.egg-info/
|
||||
.installed.cfg
|
||||
*.egg
|
||||
MANIFEST
|
||||
|
||||
# PyInstaller
|
||||
# Usually these files are written by a python script from a template
|
||||
# before PyInstaller builds the exe, so as to inject date/other infos into it.
|
||||
*.manifest
|
||||
*.spec
|
||||
|
||||
# Installer logs
|
||||
pip-log.txt
|
||||
pip-delete-this-directory.txt
|
||||
|
||||
# Unit test / coverage reports
|
||||
htmlcov/
|
||||
.tox/
|
||||
.nox/
|
||||
.coverage
|
||||
.coverage.*
|
||||
.cache
|
||||
nosetests.xml
|
||||
coverage.xml
|
||||
*.cover
|
||||
*.py,cover
|
||||
.hypothesis/
|
||||
.pytest_cache/
|
||||
cover/
|
||||
|
||||
# Translations
|
||||
*.mo
|
||||
*.pot
|
||||
|
||||
# Django stuff:
|
||||
*.log
|
||||
local_settings.py
|
||||
db.sqlite3
|
||||
db.sqlite3-journal
|
||||
|
||||
# Flask stuff:
|
||||
instance/
|
||||
.webassets-cache
|
||||
|
||||
# Scrapy stuff:
|
||||
.scrapy
|
||||
|
||||
# Sphinx documentation
|
||||
docs/_build/
|
||||
|
||||
# PyBuilder
|
||||
.pybuilder/
|
||||
target/
|
||||
|
||||
# Jupyter Notebook
|
||||
.ipynb_checkpoints
|
||||
|
||||
# IPython
|
||||
profile_default/
|
||||
ipython_config.py
|
||||
|
||||
# pyenv
|
||||
# For a library or package, you might want to ignore these files since the code is
|
||||
# intended to run in multiple environments; otherwise, check them in:
|
||||
# .python-version
|
||||
|
||||
# pipenv
|
||||
# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
|
||||
# However, in case of collaboration, if having platform-specific dependencies or dependencies
|
||||
# having no cross-platform support, pipenv may install dependencies that don't work, or not
|
||||
# install all needed dependencies.
|
||||
#Pipfile.lock
|
||||
|
||||
# PEP 582; used by e.g. github.com/David-OConnor/pyflow
|
||||
__pypackages__/
|
||||
|
||||
# Celery stuff
|
||||
celerybeat-schedule
|
||||
celerybeat.pid
|
||||
|
||||
# SageMath parsed files
|
||||
*.sage.py
|
||||
|
||||
# Environments
|
||||
.env
|
||||
.venv
|
||||
env/
|
||||
venv/
|
||||
ENV/
|
||||
env.bak/
|
||||
venv.bak/
|
||||
|
||||
# Spyder {{package_name}} settings
|
||||
.spyderproject
|
||||
.spyproject
|
||||
|
||||
# Rope {{package_name}} settings
|
||||
.ropeproject
|
||||
|
||||
# mkdocs documentation
|
||||
/site
|
||||
|
||||
# mypy
|
||||
.mypy_cache/
|
||||
.dmypy.json
|
||||
dmypy.json
|
||||
|
||||
# Pyre type checker
|
||||
.pyre/
|
||||
|
||||
# pytype static type analyzer
|
||||
.pytype/
|
||||
|
||||
# Cython debug symbols
|
||||
cython_debug/
|
||||
|
||||
# additional files
|
||||
tests/**/*.wav
|
||||
!tests/dataset_raw/test/**/*.wav
|
||||
tests/**/*.npy
|
||||
tests/**/*.pt
|
||||
tests/**/*.txt
|
||||
tests/**/*.json
|
||||
tests/**/*.pth
|
||||
tests/**/*.download
|
||||
tests/**/*.lab
|
||||
tests/**/*.pdf
|
||||
tests/**/*.csv
|
||||
tests/**/*.ckpt
|
||||
tests/**/*.yaml
|
||||
*.tfevents.*
|
||||
*.pt
|
||||
user_gui_presets.json
|
||||
@@ -0,0 +1,8 @@
|
||||
tasks:
|
||||
- command: |
|
||||
pip install poetry
|
||||
PIP_USER=false poetry install
|
||||
- command: |
|
||||
pip install pre-commit
|
||||
pre-commit install
|
||||
PIP_USER=false pre-commit install-hooks
|
||||
@@ -0,0 +1,78 @@
|
||||
# See https://pre-commit.com for more information
|
||||
# See https://pre-commit.com/hooks.html for more hooks
|
||||
exclude: "CHANGELOG.md|.copier-answers.yml"
|
||||
default_stages: [commit]
|
||||
|
||||
ci:
|
||||
autofix_commit_msg: "chore(pre-commit.ci): auto fixes"
|
||||
autoupdate_commit_msg: "chore(pre-commit.ci): pre-commit autoupdate"
|
||||
|
||||
repos:
|
||||
- repo: https://github.com/commitizen-tools/commitizen
|
||||
rev: v2.42.1
|
||||
hooks:
|
||||
- id: commitizen
|
||||
stages: [commit-msg]
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
rev: v4.4.0
|
||||
hooks:
|
||||
- id: debug-statements
|
||||
- id: check-builtin-literals
|
||||
- id: check-case-conflict
|
||||
- id: check-docstring-first
|
||||
- id: check-json
|
||||
- id: check-toml
|
||||
- id: check-xml
|
||||
- id: check-yaml
|
||||
- id: detect-private-key
|
||||
- id: end-of-file-fixer
|
||||
- id: trailing-whitespace
|
||||
- repo: https://github.com/python-poetry/poetry
|
||||
rev: 1.4.2
|
||||
hooks:
|
||||
- id: poetry-check
|
||||
- repo: https://github.com/pre-commit/mirrors-prettier
|
||||
rev: v2.7.1
|
||||
hooks:
|
||||
- id: prettier
|
||||
args: ["--tab-width", "2"]
|
||||
- repo: https://github.com/asottile/pyupgrade
|
||||
rev: v3.3.2
|
||||
hooks:
|
||||
- id: pyupgrade
|
||||
args: [--py38-plus]
|
||||
- repo: https://github.com/PyCQA/autoflake
|
||||
rev: v2.1.1
|
||||
hooks:
|
||||
- id: autoflake
|
||||
- repo: https://github.com/PyCQA/isort
|
||||
rev: 5.12.0
|
||||
hooks:
|
||||
- id: isort
|
||||
- repo: https://github.com/psf/black
|
||||
rev: 23.3.0
|
||||
hooks:
|
||||
- id: black
|
||||
- repo: https://github.com/codespell-project/codespell
|
||||
rev: v2.2.4
|
||||
hooks:
|
||||
- id: codespell
|
||||
args: [-w]
|
||||
- repo: https://github.com/PyCQA/flake8
|
||||
rev: 6.0.0
|
||||
hooks:
|
||||
- id: flake8
|
||||
#- repo: https://github.com/pre-commit/mirrors-mypy
|
||||
# rev: v0.931
|
||||
# hooks:
|
||||
# - id: mypy
|
||||
# additional_dependencies: []
|
||||
# - repo: https://github.com/PyCQA/bandit
|
||||
# rev: 1.7.4
|
||||
# hooks:
|
||||
# - id: bandit
|
||||
# args: [-x, tests]
|
||||
- repo: https://github.com/srstevenson/nb-clean
|
||||
rev: "2.4.0"
|
||||
hooks:
|
||||
- id: nb-clean
|
||||
@@ -0,0 +1,24 @@
|
||||
# Read the Docs configuration file
|
||||
# See https://docs.readthedocs.io/en/stable/config-file/v2.html for details
|
||||
|
||||
# Required
|
||||
version: 2
|
||||
|
||||
# Set the version of Python and other tools you might need
|
||||
build:
|
||||
os: ubuntu-20.04
|
||||
tools:
|
||||
python: "3.9"
|
||||
jobs:
|
||||
post_create_environment:
|
||||
# Install poetry
|
||||
- pip install poetry
|
||||
# Tell poetry to not use a virtual environment
|
||||
- poetry config virtualenvs.create false
|
||||
post_install:
|
||||
# Install dependencies
|
||||
- poetry install --with docs
|
||||
|
||||
# Build documentation in the docs directory with Sphinx
|
||||
sphinx:
|
||||
configuration: docs/conf.py
|
||||
@@ -0,0 +1,552 @@
|
||||
# Changelog
|
||||
|
||||
<!--next-version-placeholder-->
|
||||
|
||||
## v3.12.1 (2023-04-30)
|
||||
### Fix
|
||||
* **utils:** Fix epoch variable name to log in checkpoint save/load functions ([#519](https://github.com/voicepaw/so-vits-svc-fork/issues/519)) ([`0530ea3`](https://github.com/voicepaw/so-vits-svc-fork/commit/0530ea34fa42d9af51c73872b02d6453427c5a00))
|
||||
|
||||
### Documentation
|
||||
* Add Scorpi as a contributor for code ([#532](https://github.com/voicepaw/so-vits-svc-fork/issues/532)) ([`542d3a8`](https://github.com/voicepaw/so-vits-svc-fork/commit/542d3a8382d97064f13c1dcc4ba11107614dec3f))
|
||||
|
||||
## v3.12.0 (2023-04-30)
|
||||
### Feature
|
||||
* **preprocessing:** Add pre-classify command to manually classify files ([#527](https://github.com/voicepaw/so-vits-svc-fork/issues/527)) ([`7a0319c`](https://github.com/voicepaw/so-vits-svc-fork/commit/7a0319c65f42b0cc54d1d86ae5945d4a356b507a))
|
||||
|
||||
## v3.11.2 (2023-04-30)
|
||||
### Fix
|
||||
* **train:** Decouple lf0 predictor from speaker embeddings ([#528](https://github.com/voicepaw/so-vits-svc-fork/issues/528)) ([`7ab47f4`](https://github.com/voicepaw/so-vits-svc-fork/commit/7ab47f44e2ec77aa8c9e36b2e322d2dca0f94fb0))
|
||||
|
||||
## v3.11.1 (2023-04-30)
|
||||
### Fix
|
||||
* Specify encoding to utf-8 in read_text() and write_text() ([#524](https://github.com/voicepaw/so-vits-svc-fork/issues/524)) ([`e947336`](https://github.com/voicepaw/so-vits-svc-fork/commit/e94733678955430f4e0c8ee5a26627077c0ffad9))
|
||||
|
||||
### Documentation
|
||||
* Add Highupech as a contributor for bug ([#526](https://github.com/voicepaw/so-vits-svc-fork/issues/526)) ([`8eedc24`](https://github.com/voicepaw/so-vits-svc-fork/commit/8eedc2439b6987f70c94033c3f375ea330498a64))
|
||||
* **readme:** Fix typo in README.md ([`1773940`](https://github.com/voicepaw/so-vits-svc-fork/commit/1773940ae4a17a522ebc9fe6c1c70c3e02728341))
|
||||
* Add acekagami as a contributor for translation ([#486](https://github.com/voicepaw/so-vits-svc-fork/issues/486)) ([`958b9fd`](https://github.com/voicepaw/so-vits-svc-fork/commit/958b9fdf5fd1d527b63ac488ad21db2ce90539aa))
|
||||
* **readme_zh_cn:** Update README_zh_CN.md ([#477](https://github.com/voicepaw/so-vits-svc-fork/issues/477)) ([`1ccd594`](https://github.com/voicepaw/so-vits-svc-fork/commit/1ccd5941e5f17a273dad681301a287aafb7973d9))
|
||||
|
||||
## v3.11.0 (2023-04-23)
|
||||
### Feature
|
||||
* **gui:** Configurable output file (#452) ([#453](https://github.com/voicepaw/so-vits-svc-fork/issues/453)) ([`d2e3596`](https://github.com/voicepaw/so-vits-svc-fork/commit/d2e3596d5c0874918712488765e068f4010d62b9))
|
||||
|
||||
### Documentation
|
||||
* Add alexanderkoumis as a contributor for code ([#468](https://github.com/voicepaw/so-vits-svc-fork/issues/468)) ([`5e032a3`](https://github.com/voicepaw/so-vits-svc-fork/commit/5e032a3e1eb36b0a7f99fd440b3e2a82f2345747))
|
||||
|
||||
## v3.10.5 (2023-04-22)
|
||||
### Fix
|
||||
* **utils:** Fix so-vits-svc style contentvec usage ([#455](https://github.com/voicepaw/so-vits-svc-fork/issues/455)) ([`6d35139`](https://github.com/voicepaw/so-vits-svc-fork/commit/6d351390354b17a2cd004bc9572d7dc1202f236c))
|
||||
|
||||
## v3.10.4 (2023-04-21)
|
||||
### Fix
|
||||
* **train:** Only save checkpoints on main device ([`1aaaac6`](https://github.com/voicepaw/so-vits-svc-fork/commit/1aaaac6328476249371799b92ced3edcbaac8d18))
|
||||
|
||||
### Documentation
|
||||
* Add sbersier as a contributor for bug ([#437](https://github.com/voicepaw/so-vits-svc-fork/issues/437)) ([`58b936d`](https://github.com/voicepaw/so-vits-svc-fork/commit/58b936d669fbf5156f1ae1381393762994dd7414))
|
||||
* Add escoolioinglesias as a contributor for video ([#436](https://github.com/voicepaw/so-vits-svc-fork/issues/436)) ([`69f097f`](https://github.com/voicepaw/so-vits-svc-fork/commit/69f097f388447d64b7807cf554a5c310c34b7ef0))
|
||||
* Add GarrettConway as a contributor for review ([#435](https://github.com/voicepaw/so-vits-svc-fork/issues/435)) ([`c1e4ada`](https://github.com/voicepaw/so-vits-svc-fork/commit/c1e4ada97739bf0b360295335475fef7029fbe49))
|
||||
* Add BlueAmulet as a contributor for maintenance ([#434](https://github.com/voicepaw/so-vits-svc-fork/issues/434)) ([`514ed84`](https://github.com/voicepaw/so-vits-svc-fork/commit/514ed84ffda901243c1bd6f39677eb020257f11f))
|
||||
* Add guranon as a contributor for bug, ideas, and code ([#433](https://github.com/voicepaw/so-vits-svc-fork/issues/433)) ([`b9eb3fd`](https://github.com/voicepaw/so-vits-svc-fork/commit/b9eb3fdc350588b9528a74d5b7be8e80b2bfbd51))
|
||||
* Add ZeroHackz as a contributor for bug, and code ([#432](https://github.com/voicepaw/so-vits-svc-fork/issues/432)) ([`66d5adc`](https://github.com/voicepaw/so-vits-svc-fork/commit/66d5adcf6dbb60fd6b6800162e3e16570a8dac1c))
|
||||
* Add tybantarnusa as a contributor for bug ([#431](https://github.com/voicepaw/so-vits-svc-fork/issues/431)) ([`e6e57b3`](https://github.com/voicepaw/so-vits-svc-fork/commit/e6e57b3e0d97ac91cadde45d5f080ced873df959))
|
||||
* Add Blacksingh as a contributor for bug ([#430](https://github.com/voicepaw/so-vits-svc-fork/issues/430)) ([`7bc76ba`](https://github.com/voicepaw/so-vits-svc-fork/commit/7bc76ba9355089ab94fce9231f5dbbdd54e849ee))
|
||||
* Add escoolioinglesias as a contributor for bug, and userTesting ([#429](https://github.com/voicepaw/so-vits-svc-fork/issues/429)) ([`f00fe6e`](https://github.com/voicepaw/so-vits-svc-fork/commit/f00fe6e15cd12085cd01ae3c2676c195e7924429))
|
||||
* Add outhipped as a contributor for bug ([#428](https://github.com/voicepaw/so-vits-svc-fork/issues/428)) ([`7497175`](https://github.com/voicepaw/so-vits-svc-fork/commit/74971752821a852154bbfc35c318bb05e7b1169c))
|
||||
* Add yxlllc as a contributor for ideas, and code ([#427](https://github.com/voicepaw/so-vits-svc-fork/issues/427)) ([`42e35d2`](https://github.com/voicepaw/so-vits-svc-fork/commit/42e35d2a1f83be25e3fb0318e694163b0e936c59))
|
||||
* Add Lordmau5 as a contributor for ideas, maintenance, and 2 more ([#426](https://github.com/voicepaw/so-vits-svc-fork/issues/426)) ([`352451c`](https://github.com/voicepaw/so-vits-svc-fork/commit/352451ccc9c1e1f800dc7697d5c705c0b9707c96))
|
||||
* Add tonyco82 as a contributor for bug ([#425](https://github.com/voicepaw/so-vits-svc-fork/issues/425)) ([`036ce90`](https://github.com/voicepaw/so-vits-svc-fork/commit/036ce9052f145cf047434d472f775b563e503946))
|
||||
* Add 75aosu as a contributor for bug ([#424](https://github.com/voicepaw/so-vits-svc-fork/issues/424)) ([`5afc28b`](https://github.com/voicepaw/so-vits-svc-fork/commit/5afc28bf918e1a62343f445a72487c1d932dc7b4))
|
||||
* Add hxl9654 as a contributor for bug ([#423](https://github.com/voicepaw/so-vits-svc-fork/issues/423)) ([`0953f1f`](https://github.com/voicepaw/so-vits-svc-fork/commit/0953f1fd0dfbfa557f639eb8d917805f8891d7b0))
|
||||
* Add DuctTapeGames as a contributor for bug ([#422](https://github.com/voicepaw/so-vits-svc-fork/issues/422)) ([`b0f4d39`](https://github.com/voicepaw/so-vits-svc-fork/commit/b0f4d39371ed2913ad792a46754469eb68c8c72d))
|
||||
* Add Likkkez as a contributor for bug ([#421](https://github.com/voicepaw/so-vits-svc-fork/issues/421)) ([`4a12109`](https://github.com/voicepaw/so-vits-svc-fork/commit/4a12109b6a0b3cd2741f10d6e9027204603b0f27))
|
||||
* Add AlonDan as a contributor for bug ([#420](https://github.com/voicepaw/so-vits-svc-fork/issues/420)) ([`662ec4b`](https://github.com/voicepaw/so-vits-svc-fork/commit/662ec4b39816b1a1311d56e3edaca31fb442bb8d))
|
||||
* Add mmodeusher as a contributor for bug ([#419](https://github.com/voicepaw/so-vits-svc-fork/issues/419)) ([`6a78df9`](https://github.com/voicepaw/so-vits-svc-fork/commit/6a78df97d8191b62a04c9ec48b74cf1f00e47c30))
|
||||
* Add Meldoner as a contributor for bug ([#418](https://github.com/voicepaw/so-vits-svc-fork/issues/418)) ([`5586bec`](https://github.com/voicepaw/so-vits-svc-fork/commit/5586becd35b456523cec1e1aa8c601cd1039dd1c))
|
||||
|
||||
## v3.10.3 (2023-04-19)
|
||||
### Fix
|
||||
* **train:** Don't save model when tuning for auto batch size ([`2311a35`](https://github.com/voicepaw/so-vits-svc-fork/commit/2311a35c36315123c87b7f20dde3c4dda723bea3))
|
||||
|
||||
## v3.10.2 (2023-04-19)
|
||||
### Fix
|
||||
* **train:** Properly stop training after `epochs` has been reached ([`f9bb3d8`](https://github.com/voicepaw/so-vits-svc-fork/commit/f9bb3d86605321288f11387bc853143378c3284e))
|
||||
|
||||
## v3.10.1 (2023-04-19)
|
||||
### Fix
|
||||
* **train:** Support ddp in Windows (gloo backend) ([#394](https://github.com/34j/so-vits-svc-fork/issues/394)) ([`bcb0507`](https://github.com/34j/so-vits-svc-fork/commit/bcb05078d8ca7a6ac681de919552b3a190b2cd9b))
|
||||
|
||||
## v3.10.0 (2023-04-18)
|
||||
### Feature
|
||||
* Replace `fairseq` with `transformers` ([#385](https://github.com/34j/so-vits-svc-fork/issues/385)) ([`a2fe0f3`](https://github.com/34j/so-vits-svc-fork/commit/a2fe0f376d33f02987c91a57bd90a794de90a0e1))
|
||||
|
||||
## v3.9.5 (2023-04-18)
|
||||
### Fix
|
||||
* **train:** Set persistent_workers = True in DataLoader for performance, do not save checkpoints, fix logging issue and multiple warning issues, do not do validation when global_step == 0 ([#384](https://github.com/34j/so-vits-svc-fork/issues/384)) ([`6cab9af`](https://github.com/34j/so-vits-svc-fork/commit/6cab9af86e3a96e79243fa890eb1c6c51fae4476))
|
||||
|
||||
## v3.9.4 (2023-04-18)
|
||||
### Fix
|
||||
* **gui:** Always use "spawn" context in ProcessPool ([#383](https://github.com/34j/so-vits-svc-fork/issues/383)) ([`5d7fb77`](https://github.com/34j/so-vits-svc-fork/commit/5d7fb774e8d5e97a9a31dbc891892e9f934f3884))
|
||||
|
||||
## v3.9.3 (2023-04-16)
|
||||
### Fix
|
||||
* **gui:** Fix subprocess errors in linux and fix wrong error logging ([#358](https://github.com/34j/so-vits-svc-fork/issues/358)) ([`fd67db6`](https://github.com/34j/so-vits-svc-fork/commit/fd67db6312944557c09afd7b1ccbb97987a03489))
|
||||
|
||||
## v3.9.2 (2023-04-16)
|
||||
### Fix
|
||||
* **train:** Fix y_mel length ([#356](https://github.com/34j/so-vits-svc-fork/issues/356)) ([`2d71992`](https://github.com/34j/so-vits-svc-fork/commit/2d71992d80ba4142d2d5a5df17c69c2f2ac553fd))
|
||||
|
||||
## v3.9.1 (2023-04-16)
|
||||
### Fix
|
||||
* **train:** Allow higher segment size ([#351](https://github.com/34j/so-vits-svc-fork/issues/351)) ([`09d5a52`](https://github.com/34j/so-vits-svc-fork/commit/09d5a52b9bfc8eba8857f2b6c804ecdb39b4b38b))
|
||||
* **cluster:** Do not use weights_only in get_cluster_model() ([#354](https://github.com/34j/so-vits-svc-fork/issues/354)) ([`24c05d1`](https://github.com/34j/so-vits-svc-fork/commit/24c05d16c3b55f664699400496a7e0fd2fd84353))
|
||||
|
||||
## v3.9.0 (2023-04-16)
|
||||
### Feature
|
||||
* **train:** Add option to name ckpts by epochs ([#353](https://github.com/34j/so-vits-svc-fork/issues/353)) ([`bba24c4`](https://github.com/34j/so-vits-svc-fork/commit/bba24c4a62b935ed29572aa2c2c437d1b54aa2e2))
|
||||
|
||||
## v3.8.1 (2023-04-16)
|
||||
### Fix
|
||||
* Patch stft and add mps to get_optimal_device() ([#352](https://github.com/34j/so-vits-svc-fork/issues/352)) ([`da928aa`](https://github.com/34j/so-vits-svc-fork/commit/da928aa0bb1399bf5780526f8a7e9b674476a000))
|
||||
|
||||
## v3.8.0 (2023-04-15)
|
||||
### Feature
|
||||
* **train:** Automatically decide batch_size ([#342](https://github.com/34j/so-vits-svc-fork/issues/342)) ([`8ffa128`](https://github.com/34j/so-vits-svc-fork/commit/8ffa128aa209787fde8fb1f0e4ae5c96dfe31217))
|
||||
|
||||
## v3.7.3 (2023-04-15)
|
||||
### Fix
|
||||
* **gui:** Show errors raised in inference ([#341](https://github.com/34j/so-vits-svc-fork/issues/341)) ([`99833c5`](https://github.com/34j/so-vits-svc-fork/commit/99833c55045647b9a766042765b454cb3d7d18ce))
|
||||
|
||||
## v3.7.2 (2023-04-15)
|
||||
### Fix
|
||||
* **train:** Suppress pytorch logs for deprecated TypedStorage ([#336](https://github.com/34j/so-vits-svc-fork/issues/336)) ([`e67ac62`](https://github.com/34j/so-vits-svc-fork/commit/e67ac621296cf6667d05b51f23ce8cb9ef8a0855))
|
||||
|
||||
## v3.7.1 (2023-04-15)
|
||||
### Fix
|
||||
* **train:** Fix check for notebook / Colab ([#335](https://github.com/34j/so-vits-svc-fork/issues/335)) ([`7f69814`](https://github.com/34j/so-vits-svc-fork/commit/7f698141e1b65e901579a5dbbabf28bfae5cc91f))
|
||||
|
||||
## v3.7.0 (2023-04-14)
|
||||
### Feature
|
||||
* **train:** Add option to specify TensorBoardLogger version parameter support ([#331](https://github.com/34j/so-vits-svc-fork/issues/331)) ([`a685123`](https://github.com/34j/so-vits-svc-fork/commit/a685123a4063e08e0b021a1ad51098d3154b75de))
|
||||
|
||||
## v3.6.2 (2023-04-14)
|
||||
### Fix
|
||||
* Fix torch.load and save to use file objects and weights_only and remove unidecode ([#327](https://github.com/34j/so-vits-svc-fork/issues/327)) ([`4aad701`](https://github.com/34j/so-vits-svc-fork/commit/4aad701badc1eae5195e874dec40f9ed8dd40ee6))
|
||||
|
||||
## v3.6.1 (2023-04-14)
|
||||
### Fix
|
||||
* **train:** Fix gradient logging ([#320](https://github.com/34j/so-vits-svc-fork/issues/320)) ([`73ef3dc`](https://github.com/34j/so-vits-svc-fork/commit/73ef3dc94ccd4c0514ab33b0c5a65edf8b356484))
|
||||
|
||||
## v3.6.0 (2023-04-13)
|
||||
### Feature
|
||||
* **realtime:** Support sola algorithm ([#316](https://github.com/34j/so-vits-svc-fork/issues/316)) ([`0fcbf99`](https://github.com/34j/so-vits-svc-fork/commit/0fcbf9979862e945ca2427612a92549db2d627d0))
|
||||
|
||||
## v3.5.1 (2023-04-13)
|
||||
### Fix
|
||||
* **logger:** Do not use rich in notebook ([#317](https://github.com/34j/so-vits-svc-fork/issues/317)) ([`03c8240`](https://github.com/34j/so-vits-svc-fork/commit/03c824015872e3d7e4e5795b9d65fad4116d54e4))
|
||||
|
||||
## v3.5.0 (2023-04-13)
|
||||
### Feature
|
||||
* **gui:** Run inference in thread and disable button ([#279](https://github.com/34j/so-vits-svc-fork/issues/279)) ([`c55caa8`](https://github.com/34j/so-vits-svc-fork/commit/c55caa8019cc06fc6bd8851b0fd895b73cf926a4))
|
||||
|
||||
## v3.4.0 (2023-04-13)
|
||||
### Feature
|
||||
* **train:** Make num_workers configurable ([#315](https://github.com/34j/so-vits-svc-fork/issues/315)) ([`e8df714`](https://github.com/34j/so-vits-svc-fork/commit/e8df7146b0d1d3ee32af576c251f47d8fdd80bb3))
|
||||
|
||||
## v3.3.1 (2023-04-13)
|
||||
### Performance
|
||||
* **train:** Specify num_workers in DataLoader ([#313](https://github.com/34j/so-vits-svc-fork/issues/313)) ([`6042164`](https://github.com/34j/so-vits-svc-fork/commit/6042164a60f9990eb0636e37dd650bb0cdff032b))
|
||||
|
||||
## v3.3.0 (2023-04-13)
|
||||
### Feature
|
||||
* **train:** Use RichProgressBar ([#311](https://github.com/34j/so-vits-svc-fork/issues/311)) ([`17e937a`](https://github.com/34j/so-vits-svc-fork/commit/17e937aae9c90b513e4b7674f442a60161c84e83))
|
||||
|
||||
## v3.2.0 (2023-04-13)
|
||||
### Feature
|
||||
* **train:** Add optional `accumulate_grad_batches` config param ([#306](https://github.com/34j/so-vits-svc-fork/issues/306)) ([`1172b23`](https://github.com/34j/so-vits-svc-fork/commit/1172b2385cfe5239da3222cf93916436395e0f1a))
|
||||
|
||||
## v3.1.13 (2023-04-12)
|
||||
### Fix
|
||||
* **logger:** Fix too noisy logger ([#300](https://github.com/34j/so-vits-svc-fork/issues/300)) ([`bd0eb33`](https://github.com/34j/so-vits-svc-fork/commit/bd0eb33a66d77afff8328d08008f2643651c712a))
|
||||
* **__main__:** Fix cli() not called in __main__ ([#299](https://github.com/34j/so-vits-svc-fork/issues/299)) ([`11f2d24`](https://github.com/34j/so-vits-svc-fork/commit/11f2d245137da240f5e8214e4b6ce4330d726143))
|
||||
|
||||
## v3.1.12 (2023-04-12)
|
||||
### Fix
|
||||
* **train:** Fix ddp not working ([#297](https://github.com/34j/so-vits-svc-fork/issues/297)) ([`bec43fc`](https://github.com/34j/so-vits-svc-fork/commit/bec43fcbedf6b16260411655b19cf780ddbafe8e))
|
||||
|
||||
## v3.1.11 (2023-04-12)
|
||||
### Fix
|
||||
* **logger:** Fix init_logger not showing debug messages in certain conditions as intended ([#296](https://github.com/34j/so-vits-svc-fork/issues/296)) ([`d3ab7d6`](https://github.com/34j/so-vits-svc-fork/commit/d3ab7d667c391ba1d8d1b34e2b66992256b3989d))
|
||||
|
||||
## v3.1.10 (2023-04-11)
|
||||
### Fix
|
||||
* **notebooks:** Improves inference ([#286](https://github.com/34j/so-vits-svc-fork/issues/286)) ([`d3228df`](https://github.com/34j/so-vits-svc-fork/commit/d3228df704b2e6a0746b3f842ca5f2240890d829))
|
||||
* **train:** Step lr schedulers at end of epoch ([#291](https://github.com/34j/so-vits-svc-fork/issues/291)) ([`3af223e`](https://github.com/34j/so-vits-svc-fork/commit/3af223eeb5146abcbb8198d4c11e2c1895ece130))
|
||||
|
||||
## v3.1.9 (2023-04-10)
|
||||
### Fix
|
||||
* **train:** Fix fp16_run not being mix precision and fix bf16 errors ([#283](https://github.com/34j/so-vits-svc-fork/issues/283)) ([`b0dd0ed`](https://github.com/34j/so-vits-svc-fork/commit/b0dd0ed4014d32e9f19e335ec603bdab92c52039))
|
||||
|
||||
## v3.1.8 (2023-04-10)
|
||||
### Fix
|
||||
* **readme:** Fix wrong commands in "Before training" ([#280](https://github.com/34j/so-vits-svc-fork/issues/280)) ([`e056ad9`](https://github.com/34j/so-vits-svc-fork/commit/e056ad9ec22cbaa119f7c93cb60b5b8851e80a7e))
|
||||
|
||||
## v3.1.7 (2023-04-09)
|
||||
### Fix
|
||||
* **train:** Improve quality of training ([#274](https://github.com/34j/so-vits-svc-fork/issues/274)) ([`7ed71d6`](https://github.com/34j/so-vits-svc-fork/commit/7ed71d6fd89ca8bf2c4aefbb280e705b1d7ae6b8))
|
||||
|
||||
## v3.1.6 (2023-04-09)
|
||||
### Fix
|
||||
* **train:** Fix checkpoint not properly loaded ([#271](https://github.com/34j/so-vits-svc-fork/issues/271)) ([`0979147`](https://github.com/34j/so-vits-svc-fork/commit/0979147a234e08999a19dba4988a53886f61dade))
|
||||
|
||||
## v3.1.5 (2023-04-09)
|
||||
### Fix
|
||||
* **train:** Fix optim_d functions called in wrong order ([#269](https://github.com/34j/so-vits-svc-fork/issues/269)) ([`13d6346`](https://github.com/34j/so-vits-svc-fork/commit/13d63469b0a84ace0dc8848df47dc20538b98770))
|
||||
|
||||
## v3.1.4 (2023-04-09)
|
||||
### Fix
|
||||
* **train:** Add bf16 and fp16 support ([#268](https://github.com/34j/so-vits-svc-fork/issues/268)) ([`4229fd8`](https://github.com/34j/so-vits-svc-fork/commit/4229fd8ead64cf03caad9acd3d8f7f0fec3a7fee))
|
||||
|
||||
## v3.1.3 (2023-04-09)
|
||||
### Fix
|
||||
* **deps:** Update dependency starlette to v0.26.1 ([#256](https://github.com/34j/so-vits-svc-fork/issues/256)) ([`5eb574b`](https://github.com/34j/so-vits-svc-fork/commit/5eb574bec01430399df48e90e6112cef85e21945))
|
||||
|
||||
## v3.1.2 (2023-04-09)
|
||||
### Fix
|
||||
* Remove wrong test and trigger release ([#266](https://github.com/34j/so-vits-svc-fork/issues/266)) ([`9ea77e4`](https://github.com/34j/so-vits-svc-fork/commit/9ea77e4c5c6575844685998e237994d54be84bb9))
|
||||
* **deps:** Remove pydantic constraints ([#263](https://github.com/34j/so-vits-svc-fork/issues/263)) ([`f446e3b`](https://github.com/34j/so-vits-svc-fork/commit/f446e3bbd62205b9c847e9ecdc46f519417b572a))
|
||||
* Fix fastapi version to 0.88 ([#261](https://github.com/34j/so-vits-svc-fork/issues/261)) ([`a26f387`](https://github.com/34j/so-vits-svc-fork/commit/a26f387abea585c300cd1ed0c36c6b9afc731764))
|
||||
* **utils:** Fix get_optimal_device ([#262](https://github.com/34j/so-vits-svc-fork/issues/262)) ([`79e4b5a`](https://github.com/34j/so-vits-svc-fork/commit/79e4b5a0abe20789335eaaf4a359880c099aaa35))
|
||||
|
||||
## v3.1.1 (2023-04-08)
|
||||
### Fix
|
||||
* **deps:** Update dependency fastapi to <0.96 ([#255](https://github.com/34j/so-vits-svc-fork/issues/255)) ([`29c8cc0`](https://github.com/34j/so-vits-svc-fork/commit/29c8cc05b7e5180058e03f2dc1f681e58cc67f09))
|
||||
|
||||
## v3.1.0 (2023-04-08)
|
||||
### Feature
|
||||
* Migrate to lightning ([#246](https://github.com/34j/so-vits-svc-fork/issues/246)) ([`824ecbd`](https://github.com/34j/so-vits-svc-fork/commit/824ecbd7222b9b9ada77c4fbbd7ae7f491049f21))
|
||||
|
||||
## v3.0.5 (2023-04-08)
|
||||
### Fix
|
||||
* **cluster:** Fix train_cluster ([#250](https://github.com/34j/so-vits-svc-fork/issues/250)) ([`b0c93e4`](https://github.com/34j/so-vits-svc-fork/commit/b0c93e49f9cdfdcd714575fc27011bf56ce4493d))
|
||||
|
||||
## v3.0.4 (2023-04-06)
|
||||
### Fix
|
||||
* **__main__:** Fix default config type to revert breaking changes ([#243](https://github.com/34j/so-vits-svc-fork/issues/243)) ([`e05c0b5`](https://github.com/34j/so-vits-svc-fork/commit/e05c0b52b6affac5e4483c0938e04584e1bd8d98))
|
||||
|
||||
## v3.0.3 (2023-04-05)
|
||||
### Fix
|
||||
* Fix issues when loading legacy checkpoint and fix pre-hubert n_jobs ([#236](https://github.com/34j/so-vits-svc-fork/issues/236)) ([`15f1e7f`](https://github.com/34j/so-vits-svc-fork/commit/15f1e7ffca80cb551316affae546ea72e8cccb34))
|
||||
|
||||
## v3.0.2 (2023-04-04)
|
||||
### Performance
|
||||
* Move methods from dataloader to pre-hubert ([#218](https://github.com/34j/so-vits-svc-fork/issues/218)) ([`d5a4456`](https://github.com/34j/so-vits-svc-fork/commit/d5a4456ebd5b6659ca037ee2f43480a00d7915f6))
|
||||
|
||||
## v3.0.1 (2023-04-03)
|
||||
### Fix
|
||||
* Remove possible leak in unused code ([#203](https://github.com/34j/so-vits-svc-fork/issues/203)) ([`e921c3d`](https://github.com/34j/so-vits-svc-fork/commit/e921c3dc018ea783b4c26375a04f499a45ad9df0))
|
||||
|
||||
### Performance
|
||||
* **utils:** Better implementation of repeat_expand_2d ([#216](https://github.com/34j/so-vits-svc-fork/issues/216)) ([`ef30a9d`](https://github.com/34j/so-vits-svc-fork/commit/ef30a9d5ae60fdde5f6b44d6cea8cee0a40dd3e9))
|
||||
|
||||
## v3.0.0 (2023-04-03)
|
||||
### Feature
|
||||
* Add quickvc, fix usage of ContentVec, remove onnx support ([#197](https://github.com/34j/so-vits-svc-fork/issues/197)) ([`1a6c021`](https://github.com/34j/so-vits-svc-fork/commit/1a6c021cd102b48b44e006decebc165062df8a95))
|
||||
|
||||
### Breaking
|
||||
* The module structure has been completely changed, and some of the default values for configurations have also been changed. ([`1a6c021`](https://github.com/34j/so-vits-svc-fork/commit/1a6c021cd102b48b44e006decebc165062df8a95))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Update allcontributors link for @MashiroSA ([#210](https://github.com/34j/so-vits-svc-fork/issues/210)) ([`650524b`](https://github.com/34j/so-vits-svc-fork/commit/650524bb37997326e924814632c6202b76660f77))
|
||||
* **readme:** Add paperspace referral ([#209](https://github.com/34j/so-vits-svc-fork/issues/209)) ([`7280012`](https://github.com/34j/so-vits-svc-fork/commit/7280012df66b5ea71291e5a80bb22451f0ca236e))
|
||||
* **readme:** Add paperspace link and add more description, add a link for zh-CN docs ([#208](https://github.com/34j/so-vits-svc-fork/issues/208)) ([`bc4b122`](https://github.com/34j/so-vits-svc-fork/commit/bc4b1229e4ad9c046fda38334c4c6d22548356c2))
|
||||
|
||||
## v2.1.5 (2023-04-01)
|
||||
### Fix
|
||||
* **deps:** Update dependency tensorboard to v2.12.1 ([#199](https://github.com/34j/so-vits-svc-fork/issues/199)) ([`0ccda1c`](https://github.com/34j/so-vits-svc-fork/commit/0ccda1ccb34b8125abe369f738b06de7b77c8efc))
|
||||
|
||||
## v2.1.4 (2023-03-31)
|
||||
### Fix
|
||||
* **deps:** Update dependency gradio to v3.24.1 ([#196](https://github.com/34j/so-vits-svc-fork/issues/196)) ([`4fa141b`](https://github.com/34j/so-vits-svc-fork/commit/4fa141b210cb9b80bc7f75176fb01b18352c91cd))
|
||||
|
||||
## v2.1.3 (2023-03-31)
|
||||
### Fix
|
||||
* **deps:** Update dependency gradio to v3.24.0 ([#192](https://github.com/34j/so-vits-svc-fork/issues/192)) ([`4e441cb`](https://github.com/34j/so-vits-svc-fork/commit/4e441cb30429e4a47afd261d69e32ec5f86564c9))
|
||||
|
||||
### Documentation
|
||||
* Add sbersier as a contributor for ideas, and userTesting ([#185](https://github.com/34j/so-vits-svc-fork/issues/185)) ([`a655bf4`](https://github.com/34j/so-vits-svc-fork/commit/a655bf47dde4ad2506283997987bce3a09229c57))
|
||||
* Add ColdCawfee as a contributor for bug ([#177](https://github.com/34j/so-vits-svc-fork/issues/177)) ([`87a09e6`](https://github.com/34j/so-vits-svc-fork/commit/87a09e654a0e8f064293750779b743abf2897ebb))
|
||||
|
||||
## v2.1.2 (2023-03-28)
|
||||
### Fix
|
||||
* **gui:** Fix wrong devices set as default ([#176](https://github.com/34j/so-vits-svc-fork/issues/176)) ([`6265f8f`](https://github.com/34j/so-vits-svc-fork/commit/6265f8f93e8facd4f58aab906bfcb23e05d4032b))
|
||||
* **__main__:** Fix -h option overridden ([#175](https://github.com/34j/so-vits-svc-fork/issues/175)) ([`52f1cfe`](https://github.com/34j/so-vits-svc-fork/commit/52f1cfe1f08bd63966b0d1d7c025abed17cb36a6))
|
||||
|
||||
### Documentation
|
||||
* Add xieyumc as a contributor for doc ([#174](https://github.com/34j/so-vits-svc-fork/issues/174)) ([`29474d9`](https://github.com/34j/so-vits-svc-fork/commit/29474d9dc77555fe5a55427278d44dfea7ece5ef))
|
||||
* **readme_zh_cn:** Update README_zh_CN.md ([#173](https://github.com/34j/so-vits-svc-fork/issues/173)) ([`f94a14c`](https://github.com/34j/so-vits-svc-fork/commit/f94a14cb63e2afd40cba3e94f84077643d9a7560))
|
||||
|
||||
## v2.1.1 (2023-03-27)
|
||||
### Fix
|
||||
* **deps:** Update dependency rich to v13.3.3 ([#171](https://github.com/34j/so-vits-svc-fork/issues/171)) ([`8bdefa9`](https://github.com/34j/so-vits-svc-fork/commit/8bdefa9636e13fb0a24058a589675a20655357f4))
|
||||
|
||||
### Documentation
|
||||
* Add nerdyrodent as a contributor for video ([#168](https://github.com/34j/so-vits-svc-fork/issues/168)) ([`78ab661`](https://github.com/34j/so-vits-svc-fork/commit/78ab661af198d87ce2ca5525fa262c639ed03cdc))
|
||||
* Add heyfixit as a contributor for doc ([#167](https://github.com/34j/so-vits-svc-fork/issues/167)) ([`32a2a63`](https://github.com/34j/so-vits-svc-fork/commit/32a2a63b375300be6d67be56035005956003bdfd))
|
||||
* Add Desuka-art as a contributor for bug ([#165](https://github.com/34j/so-vits-svc-fork/issues/165)) ([`fe3c6bf`](https://github.com/34j/so-vits-svc-fork/commit/fe3c6bf8270fc219cdaeef05b7deacdbfc4df313))
|
||||
* Add ruckusmattster as a contributor for bug ([#163](https://github.com/34j/so-vits-svc-fork/issues/163)) ([`2b971db`](https://github.com/34j/so-vits-svc-fork/commit/2b971db5c7a332c8321e99bd77bb956a0ee3ec88))
|
||||
* Add pierluigizagaria as a contributor for userTesting ([#160](https://github.com/34j/so-vits-svc-fork/issues/160)) ([`6fabe8d`](https://github.com/34j/so-vits-svc-fork/commit/6fabe8d10b684caa236331a157455db1da686f8f))
|
||||
* Add Satisfy256 as a contributor for bug ([#158](https://github.com/34j/so-vits-svc-fork/issues/158)) ([`ee72aee`](https://github.com/34j/so-vits-svc-fork/commit/ee72aee12f23fee458599b8b7fa4f0ed27d33b1c))
|
||||
* Add DL909 as a contributor for bug ([#152](https://github.com/34j/so-vits-svc-fork/issues/152)) ([`a5e6651`](https://github.com/34j/so-vits-svc-fork/commit/a5e6651a8f537961caf53adbb8bc52c1412c0762))
|
||||
|
||||
## v2.1.0 (2023-03-27)
|
||||
### Feature
|
||||
* **__main__:** Add an option to launch tensorboard in `train` command ([#149](https://github.com/34j/so-vits-svc-fork/issues/149)) ([`ef22cce`](https://github.com/34j/so-vits-svc-fork/commit/ef22cceaeb7f06ea53b2151ef9c962d1040de20d))
|
||||
|
||||
## v2.0.0 (2023-03-27)
|
||||
### Fix
|
||||
* Fix preprocessing and convert bool options to flags, use `unidecode` to decode non-ASCII filenames in `pre-resample` ([#147](https://github.com/34j/so-vits-svc-fork/issues/147)) ([`98d7ee2`](https://github.com/34j/so-vits-svc-fork/commit/98d7ee22a40104468285324cc6ec21c707c30d54))
|
||||
|
||||
### Breaking
|
||||
* Preprocessing default parameters changed and some options became flags. ([`98d7ee2`](https://github.com/34j/so-vits-svc-fork/commit/98d7ee22a40104468285324cc6ec21c707c30d54))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Add yt tutorial vid link ([#143](https://github.com/34j/so-vits-svc-fork/issues/143)) ([`1694f44`](https://github.com/34j/so-vits-svc-fork/commit/1694f449e5a9f7b9da71e9a4c2764830c5268de3))
|
||||
|
||||
## v1.4.3 (2023-03-26)
|
||||
### Performance
|
||||
* **preprocess:** Specify samplerate to reduce memory usage ([#137](https://github.com/34j/so-vits-svc-fork/issues/137)) ([`6217eda`](https://github.com/34j/so-vits-svc-fork/commit/6217eda0ec3bac27e408fcd0466a6b658cf718c5))
|
||||
|
||||
## v1.4.2 (2023-03-26)
|
||||
### Fix
|
||||
* **logging:** Initialize logging in logger file and move version log ([#131](https://github.com/34j/so-vits-svc-fork/issues/131)) ([`441d51f`](https://github.com/34j/so-vits-svc-fork/commit/441d51f8efa84144d8a9f8fa02f2adaaf15295c0))
|
||||
* **preprocess:** Fix dtype in sf.read() to save memory and fix preprocess_resample ([#132](https://github.com/34j/so-vits-svc-fork/issues/132)) ([`0af1e13`](https://github.com/34j/so-vits-svc-fork/commit/0af1e13a468ad282266a595b8d3c77d62aa938dc))
|
||||
* Fix audio resampled to 22kHz ([#130](https://github.com/34j/so-vits-svc-fork/issues/130)) ([`4203f37`](https://github.com/34j/so-vits-svc-fork/commit/4203f374c5625369518063888e1ca70d1af4f694))
|
||||
|
||||
### Documentation
|
||||
* Update notebook and README.md ([#128](https://github.com/34j/so-vits-svc-fork/issues/128)) ([`38d9744`](https://github.com/34j/so-vits-svc-fork/commit/38d97449d5b443167926f409f904f4b40c6e0f03))
|
||||
|
||||
## v1.4.1 (2023-03-26)
|
||||
### Fix
|
||||
* **__main__,gui:** Fix some parameters not passed ([#124](https://github.com/34j/so-vits-svc-fork/issues/124)) ([`6cfe3d3`](https://github.com/34j/so-vits-svc-fork/commit/6cfe3d3f567c03e1c59065ff827f564a13a7aaaf))
|
||||
|
||||
## v1.4.0 (2023-03-26)
|
||||
### Feature
|
||||
* **preprocessing:** Add 2 more preprocessing commands ([#123](https://github.com/34j/so-vits-svc-fork/issues/123)) ([`45eba0f`](https://github.com/34j/so-vits-svc-fork/commit/45eba0f25db1346757fcd9134ccb3a62125a05a9))
|
||||
|
||||
### Documentation
|
||||
* Add BlueAmulet as a contributor for code ([#119](https://github.com/34j/so-vits-svc-fork/issues/119)) ([`6a7e8ba`](https://github.com/34j/so-vits-svc-fork/commit/6a7e8ba827ee69f1ceca60b83dfbae437bbe6667))
|
||||
|
||||
## v1.3.5 (2023-03-26)
|
||||
### Fix
|
||||
* **data_utils:** Allow float32 audio to be processed properly ([#115](https://github.com/34j/so-vits-svc-fork/issues/115)) ([`13943b6`](https://github.com/34j/so-vits-svc-fork/commit/13943b693d177cf5417127647a3280a9e5ff9ca5))
|
||||
|
||||
## v1.3.4 (2023-03-25)
|
||||
### Fix
|
||||
* Change default f0 method from crepe to dio ([#100](https://github.com/34j/so-vits-svc-fork/issues/100)) ([`baf58d2`](https://github.com/34j/so-vits-svc-fork/commit/baf58d286c286c0064fd015e0e8f0b9e690021f7))
|
||||
|
||||
## v1.3.3 (2023-03-25)
|
||||
### Fix
|
||||
* Fix old checkpoint deletion by sorting the models properly (#65) ([#89](https://github.com/34j/so-vits-svc-fork/issues/89)) ([`287dc94`](https://github.com/34j/so-vits-svc-fork/commit/287dc94be719147023af0ecfe7e92b16a8e98fc5))
|
||||
|
||||
### Documentation
|
||||
* Add Lordmau5 as a contributor for bug, and code ([#102](https://github.com/34j/so-vits-svc-fork/issues/102)) ([`4df46ee`](https://github.com/34j/so-vits-svc-fork/commit/4df46eed47378f41d76c7637f540779db3bb54a3))
|
||||
|
||||
## v1.3.2 (2023-03-24)
|
||||
### Fix
|
||||
* **gui:** Fix devices list and fix tqdm error in gui ([#99](https://github.com/34j/so-vits-svc-fork/issues/99)) ([`59724cd`](https://github.com/34j/so-vits-svc-fork/commit/59724cd2afc6a8d5ef6ea4b7fa8c012e21fc4af6))
|
||||
|
||||
### Documentation
|
||||
* Add MashiroSA as a contributor for doc, and bug ([#98](https://github.com/34j/so-vits-svc-fork/issues/98)) ([`495b7cb`](https://github.com/34j/so-vits-svc-fork/commit/495b7cbfc9f9468d49bc3f57efe6c5c076dcb0d3))
|
||||
* **notebook:** Fix cluster inference command and improve cluster training command ([#93](https://github.com/34j/so-vits-svc-fork/issues/93)) ([`7642594`](https://github.com/34j/so-vits-svc-fork/commit/7642594472bd660fe046c45909f0475398af199e))
|
||||
|
||||
## v1.3.1 (2023-03-24)
|
||||
### Fix
|
||||
* **gui:** Fix defaut for auto_play ([#97](https://github.com/34j/so-vits-svc-fork/issues/97)) ([`07920a4`](https://github.com/34j/so-vits-svc-fork/commit/07920a4954e1a14d47fcb2687f050d49d03da415))
|
||||
* **infer_tool:** Fix speaker not automaticlly set to the first one if not found in cluster inference ([#96](https://github.com/34j/so-vits-svc-fork/issues/96)) ([`a643e4f`](https://github.com/34j/so-vits-svc-fork/commit/a643e4f26b59f12f00b316467edad876467dad49))
|
||||
|
||||
### Documentation
|
||||
* **notebook:** Add cluster training and inference ([#84](https://github.com/34j/so-vits-svc-fork/issues/84)) ([`9ffb621`](https://github.com/34j/so-vits-svc-fork/commit/9ffb6216f418d8c5a4a9f1bdd79fc2cebb885db1))
|
||||
|
||||
## v1.3.0 (2023-03-23)
|
||||
### Feature
|
||||
* **gui:** Better error handling ([#85](https://github.com/34j/so-vits-svc-fork/issues/85)) ([`985704b`](https://github.com/34j/so-vits-svc-fork/commit/985704b1afa8af15fe8eab5e3fc838465f5162c8))
|
||||
|
||||
## v1.2.11 (2023-03-23)
|
||||
### Fix
|
||||
* **gui,onnx:** Fix onnx export and fix gui ([#83](https://github.com/34j/so-vits-svc-fork/issues/83)) ([`3e9a47d`](https://github.com/34j/so-vits-svc-fork/commit/3e9a47dd4faa938a6aaebf2d7c1c0b9d68cc97d3))
|
||||
|
||||
## v1.2.10 (2023-03-23)
|
||||
### Fix
|
||||
* **cluster:** Fix cluster not working ([#82](https://github.com/34j/so-vits-svc-fork/issues/82)) ([`29b209c`](https://github.com/34j/so-vits-svc-fork/commit/29b209cf7060deb7f15ae28fe2e520bb20a236f4))
|
||||
|
||||
## v1.2.9 (2023-03-23)
|
||||
### Fix
|
||||
* **gui:** Fix speakers and devices not updated and fix default presets ([#80](https://github.com/34j/so-vits-svc-fork/issues/80)) ([`a851150`](https://github.com/34j/so-vits-svc-fork/commit/a8511508b0d2b3a62e7b77833280e4264997d9ed))
|
||||
|
||||
## v1.2.8 (2023-03-22)
|
||||
### Fix
|
||||
* **deps:** Update dependency torchcrepe to v0.0.18 ([#76](https://github.com/34j/so-vits-svc-fork/issues/76)) ([`4fda479`](https://github.com/34j/so-vits-svc-fork/commit/4fda4799f017e7de57de36c95cd8d64ab6f9b446))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Shorten docs ([#75](https://github.com/34j/so-vits-svc-fork/issues/75)) ([`e0c1572`](https://github.com/34j/so-vits-svc-fork/commit/e0c1572d057032735c3118e9137be8e4399c6251))
|
||||
|
||||
## v1.2.7 (2023-03-22)
|
||||
### Fix
|
||||
* Fix clean_checkpoints ([#66](https://github.com/34j/so-vits-svc-fork/issues/66)) ([`e5169bf`](https://github.com/34j/so-vits-svc-fork/commit/e5169bf8121578a6cc3ed1bccd1b47a6281cafe4))
|
||||
|
||||
## v1.2.6 (2023-03-22)
|
||||
### Fix
|
||||
* **gui:** Disable checkbox if CUDA is not available and show errors for VC ([#71](https://github.com/34j/so-vits-svc-fork/issues/71)) ([`3fdd983`](https://github.com/34j/so-vits-svc-fork/commit/3fdd9836c3b60d2e737fc7e40efe42a9cc84888e))
|
||||
|
||||
### Documentation
|
||||
* Add BlueAmulet as a contributor for question ([#74](https://github.com/34j/so-vits-svc-fork/issues/74)) ([`8d073e3`](https://github.com/34j/so-vits-svc-fork/commit/8d073e3e0798a0739cea5b979cf6cfd361f3e6d3))
|
||||
* Add GarrettConway as a contributor for doc ([#73](https://github.com/34j/so-vits-svc-fork/issues/73)) ([`6c6cbc6`](https://github.com/34j/so-vits-svc-fork/commit/6c6cbc6ac8a97ecb71d789a5782bb8db2c4c52f8))
|
||||
* **readme:** Update README.md regarding installation, update. WSL audio support ([#72](https://github.com/34j/so-vits-svc-fork/issues/72)) ([`4f1323b`](https://github.com/34j/so-vits-svc-fork/commit/4f1323b3d12a080f38a195bf494db7086dbfa7e4))
|
||||
|
||||
## v1.2.5 (2023-03-22)
|
||||
### Fix
|
||||
* Fix RTF calculation ([#70](https://github.com/34j/so-vits-svc-fork/issues/70)) ([`fb25500`](https://github.com/34j/so-vits-svc-fork/commit/fb25500f4e3e70e5d71462715b83fb3bedcf8bd5))
|
||||
|
||||
## v1.2.4 (2023-03-22)
|
||||
### Fix
|
||||
* **utils:** Fix latest_checkpoint_path ([#64](https://github.com/34j/so-vits-svc-fork/issues/64)) ([`00b9f4a`](https://github.com/34j/so-vits-svc-fork/commit/00b9f4acd005cdb801b3f41df6e25b0b8799d631))
|
||||
|
||||
## v1.2.3 (2023-03-21)
|
||||
### Fix
|
||||
* **deps:** Update dependency onnxsim to v0.4.19 ([#62](https://github.com/34j/so-vits-svc-fork/issues/62)) ([`f8a4cf6`](https://github.com/34j/so-vits-svc-fork/commit/f8a4cf61bad5d0d55a7334af8f022114605e7038))
|
||||
|
||||
## v1.2.2 (2023-03-21)
|
||||
### Fix
|
||||
* **deps:** Update dependency onnxoptimizer to v0.3.10 ([#61](https://github.com/34j/so-vits-svc-fork/issues/61)) ([`d0137f9`](https://github.com/34j/so-vits-svc-fork/commit/d0137f920083a08173d58e35492b9b9fb925e41f))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Add links for pretrained models and fix GUI pic height ([#60](https://github.com/34j/so-vits-svc-fork/issues/60)) ([`34ac39f`](https://github.com/34j/so-vits-svc-fork/commit/34ac39f0c9ce89f2effdd18f3fc4ab91e72b3f82))
|
||||
* **notebook:** Add more explanation to notebook ([#59](https://github.com/34j/so-vits-svc-fork/issues/59)) ([`9b3c483`](https://github.com/34j/so-vits-svc-fork/commit/9b3c4835e063d26d1e66d172cf592e69e30d59b8))
|
||||
|
||||
## v1.2.1 (2023-03-21)
|
||||
### Fix
|
||||
* Use librosa.load() instead of soundfile.read() ([#58](https://github.com/34j/so-vits-svc-fork/issues/58)) ([`b343106`](https://github.com/34j/so-vits-svc-fork/commit/b34310662b2bac53884df396932f72366132ea01))
|
||||
* **gui:** Fix window too big to show in a FHD environment ([#57](https://github.com/34j/so-vits-svc-fork/issues/57)) ([`259e6e6`](https://github.com/34j/so-vits-svc-fork/commit/259e6e6eb6ebfd9027b1813756d67d1a516e0214))
|
||||
|
||||
## v1.2.0 (2023-03-21)
|
||||
### Feature
|
||||
* Add presets ([#55](https://github.com/34j/so-vits-svc-fork/issues/55)) ([`e8adcc6`](https://github.com/34j/so-vits-svc-fork/commit/e8adcc621f6caf5f4b20846575b3559c032ed47f))
|
||||
|
||||
## v1.1.1 (2023-03-21)
|
||||
### Fix
|
||||
* **deps:** Update dependency gradio to v3.23.0 ([#54](https://github.com/34j/so-vits-svc-fork/issues/54)) ([`a2bdb48`](https://github.com/34j/so-vits-svc-fork/commit/a2bdb48b436d206b30bb72409852c0b30d6811e9))
|
||||
|
||||
## v1.1.0 (2023-03-21)
|
||||
### Feature
|
||||
* Enhance RealtimeVC ([#52](https://github.com/34j/so-vits-svc-fork/issues/52)) ([`81551ce`](https://github.com/34j/so-vits-svc-fork/commit/81551ce9c6fb7924d184c3c5a4cf9035168b28d2))
|
||||
|
||||
### Documentation
|
||||
* Update gui screenshot ([#53](https://github.com/34j/so-vits-svc-fork/issues/53)) ([`58d06aa`](https://github.com/34j/so-vits-svc-fork/commit/58d06aa7460dd75ef793da295bf7651ae9940814))
|
||||
|
||||
## v1.0.2 (2023-03-21)
|
||||
### Fix
|
||||
* **deps:** Update dependency scipy to v1.10.1 ([#35](https://github.com/34j/so-vits-svc-fork/issues/35)) ([`e0253bf`](https://github.com/34j/so-vits-svc-fork/commit/e0253bf1e655f86be605395a18f343763d975101))
|
||||
|
||||
## v1.0.1 (2023-03-20)
|
||||
### Documentation
|
||||
* Add ThrowawayAccount01 as a contributor for bug ([#47](https://github.com/34j/so-vits-svc-fork/issues/47)) ([`15e31fa`](https://github.com/34j/so-vits-svc-fork/commit/15e31fa806249d45235918fa62a48a86c43538cb))
|
||||
* Add BlueAmulet as a contributor for ideas ([#46](https://github.com/34j/so-vits-svc-fork/issues/46)) ([`a3bcb2b`](https://github.com/34j/so-vits-svc-fork/commit/a3bcb2be2992c98bcc2485082c19009c74cb3194))
|
||||
|
||||
### Performance
|
||||
* **inference_main:** Do dummy inference before running vc ([#45](https://github.com/34j/so-vits-svc-fork/issues/45)) ([`4066c43`](https://github.com/34j/so-vits-svc-fork/commit/4066c4334b107062d2daa7c9dc00600a56c6e553))
|
||||
|
||||
## v1.0.0 (2023-03-20)
|
||||
### Fix
|
||||
* Fix default dataset path ([#43](https://github.com/34j/so-vits-svc-fork/issues/43)) ([`ac47fed`](https://github.com/34j/so-vits-svc-fork/commit/ac47fede2581d375c2be9c28102961f19f5a9aa1))
|
||||
|
||||
### Breaking
|
||||
* the behaviour of preprocess_resample changes when there is a folder ./dataset_raw/44k and "44k" is no longer allowed as a speaker name in some conditions ([`ac47fed`](https://github.com/34j/so-vits-svc-fork/commit/ac47fede2581d375c2be9c28102961f19f5a9aa1))
|
||||
|
||||
## v0.8.2 (2023-03-20)
|
||||
### Fix
|
||||
* Fix compute_f0_crepe returning wrong length ([#42](https://github.com/34j/so-vits-svc-fork/issues/42)) ([`afb42b0`](https://github.com/34j/so-vits-svc-fork/commit/afb42b019ccd133876a2c55cf01007950a733d8c))
|
||||
|
||||
## v0.8.1 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency librosa to v0.10.0 ([#40](https://github.com/34j/so-vits-svc-fork/issues/40)) ([`8e92f71`](https://github.com/34j/so-vits-svc-fork/commit/8e92f71b2820628f0f8583e6bc455d8f753f4302))
|
||||
|
||||
## v0.8.0 (2023-03-20)
|
||||
### Feature
|
||||
* Add more f0 calculation methods ([#39](https://github.com/34j/so-vits-svc-fork/issues/39)) ([`6b3b20d`](https://github.com/34j/so-vits-svc-fork/commit/6b3b20dfd609d81cb1184b7c8e8865a58f8d45f9))
|
||||
|
||||
## v0.7.1 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency gradio to v3.22.1 ([#33](https://github.com/34j/so-vits-svc-fork/issues/33)) ([`f09fc23`](https://github.com/34j/so-vits-svc-fork/commit/f09fc23ca82519cc095509d4d4760561424a17ec))
|
||||
|
||||
## v0.7.0 (2023-03-20)
|
||||
### Feature
|
||||
* **preprocessing:** Allow nested dataset ([#19](https://github.com/34j/so-vits-svc-fork/issues/19)) ([`0433151`](https://github.com/34j/so-vits-svc-fork/commit/0433151d94c4da8e84a0183bdd47f1e08ea3c462))
|
||||
|
||||
## v0.6.3 (2023-03-20)
|
||||
### Fix
|
||||
* **deps:** Update dependency torch to v1.13.1 ([#27](https://github.com/34j/so-vits-svc-fork/issues/27)) ([`8826d68`](https://github.com/34j/so-vits-svc-fork/commit/8826d6870e223e7969baa069bf12235e0deec0b7))
|
||||
* **deps:** Update dependency torchaudio to v0.13.1 ([#28](https://github.com/34j/so-vits-svc-fork/issues/28)) ([`989f5d9`](https://github.com/34j/so-vits-svc-fork/commit/989f5d903b47ba9b0ea1d0fe37cbfe76edf0a811))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Update notes about VRAM caps ([#18](https://github.com/34j/so-vits-svc-fork/issues/18)) ([`0a245f4`](https://github.com/34j/so-vits-svc-fork/commit/0a245f4ee69bd0d4371836367becf0fe409431e2))
|
||||
|
||||
## v0.6.2 (2023-03-19)
|
||||
### Fix
|
||||
* Use hubert preprocess force_rebuild argument ([#15](https://github.com/34j/so-vits-svc-fork/issues/15)) ([`87cf807`](https://github.com/34j/so-vits-svc-fork/commit/87cf807496248e2c7b859069f81aa040e86aec59))
|
||||
|
||||
### Documentation
|
||||
* Add GarrettConway as a contributor for bug ([#17](https://github.com/34j/so-vits-svc-fork/issues/17)) ([`31d9671`](https://github.com/34j/so-vits-svc-fork/commit/31d9671207143fd06b8db148802d1e27874151ce))
|
||||
* **notebook:** Launch tensorboard ([#16](https://github.com/34j/so-vits-svc-fork/issues/16)) ([`52229ba`](https://github.com/34j/so-vits-svc-fork/commit/52229ba0fe9458e37b45287c0a716c7cd36adbd6))
|
||||
* Add 34j as a contributor for example, infra, and 6 more ([#14](https://github.com/34j/so-vits-svc-fork/issues/14)) ([`1b90378`](https://github.com/34j/so-vits-svc-fork/commit/1b903783b4b89f2f5a4fc2e1b47f3eade0c0402f))
|
||||
* Add GarrettConway as a contributor for code ([#13](https://github.com/34j/so-vits-svc-fork/issues/13)) ([`716813f`](https://github.com/34j/so-vits-svc-fork/commit/716813fbff85ab4609d8ec3f374b78c6551877e5))
|
||||
|
||||
## v0.6.1 (2023-03-19)
|
||||
### Performance
|
||||
* **preprocessing:** Better performance ([#12](https://github.com/34j/so-vits-svc-fork/issues/12)) ([`668c8e1`](https://github.com/34j/so-vits-svc-fork/commit/668c8e1f18cefb0ebd2fb2f1d6572ce4d37d1102))
|
||||
|
||||
## v0.6.0 (2023-03-18)
|
||||
### Feature
|
||||
* Configurable input and output devices ([#11](https://github.com/34j/so-vits-svc-fork/issues/11)) ([`a822a60`](https://github.com/34j/so-vits-svc-fork/commit/a822a6098d322ff37725eee19d17758f72a6db49))
|
||||
|
||||
### Documentation
|
||||
* **notebook:** Fix notebook ([#9](https://github.com/34j/so-vits-svc-fork/issues/9)) ([`427b4c1`](https://github.com/34j/so-vits-svc-fork/commit/427b4c1c6e0482345b17fedb018f7a18db68ccc5))
|
||||
* Update notebook ([#8](https://github.com/34j/so-vits-svc-fork/issues/8)) ([`ae3e471`](https://github.com/34j/so-vits-svc-fork/commit/ae3e4710aac41555f00ddcdfbcf5a5e925afb718))
|
||||
|
||||
## v0.5.0 (2023-03-18)
|
||||
### Feature
|
||||
* **gui:** Remember last directory (misc) ([`92558da`](https://github.com/34j/so-vits-svc-fork/commit/92558da2f0e4eb24a8de412fb7e22dc3530b648a))
|
||||
* **__main__:** Show defaults ([`3d298df`](https://github.com/34j/so-vits-svc-fork/commit/3d298df91bdfca230959603da74331b5eef4d487))
|
||||
|
||||
### Fix
|
||||
* **__main__:** Fix option names ([`7ff34fe`](https://github.com/34j/so-vits-svc-fork/commit/7ff34fe623dde6b0a684c45cf33dc54118f9a800))
|
||||
|
||||
### Documentation
|
||||
* **readme:** Update README.md ([#6](https://github.com/34j/so-vits-svc-fork/issues/6)) ([`b988101`](https://github.com/34j/so-vits-svc-fork/commit/b98810194703b6bb0ede03a00c460eeecdab5131))
|
||||
|
||||
## v0.4.1 (2023-03-18)
|
||||
### Fix
|
||||
* Call init_logger() ([#5](https://github.com/34j/so-vits-svc-fork/issues/5)) ([`e6378f1`](https://github.com/34j/so-vits-svc-fork/commit/e6378f12e747e618ff90ece1552d09c0d0714d41))
|
||||
|
||||
## v0.4.0 (2023-03-18)
|
||||
### Feature
|
||||
* Enhance realtime algorythm ([#4](https://github.com/34j/so-vits-svc-fork/issues/4)) ([`d789a12`](https://github.com/34j/so-vits-svc-fork/commit/d789a12308784473ae5d09e0b73fa15bf7554de1))
|
||||
|
||||
## v0.3.0 (2023-03-17)
|
||||
### Feature
|
||||
* Add gui ([#3](https://github.com/34j/so-vits-svc-fork/issues/3)) ([`34aec2b`](https://github.com/34j/so-vits-svc-fork/commit/34aec2b98ee4ef82ef488129b61a7952af5226a3))
|
||||
|
||||
### Documentation
|
||||
* Update notebook ([`7b74606`](https://github.com/34j/so-vits-svc-fork/commit/7b74606508cfb7e45224cbd76f3de9c43c8b4309))
|
||||
|
||||
## v0.2.1 (2023-03-17)
|
||||
### Fix
|
||||
* **notebook:** Fix notebook ([`3ed00cc`](https://github.com/34j/so-vits-svc-fork/commit/3ed00cc66d4f66e045f61fc14937cb9160eee556))
|
||||
|
||||
## v0.2.0 (2023-03-17)
|
||||
### Feature
|
||||
* Realtime inference ([#2](https://github.com/34j/so-vits-svc-fork/issues/2)) ([`4dea1ae`](https://github.com/34j/so-vits-svc-fork/commit/4dea1ae51fe2e47a3f41556bdbe3fefd033d729a))
|
||||
|
||||
## v0.1.0 (2023-03-17)
|
||||
### Feature
|
||||
* Main feat ([#1](https://github.com/34j/so-vits-svc-fork/issues/1)) ([`faa990c`](https://github.com/34j/so-vits-svc-fork/commit/faa990ce6411d8b4e8b3d2d48c4b532b76ff7800))
|
||||
@@ -0,0 +1,117 @@
|
||||
# Contributing
|
||||
|
||||
Contributions are welcome, and they are greatly appreciated! Every little helps, and credit will always be given.
|
||||
|
||||
You can contribute in many ways:
|
||||
|
||||
## Types of Contributions
|
||||
|
||||
### Report Bugs
|
||||
|
||||
Report bugs to [our issue page][gh-issues]. If you are reporting a bug, please include:
|
||||
|
||||
- Your operating system name and version.
|
||||
- Any details about your local setup that might be helpful in troubleshooting.
|
||||
- Detailed steps to reproduce the bug.
|
||||
|
||||
### Fix Bugs
|
||||
|
||||
Look through the GitHub issues for bugs. Anything tagged with "bug" and "help wanted" is open to whoever wants to implement it.
|
||||
|
||||
### Implement Features
|
||||
|
||||
Look through the GitHub issues for features. Anything tagged with "enhancement" and "help wanted" is open to whoever wants to implement it.
|
||||
|
||||
### Write Documentation
|
||||
|
||||
SoftVC VITS Singing Voice Conversion Fork could always use more documentation, whether as part of the official SoftVC VITS Singing Voice Conversion Fork docs, in docstrings, or even on the web in blog posts, articles, and such.
|
||||
|
||||
### Submit Feedback
|
||||
|
||||
The best way to send feedback [our issue page][gh-issues] on GitHub. If you are proposing a feature:
|
||||
|
||||
- Explain in detail how it would work.
|
||||
- Keep the scope as narrow as possible, to make it easier to implement.
|
||||
- Remember that this is a volunteer-driven project, and that contributions are welcome 😊
|
||||
|
||||
## Get Started!
|
||||
|
||||
Ready to contribute? Here's how to set yourself up for local development.
|
||||
|
||||
1. Fork the repo on GitHub.
|
||||
|
||||
2. Clone your fork locally:
|
||||
|
||||
```shell
|
||||
$ git clone git@github.com:your_name_here/so-vits-svc-fork.git
|
||||
```
|
||||
|
||||
3. Install the project dependencies with [Poetry](https://python-poetry.org):
|
||||
|
||||
```shell
|
||||
$ poetry install
|
||||
```
|
||||
|
||||
4. Create a branch for local development:
|
||||
|
||||
```shell
|
||||
$ git checkout -b name-of-your-bugfix-or-feature
|
||||
```
|
||||
|
||||
Now you can make your changes locally.
|
||||
|
||||
5. When you're done making changes, check that your changes pass our tests:
|
||||
|
||||
```shell
|
||||
$ poetry run pytest
|
||||
```
|
||||
|
||||
6. Linting is done through [pre-commit](https://pre-commit.com). Provided you have the tool installed globally, you can run them all as one-off:
|
||||
|
||||
```shell
|
||||
$ pre-commit run -a
|
||||
```
|
||||
|
||||
Or better, install the hooks once and have them run automatically each time you commit:
|
||||
|
||||
```shell
|
||||
$ pre-commit install
|
||||
```
|
||||
|
||||
7. Commit your changes and push your branch to GitHub:
|
||||
|
||||
```shell
|
||||
$ git add .
|
||||
$ git commit -m "feat(something): your detailed description of your changes"
|
||||
$ git push origin name-of-your-bugfix-or-feature
|
||||
```
|
||||
|
||||
Note: the commit message should follow [the conventional commits](https://www.conventionalcommits.org). We run [`commitlint` on CI](https://github.com/marketplace/actions/commit-linter) to validate it, and if you've installed pre-commit hooks at the previous step, the message will be checked at commit time.
|
||||
|
||||
8. Submit a pull request through the GitHub website or using the GitHub CLI (if you have it installed):
|
||||
|
||||
```shell
|
||||
$ gh pr create --fill
|
||||
```
|
||||
|
||||
## Pull Request Guidelines
|
||||
|
||||
We like to have the pull request open as soon as possible, that's a great place to discuss any piece of work, even unfinished. You can use draft pull request if it's still a work in progress. Here are a few guidelines to follow:
|
||||
|
||||
1. Include tests for feature or bug fixes.
|
||||
2. Update the documentation for significant features.
|
||||
3. Ensure tests are passing on CI.
|
||||
|
||||
## Tips
|
||||
|
||||
To run a subset of tests:
|
||||
|
||||
```shell
|
||||
$ pytest tests
|
||||
```
|
||||
|
||||
## Making a new release
|
||||
|
||||
The deployment should be automated and can be triggered from the Semantic Release workflow in GitHub. The next version will be based on [the commit logs](https://python-semantic-release.readthedocs.io/en/latest/commit-log-parsing.html#commit-log-parsing). This is done by [python-semantic-release](https://python-semantic-release.readthedocs.io/en/latest/index.html) via a GitHub action.
|
||||
|
||||
[gh-issues]: https://github.com/34j/so-vits-svc-fork/issues
|
||||
@@ -0,0 +1,37 @@
|
||||
FROM nvidia/cuda:12.0.1-runtime-ubuntu22.04
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive
|
||||
|
||||
# NB: ffmpeg for transcoding opus -> wav
|
||||
RUN apt-get update && apt-get install -y \
|
||||
build-essential \
|
||||
curl \
|
||||
ffmpeg \
|
||||
htop \
|
||||
libsndfile1 \
|
||||
nvidia-driver-515 \
|
||||
python3-pip \
|
||||
python3.10 \
|
||||
python3.10-dev \
|
||||
python3.10-venv \
|
||||
vim \
|
||||
wget \
|
||||
--no-install-recommends \
|
||||
&& apt-get clean autoclean && apt-get autoremove -y && rm -rf /var/lib/{apt,dpkg,cache,log}/
|
||||
|
||||
|
||||
RUN mkdir /install
|
||||
WORKDIR /install
|
||||
|
||||
COPY requirements.txt .
|
||||
|
||||
#RUN pip install -r requirements-without-poetry.txt
|
||||
|
||||
RUN python3 -m venv python \
|
||||
&& . python/bin/activate \
|
||||
&& pip install -r requirements.txt
|
||||
|
||||
WORKDIR /
|
||||
|
||||
COPY . /models/voice_conversion/so-vits-svc
|
||||
|
||||
@@ -0,0 +1,223 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2023 34j and contributors
|
||||
Copyright (c) 2021 Jingyi Li
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
@@ -0,0 +1,49 @@
|
||||
so-vits-svc
|
||||
===========
|
||||
|
||||
Original docs are in [README\_ORIGINAL.md](./README_ORIGINAL.md).
|
||||
|
||||
This is a snapshot of `f9f16d67e44c127b9cf6d02d6eb5a235d28b70d2` (branch `tag v3.12.1`). It was taken
|
||||
from voicepaw's fork at https://github.com/voicepaw/so-vits-svc-fork
|
||||
|
||||
|
||||
Dev Installation
|
||||
----------------
|
||||
|
||||
`pip install -e .`
|
||||
|
||||
There is also a Dockerfile available so if you prefer:
|
||||
```sh
|
||||
docker build -t so-vits-svc .`
|
||||
docker run -it --privileged --gpus 0 so-vits-svc
|
||||
```
|
||||
|
||||
Usage
|
||||
-----
|
||||
```
|
||||
Usage: svc infer [OPTIONS] INPUT_PATH
|
||||
|
||||
Inference
|
||||
|
||||
Options:
|
||||
-o, --output-path PATH path to output dir
|
||||
-s, --speaker TEXT speaker name
|
||||
-m, --model-path PATH path to model [default: logs/44k]
|
||||
-c, --config-path PATH path to config [default: configs/44k/config.json]
|
||||
-k, --cluster-model-path PATH path to cluster model
|
||||
-t, --transpose INTEGER transpose [default: 0]
|
||||
-db, --db-thresh INTEGER threshold (DB) (RELATIVE) [default: -20]
|
||||
-fm, --f0-method [crepe|crepe-tiny|parselmouth|dio|harvest]
|
||||
f0 prediction method [default: dio]
|
||||
-a, --auto-predict-f0 / -na, --no-auto-predict-f0
|
||||
auto predict f0 [default: na]
|
||||
-r, --cluster-infer-ratio FLOAT
|
||||
cluster infer ratio [default: 0]
|
||||
-n, --noise-scale FLOAT noise scale [default: 0.4]
|
||||
-p, --pad-seconds FLOAT pad seconds [default: 0.5]
|
||||
-d, --device TEXT device [default: cuda:0]
|
||||
-ch, --chunk-seconds FLOAT chunk seconds [default: 0.5]
|
||||
-ab, --absolute-thresh / -nab, --no-absolute-thresh
|
||||
absolute thresh [default: nab]
|
||||
-h, --help Show this message and exit.```
|
||||
```
|
||||
@@ -0,0 +1,293 @@
|
||||
# SoftVC VITS Singing Voice Conversion Fork
|
||||
|
||||
[简体中文](README_zh_CN.md)
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/34j/so-vits-svc-fork/actions/workflows/ci.yml?query=branch%3Amain">
|
||||
<img src="https://img.shields.io/github/actions/workflow/status/34j/so-vits-svc-fork/ci.yml?branch=main&label=CI&logo=github&style=flat-square" alt="CI Status" >
|
||||
</a>
|
||||
<a href="https://so-vits-svc-fork.readthedocs.io">
|
||||
<img src="https://img.shields.io/readthedocs/so-vits-svc-fork.svg?logo=read-the-docs&logoColor=fff&style=flat-square" alt="Documentation Status">
|
||||
</a>
|
||||
<a href="https://codecov.io/gh/34j/so-vits-svc-fork">
|
||||
<img src="https://img.shields.io/codecov/c/github/34j/so-vits-svc-fork.svg?logo=codecov&logoColor=fff&style=flat-square" alt="Test coverage percentage">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://python-poetry.org/">
|
||||
<img src="https://img.shields.io/badge/packaging-poetry-299bd7?style=flat-square&logo=data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAA4AAAASCAYAAABrXO8xAAAACXBIWXMAAAsTAAALEwEAmpwYAAAAAXNSR0IArs4c6QAAAARnQU1BAACxjwv8YQUAAAJJSURBVHgBfZLPa1NBEMe/s7tNXoxW1KJQKaUHkXhQvHgW6UHQQ09CBS/6V3hKc/AP8CqCrUcpmop3Cx48eDB4yEECjVQrlZb80CRN8t6OM/teagVxYZi38+Yz853dJbzoMV3MM8cJUcLMSUKIE8AzQ2PieZzFxEJOHMOgMQQ+dUgSAckNXhapU/NMhDSWLs1B24A8sO1xrN4NECkcAC9ASkiIJc6k5TRiUDPhnyMMdhKc+Zx19l6SgyeW76BEONY9exVQMzKExGKwwPsCzza7KGSSWRWEQhyEaDXp6ZHEr416ygbiKYOd7TEWvvcQIeusHYMJGhTwF9y7sGnSwaWyFAiyoxzqW0PM/RjghPxF2pWReAowTEXnDh0xgcLs8l2YQmOrj3N7ByiqEoH0cARs4u78WgAVkoEDIDoOi3AkcLOHU60RIg5wC4ZuTC7FaHKQm8Hq1fQuSOBvX/sodmNJSB5geaF5CPIkUeecdMxieoRO5jz9bheL6/tXjrwCyX/UYBUcjCaWHljx1xiX6z9xEjkYAzbGVnB8pvLmyXm9ep+W8CmsSHQQY77Zx1zboxAV0w7ybMhQmfqdmmw3nEp1I0Z+FGO6M8LZdoyZnuzzBdjISicKRnpxzI9fPb+0oYXsNdyi+d3h9bm9MWYHFtPeIZfLwzmFDKy1ai3p+PDls1Llz4yyFpferxjnyjJDSEy9CaCx5m2cJPerq6Xm34eTrZt3PqxYO1XOwDYZrFlH1fWnpU38Y9HRze3lj0vOujZcXKuuXm3jP+s3KbZVra7y2EAAAAAASUVORK5CYII=" alt="Poetry">
|
||||
</a>
|
||||
<a href="https://github.com/ambv/black">
|
||||
<img src="https://img.shields.io/badge/code%20style-black-000000.svg?style=flat-square" alt="black">
|
||||
</a>
|
||||
<a href="https://github.com/pre-commit/pre-commit">
|
||||
<img src="https://img.shields.io/badge/pre--commit-enabled-brightgreen?logo=pre-commit&logoColor=white&style=flat-square" alt="pre-commit">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://pypi.org/project/so-vits-svc-fork/">
|
||||
<img src="https://img.shields.io/pypi/v/so-vits-svc-fork.svg?logo=python&logoColor=fff&style=flat-square" alt="PyPI Version">
|
||||
</a>
|
||||
<img src="https://img.shields.io/pypi/pyversions/so-vits-svc-fork.svg?style=flat-square&logo=python&logoColor=fff" alt="Supported Python versions">
|
||||
<img src="https://img.shields.io/pypi/l/so-vits-svc-fork.svg?style=flat-square" alt="License">
|
||||
</p>
|
||||
|
||||
A fork of [`so-vits-svc`](https://github.com/svc-develop-team/so-vits-svc) with **realtime support** and **greatly improved interface**. Based on branch `4.0` (v1) and the models are compatible.
|
||||
|
||||
## Features not available in the original repo
|
||||
|
||||
- **Realtime voice conversion** (enhanced in v1.1.0)
|
||||
- Integrates [`QuickVC`](https://github.com/quickvc/QuickVC-VoiceConversion)
|
||||
- Fixed misuse of [`ContentVec`](https://github.com/auspicious3000/contentvec) in the original repository.[^c]
|
||||
- More accurate pitch estimation using [`CREPE`](https://github.com/marl/crepe/).
|
||||
- GUI and unified CLI available
|
||||
- ~2x faster training
|
||||
- Ready to use just by installing with `pip`.
|
||||
- Automatically download pretrained models. No need to install `fairseq`.
|
||||
- Code completely formatted with black, isort, autoflake etc.
|
||||
|
||||
[^c]: [#206](https://github.com/34j/so-vits-svc-fork/issues/206)
|
||||
|
||||
## Installation
|
||||
|
||||
### One click easy installation
|
||||
|
||||
<a href="https://github.com/34j/so-vits-svc-fork/releases/download/v1.3.2/install.bat" download>
|
||||
<img src="https://img.shields.io/badge/.bat-download-blue?style=flat-square&logo=windows" alt="Download .bat">
|
||||
</a>
|
||||
|
||||
### Manual installation
|
||||
|
||||
<details>
|
||||
<summary>Creating a virtual environment</summary>
|
||||
|
||||
Windows:
|
||||
|
||||
```shell
|
||||
py -3.10 -m venv venv
|
||||
venv\Scripts\activate
|
||||
```
|
||||
|
||||
Linux/MacOS:
|
||||
|
||||
```shell
|
||||
python3.10 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
Anaconda:
|
||||
|
||||
```shell
|
||||
conda create -n so-vits-svc-fork python=3.10 pip
|
||||
conda activate so-vits-svc-fork
|
||||
```
|
||||
|
||||
Installing without creating a virtual environment may cause a `PermissionError` if Python is installed in Program Files, etc.
|
||||
|
||||
</details>
|
||||
|
||||
Install this via pip (or your favourite package manager that uses pip):
|
||||
|
||||
```shell
|
||||
python -m pip install -U pip setuptools wheel
|
||||
pip install -U torch torchaudio --index-url https://download.pytorch.org/whl/cu118
|
||||
pip install -U so-vits-svc-fork
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Notes</summary>
|
||||
|
||||
- If no GPU is available or using MacOS, simply remove `pip install -U torch torchaudio --index-url https://download.pytorch.org/whl/cu118`. MPS is probably supported.
|
||||
- If you are using an AMD GPU on Linux, replace `--index-url https://download.pytorch.org/whl/cu118` with `--index-url https://download.pytorch.org/whl/rocm5.4.2`. AMD GPUs are not supported on Windows ([#120](https://github.com/34j/so-vits-svc-fork/issues/120)).
|
||||
</details>
|
||||
|
||||
### Update
|
||||
|
||||
Please update this package regularly to get the latest features and bug fixes.
|
||||
|
||||
```shell
|
||||
pip install -U so-vits-svc-fork
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Inference
|
||||
|
||||
#### GUI
|
||||
|
||||
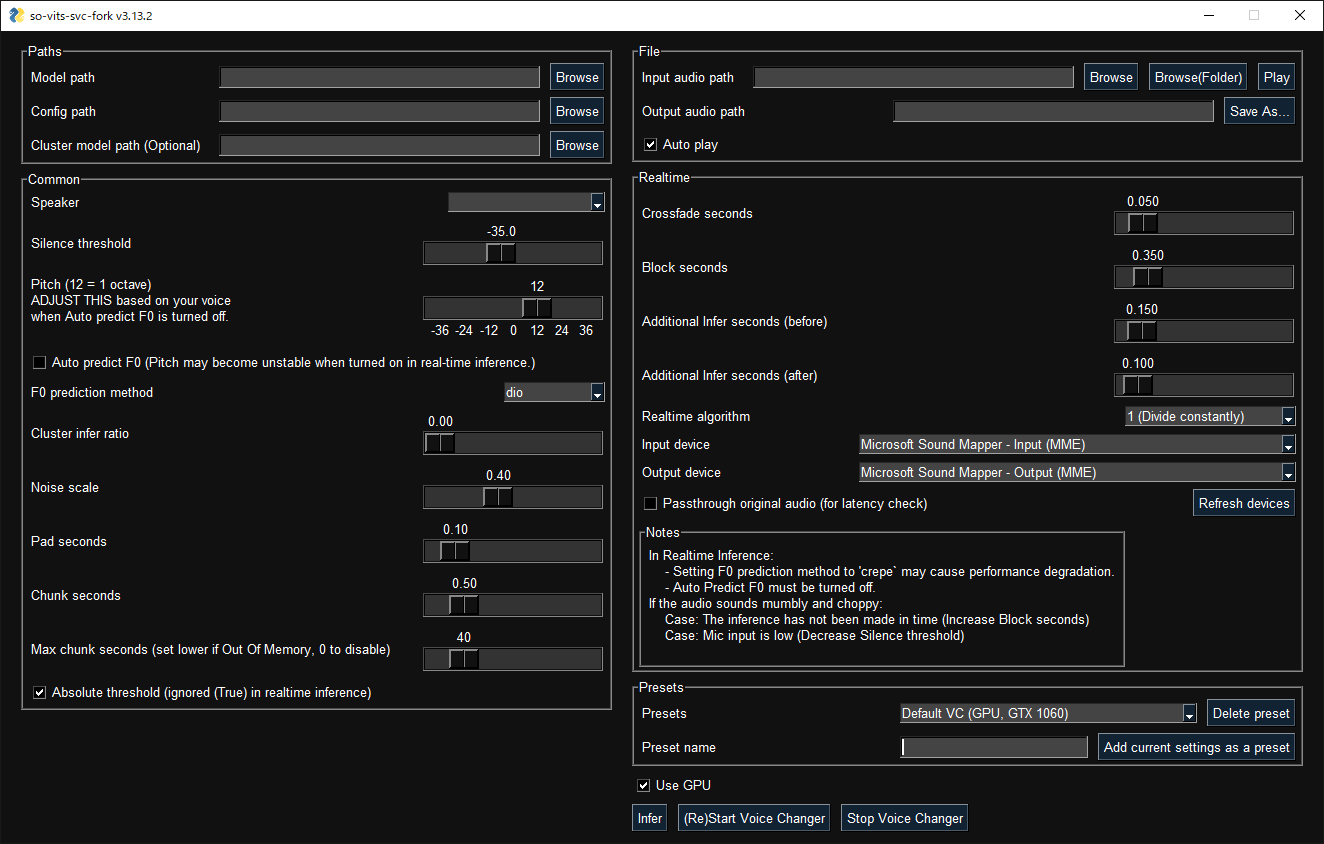
|
||||
|
||||
GUI launches with the following command:
|
||||
|
||||
```shell
|
||||
svcg
|
||||
```
|
||||
|
||||
#### CLI
|
||||
|
||||
- Realtime (from microphone)
|
||||
|
||||
```shell
|
||||
svc vc
|
||||
```
|
||||
|
||||
- File
|
||||
|
||||
```shell
|
||||
svc infer source.wav
|
||||
```
|
||||
|
||||
[Pretrained models](https://huggingface.co/models?search=so-vits-svc-4.0) are available on Hugging Face.
|
||||
|
||||
#### Notes
|
||||
|
||||
- If using WSL, please note that WSL requires additional setup to handle audio and the GUI will not work without finding an audio device.
|
||||
- In real-time inference, if there is noise on the inputs, the HuBERT model will react to those as well. Consider using realtime noise reduction applications such as [RTX Voice](https://www.nvidia.com/en-us/geforce/guides/nvidia-rtx-voice-setup-guide/) in this case.
|
||||
|
||||
### Training
|
||||
|
||||
#### Before training
|
||||
|
||||
- If your dataset has BGM, please remove the BGM using software such as [Ultimate Vocal Remover](https://ultimatevocalremover.com/). `3_HP-Vocal-UVR.pth` or `UVR-MDX-NET Main` is recommended. [^1]
|
||||
- If your dataset is a long audio file with a single speaker, use `svc pre-split` to split the dataset into multiple files (using `librosa`).
|
||||
- If your dataset is a long audio file with multiple speakers, use `svc pre-sd` to split the dataset into multiple files (using `pyannote.audio`). Further manual classification may be necessary due to accuracy issues. If speakers speak with a variety of speech styles, set --min-speakers larger than the actual number of speakers. Due to unresolved dependencies, please install `pyannote.audio` manually: `pip install pyannote-audio`.
|
||||
- To manually classify audio files, `svc pre-classify` is available. Up and down arrow keys can be used to change the playback speed.
|
||||
|
||||
[^1]: https://ytpmv.info/how-to-use-uvr/
|
||||
|
||||
#### Cloud
|
||||
|
||||
[](https://colab.research.google.com/github/34j/so-vits-svc-fork/blob/main/notebooks/so-vits-svc-fork-4.0.ipynb)
|
||||
[](https://console.paperspace.com/github/34j/so-vits-svc-fork-paperspace/blob/main/so-vits-svc-fork-4.0-paperspace.ipynb)
|
||||
[](https://www.paperspace.com/?r=9VJN74I)[^p]
|
||||
|
||||
If you do not have access to a GPU with more than 10 GB of VRAM, the free plan of Google Colab is recommended for light users and the Pro/Growth plan of Paperspace is recommended for heavy users. Conversely, if you have access to a high-end GPU, the use of cloud services is not recommended.
|
||||
|
||||
[^p]: If you register a referral code and then add a payment method, you may save about $5 on your first month's monthly billing. Note that both referral rewards are Paperspace credits and not cash. It was a tough decision but inserted because debugging and training the initial model requires a large amount of computing power and the developer is a student.
|
||||
|
||||
#### Local
|
||||
|
||||
Place your dataset like `dataset_raw/{speaker_id}/**/{wav_file}.{any_format}` (subfolders and non-ASCII filenames are acceptable) and run:
|
||||
|
||||
```shell
|
||||
svc pre-resample
|
||||
svc pre-config
|
||||
svc pre-hubert
|
||||
svc train -t
|
||||
```
|
||||
|
||||
#### Notes
|
||||
|
||||
- Dataset audio duration per file should be <~ 10s.
|
||||
- It is recommended to increase the `batch_size` as much as possible in `config.json` before the `train` command to match the VRAM capacity. Setting `batch_size` to `auto-{init_batch_size}-{max_n_trials}` (or simply `auto`) will automatically increase `batch_size` until OOM error occurs, but may not be useful in some cases.
|
||||
- To use `CREPE`, replace `svc pre-hubert` with `svc pre-hubert -fm crepe`.
|
||||
- To use `ContentVec` correctly, replace `svc pre-config` with `-t so-vits-svc-4.0v1`. Training may take slightly longer because some weights are reset due to reusing legacy initial generator weights.
|
||||
- To use `MS-iSTFT Decoder`, replace `svc pre-config` with `svc pre-config -t quickvc`.
|
||||
- Silence removal and volume normalization are automatically performed (as in the upstream repo) and are not required.
|
||||
- If you have trained on a large, copyright-free dataset, consider releasing it as an initial model.
|
||||
- For further details (e.g. parameters, etc.), you can see the [Wiki](https://github.com/34j/so-vits-svc-fork/wiki) or [Discussions](https://github.com/34j/so-vits-svc-fork/discussions).
|
||||
|
||||
### Further help
|
||||
|
||||
For more details, run `svc -h` or `svc <subcommand> -h`.
|
||||
|
||||
```shell
|
||||
> svc -h
|
||||
Usage: svc [OPTIONS] COMMAND [ARGS]...
|
||||
|
||||
so-vits-svc allows any folder structure for training data.
|
||||
However, the following folder structure is recommended.
|
||||
When training: dataset_raw/{speaker_name}/**/{wav_name}.{any_format}
|
||||
When inference: configs/44k/config.json, logs/44k/G_XXXX.pth
|
||||
If the folder structure is followed, you DO NOT NEED TO SPECIFY model path, config path, etc.
|
||||
(The latest model will be automatically loaded.)
|
||||
To train a model, run pre-resample, pre-config, pre-hubert, train.
|
||||
To infer a model, run infer.
|
||||
|
||||
Options:
|
||||
-h, --help Show this message and exit.
|
||||
|
||||
Commands:
|
||||
clean Clean up files, only useful if you are using the default file structure
|
||||
infer Inference
|
||||
onnx Export model to onnx (currently not working)
|
||||
pre-classify Classify multiple audio files into multiple files
|
||||
pre-config Preprocessing part 2: config
|
||||
pre-hubert Preprocessing part 3: hubert If the HuBERT model is not found, it will be...
|
||||
pre-resample Preprocessing part 1: resample
|
||||
pre-sd Speech diarization using pyannote.audio
|
||||
pre-split Split audio files into multiple files
|
||||
train Train model If D_0.pth or G_0.pth not found, automatically download from hub.
|
||||
train-cluster Train k-means clustering
|
||||
vc Realtime inference from microphone
|
||||
```
|
||||
|
||||
#### External Links
|
||||
|
||||
[Video Tutorial](https://www.youtube.com/watch?v=tZn0lcGO5OQ)
|
||||
|
||||
## Contributors ✨
|
||||
|
||||
Thanks goes to these wonderful people ([emoji key](https://allcontributors.org/docs/en/emoji-key)):
|
||||
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- ALL-CONTRIBUTORS-LIST:START - Do not remove or modify this section -->
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- markdownlint-disable -->
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/34j"><img src="https://avatars.githubusercontent.com/u/55338215?v=4?s=80" width="80px;" alt="34j"/><br /><sub><b>34j</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Code">💻</a> <a href="#ideas-34j" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Documentation">📖</a> <a href="#example-34j" title="Examples">💡</a> <a href="#infra-34j" title="Infrastructure (Hosting, Build-Tools, etc)">🚇</a> <a href="#maintenance-34j" title="Maintenance">🚧</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/pulls?q=is%3Apr+reviewed-by%3A34j" title="Reviewed Pull Requests">👀</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Tests">⚠️</a> <a href="#tutorial-34j" title="Tutorials">✅</a> <a href="#promotion-34j" title="Promotion">📣</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3A34j" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/GarrettConway"><img src="https://avatars.githubusercontent.com/u/22782004?v=4?s=80" width="80px;" alt="GarrettConway"/><br /><sub><b>GarrettConway</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=GarrettConway" title="Code">💻</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AGarrettConway" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=GarrettConway" title="Documentation">📖</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/pulls?q=is%3Apr+reviewed-by%3AGarrettConway" title="Reviewed Pull Requests">👀</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/BlueAmulet"><img src="https://avatars.githubusercontent.com/u/43395286?v=4?s=80" width="80px;" alt="BlueAmulet"/><br /><sub><b>BlueAmulet</b></sub></a><br /><a href="#ideas-BlueAmulet" title="Ideas, Planning, & Feedback">🤔</a> <a href="#question-BlueAmulet" title="Answering Questions">💬</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=BlueAmulet" title="Code">💻</a> <a href="#maintenance-BlueAmulet" title="Maintenance">🚧</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ThrowawayAccount01"><img src="https://avatars.githubusercontent.com/u/125531852?v=4?s=80" width="80px;" alt="ThrowawayAccount01"/><br /><sub><b>ThrowawayAccount01</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AThrowawayAccount01" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/MashiroSA"><img src="https://avatars.githubusercontent.com/u/40637516?v=4?s=80" width="80px;" alt="緋"/><br /><sub><b>緋</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=MashiroSA" title="Documentation">📖</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AMashiroSA" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Lordmau5"><img src="https://avatars.githubusercontent.com/u/1345036?v=4?s=80" width="80px;" alt="Lordmau5"/><br /><sub><b>Lordmau5</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ALordmau5" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=Lordmau5" title="Code">💻</a> <a href="#ideas-Lordmau5" title="Ideas, Planning, & Feedback">🤔</a> <a href="#maintenance-Lordmau5" title="Maintenance">🚧</a> <a href="#question-Lordmau5" title="Answering Questions">💬</a> <a href="#userTesting-Lordmau5" title="User Testing">📓</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/DL909"><img src="https://avatars.githubusercontent.com/u/71912115?v=4?s=80" width="80px;" alt="DL909"/><br /><sub><b>DL909</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADL909" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Satisfy256"><img src="https://avatars.githubusercontent.com/u/101394399?v=4?s=80" width="80px;" alt="Satisfy256"/><br /><sub><b>Satisfy256</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ASatisfy256" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/pierluigizagaria"><img src="https://avatars.githubusercontent.com/u/57801386?v=4?s=80" width="80px;" alt="Pierluigi Zagaria"/><br /><sub><b>Pierluigi Zagaria</b></sub></a><br /><a href="#userTesting-pierluigizagaria" title="User Testing">📓</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ruckusmattster"><img src="https://avatars.githubusercontent.com/u/77196088?v=4?s=80" width="80px;" alt="ruckusmattster"/><br /><sub><b>ruckusmattster</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aruckusmattster" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Desuka-art"><img src="https://avatars.githubusercontent.com/u/111822082?v=4?s=80" width="80px;" alt="Desuka-art"/><br /><sub><b>Desuka-art</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADesuka-art" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/heyfixit"><img src="https://avatars.githubusercontent.com/u/41658450?v=4?s=80" width="80px;" alt="heyfixit"/><br /><sub><b>heyfixit</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=heyfixit" title="Documentation">📖</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://www.youtube.com/c/NerdyRodent"><img src="https://avatars.githubusercontent.com/u/74688049?v=4?s=80" width="80px;" alt="Nerdy Rodent"/><br /><sub><b>Nerdy Rodent</b></sub></a><br /><a href="#video-nerdyrodent" title="Videos">📹</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/xieyumc"><img src="https://avatars.githubusercontent.com/u/47858007?v=4?s=80" width="80px;" alt="谢宇"/><br /><sub><b>谢宇</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=xieyumc" title="Documentation">📖</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ColdCawfee"><img src="https://avatars.githubusercontent.com/u/79474598?v=4?s=80" width="80px;" alt="ColdCawfee"/><br /><sub><b>ColdCawfee</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AColdCawfee" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/sbersier"><img src="https://avatars.githubusercontent.com/u/34165937?v=4?s=80" width="80px;" alt="sbersier"/><br /><sub><b>sbersier</b></sub></a><br /><a href="#ideas-sbersier" title="Ideas, Planning, & Feedback">🤔</a> <a href="#userTesting-sbersier" title="User Testing">📓</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Asbersier" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Meldoner"><img src="https://avatars.githubusercontent.com/u/43951115?v=4?s=80" width="80px;" alt="Meldoner"/><br /><sub><b>Meldoner</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AMeldoner" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/mmodeusher"><img src="https://avatars.githubusercontent.com/u/46575920?v=4?s=80" width="80px;" alt="mmodeusher"/><br /><sub><b>mmodeusher</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Ammodeusher" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/AlonDan"><img src="https://avatars.githubusercontent.com/u/21152334?v=4?s=80" width="80px;" alt="AlonDan"/><br /><sub><b>AlonDan</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AAlonDan" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Likkkez"><img src="https://avatars.githubusercontent.com/u/44336181?v=4?s=80" width="80px;" alt="Likkkez"/><br /><sub><b>Likkkez</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ALikkkez" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/DuctTapeGames"><img src="https://avatars.githubusercontent.com/u/84365142?v=4?s=80" width="80px;" alt="Duct Tape Games"/><br /><sub><b>Duct Tape Games</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADuctTapeGames" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://tec.hxlxz.com/"><img src="https://avatars.githubusercontent.com/u/6624983?v=4?s=80" width="80px;" alt="Xianglong He"/><br /><sub><b>Xianglong He</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Ahxl9654" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/75aosu"><img src="https://avatars.githubusercontent.com/u/79185331?v=4?s=80" width="80px;" alt="75aosu"/><br /><sub><b>75aosu</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3A75aosu" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/tonyco82"><img src="https://avatars.githubusercontent.com/u/56610534?v=4?s=80" width="80px;" alt="tonyco82"/><br /><sub><b>tonyco82</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Atonyco82" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/yxlllc"><img src="https://avatars.githubusercontent.com/u/33565655?v=4?s=80" width="80px;" alt="yxlllc"/><br /><sub><b>yxlllc</b></sub></a><br /><a href="#ideas-yxlllc" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=yxlllc" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/outhipped"><img src="https://avatars.githubusercontent.com/u/116147475?v=4?s=80" width="80px;" alt="outhipped"/><br /><sub><b>outhipped</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aouthipped" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/escoolioinglesias"><img src="https://avatars.githubusercontent.com/u/73505402?v=4?s=80" width="80px;" alt="escoolioinglesias"/><br /><sub><b>escoolioinglesias</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aescoolioinglesias" title="Bug reports">🐛</a> <a href="#userTesting-escoolioinglesias" title="User Testing">📓</a> <a href="#video-escoolioinglesias" title="Videos">📹</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Blacksingh"><img src="https://avatars.githubusercontent.com/u/130872856?v=4?s=80" width="80px;" alt="Blacksingh"/><br /><sub><b>Blacksingh</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ABlacksingh" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="http://tybantarnusa.com"><img src="https://avatars.githubusercontent.com/u/9532857?v=4?s=80" width="80px;" alt="Mgs. M. Thoyib Antarnusa"/><br /><sub><b>Mgs. M. Thoyib Antarnusa</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Atybantarnusa" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ZeroHackz"><img src="https://avatars.githubusercontent.com/u/15729496?v=4?s=80" width="80px;" alt="Exosfeer"/><br /><sub><b>Exosfeer</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AZeroHackz" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=ZeroHackz" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/guranon"><img src="https://avatars.githubusercontent.com/u/130421189?v=4?s=80" width="80px;" alt="guranon"/><br /><sub><b>guranon</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aguranon" title="Bug reports">🐛</a> <a href="#ideas-guranon" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=guranon" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/alexanderkoumis"><img src="https://avatars.githubusercontent.com/u/5108856?v=4?s=80" width="80px;" alt="Alexander Koumis"/><br /><sub><b>Alexander Koumis</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=alexanderkoumis" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/acekagami"><img src="https://avatars.githubusercontent.com/u/127201056?v=4?s=80" width="80px;" alt="acekagami"/><br /><sub><b>acekagami</b></sub></a><br /><a href="#translation-acekagami" title="Translation">🌍</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Highupech"><img src="https://avatars.githubusercontent.com/u/114140670?v=4?s=80" width="80px;" alt="Highupech"/><br /><sub><b>Highupech</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AHighupech" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Scorpi"><img src="https://avatars.githubusercontent.com/u/969654?v=4?s=80" width="80px;" alt="Scorpi"/><br /><sub><b>Scorpi</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=Scorpi" title="Code">💻</a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
<!-- markdownlint-restore -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:END -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
This project follows the [all-contributors](https://github.com/all-contributors/all-contributors) specification. Contributions of any kind welcome!
|
||||
@@ -0,0 +1,295 @@
|
||||
# SoftVC VITS Singing Voice Conversion
|
||||
|
||||
<p align="center">
|
||||
<a href="https://github.com/34j/so-vits-svc-fork/actions/workflows/ci.yml?query=branch%3Amain">
|
||||
<img src="https://img.shields.io/github/actions/workflow/status/34j/so-vits-svc-fork/ci.yml?branch=main&label=CI&logo=github&style=flat-square" alt="CI Status" >
|
||||
</a>
|
||||
<a href="https://so-vits-svc-fork.readthedocs.io">
|
||||
<img src="https://img.shields.io/readthedocs/so-vits-svc-fork.svg?logo=read-the-docs&logoColor=fff&style=flat-square" alt="Documentation Status">
|
||||
</a>
|
||||
<a href="https://codecov.io/gh/34j/so-vits-svc-fork">
|
||||
<img src="https://img.shields.io/codecov/c/github/34j/so-vits-svc-fork.svg?logo=codecov&logoColor=fff&style=flat-square" alt="Test coverage percentage">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://python-poetry.org/">
|
||||
<img src="https://img.shields.io/badge/packaging-poetry-299bd7?style=flat-square&logo=data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAA4AAAASCAYAAABrXO8xAAAACXBIWXMAAAsTAAALEwEAmpwYAAAAAXNSR0IArs4c6QAAAARnQU1BAACxjwv8YQUAAAJJSURBVHgBfZLPa1NBEMe/s7tNXoxW1KJQKaUHkXhQvHgW6UHQQ09CBS/6V3hKc/AP8CqCrUcpmop3Cx48eDB4yEECjVQrlZb80CRN8t6OM/teagVxYZi38+Yz853dJbzoMV3MM8cJUcLMSUKIE8AzQ2PieZzFxEJOHMOgMQQ+dUgSAckNXhapU/NMhDSWLs1B24A8sO1xrN4NECkcAC9ASkiIJc6k5TRiUDPhnyMMdhKc+Zx19l6SgyeW76BEONY9exVQMzKExGKwwPsCzza7KGSSWRWEQhyEaDXp6ZHEr416ygbiKYOd7TEWvvcQIeusHYMJGhTwF9y7sGnSwaWyFAiyoxzqW0PM/RjghPxF2pWReAowTEXnDh0xgcLs8l2YQmOrj3N7ByiqEoH0cARs4u78WgAVkoEDIDoOi3AkcLOHU60RIg5wC4ZuTC7FaHKQm8Hq1fQuSOBvX/sodmNJSB5geaF5CPIkUeecdMxieoRO5jz9bheL6/tXjrwCyX/UYBUcjCaWHljx1xiX6z9xEjkYAzbGVnB8pvLmyXm9ep+W8CmsSHQQY77Zx1zboxAV0w7ybMhQmfqdmmw3nEp1I0Z+FGO6M8LZdoyZnuzzBdjISicKRnpxzI9fPb+0oYXsNdyi+d3h9bm9MWYHFtPeIZfLwzmFDKy1ai3p+PDls1Llz4yyFpferxjnyjJDSEy9CaCx5m2cJPerq6Xm34eTrZt3PqxYO1XOwDYZrFlH1fWnpU38Y9HRze3lj0vOujZcXKuuXm3jP+s3KbZVra7y2EAAAAAASUVORK5CYII=" alt="Poetry">
|
||||
</a>
|
||||
<a href="https://github.com/ambv/black">
|
||||
<img src="https://img.shields.io/badge/code%20style-black-000000.svg?style=flat-square" alt="black">
|
||||
</a>
|
||||
<a href="https://github.com/pre-commit/pre-commit">
|
||||
<img src="https://img.shields.io/badge/pre--commit-enabled-brightgreen?logo=pre-commit&logoColor=white&style=flat-square" alt="pre-commit">
|
||||
</a>
|
||||
</p>
|
||||
<p align="center">
|
||||
<a href="https://pypi.org/project/so-vits-svc-fork/">
|
||||
<img src="https://img.shields.io/pypi/v/so-vits-svc-fork.svg?logo=python&logoColor=fff&style=flat-square" alt="PyPI Version">
|
||||
</a>
|
||||
<img src="https://img.shields.io/pypi/pyversions/so-vits-svc-fork.svg?style=flat-square&logo=python&logoColor=fff" alt="Supported Python versions">
|
||||
<img src="https://img.shields.io/pypi/l/so-vits-svc-fork.svg?style=flat-square" alt="License">
|
||||
</p>
|
||||
|
||||
基于 [`so-vits-svc4.0(V1)`](https://github.com/svc-develop-team/so-vits-svc)的一个分支,支持实时推理和图形化推理界面,且兼容其模型。
|
||||
|
||||
## 新功能
|
||||
|
||||
- **实时语音转换** (增强版本 v1.1.0)
|
||||
- 与[`QuickVC`](https://github.com/quickvc/QuickVC-VoiceConversion)相结合
|
||||
- 修复了原始版本中对 [`ContentVec`](https://github.com/auspicious3000/contentvec) 的误用[^c]
|
||||
- 使用 CREPE 进行更准确的音高推测
|
||||
- 图形化界面和统一命令行界面
|
||||
- 相比之前双倍的训练速度
|
||||
- 只需使用 `pip` 安装即可使用,不需要安装 `fairseq`
|
||||
- 自动下载预训练模型和 HuBERT 模型
|
||||
- 使用 black、isort、autoflake 等完全格式化的代码
|
||||
|
||||
[^c]: [#206](https://github.com/34j/so-vits-svc-fork/issues/206)
|
||||
|
||||
## 安装教程
|
||||
|
||||
### 可以使用 bat 一键安装
|
||||
|
||||
<a href="https://github.com/xieyumc/so-vits-svc-fork-cn/releases/download/install/install-cn.bat" download>
|
||||
<img src="https://img.shields.io/badge/.bat-download-blue?style=flat-square&logo=windows" alt="Download .bat">
|
||||
</a>
|
||||
|
||||
### 本 bat 汉化基于英文版,对原版进行了一些本地工作和优化,如安装过程有问题,可以尝试安装原版
|
||||
|
||||
<a href="https://github.com/34j/so-vits-svc-fork/releases/download/v1.3.2/install.bat" download>
|
||||
<img src="https://img.shields.io/badge/.bat-download-blue?style=flat-square&logo=windows" alt="Download .bat">
|
||||
</a>
|
||||
|
||||
### 手动安装
|
||||
|
||||
<details>
|
||||
<summary>创建一个虚拟环境</summary>
|
||||
|
||||
Windows:
|
||||
|
||||
```shell
|
||||
py -3.10 -m venv venv
|
||||
venv\Scripts\activate
|
||||
```
|
||||
|
||||
Linux/MacOS:
|
||||
|
||||
```shell
|
||||
python3.10 -m venv venv
|
||||
source venv/bin/activate
|
||||
```
|
||||
|
||||
Anaconda:
|
||||
|
||||
```shell
|
||||
conda create -n so-vits-svc-fork python=3.10 pip
|
||||
conda activate so-vits-svc-fork
|
||||
```
|
||||
|
||||
如果 Python 安装在 Program Files,在安装时未创造虚拟环境可能会导致`PermissionError`
|
||||
|
||||
</details>
|
||||
|
||||
### 安装
|
||||
|
||||
通过 pip 安装 (或者通过包管理器使用 pip 安装):
|
||||
|
||||
```shell
|
||||
python -m pip install -U pip setuptools wheel
|
||||
pip install -U torch torchaudio --index-url https://download.pytorch.org/whl/cu118
|
||||
pip install -U so-vits-svc-fork
|
||||
```
|
||||
|
||||
- 如果没有可用 GPU 或使用 MacOS, 不需要执行 `pip install -U torch torchaudio --index-url https://download.pytorch.org/whl/cu118`. MPS 可能已经安装了.
|
||||
- 如果在 Linux 下使用 AMD GPU, 请使用此命令 `--index-url https://download.pytorch.org/whl/rocm5.4.2`
|
||||
替换掉 `--index-url https://download.pytorch.org/whl/cu118` . Windows 下不支持 AMD GPUs (#120).
|
||||
|
||||
### 更新
|
||||
|
||||
请经常更新以获取最新功能和修复错误:
|
||||
|
||||
```shell
|
||||
pip install -U so-vits-svc-fork
|
||||
```
|
||||
|
||||
## 使用教程
|
||||
|
||||
### 推理
|
||||
|
||||
#### 图形化界面
|
||||
|
||||

|
||||
|
||||
请使用以下命令运行图形化界面:
|
||||
|
||||
```shell
|
||||
svcg
|
||||
```
|
||||
|
||||
#### 命令行界面
|
||||
|
||||
- 实时转换 (输入源为麦克风)
|
||||
|
||||
```shell
|
||||
svc vc
|
||||
```
|
||||
|
||||
- 从文件转换
|
||||
|
||||
```shell
|
||||
svc infer source.wav
|
||||
```
|
||||
|
||||
[预训练模型](https://huggingface.co/models?search=so-vits-svc-4.0) 可以在 HuggingFace 获得。
|
||||
|
||||
#### 注意
|
||||
|
||||
- 如果使用 WSL, 请注意 WSL 需要额外设置来处理音频,如果 GUI 找不到音频设备将不能正常工作。
|
||||
- 在实时语音转换中, 如果输入源有杂音, HuBERT
|
||||
模型依然会把杂音进行推理.可以考虑使用实时噪音减弱程序比如 [RTX Voice](https://www.nvidia.com/en-us/geforce/guides/nvidia-rtx-voice-setup-guide/)
|
||||
来解决.
|
||||
|
||||
### 训练
|
||||
|
||||
#### 预处理
|
||||
|
||||
- 如果数据集有 BGM,请用例如[Ultimate Vocal Remover](https://ultimatevocalremover.com/)等软件去除 BGM.
|
||||
推荐使用`3_HP-Vocal-UVR.pth` 或者 `UVR-MDX-NET Main` . [^1]
|
||||
- 如果数据集是包含单个歌手的长音频文件, 使用 `svc pre-split` 将数据集拆分为多个文件 (使用 `librosa`).
|
||||
- 如果数据集是包含多个歌手的长音频文件, 使用 `svc pre-sd` 将数据集拆分为多个文件 (使用 `pyannote.audio`)
|
||||
。为了提高准确率,可能需要手动进行分类。如果歌手的声线多样,请把 --min-speakers 设置为大于实际说话者数量. 如果出现依赖未安装,
|
||||
请通过 `pip install pyannote-audio`来安装 `pyannote.audio`。
|
||||
|
||||
[^1]: https://ytpmv.info/how-to-use-uvr/
|
||||
|
||||
#### 云端
|
||||
|
||||
[](https://colab.research.google.com/github/34j/so-vits-svc-fork/blob/main/notebooks/so-vits-svc-fork-4.0.ipynb)
|
||||
[](https://console.paperspace.com/github/34j/so-vits-svc-fork-paperspace/blob/main/so-vits-svc-fork-4.0-paperspace.ipynb)
|
||||
[](https://www.paperspace.com/?r=9VJN74I)[^p]
|
||||
|
||||
如果你无法获取 10GB 显存以上的显卡,对于轻量用户,推荐使用 Google Colab 的免费方案;而重度用户,则建议使用 Paperspace 的 Pro/Growth Plan。当然,如果你有高端的显卡,就没必要使用云服务了。
|
||||
|
||||
[^p]: If you register a referral code and then add a payment method, you may save about $5 on your first month's monthly billing. Note that both referral rewards are Paperspace credits and not cash. It was a tough decision but inserted because debugging and training the initial model requires a large amount of computing power and the developer is a student.
|
||||
|
||||
#### 本地
|
||||
|
||||
将数据集处理成 `dataset_raw/{speaker_id}/**/{wav_file}.{any_format}` 的格式(可以使用子文件夹和非 ASCII 文件名)然后运行:
|
||||
|
||||
```shell
|
||||
svc pre-resample
|
||||
svc pre-config
|
||||
svc pre-hubert
|
||||
svc train -t
|
||||
```
|
||||
|
||||
#### 注意
|
||||
|
||||
- 数据集的每个文件应该小于 10s,不然显存会爆。
|
||||
- 建议在执行 `train` 命令之前提高 `config.json` 中的 `batch_size` 以匹配显存容量。 将`batch_size`设为`auto-{init_batch_size}-{max_n_trials}`(或者只需设为`auto`)就会自动提高`batch_size`,直到爆显存为止(不过自动调高 batch_size 有概率失效)
|
||||
- 如果想要 f0 的推理方式为 `CREPE`, 用 `svc pre-hubert -fm crepe` 替换 `svc pre-hubert`.
|
||||
- 若想正确使用`ContentVec`,用 `-t so-vits-svc-4.0v1`替换`svc pre-config`。由于复用 generator weights,一些 weights 会被重置而导致训练时间稍微延长.
|
||||
- 若要使用`MS-iSTFT Decoder`,用 `svc pre-config -t quickvc`替换 `svc pre-config`.
|
||||
- 在原始仓库中,会自动移除静音和进行音量平衡,且这个操作并不是必须要处理的。
|
||||
- 倘若你已经大规模训练了一个免费公开版权的数据集,可以考虑将其作为底模发布。
|
||||
- 对于更多细节(比如参数等),详见[Wiki](https://github.com/34j/so-vits-svc-fork/wiki) 或 [Discussions](https://github.com/34j/so-vits-svc-fork/discussions).
|
||||
|
||||
### 帮助
|
||||
|
||||
更多命令, 运行 `svc -h` 或者 `svc <subcommand> -h`
|
||||
|
||||
```shell
|
||||
> svc -h
|
||||
用法: svc [OPTIONS] COMMAND [ARGS]...
|
||||
|
||||
so-vits-svc 允许任何文件夹结构用于训练数据
|
||||
但是, 建议使用以下文件夹结构
|
||||
训练: dataset_raw/{speaker_name}/**/{wav_name}.{any_format}
|
||||
推理: configs/44k/config.json, logs/44k/G_XXXX.pth
|
||||
如果遵循文件夹结构,则无需指定模型路径,配置路径等,将自动加载最新模型
|
||||
若要要训练模型, 运行 pre-resample, pre-config, pre-hubert, train.
|
||||
若要要推理模型, 运行 infer.
|
||||
|
||||
可选:
|
||||
-h, --help 显示信息并退出
|
||||
|
||||
命令:
|
||||
clean 清理文件,仅在使用默认文件结构时有用
|
||||
infer 推理
|
||||
onnx 导出模型到onnx
|
||||
pre-config 预处理第 2 部分: config
|
||||
pre-hubert 预处理第 3 部分: 如果没有找到 HuBERT 模型,则会...
|
||||
pre-resample 预处理第 1 部分: resample
|
||||
pre-sd Speech diarization 使用 pyannote.audio
|
||||
pre-split 将音频文件拆分为多个文件
|
||||
train 训练模型 如果 D_0.pth 或 G_0.pth 没有找到,自动从集线器下载.
|
||||
train-cluster 训练 k-means 聚类模型
|
||||
vc 麦克风实时推理
|
||||
```
|
||||
|
||||
#### 补充链接
|
||||
|
||||
[视频教程](https://www.youtube.com/watch?v=tZn0lcGO5OQ)
|
||||
|
||||
## Contributors ✨
|
||||
|
||||
Thanks goes to these wonderful people ([emoji key](https://allcontributors.org/docs/en/emoji-key)):
|
||||
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- ALL-CONTRIBUTORS-LIST:START - Do not remove or modify this section -->
|
||||
<!-- prettier-ignore-start -->
|
||||
<!-- markdownlint-disable -->
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/34j"><img src="https://avatars.githubusercontent.com/u/55338215?v=4?s=80" width="80px;" alt="34j"/><br /><sub><b>34j</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Code">💻</a> <a href="#ideas-34j" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Documentation">📖</a> <a href="#example-34j" title="Examples">💡</a> <a href="#infra-34j" title="Infrastructure (Hosting, Build-Tools, etc)">🚇</a> <a href="#maintenance-34j" title="Maintenance">🚧</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/pulls?q=is%3Apr+reviewed-by%3A34j" title="Reviewed Pull Requests">👀</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=34j" title="Tests">⚠️</a> <a href="#tutorial-34j" title="Tutorials">✅</a> <a href="#promotion-34j" title="Promotion">📣</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3A34j" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/GarrettConway"><img src="https://avatars.githubusercontent.com/u/22782004?v=4?s=80" width="80px;" alt="GarrettConway"/><br /><sub><b>GarrettConway</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=GarrettConway" title="Code">💻</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AGarrettConway" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=GarrettConway" title="Documentation">📖</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/pulls?q=is%3Apr+reviewed-by%3AGarrettConway" title="Reviewed Pull Requests">👀</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/BlueAmulet"><img src="https://avatars.githubusercontent.com/u/43395286?v=4?s=80" width="80px;" alt="BlueAmulet"/><br /><sub><b>BlueAmulet</b></sub></a><br /><a href="#ideas-BlueAmulet" title="Ideas, Planning, & Feedback">🤔</a> <a href="#question-BlueAmulet" title="Answering Questions">💬</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=BlueAmulet" title="Code">💻</a> <a href="#maintenance-BlueAmulet" title="Maintenance">🚧</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ThrowawayAccount01"><img src="https://avatars.githubusercontent.com/u/125531852?v=4?s=80" width="80px;" alt="ThrowawayAccount01"/><br /><sub><b>ThrowawayAccount01</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AThrowawayAccount01" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/MashiroSA"><img src="https://avatars.githubusercontent.com/u/40637516?v=4?s=80" width="80px;" alt="緋"/><br /><sub><b>緋</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=MashiroSA" title="Documentation">📖</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AMashiroSA" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Lordmau5"><img src="https://avatars.githubusercontent.com/u/1345036?v=4?s=80" width="80px;" alt="Lordmau5"/><br /><sub><b>Lordmau5</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ALordmau5" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=Lordmau5" title="Code">💻</a> <a href="#ideas-Lordmau5" title="Ideas, Planning, & Feedback">🤔</a> <a href="#maintenance-Lordmau5" title="Maintenance">🚧</a> <a href="#question-Lordmau5" title="Answering Questions">💬</a> <a href="#userTesting-Lordmau5" title="User Testing">📓</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/DL909"><img src="https://avatars.githubusercontent.com/u/71912115?v=4?s=80" width="80px;" alt="DL909"/><br /><sub><b>DL909</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADL909" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Satisfy256"><img src="https://avatars.githubusercontent.com/u/101394399?v=4?s=80" width="80px;" alt="Satisfy256"/><br /><sub><b>Satisfy256</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ASatisfy256" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/pierluigizagaria"><img src="https://avatars.githubusercontent.com/u/57801386?v=4?s=80" width="80px;" alt="Pierluigi Zagaria"/><br /><sub><b>Pierluigi Zagaria</b></sub></a><br /><a href="#userTesting-pierluigizagaria" title="User Testing">📓</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ruckusmattster"><img src="https://avatars.githubusercontent.com/u/77196088?v=4?s=80" width="80px;" alt="ruckusmattster"/><br /><sub><b>ruckusmattster</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aruckusmattster" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Desuka-art"><img src="https://avatars.githubusercontent.com/u/111822082?v=4?s=80" width="80px;" alt="Desuka-art"/><br /><sub><b>Desuka-art</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADesuka-art" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/heyfixit"><img src="https://avatars.githubusercontent.com/u/41658450?v=4?s=80" width="80px;" alt="heyfixit"/><br /><sub><b>heyfixit</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=heyfixit" title="Documentation">📖</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://www.youtube.com/c/NerdyRodent"><img src="https://avatars.githubusercontent.com/u/74688049?v=4?s=80" width="80px;" alt="Nerdy Rodent"/><br /><sub><b>Nerdy Rodent</b></sub></a><br /><a href="#video-nerdyrodent" title="Videos">📹</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/xieyumc"><img src="https://avatars.githubusercontent.com/u/47858007?v=4?s=80" width="80px;" alt="谢宇"/><br /><sub><b>谢宇</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=xieyumc" title="Documentation">📖</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ColdCawfee"><img src="https://avatars.githubusercontent.com/u/79474598?v=4?s=80" width="80px;" alt="ColdCawfee"/><br /><sub><b>ColdCawfee</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AColdCawfee" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/sbersier"><img src="https://avatars.githubusercontent.com/u/34165937?v=4?s=80" width="80px;" alt="sbersier"/><br /><sub><b>sbersier</b></sub></a><br /><a href="#ideas-sbersier" title="Ideas, Planning, & Feedback">🤔</a> <a href="#userTesting-sbersier" title="User Testing">📓</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Asbersier" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Meldoner"><img src="https://avatars.githubusercontent.com/u/43951115?v=4?s=80" width="80px;" alt="Meldoner"/><br /><sub><b>Meldoner</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AMeldoner" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/mmodeusher"><img src="https://avatars.githubusercontent.com/u/46575920?v=4?s=80" width="80px;" alt="mmodeusher"/><br /><sub><b>mmodeusher</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Ammodeusher" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/AlonDan"><img src="https://avatars.githubusercontent.com/u/21152334?v=4?s=80" width="80px;" alt="AlonDan"/><br /><sub><b>AlonDan</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AAlonDan" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Likkkez"><img src="https://avatars.githubusercontent.com/u/44336181?v=4?s=80" width="80px;" alt="Likkkez"/><br /><sub><b>Likkkez</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ALikkkez" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/DuctTapeGames"><img src="https://avatars.githubusercontent.com/u/84365142?v=4?s=80" width="80px;" alt="Duct Tape Games"/><br /><sub><b>Duct Tape Games</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ADuctTapeGames" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://tec.hxlxz.com/"><img src="https://avatars.githubusercontent.com/u/6624983?v=4?s=80" width="80px;" alt="Xianglong He"/><br /><sub><b>Xianglong He</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Ahxl9654" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/75aosu"><img src="https://avatars.githubusercontent.com/u/79185331?v=4?s=80" width="80px;" alt="75aosu"/><br /><sub><b>75aosu</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3A75aosu" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/tonyco82"><img src="https://avatars.githubusercontent.com/u/56610534?v=4?s=80" width="80px;" alt="tonyco82"/><br /><sub><b>tonyco82</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Atonyco82" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/yxlllc"><img src="https://avatars.githubusercontent.com/u/33565655?v=4?s=80" width="80px;" alt="yxlllc"/><br /><sub><b>yxlllc</b></sub></a><br /><a href="#ideas-yxlllc" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=yxlllc" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/outhipped"><img src="https://avatars.githubusercontent.com/u/116147475?v=4?s=80" width="80px;" alt="outhipped"/><br /><sub><b>outhipped</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aouthipped" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/escoolioinglesias"><img src="https://avatars.githubusercontent.com/u/73505402?v=4?s=80" width="80px;" alt="escoolioinglesias"/><br /><sub><b>escoolioinglesias</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aescoolioinglesias" title="Bug reports">🐛</a> <a href="#userTesting-escoolioinglesias" title="User Testing">📓</a> <a href="#video-escoolioinglesias" title="Videos">📹</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/Blacksingh"><img src="https://avatars.githubusercontent.com/u/130872856?v=4?s=80" width="80px;" alt="Blacksingh"/><br /><sub><b>Blacksingh</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3ABlacksingh" title="Bug reports">🐛</a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center" valign="top" width="14.28%"><a href="http://tybantarnusa.com"><img src="https://avatars.githubusercontent.com/u/9532857?v=4?s=80" width="80px;" alt="Mgs. M. Thoyib Antarnusa"/><br /><sub><b>Mgs. M. Thoyib Antarnusa</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Atybantarnusa" title="Bug reports">🐛</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/ZeroHackz"><img src="https://avatars.githubusercontent.com/u/15729496?v=4?s=80" width="80px;" alt="Exosfeer"/><br /><sub><b>Exosfeer</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3AZeroHackz" title="Bug reports">🐛</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=ZeroHackz" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/guranon"><img src="https://avatars.githubusercontent.com/u/130421189?v=4?s=80" width="80px;" alt="guranon"/><br /><sub><b>guranon</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/issues?q=author%3Aguranon" title="Bug reports">🐛</a> <a href="#ideas-guranon" title="Ideas, Planning, & Feedback">🤔</a> <a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=guranon" title="Code">💻</a></td>
|
||||
<td align="center" valign="top" width="14.28%"><a href="https://github.com/alexanderkoumis"><img src="https://avatars.githubusercontent.com/u/5108856?v=4?s=80" width="80px;" alt="Alexander Koumis"/><br /><sub><b>Alexander Koumis</b></sub></a><br /><a href="https://github.com/voicepaw/so-vits-svc-fork/commits?author=alexanderkoumis" title="Code">💻</a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
<!-- markdownlint-restore -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
<!-- ALL-CONTRIBUTORS-LIST:END -->
|
||||
<!-- prettier-ignore-end -->
|
||||
|
||||
This project follows the [all-contributors](https://github.com/all-contributors/all-contributors) specification. Contributions of any kind welcome!
|
||||
@@ -0,0 +1,8 @@
|
||||
module.exports = {
|
||||
extends: ["@commitlint/config-conventional"],
|
||||
rules: {
|
||||
"header-max-length": [0, "always", Infinity],
|
||||
"body-max-line-length": [0, "always", Infinity],
|
||||
"footer-max-line-length": [0, "always", Infinity],
|
||||
},
|
||||
};
|
||||
@@ -0,0 +1,20 @@
|
||||
# Minimal makefile for Sphinx documentation
|
||||
#
|
||||
|
||||
# You can set these variables from the command line, and also
|
||||
# from the environment for the first two.
|
||||
SPHINXOPTS ?=
|
||||
SPHINXBUILD ?= sphinx-build
|
||||
SOURCEDIR = .
|
||||
BUILDDIR = _build
|
||||
|
||||
# Put it first so that "make" without argument is like "make help".
|
||||
help:
|
||||
@$(SPHINXBUILD) -M help "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
|
||||
|
||||
.PHONY: help Makefile
|
||||
|
||||
# Catch-all target: route all unknown targets to Sphinx using the new
|
||||
# "make mode" option. $(O) is meant as a shortcut for $(SPHINXOPTS).
|
||||
%: Makefile
|
||||
@$(SPHINXBUILD) -M $@ "$(SOURCEDIR)" "$(BUILDDIR)" $(SPHINXOPTS) $(O)
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 83 KiB |
@@ -0,0 +1,3 @@
|
||||
```{include} ../CHANGELOG.md
|
||||
|
||||
```
|
||||
@@ -0,0 +1,78 @@
|
||||
# Configuration file for the Sphinx documentation builder.
|
||||
#
|
||||
# This file only contains a selection of the most common options. For a full
|
||||
# list see the documentation:
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from sphinx.application import Sphinx
|
||||
from sphinx.ext import apidoc
|
||||
|
||||
# -- Project information -----------------------------------------------------
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html#project-information
|
||||
|
||||
project = "SoftVC VITS Singing Voice Conversion Fork"
|
||||
copyright = "2023, 34j"
|
||||
author = "34j"
|
||||
release = "0.0.0"
|
||||
|
||||
# -- General configuration ---------------------------------------------------
|
||||
# https://www.sphinx-doc.org/en/master/usage/configuration.html#general-configuration
|
||||
|
||||
# Add any Sphinx extension module names here, as strings. They can be
|
||||
# extensions coming with Sphinx (named 'sphinx.ext.*') or your custom
|
||||
# ones.
|
||||
extensions = [
|
||||
"myst_parser",
|
||||
"sphinx.ext.napoleon",
|
||||
"sphinx.ext.autodoc",
|
||||
"sphinx.ext.viewcode",
|
||||
]
|
||||
napoleon_google_docstring = False
|
||||
|
||||
# The suffix of source filenames.
|
||||
source_suffix = [".rst", ".md"]
|
||||
|
||||
# Add any paths that contain templates here, relative to this directory.
|
||||
templates_path = ["_templates"]
|
||||
|
||||
# List of patterns, relative to source directory, that match files and
|
||||
# directories to ignore when looking for source files.
|
||||
# This pattern also affects html_static_path and html_extra_path.
|
||||
exclude_patterns: list[str] = []
|
||||
|
||||
|
||||
# -- Options for HTML output -------------------------------------------------
|
||||
|
||||
# The theme to use for HTML and HTML Help pages. See the documentation for
|
||||
# a list of builtin themes.
|
||||
#
|
||||
html_theme = "sphinx_rtd_theme"
|
||||
|
||||
# Add any paths that contain custom static files (such as style sheets) here,
|
||||
# relative to this directory. They are copied after the builtin static files,
|
||||
# so a file named "default.css" will overwrite the builtin "default.css".
|
||||
html_static_path = ["_static"]
|
||||
|
||||
|
||||
# -- Automatically run sphinx-apidoc -----------------------------------------
|
||||
|
||||
|
||||
def run_apidoc(_: Any) -> None:
|
||||
docs_path = Path(__file__).parent
|
||||
module_path = docs_path.parent / "src" / "so_vits_svc_fork"
|
||||
|
||||
apidoc.main(
|
||||
[
|
||||
"--force",
|
||||
"--module-first",
|
||||
"-o",
|
||||
docs_path.as_posix(),
|
||||
module_path.as_posix(),
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
def setup(app: Sphinx) -> None:
|
||||
app.connect("builder-inited", run_apidoc)
|
||||
@@ -0,0 +1,3 @@
|
||||
```{include} ../CONTRIBUTING.md
|
||||
|
||||
```
|
||||
@@ -0,0 +1,28 @@
|
||||
# Welcome to SoftVC VITS Singing Voice Conversion Fork documentation!
|
||||
|
||||
```{toctree}
|
||||
:caption: Installation & Usage
|
||||
:maxdepth: 2
|
||||
|
||||
installation
|
||||
usage
|
||||
```
|
||||
|
||||
```{toctree}
|
||||
:caption: Project Info
|
||||
:maxdepth: 2
|
||||
|
||||
changelog
|
||||
contributing
|
||||
```
|
||||
|
||||
```{toctree}
|
||||
:caption: API Reference
|
||||
:maxdepth: 2
|
||||
|
||||
so_vits_svc_fork
|
||||
```
|
||||
|
||||
```{include} ../README.md
|
||||
|
||||
```
|
||||
@@ -0,0 +1,7 @@
|
||||
# Installation
|
||||
|
||||
The package is published on [PyPI](https://pypi.org/project/so-vits-svc-fork/) and can be installed with `pip` (or any equivalent):
|
||||
|
||||
```bash
|
||||
pip install so-vits-svc-fork
|
||||
```
|
||||
@@ -0,0 +1,35 @@
|
||||
@ECHO OFF
|
||||
|
||||
pushd %~dp0
|
||||
|
||||
REM Command file for Sphinx documentation
|
||||
|
||||
if "%SPHINXBUILD%" == "" (
|
||||
set SPHINXBUILD=sphinx-build
|
||||
)
|
||||
set SOURCEDIR=.
|
||||
set BUILDDIR=_build
|
||||
|
||||
%SPHINXBUILD% >NUL 2>NUL
|
||||
if errorlevel 9009 (
|
||||
echo.
|
||||
echo.The 'sphinx-build' command was not found. Make sure you have Sphinx
|
||||
echo.installed, then set the SPHINXBUILD environment variable to point
|
||||
echo.to the full path of the 'sphinx-build' executable. Alternatively you
|
||||
echo.may add the Sphinx directory to PATH.
|
||||
echo.
|
||||
echo.If you don't have Sphinx installed, grab it from
|
||||
echo.https://www.sphinx-doc.org/
|
||||
exit /b 1
|
||||
)
|
||||
|
||||
if "%1" == "" goto help
|
||||
|
||||
%SPHINXBUILD% -M %1 %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
|
||||
goto end
|
||||
|
||||
:help
|
||||
%SPHINXBUILD% -M help %SOURCEDIR% %BUILDDIR% %SPHINXOPTS% %O%
|
||||
|
||||
:end
|
||||
popd
|
||||
@@ -0,0 +1,9 @@
|
||||
# Usage
|
||||
|
||||
To use this package, import it:
|
||||
|
||||
```python
|
||||
import so_vits_svc_fork
|
||||
```
|
||||
|
||||
TODO: Document usage
|
||||
@@ -0,0 +1,101 @@
|
||||
@echo off
|
||||
|
||||
echo 本bat汉化基于英文版,对原版进行了一些本地工作和优化,如安装过程有问题,可以尝试安装原版
|
||||
echo.
|
||||
|
||||
echo.
|
||||
echo 检查 Python 版本 3.10...
|
||||
echo.
|
||||
|
||||
py -3.10 --version >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo Python 3.10 已经安装
|
||||
echo.
|
||||
) else (
|
||||
echo Python 3.10 未安装,开始下载...
|
||||
echo.
|
||||
curl https://www.python.org/ftp/python/3.10.10/python-3.10.10-amd64.exe -o python-3.10.10-amd64.exe
|
||||
|
||||
echo 安装 Python 3.10...
|
||||
echo.
|
||||
python-3.10.10-amd64.exe /quiet InstallAllUsers=1 PrependPath=1
|
||||
|
||||
echo 清理安装器...
|
||||
echo.
|
||||
del python-3.10.10-amd64.exe
|
||||
)
|
||||
echo.
|
||||
echo 检查 GPU...
|
||||
echo.
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo 找到可用GPU
|
||||
echo.
|
||||
) else (
|
||||
echo 未找到可用found
|
||||
echo.
|
||||
)
|
||||
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
|
||||
echo.
|
||||
echo 检查CUDA...
|
||||
echo.
|
||||
|
||||
if %errorlevel%==0 (
|
||||
echo CUDA 已经安装
|
||||
echo.
|
||||
) else (
|
||||
echo 未检测到CUDA,请从下面链接手动安装CUDA,安装后再重新运行本程序
|
||||
echo https://developer.nvidia.com/cuda-11-8-0-download-archive?target_os=Windows
|
||||
echo.
|
||||
echo 如果你已经确定安装了CUDA,可能是程序检测出错,可以按任意键强制继续执行,否则请关闭本程序,安装好CUDA后再重新运行
|
||||
echo.
|
||||
Pause
|
||||
)
|
||||
|
||||
echo 检查 cuDNN...
|
||||
if exist "C:\Program Files\NVIDIA GPU Computing Toolkit\CUDA\v11.8\bin\cudnn64_8.dll" (
|
||||
echo cuDNN 已经安装
|
||||
echo.
|
||||
) else (
|
||||
echo 未检测到cuDNN,请从下面链接手动安装CUDA,安装后再重新运行本程序
|
||||
echo https://developer.nvidia.com/cudnn (https://developer.nvidia.com/downloads/compute/cudnn/secure/8.8.1/local_installers/11.8/cudnn-windows-x86_64-8.8.1.3_cuda11-archive.zip/)
|
||||
echo.
|
||||
echo 如果你已经确定安装了cuDNN,可能是程序检测出错,可以按任意键强制继续执行,否则请关闭本程序,安装好CUDA后再重新运行
|
||||
echo.
|
||||
Pause
|
||||
)
|
||||
)
|
||||
echo.
|
||||
echo 正在创建虚拟环境(需要一点时间,请耐心等待)...
|
||||
echo.
|
||||
py -3.10 -m venv venv
|
||||
echo.
|
||||
echo 升级 pip 和 wheel...
|
||||
echo.
|
||||
venv\Scripts\python.exe -m pip install --upgrade pip wheel
|
||||
echo.
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo 安装 PyTorch (GPU版本)...
|
||||
echo.
|
||||
venv\Scripts\pip.exe install torch torchvision torchaudio --index-url https://mirror.sjtu.edu.cn/pytorch-wheels
|
||||
echo 安装 PyTorch (CPU版本)...
|
||||
echo.
|
||||
venv\Scripts\pip.exe install torch torchaudio -i https://pypi.tuna.tsinghua.edu.cn/simple pyspider
|
||||
)
|
||||
echo.
|
||||
echo 请检查以上包是否都成功安装,确定成功安装后,按任意键开始安装so-vits-svc-fork
|
||||
echo.
|
||||
Pause
|
||||
echo 安装 so-vits-svc-fork...
|
||||
echo.
|
||||
venv\Scripts\pip.exe install so-vits-svc-fork
|
||||
echo.
|
||||
echo 启动 so-vits-svc-fork 图形化界面...
|
||||
echo.
|
||||
venv\Scripts\svcg.exe
|
||||
|
||||
Pause
|
||||
@@ -0,0 +1,70 @@
|
||||
@echo off
|
||||
|
||||
echo Checking for Python 3.10...
|
||||
|
||||
py -3.10 --version >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo Python 3.10 is already installed.
|
||||
) else (
|
||||
echo Python 3.10 is not installed. Downloading installer...
|
||||
curl https://www.python.org/ftp/python/3.10.10/python-3.10.10-amd64.exe -o python-3.10.10-amd64.exe
|
||||
|
||||
echo Installing Python 3.10...
|
||||
python-3.10.10-amd64.exe /quiet InstallAllUsers=1 PrependPath=1
|
||||
|
||||
echo Cleaning up installer...
|
||||
del python-3.10.10-amd64.exe
|
||||
)
|
||||
|
||||
echo Checking GPU...
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo found a GPU
|
||||
) else (
|
||||
echo no GPU found
|
||||
)
|
||||
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo Checking CUDA...
|
||||
nvcc --version
|
||||
if %errorlevel%==0 (
|
||||
echo CUDA is already installed.
|
||||
) else (
|
||||
echo CUDA is not installed.
|
||||
echo Please install CUDA 11.7 from https://developer.nvidia.com/cuda-11-8-0-download-archive?target_os=Windows
|
||||
echo If you are sure it is already installed and added to path, press any key to force the installation to continue
|
||||
Pause
|
||||
)
|
||||
|
||||
echo Checking cuDNN...
|
||||
if exist "C:\Program Files\NVIDIA GPU Computing Toolkit\CUDA\v11.8\bin\cudnn64_8.dll" (
|
||||
echo cuDNN is already installed.
|
||||
) else (
|
||||
echo cuDNN is not installed.
|
||||
echo Please install cuDNN 11.8 from https://developer.nvidia.com/cudnn (https://developer.nvidia.com/downloads/compute/cudnn/secure/8.8.1/local_installers/11.8/cudnn-windows-x86_64-8.8.1.3_cuda11-archive.zip/)
|
||||
echo If you are sure it is already installed and added to path, press any key to force the installation to continue
|
||||
Pause
|
||||
)
|
||||
)
|
||||
|
||||
echo Creating virtual environment...
|
||||
py -3.10 -m venv venv
|
||||
|
||||
echo Updating pip and wheel...
|
||||
venv\Scripts\python.exe -m pip install --upgrade pip wheel
|
||||
|
||||
nvidia-smi >nul 2>&1
|
||||
if %errorlevel%==0 (
|
||||
echo Installing PyTorch with GPU support...
|
||||
venv\Scripts\pip.exe install torch torchaudio --index-url https://download.pytorch.org/whl/cu118
|
||||
) else (
|
||||
echo Installing PyTorch without GPU support...
|
||||
venv\Scripts\pip.exe install torch torchaudio
|
||||
)
|
||||
|
||||
echo Installing so-vits-svc-fork...
|
||||
venv\Scripts\pip.exe install so-vits-svc-fork
|
||||
|
||||
echo Launching so-vits-svc-fork GUI...
|
||||
venv\Scripts\svcg.exe
|
||||
@@ -0,0 +1,315 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Before training\n",
|
||||
"\n",
|
||||
"This program saves the last 3 generations of models to Google Drive. Since 1 generation of models is >1GB, you should have at least 3GB of free space in Google Drive. If you do not have such free space, it is recommended to create another Google Account.\n",
|
||||
"\n",
|
||||
"Training requires >10GB VRAM. (T4 should be enough) Inference does not require such a lot of VRAM."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Installation"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Check GPU\n",
|
||||
"!nvidia-smi"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Mount Google Drive\n",
|
||||
"from google.colab import drive\n",
|
||||
"drive.mount('/content/drive')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Install dependencies\n",
|
||||
"#@markdown pip may fail to resolve dependencies and raise ERROR, but it can be ignored.\n",
|
||||
"!python -m pip install -U pip wheel\n",
|
||||
"%pip install -U ipython \n",
|
||||
"\n",
|
||||
"#@markdown Branch (for development)\n",
|
||||
"BRANCH = \"none\" #@param {\"type\": \"string\"}\n",
|
||||
"if BRANCH == \"none\":\n",
|
||||
" %pip install -U so-vits-svc-fork\n",
|
||||
"else:\n",
|
||||
" %pip install -U git+https://github.com/34j/so-vits-svc-fork.git@{BRANCH}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Training"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Make dataset directory\n",
|
||||
"!mkdir -p \"dataset_raw\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#!rm -r \"dataset_raw\"\n",
|
||||
"#!rm -r \"dataset/44k\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Copy your dataset\n",
|
||||
"#@markdown **We assume that your dataset is in your Google Drive's `so-vits-svc-fork/dataset/(speaker_name)` directory.**\n",
|
||||
"DATASET_NAME = \"kiritan\" #@param {type: \"string\"}\n",
|
||||
"!cp -R /content/drive/MyDrive/so-vits-svc-fork/dataset/{DATASET_NAME}/ -t \"dataset_raw/\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Download dataset (Tsukuyomi-chan JVS)\n",
|
||||
"#@markdown You can download this dataset if you don't have your own dataset.\n",
|
||||
"#@markdown Make sure you agree to the license when using this dataset.\n",
|
||||
"#@markdown https://tyc.rei-yumesaki.net/material/corpus/#toc6\n",
|
||||
"# !wget https://tyc.rei-yumesaki.net/files/sozai-tyc-corpus1.zip\n",
|
||||
"# !unzip sozai-tyc-corpus1.zip\n",
|
||||
"# !mv \"/content/つくよみちゃんコーパス Vol.1 声優統計コーパス(JVSコーパス準拠)/おまけ:WAV(+12dB増幅&高音域削減)/WAV(+12dB増幅&高音域削減)\" \"dataset_raw/tsukuyomi\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Automatic preprocessing\n",
|
||||
"!svc pre-resample"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc pre-config"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Copy configs file\n",
|
||||
"!cp configs/44k/config.json drive/MyDrive/so-vits-svc-fork"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"F0_METHOD = \"dio\" #@param [\"crepe\", \"crepe-tiny\", \"parselmouth\", \"dio\", \"harvest\"]\n",
|
||||
"!svc pre-hubert -fm {F0_METHOD}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Train\n",
|
||||
"%load_ext tensorboard\n",
|
||||
"%tensorboard --logdir drive/MyDrive/so-vits-svc-fork/logs/44k\n",
|
||||
"!svc train --model-path drive/MyDrive/so-vits-svc-fork/logs/44k"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Training Cluster model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc train-cluster --output-path drive/MyDrive/so-vits-svc-fork/logs/44k/kmeans.pt"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Inference"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Get the author's voice as a source\n",
|
||||
"import random\n",
|
||||
"NAME = str(random.randint(1, 49))\n",
|
||||
"TYPE = \"fsd50k\" #@param [\"\", \"digit\", \"dog\", \"fsd50k\"]\n",
|
||||
"CUSTOM_FILEPATH = \"\" #@param {type: \"string\"}\n",
|
||||
"if CUSTOM_FILEPATH != \"\":\n",
|
||||
" NAME = CUSTOM_FILEPATH\n",
|
||||
"else:\n",
|
||||
" # it is extremely difficult to find a voice that can download from the internet directly\n",
|
||||
" if TYPE == \"dog\":\n",
|
||||
" !wget -N f\"https://huggingface.co/datasets/437aewuh/dog-dataset/resolve/main/dogs/dogs_{NAME:.0000}.wav\" -O {NAME}.wav\n",
|
||||
" elif TYPE == \"digit\":\n",
|
||||
" # george, jackson, lucas, nicolas, ...\n",
|
||||
" !wget -N f\"https://github.com/Jakobovski/free-spoken-digit-dataset/raw/master/recordings/0_george_{NAME}.wav\" -O {NAME}.wav\n",
|
||||
" elif TYPE == \"fsd50k\":\n",
|
||||
" !wget -N f\"https://huggingface.co/datasets/Fhrozen/FSD50k/blob/main/clips/dev/{10000+int(NAME)}.wav\" -O {NAME}.wav\n",
|
||||
" else:\n",
|
||||
" !wget -N f\"https://zunko.jp/sozai/utau/voice_{\"kiritan\" if NAME < 25 else \"itako\"}{NAME % 5 + 1}.wav\" -O {NAME}.wav\n",
|
||||
"from IPython.display import Audio, display\n",
|
||||
"display(Audio(f\"{NAME}.wav\"))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title Use trained model\n",
|
||||
"#@markdown **Put your .wav file in `so-vits-svc-fork/audio` directory**\n",
|
||||
"from IPython.display import Audio, display\n",
|
||||
"!svc infer drive/MyDrive/so-vits-svc-fork/audio/{NAME}.wav -m drive/MyDrive/so-vits-svc-fork/logs/44k/ -c drive/MyDrive/so-vits-svc-fork/logs/44k/config.json\n",
|
||||
"display(Audio(f\"drive/MyDrive/so-vits-svc-fork/audio/{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"##@title Use trained model (with cluster)\n",
|
||||
"!svc infer {NAME}.wav -s speaker -r 0.1 -m drive/MyDrive/so-vits-svc-fork/logs/44k/ -c drive/MyDrive/so-vits-svc-fork/logs/44k/config.json -k drive/MyDrive/so-vits-svc-fork/logs/44k/kmeans.pt\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Pretrained models"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/tree/main\n",
|
||||
"!wget -N \"https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/resolve/main/riri/G_riri_220.pth\"\n",
|
||||
"!wget -N \"https://huggingface.co/TachibanaKimika/so-vits-svc-4.0-models/resolve/main/riri/config.json\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc infer {NAME}.wav -c config.json -m G_riri_220.pth\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"#@title https://huggingface.co/therealvul/so-vits-svc-4.0/tree/main\n",
|
||||
"!wget -N \"https://huggingface.co/therealvul/so-vits-svc-4.0/resolve/main/Pinkie%20(speaking%20sep)/G_166400.pth\"\n",
|
||||
"!wget -N \"https://huggingface.co/therealvul/so-vits-svc-4.0/resolve/main/Pinkie%20(speaking%20sep)/config.json\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!svc infer {NAME}.wav --speaker \"Pinkie {neutral}\" -c config.json -m G_166400.pth\n",
|
||||
"display(Audio(f\"{NAME}.out.wav\", autoplay=True))"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"accelerator": "GPU",
|
||||
"colab": {
|
||||
"provenance": []
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
+5209
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,130 @@
|
||||
[tool.poetry]
|
||||
name = "so-vits-svc-fork"
|
||||
version = "3.12.1"
|
||||
description = "A fork of so-vits-svc."
|
||||
authors = ["34j <34j.95a2p@simplelogin.com>"]
|
||||
license = "MIT"
|
||||
#readme = "README.md"
|
||||
repository = "https://github.com/34j/so-vits-svc-fork"
|
||||
documentation = "https://so-vits-svc-fork.readthedocs.io"
|
||||
classifiers = [
|
||||
"Development Status :: 2 - Pre-Alpha",
|
||||
"Intended Audience :: Developers",
|
||||
"Natural Language :: English",
|
||||
"Operating System :: OS Independent",
|
||||
"Topic :: Software Development :: Libraries",
|
||||
]
|
||||
packages = [
|
||||
{ include = "so_vits_svc_fork", from = "src" },
|
||||
]
|
||||
|
||||
[tool.poetry.scripts]
|
||||
so-vits-svc-fork = "so_vits_svc_fork.__main__:cli"
|
||||
svc = "so_vits_svc_fork.__main__:cli"
|
||||
svcf = "so_vits_svc_fork.__main__:cli"
|
||||
svcg = "so_vits_svc_fork.gui:main"
|
||||
svc-gui = "so_vits_svc_fork.gui:main"
|
||||
svcf-gui = "so_vits_svc_fork.gui:main"
|
||||
|
||||
[tool.poetry.urls]
|
||||
"Bug Tracker" = "https://github.com/34j/so-vits-svc-fork/issues"
|
||||
"Changelog" = "https://github.com/34j/so-vits-svc-fork/blob/main/CHANGELOG.md"
|
||||
|
||||
[tool.poetry.dependencies]
|
||||
python = ">=3.8,<3.11"
|
||||
librosa = "0.9.1"
|
||||
numpy = "1.23.5"
|
||||
pydub = "0.25.1"
|
||||
pyworld = "0.2.12"
|
||||
scipy = "1.8.0"
|
||||
tqdm = "4.65.0"
|
||||
scikit-maad = "1.3.12"
|
||||
onnx = "1.13.1"
|
||||
onnxsim = "0.4.28"
|
||||
onnxoptimizer = "0.3.10"
|
||||
torch = "1.13.1"
|
||||
torchaudio = "0.13.1"
|
||||
tensorboard = "2.12.0"
|
||||
rich = "13.3.5"
|
||||
tqdm-joblib = "0.0.3"
|
||||
tensorboardx = "2.6"
|
||||
pyinputplus = "0.2.12"
|
||||
cm-time = "0.1.2"
|
||||
pysimplegui = "4.60.4"
|
||||
pebble = "5.0.3"
|
||||
torchcrepe = "0.0.18"
|
||||
lightning = "2.0.2"
|
||||
transformers = "^4.28.1"
|
||||
matplotlib = "3.7.1"
|
||||
|
||||
[tool.poetry.group.dev.dependencies]
|
||||
pre-commit = ">=3"
|
||||
pytest = "^7.0"
|
||||
pytest-cov = "^4.0.0"
|
||||
|
||||
[tool.poetry.group.docs]
|
||||
optional = true
|
||||
|
||||
[tool.poetry.group.docs.dependencies]
|
||||
myst-parser = ">=0.16"
|
||||
sphinx = ">=4.0"
|
||||
sphinx-rtd-theme = ">=1.0"
|
||||
|
||||
[tool.semantic_release]
|
||||
branch = "main"
|
||||
version_toml = "pyproject.toml:tool.poetry.version"
|
||||
version_variable = "src/so_vits_svc_fork/__init__.py:__version__"
|
||||
build_command = "pip install poetry && poetry build"
|
||||
|
||||
[tool.pytest.ini_options]
|
||||
addopts = "-v -Wdefault --cov=so_vits_svc_fork --cov-report=term-missing:skip-covered"
|
||||
pythonpath = ["src"]
|
||||
|
||||
[tool.coverage.run]
|
||||
branch = true
|
||||
|
||||
[tool.coverage.report]
|
||||
exclude_lines = [
|
||||
"pragma: no cover",
|
||||
"@overload",
|
||||
"if TYPE_CHECKING",
|
||||
"raise NotImplementedError",
|
||||
'if __name__ == "__main__":',
|
||||
]
|
||||
|
||||
[tool.isort]
|
||||
profile = "black"
|
||||
known_first_party = ["so_vits_svc_fork", "tests"]
|
||||
|
||||
[tool.autoflake]
|
||||
remove_all_unused_imports = true
|
||||
|
||||
[tool.mypy]
|
||||
check_untyped_defs = true
|
||||
disallow_any_generics = true
|
||||
disallow_incomplete_defs = true
|
||||
disallow_untyped_defs = true
|
||||
mypy_path = "src/"
|
||||
no_implicit_optional = true
|
||||
show_error_codes = true
|
||||
warn_unreachable = true
|
||||
warn_unused_ignores = true
|
||||
exclude = [
|
||||
'docs/.*',
|
||||
'setup.py',
|
||||
]
|
||||
|
||||
[[tool.mypy.overrides]]
|
||||
module = "tests.*"
|
||||
allow_untyped_defs = true
|
||||
|
||||
[[tool.mypy.overrides]]
|
||||
module = "docs.*"
|
||||
ignore_errors = true
|
||||
|
||||
[tool.bandit]
|
||||
exclude_dirs = ["src"]
|
||||
|
||||
[build-system]
|
||||
requires = ["poetry-core>=1.0.0"]
|
||||
build-backend = "poetry.core.masonry.api"
|
||||
@@ -0,0 +1,3 @@
|
||||
{
|
||||
"extends": ["github>browniebroke/renovate-configs:python"]
|
||||
}
|
||||
@@ -0,0 +1,24 @@
|
||||
librosa = "0.9.1"
|
||||
numpy = "1.23.5"
|
||||
pydub = "0.25.1"
|
||||
pyworld = "0.2.12"
|
||||
scipy = "1.8.0"
|
||||
tqdm = "4.65.0"
|
||||
scikit-maad = "1.3.12"
|
||||
onnx = "1.13.1"
|
||||
onnxsim = "0.4.28"
|
||||
onnxoptimizer = "0.3.10"
|
||||
torch = "1.13.1"
|
||||
torchaudio = "0.13.1"
|
||||
tensorboard = "2.12.0"
|
||||
rich = "13.3.5"
|
||||
tqdm-joblib = "0.0.3"
|
||||
tensorboardx = "2.6"
|
||||
pyinputplus = "0.2.12"
|
||||
cm-time = "0.1.2"
|
||||
pysimplegui = "4.60.4"
|
||||
pebble = "5.0.3"
|
||||
torchcrepe = "0.0.18"
|
||||
lightning = "2.0.2"
|
||||
transformers = "4.28.1"
|
||||
matplotlib = "3.7.1"
|
||||
@@ -0,0 +1,9 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
# This is a shim to allow GitHub to detect the package, build is done with poetry
|
||||
# Taken from https://github.com/Textualize/rich
|
||||
|
||||
import setuptools
|
||||
|
||||
if __name__ == "__main__":
|
||||
setuptools.setup(name="so-vits-svc-fork")
|
||||
@@ -0,0 +1,5 @@
|
||||
__version__ = "3.12.1"
|
||||
|
||||
from .logger import init_logger
|
||||
|
||||
init_logger()
|
||||
@@ -0,0 +1,863 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from logging import getLogger
|
||||
from multiprocessing import freeze_support
|
||||
from pathlib import Path
|
||||
from typing import Literal
|
||||
|
||||
import click
|
||||
import pyinputplus as pyip
|
||||
import torch
|
||||
|
||||
from so_vits_svc_fork import __version__
|
||||
from so_vits_svc_fork.utils import get_optimal_device
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
IS_TEST = "test" in Path(__file__).parent.stem
|
||||
if IS_TEST:
|
||||
LOG.debug("Test mode is on.")
|
||||
|
||||
|
||||
class RichHelpFormatter(click.HelpFormatter):
|
||||
def __init__(
|
||||
self,
|
||||
indent_increment: int = 2,
|
||||
width: int | None = None,
|
||||
max_width: int | None = None,
|
||||
) -> None:
|
||||
width = 100
|
||||
super().__init__(indent_increment, width, max_width)
|
||||
LOG.info(f"Version: {__version__}")
|
||||
|
||||
|
||||
def patch_wrap_text():
|
||||
orig_wrap_text = click.formatting.wrap_text
|
||||
|
||||
def wrap_text(
|
||||
text,
|
||||
width=78,
|
||||
initial_indent="",
|
||||
subsequent_indent="",
|
||||
preserve_paragraphs=False,
|
||||
):
|
||||
return orig_wrap_text(
|
||||
text.replace("\n", "\n\n"),
|
||||
width=width,
|
||||
initial_indent=initial_indent,
|
||||
subsequent_indent=subsequent_indent,
|
||||
preserve_paragraphs=True,
|
||||
).replace("\n\n", "\n")
|
||||
|
||||
click.formatting.wrap_text = wrap_text
|
||||
|
||||
|
||||
patch_wrap_text()
|
||||
|
||||
CONTEXT_SETTINGS = dict(help_option_names=["-h", "--help"], show_default=True)
|
||||
click.Context.formatter_class = RichHelpFormatter
|
||||
|
||||
|
||||
@click.group(context_settings=CONTEXT_SETTINGS)
|
||||
def cli():
|
||||
"""so-vits-svc allows any folder structure for training data.
|
||||
However, the following folder structure is recommended.\n
|
||||
When training: dataset_raw/{speaker_name}/**/{wav_name}.{any_format}\n
|
||||
When inference: configs/44k/config.json, logs/44k/G_XXXX.pth\n
|
||||
If the folder structure is followed, you DO NOT NEED TO SPECIFY model path, config path, etc.
|
||||
(The latest model will be automatically loaded.)\n
|
||||
To train a model, run pre-resample, pre-config, pre-hubert, train.\n
|
||||
To infer a model, run infer.
|
||||
"""
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
help="path to config",
|
||||
default=Path("./configs/44k/config.json"),
|
||||
)
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(),
|
||||
help="path to output dir",
|
||||
default=Path("./logs/44k"),
|
||||
)
|
||||
@click.option(
|
||||
"-t/-nt",
|
||||
"--tensorboard/--no-tensorboard",
|
||||
default=False,
|
||||
type=bool,
|
||||
help="launch tensorboard",
|
||||
)
|
||||
@click.option(
|
||||
"-r",
|
||||
"--reset-optimizer",
|
||||
default=False,
|
||||
type=bool,
|
||||
help="reset optimizer",
|
||||
is_flag=True,
|
||||
)
|
||||
def train(
|
||||
config_path: Path,
|
||||
model_path: Path,
|
||||
tensorboard: bool = False,
|
||||
reset_optimizer: bool = False,
|
||||
):
|
||||
"""Train model
|
||||
If D_0.pth or G_0.pth not found, automatically download from hub."""
|
||||
from .train import train
|
||||
|
||||
config_path = Path(config_path)
|
||||
model_path = Path(model_path)
|
||||
|
||||
if tensorboard:
|
||||
import webbrowser
|
||||
|
||||
from tensorboard import program
|
||||
|
||||
getLogger("tensorboard").setLevel(30)
|
||||
tb = program.TensorBoard()
|
||||
tb.configure(argv=[None, "--logdir", model_path.as_posix()])
|
||||
url = tb.launch()
|
||||
webbrowser.open(url)
|
||||
|
||||
train(
|
||||
config_path=config_path, model_path=model_path, reset_optimizer=reset_optimizer
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.argument(
|
||||
"input-path",
|
||||
type=click.Path(exists=True),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./logs/44k/"),
|
||||
help="path to model",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-k",
|
||||
"--cluster-model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=None,
|
||||
help="path to cluster model",
|
||||
)
|
||||
@click.option("-t", "--transpose", type=int, default=0, help="transpose")
|
||||
@click.option(
|
||||
"-db", "--db-thresh", type=int, default=-20, help="threshold (DB) (RELATIVE)"
|
||||
)
|
||||
@click.option(
|
||||
"-fm",
|
||||
"--f0-method",
|
||||
type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
default="dio",
|
||||
help="f0 prediction method",
|
||||
)
|
||||
@click.option(
|
||||
"-a/-na",
|
||||
"--auto-predict-f0/--no-auto-predict-f0",
|
||||
type=bool,
|
||||
default=False,
|
||||
help="auto predict f0",
|
||||
)
|
||||
@click.option(
|
||||
"-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
)
|
||||
@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
@click.option("-p", "--pad-seconds", type=float, default=0.5, help="pad seconds")
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default=get_optimal_device(),
|
||||
help="device",
|
||||
)
|
||||
@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
@click.option(
|
||||
"-ab/-nab",
|
||||
"--absolute-thresh/--no-absolute-thresh",
|
||||
type=bool,
|
||||
default=False,
|
||||
help="absolute thresh",
|
||||
)
|
||||
def infer(
|
||||
# paths
|
||||
input_path: Path,
|
||||
output_path: Path,
|
||||
model_path: Path,
|
||||
config_path: Path,
|
||||
# svc config
|
||||
speaker: str,
|
||||
cluster_model_path: Path | None = None,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
device: str | torch.device = get_optimal_device(),
|
||||
):
|
||||
"""Inference"""
|
||||
from so_vits_svc_fork.inference.main import infer
|
||||
|
||||
if not auto_predict_f0:
|
||||
LOG.warning(
|
||||
f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please set transpose."
|
||||
"Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
)
|
||||
|
||||
input_path = Path(input_path)
|
||||
if output_path is None:
|
||||
output_path = input_path.parent / f"{input_path.stem}.out{input_path.suffix}"
|
||||
output_path = Path(output_path)
|
||||
model_path = Path(model_path)
|
||||
if model_path.is_dir():
|
||||
model_path = list(
|
||||
sorted(model_path.glob("G_*.pth"), key=lambda x: x.stat().st_mtime)
|
||||
)[-1]
|
||||
LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
config_path = Path(config_path)
|
||||
if cluster_model_path is not None:
|
||||
cluster_model_path = Path(cluster_model_path)
|
||||
infer(
|
||||
# paths
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
model_path=model_path,
|
||||
config_path=config_path,
|
||||
# svc config
|
||||
speaker=speaker,
|
||||
cluster_model_path=cluster_model_path,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
# slice config
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=absolute_thresh,
|
||||
device=device,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./logs/44k/"),
|
||||
help="path to model",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-k",
|
||||
"--cluster-model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=None,
|
||||
help="path to cluster model",
|
||||
)
|
||||
@click.option("-t", "--transpose", type=int, default=12, help="transpose")
|
||||
@click.option(
|
||||
"-a/-na",
|
||||
"--auto-predict-f0/--no-auto-predict-f0",
|
||||
type=bool,
|
||||
default=True,
|
||||
help="auto predict f0 (not recommended for realtime since voice pitch will not be stable)",
|
||||
)
|
||||
@click.option(
|
||||
"-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
)
|
||||
@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
@click.option(
|
||||
"-db", "--db-thresh", type=int, default=-30, help="threshold (DB) (ABSOLUTE)"
|
||||
)
|
||||
@click.option(
|
||||
"-fm",
|
||||
"--f0-method",
|
||||
type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
default="dio",
|
||||
help="f0 prediction method",
|
||||
)
|
||||
@click.option("-p", "--pad-seconds", type=float, default=0.02, help="pad seconds")
|
||||
@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
@click.option(
|
||||
"-cr",
|
||||
"--crossfade-seconds",
|
||||
type=float,
|
||||
default=0.01,
|
||||
help="crossfade seconds",
|
||||
)
|
||||
@click.option(
|
||||
"-ab",
|
||||
"--additional-infer-before-seconds",
|
||||
type=float,
|
||||
default=0.2,
|
||||
help="additional infer before seconds",
|
||||
)
|
||||
@click.option(
|
||||
"-aa",
|
||||
"--additional-infer-after-seconds",
|
||||
type=float,
|
||||
default=0.1,
|
||||
help="additional infer after seconds",
|
||||
)
|
||||
@click.option("-b", "--block-seconds", type=float, default=0.5, help="block seconds")
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default=get_optimal_device(),
|
||||
help="device",
|
||||
)
|
||||
@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
@click.option("-v", "--version", type=int, default=2, help="version")
|
||||
@click.option("-i", "--input-device", type=int, default=None, help="input device")
|
||||
@click.option("-o", "--output-device", type=int, default=None, help="output device")
|
||||
@click.option(
|
||||
"-po",
|
||||
"--passthrough-original",
|
||||
type=bool,
|
||||
default=False,
|
||||
is_flag=True,
|
||||
help="passthrough original (for latency check)",
|
||||
)
|
||||
def vc(
|
||||
# paths
|
||||
model_path: Path,
|
||||
config_path: Path,
|
||||
# svc config
|
||||
speaker: str,
|
||||
cluster_model_path: Path | None,
|
||||
transpose: int,
|
||||
auto_predict_f0: bool,
|
||||
cluster_infer_ratio: float,
|
||||
noise_scale: float,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
# slice config
|
||||
db_thresh: int,
|
||||
pad_seconds: float,
|
||||
chunk_seconds: float,
|
||||
# realtime config
|
||||
crossfade_seconds: float,
|
||||
additional_infer_before_seconds: float,
|
||||
additional_infer_after_seconds: float,
|
||||
block_seconds: float,
|
||||
version: int,
|
||||
input_device: int | str | None,
|
||||
output_device: int | str | None,
|
||||
device: torch.device,
|
||||
passthrough_original: bool = False,
|
||||
) -> None:
|
||||
"""Realtime inference from microphone"""
|
||||
from so_vits_svc_fork.inference.main import realtime
|
||||
|
||||
if auto_predict_f0:
|
||||
LOG.warning(
|
||||
"auto_predict_f0 = True in realtime inference will cause unstable voice pitch, use with caution"
|
||||
)
|
||||
else:
|
||||
LOG.warning(
|
||||
f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please change the transpose value."
|
||||
"Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
)
|
||||
model_path = Path(model_path)
|
||||
config_path = Path(config_path)
|
||||
if cluster_model_path is not None:
|
||||
cluster_model_path = Path(cluster_model_path)
|
||||
if model_path.is_dir():
|
||||
model_path = list(
|
||||
sorted(model_path.glob("G_*.pth"), key=lambda x: x.stat().st_mtime)
|
||||
)[-1]
|
||||
LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
|
||||
realtime(
|
||||
# paths
|
||||
model_path=model_path,
|
||||
config_path=config_path,
|
||||
# svc config
|
||||
speaker=speaker,
|
||||
cluster_model_path=cluster_model_path,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
# slice config
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
# realtime config
|
||||
crossfade_seconds=crossfade_seconds,
|
||||
additional_infer_before_seconds=additional_infer_before_seconds,
|
||||
additional_infer_after_seconds=additional_infer_after_seconds,
|
||||
block_seconds=block_seconds,
|
||||
version=version,
|
||||
input_device=input_device,
|
||||
output_device=output_device,
|
||||
device=device,
|
||||
passthrough_original=passthrough_original,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset_raw"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-dir",
|
||||
type=click.Path(),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option("-s", "--sampling-rate", type=int, default=44100, help="sampling rate")
|
||||
@click.option(
|
||||
"-n",
|
||||
"--n-jobs",
|
||||
type=int,
|
||||
default=-1,
|
||||
help="number of jobs (optimal value may depend on your RAM capacity and audio duration per file)",
|
||||
)
|
||||
@click.option("-d", "--top-db", type=float, default=30, help="top db")
|
||||
@click.option("-f", "--frame-seconds", type=float, default=1, help="frame seconds")
|
||||
@click.option(
|
||||
"-ho", "-hop", "--hop-seconds", type=float, default=0.3, help="hop seconds"
|
||||
)
|
||||
def pre_resample(
|
||||
input_dir: Path,
|
||||
output_dir: Path,
|
||||
sampling_rate: int,
|
||||
n_jobs: int,
|
||||
top_db: int,
|
||||
frame_seconds: float,
|
||||
hop_seconds: float,
|
||||
) -> None:
|
||||
"""Preprocessing part 1: resample"""
|
||||
from so_vits_svc_fork.preprocessing.preprocess_resample import preprocess_resample
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
preprocess_resample(
|
||||
input_dir=input_dir,
|
||||
output_dir=output_dir,
|
||||
sampling_rate=sampling_rate,
|
||||
n_jobs=n_jobs,
|
||||
top_db=top_db,
|
||||
frame_seconds=frame_seconds,
|
||||
hop_seconds=hop_seconds,
|
||||
)
|
||||
|
||||
|
||||
from so_vits_svc_fork.preprocessing.preprocess_flist_config import CONFIG_TEMPLATE_DIR
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-f",
|
||||
"--filelist-path",
|
||||
type=click.Path(),
|
||||
default=Path("./filelists/44k"),
|
||||
help="path to filelist dir",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-t",
|
||||
"--config-type",
|
||||
type=click.Choice([x.stem for x in CONFIG_TEMPLATE_DIR.rglob("*.json")]),
|
||||
default="so-vits-svc-4.0v1-legacy",
|
||||
help="config type",
|
||||
)
|
||||
def pre_config(
|
||||
input_dir: Path,
|
||||
filelist_path: Path,
|
||||
config_path: Path,
|
||||
config_type: str,
|
||||
):
|
||||
"""Preprocessing part 2: config"""
|
||||
from so_vits_svc_fork.preprocessing.preprocess_flist_config import preprocess_config
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
filelist_path = Path(filelist_path)
|
||||
config_path = Path(config_path)
|
||||
preprocess_config(
|
||||
input_dir=input_dir,
|
||||
train_list_path=filelist_path / "train.txt",
|
||||
val_list_path=filelist_path / "val.txt",
|
||||
test_list_path=filelist_path / "test.txt",
|
||||
config_path=config_path,
|
||||
config_name=config_type,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset/44k"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
help="path to config",
|
||||
default=Path("./configs/44k/config.json"),
|
||||
)
|
||||
@click.option(
|
||||
"-n",
|
||||
"--n-jobs",
|
||||
type=int,
|
||||
default=None,
|
||||
help="number of jobs (optimal value may depend on your VRAM capacity and audio duration per file)",
|
||||
)
|
||||
@click.option(
|
||||
"-f/-nf",
|
||||
"--force-rebuild/--no-force-rebuild",
|
||||
type=bool,
|
||||
default=True,
|
||||
help="force rebuild existing preprocessed files",
|
||||
)
|
||||
@click.option(
|
||||
"-fm",
|
||||
"--f0-method",
|
||||
type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
default="dio",
|
||||
)
|
||||
def pre_hubert(
|
||||
input_dir: Path,
|
||||
config_path: Path,
|
||||
n_jobs: bool,
|
||||
force_rebuild: bool,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
) -> None:
|
||||
"""Preprocessing part 3: hubert
|
||||
If the HuBERT model is not found, it will be downloaded automatically."""
|
||||
from so_vits_svc_fork.preprocessing.preprocess_hubert_f0 import preprocess_hubert_f0
|
||||
|
||||
input_dir = Path(input_dir)
|
||||
config_path = Path(config_path)
|
||||
preprocess_hubert_f0(
|
||||
input_dir=input_dir,
|
||||
config_path=config_path,
|
||||
n_jobs=n_jobs,
|
||||
force_rebuild=force_rebuild,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset_raw_raw/"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-dir",
|
||||
type=click.Path(),
|
||||
default=Path("./dataset_raw/"),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option(
|
||||
"-n",
|
||||
"--n-jobs",
|
||||
type=int,
|
||||
default=-1,
|
||||
help="number of jobs (optimal value may depend on your VRAM capacity and audio duration per file)",
|
||||
)
|
||||
@click.option("-min", "--min-speakers", type=int, default=2, help="min speakers")
|
||||
@click.option("-max", "--max-speakers", type=int, default=2, help="max speakers")
|
||||
@click.option(
|
||||
"-t", "--huggingface-token", type=str, default=None, help="huggingface token"
|
||||
)
|
||||
@click.option("-s", "--sr", type=int, default=44100, help="sampling rate")
|
||||
def pre_sd(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str,
|
||||
min_speakers: int,
|
||||
max_speakers: int,
|
||||
huggingface_token: str | None,
|
||||
n_jobs: int,
|
||||
sr: int,
|
||||
):
|
||||
"""Speech diarization using pyannote.audio"""
|
||||
if huggingface_token is None:
|
||||
huggingface_token = os.environ.get("HUGGINGFACE_TOKEN", None)
|
||||
if huggingface_token is None:
|
||||
huggingface_token = click.prompt(
|
||||
"Please enter your HuggingFace token", hide_input=True
|
||||
)
|
||||
if os.environ.get("HUGGINGFACE_TOKEN", None) is None:
|
||||
LOG.info("You can also set the HUGGINGFACE_TOKEN environment variable.")
|
||||
assert huggingface_token is not None
|
||||
huggingface_token = huggingface_token.rstrip(" \n\r\t\0")
|
||||
if len(huggingface_token) <= 1:
|
||||
raise ValueError("HuggingFace token is empty: " + huggingface_token)
|
||||
|
||||
if max_speakers == 1:
|
||||
LOG.warning("Consider using pre-split if max_speakers == 1")
|
||||
from so_vits_svc_fork.preprocessing.preprocess_speaker_diarization import (
|
||||
preprocess_speaker_diarization,
|
||||
)
|
||||
|
||||
preprocess_speaker_diarization(
|
||||
input_dir=input_dir,
|
||||
output_dir=output_dir,
|
||||
min_speakers=min_speakers,
|
||||
max_speakers=max_speakers,
|
||||
huggingface_token=huggingface_token,
|
||||
n_jobs=n_jobs,
|
||||
sr=sr,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./dataset_raw_raw/"),
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-dir",
|
||||
type=click.Path(),
|
||||
default=Path("./dataset_raw/"),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option(
|
||||
"-n",
|
||||
"--n-jobs",
|
||||
type=int,
|
||||
default=-1,
|
||||
help="number of jobs (optimal value may depend on your RAM capacity and audio duration per file)",
|
||||
)
|
||||
@click.option("-d", "--top-db", type=float, default=30, help="top db")
|
||||
@click.option("-f", "--frame-seconds", type=float, default=1, help="frame seconds")
|
||||
@click.option(
|
||||
"-ho", "-hop", "--hop-seconds", type=float, default=0.3, help="hop seconds"
|
||||
)
|
||||
@click.option("-s", "--sr", type=int, default=44100, help="sample rate")
|
||||
def pre_split(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str,
|
||||
top_db: int,
|
||||
frame_seconds: float,
|
||||
hop_seconds: float,
|
||||
n_jobs: int,
|
||||
sr: int,
|
||||
):
|
||||
"""Split audio files into multiple files"""
|
||||
from so_vits_svc_fork.preprocessing.preprocess_split import preprocess_split
|
||||
|
||||
preprocess_split(
|
||||
input_dir=input_dir,
|
||||
output_dir=output_dir,
|
||||
top_db=top_db,
|
||||
frame_seconds=frame_seconds,
|
||||
hop_seconds=hop_seconds,
|
||||
n_jobs=n_jobs,
|
||||
sr=sr,
|
||||
)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
required=True,
|
||||
help="path to source dir",
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-dir",
|
||||
type=click.Path(),
|
||||
default=None,
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option(
|
||||
"-c/-nc",
|
||||
"--create-new/--no-create-new",
|
||||
type=bool,
|
||||
default=True,
|
||||
help="create a new folder for the speaker if not exist",
|
||||
)
|
||||
def pre_classify(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str | None,
|
||||
create_new: bool,
|
||||
) -> None:
|
||||
"""Classify multiple audio files into multiple files"""
|
||||
from so_vits_svc_fork.preprocessing.preprocess_classify import preprocess_classify
|
||||
|
||||
if output_dir is None:
|
||||
output_dir = input_dir
|
||||
preprocess_classify(
|
||||
input_dir=input_dir,
|
||||
output_dir=output_dir,
|
||||
create_new=create_new,
|
||||
)
|
||||
|
||||
|
||||
@cli.command
|
||||
def clean():
|
||||
"""Clean up files, only useful if you are using the default file structure"""
|
||||
import shutil
|
||||
|
||||
folders = ["dataset", "filelists", "logs"]
|
||||
if pyip.inputYesNo(f"Are you sure you want to delete files in {folders}?") == "yes":
|
||||
for folder in folders:
|
||||
if Path(folder).exists():
|
||||
shutil.rmtree(folder)
|
||||
LOG.info("Cleaned up files")
|
||||
else:
|
||||
LOG.info("Aborted")
|
||||
|
||||
|
||||
@cli.command
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-path",
|
||||
type=click.Path(exists=True),
|
||||
help="model path",
|
||||
default=Path("./logs/44k/"),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="onnx model path to save",
|
||||
default=None,
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(),
|
||||
help="config path",
|
||||
default=Path("./configs/44k/config.json"),
|
||||
)
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default="cpu",
|
||||
help="device to use",
|
||||
)
|
||||
def onnx(
|
||||
input_path: Path, output_path: Path, config_path: Path, device: torch.device | str
|
||||
) -> None:
|
||||
"""Export model to onnx (currently not working)"""
|
||||
raise NotImplementedError("ONNX export is not yet supported")
|
||||
input_path = Path(input_path)
|
||||
if input_path.is_dir():
|
||||
input_path = list(input_path.glob("*.pth"))[0]
|
||||
if output_path is None:
|
||||
output_path = input_path.with_suffix(".onnx")
|
||||
output_path = Path(output_path)
|
||||
if output_path.is_dir():
|
||||
output_path = output_path / (input_path.stem + ".onnx")
|
||||
config_path = Path(config_path)
|
||||
device_ = torch.device(device)
|
||||
from so_vits_svc_fork.modules.onnx._export import onnx_export
|
||||
|
||||
onnx_export(
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
config_path=config_path,
|
||||
device=device_,
|
||||
)
|
||||
|
||||
|
||||
@cli.command
|
||||
@click.option(
|
||||
"-i",
|
||||
"--input-dir",
|
||||
type=click.Path(exists=True),
|
||||
help="dataset directory",
|
||||
default=Path("./dataset/44k"),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="model path to save",
|
||||
default=Path("./logs/44k/kmeans.pt"),
|
||||
)
|
||||
@click.option("-n", "--n-clusters", type=int, help="number of clusters", default=2000)
|
||||
@click.option(
|
||||
"-m/-nm", "--minibatch/--no-minibatch", default=True, help="use minibatch k-means"
|
||||
)
|
||||
def train_cluster(
|
||||
input_dir: Path, output_path: Path, n_clusters: int, minibatch: bool
|
||||
) -> None:
|
||||
"""Train k-means clustering"""
|
||||
from .cluster.train_cluster import main
|
||||
|
||||
main(
|
||||
input_dir=input_dir,
|
||||
output_path=output_path,
|
||||
n_clusters=n_clusters,
|
||||
verbose=True,
|
||||
use_minibatch=minibatch,
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
freeze_support()
|
||||
cli()
|
||||
@@ -0,0 +1,48 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
from sklearn.cluster import KMeans
|
||||
|
||||
|
||||
def get_cluster_model(ckpt_path: Path | str):
|
||||
with Path(ckpt_path).open("rb") as f:
|
||||
checkpoint = torch.load(
|
||||
f, map_location="cpu"
|
||||
) # Danger of arbitrary code execution
|
||||
kmeans_dict = {}
|
||||
for spk, ckpt in checkpoint.items():
|
||||
km = KMeans(ckpt["n_features_in_"])
|
||||
km.__dict__["n_features_in_"] = ckpt["n_features_in_"]
|
||||
km.__dict__["_n_threads"] = ckpt["_n_threads"]
|
||||
km.__dict__["cluster_centers_"] = ckpt["cluster_centers_"]
|
||||
kmeans_dict[spk] = km
|
||||
return kmeans_dict
|
||||
|
||||
|
||||
def check_speaker(model: Any, speaker: Any):
|
||||
if speaker not in model:
|
||||
raise ValueError(f"Speaker {speaker} not in {list(model.keys())}")
|
||||
|
||||
|
||||
def get_cluster_result(model: Any, x: Any, speaker: Any):
|
||||
"""
|
||||
x: np.array [t, 256]
|
||||
return cluster class result
|
||||
"""
|
||||
check_speaker(model, speaker)
|
||||
return model[speaker].predict(x)
|
||||
|
||||
|
||||
def get_cluster_center_result(model: Any, x: Any, speaker: Any):
|
||||
"""x: np.array [t, 256]"""
|
||||
check_speaker(model, speaker)
|
||||
predict = model[speaker].predict(x)
|
||||
return model[speaker].cluster_centers_[predict]
|
||||
|
||||
|
||||
def get_center(model: Any, x: Any, speaker: Any):
|
||||
check_speaker(model, speaker)
|
||||
return model[speaker].cluster_centers_[x]
|
||||
@@ -0,0 +1,91 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from cm_time import timer
|
||||
from joblib import Parallel, delayed
|
||||
from sklearn.cluster import KMeans, MiniBatchKMeans
|
||||
from tqdm_joblib import tqdm_joblib
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def train_cluster(
|
||||
input_dir: Path | str,
|
||||
n_clusters: int,
|
||||
use_minibatch: bool = True,
|
||||
verbose: bool = False,
|
||||
) -> dict:
|
||||
input_dir = Path(input_dir)
|
||||
LOG.info(f"Loading features from {input_dir}")
|
||||
features = []
|
||||
for path in input_dir.rglob("*.data.pt"):
|
||||
with path.open("rb") as f:
|
||||
features.append(
|
||||
torch.load(f, weights_only=True)["content"].squeeze(0).numpy().T
|
||||
)
|
||||
if not features:
|
||||
raise ValueError(f"No features found in {input_dir}")
|
||||
features = np.concatenate(features, axis=0).astype(np.float32)
|
||||
if features.shape[0] < n_clusters:
|
||||
raise ValueError(
|
||||
"Too few HuBERT features to cluster. Consider using a smaller number of clusters."
|
||||
)
|
||||
LOG.info(
|
||||
f"shape: {features.shape}, size: {features.nbytes/1024**2:.2f} MB, dtype: {features.dtype}"
|
||||
)
|
||||
with timer() as t:
|
||||
if use_minibatch:
|
||||
kmeans = MiniBatchKMeans(
|
||||
n_clusters=n_clusters,
|
||||
verbose=verbose,
|
||||
batch_size=4096,
|
||||
max_iter=80,
|
||||
n_init="auto",
|
||||
).fit(features)
|
||||
else:
|
||||
kmeans = KMeans(n_clusters=n_clusters, verbose=verbose, n_init="auto").fit(
|
||||
features
|
||||
)
|
||||
LOG.info(f"Clustering took {t.elapsed:.2f} seconds")
|
||||
|
||||
x = {
|
||||
"n_features_in_": kmeans.n_features_in_,
|
||||
"_n_threads": kmeans._n_threads,
|
||||
"cluster_centers_": kmeans.cluster_centers_,
|
||||
}
|
||||
return x
|
||||
|
||||
|
||||
def main(
|
||||
input_dir: Path | str,
|
||||
output_path: Path | str,
|
||||
n_clusters: int = 10000,
|
||||
use_minibatch: bool = True,
|
||||
verbose: bool = False,
|
||||
) -> None:
|
||||
input_dir = Path(input_dir)
|
||||
output_path = Path(output_path)
|
||||
|
||||
def train_cluster_(input_path: Path, **kwargs: Any) -> tuple[str, dict]:
|
||||
return input_path.stem, train_cluster(input_path, **kwargs)
|
||||
|
||||
with tqdm_joblib(desc="Training clusters", total=len(list(input_dir.iterdir()))):
|
||||
parallel_result = Parallel(n_jobs=-1)(
|
||||
delayed(train_cluster_)(
|
||||
speaker_name,
|
||||
n_clusters=n_clusters,
|
||||
use_minibatch=use_minibatch,
|
||||
verbose=verbose,
|
||||
)
|
||||
for speaker_name in input_dir.iterdir()
|
||||
)
|
||||
assert parallel_result is not None
|
||||
checkpoint = dict(parallel_result)
|
||||
output_path.parent.mkdir(exist_ok=True, parents=True)
|
||||
with output_path.open("wb") as f:
|
||||
torch.save(checkpoint, f)
|
||||
@@ -0,0 +1,87 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
from random import Random
|
||||
from typing import Sequence
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from torch.utils.data import Dataset
|
||||
|
||||
from .hparams import HParams
|
||||
|
||||
|
||||
class TextAudioDataset(Dataset):
|
||||
def __init__(self, hps: HParams, is_validation: bool = False):
|
||||
self.datapaths = [
|
||||
Path(x).parent / (Path(x).name + ".data.pt")
|
||||
for x in Path(
|
||||
hps.data.validation_files if is_validation else hps.data.training_files
|
||||
)
|
||||
.read_text("utf-8")
|
||||
.splitlines()
|
||||
]
|
||||
self.hps = hps
|
||||
self.random = Random(hps.train.seed)
|
||||
self.random.shuffle(self.datapaths)
|
||||
self.max_spec_len = 800
|
||||
|
||||
def __getitem__(self, index: int) -> dict[str, torch.Tensor]:
|
||||
with Path(self.datapaths[index]).open("rb") as f:
|
||||
data = torch.load(f, weights_only=True, map_location="cpu")
|
||||
|
||||
# cut long data randomly
|
||||
spec_len = data["mel_spec"].shape[1]
|
||||
hop_len = self.hps.data.hop_length
|
||||
if spec_len > self.max_spec_len:
|
||||
start = self.random.randint(0, spec_len - self.max_spec_len)
|
||||
end = start + self.max_spec_len - 10
|
||||
for key in data.keys():
|
||||
if key == "audio":
|
||||
data[key] = data[key][:, start * hop_len : end * hop_len]
|
||||
elif key == "spk":
|
||||
continue
|
||||
else:
|
||||
data[key] = data[key][..., start:end]
|
||||
torch.cuda.empty_cache()
|
||||
return data
|
||||
|
||||
def __len__(self) -> int:
|
||||
return len(self.datapaths)
|
||||
|
||||
|
||||
def _pad_stack(array: Sequence[torch.Tensor]) -> torch.Tensor:
|
||||
max_idx = torch.argmax(torch.tensor([x_.shape[-1] for x_ in array]))
|
||||
max_x = array[max_idx]
|
||||
x_padded = [
|
||||
F.pad(x_, (0, max_x.shape[-1] - x_.shape[-1]), mode="constant", value=0)
|
||||
for x_ in array
|
||||
]
|
||||
return torch.stack(x_padded)
|
||||
|
||||
|
||||
class TextAudioCollate(nn.Module):
|
||||
def forward(
|
||||
self, batch: Sequence[dict[str, torch.Tensor]]
|
||||
) -> tuple[torch.Tensor, ...]:
|
||||
batch = [b for b in batch if b is not None]
|
||||
batch = list(sorted(batch, key=lambda x: x["mel_spec"].shape[1], reverse=True))
|
||||
lengths = torch.tensor([b["mel_spec"].shape[1] for b in batch]).long()
|
||||
results = {}
|
||||
for key in batch[0].keys():
|
||||
if key not in ["spk"]:
|
||||
results[key] = _pad_stack([b[key] for b in batch]).cpu()
|
||||
else:
|
||||
results[key] = torch.tensor([[b[key]] for b in batch]).cpu()
|
||||
|
||||
return (
|
||||
results["content"],
|
||||
results["f0"],
|
||||
results["spec"],
|
||||
results["mel_spec"],
|
||||
results["audio"],
|
||||
results["spk"],
|
||||
lengths,
|
||||
results["uv"],
|
||||
)
|
||||
@@ -0,0 +1,87 @@
|
||||
{
|
||||
"Default VC (GPU, GTX 1060)": {
|
||||
"silence_threshold": -35.0,
|
||||
"transpose": 12.0,
|
||||
"auto_predict_f0": false,
|
||||
"f0_method": "dio",
|
||||
"cluster_infer_ratio": 0.0,
|
||||
"noise_scale": 0.4,
|
||||
"pad_seconds": 0.1,
|
||||
"chunk_seconds": 0.5,
|
||||
"absolute_thresh": true,
|
||||
"crossfade_seconds": 0.05,
|
||||
"block_seconds": 0.35,
|
||||
"additional_infer_before_seconds": 0.15,
|
||||
"additional_infer_after_seconds": 0.1,
|
||||
"realtime_algorithm": "1 (Divide constantly)",
|
||||
"passthrough_original": false,
|
||||
"use_gpu": true
|
||||
},
|
||||
"Default VC (CPU)": {
|
||||
"silence_threshold": -35.0,
|
||||
"transpose": 12.0,
|
||||
"auto_predict_f0": false,
|
||||
"f0_method": "dio",
|
||||
"cluster_infer_ratio": 0.0,
|
||||
"noise_scale": 0.4,
|
||||
"pad_seconds": 0.1,
|
||||
"chunk_seconds": 0.5,
|
||||
"absolute_thresh": true,
|
||||
"crossfade_seconds": 0.05,
|
||||
"block_seconds": 1.5,
|
||||
"additional_infer_before_seconds": 0.01,
|
||||
"additional_infer_after_seconds": 0.01,
|
||||
"realtime_algorithm": "1 (Divide constantly)",
|
||||
"passthrough_original": false,
|
||||
"use_gpu": false
|
||||
},
|
||||
"Default VC (Mobile CPU)": {
|
||||
"silence_threshold": -35.0,
|
||||
"transpose": 12.0,
|
||||
"auto_predict_f0": false,
|
||||
"f0_method": "dio",
|
||||
"cluster_infer_ratio": 0.0,
|
||||
"noise_scale": 0.4,
|
||||
"pad_seconds": 0.1,
|
||||
"chunk_seconds": 0.5,
|
||||
"absolute_thresh": true,
|
||||
"crossfade_seconds": 0.05,
|
||||
"block_seconds": 2.5,
|
||||
"additional_infer_before_seconds": 0.01,
|
||||
"additional_infer_after_seconds": 0.01,
|
||||
"realtime_algorithm": "1 (Divide constantly)",
|
||||
"passthrough_original": false,
|
||||
"use_gpu": false
|
||||
},
|
||||
"Default VC (Crooning)": {
|
||||
"silence_threshold": -35.0,
|
||||
"transpose": 12.0,
|
||||
"auto_predict_f0": false,
|
||||
"f0_method": "dio",
|
||||
"cluster_infer_ratio": 0.0,
|
||||
"noise_scale": 0.4,
|
||||
"pad_seconds": 0.1,
|
||||
"chunk_seconds": 0.5,
|
||||
"absolute_thresh": true,
|
||||
"crossfade_seconds": 0.04,
|
||||
"block_seconds": 0.15,
|
||||
"additional_infer_before_seconds": 0.05,
|
||||
"additional_infer_after_seconds": 0.05,
|
||||
"realtime_algorithm": "1 (Divide constantly)",
|
||||
"passthrough_original": false,
|
||||
"use_gpu": true
|
||||
},
|
||||
"Default File": {
|
||||
"silence_threshold": -35.0,
|
||||
"transpose": 0.0,
|
||||
"auto_predict_f0": true,
|
||||
"f0_method": "crepe",
|
||||
"cluster_infer_ratio": 0.0,
|
||||
"noise_scale": 0.4,
|
||||
"pad_seconds": 0.1,
|
||||
"chunk_seconds": 0.5,
|
||||
"absolute_thresh": true,
|
||||
"auto_play": true,
|
||||
"passthrough_original": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,239 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from typing import Any, Literal
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchcrepe
|
||||
from cm_time import timer
|
||||
from numpy import dtype, float32, ndarray
|
||||
from torch import FloatTensor, Tensor
|
||||
|
||||
from so_vits_svc_fork.utils import get_optimal_device
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def normalize_f0(
|
||||
f0: FloatTensor, x_mask: FloatTensor, uv: FloatTensor, random_scale=True
|
||||
) -> FloatTensor:
|
||||
# calculate means based on x_mask
|
||||
uv_sum = torch.sum(uv, dim=1, keepdim=True)
|
||||
uv_sum[uv_sum == 0] = 9999
|
||||
means = torch.sum(f0[:, 0, :] * uv, dim=1, keepdim=True) / uv_sum
|
||||
|
||||
if random_scale:
|
||||
factor = torch.Tensor(f0.shape[0], 1).uniform_(0.8, 1.2).to(f0.device)
|
||||
else:
|
||||
factor = torch.ones(f0.shape[0], 1).to(f0.device)
|
||||
# normalize f0 based on means and factor
|
||||
f0_norm = (f0 - means.unsqueeze(-1)) * factor.unsqueeze(-1)
|
||||
if torch.isnan(f0_norm).any():
|
||||
exit(0)
|
||||
return f0_norm * x_mask
|
||||
|
||||
|
||||
def interpolate_f0(
|
||||
f0: ndarray[Any, dtype[float32]]
|
||||
) -> tuple[ndarray[Any, dtype[float32]], ndarray[Any, dtype[float32]]]:
|
||||
data = np.reshape(f0, (f0.size, 1))
|
||||
|
||||
vuv_vector = np.zeros((data.size, 1), dtype=np.float32)
|
||||
vuv_vector[data > 0.0] = 1.0
|
||||
vuv_vector[data <= 0.0] = 0.0
|
||||
|
||||
ip_data = data
|
||||
|
||||
frame_number = data.size
|
||||
last_value = 0.0
|
||||
for i in range(frame_number):
|
||||
if data[i] <= 0.0:
|
||||
j = i + 1
|
||||
for j in range(i + 1, frame_number):
|
||||
if data[j] > 0.0:
|
||||
break
|
||||
if j < frame_number - 1:
|
||||
if last_value > 0.0:
|
||||
step = (data[j] - data[i - 1]) / float(j - i)
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[i - 1] + step * (k - i + 1)
|
||||
else:
|
||||
for k in range(i, j):
|
||||
ip_data[k] = data[j]
|
||||
else:
|
||||
for k in range(i, frame_number):
|
||||
ip_data[k] = last_value
|
||||
else:
|
||||
ip_data[i] = data[i]
|
||||
last_value = data[i]
|
||||
|
||||
return ip_data[:, 0], vuv_vector[:, 0]
|
||||
|
||||
|
||||
def compute_f0_parselmouth(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
):
|
||||
import parselmouth
|
||||
|
||||
x = wav_numpy
|
||||
if p_len is None:
|
||||
p_len = x.shape[0] // hop_length
|
||||
else:
|
||||
assert abs(p_len - x.shape[0] // hop_length) < 4, "pad length error"
|
||||
time_step = hop_length / sampling_rate * 1000
|
||||
f0_min = 50
|
||||
f0_max = 1100
|
||||
f0 = (
|
||||
parselmouth.Sound(x, sampling_rate)
|
||||
.to_pitch_ac(
|
||||
time_step=time_step / 1000,
|
||||
voicing_threshold=0.6,
|
||||
pitch_floor=f0_min,
|
||||
pitch_ceiling=f0_max,
|
||||
)
|
||||
.selected_array["frequency"]
|
||||
)
|
||||
|
||||
pad_size = (p_len - len(f0) + 1) // 2
|
||||
if pad_size > 0 or p_len - len(f0) - pad_size > 0:
|
||||
f0 = np.pad(f0, [[pad_size, p_len - len(f0) - pad_size]], mode="constant")
|
||||
return f0
|
||||
|
||||
|
||||
def _resize_f0(
|
||||
x: ndarray[Any, dtype[float32]], target_len: int
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
source = np.array(x)
|
||||
source[source < 0.001] = np.nan
|
||||
target = np.interp(
|
||||
np.arange(0, len(source) * target_len, len(source)) / target_len,
|
||||
np.arange(0, len(source)),
|
||||
source,
|
||||
)
|
||||
res = np.nan_to_num(target)
|
||||
return res
|
||||
|
||||
|
||||
def compute_f0_pyworld(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
type_: Literal["dio", "harvest"] = "dio",
|
||||
):
|
||||
import pyworld
|
||||
|
||||
if p_len is None:
|
||||
p_len = wav_numpy.shape[0] // hop_length
|
||||
if type_ == "dio":
|
||||
f0, t = pyworld.dio(
|
||||
wav_numpy.astype(np.double),
|
||||
fs=sampling_rate,
|
||||
f0_ceil=f0_max,
|
||||
f0_floor=f0_min,
|
||||
frame_period=1000 * hop_length / sampling_rate,
|
||||
)
|
||||
elif type_ == "harvest":
|
||||
f0, t = pyworld.harvest(
|
||||
wav_numpy.astype(np.double),
|
||||
fs=sampling_rate,
|
||||
f0_ceil=f0_max,
|
||||
f0_floor=f0_min,
|
||||
frame_period=1000 * hop_length / sampling_rate,
|
||||
)
|
||||
f0 = pyworld.stonemask(wav_numpy.astype(np.double), f0, t, sampling_rate)
|
||||
for index, pitch in enumerate(f0):
|
||||
f0[index] = round(pitch, 1)
|
||||
return _resize_f0(f0, p_len)
|
||||
|
||||
|
||||
def compute_f0_crepe(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
device: str | torch.device = get_optimal_device(),
|
||||
model: Literal["full", "tiny"] = "full",
|
||||
):
|
||||
audio = torch.from_numpy(wav_numpy).to(device, copy=True)
|
||||
audio = torch.unsqueeze(audio, dim=0)
|
||||
|
||||
if audio.ndim == 2 and audio.shape[0] > 1:
|
||||
audio = torch.mean(audio, dim=0, keepdim=True).detach()
|
||||
# (T) -> (1, T)
|
||||
audio = audio.detach()
|
||||
|
||||
pitch: Tensor = torchcrepe.predict(
|
||||
audio,
|
||||
sampling_rate,
|
||||
hop_length,
|
||||
f0_min,
|
||||
f0_max,
|
||||
model,
|
||||
batch_size=hop_length * 2,
|
||||
device=device,
|
||||
pad=True,
|
||||
)
|
||||
|
||||
f0 = pitch.squeeze(0).cpu().float().numpy()
|
||||
p_len = p_len or wav_numpy.shape[0] // hop_length
|
||||
f0 = _resize_f0(f0, p_len)
|
||||
return f0
|
||||
|
||||
|
||||
def compute_f0(
|
||||
wav_numpy: ndarray[Any, dtype[float32]],
|
||||
p_len: None | int = None,
|
||||
sampling_rate: int = 44100,
|
||||
hop_length: int = 512,
|
||||
method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
**kwargs,
|
||||
):
|
||||
with timer() as t:
|
||||
wav_numpy = wav_numpy.astype(np.float32)
|
||||
wav_numpy /= np.quantile(np.abs(wav_numpy), 0.999)
|
||||
if method in ["dio", "harvest"]:
|
||||
f0 = compute_f0_pyworld(wav_numpy, p_len, sampling_rate, hop_length, method)
|
||||
elif method == "crepe":
|
||||
f0 = compute_f0_crepe(wav_numpy, p_len, sampling_rate, hop_length, **kwargs)
|
||||
elif method == "crepe-tiny":
|
||||
f0 = compute_f0_crepe(
|
||||
wav_numpy, p_len, sampling_rate, hop_length, model="tiny", **kwargs
|
||||
)
|
||||
elif method == "parselmouth":
|
||||
f0 = compute_f0_parselmouth(wav_numpy, p_len, sampling_rate, hop_length)
|
||||
else:
|
||||
raise ValueError(
|
||||
"type must be dio, crepe, crepe-tiny, harvest or parselmouth"
|
||||
)
|
||||
rtf = t.elapsed / (len(wav_numpy) / sampling_rate)
|
||||
LOG.info(f"F0 inference time: {t.elapsed:.3f}s, RTF: {rtf:.3f}")
|
||||
return f0
|
||||
|
||||
|
||||
def f0_to_coarse(f0: torch.Tensor | float):
|
||||
is_torch = isinstance(f0, torch.Tensor)
|
||||
f0_mel = 1127 * (1 + f0 / 700).log() if is_torch else 1127 * np.log(1 + f0 / 700)
|
||||
f0_mel[f0_mel > 0] = (f0_mel[f0_mel > 0] - f0_mel_min) * (f0_bin - 2) / (
|
||||
f0_mel_max - f0_mel_min
|
||||
) + 1
|
||||
|
||||
f0_mel[f0_mel <= 1] = 1
|
||||
f0_mel[f0_mel > f0_bin - 1] = f0_bin - 1
|
||||
f0_coarse = (f0_mel + 0.5).long() if is_torch else np.rint(f0_mel).astype(np.int)
|
||||
assert f0_coarse.max() <= 255 and f0_coarse.min() >= 1, (
|
||||
f0_coarse.max(),
|
||||
f0_coarse.min(),
|
||||
)
|
||||
return f0_coarse
|
||||
|
||||
|
||||
f0_bin = 256
|
||||
f0_max = 1100.0
|
||||
f0_min = 50.0
|
||||
f0_mel_min = 1127 * np.log(1 + f0_min / 700)
|
||||
f0_mel_max = 1127 * np.log(1 + f0_max / 700)
|
||||
@@ -0,0 +1,612 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
#sys.path.append(".")
|
||||
#sys.path.append("/models/voice_conversion/so-vits-svc/src/so_vits_svc_fork")
|
||||
|
||||
import os
|
||||
from logging import (
|
||||
DEBUG,
|
||||
INFO,
|
||||
FileHandler,
|
||||
StreamHandler,
|
||||
basicConfig,
|
||||
captureWarnings,
|
||||
getLogger,
|
||||
)
|
||||
from pathlib import Path
|
||||
from typing import Literal
|
||||
|
||||
import click
|
||||
import pyinputplus as pyip
|
||||
import torch
|
||||
from rich.logging import RichHandler
|
||||
|
||||
print("Env vars:")
|
||||
print(os.environ)
|
||||
|
||||
|
||||
def print_gpu_info():
|
||||
print('========================================')
|
||||
print('Python interpreter', sys.executable)
|
||||
print('PyTorch version', torch.__version__)
|
||||
print('CUDA Available?', torch.cuda.is_available())
|
||||
print('CUDA Device count', torch.cuda.device_count())
|
||||
print('CUDA architectures library was compiled for', torch.cuda.get_arch_list())
|
||||
|
||||
#try:
|
||||
# from tensorflow.python.client import device_lib
|
||||
# print('local devices', str(device_lib.list_local_devices()).replace("\n", "\n "))
|
||||
#except ImportError:
|
||||
# print('no tensorflow - cannot list devices')
|
||||
# pass
|
||||
print('========================================', flush=True)
|
||||
|
||||
print_gpu_info()
|
||||
|
||||
def init_logger() -> None:
|
||||
IN_COLAB = os.getenv("COLAB_RELEASE_TAG")
|
||||
IS_TEST = "test" in Path(__file__).parent.stem
|
||||
|
||||
basicConfig(
|
||||
level=DEBUG if IS_TEST else INFO,
|
||||
format="%(asctime)s %(message)s",
|
||||
datefmt="[%X]",
|
||||
handlers=[
|
||||
RichHandler() if not IN_COLAB else StreamHandler(),
|
||||
FileHandler(f"{__name__.split('.')[0]}.log"),
|
||||
],
|
||||
)
|
||||
captureWarnings(True)
|
||||
if IS_TEST:
|
||||
LOG.debug("Test mode is on.")
|
||||
|
||||
|
||||
init_logger()
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
class RichHelpFormatter(click.HelpFormatter):
|
||||
def __init__(
|
||||
self,
|
||||
indent_increment: int = 2,
|
||||
width: int | None = None,
|
||||
max_width: int | None = None,
|
||||
) -> None:
|
||||
width = 100
|
||||
super().__init__(indent_increment, width, max_width)
|
||||
|
||||
|
||||
def patch_wrap_text():
|
||||
orig_wrap_text = click.formatting.wrap_text
|
||||
|
||||
def wrap_text(
|
||||
text,
|
||||
width=78,
|
||||
initial_indent="",
|
||||
subsequent_indent="",
|
||||
preserve_paragraphs=False,
|
||||
):
|
||||
return orig_wrap_text(
|
||||
text.replace("\n", "\n\n"),
|
||||
width=width,
|
||||
initial_indent=initial_indent,
|
||||
subsequent_indent=subsequent_indent,
|
||||
preserve_paragraphs=True,
|
||||
).replace("\n\n", "\n")
|
||||
|
||||
click.formatting.wrap_text = wrap_text
|
||||
|
||||
|
||||
patch_wrap_text()
|
||||
|
||||
CONTEXT_SETTINGS = dict(help_option_names=["-h", "--help"], show_default=True)
|
||||
click.Context.formatter_class = RichHelpFormatter
|
||||
|
||||
|
||||
@click.group(context_settings=CONTEXT_SETTINGS)
|
||||
def cli():
|
||||
"""so-vits-svc allows any folder structure for training data.
|
||||
However, the following folder structure is recommended.\n
|
||||
When training: dataset_raw/{speaker_name}/**/{wav_name}.{any_format}\n
|
||||
When inference: configs/44k/config.json, logs/44k/G_XXXX.pth\n
|
||||
If the folder structure is followed, you DO NOT NEED TO SPECIFY model path, config path, etc.
|
||||
(The latest model will be automatically loaded.)\n
|
||||
To train a model, run pre-resample, pre-config, pre-hubert, train.\n
|
||||
To infer a model, run infer.
|
||||
"""
|
||||
init_logger()
|
||||
|
||||
|
||||
#@cli.command()
|
||||
#@click.option(
|
||||
# "-c",
|
||||
# "--config-path",
|
||||
# type=click.Path(exists=True),
|
||||
# help="path to config",
|
||||
# default=Path("./configs/44k/config.json"),
|
||||
#)
|
||||
#@click.option(
|
||||
# "-m",
|
||||
# "--model-path",
|
||||
# type=click.Path(),
|
||||
# help="path to output dir",
|
||||
# default=Path("./logs/44k"),
|
||||
#)
|
||||
#def train(config_path: Path, model_path: Path):
|
||||
# """Train model
|
||||
# If D_0.pth or G_0.pth not found, automatically download from hub."""
|
||||
# from .train import train
|
||||
#
|
||||
# config_path = Path(config_path)
|
||||
# model_path = Path(model_path)
|
||||
# train(config_path=config_path, model_path=model_path)
|
||||
|
||||
|
||||
@cli.command()
|
||||
@click.argument(
|
||||
"input-path",
|
||||
type=click.Path(exists=True),
|
||||
)
|
||||
@click.option(
|
||||
"-o",
|
||||
"--output-path",
|
||||
type=click.Path(),
|
||||
help="path to output dir",
|
||||
)
|
||||
@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
@click.option(
|
||||
"-m",
|
||||
"--model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./logs/44k/"),
|
||||
help="path to model",
|
||||
)
|
||||
@click.option(
|
||||
"-c",
|
||||
"--config-path",
|
||||
type=click.Path(exists=True),
|
||||
default=Path("./configs/44k/config.json"),
|
||||
help="path to config",
|
||||
)
|
||||
@click.option(
|
||||
"-k",
|
||||
"--cluster-model-path",
|
||||
type=click.Path(exists=True),
|
||||
default=None,
|
||||
help="path to cluster model",
|
||||
)
|
||||
@click.option("-t", "--transpose", type=int, default=0, help="transpose")
|
||||
@click.option(
|
||||
"-db", "--db-thresh", type=int, default=-20, help="threshold (DB) (RELATIVE)"
|
||||
)
|
||||
@click.option(
|
||||
"-a", "--auto-predict-f0", type=bool, default=True, help="auto predict f0"
|
||||
)
|
||||
@click.option(
|
||||
"-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
)
|
||||
@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
@click.option("-p", "--pad-seconds", type=float, default=0.5, help="pad seconds")
|
||||
@click.option(
|
||||
"-d",
|
||||
"--device",
|
||||
type=str,
|
||||
default="cuda" if torch.cuda.is_available() else "cpu",
|
||||
help="device",
|
||||
)
|
||||
@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
@click.option(
|
||||
"-ab", "--absolute-thresh", type=bool, default=False, help="absolute thresh"
|
||||
)
|
||||
def infer(
|
||||
input_path: Path,
|
||||
output_path: Path,
|
||||
speaker: str,
|
||||
model_path: Path,
|
||||
config_path: Path,
|
||||
cluster_model_path: Path | None = None,
|
||||
transpose: int = 0,
|
||||
db_thresh: int = -40,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
device: Literal["cpu", "cuda"] = "cuda" if torch.cuda.is_available() else "cpu",
|
||||
):
|
||||
"""Inference"""
|
||||
from .inference_main import infer
|
||||
#from inference_main import infer
|
||||
|
||||
if not auto_predict_f0:
|
||||
LOG.warning(
|
||||
f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please set transpose."
|
||||
"Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
)
|
||||
|
||||
input_path = Path(input_path)
|
||||
if output_path is None:
|
||||
output_path = input_path.parent / f"{input_path.stem}.out{input_path.suffix}"
|
||||
output_path = Path(output_path)
|
||||
model_path = Path(model_path)
|
||||
if model_path.is_dir():
|
||||
model_path = list(sorted(model_path.glob("*.pth")))[-1]
|
||||
LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
config_path = Path(config_path)
|
||||
if cluster_model_path is not None:
|
||||
cluster_model_path = Path(cluster_model_path)
|
||||
|
||||
LOG.info("Calling infer()...")
|
||||
|
||||
infer(
|
||||
input_path=input_path,
|
||||
output_path=output_path,
|
||||
speaker=speaker,
|
||||
model_path=model_path,
|
||||
config_path=config_path,
|
||||
cluster_model_path=cluster_model_path,
|
||||
transpose=transpose,
|
||||
db_thresh=db_thresh,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=absolute_thresh,
|
||||
device=device,
|
||||
)
|
||||
|
||||
|
||||
#@cli.command()
|
||||
#@click.option(
|
||||
# "-m",
|
||||
# "--model-path",
|
||||
# type=click.Path(exists=True),
|
||||
# default=Path("./logs/44k/"),
|
||||
# help="path to model",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-c",
|
||||
# "--config-path",
|
||||
# type=click.Path(exists=True),
|
||||
# default=Path("./configs/44k/config.json"),
|
||||
# help="path to config",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-k",
|
||||
# "--cluster-model-path",
|
||||
# type=click.Path(exists=True),
|
||||
# default=None,
|
||||
# help="path to cluster model",
|
||||
#)
|
||||
#@click.option("-t", "--transpose", type=int, default=12, help="transpose")
|
||||
#@click.option(
|
||||
# "-a",
|
||||
# "--auto-predict-f0",
|
||||
# type=bool,
|
||||
# default=False,
|
||||
# help="auto predict f0 (not recommended for realtime since voice pitch will not be stable)",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-r", "--cluster-infer-ratio", type=float, default=0, help="cluster infer ratio"
|
||||
#)
|
||||
#@click.option("-n", "--noise-scale", type=float, default=0.4, help="noise scale")
|
||||
#@click.option(
|
||||
# "-db", "--db-thresh", type=int, default=-30, help="threshold (DB) (ABSOLUTE)"
|
||||
#)
|
||||
#@click.option(
|
||||
# "-fm",
|
||||
# "--f0-method",
|
||||
# type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
# default="crepe",
|
||||
# help="f0 prediction method",
|
||||
#)
|
||||
#@click.option("-p", "--pad-seconds", type=float, default=0.02, help="pad seconds")
|
||||
#@click.option("-ch", "--chunk-seconds", type=float, default=0.5, help="chunk seconds")
|
||||
#@click.option(
|
||||
# "-cr",
|
||||
# "--crossfade-seconds",
|
||||
# type=float,
|
||||
# default=0.01,
|
||||
# help="crossfade seconds",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-ab",
|
||||
# "--additional-infer-before-seconds",
|
||||
# type=float,
|
||||
# default=0.2,
|
||||
# help="additional infer before seconds",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-aa",
|
||||
# "--additional-infer-after-seconds",
|
||||
# type=float,
|
||||
# default=0.1,
|
||||
# help="additional infer after seconds",
|
||||
#)
|
||||
#@click.option("-b", "--block-seconds", type=float, default=0.5, help="block seconds")
|
||||
#@click.option(
|
||||
# "-d",
|
||||
# "--device",
|
||||
# type=str,
|
||||
# default="cuda" if torch.cuda.is_available() else "cpu",
|
||||
# help="device",
|
||||
#)
|
||||
#@click.option("-s", "--speaker", type=str, default=None, help="speaker name")
|
||||
#@click.option("-v", "--version", type=int, default=2, help="version")
|
||||
#@click.option("-i", "--input-device", type=int, default=None, help="input device")
|
||||
#@click.option("-o", "--output-device", type=int, default=None, help="output device")
|
||||
#@click.option(
|
||||
# "-po",
|
||||
# "--passthrough-original",
|
||||
# type=bool,
|
||||
# default=False,
|
||||
# is_flag=True,
|
||||
# help="passthrough original (for latency check)",
|
||||
#)
|
||||
#def vc(
|
||||
# # paths
|
||||
# model_path: Path,
|
||||
# config_path: Path,
|
||||
# # svc config
|
||||
# speaker: str,
|
||||
# cluster_model_path: Path | None,
|
||||
# transpose: int,
|
||||
# auto_predict_f0: bool,
|
||||
# cluster_infer_ratio: float,
|
||||
# noise_scale: float,
|
||||
# f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
# # slice config
|
||||
# db_thresh: int,
|
||||
# pad_seconds: float,
|
||||
# chunk_seconds: float,
|
||||
# # realtime config
|
||||
# crossfade_seconds: float,
|
||||
# additional_infer_before_seconds: float,
|
||||
# additional_infer_after_seconds: float,
|
||||
# block_seconds: float,
|
||||
# version: int,
|
||||
# input_device: int | str | None,
|
||||
# output_device: int | str | None,
|
||||
# device: Literal["cpu", "cuda"],
|
||||
# passthrough_original: bool = False,
|
||||
#) -> None:
|
||||
# """Realtime inference from microphone"""
|
||||
# from .inference_main import realtime
|
||||
#
|
||||
# if auto_predict_f0:
|
||||
# LOG.warning(
|
||||
# "auto_predict_f0 = True in realtime inference will cause unstable voice pitch, use with caution"
|
||||
# )
|
||||
# else:
|
||||
# LOG.warning(
|
||||
# f"auto_predict_f0 = False, transpose = {transpose}. If you want to change the pitch, please change the transpose value."
|
||||
# "Generally transpose = 0 does not work because your voice pitch and target voice pitch are different."
|
||||
# )
|
||||
# model_path = Path(model_path)
|
||||
# config_path = Path(config_path)
|
||||
# if cluster_model_path is not None:
|
||||
# cluster_model_path = Path(cluster_model_path)
|
||||
# if model_path.is_dir():
|
||||
# model_path = list(sorted(model_path.glob("*.pth")))[-1]
|
||||
# LOG.info(f"Since model_path is a directory, use {model_path}")
|
||||
#
|
||||
# realtime(
|
||||
# # paths
|
||||
# model_path=model_path,
|
||||
# config_path=config_path,
|
||||
# # svc config
|
||||
# speaker=speaker,
|
||||
# cluster_model_path=cluster_model_path,
|
||||
# transpose=transpose,
|
||||
# auto_predict_f0=auto_predict_f0,
|
||||
# cluster_infer_ratio=cluster_infer_ratio,
|
||||
# noise_scale=noise_scale,
|
||||
# f0_method=f0_method,
|
||||
# # slice config
|
||||
# db_thresh=db_thresh,
|
||||
# pad_seconds=pad_seconds,
|
||||
# chunk_seconds=chunk_seconds,
|
||||
# # realtime config
|
||||
# crossfade_seconds=crossfade_seconds,
|
||||
# additional_infer_before_seconds=additional_infer_before_seconds,
|
||||
# additional_infer_after_seconds=additional_infer_after_seconds,
|
||||
# block_seconds=block_seconds,
|
||||
# version=version,
|
||||
# input_device=input_device,
|
||||
# output_device=output_device,
|
||||
# device=device,
|
||||
# passthrough_original=passthrough_original,
|
||||
# )
|
||||
|
||||
|
||||
#@cli.command()
|
||||
#@click.option(
|
||||
# "-i",
|
||||
# "--input-dir",
|
||||
# type=click.Path(exists=True),
|
||||
# default=Path("./dataset_raw"),
|
||||
# help="path to source dir",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-o",
|
||||
# "--output-dir",
|
||||
# type=click.Path(),
|
||||
# default=Path("./dataset/44k"),
|
||||
# help="path to output dir",
|
||||
#)
|
||||
#@click.option("-s", "--sampling-rate", type=int, default=44100, help="sampling rate")
|
||||
#def pre_resample(input_dir: Path, output_dir: Path, sampling_rate: int) -> None:
|
||||
# """Preprocessing part 1: resample"""
|
||||
# from .preprocess_resample import preprocess_resample
|
||||
#
|
||||
# input_dir = Path(input_dir)
|
||||
# output_dir = Path(output_dir)
|
||||
# preprocess_resample(
|
||||
# input_dir=input_dir, output_dir=output_dir, sampling_rate=sampling_rate
|
||||
# )
|
||||
|
||||
|
||||
#@cli.command()
|
||||
#@click.option(
|
||||
# "-i",
|
||||
# "--input-dir",
|
||||
# type=click.Path(exists=True),
|
||||
# default=Path("./dataset/44k"),
|
||||
# help="path to source dir",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-f",
|
||||
# "--filelist-path",
|
||||
# type=click.Path(),
|
||||
# default=Path("./filelists/44k"),
|
||||
# help="path to filelist dir",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-c",
|
||||
# "--config-path",
|
||||
# type=click.Path(),
|
||||
# default=Path("./configs/44k/config.json"),
|
||||
# help="path to config",
|
||||
#)
|
||||
#def pre_config(
|
||||
# input_dir: Path,
|
||||
# filelist_path: Path,
|
||||
# config_path: Path,
|
||||
#):
|
||||
# """Preprocessing part 2: config"""
|
||||
# from .preprocess_flist_config import preprocess_config
|
||||
#
|
||||
# input_dir = Path(input_dir)
|
||||
# filelist_path = Path(filelist_path)
|
||||
# config_path = Path(config_path)
|
||||
# preprocess_config(
|
||||
# input_dir=input_dir,
|
||||
# train_list_path=filelist_path / "train.txt",
|
||||
# val_list_path=filelist_path / "val.txt",
|
||||
# test_list_path=filelist_path / "test.txt",
|
||||
# config_path=config_path,
|
||||
# )
|
||||
|
||||
|
||||
#@cli.command()
|
||||
#@click.option(
|
||||
# "-i",
|
||||
# "--input-dir",
|
||||
# type=click.Path(exists=True),
|
||||
# default=Path("./dataset/44k"),
|
||||
# help="path to source dir",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-c",
|
||||
# "--config-path",
|
||||
# type=click.Path(exists=True),
|
||||
# help="path to config",
|
||||
# default=Path("./configs/44k/config.json"),
|
||||
#)
|
||||
#@click.option(
|
||||
# "-n",
|
||||
# "--n_jobs",
|
||||
# type=int,
|
||||
# default=4,
|
||||
# help="number of jobs (optimal value may depend on your VRAM capacity and audio duration per file)",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-f",
|
||||
# "--force-rebuild",
|
||||
# type=bool,
|
||||
# default=True,
|
||||
# help="force rebuild existing preprocessed files",
|
||||
#)
|
||||
#@click.option(
|
||||
# "-fm",
|
||||
# "--f0-method",
|
||||
# type=click.Choice(["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"]),
|
||||
# default="dio",
|
||||
#)
|
||||
#def pre_hubert(
|
||||
# input_dir: Path,
|
||||
# config_path: Path,
|
||||
# n_jobs: bool,
|
||||
# force_rebuild: bool,
|
||||
# f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
#) -> None:
|
||||
# """Preprocessing part 3: hubert
|
||||
# If the HuBERT model is not found, it will be downloaded automatically."""
|
||||
# from .preprocess_hubert_f0 import preprocess_hubert_f0
|
||||
#
|
||||
# input_dir = Path(input_dir)
|
||||
# config_path = Path(config_path)
|
||||
# preprocess_hubert_f0(
|
||||
# input_dir=input_dir,
|
||||
# config_path=config_path,
|
||||
# n_jobs=n_jobs,
|
||||
# force_rebuild=force_rebuild,
|
||||
# f0_method=f0_method,
|
||||
# )
|
||||
|
||||
|
||||
#@cli.command
|
||||
#def clean():
|
||||
# """Clean up files, only useful if you are using the default file structure"""
|
||||
# import shutil
|
||||
#
|
||||
# folders = ["dataset", "filelists", "logs"]
|
||||
# if pyip.inputYesNo(f"Are you sure you want to delete files in {folders}?") == "yes":
|
||||
# for folder in folders:
|
||||
# if Path(folder).exists():
|
||||
# shutil.rmtree(folder)
|
||||
# LOG.info("Cleaned up files")
|
||||
# else:
|
||||
# LOG.info("Aborted")
|
||||
|
||||
|
||||
#@cli.command
|
||||
#@click.option("-i", "--input-path", type=click.Path(exists=True), help="model path")
|
||||
#@click.option("-o", "--output-path", type=click.Path(), help="onnx model path to save")
|
||||
#@click.option("-c", "--config-path", type=click.Path(), help="config path")
|
||||
#@click.option("-d", "--device", type=str, default="cpu", help="torch device")
|
||||
#def onnx(input_path: Path, output_path: Path, config_path: Path, device: str) -> None:
|
||||
# """Export model to onnx"""
|
||||
# input_path = Path(input_path)
|
||||
# output_path = Path(output_path)
|
||||
# config_path = Path(config_path)
|
||||
# device_ = torch.device(device)
|
||||
# from .onnx_export import onnx_export
|
||||
#
|
||||
# onnx_export(
|
||||
# input_path=input_path,
|
||||
# output_path=output_path,
|
||||
# config_path=config_path,
|
||||
# device=device_,
|
||||
# )
|
||||
|
||||
|
||||
#@cli.command
|
||||
#@click.option(
|
||||
# "-i",
|
||||
# "--input-dir",
|
||||
# type=click.Path(exists=True),
|
||||
# help="dataset directory",
|
||||
# default=Path("./dataset/44k"),
|
||||
#)
|
||||
#@click.option(
|
||||
# "-o",
|
||||
# "--output-path",
|
||||
# type=click.Path(),
|
||||
# help="model path to save",
|
||||
# default=Path("./models/44k/kmeans.pt"),
|
||||
#)
|
||||
#@click.option("-n", "--n-clusters", type=int, help="number of clusters", default=10000)
|
||||
#def train_cluster(input_dir: Path, output_path: Path, n_clusters: int) -> None:
|
||||
# """Train k-means clustering"""
|
||||
# from .cluster.train_cluster import main
|
||||
#
|
||||
# main(input_dir=input_dir, output_path=output_path, n_clusters=n_clusters)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
infer()
|
||||
@@ -0,0 +1,746 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import multiprocessing
|
||||
from copy import copy
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import PySimpleGUI as sg
|
||||
import sounddevice as sd
|
||||
import soundfile as sf
|
||||
import torch
|
||||
from pebble import ProcessFuture, ProcessPool
|
||||
|
||||
from . import __version__
|
||||
from .utils import get_optimal_device
|
||||
|
||||
GUI_DEFAULT_PRESETS_PATH = Path(__file__).parent / "default_gui_presets.json"
|
||||
GUI_PRESETS_PATH = Path("./user_gui_presets.json").absolute()
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def play_audio(path: Path | str):
|
||||
if isinstance(path, Path):
|
||||
path = path.as_posix()
|
||||
data, sr = sf.read(path)
|
||||
sd.play(data, sr)
|
||||
|
||||
|
||||
def load_presets() -> dict:
|
||||
defaults = json.loads(GUI_DEFAULT_PRESETS_PATH.read_text("utf-8"))
|
||||
users = (
|
||||
json.loads(GUI_PRESETS_PATH.read_text("utf-8"))
|
||||
if GUI_PRESETS_PATH.exists()
|
||||
else {}
|
||||
)
|
||||
# prioriy: defaults > users
|
||||
# order: defaults -> users
|
||||
return {**defaults, **users, **defaults}
|
||||
|
||||
|
||||
def add_preset(name: str, preset: dict) -> dict:
|
||||
presets = load_presets()
|
||||
presets[name] = preset
|
||||
with GUI_PRESETS_PATH.open("w") as f:
|
||||
json.dump(presets, f, indent=2)
|
||||
return load_presets()
|
||||
|
||||
|
||||
def delete_preset(name: str) -> dict:
|
||||
presets = load_presets()
|
||||
if name in presets:
|
||||
del presets[name]
|
||||
else:
|
||||
LOG.warning(f"Cannot delete preset {name} because it does not exist.")
|
||||
with GUI_PRESETS_PATH.open("w") as f:
|
||||
json.dump(presets, f, indent=2)
|
||||
return load_presets()
|
||||
|
||||
|
||||
def get_output_path(input_path: Path) -> Path:
|
||||
# Default output path
|
||||
output_path = input_path.parent / f"{input_path.stem}.out{input_path.suffix}"
|
||||
|
||||
# Increment file number in path if output file already exists
|
||||
file_num = 1
|
||||
while output_path.exists():
|
||||
output_path = (
|
||||
input_path.parent / f"{input_path.stem}.out_{file_num}{input_path.suffix}"
|
||||
)
|
||||
file_num += 1
|
||||
return output_path
|
||||
|
||||
|
||||
def get_supported_file_types() -> tuple[tuple[str], ...]:
|
||||
return tuple(
|
||||
[
|
||||
((extension, f".{extension.lower()}"))
|
||||
for extension in sf.available_formats().keys()
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
def validate_output_file_type(output_path: Path) -> bool:
|
||||
supported_file_types = sorted(
|
||||
[f".{extension.lower()}" for extension in sf.available_formats().keys()]
|
||||
)
|
||||
if not output_path.suffix:
|
||||
sg.popup_ok(
|
||||
"Error: Output path missing file type extension, enter "
|
||||
+ "one of the following manually:\n\n"
|
||||
+ "\n".join(supported_file_types)
|
||||
)
|
||||
return False
|
||||
if output_path.suffix.lower() not in supported_file_types:
|
||||
sg.popup_ok(
|
||||
f"Error: {output_path.suffix.lower()} is not a supported "
|
||||
+ "extension; use one of the following:\n\n"
|
||||
+ "\n".join(supported_file_types)
|
||||
)
|
||||
return False
|
||||
return True
|
||||
|
||||
|
||||
def get_devices(
|
||||
update: bool = True,
|
||||
) -> tuple[list[str], list[str], list[int], list[int]]:
|
||||
if update:
|
||||
sd._terminate()
|
||||
sd._initialize()
|
||||
devices = sd.query_devices()
|
||||
hostapis = sd.query_hostapis()
|
||||
for hostapi in hostapis:
|
||||
for device_idx in hostapi["devices"]:
|
||||
devices[device_idx]["hostapi_name"] = hostapi["name"]
|
||||
input_devices = [
|
||||
f"{d['name']} ({d['hostapi_name']})"
|
||||
for d in devices
|
||||
if d["max_input_channels"] > 0
|
||||
]
|
||||
output_devices = [
|
||||
f"{d['name']} ({d['hostapi_name']})"
|
||||
for d in devices
|
||||
if d["max_output_channels"] > 0
|
||||
]
|
||||
input_devices_indices = [d["index"] for d in devices if d["max_input_channels"] > 0]
|
||||
output_devices_indices = [
|
||||
d["index"] for d in devices if d["max_output_channels"] > 0
|
||||
]
|
||||
return input_devices, output_devices, input_devices_indices, output_devices_indices
|
||||
|
||||
|
||||
def after_inference(window: sg.Window, path: Path, auto_play: bool, output_path: Path):
|
||||
try:
|
||||
LOG.info(f"Finished inference for {path.stem}{path.suffix}")
|
||||
window["infer"].update(disabled=False)
|
||||
|
||||
if auto_play:
|
||||
play_audio(output_path)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
|
||||
|
||||
def main():
|
||||
LOG.info(f"version: {__version__}")
|
||||
|
||||
sg.theme("Dark")
|
||||
model_candidates = list(sorted(Path("./logs/44k/").glob("G_*.pth")))
|
||||
|
||||
frame_contents = {
|
||||
"Paths": [
|
||||
[
|
||||
sg.Text("Model path"),
|
||||
sg.Push(),
|
||||
sg.InputText(
|
||||
key="model_path",
|
||||
default_text=model_candidates[-1].absolute().as_posix()
|
||||
if model_candidates
|
||||
else "",
|
||||
enable_events=True,
|
||||
),
|
||||
sg.FileBrowse(
|
||||
initial_folder=Path("./logs/44k/").absolute
|
||||
if Path("./logs/44k/").exists()
|
||||
else Path(".").absolute().as_posix(),
|
||||
key="model_path_browse",
|
||||
file_types=(("PyTorch", "*.pth"),),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Config path"),
|
||||
sg.Push(),
|
||||
sg.InputText(
|
||||
key="config_path",
|
||||
default_text=Path("./configs/44k/config.json").absolute().as_posix()
|
||||
if Path("./configs/44k/config.json").exists()
|
||||
else "",
|
||||
enable_events=True,
|
||||
),
|
||||
sg.FileBrowse(
|
||||
initial_folder=Path("./configs/44k/").as_posix()
|
||||
if Path("./configs/44k/").exists()
|
||||
else Path(".").absolute().as_posix(),
|
||||
key="config_path_browse",
|
||||
file_types=(("JSON", "*.json"),),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Cluster model path (Optional)"),
|
||||
sg.Push(),
|
||||
sg.InputText(
|
||||
key="cluster_model_path",
|
||||
default_text=Path("./logs/44k/kmeans.pt").absolute().as_posix()
|
||||
if Path("./logs/44k/kmeans.pt").exists()
|
||||
else "",
|
||||
enable_events=True,
|
||||
),
|
||||
sg.FileBrowse(
|
||||
initial_folder="./logs/44k/"
|
||||
if Path("./logs/44k/").exists()
|
||||
else ".",
|
||||
key="cluster_model_path_browse",
|
||||
file_types=(("PyTorch", "*.pt"),),
|
||||
),
|
||||
],
|
||||
],
|
||||
"Common": [
|
||||
[
|
||||
sg.Text("Speaker"),
|
||||
sg.Push(),
|
||||
sg.Combo(values=[], key="speaker", size=(20, 1)),
|
||||
],
|
||||
[
|
||||
sg.Text("Silence threshold"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(-60.0, 0),
|
||||
orientation="h",
|
||||
key="silence_threshold",
|
||||
resolution=0.1,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text(
|
||||
"Pitch (12 = 1 octave)\n"
|
||||
"ADJUST THIS based on your voice\n"
|
||||
"when Auto predict F0 is turned off.",
|
||||
size=(None, 4),
|
||||
),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(-36, 36),
|
||||
orientation="h",
|
||||
key="transpose",
|
||||
tick_interval=12,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
key="auto_predict_f0",
|
||||
text="Auto predict F0 (Pitch may become unstable when turned on in real-time inference.)",
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Text("F0 prediction method"),
|
||||
sg.Push(),
|
||||
sg.Combo(
|
||||
["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"],
|
||||
key="f0_method",
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Cluster infer ratio"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 1.0),
|
||||
orientation="h",
|
||||
key="cluster_infer_ratio",
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Noise scale"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 1.0),
|
||||
orientation="h",
|
||||
key="noise_scale",
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Pad seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 1.0),
|
||||
orientation="h",
|
||||
key="pad_seconds",
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Chunk seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0.0, 3.0),
|
||||
orientation="h",
|
||||
key="chunk_seconds",
|
||||
resolution=0.01,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
key="absolute_thresh",
|
||||
text="Absolute threshold (ignored (True) in realtime inference)",
|
||||
)
|
||||
],
|
||||
],
|
||||
"File": [
|
||||
[
|
||||
sg.Text("Input audio path"),
|
||||
sg.Push(),
|
||||
sg.InputText(key="input_path", enable_events=True),
|
||||
sg.FileBrowse(initial_folder=".", key="input_path_browse"),
|
||||
sg.Button("Play", key="play_input"),
|
||||
],
|
||||
[
|
||||
sg.Text("Output audio path"),
|
||||
sg.Push(),
|
||||
sg.InputText(key="output_path"),
|
||||
sg.FileSaveAs(
|
||||
initial_folder=".",
|
||||
key="output_path_browse",
|
||||
file_types=get_supported_file_types(),
|
||||
),
|
||||
],
|
||||
[sg.Checkbox(key="auto_play", text="Auto play", default=True)],
|
||||
],
|
||||
"Realtime": [
|
||||
[
|
||||
sg.Text("Crossfade seconds"),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 0.6),
|
||||
orientation="h",
|
||||
key="crossfade_seconds",
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text(
|
||||
"Block seconds", # \n(big -> more robust, slower, (the same) latency)"
|
||||
tooltip="Big -> more robust, slower, (the same) latency",
|
||||
),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 3.0),
|
||||
orientation="h",
|
||||
key="block_seconds",
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text(
|
||||
"Additional Infer seconds (before)", # \n(big -> more robust, slower)"
|
||||
tooltip="Big -> more robust, slower, additional latency",
|
||||
),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 2.0),
|
||||
orientation="h",
|
||||
key="additional_infer_before_seconds",
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text(
|
||||
"Additional Infer seconds (after)", # \n(big -> more robust, slower, additional latency)"
|
||||
tooltip="Big -> more robust, slower, additional latency",
|
||||
),
|
||||
sg.Push(),
|
||||
sg.Slider(
|
||||
range=(0, 2.0),
|
||||
orientation="h",
|
||||
key="additional_infer_after_seconds",
|
||||
resolution=0.001,
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Realtime algorithm"),
|
||||
sg.Push(),
|
||||
sg.Combo(
|
||||
["2 (Divide by speech)", "1 (Divide constantly)"],
|
||||
default_value="1 (Divide constantly)",
|
||||
key="realtime_algorithm",
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Input device"),
|
||||
sg.Push(),
|
||||
sg.Combo(
|
||||
key="input_device",
|
||||
values=[],
|
||||
size=(60, 1),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Text("Output device"),
|
||||
sg.Push(),
|
||||
sg.Combo(
|
||||
key="output_device",
|
||||
values=[],
|
||||
size=(60, 1),
|
||||
),
|
||||
],
|
||||
[
|
||||
sg.Checkbox(
|
||||
"Passthrough original audio (for latency check)",
|
||||
key="passthrough_original",
|
||||
default=False,
|
||||
),
|
||||
sg.Push(),
|
||||
sg.Button("Refresh devices", key="refresh_devices"),
|
||||
],
|
||||
[
|
||||
sg.Frame(
|
||||
"Notes",
|
||||
[
|
||||
[
|
||||
sg.Text(
|
||||
"In Realtime Inference:\n"
|
||||
" - Setting F0 prediction method to 'crepe` may cause performance degradation.\n"
|
||||
" - Auto Predict F0 must be turned off.\n"
|
||||
"If the audio sounds mumbly and choppy:\n"
|
||||
" Case: The inference has not been made in time (Increase Block seconds)\n"
|
||||
" Case: Mic input is low (Decrease Silence threshold)\n"
|
||||
)
|
||||
]
|
||||
],
|
||||
),
|
||||
],
|
||||
],
|
||||
"Presets": [
|
||||
[
|
||||
sg.Text("Presets"),
|
||||
sg.Push(),
|
||||
sg.Combo(
|
||||
key="presets",
|
||||
values=list(load_presets().keys()),
|
||||
size=(20, 1),
|
||||
enable_events=True,
|
||||
),
|
||||
sg.Button("Delete preset", key="delete_preset"),
|
||||
],
|
||||
[
|
||||
sg.Text("Preset name"),
|
||||
sg.Stretch(),
|
||||
sg.InputText(key="preset_name", size=(20, 1)),
|
||||
sg.Button("Add current settings as a preset", key="add_preset"),
|
||||
],
|
||||
],
|
||||
}
|
||||
|
||||
# frames
|
||||
frames = {}
|
||||
for name, items in frame_contents.items():
|
||||
frame = sg.Frame(name, items)
|
||||
frame.expand_x = True
|
||||
frames[name] = [frame]
|
||||
|
||||
column1 = sg.Column(
|
||||
[
|
||||
frames["Paths"],
|
||||
frames["Common"],
|
||||
],
|
||||
vertical_alignment="top",
|
||||
)
|
||||
column2 = sg.Column(
|
||||
[
|
||||
frames["File"],
|
||||
frames["Realtime"],
|
||||
frames["Presets"],
|
||||
[
|
||||
sg.Checkbox(
|
||||
key="use_gpu",
|
||||
default=get_optimal_device() != torch.device("cpu"),
|
||||
text="Use GPU"
|
||||
+ (
|
||||
" (not available; if your device has GPU, make sure you installed PyTorch with CUDA support)"
|
||||
if get_optimal_device() == torch.device("cpu")
|
||||
else ""
|
||||
),
|
||||
disabled=get_optimal_device() == torch.device("cpu"),
|
||||
)
|
||||
],
|
||||
[
|
||||
sg.Button("Infer", key="infer"),
|
||||
sg.Button("(Re)Start Voice Changer", key="start_vc"),
|
||||
sg.Button("Stop Voice Changer", key="stop_vc"),
|
||||
sg.Push(),
|
||||
# sg.Button("ONNX Export", key="onnx_export"),
|
||||
],
|
||||
]
|
||||
)
|
||||
|
||||
# columns
|
||||
layout = [[column1, column2]]
|
||||
# layout = [[sg.Column(layout, vertical_alignment="top", scrollable=True, expand_x=True, expand_y=True)]]
|
||||
window = sg.Window(
|
||||
f"{__name__.split('.')[0]}", layout, grab_anywhere=True, finalize=True
|
||||
) # , use_custom_titlebar=True)
|
||||
# for n in ["input_device", "output_device"]:
|
||||
# window[n].Widget.configure(justify="right")
|
||||
event, values = window.read(timeout=0.01)
|
||||
|
||||
def update_speaker() -> None:
|
||||
from . import utils
|
||||
|
||||
config_path = Path(values["config_path"])
|
||||
if config_path.exists() and config_path.is_file():
|
||||
hp = utils.get_hparams(values["config_path"])
|
||||
LOG.debug(f"Loaded config from {values['config_path']}")
|
||||
window["speaker"].update(
|
||||
values=list(hp.__dict__["spk"].keys()), set_to_index=0
|
||||
)
|
||||
|
||||
def update_devices() -> None:
|
||||
(
|
||||
input_devices,
|
||||
output_devices,
|
||||
input_device_indices,
|
||||
output_device_indices,
|
||||
) = get_devices()
|
||||
input_device_indices_reversed = {
|
||||
v: k for k, v in enumerate(input_device_indices)
|
||||
}
|
||||
output_device_indices_reversed = {
|
||||
v: k for k, v in enumerate(output_device_indices)
|
||||
}
|
||||
window["input_device"].update(
|
||||
values=input_devices, value=values["input_device"]
|
||||
)
|
||||
window["output_device"].update(
|
||||
values=output_devices, value=values["output_device"]
|
||||
)
|
||||
input_default, output_default = sd.default.device
|
||||
if values["input_device"] not in input_devices:
|
||||
window["input_device"].update(
|
||||
values=input_devices,
|
||||
set_to_index=input_device_indices_reversed.get(input_default, 0),
|
||||
)
|
||||
if values["output_device"] not in output_devices:
|
||||
window["output_device"].update(
|
||||
values=output_devices,
|
||||
set_to_index=output_device_indices_reversed.get(output_default, 0),
|
||||
)
|
||||
|
||||
PRESET_KEYS = [
|
||||
key
|
||||
for key in values.keys()
|
||||
if not any(exclude in key for exclude in ["preset", "browse"])
|
||||
]
|
||||
|
||||
def apply_preset(name: str) -> None:
|
||||
for key, value in load_presets()[name].items():
|
||||
if key in PRESET_KEYS:
|
||||
window[key].update(value)
|
||||
values[key] = value
|
||||
|
||||
default_name = list(load_presets().keys())[0]
|
||||
apply_preset(default_name)
|
||||
window["presets"].update(default_name)
|
||||
del default_name
|
||||
update_speaker()
|
||||
update_devices()
|
||||
# with ProcessPool(max_workers=1) as pool:
|
||||
# to support Linux
|
||||
with ProcessPool(
|
||||
max_workers=min(2, multiprocessing.cpu_count()),
|
||||
context=multiprocessing.get_context("spawn"),
|
||||
) as pool:
|
||||
future: None | ProcessFuture = None
|
||||
infer_futures: set[ProcessFuture] = set()
|
||||
while True:
|
||||
event, values = window.read(200)
|
||||
if event == sg.WIN_CLOSED:
|
||||
break
|
||||
if not event == sg.EVENT_TIMEOUT:
|
||||
LOG.info(f"Event {event}, values {values}")
|
||||
if event.endswith("_path"):
|
||||
for name in window.AllKeysDict:
|
||||
if str(name).endswith("_browse"):
|
||||
browser = window[name]
|
||||
if isinstance(browser, sg.Button):
|
||||
LOG.info(
|
||||
f"Updating browser {browser} to {Path(values[event]).parent}"
|
||||
)
|
||||
browser.InitialFolder = Path(values[event]).parent
|
||||
browser.update()
|
||||
else:
|
||||
LOG.warning(f"Browser {browser} is not a FileBrowse")
|
||||
window["transpose"].update(
|
||||
disabled=values["auto_predict_f0"],
|
||||
visible=not values["auto_predict_f0"],
|
||||
)
|
||||
|
||||
input_path = Path(values["input_path"])
|
||||
output_path = Path(values["output_path"])
|
||||
|
||||
if event == "add_preset":
|
||||
presets = add_preset(
|
||||
values["preset_name"], {key: values[key] for key in PRESET_KEYS}
|
||||
)
|
||||
window["presets"].update(values=list(presets.keys()))
|
||||
elif event == "delete_preset":
|
||||
presets = delete_preset(values["presets"])
|
||||
window["presets"].update(values=list(presets.keys()))
|
||||
elif event == "presets":
|
||||
apply_preset(values["presets"])
|
||||
update_speaker()
|
||||
elif event == "refresh_devices":
|
||||
update_devices()
|
||||
elif event == "config_path":
|
||||
update_speaker()
|
||||
elif event == "input_path":
|
||||
# Don't change the output path if it's already set
|
||||
if values["output_path"]:
|
||||
continue
|
||||
# Set a sensible default output path
|
||||
window.Element("output_path").Update(str(get_output_path(input_path)))
|
||||
elif event == "infer":
|
||||
if not input_path.exists() or not input_path.is_file():
|
||||
LOG.warning(f"Input path {input_path} does not exist.")
|
||||
continue
|
||||
if not validate_output_file_type(output_path):
|
||||
continue
|
||||
|
||||
try:
|
||||
from so_vits_svc_fork.inference.main import infer
|
||||
|
||||
LOG.info("Starting inference...")
|
||||
window["infer"].update(disabled=True)
|
||||
infer_future = pool.schedule(
|
||||
infer,
|
||||
kwargs=dict(
|
||||
# paths
|
||||
model_path=Path(values["model_path"]),
|
||||
output_path=output_path,
|
||||
input_path=input_path,
|
||||
config_path=Path(values["config_path"]),
|
||||
# svc config
|
||||
speaker=values["speaker"],
|
||||
cluster_model_path=Path(values["cluster_model_path"])
|
||||
if values["cluster_model_path"]
|
||||
else None,
|
||||
transpose=values["transpose"],
|
||||
auto_predict_f0=values["auto_predict_f0"],
|
||||
cluster_infer_ratio=values["cluster_infer_ratio"],
|
||||
noise_scale=values["noise_scale"],
|
||||
f0_method=values["f0_method"],
|
||||
# slice config
|
||||
db_thresh=values["silence_threshold"],
|
||||
pad_seconds=values["pad_seconds"],
|
||||
chunk_seconds=values["chunk_seconds"],
|
||||
absolute_thresh=values["absolute_thresh"],
|
||||
device="cpu"
|
||||
if not values["use_gpu"]
|
||||
else get_optimal_device(),
|
||||
),
|
||||
)
|
||||
infer_future.add_done_callback(
|
||||
lambda _future: after_inference(
|
||||
window, input_path, values["auto_play"], output_path
|
||||
)
|
||||
)
|
||||
infer_futures.add(infer_future)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
elif event == "play_input":
|
||||
if Path(values["input_path"]).exists():
|
||||
pool.schedule(play_audio, args=[Path(values["input_path"])])
|
||||
elif event == "start_vc":
|
||||
_, _, input_device_indices, output_device_indices = get_devices(
|
||||
update=False
|
||||
)
|
||||
from so_vits_svc_fork.inference.main import realtime
|
||||
|
||||
if future:
|
||||
LOG.info("Canceling previous task")
|
||||
future.cancel()
|
||||
future = pool.schedule(
|
||||
realtime,
|
||||
kwargs=dict(
|
||||
# paths
|
||||
model_path=Path(values["model_path"]),
|
||||
config_path=Path(values["config_path"]),
|
||||
speaker=values["speaker"],
|
||||
# svc config
|
||||
cluster_model_path=Path(values["cluster_model_path"])
|
||||
if values["cluster_model_path"]
|
||||
else None,
|
||||
transpose=values["transpose"],
|
||||
auto_predict_f0=values["auto_predict_f0"],
|
||||
cluster_infer_ratio=values["cluster_infer_ratio"],
|
||||
noise_scale=values["noise_scale"],
|
||||
f0_method=values["f0_method"],
|
||||
# slice config
|
||||
db_thresh=values["silence_threshold"],
|
||||
pad_seconds=values["pad_seconds"],
|
||||
chunk_seconds=values["chunk_seconds"],
|
||||
# realtime config
|
||||
crossfade_seconds=values["crossfade_seconds"],
|
||||
additional_infer_before_seconds=values[
|
||||
"additional_infer_before_seconds"
|
||||
],
|
||||
additional_infer_after_seconds=values[
|
||||
"additional_infer_after_seconds"
|
||||
],
|
||||
block_seconds=values["block_seconds"],
|
||||
version=int(values["realtime_algorithm"][0]),
|
||||
input_device=input_device_indices[
|
||||
window["input_device"].widget.current()
|
||||
],
|
||||
output_device=output_device_indices[
|
||||
window["output_device"].widget.current()
|
||||
],
|
||||
device=get_optimal_device() if values["use_gpu"] else "cpu",
|
||||
passthrough_original=values["passthrough_original"],
|
||||
),
|
||||
)
|
||||
elif event == "stop_vc":
|
||||
if future:
|
||||
future.cancel()
|
||||
future = None
|
||||
elif event == "onnx_export":
|
||||
try:
|
||||
raise NotImplementedError("ONNX export is not implemented yet.")
|
||||
from so_vits_svc_fork.modules.onnx._export import onnx_export
|
||||
|
||||
onnx_export(
|
||||
input_path=Path(values["model_path"]),
|
||||
output_path=Path(values["model_path"]).with_suffix(".onnx"),
|
||||
config_path=Path(values["config_path"]),
|
||||
device="cpu",
|
||||
)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
if future is not None and future.done():
|
||||
try:
|
||||
future.result()
|
||||
except Exception as e:
|
||||
LOG.error("Error in realtime: ")
|
||||
LOG.exception(e)
|
||||
future = None
|
||||
for future in copy(infer_futures):
|
||||
if future.done():
|
||||
try:
|
||||
future.result()
|
||||
except Exception as e:
|
||||
LOG.error("Error in inference: ")
|
||||
LOG.exception(e)
|
||||
infer_futures.remove(future)
|
||||
if future:
|
||||
future.cancel()
|
||||
window.close()
|
||||
@@ -0,0 +1,38 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
|
||||
class HParams:
|
||||
def __init__(self, **kwargs: Any) -> None:
|
||||
for k, v in kwargs.items():
|
||||
if type(v) == dict:
|
||||
v = HParams(**v)
|
||||
self[k] = v
|
||||
|
||||
def keys(self):
|
||||
return self.__dict__.keys()
|
||||
|
||||
def items(self):
|
||||
return self.__dict__.items()
|
||||
|
||||
def values(self):
|
||||
return self.__dict__.values()
|
||||
|
||||
def get(self, key: str, default: Any = None):
|
||||
return self.__dict__.get(key, default)
|
||||
|
||||
def __len__(self):
|
||||
return len(self.__dict__)
|
||||
|
||||
def __getitem__(self, key):
|
||||
return getattr(self, key)
|
||||
|
||||
def __setitem__(self, key, value):
|
||||
return setattr(self, key, value)
|
||||
|
||||
def __contains__(self, key):
|
||||
return key in self.__dict__
|
||||
|
||||
def __repr__(self):
|
||||
return self.__dict__.__repr__()
|
||||
@@ -0,0 +1,686 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from copy import deepcopy
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable, Iterable, Literal
|
||||
|
||||
import attrs
|
||||
import librosa
|
||||
import numpy as np
|
||||
import torch
|
||||
from cm_time import timer
|
||||
from numpy import dtype, float32, ndarray
|
||||
|
||||
import so_vits_svc_fork.f0
|
||||
from so_vits_svc_fork import cluster, utils
|
||||
|
||||
from ..modules.synthesizers import SynthesizerTrn
|
||||
from ..utils import get_optimal_device
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def pad_array(array_, target_length: int):
|
||||
current_length = array_.shape[0]
|
||||
if current_length >= target_length:
|
||||
return array_[
|
||||
(current_length - target_length)
|
||||
// 2 : (current_length - target_length)
|
||||
// 2
|
||||
+ target_length,
|
||||
...,
|
||||
]
|
||||
else:
|
||||
pad_width = target_length - current_length
|
||||
pad_left = pad_width // 2
|
||||
pad_right = pad_width - pad_left
|
||||
padded_arr = np.pad(
|
||||
array_, (pad_left, pad_right), "constant", constant_values=(0, 0)
|
||||
)
|
||||
return padded_arr
|
||||
|
||||
|
||||
@attrs.frozen(kw_only=True)
|
||||
class Chunk:
|
||||
is_speech: bool
|
||||
audio: ndarray[Any, dtype[float32]]
|
||||
start: int
|
||||
end: int
|
||||
|
||||
@property
|
||||
def duration(self) -> float32:
|
||||
# return self.end - self.start
|
||||
return float32(self.audio.shape[0])
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"Chunk(Speech: {self.is_speech}, {self.duration})"
|
||||
|
||||
|
||||
def split_silence(
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
top_db: int = 40,
|
||||
ref: float | Callable[[ndarray[Any, dtype[float32]]], float] = 1,
|
||||
frame_length: int = 2048,
|
||||
hop_length: int = 512,
|
||||
aggregate: Callable[[ndarray[Any, dtype[float32]]], float] = np.mean,
|
||||
chunk_size_max: int = 44100 * 10
|
||||
) -> Iterable[Chunk]:
|
||||
non_silence_indices = librosa.effects.split(
|
||||
audio,
|
||||
top_db=top_db,
|
||||
ref=ref,
|
||||
frame_length=frame_length,
|
||||
hop_length=hop_length,
|
||||
#aggregate=aggregate,
|
||||
)
|
||||
last_end = 0
|
||||
for start, end in non_silence_indices:
|
||||
if start != last_end:
|
||||
yield Chunk(
|
||||
is_speech=False, audio=audio[last_end:start], start=last_end, end=start
|
||||
)
|
||||
if end-start > chunk_size_max:
|
||||
chunk_count = (end-start) // chunk_size_max
|
||||
for i in range(0, chunk_count):
|
||||
yield Chunk(is_speech=True, audio=audio[start+(i*chunk_size_max):start+((i+1)*chunk_size_max)],
|
||||
start=start+(i*chunk_size_max), end=start+((i+1)*chunk_size_max))
|
||||
yield Chunk(is_speech=True, audio=audio[start+chunk_count*chunk_size_max:end],
|
||||
start=start+chunk_count*chunk_size_max, end=end)
|
||||
last_end=end
|
||||
else:
|
||||
yield Chunk(is_speech=True, audio=audio[start:end], start=start, end=end)
|
||||
last_end = end
|
||||
if last_end != len(audio):
|
||||
yield Chunk(
|
||||
is_speech=False, audio=audio[last_end:], start=last_end, end=len(audio)
|
||||
)
|
||||
|
||||
|
||||
class Svc:
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
net_g_path: Path | str,
|
||||
config_path: Path | str,
|
||||
device: torch.device | str | None = None,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
half: bool = False,
|
||||
):
|
||||
self.net_g_path = net_g_path
|
||||
if device is None:
|
||||
self.device = (get_optimal_device(),)
|
||||
else:
|
||||
self.device = torch.device(device)
|
||||
self.hps = utils.get_hparams(config_path)
|
||||
self.target_sample = self.hps.data.sampling_rate
|
||||
self.hop_size = self.hps.data.hop_length
|
||||
self.spk2id = self.hps.spk
|
||||
self.hubert_model = utils.get_hubert_model(
|
||||
self.device, self.hps.data.get("contentvec_final_proj", True)
|
||||
)
|
||||
self.dtype = torch.float16 if half else torch.float32
|
||||
self.contentvec_final_proj = self.hps.data.__dict__.get(
|
||||
"contentvec_final_proj", True
|
||||
)
|
||||
self.load_model()
|
||||
if cluster_model_path is not None and Path(cluster_model_path).exists():
|
||||
self.cluster_model = cluster.get_cluster_model(cluster_model_path)
|
||||
|
||||
def load_model(self):
|
||||
self.net_g = SynthesizerTrn(
|
||||
self.hps.data.filter_length // 2 + 1,
|
||||
self.hps.train.segment_size // self.hps.data.hop_length,
|
||||
**self.hps.model,
|
||||
)
|
||||
_ = utils.load_checkpoint(self.net_g_path, self.net_g, None)
|
||||
_ = self.net_g.eval().to(self.device, dtype=self.dtype)
|
||||
|
||||
def get_unit_f0(
|
||||
self,
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
tran: int,
|
||||
cluster_infer_ratio: float,
|
||||
speaker: int | str,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
):
|
||||
f0 = so_vits_svc_fork.f0.compute_f0(
|
||||
audio,
|
||||
sampling_rate=self.target_sample,
|
||||
hop_length=self.hop_size,
|
||||
method=f0_method,
|
||||
)
|
||||
f0, uv = so_vits_svc_fork.f0.interpolate_f0(f0)
|
||||
f0 = torch.as_tensor(f0, dtype=self.dtype, device=self.device)
|
||||
uv = torch.as_tensor(uv, dtype=self.dtype, device=self.device)
|
||||
f0 = f0 * 2 ** (tran / 12)
|
||||
f0 = f0.unsqueeze(0)
|
||||
uv = uv.unsqueeze(0)
|
||||
|
||||
c = utils.get_content(
|
||||
self.hubert_model,
|
||||
audio,
|
||||
self.device,
|
||||
self.target_sample,
|
||||
self.contentvec_final_proj,
|
||||
).to(self.dtype)
|
||||
c = utils.repeat_expand_2d(c.squeeze(0), f0.shape[1])
|
||||
|
||||
if cluster_infer_ratio != 0:
|
||||
cluster_c = cluster.get_cluster_center_result(
|
||||
self.cluster_model, c.cpu().numpy().T, speaker
|
||||
).T
|
||||
cluster_c = torch.FloatTensor(cluster_c).to(self.device)
|
||||
c = cluster_infer_ratio * cluster_c + (1 - cluster_infer_ratio) * c
|
||||
|
||||
c = c.unsqueeze(0)
|
||||
return c, f0, uv
|
||||
|
||||
def infer(
|
||||
self,
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
audio: ndarray[Any, dtype[float32]],
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
) -> tuple[torch.Tensor, int]:
|
||||
audio = audio.astype(np.float32)
|
||||
# get speaker id
|
||||
if isinstance(speaker, int):
|
||||
if len(self.spk2id.__dict__) >= speaker:
|
||||
speaker_id = speaker
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Speaker id {speaker} >= number of speakers {len(self.spk2id.__dict__)}"
|
||||
)
|
||||
else:
|
||||
if speaker in self.spk2id.__dict__:
|
||||
speaker_id = self.spk2id.__dict__[speaker]
|
||||
else:
|
||||
LOG.warning(f"Speaker {speaker} is not found. Use speaker 0 instead.")
|
||||
speaker_id = 0
|
||||
speaker_candidates = list(
|
||||
filter(lambda x: x[1] == speaker_id, self.spk2id.__dict__.items())
|
||||
)
|
||||
if len(speaker_candidates) > 1:
|
||||
raise ValueError(
|
||||
f"Speaker_id {speaker_id} is not unique. Candidates: {speaker_candidates}"
|
||||
)
|
||||
elif len(speaker_candidates) == 0:
|
||||
raise ValueError(f"Speaker_id {speaker_id} is not found.")
|
||||
speaker = speaker_candidates[0][0]
|
||||
sid = torch.LongTensor([int(speaker_id)]).to(self.device).unsqueeze(0)
|
||||
|
||||
# get unit f0
|
||||
c, f0, uv = self.get_unit_f0(
|
||||
audio, transpose, cluster_infer_ratio, speaker, f0_method
|
||||
)
|
||||
|
||||
# inference
|
||||
with torch.no_grad():
|
||||
with timer() as t:
|
||||
audio = self.net_g.infer(
|
||||
c,
|
||||
f0=f0,
|
||||
g=sid,
|
||||
uv=uv,
|
||||
predict_f0=auto_predict_f0,
|
||||
noice_scale=noise_scale,
|
||||
)[0, 0].data.float()
|
||||
audio_duration = audio.shape[-1] / self.target_sample
|
||||
LOG.info(
|
||||
f"Inferece time: {t.elapsed:.2f}s, RTF: {t.elapsed / audio_duration:.2f}"
|
||||
)
|
||||
torch.cuda.empty_cache()
|
||||
return audio, audio.shape[-1]
|
||||
|
||||
def infer_silence(
|
||||
self,
|
||||
audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
*,
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
# fade_seconds: float = 0.0,
|
||||
) -> np.ndarray[Any, np.dtype[np.float32]]:
|
||||
sr = self.target_sample
|
||||
result_audio = np.array([], dtype=np.float32)
|
||||
chunk_length_min = chunk_length_min = (
|
||||
int(
|
||||
min(
|
||||
sr / so_vits_svc_fork.f0.f0_min * 20 + 1,
|
||||
chunk_seconds * sr,
|
||||
)
|
||||
)
|
||||
// 2
|
||||
)
|
||||
for chunk in split_silence(
|
||||
audio,
|
||||
top_db=-db_thresh,
|
||||
frame_length=chunk_length_min * 2,
|
||||
hop_length=chunk_length_min,
|
||||
ref=1 if absolute_thresh else np.max,
|
||||
):
|
||||
LOG.info(f"Chunk: {chunk}")
|
||||
if not chunk.is_speech:
|
||||
audio_chunk_infer = np.zeros_like(chunk.audio)
|
||||
else:
|
||||
# pad
|
||||
pad_len = int(sr * pad_seconds)
|
||||
audio_chunk_pad = np.concatenate(
|
||||
[
|
||||
np.zeros([pad_len], dtype=np.float32),
|
||||
chunk.audio,
|
||||
np.zeros([pad_len], dtype=np.float32),
|
||||
]
|
||||
)
|
||||
audio_chunk_pad_infer_tensor, _ = self.infer(
|
||||
speaker,
|
||||
transpose,
|
||||
audio_chunk_pad,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
audio_chunk_pad_infer = audio_chunk_pad_infer_tensor.cpu().numpy()
|
||||
pad_len = int(self.target_sample * pad_seconds)
|
||||
cut_len_2 = (len(audio_chunk_pad_infer) - len(chunk.audio)) // 2
|
||||
audio_chunk_infer = audio_chunk_pad_infer[
|
||||
cut_len_2 : cut_len_2 + len(chunk.audio)
|
||||
]
|
||||
|
||||
# add fade
|
||||
# fade_len = int(self.target_sample * fade_seconds)
|
||||
# _audio[:fade_len] = _audio[:fade_len] * np.linspace(0, 1, fade_len)
|
||||
# _audio[-fade_len:] = _audio[-fade_len:] * np.linspace(1, 0, fade_len)
|
||||
|
||||
# empty cache
|
||||
torch.cuda.empty_cache()
|
||||
result_audio = np.concatenate([result_audio, audio_chunk_infer])
|
||||
result_audio = result_audio[: audio.shape[0]]
|
||||
return result_audio
|
||||
|
||||
|
||||
def sola_crossfade(
|
||||
first: ndarray[Any, dtype[float32]],
|
||||
second: ndarray[Any, dtype[float32]],
|
||||
crossfade_len: int,
|
||||
sola_search_len: int,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
cor_nom = np.convolve(
|
||||
second[: sola_search_len + crossfade_len],
|
||||
np.flip(first[-crossfade_len:]),
|
||||
"valid",
|
||||
)
|
||||
cor_den = np.sqrt(
|
||||
np.convolve(
|
||||
second[: sola_search_len + crossfade_len] ** 2,
|
||||
np.ones(crossfade_len),
|
||||
"valid",
|
||||
)
|
||||
+ 1e-8
|
||||
)
|
||||
sola_shift = np.argmax(cor_nom / cor_den)
|
||||
LOG.info(f"SOLA shift: {sola_shift}")
|
||||
second = second[sola_shift : sola_shift + len(second) - sola_search_len]
|
||||
return np.concatenate(
|
||||
[
|
||||
first[:-crossfade_len],
|
||||
first[-crossfade_len:] * np.linspace(1, 0, crossfade_len)
|
||||
+ second[:crossfade_len] * np.linspace(0, 1, crossfade_len),
|
||||
second[crossfade_len:],
|
||||
]
|
||||
)
|
||||
|
||||
|
||||
class Crossfader:
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
additional_infer_before_len: int,
|
||||
additional_infer_after_len: int,
|
||||
crossfade_len: int,
|
||||
sola_search_len: int = 384,
|
||||
) -> None:
|
||||
if additional_infer_before_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
if crossfade_len < 0:
|
||||
raise ValueError("crossfade_len must be >= 0")
|
||||
if additional_infer_after_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
if additional_infer_before_len < 0:
|
||||
raise ValueError("additional_infer_len must be >= 0")
|
||||
self.additional_infer_before_len = additional_infer_before_len
|
||||
self.additional_infer_after_len = additional_infer_after_len
|
||||
self.crossfade_len = crossfade_len
|
||||
self.sola_search_len = sola_search_len
|
||||
self.last_input_left = np.zeros(
|
||||
sola_search_len
|
||||
+ crossfade_len
|
||||
+ additional_infer_before_len
|
||||
+ additional_infer_after_len,
|
||||
dtype=np.float32,
|
||||
)
|
||||
self.last_infered_left = np.zeros(crossfade_len, dtype=np.float32)
|
||||
|
||||
def process(
|
||||
self, input_audio: ndarray[Any, dtype[float32]], *args, **kwargs: Any
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
"""
|
||||
chunks : ■■■■■■□□□□□□
|
||||
add last input:□■■■■■■
|
||||
■□□□□□□
|
||||
infer :□■■■■■■
|
||||
■□□□□□□
|
||||
crossfade :▲■■■■■
|
||||
▲□□□□□
|
||||
"""
|
||||
# check input
|
||||
if input_audio.ndim != 1:
|
||||
raise ValueError("Input audio must be 1-dimensional.")
|
||||
if (
|
||||
input_audio.shape[0] + self.additional_infer_before_len
|
||||
<= self.crossfade_len
|
||||
):
|
||||
raise ValueError(
|
||||
f"Input audio length ({input_audio.shape[0]}) + additional_infer_len ({self.additional_infer_before_len}) must be greater than crossfade_len ({self.crossfade_len})."
|
||||
)
|
||||
input_audio = input_audio.astype(np.float32)
|
||||
input_audio_len = len(input_audio)
|
||||
|
||||
# concat last input and infer
|
||||
input_audio_concat = np.concatenate([self.last_input_left, input_audio])
|
||||
del input_audio
|
||||
pad_len = 0
|
||||
if pad_len:
|
||||
infer_audio_concat = self.infer(
|
||||
np.pad(input_audio_concat, (pad_len, pad_len), mode="reflect"),
|
||||
*args,
|
||||
**kwargs,
|
||||
)[pad_len:-pad_len]
|
||||
else:
|
||||
infer_audio_concat = self.infer(input_audio_concat, *args, **kwargs)
|
||||
|
||||
# debug SOLA (using copy synthesis with a random shift)
|
||||
"""
|
||||
rs = int(np.random.uniform(-200,200))
|
||||
LOG.info(f"Debug random shift: {rs}")
|
||||
infer_audio_concat = np.roll(input_audio_concat, rs)
|
||||
"""
|
||||
|
||||
if len(infer_audio_concat) != len(input_audio_concat):
|
||||
raise ValueError(
|
||||
f"Inferred audio length ({len(infer_audio_concat)}) should be equal to input audio length ({len(input_audio_concat)})."
|
||||
)
|
||||
infer_audio_to_use = infer_audio_concat[
|
||||
-(
|
||||
self.sola_search_len
|
||||
+ self.crossfade_len
|
||||
+ input_audio_len
|
||||
+ self.additional_infer_after_len
|
||||
) : -self.additional_infer_after_len
|
||||
]
|
||||
assert (
|
||||
len(infer_audio_to_use)
|
||||
== input_audio_len + self.sola_search_len + self.crossfade_len
|
||||
), f"{len(infer_audio_to_use)} != {input_audio_len + self.sola_search_len + self.cross_fade_len}"
|
||||
_audio = sola_crossfade(
|
||||
self.last_infered_left,
|
||||
infer_audio_to_use,
|
||||
self.crossfade_len,
|
||||
self.sola_search_len,
|
||||
)
|
||||
result_audio = _audio[: -self.crossfade_len]
|
||||
assert (
|
||||
len(result_audio) == input_audio_len
|
||||
), f"{len(result_audio)} != {input_audio_len}"
|
||||
|
||||
# update last input and inferred
|
||||
self.last_input_left = input_audio_concat[
|
||||
-(
|
||||
self.sola_search_len
|
||||
+ self.crossfade_len
|
||||
+ self.additional_infer_before_len
|
||||
+ self.additional_infer_after_len
|
||||
) :
|
||||
]
|
||||
self.last_infered_left = _audio[-self.crossfade_len :]
|
||||
return result_audio
|
||||
|
||||
def infer(
|
||||
self, input_audio: ndarray[Any, dtype[float32]]
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
return input_audio
|
||||
|
||||
|
||||
class RealtimeVC(Crossfader):
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
svc_model: Svc,
|
||||
crossfade_len: int = 3840,
|
||||
additional_infer_before_len: int = 7680,
|
||||
additional_infer_after_len: int = 7680,
|
||||
split: bool = True,
|
||||
) -> None:
|
||||
self.svc_model = svc_model
|
||||
self.split = split
|
||||
super().__init__(
|
||||
crossfade_len=crossfade_len,
|
||||
additional_infer_before_len=additional_infer_before_len,
|
||||
additional_infer_after_len=additional_infer_after_len,
|
||||
)
|
||||
|
||||
def process(
|
||||
self,
|
||||
input_audio: ndarray[Any, dtype[float32]],
|
||||
*args: Any,
|
||||
**kwargs: Any,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
return super().process(input_audio, *args, **kwargs)
|
||||
|
||||
def infer(
|
||||
self,
|
||||
input_audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
# infer
|
||||
if self.split:
|
||||
return self.svc_model.infer_silence(
|
||||
audio=input_audio,
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=True,
|
||||
)
|
||||
else:
|
||||
rms = np.sqrt(np.mean(input_audio**2))
|
||||
min_rms = 10 ** (db_thresh / 20)
|
||||
if rms < min_rms:
|
||||
LOG.info(f"Skip silence: RMS={rms:.2f} < {min_rms:.2f}")
|
||||
return np.zeros_like(input_audio)
|
||||
else:
|
||||
LOG.info(f"Start inference: RMS={rms:.2f} >= {min_rms:.2f}")
|
||||
infered_audio_c, _ = self.svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
audio=input_audio,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
return infered_audio_c.cpu().numpy()
|
||||
|
||||
|
||||
class RealtimeVC2:
|
||||
chunk_store: list[Chunk]
|
||||
|
||||
def __init__(self, svc_model: Svc) -> None:
|
||||
self.input_audio_store = np.array([], dtype=np.float32)
|
||||
self.chunk_store = []
|
||||
self.svc_model = svc_model
|
||||
|
||||
def process(
|
||||
self,
|
||||
input_audio: np.ndarray[Any, np.dtype[np.float32]],
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
transpose: int,
|
||||
cluster_infer_ratio: float = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal[
|
||||
"crepe", "crepe-tiny", "parselmouth", "dio", "harvest"
|
||||
] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
chunk_seconds: float = 0.5,
|
||||
) -> ndarray[Any, dtype[float32]]:
|
||||
def infer(audio: ndarray[Any, dtype[float32]]) -> ndarray[Any, dtype[float32]]:
|
||||
infered_audio_c, _ = self.svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
audio=audio,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
)
|
||||
return infered_audio_c.cpu().numpy()
|
||||
|
||||
self.input_audio_store = np.concatenate([self.input_audio_store, input_audio])
|
||||
LOG.info(f"input_audio_store: {self.input_audio_store.shape}")
|
||||
sr = self.svc_model.target_sample
|
||||
chunk_length_min = (
|
||||
int(min(sr / so_vits_svc_fork.f0.f0_min * 20 + 1, chunk_seconds * sr)) // 2
|
||||
)
|
||||
LOG.info(f"Chunk length min: {chunk_length_min}")
|
||||
chunk_list = list(
|
||||
split_silence(
|
||||
self.input_audio_store,
|
||||
-db_thresh,
|
||||
frame_length=chunk_length_min * 2,
|
||||
hop_length=chunk_length_min,
|
||||
ref=1, # use absolute threshold
|
||||
)
|
||||
)
|
||||
assert len(chunk_list) > 0
|
||||
LOG.info(f"Chunk list: {chunk_list}")
|
||||
# do not infer LAST incomplete is_speech chunk and save to store
|
||||
if chunk_list[-1].is_speech:
|
||||
self.input_audio_store = chunk_list.pop().audio
|
||||
else:
|
||||
self.input_audio_store = np.array([], dtype=np.float32)
|
||||
|
||||
# infer complete is_speech chunk and save to store
|
||||
self.chunk_store.extend(
|
||||
[
|
||||
attrs.evolve(c, audio=infer(c.audio) if c.is_speech else c.audio)
|
||||
for c in chunk_list
|
||||
]
|
||||
)
|
||||
|
||||
# calculate lengths and determine compress rate
|
||||
total_speech_len = sum(
|
||||
[c.duration if c.is_speech else 0 for c in self.chunk_store]
|
||||
)
|
||||
total_silence_len = sum(
|
||||
[c.duration if not c.is_speech else 0 for c in self.chunk_store]
|
||||
)
|
||||
input_audio_len = input_audio.shape[0]
|
||||
silence_compress_rate = total_silence_len / max(
|
||||
0, input_audio_len - total_speech_len
|
||||
)
|
||||
LOG.info(
|
||||
f"Total speech len: {total_speech_len}, silence len: {total_silence_len}, silence compress rate: {silence_compress_rate}"
|
||||
)
|
||||
|
||||
# generate output audio
|
||||
output_audio = np.array([], dtype=np.float32)
|
||||
break_flag = False
|
||||
LOG.info(f"Chunk store: {self.chunk_store}")
|
||||
for chunk in deepcopy(self.chunk_store):
|
||||
compress_rate = 1 if chunk.is_speech else silence_compress_rate
|
||||
left_len = input_audio_len - output_audio.shape[0]
|
||||
# calculate chunk duration
|
||||
chunk_duration_output = int(min(chunk.duration / compress_rate, left_len))
|
||||
chunk_duration_input = int(min(chunk.duration, left_len * compress_rate))
|
||||
LOG.info(
|
||||
f"Chunk duration output: {chunk_duration_output}, input: {chunk_duration_input}, left len: {left_len}"
|
||||
)
|
||||
|
||||
# remove chunk from store
|
||||
self.chunk_store.pop(0)
|
||||
if chunk.duration > chunk_duration_input:
|
||||
left_chunk = attrs.evolve(
|
||||
chunk, audio=chunk.audio[chunk_duration_input:]
|
||||
)
|
||||
chunk = attrs.evolve(chunk, audio=chunk.audio[:chunk_duration_input])
|
||||
|
||||
self.chunk_store.insert(0, left_chunk)
|
||||
break_flag = True
|
||||
|
||||
if chunk.is_speech:
|
||||
# if is_speech, just concat
|
||||
output_audio = np.concatenate([output_audio, chunk.audio])
|
||||
else:
|
||||
# if is_silence, concat with zeros and compress with silence_compress_rate
|
||||
output_audio = np.concatenate(
|
||||
[
|
||||
output_audio,
|
||||
np.zeros(
|
||||
chunk_duration_output,
|
||||
dtype=np.float32,
|
||||
),
|
||||
]
|
||||
)
|
||||
|
||||
if break_flag:
|
||||
break
|
||||
LOG.info(f"Chunk store: {self.chunk_store}, output_audio: {output_audio.shape}")
|
||||
# make same length (errors)
|
||||
output_audio = output_audio[:input_audio_len]
|
||||
output_audio = np.concatenate(
|
||||
[
|
||||
output_audio,
|
||||
np.zeros(input_audio_len - output_audio.shape[0], dtype=np.float32),
|
||||
]
|
||||
)
|
||||
return output_audio
|
||||
@@ -0,0 +1,226 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Literal
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile
|
||||
import torch
|
||||
from cm_time import timer
|
||||
|
||||
from so_vits_svc_fork.inference.core import RealtimeVC, RealtimeVC2, Svc
|
||||
from so_vits_svc_fork.utils import get_optimal_device
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def infer(
|
||||
*,
|
||||
# paths
|
||||
input_path: Path | str,
|
||||
output_path: Path | str,
|
||||
model_path: Path | str,
|
||||
config_path: Path | str,
|
||||
# svc config
|
||||
speaker: int | str,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
absolute_thresh: bool = False,
|
||||
device: str | torch.device = get_optimal_device(),
|
||||
):
|
||||
model_path = Path(model_path)
|
||||
output_path = Path(output_path)
|
||||
input_path = Path(input_path)
|
||||
config_path = Path(config_path)
|
||||
cluster_model_path = Path(cluster_model_path) if cluster_model_path else None
|
||||
svc_model = Svc(
|
||||
net_g_path=model_path.as_posix(),
|
||||
config_path=config_path.as_posix(),
|
||||
cluster_model_path=cluster_model_path.as_posix()
|
||||
if cluster_model_path
|
||||
else None,
|
||||
device=device,
|
||||
)
|
||||
|
||||
audio, _ = librosa.load(input_path, sr=svc_model.target_sample)
|
||||
audio = svc_model.infer_silence(
|
||||
audio.astype(np.float32),
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
db_thresh=db_thresh,
|
||||
pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
absolute_thresh=absolute_thresh,
|
||||
)
|
||||
|
||||
soundfile.write(output_path, audio, svc_model.target_sample)
|
||||
|
||||
|
||||
def realtime(
|
||||
*,
|
||||
# paths
|
||||
model_path: Path | str,
|
||||
config_path: Path | str,
|
||||
# svc config
|
||||
speaker: str,
|
||||
cluster_model_path: Path | str | None = None,
|
||||
transpose: int = 0,
|
||||
auto_predict_f0: bool = False,
|
||||
cluster_infer_ratio: float = 0,
|
||||
noise_scale: float = 0.4,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
# slice config
|
||||
db_thresh: int = -40,
|
||||
pad_seconds: float = 0.5,
|
||||
chunk_seconds: float = 0.5,
|
||||
# realtime config
|
||||
crossfade_seconds: float = 0.05,
|
||||
additional_infer_before_seconds: float = 0.2,
|
||||
additional_infer_after_seconds: float = 0.1,
|
||||
block_seconds: float = 0.5,
|
||||
version: int = 2,
|
||||
input_device: int | str | None = None,
|
||||
output_device: int | str | None = None,
|
||||
device: str | torch.device = get_optimal_device(),
|
||||
passthrough_original: bool = False,
|
||||
):
|
||||
import sounddevice as sd
|
||||
|
||||
model_path = Path(model_path)
|
||||
config_path = Path(config_path)
|
||||
cluster_model_path = Path(cluster_model_path) if cluster_model_path else None
|
||||
svc_model = Svc(
|
||||
net_g_path=model_path.as_posix(),
|
||||
config_path=config_path.as_posix(),
|
||||
cluster_model_path=cluster_model_path.as_posix()
|
||||
if cluster_model_path
|
||||
else None,
|
||||
device=device,
|
||||
)
|
||||
|
||||
LOG.info("Creating realtime model...")
|
||||
if version == 1:
|
||||
model = RealtimeVC(
|
||||
svc_model=svc_model,
|
||||
crossfade_len=int(crossfade_seconds * svc_model.target_sample),
|
||||
additional_infer_before_len=int(
|
||||
additional_infer_before_seconds * svc_model.target_sample
|
||||
),
|
||||
additional_infer_after_len=int(
|
||||
additional_infer_after_seconds * svc_model.target_sample
|
||||
),
|
||||
)
|
||||
else:
|
||||
model = RealtimeVC2(
|
||||
svc_model=svc_model,
|
||||
)
|
||||
|
||||
# LOG all device info
|
||||
devices = sd.query_devices()
|
||||
LOG.info(f"Device: {devices}")
|
||||
if isinstance(input_device, str):
|
||||
input_device_candidates = [
|
||||
i for i, d in enumerate(devices) if d["name"] == input_device
|
||||
]
|
||||
if len(input_device_candidates) == 0:
|
||||
LOG.warning(f"Input device {input_device} not found, using default")
|
||||
input_device = None
|
||||
else:
|
||||
input_device = input_device_candidates[0]
|
||||
if isinstance(output_device, str):
|
||||
output_device_candidates = [
|
||||
i for i, d in enumerate(devices) if d["name"] == output_device
|
||||
]
|
||||
if len(output_device_candidates) == 0:
|
||||
LOG.warning(f"Output device {output_device} not found, using default")
|
||||
output_device = None
|
||||
else:
|
||||
output_device = output_device_candidates[0]
|
||||
if input_device is None or input_device >= len(devices):
|
||||
input_device = sd.default.device[0]
|
||||
if output_device is None or output_device >= len(devices):
|
||||
output_device = sd.default.device[1]
|
||||
LOG.info(
|
||||
f"Input Device: {devices[input_device]['name']}, Output Device: {devices[output_device]['name']}"
|
||||
)
|
||||
|
||||
# the model RTL is somewhat significantly high only in the first inference
|
||||
# there could be no better way to warm up the model than to do a dummy inference
|
||||
# (there are not differences in the behavior of the model between the first and the later inferences)
|
||||
# so we do a dummy inference to warm up the model (1 second of audio)
|
||||
LOG.info("Warming up the model...")
|
||||
svc_model.infer(
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
audio=np.zeros(svc_model.target_sample, dtype=np.float32),
|
||||
)
|
||||
|
||||
def callback(
|
||||
indata: np.ndarray,
|
||||
outdata: np.ndarray,
|
||||
frames: int,
|
||||
time: int,
|
||||
status: sd.CallbackFlags,
|
||||
) -> None:
|
||||
LOG.debug(
|
||||
f"Frames: {frames}, Status: {status}, Shape: {indata.shape}, Time: {time}"
|
||||
)
|
||||
|
||||
kwargs = dict(
|
||||
input_audio=indata.mean(axis=1).astype(np.float32),
|
||||
# svc config
|
||||
speaker=speaker,
|
||||
transpose=transpose,
|
||||
auto_predict_f0=auto_predict_f0,
|
||||
cluster_infer_ratio=cluster_infer_ratio,
|
||||
noise_scale=noise_scale,
|
||||
f0_method=f0_method,
|
||||
# slice config
|
||||
db_thresh=db_thresh,
|
||||
# pad_seconds=pad_seconds,
|
||||
chunk_seconds=chunk_seconds,
|
||||
)
|
||||
if version == 1:
|
||||
kwargs["pad_seconds"] = pad_seconds
|
||||
with timer() as t:
|
||||
inference = model.process(
|
||||
**kwargs,
|
||||
).reshape(-1, 1)
|
||||
if passthrough_original:
|
||||
outdata[:] = (indata + inference) / 2
|
||||
else:
|
||||
outdata[:] = inference
|
||||
rtf = t.elapsed / block_seconds
|
||||
LOG.info(f"Realtime inference time: {t.elapsed:.3f}s, RTF: {rtf:.3f}")
|
||||
if rtf > 1:
|
||||
LOG.warning("RTF is too high, consider increasing block_seconds")
|
||||
|
||||
with sd.Stream(
|
||||
device=(input_device, output_device),
|
||||
channels=1,
|
||||
callback=callback,
|
||||
samplerate=svc_model.target_sample,
|
||||
blocksize=int(block_seconds * svc_model.target_sample),
|
||||
latency="low",
|
||||
) as stream:
|
||||
LOG.info(f"Latency: {stream.latency}")
|
||||
while True:
|
||||
sd.sleep(1000)
|
||||
@@ -0,0 +1,54 @@
|
||||
import os
|
||||
import sys
|
||||
from logging import (
|
||||
DEBUG,
|
||||
INFO,
|
||||
FileHandler,
|
||||
StreamHandler,
|
||||
basicConfig,
|
||||
captureWarnings,
|
||||
getLogger,
|
||||
)
|
||||
from pathlib import Path
|
||||
|
||||
from rich.logging import RichHandler
|
||||
|
||||
LOGGER_INIT = False
|
||||
|
||||
|
||||
def init_logger() -> None:
|
||||
global LOGGER_INIT
|
||||
if LOGGER_INIT:
|
||||
return
|
||||
|
||||
IS_TEST = "test" in Path.cwd().stem
|
||||
package_name = sys.modules[__name__].__package__
|
||||
basicConfig(
|
||||
level=INFO,
|
||||
format="%(asctime)s %(message)s",
|
||||
datefmt="[%X]",
|
||||
handlers=[
|
||||
StreamHandler() if is_notebook() else RichHandler(),
|
||||
FileHandler(f"{package_name}.log"),
|
||||
],
|
||||
)
|
||||
if IS_TEST:
|
||||
getLogger(package_name).setLevel(DEBUG)
|
||||
captureWarnings(True)
|
||||
LOGGER_INIT = True
|
||||
|
||||
|
||||
def is_notebook():
|
||||
try:
|
||||
from IPython import get_ipython
|
||||
|
||||
if "IPKernelApp" not in get_ipython().config: # pragma: no cover
|
||||
raise ImportError("console")
|
||||
return False
|
||||
if "VSCODE_PID" in os.environ: # pragma: no cover
|
||||
raise ImportError("vscode")
|
||||
return False
|
||||
except Exception:
|
||||
return False
|
||||
else: # pragma: no cover
|
||||
return True
|
||||
@@ -0,0 +1,488 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
from so_vits_svc_fork.modules import commons
|
||||
from so_vits_svc_fork.modules.modules import LayerNorm
|
||||
|
||||
|
||||
class FFT(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers=1,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
proximal_bias=False,
|
||||
proximal_init=True,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
proximal_bias=proximal_bias,
|
||||
proximal_init=proximal_init,
|
||||
)
|
||||
)
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
causal=True,
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(
|
||||
device=x.device, dtype=x.dtype
|
||||
)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
window_size=4,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
window_size=window_size,
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
)
|
||||
)
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
attn_mask = x_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.attn_layers[i](x, x, attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Decoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size=1,
|
||||
p_dropout=0.0,
|
||||
proximal_bias=False,
|
||||
proximal_init=True,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.self_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_0 = nn.ModuleList()
|
||||
self.encdec_attn_layers = nn.ModuleList()
|
||||
self.norm_layers_1 = nn.ModuleList()
|
||||
self.ffn_layers = nn.ModuleList()
|
||||
self.norm_layers_2 = nn.ModuleList()
|
||||
for i in range(self.n_layers):
|
||||
self.self_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
n_heads,
|
||||
p_dropout=p_dropout,
|
||||
proximal_bias=proximal_bias,
|
||||
proximal_init=proximal_init,
|
||||
)
|
||||
)
|
||||
self.norm_layers_0.append(LayerNorm(hidden_channels))
|
||||
self.encdec_attn_layers.append(
|
||||
MultiHeadAttention(
|
||||
hidden_channels, hidden_channels, n_heads, p_dropout=p_dropout
|
||||
)
|
||||
)
|
||||
self.norm_layers_1.append(LayerNorm(hidden_channels))
|
||||
self.ffn_layers.append(
|
||||
FFN(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
causal=True,
|
||||
)
|
||||
)
|
||||
self.norm_layers_2.append(LayerNorm(hidden_channels))
|
||||
|
||||
def forward(self, x, x_mask, h, h_mask):
|
||||
"""
|
||||
x: decoder input
|
||||
h: encoder output
|
||||
"""
|
||||
self_attn_mask = commons.subsequent_mask(x_mask.size(2)).to(
|
||||
device=x.device, dtype=x.dtype
|
||||
)
|
||||
encdec_attn_mask = h_mask.unsqueeze(2) * x_mask.unsqueeze(-1)
|
||||
x = x * x_mask
|
||||
for i in range(self.n_layers):
|
||||
y = self.self_attn_layers[i](x, x, self_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_0[i](x + y)
|
||||
|
||||
y = self.encdec_attn_layers[i](x, h, encdec_attn_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_1[i](x + y)
|
||||
|
||||
y = self.ffn_layers[i](x, x_mask)
|
||||
y = self.drop(y)
|
||||
x = self.norm_layers_2[i](x + y)
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class MultiHeadAttention(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
out_channels,
|
||||
n_heads,
|
||||
p_dropout=0.0,
|
||||
window_size=None,
|
||||
heads_share=True,
|
||||
block_length=None,
|
||||
proximal_bias=False,
|
||||
proximal_init=False,
|
||||
):
|
||||
super().__init__()
|
||||
assert channels % n_heads == 0
|
||||
|
||||
self.channels = channels
|
||||
self.out_channels = out_channels
|
||||
self.n_heads = n_heads
|
||||
self.p_dropout = p_dropout
|
||||
self.window_size = window_size
|
||||
self.heads_share = heads_share
|
||||
self.block_length = block_length
|
||||
self.proximal_bias = proximal_bias
|
||||
self.proximal_init = proximal_init
|
||||
self.attn = None
|
||||
|
||||
self.k_channels = channels // n_heads
|
||||
self.conv_q = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_k = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_v = nn.Conv1d(channels, channels, 1)
|
||||
self.conv_o = nn.Conv1d(channels, out_channels, 1)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if window_size is not None:
|
||||
n_heads_rel = 1 if heads_share else n_heads
|
||||
rel_stddev = self.k_channels**-0.5
|
||||
self.emb_rel_k = nn.Parameter(
|
||||
torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels)
|
||||
* rel_stddev
|
||||
)
|
||||
self.emb_rel_v = nn.Parameter(
|
||||
torch.randn(n_heads_rel, window_size * 2 + 1, self.k_channels)
|
||||
* rel_stddev
|
||||
)
|
||||
|
||||
nn.init.xavier_uniform_(self.conv_q.weight)
|
||||
nn.init.xavier_uniform_(self.conv_k.weight)
|
||||
nn.init.xavier_uniform_(self.conv_v.weight)
|
||||
if proximal_init:
|
||||
with torch.no_grad():
|
||||
self.conv_k.weight.copy_(self.conv_q.weight)
|
||||
self.conv_k.bias.copy_(self.conv_q.bias)
|
||||
|
||||
def forward(self, x, c, attn_mask=None):
|
||||
q = self.conv_q(x)
|
||||
k = self.conv_k(c)
|
||||
v = self.conv_v(c)
|
||||
|
||||
x, self.attn = self.attention(q, k, v, mask=attn_mask)
|
||||
|
||||
x = self.conv_o(x)
|
||||
return x
|
||||
|
||||
def attention(self, query, key, value, mask=None):
|
||||
# reshape [b, d, t] -> [b, n_h, t, d_k]
|
||||
b, d, t_s, t_t = (*key.size(), query.size(2))
|
||||
query = query.view(b, self.n_heads, self.k_channels, t_t).transpose(2, 3)
|
||||
key = key.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
value = value.view(b, self.n_heads, self.k_channels, t_s).transpose(2, 3)
|
||||
|
||||
scores = torch.matmul(query / math.sqrt(self.k_channels), key.transpose(-2, -1))
|
||||
if self.window_size is not None:
|
||||
assert (
|
||||
t_s == t_t
|
||||
), "Relative attention is only available for self-attention."
|
||||
key_relative_embeddings = self._get_relative_embeddings(self.emb_rel_k, t_s)
|
||||
rel_logits = self._matmul_with_relative_keys(
|
||||
query / math.sqrt(self.k_channels), key_relative_embeddings
|
||||
)
|
||||
scores_local = self._relative_position_to_absolute_position(rel_logits)
|
||||
scores = scores + scores_local
|
||||
if self.proximal_bias:
|
||||
assert t_s == t_t, "Proximal bias is only available for self-attention."
|
||||
scores = scores + self._attention_bias_proximal(t_s).to(
|
||||
device=scores.device, dtype=scores.dtype
|
||||
)
|
||||
if mask is not None:
|
||||
scores = scores.masked_fill(mask == 0, -1e4)
|
||||
if self.block_length is not None:
|
||||
assert (
|
||||
t_s == t_t
|
||||
), "Local attention is only available for self-attention."
|
||||
block_mask = (
|
||||
torch.ones_like(scores)
|
||||
.triu(-self.block_length)
|
||||
.tril(self.block_length)
|
||||
)
|
||||
scores = scores.masked_fill(block_mask == 0, -1e4)
|
||||
p_attn = F.softmax(scores, dim=-1) # [b, n_h, t_t, t_s]
|
||||
p_attn = self.drop(p_attn)
|
||||
output = torch.matmul(p_attn, value)
|
||||
if self.window_size is not None:
|
||||
relative_weights = self._absolute_position_to_relative_position(p_attn)
|
||||
value_relative_embeddings = self._get_relative_embeddings(
|
||||
self.emb_rel_v, t_s
|
||||
)
|
||||
output = output + self._matmul_with_relative_values(
|
||||
relative_weights, value_relative_embeddings
|
||||
)
|
||||
output = (
|
||||
output.transpose(2, 3).contiguous().view(b, d, t_t)
|
||||
) # [b, n_h, t_t, d_k] -> [b, d, t_t]
|
||||
return output, p_attn
|
||||
|
||||
def _matmul_with_relative_values(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, m]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, d]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0))
|
||||
return ret
|
||||
|
||||
def _matmul_with_relative_keys(self, x, y):
|
||||
"""
|
||||
x: [b, h, l, d]
|
||||
y: [h or 1, m, d]
|
||||
ret: [b, h, l, m]
|
||||
"""
|
||||
ret = torch.matmul(x, y.unsqueeze(0).transpose(-2, -1))
|
||||
return ret
|
||||
|
||||
def _get_relative_embeddings(self, relative_embeddings, length):
|
||||
2 * self.window_size + 1
|
||||
# Pad first before slice to avoid using cond ops.
|
||||
pad_length = max(length - (self.window_size + 1), 0)
|
||||
slice_start_position = max((self.window_size + 1) - length, 0)
|
||||
slice_end_position = slice_start_position + 2 * length - 1
|
||||
if pad_length > 0:
|
||||
padded_relative_embeddings = F.pad(
|
||||
relative_embeddings,
|
||||
commons.convert_pad_shape([[0, 0], [pad_length, pad_length], [0, 0]]),
|
||||
)
|
||||
else:
|
||||
padded_relative_embeddings = relative_embeddings
|
||||
used_relative_embeddings = padded_relative_embeddings[
|
||||
:, slice_start_position:slice_end_position
|
||||
]
|
||||
return used_relative_embeddings
|
||||
|
||||
def _relative_position_to_absolute_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, 2*l-1]
|
||||
ret: [b, h, l, l]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# Concat columns of pad to shift from relative to absolute indexing.
|
||||
x = F.pad(x, commons.convert_pad_shape([[0, 0], [0, 0], [0, 0], [0, 1]]))
|
||||
|
||||
# Concat extra elements so to add up to shape (len+1, 2*len-1).
|
||||
x_flat = x.view([batch, heads, length * 2 * length])
|
||||
x_flat = F.pad(
|
||||
x_flat, commons.convert_pad_shape([[0, 0], [0, 0], [0, length - 1]])
|
||||
)
|
||||
|
||||
# Reshape and slice out the padded elements.
|
||||
x_final = x_flat.view([batch, heads, length + 1, 2 * length - 1])[
|
||||
:, :, :length, length - 1 :
|
||||
]
|
||||
return x_final
|
||||
|
||||
def _absolute_position_to_relative_position(self, x):
|
||||
"""
|
||||
x: [b, h, l, l]
|
||||
ret: [b, h, l, 2*l-1]
|
||||
"""
|
||||
batch, heads, length, _ = x.size()
|
||||
# pad along column
|
||||
x = F.pad(
|
||||
x, commons.convert_pad_shape([[0, 0], [0, 0], [0, 0], [0, length - 1]])
|
||||
)
|
||||
x_flat = x.view([batch, heads, length**2 + length * (length - 1)])
|
||||
# add 0's in the beginning that will skew the elements after reshape
|
||||
x_flat = F.pad(x_flat, commons.convert_pad_shape([[0, 0], [0, 0], [length, 0]]))
|
||||
x_final = x_flat.view([batch, heads, length, 2 * length])[:, :, :, 1:]
|
||||
return x_final
|
||||
|
||||
def _attention_bias_proximal(self, length):
|
||||
"""Bias for self-attention to encourage attention to close positions.
|
||||
Args:
|
||||
length: an integer scalar.
|
||||
Returns:
|
||||
a Tensor with shape [1, 1, length, length]
|
||||
"""
|
||||
r = torch.arange(length, dtype=torch.float32)
|
||||
diff = torch.unsqueeze(r, 0) - torch.unsqueeze(r, 1)
|
||||
return torch.unsqueeze(torch.unsqueeze(-torch.log1p(torch.abs(diff)), 0), 0)
|
||||
|
||||
|
||||
class FFN(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
filter_channels,
|
||||
kernel_size,
|
||||
p_dropout=0.0,
|
||||
activation=None,
|
||||
causal=False,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.activation = activation
|
||||
self.causal = causal
|
||||
|
||||
if causal:
|
||||
self.padding = self._causal_padding
|
||||
else:
|
||||
self.padding = self._same_padding
|
||||
|
||||
self.conv_1 = nn.Conv1d(in_channels, filter_channels, kernel_size)
|
||||
self.conv_2 = nn.Conv1d(filter_channels, out_channels, kernel_size)
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x = self.conv_1(self.padding(x * x_mask))
|
||||
if self.activation == "gelu":
|
||||
x = x * torch.sigmoid(1.702 * x)
|
||||
else:
|
||||
x = torch.relu(x)
|
||||
x = self.drop(x)
|
||||
x = self.conv_2(self.padding(x * x_mask))
|
||||
return x * x_mask
|
||||
|
||||
def _causal_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = self.kernel_size - 1
|
||||
pad_r = 0
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
|
||||
def _same_padding(self, x):
|
||||
if self.kernel_size == 1:
|
||||
return x
|
||||
pad_l = (self.kernel_size - 1) // 2
|
||||
pad_r = self.kernel_size // 2
|
||||
padding = [[0, 0], [0, 0], [pad_l, pad_r]]
|
||||
x = F.pad(x, commons.convert_pad_shape(padding))
|
||||
return x
|
||||
@@ -0,0 +1,132 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from torch import Tensor
|
||||
|
||||
|
||||
def slice_segments(x: Tensor, starts: Tensor, length: int) -> Tensor:
|
||||
if length is None:
|
||||
return x
|
||||
length = min(length, x.size(-1))
|
||||
x_slice = torch.zeros((x.size()[:-1] + (length,)), dtype=x.dtype, device=x.device)
|
||||
ends = starts + length
|
||||
for i, (start, end) in enumerate(zip(starts, ends)):
|
||||
# LOG.debug(i, start, end, x.size(), x[i, ..., start:end].size(), x_slice.size())
|
||||
# x_slice[i, ...] = x[i, ..., start:end] need to pad
|
||||
# x_slice[i, ..., :end - start] = x[i, ..., start:end] this does not work
|
||||
x_slice[i, ...] = F.pad(x[i, ..., start:end], (0, max(0, length - x.size(-1))))
|
||||
return x_slice
|
||||
|
||||
|
||||
def rand_slice_segments_with_pitch(
|
||||
x: Tensor, f0: Tensor, x_lengths: Tensor | int | None, segment_size: int | None
|
||||
):
|
||||
if segment_size is None:
|
||||
return x, f0, torch.arange(x.size(0), device=x.device)
|
||||
if x_lengths is None:
|
||||
x_lengths = x.size(-1) * torch.ones(
|
||||
x.size(0), dtype=torch.long, device=x.device
|
||||
)
|
||||
# slice_starts = (torch.rand(z.size(0), device=z.device) * (z_lengths - segment_size)).long()
|
||||
slice_starts = (
|
||||
torch.rand(x.size(0), device=x.device)
|
||||
* torch.max(
|
||||
x_lengths - segment_size, torch.zeros_like(x_lengths, device=x.device)
|
||||
)
|
||||
).long()
|
||||
z_slice = slice_segments(x, slice_starts, segment_size)
|
||||
f0_slice = slice_segments(f0, slice_starts, segment_size)
|
||||
return z_slice, f0_slice, slice_starts
|
||||
|
||||
|
||||
def slice_2d_segments(x: Tensor, starts: Tensor, length: int) -> Tensor:
|
||||
batch_size, num_features, seq_len = x.shape
|
||||
ends = starts + length
|
||||
idxs = (
|
||||
torch.arange(seq_len, device=x.device)
|
||||
.unsqueeze(0)
|
||||
.unsqueeze(1)
|
||||
.repeat(batch_size, num_features, 1)
|
||||
)
|
||||
mask = (idxs >= starts.unsqueeze(-1).unsqueeze(-1)) & (
|
||||
idxs < ends.unsqueeze(-1).unsqueeze(-1)
|
||||
)
|
||||
return x[mask].reshape(batch_size, num_features, length)
|
||||
|
||||
|
||||
def slice_1d_segments(x: Tensor, starts: Tensor, length: int) -> Tensor:
|
||||
batch_size, seq_len = x.shape
|
||||
ends = starts + length
|
||||
idxs = torch.arange(seq_len, device=x.device).unsqueeze(0).repeat(batch_size, 1)
|
||||
mask = (idxs >= starts.unsqueeze(-1)) & (idxs < ends.unsqueeze(-1))
|
||||
return x[mask].reshape(batch_size, length)
|
||||
|
||||
|
||||
def _slice_segments_v3(x: Tensor, starts: Tensor, length: int) -> Tensor:
|
||||
shape = x.shape[:-1] + (length,)
|
||||
ends = starts + length
|
||||
idxs = torch.arange(x.shape[-1], device=x.device).unsqueeze(0).unsqueeze(0)
|
||||
unsqueeze_dims = len(shape) - len(
|
||||
x.shape
|
||||
) # calculate number of dimensions to unsqueeze
|
||||
starts = starts.reshape(starts.shape + (1,) * unsqueeze_dims)
|
||||
ends = ends.reshape(ends.shape + (1,) * unsqueeze_dims)
|
||||
mask = (idxs >= starts) & (idxs < ends)
|
||||
return x[mask].reshape(shape)
|
||||
|
||||
|
||||
def init_weights(m, mean=0.0, std=0.01):
|
||||
classname = m.__class__.__name__
|
||||
if classname.find("Conv") != -1:
|
||||
m.weight.data.normal_(mean, std)
|
||||
|
||||
|
||||
def get_padding(kernel_size, dilation=1):
|
||||
return int((kernel_size * dilation - dilation) / 2)
|
||||
|
||||
|
||||
def convert_pad_shape(pad_shape):
|
||||
l = pad_shape[::-1]
|
||||
pad_shape = [item for sublist in l for item in sublist]
|
||||
return pad_shape
|
||||
|
||||
|
||||
def subsequent_mask(length):
|
||||
mask = torch.tril(torch.ones(length, length)).unsqueeze(0).unsqueeze(0)
|
||||
return mask
|
||||
|
||||
|
||||
@torch.jit.script
|
||||
def fused_add_tanh_sigmoid_multiply(input_a, input_b, n_channels):
|
||||
n_channels_int = n_channels[0]
|
||||
in_act = input_a + input_b
|
||||
t_act = torch.tanh(in_act[:, :n_channels_int, :])
|
||||
s_act = torch.sigmoid(in_act[:, n_channels_int:, :])
|
||||
acts = t_act * s_act
|
||||
return acts
|
||||
|
||||
|
||||
def sequence_mask(length, max_length=None):
|
||||
if max_length is None:
|
||||
max_length = length.max()
|
||||
x = torch.arange(max_length, dtype=length.dtype, device=length.device)
|
||||
return x.unsqueeze(0) < length.unsqueeze(1)
|
||||
|
||||
|
||||
def clip_grad_value_(parameters, clip_value, norm_type=2):
|
||||
if isinstance(parameters, torch.Tensor):
|
||||
parameters = [parameters]
|
||||
parameters = list(filter(lambda p: p.grad is not None, parameters))
|
||||
norm_type = float(norm_type)
|
||||
if clip_value is not None:
|
||||
clip_value = float(clip_value)
|
||||
|
||||
total_norm = 0
|
||||
for p in parameters:
|
||||
param_norm = p.grad.data.norm(norm_type)
|
||||
total_norm += param_norm.item() ** norm_type
|
||||
if clip_value is not None:
|
||||
p.grad.data.clamp_(min=-clip_value, max=clip_value)
|
||||
total_norm = total_norm ** (1.0 / norm_type)
|
||||
return total_norm
|
||||
@@ -0,0 +1,46 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
from so_vits_svc_fork.modules import attentions as attentions
|
||||
|
||||
|
||||
class F0Decoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.spk_channels = spk_channels
|
||||
|
||||
self.prenet = nn.Conv1d(hidden_channels, hidden_channels, 3, padding=1)
|
||||
self.decoder = attentions.FFT(
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.f0_prenet = nn.Conv1d(1, hidden_channels, 3, padding=1)
|
||||
self.cond = nn.Conv1d(spk_channels, hidden_channels, 1)
|
||||
|
||||
def forward(self, x, norm_f0, x_mask, spk_emb=None):
|
||||
x = torch.detach(x)
|
||||
if spk_emb is not None:
|
||||
spk_emb = torch.detach(spk_emb)
|
||||
x = x + self.cond(spk_emb)
|
||||
x += self.f0_prenet(norm_f0)
|
||||
x = self.prenet(x) * x_mask
|
||||
x = self.decoder(x * x_mask, x_mask)
|
||||
x = self.proj(x) * x_mask
|
||||
return x
|
||||
+3
@@ -0,0 +1,3 @@
|
||||
from ._models import NSFHifiGANGenerator
|
||||
|
||||
__all__ = ["NSFHifiGANGenerator"]
|
||||
+311
@@ -0,0 +1,311 @@
|
||||
from logging import getLogger
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from torch.nn import Conv1d, ConvTranspose1d
|
||||
from torch.nn.utils import remove_weight_norm, weight_norm
|
||||
|
||||
from ...modules import ResBlock1, ResBlock2
|
||||
from ._utils import init_weights
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
LRELU_SLOPE = 0.1
|
||||
|
||||
|
||||
def padDiff(x):
|
||||
return F.pad(
|
||||
F.pad(x, (0, 0, -1, 1), "constant", 0) - x, (0, 0, 0, -1), "constant", 0
|
||||
)
|
||||
|
||||
|
||||
class SineGen(torch.nn.Module):
|
||||
"""Definition of sine generator
|
||||
SineGen(samp_rate, harmonic_num = 0,
|
||||
sine_amp = 0.1, noise_std = 0.003,
|
||||
voiced_threshold = 0,
|
||||
flag_for_pulse=False)
|
||||
samp_rate: sampling rate in Hz
|
||||
harmonic_num: number of harmonic overtones (default 0)
|
||||
sine_amp: amplitude of sine-wavefrom (default 0.1)
|
||||
noise_std: std of Gaussian noise (default 0.003)
|
||||
voiced_thoreshold: F0 threshold for U/V classification (default 0)
|
||||
flag_for_pulse: this SinGen is used inside PulseGen (default False)
|
||||
Note: when flag_for_pulse is True, the first time step of a voiced
|
||||
segment is always sin(np.pi) or cos(0)
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
samp_rate,
|
||||
harmonic_num=0,
|
||||
sine_amp=0.1,
|
||||
noise_std=0.003,
|
||||
voiced_threshold=0,
|
||||
flag_for_pulse=False,
|
||||
):
|
||||
super().__init__()
|
||||
self.sine_amp = sine_amp
|
||||
self.noise_std = noise_std
|
||||
self.harmonic_num = harmonic_num
|
||||
self.dim = self.harmonic_num + 1
|
||||
self.sampling_rate = samp_rate
|
||||
self.voiced_threshold = voiced_threshold
|
||||
self.flag_for_pulse = flag_for_pulse
|
||||
|
||||
def _f02uv(self, f0):
|
||||
# generate uv signal
|
||||
uv = (f0 > self.voiced_threshold).type(torch.float32)
|
||||
return uv
|
||||
|
||||
def _f02sine(self, f0_values):
|
||||
"""f0_values: (batchsize, length, dim)
|
||||
where dim indicates fundamental tone and overtones
|
||||
"""
|
||||
# convert to F0 in rad. The integer part n can be ignored
|
||||
# because 2 * np.pi * n doesn't affect phase
|
||||
rad_values = (f0_values / self.sampling_rate) % 1
|
||||
|
||||
# initial phase noise (no noise for fundamental component)
|
||||
rand_ini = torch.rand(
|
||||
f0_values.shape[0], f0_values.shape[2], device=f0_values.device
|
||||
)
|
||||
rand_ini[:, 0] = 0
|
||||
rad_values[:, 0, :] = rad_values[:, 0, :] + rand_ini
|
||||
|
||||
# instantanouse phase sine[t] = sin(2*pi \sum_i=1 ^{t} rad)
|
||||
if not self.flag_for_pulse:
|
||||
# for normal case
|
||||
|
||||
# To prevent torch.cumsum numerical overflow,
|
||||
# it is necessary to add -1 whenever \sum_k=1^n rad_value_k > 1.
|
||||
# Buffer tmp_over_one_idx indicates the time step to add -1.
|
||||
# This will not change F0 of sine because (x-1) * 2*pi = x * 2*pi
|
||||
tmp_over_one = torch.cumsum(rad_values, 1) % 1
|
||||
tmp_over_one_idx = (padDiff(tmp_over_one)) < 0
|
||||
cumsum_shift = torch.zeros_like(rad_values)
|
||||
cumsum_shift[:, 1:, :] = tmp_over_one_idx * -1.0
|
||||
|
||||
sines = torch.sin(
|
||||
torch.cumsum(rad_values + cumsum_shift, dim=1) * 2 * np.pi
|
||||
)
|
||||
else:
|
||||
# If necessary, make sure that the first time step of every
|
||||
# voiced segments is sin(pi) or cos(0)
|
||||
# This is used for pulse-train generation
|
||||
|
||||
# identify the last time step in unvoiced segments
|
||||
uv = self._f02uv(f0_values)
|
||||
uv_1 = torch.roll(uv, shifts=-1, dims=1)
|
||||
uv_1[:, -1, :] = 1
|
||||
u_loc = (uv < 1) * (uv_1 > 0)
|
||||
|
||||
# get the instantanouse phase
|
||||
tmp_cumsum = torch.cumsum(rad_values, dim=1)
|
||||
# different batch needs to be processed differently
|
||||
for idx in range(f0_values.shape[0]):
|
||||
temp_sum = tmp_cumsum[idx, u_loc[idx, :, 0], :]
|
||||
temp_sum[1:, :] = temp_sum[1:, :] - temp_sum[0:-1, :]
|
||||
# stores the accumulation of i.phase within
|
||||
# each voiced segments
|
||||
tmp_cumsum[idx, :, :] = 0
|
||||
tmp_cumsum[idx, u_loc[idx, :, 0], :] = temp_sum
|
||||
|
||||
# rad_values - tmp_cumsum: remove the accumulation of i.phase
|
||||
# within the previous voiced segment.
|
||||
i_phase = torch.cumsum(rad_values - tmp_cumsum, dim=1)
|
||||
|
||||
# get the sines
|
||||
sines = torch.cos(i_phase * 2 * np.pi)
|
||||
return sines
|
||||
|
||||
def forward(self, f0):
|
||||
"""sine_tensor, uv = forward(f0)
|
||||
input F0: tensor(batchsize=1, length, dim=1)
|
||||
f0 for unvoiced steps should be 0
|
||||
output sine_tensor: tensor(batchsize=1, length, dim)
|
||||
output uv: tensor(batchsize=1, length, 1)
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# f0_buf = torch.zeros(f0.shape[0], f0.shape[1], self.dim, device=f0.device)
|
||||
# fundamental component
|
||||
# fn = torch.multiply(
|
||||
# f0, torch.FloatTensor([[range(1, self.harmonic_num + 2)]]).to(f0.device)
|
||||
# )
|
||||
fn = torch.multiply(
|
||||
f0, torch.arange(1, self.harmonic_num + 2).to(f0.device).to(f0.dtype)
|
||||
)
|
||||
|
||||
# generate sine waveforms
|
||||
sine_waves = self._f02sine(fn) * self.sine_amp
|
||||
|
||||
# generate uv signal
|
||||
# uv = torch.ones(f0.shape)
|
||||
# uv = uv * (f0 > self.voiced_threshold)
|
||||
uv = self._f02uv(f0)
|
||||
|
||||
# noise: for unvoiced should be similar to sine_amp
|
||||
# std = self.sine_amp/3 -> max value ~ self.sine_amp
|
||||
# . for voiced regions is self.noise_std
|
||||
noise_amp = uv * self.noise_std + (1 - uv) * self.sine_amp / 3
|
||||
noise = noise_amp * torch.randn_like(sine_waves)
|
||||
|
||||
# first: set the unvoiced part to 0 by uv
|
||||
# then: additive noise
|
||||
sine_waves = sine_waves * uv + noise
|
||||
return sine_waves, uv, noise
|
||||
|
||||
|
||||
class SourceModuleHnNSF(torch.nn.Module):
|
||||
"""SourceModule for hn-nsf
|
||||
SourceModule(sampling_rate, harmonic_num=0, sine_amp=0.1,
|
||||
add_noise_std=0.003, voiced_threshod=0)
|
||||
sampling_rate: sampling_rate in Hz
|
||||
harmonic_num: number of harmonic above F0 (default: 0)
|
||||
sine_amp: amplitude of sine source signal (default: 0.1)
|
||||
add_noise_std: std of additive Gaussian noise (default: 0.003)
|
||||
note that amplitude of noise in unvoiced is decided
|
||||
by sine_amp
|
||||
voiced_threshold: threshold to set U/V given F0 (default: 0)
|
||||
Sine_source, noise_source = SourceModuleHnNSF(F0_sampled)
|
||||
F0_sampled (batchsize, length, 1)
|
||||
Sine_source (batchsize, length, 1)
|
||||
noise_source (batchsize, length 1)
|
||||
uv (batchsize, length, 1)
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sampling_rate,
|
||||
harmonic_num=0,
|
||||
sine_amp=0.1,
|
||||
add_noise_std=0.003,
|
||||
voiced_threshod=0,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.sine_amp = sine_amp
|
||||
self.noise_std = add_noise_std
|
||||
|
||||
# to produce sine waveforms
|
||||
self.l_sin_gen = SineGen(
|
||||
sampling_rate, harmonic_num, sine_amp, add_noise_std, voiced_threshod
|
||||
)
|
||||
|
||||
# to merge source harmonics into a single excitation
|
||||
self.l_linear = torch.nn.Linear(harmonic_num + 1, 1)
|
||||
self.l_tanh = torch.nn.Tanh()
|
||||
|
||||
def forward(self, x):
|
||||
"""
|
||||
Sine_source, noise_source = SourceModuleHnNSF(F0_sampled)
|
||||
F0_sampled (batchsize, length, 1)
|
||||
Sine_source (batchsize, length, 1)
|
||||
noise_source (batchsize, length 1)
|
||||
"""
|
||||
# source for harmonic branch
|
||||
sine_wavs, uv, _ = self.l_sin_gen(x)
|
||||
sine_merge = self.l_tanh(self.l_linear(sine_wavs))
|
||||
|
||||
# source for noise branch, in the same shape as uv
|
||||
noise = torch.randn_like(uv) * self.sine_amp / 3
|
||||
return sine_merge, noise, uv
|
||||
|
||||
|
||||
class NSFHifiGANGenerator(torch.nn.Module):
|
||||
def __init__(self, h):
|
||||
super().__init__()
|
||||
self.h = h
|
||||
|
||||
self.num_kernels = len(h["resblock_kernel_sizes"])
|
||||
self.num_upsamples = len(h["upsample_rates"])
|
||||
self.f0_upsamp = torch.nn.Upsample(scale_factor=np.prod(h["upsample_rates"]))
|
||||
self.m_source = SourceModuleHnNSF(
|
||||
sampling_rate=h["sampling_rate"], harmonic_num=8
|
||||
)
|
||||
self.noise_convs = nn.ModuleList()
|
||||
self.conv_pre = weight_norm(
|
||||
Conv1d(h["inter_channels"], h["upsample_initial_channel"], 7, 1, padding=3)
|
||||
)
|
||||
resblock = ResBlock1 if h["resblock"] == "1" else ResBlock2
|
||||
self.ups = nn.ModuleList()
|
||||
for i, (u, k) in enumerate(
|
||||
zip(h["upsample_rates"], h["upsample_kernel_sizes"])
|
||||
):
|
||||
c_cur = h["upsample_initial_channel"] // (2 ** (i + 1))
|
||||
self.ups.append(
|
||||
weight_norm(
|
||||
ConvTranspose1d(
|
||||
h["upsample_initial_channel"] // (2**i),
|
||||
h["upsample_initial_channel"] // (2 ** (i + 1)),
|
||||
k,
|
||||
u,
|
||||
padding=(k - u) // 2,
|
||||
)
|
||||
)
|
||||
)
|
||||
if i + 1 < len(h["upsample_rates"]): #
|
||||
stride_f0 = np.prod(h["upsample_rates"][i + 1 :])
|
||||
self.noise_convs.append(
|
||||
Conv1d(
|
||||
1,
|
||||
c_cur,
|
||||
kernel_size=stride_f0 * 2,
|
||||
stride=stride_f0,
|
||||
padding=stride_f0 // 2,
|
||||
)
|
||||
)
|
||||
else:
|
||||
self.noise_convs.append(Conv1d(1, c_cur, kernel_size=1))
|
||||
self.resblocks = nn.ModuleList()
|
||||
for i in range(len(self.ups)):
|
||||
ch = h["upsample_initial_channel"] // (2 ** (i + 1))
|
||||
for j, (k, d) in enumerate(
|
||||
zip(h["resblock_kernel_sizes"], h["resblock_dilation_sizes"])
|
||||
):
|
||||
self.resblocks.append(resblock(ch, k, d))
|
||||
|
||||
self.conv_post = weight_norm(Conv1d(ch, 1, 7, 1, padding=3))
|
||||
self.ups.apply(init_weights)
|
||||
self.conv_post.apply(init_weights)
|
||||
self.cond = nn.Conv1d(h["gin_channels"], h["upsample_initial_channel"], 1)
|
||||
|
||||
def forward(self, x, f0, g=None):
|
||||
# LOG.info(1,x.shape,f0.shape,f0[:, None].shape)
|
||||
f0 = self.f0_upsamp(f0[:, None]).transpose(1, 2) # bs,n,t
|
||||
# LOG.info(2,f0.shape)
|
||||
har_source, noi_source, uv = self.m_source(f0)
|
||||
har_source = har_source.transpose(1, 2)
|
||||
x = self.conv_pre(x)
|
||||
x = x + self.cond(g)
|
||||
# LOG.info(124,x.shape,har_source.shape)
|
||||
for i in range(self.num_upsamples):
|
||||
x = F.leaky_relu(x, LRELU_SLOPE)
|
||||
# LOG.info(3,x.shape)
|
||||
x = self.ups[i](x)
|
||||
x_source = self.noise_convs[i](har_source)
|
||||
# LOG.info(4,x_source.shape,har_source.shape,x.shape)
|
||||
x = x + x_source
|
||||
xs = None
|
||||
for j in range(self.num_kernels):
|
||||
if xs is None:
|
||||
xs = self.resblocks[i * self.num_kernels + j](x)
|
||||
else:
|
||||
xs += self.resblocks[i * self.num_kernels + j](x)
|
||||
x = xs / self.num_kernels
|
||||
x = F.leaky_relu(x)
|
||||
x = self.conv_post(x)
|
||||
x = torch.tanh(x)
|
||||
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
LOG.info("Removing weight norm...")
|
||||
for l in self.ups:
|
||||
remove_weight_norm(l)
|
||||
for l in self.resblocks:
|
||||
l.remove_weight_norm()
|
||||
remove_weight_norm(self.conv_pre)
|
||||
remove_weight_norm(self.conv_post)
|
||||
+15
@@ -0,0 +1,15 @@
|
||||
from logging import getLogger
|
||||
|
||||
# matplotlib.use("Agg")
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def init_weights(m, mean=0.0, std=0.01):
|
||||
classname = m.__class__.__name__
|
||||
if classname.find("Conv") != -1:
|
||||
m.weight.data.normal_(mean, std)
|
||||
|
||||
|
||||
def get_padding(kernel_size, dilation=1):
|
||||
return int((kernel_size * dilation - dilation) / 2)
|
||||
+15
@@ -0,0 +1,15 @@
|
||||
from ._generators import (
|
||||
Multiband_iSTFT_Generator,
|
||||
Multistream_iSTFT_Generator,
|
||||
iSTFT_Generator,
|
||||
)
|
||||
from ._loss import subband_stft_loss
|
||||
from ._pqmf import PQMF
|
||||
|
||||
__all__ = [
|
||||
"subband_stft_loss",
|
||||
"PQMF",
|
||||
"iSTFT_Generator",
|
||||
"Multiband_iSTFT_Generator",
|
||||
"Multistream_iSTFT_Generator",
|
||||
]
|
||||
+376
@@ -0,0 +1,376 @@
|
||||
import math
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import Conv1d, ConvTranspose1d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import remove_weight_norm, weight_norm
|
||||
|
||||
from ....modules import modules
|
||||
from ....modules.commons import get_padding, init_weights
|
||||
from ._pqmf import PQMF
|
||||
from ._stft import TorchSTFT
|
||||
|
||||
|
||||
class iSTFT_Generator(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
initial_channel,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gen_istft_n_fft,
|
||||
gen_istft_hop_size,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
# self.h = h
|
||||
self.gen_istft_n_fft = gen_istft_n_fft
|
||||
self.gen_istft_hop_size = gen_istft_hop_size
|
||||
|
||||
self.num_kernels = len(resblock_kernel_sizes)
|
||||
self.num_upsamples = len(upsample_rates)
|
||||
self.conv_pre = weight_norm(
|
||||
Conv1d(initial_channel, upsample_initial_channel, 7, 1, padding=3)
|
||||
)
|
||||
resblock = modules.ResBlock1 if resblock == "1" else modules.ResBlock2
|
||||
|
||||
self.ups = nn.ModuleList()
|
||||
for i, (u, k) in enumerate(zip(upsample_rates, upsample_kernel_sizes)):
|
||||
self.ups.append(
|
||||
weight_norm(
|
||||
ConvTranspose1d(
|
||||
upsample_initial_channel // (2**i),
|
||||
upsample_initial_channel // (2 ** (i + 1)),
|
||||
k,
|
||||
u,
|
||||
padding=(k - u) // 2,
|
||||
)
|
||||
)
|
||||
)
|
||||
|
||||
self.resblocks = nn.ModuleList()
|
||||
for i in range(len(self.ups)):
|
||||
ch = upsample_initial_channel // (2 ** (i + 1))
|
||||
for j, (k, d) in enumerate(
|
||||
zip(resblock_kernel_sizes, resblock_dilation_sizes)
|
||||
):
|
||||
self.resblocks.append(resblock(ch, k, d))
|
||||
|
||||
self.post_n_fft = self.gen_istft_n_fft
|
||||
self.conv_post = weight_norm(Conv1d(ch, self.post_n_fft + 2, 7, 1, padding=3))
|
||||
self.ups.apply(init_weights)
|
||||
self.conv_post.apply(init_weights)
|
||||
self.reflection_pad = torch.nn.ReflectionPad1d((1, 0))
|
||||
self.stft = TorchSTFT(
|
||||
filter_length=self.gen_istft_n_fft,
|
||||
hop_length=self.gen_istft_hop_size,
|
||||
win_length=self.gen_istft_n_fft,
|
||||
)
|
||||
|
||||
def forward(self, x, g=None):
|
||||
x = self.conv_pre(x)
|
||||
for i in range(self.num_upsamples):
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
x = self.ups[i](x)
|
||||
xs = None
|
||||
for j in range(self.num_kernels):
|
||||
if xs is None:
|
||||
xs = self.resblocks[i * self.num_kernels + j](x)
|
||||
else:
|
||||
xs += self.resblocks[i * self.num_kernels + j](x)
|
||||
x = xs / self.num_kernels
|
||||
x = F.leaky_relu(x)
|
||||
x = self.reflection_pad(x)
|
||||
x = self.conv_post(x)
|
||||
spec = torch.exp(x[:, : self.post_n_fft // 2 + 1, :])
|
||||
phase = math.pi * torch.sin(x[:, self.post_n_fft // 2 + 1 :, :])
|
||||
out = self.stft.inverse(spec, phase).to(x.device)
|
||||
return out, None
|
||||
|
||||
def remove_weight_norm(self):
|
||||
print("Removing weight norm...")
|
||||
for l in self.ups:
|
||||
remove_weight_norm(l)
|
||||
for l in self.resblocks:
|
||||
l.remove_weight_norm()
|
||||
remove_weight_norm(self.conv_pre)
|
||||
remove_weight_norm(self.conv_post)
|
||||
|
||||
|
||||
class Multiband_iSTFT_Generator(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
initial_channel,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gen_istft_n_fft,
|
||||
gen_istft_hop_size,
|
||||
subbands,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
# self.h = h
|
||||
self.subbands = subbands
|
||||
self.num_kernels = len(resblock_kernel_sizes)
|
||||
self.num_upsamples = len(upsample_rates)
|
||||
self.conv_pre = weight_norm(
|
||||
Conv1d(initial_channel, upsample_initial_channel, 7, 1, padding=3)
|
||||
)
|
||||
resblock = modules.ResBlock1 if resblock == "1" else modules.ResBlock2
|
||||
|
||||
self.ups = nn.ModuleList()
|
||||
for i, (u, k) in enumerate(zip(upsample_rates, upsample_kernel_sizes)):
|
||||
self.ups.append(
|
||||
weight_norm(
|
||||
ConvTranspose1d(
|
||||
upsample_initial_channel // (2**i),
|
||||
upsample_initial_channel // (2 ** (i + 1)),
|
||||
k,
|
||||
u,
|
||||
padding=(k - u) // 2,
|
||||
)
|
||||
)
|
||||
)
|
||||
|
||||
self.resblocks = nn.ModuleList()
|
||||
for i in range(len(self.ups)):
|
||||
ch = upsample_initial_channel // (2 ** (i + 1))
|
||||
for j, (k, d) in enumerate(
|
||||
zip(resblock_kernel_sizes, resblock_dilation_sizes)
|
||||
):
|
||||
self.resblocks.append(resblock(ch, k, d))
|
||||
|
||||
self.post_n_fft = gen_istft_n_fft
|
||||
self.ups.apply(init_weights)
|
||||
self.reflection_pad = torch.nn.ReflectionPad1d((1, 0))
|
||||
self.reshape_pixelshuffle = []
|
||||
|
||||
self.subband_conv_post = weight_norm(
|
||||
Conv1d(ch, self.subbands * (self.post_n_fft + 2), 7, 1, padding=3)
|
||||
)
|
||||
|
||||
self.subband_conv_post.apply(init_weights)
|
||||
|
||||
self.gen_istft_n_fft = gen_istft_n_fft
|
||||
self.gen_istft_hop_size = gen_istft_hop_size
|
||||
|
||||
def forward(self, x, g=None):
|
||||
stft = TorchSTFT(
|
||||
filter_length=self.gen_istft_n_fft,
|
||||
hop_length=self.gen_istft_hop_size,
|
||||
win_length=self.gen_istft_n_fft,
|
||||
).to(x.device)
|
||||
pqmf = PQMF(x.device, subbands=self.subbands).to(x.device, dtype=x.dtype)
|
||||
|
||||
x = self.conv_pre(x) # [B, ch, length]
|
||||
|
||||
for i in range(self.num_upsamples):
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
x = self.ups[i](x)
|
||||
|
||||
xs = None
|
||||
for j in range(self.num_kernels):
|
||||
if xs is None:
|
||||
xs = self.resblocks[i * self.num_kernels + j](x)
|
||||
else:
|
||||
xs += self.resblocks[i * self.num_kernels + j](x)
|
||||
x = xs / self.num_kernels
|
||||
|
||||
x = F.leaky_relu(x)
|
||||
x = self.reflection_pad(x)
|
||||
x = self.subband_conv_post(x)
|
||||
x = torch.reshape(
|
||||
x, (x.shape[0], self.subbands, x.shape[1] // self.subbands, x.shape[-1])
|
||||
)
|
||||
|
||||
spec = torch.exp(x[:, :, : self.post_n_fft // 2 + 1, :])
|
||||
phase = math.pi * torch.sin(x[:, :, self.post_n_fft // 2 + 1 :, :])
|
||||
|
||||
y_mb_hat = stft.inverse(
|
||||
torch.reshape(
|
||||
spec,
|
||||
(
|
||||
spec.shape[0] * self.subbands,
|
||||
self.gen_istft_n_fft // 2 + 1,
|
||||
spec.shape[-1],
|
||||
),
|
||||
),
|
||||
torch.reshape(
|
||||
phase,
|
||||
(
|
||||
phase.shape[0] * self.subbands,
|
||||
self.gen_istft_n_fft // 2 + 1,
|
||||
phase.shape[-1],
|
||||
),
|
||||
),
|
||||
)
|
||||
y_mb_hat = torch.reshape(
|
||||
y_mb_hat, (x.shape[0], self.subbands, 1, y_mb_hat.shape[-1])
|
||||
)
|
||||
y_mb_hat = y_mb_hat.squeeze(-2)
|
||||
|
||||
y_g_hat = pqmf.synthesis(y_mb_hat)
|
||||
|
||||
return y_g_hat, y_mb_hat
|
||||
|
||||
def remove_weight_norm(self):
|
||||
print("Removing weight norm...")
|
||||
for l in self.ups:
|
||||
remove_weight_norm(l)
|
||||
for l in self.resblocks:
|
||||
l.remove_weight_norm()
|
||||
|
||||
|
||||
class Multistream_iSTFT_Generator(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
initial_channel,
|
||||
resblock,
|
||||
resblock_kernel_sizes,
|
||||
resblock_dilation_sizes,
|
||||
upsample_rates,
|
||||
upsample_initial_channel,
|
||||
upsample_kernel_sizes,
|
||||
gen_istft_n_fft,
|
||||
gen_istft_hop_size,
|
||||
subbands,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
# self.h = h
|
||||
self.subbands = subbands
|
||||
self.num_kernels = len(resblock_kernel_sizes)
|
||||
self.num_upsamples = len(upsample_rates)
|
||||
self.conv_pre = weight_norm(
|
||||
Conv1d(initial_channel, upsample_initial_channel, 7, 1, padding=3)
|
||||
)
|
||||
resblock = modules.ResBlock1 if resblock == "1" else modules.ResBlock2
|
||||
|
||||
self.ups = nn.ModuleList()
|
||||
for i, (u, k) in enumerate(zip(upsample_rates, upsample_kernel_sizes)):
|
||||
self.ups.append(
|
||||
weight_norm(
|
||||
ConvTranspose1d(
|
||||
upsample_initial_channel // (2**i),
|
||||
upsample_initial_channel // (2 ** (i + 1)),
|
||||
k,
|
||||
u,
|
||||
padding=(k - u) // 2,
|
||||
)
|
||||
)
|
||||
)
|
||||
|
||||
self.resblocks = nn.ModuleList()
|
||||
for i in range(len(self.ups)):
|
||||
ch = upsample_initial_channel // (2 ** (i + 1))
|
||||
for j, (k, d) in enumerate(
|
||||
zip(resblock_kernel_sizes, resblock_dilation_sizes)
|
||||
):
|
||||
self.resblocks.append(resblock(ch, k, d))
|
||||
|
||||
self.post_n_fft = gen_istft_n_fft
|
||||
self.ups.apply(init_weights)
|
||||
self.reflection_pad = torch.nn.ReflectionPad1d((1, 0))
|
||||
self.reshape_pixelshuffle = []
|
||||
|
||||
self.subband_conv_post = weight_norm(
|
||||
Conv1d(ch, self.subbands * (self.post_n_fft + 2), 7, 1, padding=3)
|
||||
)
|
||||
|
||||
self.subband_conv_post.apply(init_weights)
|
||||
|
||||
self.gen_istft_n_fft = gen_istft_n_fft
|
||||
self.gen_istft_hop_size = gen_istft_hop_size
|
||||
|
||||
updown_filter = torch.zeros(
|
||||
(self.subbands, self.subbands, self.subbands)
|
||||
).float()
|
||||
for k in range(self.subbands):
|
||||
updown_filter[k, k, 0] = 1.0
|
||||
self.register_buffer("updown_filter", updown_filter)
|
||||
self.multistream_conv_post = weight_norm(
|
||||
Conv1d(
|
||||
self.subbands, 1, kernel_size=63, bias=False, padding=get_padding(63, 1)
|
||||
)
|
||||
)
|
||||
self.multistream_conv_post.apply(init_weights)
|
||||
|
||||
def forward(self, x, g=None):
|
||||
stft = TorchSTFT(
|
||||
filter_length=self.gen_istft_n_fft,
|
||||
hop_length=self.gen_istft_hop_size,
|
||||
win_length=self.gen_istft_n_fft,
|
||||
).to(x.device)
|
||||
# pqmf = PQMF(x.device)
|
||||
|
||||
x = self.conv_pre(x) # [B, ch, length]
|
||||
|
||||
for i in range(self.num_upsamples):
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
x = self.ups[i](x)
|
||||
|
||||
xs = None
|
||||
for j in range(self.num_kernels):
|
||||
if xs is None:
|
||||
xs = self.resblocks[i * self.num_kernels + j](x)
|
||||
else:
|
||||
xs += self.resblocks[i * self.num_kernels + j](x)
|
||||
x = xs / self.num_kernels
|
||||
|
||||
x = F.leaky_relu(x)
|
||||
x = self.reflection_pad(x)
|
||||
x = self.subband_conv_post(x)
|
||||
x = torch.reshape(
|
||||
x, (x.shape[0], self.subbands, x.shape[1] // self.subbands, x.shape[-1])
|
||||
)
|
||||
|
||||
spec = torch.exp(x[:, :, : self.post_n_fft // 2 + 1, :])
|
||||
phase = math.pi * torch.sin(x[:, :, self.post_n_fft // 2 + 1 :, :])
|
||||
|
||||
y_mb_hat = stft.inverse(
|
||||
torch.reshape(
|
||||
spec,
|
||||
(
|
||||
spec.shape[0] * self.subbands,
|
||||
self.gen_istft_n_fft // 2 + 1,
|
||||
spec.shape[-1],
|
||||
),
|
||||
),
|
||||
torch.reshape(
|
||||
phase,
|
||||
(
|
||||
phase.shape[0] * self.subbands,
|
||||
self.gen_istft_n_fft // 2 + 1,
|
||||
phase.shape[-1],
|
||||
),
|
||||
),
|
||||
)
|
||||
y_mb_hat = torch.reshape(
|
||||
y_mb_hat, (x.shape[0], self.subbands, 1, y_mb_hat.shape[-1])
|
||||
)
|
||||
y_mb_hat = y_mb_hat.squeeze(-2)
|
||||
|
||||
y_mb_hat = F.conv_transpose1d(
|
||||
y_mb_hat,
|
||||
self.updown_filter.to(x.device) * self.subbands,
|
||||
stride=self.subbands,
|
||||
)
|
||||
|
||||
y_g_hat = self.multistream_conv_post(y_mb_hat)
|
||||
|
||||
return y_g_hat, y_mb_hat
|
||||
|
||||
def remove_weight_norm(self):
|
||||
print("Removing weight norm...")
|
||||
for l in self.ups:
|
||||
remove_weight_norm(l)
|
||||
for l in self.resblocks:
|
||||
l.remove_weight_norm()
|
||||
+11
@@ -0,0 +1,11 @@
|
||||
from ._stft_loss import MultiResolutionSTFTLoss
|
||||
|
||||
|
||||
def subband_stft_loss(h, y_mb, y_hat_mb):
|
||||
sub_stft_loss = MultiResolutionSTFTLoss(
|
||||
h.train.fft_sizes, h.train.hop_sizes, h.train.win_lengths
|
||||
)
|
||||
y_mb = y_mb.view(-1, y_mb.size(2))
|
||||
y_hat_mb = y_hat_mb.view(-1, y_hat_mb.size(2))
|
||||
sub_sc_loss, sub_mag_loss = sub_stft_loss(y_hat_mb[:, : y_mb.size(-1)], y_mb)
|
||||
return sub_sc_loss + sub_mag_loss
|
||||
+128
@@ -0,0 +1,128 @@
|
||||
# Copyright 2020 Tomoki Hayashi
|
||||
# MIT License (https://opensource.org/licenses/MIT)
|
||||
|
||||
"""Pseudo QMF modules."""
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from scipy.signal import kaiser
|
||||
|
||||
|
||||
def design_prototype_filter(taps=62, cutoff_ratio=0.15, beta=9.0):
|
||||
"""Design prototype filter for PQMF.
|
||||
This method is based on `A Kaiser window approach for the design of prototype
|
||||
filters of cosine modulated filterbanks`_.
|
||||
Args:
|
||||
taps (int): The number of filter taps.
|
||||
cutoff_ratio (float): Cut-off frequency ratio.
|
||||
beta (float): Beta coefficient for kaiser window.
|
||||
Returns:
|
||||
ndarray: Impluse response of prototype filter (taps + 1,).
|
||||
.. _`A Kaiser window approach for the design of prototype filters of cosine modulated filterbanks`:
|
||||
https://ieeexplore.ieee.org/abstract/document/681427
|
||||
"""
|
||||
# check the arguments are valid
|
||||
assert taps % 2 == 0, "The number of taps mush be even number."
|
||||
assert 0.0 < cutoff_ratio < 1.0, "Cutoff ratio must be > 0.0 and < 1.0."
|
||||
|
||||
# make initial filter
|
||||
omega_c = np.pi * cutoff_ratio
|
||||
with np.errstate(invalid="ignore"):
|
||||
h_i = np.sin(omega_c * (np.arange(taps + 1) - 0.5 * taps)) / (
|
||||
np.pi * (np.arange(taps + 1) - 0.5 * taps)
|
||||
)
|
||||
h_i[taps // 2] = np.cos(0) * cutoff_ratio # fix nan due to indeterminate form
|
||||
|
||||
# apply kaiser window
|
||||
w = kaiser(taps + 1, beta)
|
||||
h = h_i * w
|
||||
|
||||
return h
|
||||
|
||||
|
||||
class PQMF(torch.nn.Module):
|
||||
"""PQMF module.
|
||||
This module is based on `Near-perfect-reconstruction pseudo-QMF banks`_.
|
||||
.. _`Near-perfect-reconstruction pseudo-QMF banks`:
|
||||
https://ieeexplore.ieee.org/document/258122
|
||||
"""
|
||||
|
||||
def __init__(self, device, subbands=8, taps=62, cutoff_ratio=0.15, beta=9.0):
|
||||
"""Initialize PQMF module.
|
||||
Args:
|
||||
subbands (int): The number of subbands.
|
||||
taps (int): The number of filter taps.
|
||||
cutoff_ratio (float): Cut-off frequency ratio.
|
||||
beta (float): Beta coefficient for kaiser window.
|
||||
"""
|
||||
super().__init__()
|
||||
|
||||
# define filter coefficient
|
||||
h_proto = design_prototype_filter(taps, cutoff_ratio, beta)
|
||||
h_analysis = np.zeros((subbands, len(h_proto)))
|
||||
h_synthesis = np.zeros((subbands, len(h_proto)))
|
||||
for k in range(subbands):
|
||||
h_analysis[k] = (
|
||||
2
|
||||
* h_proto
|
||||
* np.cos(
|
||||
(2 * k + 1)
|
||||
* (np.pi / (2 * subbands))
|
||||
* (np.arange(taps + 1) - ((taps - 1) / 2))
|
||||
+ (-1) ** k * np.pi / 4
|
||||
)
|
||||
)
|
||||
h_synthesis[k] = (
|
||||
2
|
||||
* h_proto
|
||||
* np.cos(
|
||||
(2 * k + 1)
|
||||
* (np.pi / (2 * subbands))
|
||||
* (np.arange(taps + 1) - ((taps - 1) / 2))
|
||||
- (-1) ** k * np.pi / 4
|
||||
)
|
||||
)
|
||||
|
||||
# convert to tensor
|
||||
analysis_filter = torch.from_numpy(h_analysis).float().unsqueeze(1).to(device)
|
||||
synthesis_filter = torch.from_numpy(h_synthesis).float().unsqueeze(0).to(device)
|
||||
|
||||
# register coefficients as buffer
|
||||
self.register_buffer("analysis_filter", analysis_filter)
|
||||
self.register_buffer("synthesis_filter", synthesis_filter)
|
||||
|
||||
# filter for downsampling & upsampling
|
||||
updown_filter = torch.zeros((subbands, subbands, subbands)).float().to(device)
|
||||
for k in range(subbands):
|
||||
updown_filter[k, k, 0] = 1.0
|
||||
self.register_buffer("updown_filter", updown_filter)
|
||||
self.subbands = subbands
|
||||
|
||||
# keep padding info
|
||||
self.pad_fn = torch.nn.ConstantPad1d(taps // 2, 0.0)
|
||||
|
||||
def analysis(self, x):
|
||||
"""Analysis with PQMF.
|
||||
Args:
|
||||
x (Tensor): Input tensor (B, 1, T).
|
||||
Returns:
|
||||
Tensor: Output tensor (B, subbands, T // subbands).
|
||||
"""
|
||||
x = F.conv1d(self.pad_fn(x), self.analysis_filter)
|
||||
return F.conv1d(x, self.updown_filter, stride=self.subbands)
|
||||
|
||||
def synthesis(self, x):
|
||||
"""Synthesis with PQMF.
|
||||
Args:
|
||||
x (Tensor): Input tensor (B, subbands, T // subbands).
|
||||
Returns:
|
||||
Tensor: Output tensor (B, 1, T).
|
||||
"""
|
||||
# NOTE(kan-bayashi): Power will be dreased so here multiply by # subbands.
|
||||
# Not sure this is the correct way, it is better to check again.
|
||||
# TODO(kan-bayashi): Understand the reconstruction procedure
|
||||
x = F.conv_transpose1d(
|
||||
x, self.updown_filter * self.subbands, stride=self.subbands
|
||||
)
|
||||
return F.conv1d(self.pad_fn(x), self.synthesis_filter)
|
||||
+244
@@ -0,0 +1,244 @@
|
||||
"""
|
||||
BSD 3-Clause License
|
||||
Copyright (c) 2017, Prem Seetharaman
|
||||
All rights reserved.
|
||||
* Redistribution and use in source and binary forms, with or without
|
||||
modification, are permitted provided that the following conditions are met:
|
||||
* Redistributions of source code must retain the above copyright notice,
|
||||
this list of conditions and the following disclaimer.
|
||||
* Redistributions in binary form must reproduce the above copyright notice, this
|
||||
list of conditions and the following disclaimer in the
|
||||
documentation and/or other materials provided with the distribution.
|
||||
* Neither the name of the copyright holder nor the names of its
|
||||
contributors may be used to endorse or promote products derived from this
|
||||
software without specific prior written permission.
|
||||
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS" AND
|
||||
ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED
|
||||
WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
|
||||
DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE FOR
|
||||
ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES
|
||||
(INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES;
|
||||
LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND ON
|
||||
ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT
|
||||
(INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE OF THIS
|
||||
SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
"""
|
||||
|
||||
import librosa.util as librosa_util
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from librosa.util import pad_center, tiny
|
||||
from scipy.signal import get_window
|
||||
from torch.autograd import Variable
|
||||
|
||||
|
||||
def window_sumsquare(
|
||||
window,
|
||||
n_frames,
|
||||
hop_length=200,
|
||||
win_length=800,
|
||||
n_fft=800,
|
||||
dtype=np.float32,
|
||||
norm=None,
|
||||
):
|
||||
"""
|
||||
# from librosa 0.6
|
||||
Compute the sum-square envelope of a window function at a given hop length.
|
||||
This is used to estimate modulation effects induced by windowing
|
||||
observations in short-time fourier transforms.
|
||||
Parameters
|
||||
----------
|
||||
window : string, tuple, number, callable, or list-like
|
||||
Window specification, as in `get_window`
|
||||
n_frames : int > 0
|
||||
The number of analysis frames
|
||||
hop_length : int > 0
|
||||
The number of samples to advance between frames
|
||||
win_length : [optional]
|
||||
The length of the window function. By default, this matches `n_fft`.
|
||||
n_fft : int > 0
|
||||
The length of each analysis frame.
|
||||
dtype : np.dtype
|
||||
The data type of the output
|
||||
Returns
|
||||
-------
|
||||
wss : np.ndarray, shape=`(n_fft + hop_length * (n_frames - 1))`
|
||||
The sum-squared envelope of the window function
|
||||
"""
|
||||
if win_length is None:
|
||||
win_length = n_fft
|
||||
|
||||
n = n_fft + hop_length * (n_frames - 1)
|
||||
x = np.zeros(n, dtype=dtype)
|
||||
|
||||
# Compute the squared window at the desired length
|
||||
win_sq = get_window(window, win_length, fftbins=True)
|
||||
win_sq = librosa_util.normalize(win_sq, norm=norm) ** 2
|
||||
win_sq = librosa_util.pad_center(win_sq, n_fft)
|
||||
|
||||
# Fill the envelope
|
||||
for i in range(n_frames):
|
||||
sample = i * hop_length
|
||||
x[sample : min(n, sample + n_fft)] += win_sq[: max(0, min(n_fft, n - sample))]
|
||||
return x
|
||||
|
||||
|
||||
class STFT(torch.nn.Module):
|
||||
"""adapted from Prem Seetharaman's https://github.com/pseeth/pytorch-stft"""
|
||||
|
||||
def __init__(
|
||||
self, filter_length=800, hop_length=200, win_length=800, window="hann"
|
||||
):
|
||||
super().__init__()
|
||||
self.filter_length = filter_length
|
||||
self.hop_length = hop_length
|
||||
self.win_length = win_length
|
||||
self.window = window
|
||||
self.forward_transform = None
|
||||
scale = self.filter_length / self.hop_length
|
||||
fourier_basis = np.fft.fft(np.eye(self.filter_length))
|
||||
|
||||
cutoff = int(self.filter_length / 2 + 1)
|
||||
fourier_basis = np.vstack(
|
||||
[np.real(fourier_basis[:cutoff, :]), np.imag(fourier_basis[:cutoff, :])]
|
||||
)
|
||||
|
||||
forward_basis = torch.FloatTensor(fourier_basis[:, None, :])
|
||||
inverse_basis = torch.FloatTensor(
|
||||
np.linalg.pinv(scale * fourier_basis).T[:, None, :]
|
||||
)
|
||||
|
||||
if window is not None:
|
||||
assert filter_length >= win_length
|
||||
# get window and zero center pad it to filter_length
|
||||
fft_window = get_window(window, win_length, fftbins=True)
|
||||
fft_window = pad_center(fft_window, filter_length)
|
||||
fft_window = torch.from_numpy(fft_window).float()
|
||||
|
||||
# window the bases
|
||||
forward_basis *= fft_window
|
||||
inverse_basis *= fft_window
|
||||
|
||||
self.register_buffer("forward_basis", forward_basis.float())
|
||||
self.register_buffer("inverse_basis", inverse_basis.float())
|
||||
|
||||
def transform(self, input_data):
|
||||
num_batches = input_data.size(0)
|
||||
num_samples = input_data.size(1)
|
||||
|
||||
self.num_samples = num_samples
|
||||
|
||||
# similar to librosa, reflect-pad the input
|
||||
input_data = input_data.view(num_batches, 1, num_samples)
|
||||
input_data = F.pad(
|
||||
input_data.unsqueeze(1),
|
||||
(int(self.filter_length / 2), int(self.filter_length / 2), 0, 0),
|
||||
mode="reflect",
|
||||
)
|
||||
input_data = input_data.squeeze(1)
|
||||
|
||||
forward_transform = F.conv1d(
|
||||
input_data,
|
||||
Variable(self.forward_basis, requires_grad=False),
|
||||
stride=self.hop_length,
|
||||
padding=0,
|
||||
)
|
||||
|
||||
cutoff = int((self.filter_length / 2) + 1)
|
||||
real_part = forward_transform[:, :cutoff, :]
|
||||
imag_part = forward_transform[:, cutoff:, :]
|
||||
|
||||
magnitude = torch.sqrt(real_part**2 + imag_part**2)
|
||||
phase = torch.autograd.Variable(torch.atan2(imag_part.data, real_part.data))
|
||||
|
||||
return magnitude, phase
|
||||
|
||||
def inverse(self, magnitude, phase):
|
||||
recombine_magnitude_phase = torch.cat(
|
||||
[magnitude * torch.cos(phase), magnitude * torch.sin(phase)], dim=1
|
||||
)
|
||||
|
||||
inverse_transform = F.conv_transpose1d(
|
||||
recombine_magnitude_phase,
|
||||
Variable(self.inverse_basis, requires_grad=False),
|
||||
stride=self.hop_length,
|
||||
padding=0,
|
||||
)
|
||||
|
||||
if self.window is not None:
|
||||
window_sum = window_sumsquare(
|
||||
self.window,
|
||||
magnitude.size(-1),
|
||||
hop_length=self.hop_length,
|
||||
win_length=self.win_length,
|
||||
n_fft=self.filter_length,
|
||||
dtype=np.float32,
|
||||
)
|
||||
# remove modulation effects
|
||||
approx_nonzero_indices = torch.from_numpy(
|
||||
np.where(window_sum > tiny(window_sum))[0]
|
||||
)
|
||||
window_sum = torch.autograd.Variable(
|
||||
torch.from_numpy(window_sum), requires_grad=False
|
||||
)
|
||||
window_sum = window_sum.to(inverse_transform.device())
|
||||
inverse_transform[:, :, approx_nonzero_indices] /= window_sum[
|
||||
approx_nonzero_indices
|
||||
]
|
||||
|
||||
# scale by hop ratio
|
||||
inverse_transform *= float(self.filter_length) / self.hop_length
|
||||
|
||||
inverse_transform = inverse_transform[:, :, int(self.filter_length / 2) :]
|
||||
inverse_transform = inverse_transform[:, :, : -int(self.filter_length / 2) :]
|
||||
|
||||
return inverse_transform
|
||||
|
||||
def forward(self, input_data):
|
||||
self.magnitude, self.phase = self.transform(input_data)
|
||||
reconstruction = self.inverse(self.magnitude, self.phase)
|
||||
return reconstruction
|
||||
|
||||
|
||||
class TorchSTFT(torch.nn.Module):
|
||||
def __init__(
|
||||
self, filter_length=800, hop_length=200, win_length=800, window="hann"
|
||||
):
|
||||
super().__init__()
|
||||
self.filter_length = filter_length
|
||||
self.hop_length = hop_length
|
||||
self.win_length = win_length
|
||||
self.window = torch.from_numpy(
|
||||
get_window(window, win_length, fftbins=True).astype(np.float32)
|
||||
)
|
||||
|
||||
def transform(self, input_data):
|
||||
forward_transform = torch.stft(
|
||||
input_data,
|
||||
self.filter_length,
|
||||
self.hop_length,
|
||||
self.win_length,
|
||||
window=self.window,
|
||||
return_complex=True,
|
||||
)
|
||||
|
||||
return torch.abs(forward_transform), torch.angle(forward_transform)
|
||||
|
||||
def inverse(self, magnitude, phase):
|
||||
inverse_transform = torch.istft(
|
||||
magnitude * torch.exp(phase * 1j),
|
||||
self.filter_length,
|
||||
self.hop_length,
|
||||
self.win_length,
|
||||
window=self.window.to(magnitude.device),
|
||||
)
|
||||
|
||||
return inverse_transform.unsqueeze(
|
||||
-2
|
||||
) # unsqueeze to stay consistent with conv_transpose1d implementation
|
||||
|
||||
def forward(self, input_data):
|
||||
self.magnitude, self.phase = self.transform(input_data)
|
||||
reconstruction = self.inverse(self.magnitude, self.phase)
|
||||
return reconstruction
|
||||
+142
@@ -0,0 +1,142 @@
|
||||
# Copyright 2019 Tomoki Hayashi
|
||||
# MIT License (https://opensource.org/licenses/MIT)
|
||||
|
||||
"""STFT-based Loss modules."""
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
|
||||
|
||||
def stft(x, fft_size, hop_size, win_length, window):
|
||||
"""Perform STFT and convert to magnitude spectrogram.
|
||||
Args:
|
||||
x (Tensor): Input signal tensor (B, T).
|
||||
fft_size (int): FFT size.
|
||||
hop_size (int): Hop size.
|
||||
win_length (int): Window length.
|
||||
window (str): Window function type.
|
||||
Returns:
|
||||
Tensor: Magnitude spectrogram (B, #frames, fft_size // 2 + 1).
|
||||
"""
|
||||
x_stft = torch.stft(
|
||||
x, fft_size, hop_size, win_length, window.to(x.device), return_complex=False
|
||||
)
|
||||
real = x_stft[..., 0]
|
||||
imag = x_stft[..., 1]
|
||||
|
||||
# NOTE(kan-bayashi): clamp is needed to avoid nan or inf
|
||||
return torch.sqrt(torch.clamp(real**2 + imag**2, min=1e-7)).transpose(2, 1)
|
||||
|
||||
|
||||
class SpectralConvergengeLoss(torch.nn.Module):
|
||||
"""Spectral convergence loss module."""
|
||||
|
||||
def __init__(self):
|
||||
"""Initialize spectral convergence loss module."""
|
||||
super().__init__()
|
||||
|
||||
def forward(self, x_mag, y_mag):
|
||||
"""Calculate forward propagation.
|
||||
Args:
|
||||
x_mag (Tensor): Magnitude spectrogram of predicted signal (B, #frames, #freq_bins).
|
||||
y_mag (Tensor): Magnitude spectrogram of groundtruth signal (B, #frames, #freq_bins).
|
||||
Returns:
|
||||
Tensor: Spectral convergence loss value.
|
||||
"""
|
||||
return torch.norm(y_mag - x_mag) / torch.norm(
|
||||
y_mag
|
||||
) # MB-iSTFT-VITS changed here due to codespell
|
||||
|
||||
|
||||
class LogSTFTMagnitudeLoss(torch.nn.Module):
|
||||
"""Log STFT magnitude loss module."""
|
||||
|
||||
def __init__(self):
|
||||
"""Initialize los STFT magnitude loss module."""
|
||||
super().__init__()
|
||||
|
||||
def forward(self, x_mag, y_mag):
|
||||
"""Calculate forward propagation.
|
||||
Args:
|
||||
x_mag (Tensor): Magnitude spectrogram of predicted signal (B, #frames, #freq_bins).
|
||||
y_mag (Tensor): Magnitude spectrogram of groundtruth signal (B, #frames, #freq_bins).
|
||||
Returns:
|
||||
Tensor: Log STFT magnitude loss value.
|
||||
"""
|
||||
return F.l1_loss(torch.log(y_mag), torch.log(x_mag))
|
||||
|
||||
|
||||
class STFTLoss(torch.nn.Module):
|
||||
"""STFT loss module."""
|
||||
|
||||
def __init__(
|
||||
self, fft_size=1024, shift_size=120, win_length=600, window="hann_window"
|
||||
):
|
||||
"""Initialize STFT loss module."""
|
||||
super().__init__()
|
||||
self.fft_size = fft_size
|
||||
self.shift_size = shift_size
|
||||
self.win_length = win_length
|
||||
self.window = getattr(torch, window)(win_length)
|
||||
self.spectral_convergenge_loss = SpectralConvergengeLoss()
|
||||
self.log_stft_magnitude_loss = LogSTFTMagnitudeLoss()
|
||||
|
||||
def forward(self, x, y):
|
||||
"""Calculate forward propagation.
|
||||
Args:
|
||||
x (Tensor): Predicted signal (B, T).
|
||||
y (Tensor): Groundtruth signal (B, T).
|
||||
Returns:
|
||||
Tensor: Spectral convergence loss value.
|
||||
Tensor: Log STFT magnitude loss value.
|
||||
"""
|
||||
x_mag = stft(x, self.fft_size, self.shift_size, self.win_length, self.window)
|
||||
y_mag = stft(y, self.fft_size, self.shift_size, self.win_length, self.window)
|
||||
sc_loss = self.spectral_convergenge_loss(x_mag, y_mag)
|
||||
mag_loss = self.log_stft_magnitude_loss(x_mag, y_mag)
|
||||
|
||||
return sc_loss, mag_loss
|
||||
|
||||
|
||||
class MultiResolutionSTFTLoss(torch.nn.Module):
|
||||
"""Multi resolution STFT loss module."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
fft_sizes=[1024, 2048, 512],
|
||||
hop_sizes=[120, 240, 50],
|
||||
win_lengths=[600, 1200, 240],
|
||||
window="hann_window",
|
||||
):
|
||||
"""Initialize Multi resolution STFT loss module.
|
||||
Args:
|
||||
fft_sizes (list): List of FFT sizes.
|
||||
hop_sizes (list): List of hop sizes.
|
||||
win_lengths (list): List of window lengths.
|
||||
window (str): Window function type.
|
||||
"""
|
||||
super().__init__()
|
||||
assert len(fft_sizes) == len(hop_sizes) == len(win_lengths)
|
||||
self.stft_losses = torch.nn.ModuleList()
|
||||
for fs, ss, wl in zip(fft_sizes, hop_sizes, win_lengths):
|
||||
self.stft_losses += [STFTLoss(fs, ss, wl, window)]
|
||||
|
||||
def forward(self, x, y):
|
||||
"""Calculate forward propagation.
|
||||
Args:
|
||||
x (Tensor): Predicted signal (B, T).
|
||||
y (Tensor): Groundtruth signal (B, T).
|
||||
Returns:
|
||||
Tensor: Multi resolution spectral convergence loss value.
|
||||
Tensor: Multi resolution log STFT magnitude loss value.
|
||||
"""
|
||||
sc_loss = 0.0
|
||||
mag_loss = 0.0
|
||||
for f in self.stft_losses:
|
||||
sc_l, mag_l = f(x, y)
|
||||
sc_loss += sc_l
|
||||
mag_loss += mag_l
|
||||
sc_loss /= len(self.stft_losses)
|
||||
mag_loss /= len(self.stft_losses)
|
||||
|
||||
return sc_loss, mag_loss
|
||||
@@ -0,0 +1,177 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import AvgPool1d, Conv1d, Conv2d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import spectral_norm, weight_norm
|
||||
|
||||
from so_vits_svc_fork.modules import modules as modules
|
||||
from so_vits_svc_fork.modules.commons import get_padding
|
||||
|
||||
|
||||
class DiscriminatorP(torch.nn.Module):
|
||||
def __init__(self, period, kernel_size=5, stride=3, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
self.period = period
|
||||
self.use_spectral_norm = use_spectral_norm
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1,
|
||||
32,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
32,
|
||||
128,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
128,
|
||||
512,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
512,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
(stride, 1),
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
norm_f(
|
||||
Conv2d(
|
||||
1024,
|
||||
1024,
|
||||
(kernel_size, 1),
|
||||
1,
|
||||
padding=(get_padding(kernel_size, 1), 0),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv2d(1024, 1, (3, 1), 1, padding=(1, 0)))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
# 1d to 2d
|
||||
b, c, t = x.shape
|
||||
if t % self.period != 0: # pad first
|
||||
n_pad = self.period - (t % self.period)
|
||||
x = F.pad(x, (0, n_pad), "reflect")
|
||||
t = t + n_pad
|
||||
x = x.view(b, c, t // self.period, self.period)
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class DiscriminatorS(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
norm_f = weight_norm if use_spectral_norm == False else spectral_norm
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
norm_f(Conv1d(1, 16, 15, 1, padding=7)),
|
||||
norm_f(Conv1d(16, 64, 41, 4, groups=4, padding=20)),
|
||||
norm_f(Conv1d(64, 256, 41, 4, groups=16, padding=20)),
|
||||
norm_f(Conv1d(256, 1024, 41, 4, groups=64, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 41, 4, groups=256, padding=20)),
|
||||
norm_f(Conv1d(1024, 1024, 5, 1, padding=2)),
|
||||
]
|
||||
)
|
||||
self.conv_post = norm_f(Conv1d(1024, 1, 3, 1, padding=1))
|
||||
|
||||
def forward(self, x):
|
||||
fmap = []
|
||||
|
||||
for l in self.convs:
|
||||
x = l(x)
|
||||
x = F.leaky_relu(x, modules.LRELU_SLOPE)
|
||||
fmap.append(x)
|
||||
x = self.conv_post(x)
|
||||
fmap.append(x)
|
||||
x = torch.flatten(x, 1, -1)
|
||||
|
||||
return x, fmap
|
||||
|
||||
|
||||
class MultiPeriodDiscriminator(torch.nn.Module):
|
||||
def __init__(self, use_spectral_norm=False):
|
||||
super().__init__()
|
||||
periods = [2, 3, 5, 7, 11]
|
||||
|
||||
discs = [DiscriminatorS(use_spectral_norm=use_spectral_norm)]
|
||||
discs = discs + [
|
||||
DiscriminatorP(i, use_spectral_norm=use_spectral_norm) for i in periods
|
||||
]
|
||||
self.discriminators = nn.ModuleList(discs)
|
||||
|
||||
def forward(self, y, y_hat):
|
||||
y_d_rs = []
|
||||
y_d_gs = []
|
||||
fmap_rs = []
|
||||
fmap_gs = []
|
||||
for i, d in enumerate(self.discriminators):
|
||||
y_d_r, fmap_r = d(y)
|
||||
y_d_g, fmap_g = d(y_hat)
|
||||
y_d_rs.append(y_d_r)
|
||||
y_d_gs.append(y_d_g)
|
||||
fmap_rs.append(fmap_r)
|
||||
fmap_gs.append(fmap_g)
|
||||
|
||||
return y_d_rs, y_d_gs, fmap_rs, fmap_gs
|
||||
|
||||
|
||||
class MultiScaleDiscriminator(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.discriminators = nn.ModuleList(
|
||||
[
|
||||
DiscriminatorS(use_spectral_norm=True),
|
||||
DiscriminatorS(),
|
||||
DiscriminatorS(),
|
||||
]
|
||||
)
|
||||
self.meanpools = nn.ModuleList(
|
||||
[AvgPool1d(4, 2, padding=2), AvgPool1d(4, 2, padding=2)]
|
||||
)
|
||||
|
||||
def forward(self, y, y_hat):
|
||||
y_d_rs = []
|
||||
y_d_gs = []
|
||||
fmap_rs = []
|
||||
fmap_gs = []
|
||||
for i, d in enumerate(self.discriminators):
|
||||
if i != 0:
|
||||
y = self.meanpools[i - 1](y)
|
||||
y_hat = self.meanpools[i - 1](y_hat)
|
||||
y_d_r, fmap_r = d(y)
|
||||
y_d_g, fmap_g = d(y_hat)
|
||||
y_d_rs.append(y_d_r)
|
||||
fmap_rs.append(fmap_r)
|
||||
y_d_gs.append(y_d_g)
|
||||
fmap_gs.append(fmap_g)
|
||||
|
||||
return y_d_rs, y_d_gs, fmap_rs, fmap_gs
|
||||
@@ -0,0 +1,136 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
from so_vits_svc_fork.modules import attentions as attentions
|
||||
from so_vits_svc_fork.modules import commons as commons
|
||||
from so_vits_svc_fork.modules import modules as modules
|
||||
|
||||
|
||||
class SpeakerEncoder(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
mel_n_channels=80,
|
||||
model_num_layers=3,
|
||||
model_hidden_size=256,
|
||||
model_embedding_size=256,
|
||||
):
|
||||
super().__init__()
|
||||
self.lstm = nn.LSTM(
|
||||
mel_n_channels, model_hidden_size, model_num_layers, batch_first=True
|
||||
)
|
||||
self.linear = nn.Linear(model_hidden_size, model_embedding_size)
|
||||
self.relu = nn.ReLU()
|
||||
|
||||
def forward(self, mels):
|
||||
self.lstm.flatten_parameters()
|
||||
_, (hidden, _) = self.lstm(mels)
|
||||
embeds_raw = self.relu(self.linear(hidden[-1]))
|
||||
return embeds_raw / torch.norm(embeds_raw, dim=1, keepdim=True)
|
||||
|
||||
def compute_partial_slices(self, total_frames, partial_frames, partial_hop):
|
||||
mel_slices = []
|
||||
for i in range(0, total_frames - partial_frames, partial_hop):
|
||||
mel_range = torch.arange(i, i + partial_frames)
|
||||
mel_slices.append(mel_range)
|
||||
|
||||
return mel_slices
|
||||
|
||||
def embed_utterance(self, mel, partial_frames=128, partial_hop=64):
|
||||
mel_len = mel.size(1)
|
||||
last_mel = mel[:, -partial_frames:]
|
||||
|
||||
if mel_len > partial_frames:
|
||||
mel_slices = self.compute_partial_slices(
|
||||
mel_len, partial_frames, partial_hop
|
||||
)
|
||||
mels = list(mel[:, s] for s in mel_slices)
|
||||
mels.append(last_mel)
|
||||
mels = torch.stack(tuple(mels), 0).squeeze(1)
|
||||
|
||||
with torch.no_grad():
|
||||
partial_embeds = self(mels)
|
||||
embed = torch.mean(partial_embeds, axis=0).unsqueeze(0)
|
||||
# embed = embed / torch.linalg.norm(embed, 2)
|
||||
else:
|
||||
with torch.no_grad():
|
||||
embed = self(last_mel)
|
||||
|
||||
return embed
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.pre = nn.Conv1d(in_channels, hidden_channels, 1)
|
||||
self.enc = modules.WN(
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
|
||||
def forward(self, x, x_lengths, g=None):
|
||||
# print(x.shape,x_lengths.shape)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(x_lengths, x.size(2)), 1).to(
|
||||
x.dtype
|
||||
)
|
||||
x = self.pre(x) * x_mask
|
||||
x = self.enc(x, x_mask, g=g)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs)) * x_mask
|
||||
return z, m, logs, x_mask
|
||||
|
||||
|
||||
class TextEncoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
out_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
filter_channels=None,
|
||||
n_heads=None,
|
||||
p_dropout=None,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels * 2, 1)
|
||||
self.f0_emb = nn.Embedding(256, hidden_channels)
|
||||
|
||||
self.enc_ = attentions.Encoder(
|
||||
hidden_channels, filter_channels, n_heads, n_layers, kernel_size, p_dropout
|
||||
)
|
||||
|
||||
def forward(self, x, x_mask, f0=None, noice_scale=1):
|
||||
x = x + self.f0_emb(f0).transpose(1, 2)
|
||||
x = self.enc_(x * x_mask, x_mask)
|
||||
stats = self.proj(x) * x_mask
|
||||
m, logs = torch.split(stats, self.out_channels, dim=1)
|
||||
z = (m + torch.randn_like(m) * torch.exp(logs) * noice_scale) * x_mask
|
||||
|
||||
return z, m, logs, x_mask
|
||||
@@ -0,0 +1,48 @@
|
||||
from torch import nn
|
||||
|
||||
from so_vits_svc_fork.modules import modules as modules
|
||||
|
||||
|
||||
class ResidualCouplingBlock(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
n_flows=4,
|
||||
gin_channels=0,
|
||||
):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.n_flows = n_flows
|
||||
self.gin_channels = gin_channels
|
||||
|
||||
self.flows = nn.ModuleList()
|
||||
for i in range(n_flows):
|
||||
self.flows.append(
|
||||
modules.ResidualCouplingLayer(
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=gin_channels,
|
||||
mean_only=True,
|
||||
)
|
||||
)
|
||||
self.flows.append(modules.Flip())
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
if not reverse:
|
||||
for flow in self.flows:
|
||||
x, _ = flow(x, x_mask, g=g, reverse=reverse)
|
||||
else:
|
||||
for flow in reversed(self.flows):
|
||||
x = flow(x, x_mask, g=g, reverse=reverse)
|
||||
return x
|
||||
@@ -0,0 +1,58 @@
|
||||
import torch
|
||||
|
||||
|
||||
def feature_loss(fmap_r, fmap_g):
|
||||
loss = 0
|
||||
for dr, dg in zip(fmap_r, fmap_g):
|
||||
for rl, gl in zip(dr, dg):
|
||||
rl = rl.float().detach()
|
||||
gl = gl.float()
|
||||
loss += torch.mean(torch.abs(rl - gl))
|
||||
|
||||
return loss * 2
|
||||
|
||||
|
||||
def discriminator_loss(disc_real_outputs, disc_generated_outputs):
|
||||
loss = 0
|
||||
r_losses = []
|
||||
g_losses = []
|
||||
for dr, dg in zip(disc_real_outputs, disc_generated_outputs):
|
||||
dr = dr.float()
|
||||
dg = dg.float()
|
||||
r_loss = torch.mean((1 - dr) ** 2)
|
||||
g_loss = torch.mean(dg**2)
|
||||
loss += r_loss + g_loss
|
||||
r_losses.append(r_loss.item())
|
||||
g_losses.append(g_loss.item())
|
||||
|
||||
return loss, r_losses, g_losses
|
||||
|
||||
|
||||
def generator_loss(disc_outputs):
|
||||
loss = 0
|
||||
gen_losses = []
|
||||
for dg in disc_outputs:
|
||||
dg = dg.float()
|
||||
l = torch.mean((1 - dg) ** 2)
|
||||
gen_losses.append(l)
|
||||
loss += l
|
||||
|
||||
return loss, gen_losses
|
||||
|
||||
|
||||
def kl_loss(z_p, logs_q, m_p, logs_p, z_mask):
|
||||
"""
|
||||
z_p, logs_q: [b, h, t_t]
|
||||
m_p, logs_p: [b, h, t_t]
|
||||
"""
|
||||
z_p = z_p.float()
|
||||
logs_q = logs_q.float()
|
||||
m_p = m_p.float()
|
||||
logs_p = logs_p.float()
|
||||
z_mask = z_mask.float()
|
||||
# print(logs_p)
|
||||
kl = logs_p - logs_q - 0.5
|
||||
kl += 0.5 * ((z_p - m_p) ** 2) * torch.exp(-2.0 * logs_p)
|
||||
kl = torch.sum(kl * z_mask)
|
||||
l = kl / torch.sum(z_mask)
|
||||
return l
|
||||
@@ -0,0 +1,205 @@
|
||||
"""from logging import getLogger
|
||||
|
||||
import torch
|
||||
import torch.utils.data
|
||||
import torchaudio
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
from ..hparams import HParams
|
||||
|
||||
|
||||
def spectrogram_torch(audio: torch.Tensor, hps: HParams) -> torch.Tensor:
|
||||
return torchaudio.transforms.Spectrogram(
|
||||
n_fft=hps.data.filter_length,
|
||||
win_length=hps.data.win_length,
|
||||
hop_length=hps.data.hop_length,
|
||||
power=1.0,
|
||||
window_fn=torch.hann_window,
|
||||
normalized=False,
|
||||
).to(audio.device)(audio)
|
||||
|
||||
|
||||
def spec_to_mel_torch(spec: torch.Tensor, hps: HParams) -> torch.Tensor:
|
||||
return torchaudio.transforms.MelScale(
|
||||
n_mels=hps.data.n_mel_channels,
|
||||
sample_rate=hps.data.sampling_rate,
|
||||
f_min=hps.data.mel_fmin,
|
||||
f_max=hps.data.mel_fmax,
|
||||
).to(spec.device)(spec)
|
||||
|
||||
|
||||
def mel_spectrogram_torch(audio: torch.Tensor, hps: HParams) -> torch.Tensor:
|
||||
return torchaudio.transforms.MelSpectrogram(
|
||||
sample_rate=hps.data.sampling_rate,
|
||||
n_fft=hps.data.filter_length,
|
||||
n_mels=hps.data.n_mel_channels,
|
||||
win_length=hps.data.win_length,
|
||||
hop_length=hps.data.hop_length,
|
||||
f_min=hps.data.mel_fmin,
|
||||
f_max=hps.data.mel_fmax,
|
||||
power=1.0,
|
||||
window_fn=torch.hann_window,
|
||||
normalized=False,
|
||||
).to(audio.device)(audio)"""
|
||||
|
||||
from logging import getLogger
|
||||
|
||||
import torch
|
||||
import torch.utils.data
|
||||
from librosa.filters import mel as librosa_mel_fn
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
MAX_WAV_VALUE = 32768.0
|
||||
|
||||
|
||||
def dynamic_range_compression_torch(x, C=1, clip_val=1e-5):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor
|
||||
"""
|
||||
return torch.log(torch.clamp(x, min=clip_val) * C)
|
||||
|
||||
|
||||
def dynamic_range_decompression_torch(x, C=1):
|
||||
"""
|
||||
PARAMS
|
||||
------
|
||||
C: compression factor used to compress
|
||||
"""
|
||||
return torch.exp(x) / C
|
||||
|
||||
|
||||
def spectral_normalize_torch(magnitudes):
|
||||
output = dynamic_range_compression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
def spectral_de_normalize_torch(magnitudes):
|
||||
output = dynamic_range_decompression_torch(magnitudes)
|
||||
return output
|
||||
|
||||
|
||||
mel_basis = {}
|
||||
hann_window = {}
|
||||
|
||||
|
||||
def spectrogram_torch(y, hps, center=False):
|
||||
if torch.min(y) < -1.0:
|
||||
LOG.info("min value is ", torch.min(y))
|
||||
if torch.max(y) > 1.0:
|
||||
LOG.info("max value is ", torch.max(y))
|
||||
n_fft = hps.data.filter_length
|
||||
hop_size = hps.data.hop_length
|
||||
win_size = hps.data.win_length
|
||||
global hann_window
|
||||
dtype_device = str(y.dtype) + "_" + str(y.device)
|
||||
wnsize_dtype_device = str(win_size) + "_" + dtype_device
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
|
||||
y = torch.nn.functional.pad(
|
||||
y.unsqueeze(1),
|
||||
(int((n_fft - hop_size) / 2), int((n_fft - hop_size) / 2)),
|
||||
mode="reflect",
|
||||
)
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(
|
||||
y,
|
||||
n_fft,
|
||||
hop_length=hop_size,
|
||||
win_length=win_size,
|
||||
window=hann_window[wnsize_dtype_device],
|
||||
center=center,
|
||||
pad_mode="reflect",
|
||||
normalized=False,
|
||||
onesided=True,
|
||||
return_complex=False,
|
||||
)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
return spec
|
||||
|
||||
|
||||
def spec_to_mel_torch(spec, hps):
|
||||
sampling_rate = hps.data.sampling_rate
|
||||
n_fft = hps.data.filter_length
|
||||
num_mels = hps.data.n_mel_channels
|
||||
fmin = hps.data.mel_fmin
|
||||
fmax = hps.data.mel_fmax
|
||||
global mel_basis
|
||||
dtype_device = str(spec.dtype) + "_" + str(spec.device)
|
||||
fmax_dtype_device = str(fmax) + "_" + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(
|
||||
sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax
|
||||
)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(
|
||||
dtype=spec.dtype, device=spec.device
|
||||
)
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
return spec
|
||||
|
||||
|
||||
def mel_spectrogram_torch(y, hps, center=False):
|
||||
sampling_rate = hps.data.sampling_rate
|
||||
n_fft = hps.data.filter_length
|
||||
num_mels = hps.data.n_mel_channels
|
||||
fmin = hps.data.mel_fmin
|
||||
fmax = hps.data.mel_fmax
|
||||
hop_size = hps.data.hop_length
|
||||
win_size = hps.data.win_length
|
||||
if torch.min(y) < -1.0:
|
||||
LOG.info(f"min value is {torch.min(y)}")
|
||||
if torch.max(y) > 1.0:
|
||||
LOG.info(f"max value is {torch.max(y)}")
|
||||
|
||||
global mel_basis, hann_window
|
||||
dtype_device = str(y.dtype) + "_" + str(y.device)
|
||||
fmax_dtype_device = str(fmax) + "_" + dtype_device
|
||||
wnsize_dtype_device = str(win_size) + "_" + dtype_device
|
||||
if fmax_dtype_device not in mel_basis:
|
||||
mel = librosa_mel_fn(
|
||||
sr=sampling_rate, n_fft=n_fft, n_mels=num_mels, fmin=fmin, fmax=fmax
|
||||
)
|
||||
mel_basis[fmax_dtype_device] = torch.from_numpy(mel).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
if wnsize_dtype_device not in hann_window:
|
||||
hann_window[wnsize_dtype_device] = torch.hann_window(win_size).to(
|
||||
dtype=y.dtype, device=y.device
|
||||
)
|
||||
|
||||
y = torch.nn.functional.pad(
|
||||
y.unsqueeze(1),
|
||||
(int((n_fft - hop_size) / 2), int((n_fft - hop_size) / 2)),
|
||||
mode="reflect",
|
||||
)
|
||||
y = y.squeeze(1)
|
||||
|
||||
spec = torch.stft(
|
||||
y,
|
||||
n_fft,
|
||||
hop_length=hop_size,
|
||||
win_length=win_size,
|
||||
window=hann_window[wnsize_dtype_device],
|
||||
center=center,
|
||||
pad_mode="reflect",
|
||||
normalized=False,
|
||||
onesided=True,
|
||||
return_complex=False,
|
||||
)
|
||||
|
||||
spec = torch.sqrt(spec.pow(2).sum(-1) + 1e-6)
|
||||
|
||||
spec = torch.matmul(mel_basis[fmax_dtype_device], spec)
|
||||
spec = spectral_normalize_torch(spec)
|
||||
|
||||
return spec
|
||||
@@ -0,0 +1,452 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import Conv1d
|
||||
from torch.nn import functional as F
|
||||
from torch.nn.utils import remove_weight_norm, weight_norm
|
||||
|
||||
from so_vits_svc_fork.modules import commons
|
||||
from so_vits_svc_fork.modules.commons import get_padding, init_weights
|
||||
|
||||
LRELU_SLOPE = 0.1
|
||||
|
||||
|
||||
class LayerNorm(nn.Module):
|
||||
def __init__(self, channels, eps=1e-5):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.eps = eps
|
||||
|
||||
self.gamma = nn.Parameter(torch.ones(channels))
|
||||
self.beta = nn.Parameter(torch.zeros(channels))
|
||||
|
||||
def forward(self, x):
|
||||
x = x.transpose(1, -1)
|
||||
x = F.layer_norm(x, (self.channels,), self.gamma, self.beta, self.eps)
|
||||
return x.transpose(1, -1)
|
||||
|
||||
|
||||
class ConvReluNorm(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
hidden_channels,
|
||||
out_channels,
|
||||
kernel_size,
|
||||
n_layers,
|
||||
p_dropout,
|
||||
):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.out_channels = out_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
assert n_layers > 1, "Number of layers should be larger than 0."
|
||||
|
||||
self.conv_layers = nn.ModuleList()
|
||||
self.norm_layers = nn.ModuleList()
|
||||
self.conv_layers.append(
|
||||
nn.Conv1d(
|
||||
in_channels, hidden_channels, kernel_size, padding=kernel_size // 2
|
||||
)
|
||||
)
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.relu_drop = nn.Sequential(nn.ReLU(), nn.Dropout(p_dropout))
|
||||
for _ in range(n_layers - 1):
|
||||
self.conv_layers.append(
|
||||
nn.Conv1d(
|
||||
hidden_channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
padding=kernel_size // 2,
|
||||
)
|
||||
)
|
||||
self.norm_layers.append(LayerNorm(hidden_channels))
|
||||
self.proj = nn.Conv1d(hidden_channels, out_channels, 1)
|
||||
self.proj.weight.data.zero_()
|
||||
self.proj.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask):
|
||||
x_org = x
|
||||
for i in range(self.n_layers):
|
||||
x = self.conv_layers[i](x * x_mask)
|
||||
x = self.norm_layers[i](x)
|
||||
x = self.relu_drop(x)
|
||||
x = x_org + self.proj(x)
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class DDSConv(nn.Module):
|
||||
"""
|
||||
Dialted and Depth-Separable Convolution
|
||||
"""
|
||||
|
||||
def __init__(self, channels, kernel_size, n_layers, p_dropout=0.0):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.kernel_size = kernel_size
|
||||
self.n_layers = n_layers
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
self.convs_sep = nn.ModuleList()
|
||||
self.convs_1x1 = nn.ModuleList()
|
||||
self.norms_1 = nn.ModuleList()
|
||||
self.norms_2 = nn.ModuleList()
|
||||
for i in range(n_layers):
|
||||
dilation = kernel_size**i
|
||||
padding = (kernel_size * dilation - dilation) // 2
|
||||
self.convs_sep.append(
|
||||
nn.Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
groups=channels,
|
||||
dilation=dilation,
|
||||
padding=padding,
|
||||
)
|
||||
)
|
||||
self.convs_1x1.append(nn.Conv1d(channels, channels, 1))
|
||||
self.norms_1.append(LayerNorm(channels))
|
||||
self.norms_2.append(LayerNorm(channels))
|
||||
|
||||
def forward(self, x, x_mask, g=None):
|
||||
if g is not None:
|
||||
x = x + g
|
||||
for i in range(self.n_layers):
|
||||
y = self.convs_sep[i](x * x_mask)
|
||||
y = self.norms_1[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.convs_1x1[i](y)
|
||||
y = self.norms_2[i](y)
|
||||
y = F.gelu(y)
|
||||
y = self.drop(y)
|
||||
x = x + y
|
||||
return x * x_mask
|
||||
|
||||
|
||||
class WN(torch.nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
gin_channels=0,
|
||||
p_dropout=0,
|
||||
):
|
||||
super().__init__()
|
||||
assert kernel_size % 2 == 1
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = (kernel_size,)
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.gin_channels = gin_channels
|
||||
self.p_dropout = p_dropout
|
||||
|
||||
self.in_layers = torch.nn.ModuleList()
|
||||
self.res_skip_layers = torch.nn.ModuleList()
|
||||
self.drop = nn.Dropout(p_dropout)
|
||||
|
||||
if gin_channels != 0:
|
||||
cond_layer = torch.nn.Conv1d(
|
||||
gin_channels, 2 * hidden_channels * n_layers, 1
|
||||
)
|
||||
self.cond_layer = torch.nn.utils.weight_norm(cond_layer, name="weight")
|
||||
|
||||
for i in range(n_layers):
|
||||
dilation = dilation_rate**i
|
||||
padding = int((kernel_size * dilation - dilation) / 2)
|
||||
in_layer = torch.nn.Conv1d(
|
||||
hidden_channels,
|
||||
2 * hidden_channels,
|
||||
kernel_size,
|
||||
dilation=dilation,
|
||||
padding=padding,
|
||||
)
|
||||
in_layer = torch.nn.utils.weight_norm(in_layer, name="weight")
|
||||
self.in_layers.append(in_layer)
|
||||
|
||||
# last one is not necessary
|
||||
if i < n_layers - 1:
|
||||
res_skip_channels = 2 * hidden_channels
|
||||
else:
|
||||
res_skip_channels = hidden_channels
|
||||
|
||||
res_skip_layer = torch.nn.Conv1d(hidden_channels, res_skip_channels, 1)
|
||||
res_skip_layer = torch.nn.utils.weight_norm(res_skip_layer, name="weight")
|
||||
self.res_skip_layers.append(res_skip_layer)
|
||||
|
||||
def forward(self, x, x_mask, g=None, **kwargs):
|
||||
output = torch.zeros_like(x)
|
||||
n_channels_tensor = torch.IntTensor([self.hidden_channels])
|
||||
|
||||
if g is not None:
|
||||
g = self.cond_layer(g)
|
||||
|
||||
for i in range(self.n_layers):
|
||||
x_in = self.in_layers[i](x)
|
||||
if g is not None:
|
||||
cond_offset = i * 2 * self.hidden_channels
|
||||
g_l = g[:, cond_offset : cond_offset + 2 * self.hidden_channels, :]
|
||||
else:
|
||||
g_l = torch.zeros_like(x_in)
|
||||
|
||||
acts = commons.fused_add_tanh_sigmoid_multiply(x_in, g_l, n_channels_tensor)
|
||||
acts = self.drop(acts)
|
||||
|
||||
res_skip_acts = self.res_skip_layers[i](acts)
|
||||
if i < self.n_layers - 1:
|
||||
res_acts = res_skip_acts[:, : self.hidden_channels, :]
|
||||
x = (x + res_acts) * x_mask
|
||||
output = output + res_skip_acts[:, self.hidden_channels :, :]
|
||||
else:
|
||||
output = output + res_skip_acts
|
||||
return output * x_mask
|
||||
|
||||
def remove_weight_norm(self):
|
||||
if self.gin_channels != 0:
|
||||
torch.nn.utils.remove_weight_norm(self.cond_layer)
|
||||
for l in self.in_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
for l in self.res_skip_layers:
|
||||
torch.nn.utils.remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock1(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3, 5)):
|
||||
super().__init__()
|
||||
self.convs1 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[2],
|
||||
padding=get_padding(kernel_size, dilation[2]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs1.apply(init_weights)
|
||||
|
||||
self.convs2 = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=1,
|
||||
padding=get_padding(kernel_size, 1),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs2.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c1, c2 in zip(self.convs1, self.convs2):
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c1(xt)
|
||||
xt = F.leaky_relu(xt, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c2(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs1:
|
||||
remove_weight_norm(l)
|
||||
for l in self.convs2:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class ResBlock2(torch.nn.Module):
|
||||
def __init__(self, channels, kernel_size=3, dilation=(1, 3)):
|
||||
super().__init__()
|
||||
self.convs = nn.ModuleList(
|
||||
[
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[0],
|
||||
padding=get_padding(kernel_size, dilation[0]),
|
||||
)
|
||||
),
|
||||
weight_norm(
|
||||
Conv1d(
|
||||
channels,
|
||||
channels,
|
||||
kernel_size,
|
||||
1,
|
||||
dilation=dilation[1],
|
||||
padding=get_padding(kernel_size, dilation[1]),
|
||||
)
|
||||
),
|
||||
]
|
||||
)
|
||||
self.convs.apply(init_weights)
|
||||
|
||||
def forward(self, x, x_mask=None):
|
||||
for c in self.convs:
|
||||
xt = F.leaky_relu(x, LRELU_SLOPE)
|
||||
if x_mask is not None:
|
||||
xt = xt * x_mask
|
||||
xt = c(xt)
|
||||
x = xt + x
|
||||
if x_mask is not None:
|
||||
x = x * x_mask
|
||||
return x
|
||||
|
||||
def remove_weight_norm(self):
|
||||
for l in self.convs:
|
||||
remove_weight_norm(l)
|
||||
|
||||
|
||||
class Log(nn.Module):
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = torch.log(torch.clamp_min(x, 1e-5)) * x_mask
|
||||
logdet = torch.sum(-y, [1, 2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = torch.exp(x) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class Flip(nn.Module):
|
||||
def forward(self, x, *args, reverse=False, **kwargs):
|
||||
x = torch.flip(x, [1])
|
||||
if not reverse:
|
||||
logdet = torch.zeros(x.size(0)).to(dtype=x.dtype, device=x.device)
|
||||
return x, logdet
|
||||
else:
|
||||
return x
|
||||
|
||||
|
||||
class ElementwiseAffine(nn.Module):
|
||||
def __init__(self, channels):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.m = nn.Parameter(torch.zeros(channels, 1))
|
||||
self.logs = nn.Parameter(torch.zeros(channels, 1))
|
||||
|
||||
def forward(self, x, x_mask, reverse=False, **kwargs):
|
||||
if not reverse:
|
||||
y = self.m + torch.exp(self.logs) * x
|
||||
y = y * x_mask
|
||||
logdet = torch.sum(self.logs * x_mask, [1, 2])
|
||||
return y, logdet
|
||||
else:
|
||||
x = (x - self.m) * torch.exp(-self.logs) * x_mask
|
||||
return x
|
||||
|
||||
|
||||
class ResidualCouplingLayer(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
p_dropout=0,
|
||||
gin_channels=0,
|
||||
mean_only=False,
|
||||
):
|
||||
assert channels % 2 == 0, "channels should be divisible by 2"
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.kernel_size = kernel_size
|
||||
self.dilation_rate = dilation_rate
|
||||
self.n_layers = n_layers
|
||||
self.half_channels = channels // 2
|
||||
self.mean_only = mean_only
|
||||
|
||||
self.pre = nn.Conv1d(self.half_channels, hidden_channels, 1)
|
||||
self.enc = WN(
|
||||
hidden_channels,
|
||||
kernel_size,
|
||||
dilation_rate,
|
||||
n_layers,
|
||||
p_dropout=p_dropout,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.post = nn.Conv1d(hidden_channels, self.half_channels * (2 - mean_only), 1)
|
||||
self.post.weight.data.zero_()
|
||||
self.post.bias.data.zero_()
|
||||
|
||||
def forward(self, x, x_mask, g=None, reverse=False):
|
||||
x0, x1 = torch.split(x, [self.half_channels] * 2, 1)
|
||||
h = self.pre(x0) * x_mask
|
||||
h = self.enc(h, x_mask, g=g)
|
||||
stats = self.post(h) * x_mask
|
||||
if not self.mean_only:
|
||||
m, logs = torch.split(stats, [self.half_channels] * 2, 1)
|
||||
else:
|
||||
m = stats
|
||||
logs = torch.zeros_like(m)
|
||||
|
||||
if not reverse:
|
||||
x1 = m + x1 * torch.exp(logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
logdet = torch.sum(logs, [1, 2])
|
||||
return x, logdet
|
||||
else:
|
||||
x1 = (x1 - m) * torch.exp(-logs) * x_mask
|
||||
x = torch.cat([x0, x1], 1)
|
||||
return x
|
||||
@@ -0,0 +1,233 @@
|
||||
import warnings
|
||||
from logging import getLogger
|
||||
from typing import Any, Literal, Sequence
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
import so_vits_svc_fork.f0
|
||||
from so_vits_svc_fork.f0 import f0_to_coarse
|
||||
from so_vits_svc_fork.modules import commons as commons
|
||||
from so_vits_svc_fork.modules.decoders.f0 import F0Decoder
|
||||
from so_vits_svc_fork.modules.decoders.hifigan import NSFHifiGANGenerator
|
||||
from so_vits_svc_fork.modules.decoders.mb_istft import (
|
||||
Multiband_iSTFT_Generator,
|
||||
Multistream_iSTFT_Generator,
|
||||
iSTFT_Generator,
|
||||
)
|
||||
from so_vits_svc_fork.modules.encoders import Encoder, TextEncoder
|
||||
from so_vits_svc_fork.modules.flows import ResidualCouplingBlock
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
class SynthesizerTrn(nn.Module):
|
||||
"""
|
||||
Synthesizer for Training
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
spec_channels: int,
|
||||
segment_size: int,
|
||||
inter_channels: int,
|
||||
hidden_channels: int,
|
||||
filter_channels: int,
|
||||
n_heads: int,
|
||||
n_layers: int,
|
||||
kernel_size: int,
|
||||
p_dropout: int,
|
||||
resblock: str,
|
||||
resblock_kernel_sizes: Sequence[int],
|
||||
resblock_dilation_sizes: Sequence[Sequence[int]],
|
||||
upsample_rates: Sequence[int],
|
||||
upsample_initial_channel: int,
|
||||
upsample_kernel_sizes: Sequence[int],
|
||||
gin_channels: int,
|
||||
ssl_dim: int,
|
||||
n_speakers: int,
|
||||
sampling_rate: int = 44100,
|
||||
type_: Literal["hifi-gan", "istft", "ms-istft", "mb-istft"] = "hifi-gan",
|
||||
gen_istft_n_fft: int = 16,
|
||||
gen_istft_hop_size: int = 4,
|
||||
subbands: int = 4,
|
||||
**kwargs: Any,
|
||||
):
|
||||
super().__init__()
|
||||
self.spec_channels = spec_channels
|
||||
self.inter_channels = inter_channels
|
||||
self.hidden_channels = hidden_channels
|
||||
self.filter_channels = filter_channels
|
||||
self.n_heads = n_heads
|
||||
self.n_layers = n_layers
|
||||
self.kernel_size = kernel_size
|
||||
self.p_dropout = p_dropout
|
||||
self.resblock = resblock
|
||||
self.resblock_kernel_sizes = resblock_kernel_sizes
|
||||
self.resblock_dilation_sizes = resblock_dilation_sizes
|
||||
self.upsample_rates = upsample_rates
|
||||
self.upsample_initial_channel = upsample_initial_channel
|
||||
self.upsample_kernel_sizes = upsample_kernel_sizes
|
||||
self.segment_size = segment_size
|
||||
self.gin_channels = gin_channels
|
||||
self.ssl_dim = ssl_dim
|
||||
self.n_speakers = n_speakers
|
||||
self.sampling_rate = sampling_rate
|
||||
self.type_ = type_
|
||||
self.gen_istft_n_fft = gen_istft_n_fft
|
||||
self.gen_istft_hop_size = gen_istft_hop_size
|
||||
self.subbands = subbands
|
||||
if kwargs:
|
||||
warnings.warn(f"Unused arguments: {kwargs}")
|
||||
|
||||
self.emb_g = nn.Embedding(n_speakers, gin_channels)
|
||||
|
||||
if ssl_dim is None:
|
||||
self.pre = nn.LazyConv1d(hidden_channels, kernel_size=5, padding=2)
|
||||
else:
|
||||
self.pre = nn.Conv1d(ssl_dim, hidden_channels, kernel_size=5, padding=2)
|
||||
|
||||
self.enc_p = TextEncoder(
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
filter_channels=filter_channels,
|
||||
n_heads=n_heads,
|
||||
n_layers=n_layers,
|
||||
kernel_size=kernel_size,
|
||||
p_dropout=p_dropout,
|
||||
)
|
||||
|
||||
LOG.info(f"Decoder type: {type_}")
|
||||
if type_ == "hifi-gan":
|
||||
hps = {
|
||||
"sampling_rate": sampling_rate,
|
||||
"inter_channels": inter_channels,
|
||||
"resblock": resblock,
|
||||
"resblock_kernel_sizes": resblock_kernel_sizes,
|
||||
"resblock_dilation_sizes": resblock_dilation_sizes,
|
||||
"upsample_rates": upsample_rates,
|
||||
"upsample_initial_channel": upsample_initial_channel,
|
||||
"upsample_kernel_sizes": upsample_kernel_sizes,
|
||||
"gin_channels": gin_channels,
|
||||
}
|
||||
self.dec = NSFHifiGANGenerator(h=hps)
|
||||
self.mb = False
|
||||
else:
|
||||
hps = {
|
||||
"initial_channel": inter_channels,
|
||||
"resblock": resblock,
|
||||
"resblock_kernel_sizes": resblock_kernel_sizes,
|
||||
"resblock_dilation_sizes": resblock_dilation_sizes,
|
||||
"upsample_rates": upsample_rates,
|
||||
"upsample_initial_channel": upsample_initial_channel,
|
||||
"upsample_kernel_sizes": upsample_kernel_sizes,
|
||||
"gin_channels": gin_channels,
|
||||
"gen_istft_n_fft": gen_istft_n_fft,
|
||||
"gen_istft_hop_size": gen_istft_hop_size,
|
||||
"subbands": subbands,
|
||||
}
|
||||
|
||||
# gen_istft_n_fft, gen_istft_hop_size, subbands
|
||||
if type_ == "istft":
|
||||
del hps["subbands"]
|
||||
self.dec = iSTFT_Generator(**hps)
|
||||
elif type_ == "ms-istft":
|
||||
self.dec = Multistream_iSTFT_Generator(**hps)
|
||||
elif type_ == "mb-istft":
|
||||
self.dec = Multiband_iSTFT_Generator(**hps)
|
||||
else:
|
||||
raise ValueError(f"Unknown type: {type_}")
|
||||
self.mb = True
|
||||
|
||||
self.enc_q = Encoder(
|
||||
spec_channels,
|
||||
inter_channels,
|
||||
hidden_channels,
|
||||
5,
|
||||
1,
|
||||
16,
|
||||
gin_channels=gin_channels,
|
||||
)
|
||||
self.flow = ResidualCouplingBlock(
|
||||
inter_channels, hidden_channels, 5, 1, 4, gin_channels=gin_channels
|
||||
)
|
||||
self.f0_decoder = F0Decoder(
|
||||
1,
|
||||
hidden_channels,
|
||||
filter_channels,
|
||||
n_heads,
|
||||
n_layers,
|
||||
kernel_size,
|
||||
p_dropout,
|
||||
spk_channels=gin_channels,
|
||||
)
|
||||
self.emb_uv = nn.Embedding(2, hidden_channels)
|
||||
|
||||
def forward(self, c, f0, uv, spec, g=None, c_lengths=None, spec_lengths=None):
|
||||
g = self.emb_g(g).transpose(1, 2)
|
||||
# ssl prenet
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(
|
||||
c.dtype
|
||||
)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1, 2)
|
||||
|
||||
# f0 predict
|
||||
lf0 = 2595.0 * torch.log10(1.0 + f0.unsqueeze(1) / 700.0) / 500
|
||||
norm_lf0 = so_vits_svc_fork.f0.normalize_f0(lf0, x_mask, uv)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
|
||||
# encoder
|
||||
z_ptemp, m_p, logs_p, _ = self.enc_p(x, x_mask, f0=f0_to_coarse(f0))
|
||||
z, m_q, logs_q, spec_mask = self.enc_q(spec, spec_lengths, g=g)
|
||||
|
||||
# flow
|
||||
z_p = self.flow(z, spec_mask, g=g)
|
||||
z_slice, pitch_slice, ids_slice = commons.rand_slice_segments_with_pitch(
|
||||
z, f0, spec_lengths, self.segment_size
|
||||
)
|
||||
|
||||
# MB-iSTFT-VITS
|
||||
if self.mb:
|
||||
o, o_mb = self.dec(z_slice, g=g)
|
||||
# HiFi-GAN
|
||||
else:
|
||||
o = self.dec(z_slice, g=g, f0=pitch_slice)
|
||||
o_mb = None
|
||||
return (
|
||||
o,
|
||||
o_mb,
|
||||
ids_slice,
|
||||
spec_mask,
|
||||
(z, z_p, m_p, logs_p, m_q, logs_q),
|
||||
pred_lf0,
|
||||
norm_lf0,
|
||||
lf0,
|
||||
)
|
||||
|
||||
def infer(self, c, f0, uv, g=None, noice_scale=0.35, predict_f0=False):
|
||||
c_lengths = (torch.ones(c.size(0)) * c.size(-1)).to(c.device)
|
||||
g = self.emb_g(g).transpose(1, 2)
|
||||
x_mask = torch.unsqueeze(commons.sequence_mask(c_lengths, c.size(2)), 1).to(
|
||||
c.dtype
|
||||
)
|
||||
x = self.pre(c) * x_mask + self.emb_uv(uv.long()).transpose(1, 2)
|
||||
|
||||
if predict_f0:
|
||||
lf0 = 2595.0 * torch.log10(1.0 + f0.unsqueeze(1) / 700.0) / 500
|
||||
norm_lf0 = so_vits_svc_fork.f0.normalize_f0(
|
||||
lf0, x_mask, uv, random_scale=False
|
||||
)
|
||||
pred_lf0 = self.f0_decoder(x, norm_lf0, x_mask, spk_emb=g)
|
||||
f0 = (700 * (torch.pow(10, pred_lf0 * 500 / 2595) - 1)).squeeze(1)
|
||||
|
||||
z_p, m_p, logs_p, c_mask = self.enc_p(
|
||||
x, x_mask, f0=f0_to_coarse(f0), noice_scale=noice_scale
|
||||
)
|
||||
z = self.flow(z_p, c_mask, g=g, reverse=True)
|
||||
|
||||
# MB-iSTFT-VITS
|
||||
if self.mb:
|
||||
o, o_mb = self.dec(z * c_mask, g=g)
|
||||
else:
|
||||
o = self.dec(z * c_mask, g=g, f0=f0)
|
||||
return o
|
||||
+74
@@ -0,0 +1,74 @@
|
||||
{
|
||||
"train": {
|
||||
"log_interval": 100,
|
||||
"eval_interval": 200,
|
||||
"seed": 1234,
|
||||
"epochs": 10000,
|
||||
"learning_rate": 0.0001,
|
||||
"betas": [0.8, 0.99],
|
||||
"eps": 1e-9,
|
||||
"batch_size": 16,
|
||||
"fp16_run": false,
|
||||
"bf16_run": false,
|
||||
"lr_decay": 0.999875,
|
||||
"segment_size": 10240,
|
||||
"init_lr_ratio": 1,
|
||||
"warmup_epochs": 0,
|
||||
"c_mel": 45,
|
||||
"c_kl": 1.0,
|
||||
"use_sr": true,
|
||||
"max_speclen": 512,
|
||||
"port": "8001",
|
||||
"keep_ckpts": 3,
|
||||
"fft_sizes": [768, 1366, 342],
|
||||
"hop_sizes": [60, 120, 20],
|
||||
"win_lengths": [300, 600, 120],
|
||||
"window": "hann_window",
|
||||
"num_workers": 4,
|
||||
"log_version": 0,
|
||||
"ckpt_name_by_step": false,
|
||||
"accumulate_grad_batches": 1
|
||||
},
|
||||
"data": {
|
||||
"training_files": "filelists/44k/train.txt",
|
||||
"validation_files": "filelists/44k/val.txt",
|
||||
"max_wav_value": 32768.0,
|
||||
"sampling_rate": 44100,
|
||||
"filter_length": 2048,
|
||||
"hop_length": 512,
|
||||
"win_length": 2048,
|
||||
"n_mel_channels": 80,
|
||||
"mel_fmin": 0.0,
|
||||
"mel_fmax": 22050,
|
||||
"contentvec_final_proj": false
|
||||
},
|
||||
"model": {
|
||||
"inter_channels": 192,
|
||||
"hidden_channels": 192,
|
||||
"filter_channels": 768,
|
||||
"n_heads": 2,
|
||||
"n_layers": 6,
|
||||
"kernel_size": 3,
|
||||
"p_dropout": 0.1,
|
||||
"resblock": "1",
|
||||
"resblock_kernel_sizes": [3, 7, 11],
|
||||
"resblock_dilation_sizes": [
|
||||
[1, 3, 5],
|
||||
[1, 3, 5],
|
||||
[1, 3, 5]
|
||||
],
|
||||
"upsample_rates": [8, 4],
|
||||
"upsample_initial_channel": 512,
|
||||
"upsample_kernel_sizes": [32, 16],
|
||||
"n_layers_q": 3,
|
||||
"use_spectral_norm": false,
|
||||
"gin_channels": 256,
|
||||
"ssl_dim": 768,
|
||||
"n_speakers": 200,
|
||||
"type_": "ms-istft",
|
||||
"gen_istft_n_fft": 16,
|
||||
"gen_istft_hop_size": 4,
|
||||
"subbands": 4
|
||||
},
|
||||
"spk": {}
|
||||
}
|
||||
+65
@@ -0,0 +1,65 @@
|
||||
{
|
||||
"train": {
|
||||
"log_interval": 200,
|
||||
"eval_interval": 800,
|
||||
"seed": 1234,
|
||||
"epochs": 10000,
|
||||
"learning_rate": 0.0001,
|
||||
"betas": [0.8, 0.99],
|
||||
"eps": 1e-9,
|
||||
"batch_size": 16,
|
||||
"fp16_run": false,
|
||||
"bf16_run": false,
|
||||
"lr_decay": 0.999875,
|
||||
"segment_size": 10240,
|
||||
"init_lr_ratio": 1,
|
||||
"warmup_epochs": 0,
|
||||
"c_mel": 45,
|
||||
"c_kl": 1.0,
|
||||
"use_sr": true,
|
||||
"max_speclen": 512,
|
||||
"port": "8001",
|
||||
"keep_ckpts": 3,
|
||||
"num_workers": 4,
|
||||
"log_version": 0,
|
||||
"ckpt_name_by_step": false,
|
||||
"accumulate_grad_batches": 1
|
||||
},
|
||||
"data": {
|
||||
"training_files": "filelists/44k/train.txt",
|
||||
"validation_files": "filelists/44k/val.txt",
|
||||
"max_wav_value": 32768.0,
|
||||
"sampling_rate": 44100,
|
||||
"filter_length": 2048,
|
||||
"hop_length": 512,
|
||||
"win_length": 2048,
|
||||
"n_mel_channels": 80,
|
||||
"mel_fmin": 0.0,
|
||||
"mel_fmax": 22050
|
||||
},
|
||||
"model": {
|
||||
"inter_channels": 192,
|
||||
"hidden_channels": 192,
|
||||
"filter_channels": 768,
|
||||
"n_heads": 2,
|
||||
"n_layers": 6,
|
||||
"kernel_size": 3,
|
||||
"p_dropout": 0.1,
|
||||
"resblock": "1",
|
||||
"resblock_kernel_sizes": [3, 7, 11],
|
||||
"resblock_dilation_sizes": [
|
||||
[1, 3, 5],
|
||||
[1, 3, 5],
|
||||
[1, 3, 5]
|
||||
],
|
||||
"upsample_rates": [8, 8, 2, 2, 2],
|
||||
"upsample_initial_channel": 512,
|
||||
"upsample_kernel_sizes": [16, 16, 4, 4, 4],
|
||||
"n_layers_q": 3,
|
||||
"use_spectral_norm": false,
|
||||
"gin_channels": 256,
|
||||
"ssl_dim": 256,
|
||||
"n_speakers": 200
|
||||
},
|
||||
"spk": {}
|
||||
}
|
||||
+67
@@ -0,0 +1,67 @@
|
||||
{
|
||||
"train": {
|
||||
"log_interval": 100,
|
||||
"eval_interval": 200,
|
||||
"seed": 1234,
|
||||
"epochs": 10000,
|
||||
"learning_rate": 0.0001,
|
||||
"betas": [0.8, 0.99],
|
||||
"eps": 1e-9,
|
||||
"batch_size": 16,
|
||||
"fp16_run": false,
|
||||
"bf16_run": false,
|
||||
"lr_decay": 0.999875,
|
||||
"segment_size": 10240,
|
||||
"init_lr_ratio": 1,
|
||||
"warmup_epochs": 0,
|
||||
"c_mel": 45,
|
||||
"c_kl": 1.0,
|
||||
"use_sr": true,
|
||||
"max_speclen": 512,
|
||||
"port": "8001",
|
||||
"keep_ckpts": 3,
|
||||
"num_workers": 4,
|
||||
"log_version": 0,
|
||||
"ckpt_name_by_step": false,
|
||||
"accumulate_grad_batches": 1
|
||||
},
|
||||
"data": {
|
||||
"training_files": "filelists/44k/train.txt",
|
||||
"validation_files": "filelists/44k/val.txt",
|
||||
"max_wav_value": 32768.0,
|
||||
"sampling_rate": 44100,
|
||||
"filter_length": 2048,
|
||||
"hop_length": 512,
|
||||
"win_length": 2048,
|
||||
"n_mel_channels": 80,
|
||||
"mel_fmin": 0.0,
|
||||
"mel_fmax": 22050,
|
||||
"contentvec_final_proj": false
|
||||
},
|
||||
"model": {
|
||||
"inter_channels": 192,
|
||||
"hidden_channels": 192,
|
||||
"filter_channels": 768,
|
||||
"n_heads": 2,
|
||||
"n_layers": 6,
|
||||
"kernel_size": 3,
|
||||
"p_dropout": 0.1,
|
||||
"resblock": "1",
|
||||
"resblock_kernel_sizes": [3, 7, 11],
|
||||
"resblock_dilation_sizes": [
|
||||
[1, 3, 5],
|
||||
[1, 3, 5],
|
||||
[1, 3, 5]
|
||||
],
|
||||
"upsample_rates": [8, 8, 2, 2, 2],
|
||||
"upsample_initial_channel": 512,
|
||||
"upsample_kernel_sizes": [16, 16, 4, 4, 4],
|
||||
"n_layers_q": 3,
|
||||
"use_spectral_norm": false,
|
||||
"gin_channels": 256,
|
||||
"ssl_dim": 768,
|
||||
"n_speakers": 200,
|
||||
"type_": "hifi-gan"
|
||||
},
|
||||
"spk": {}
|
||||
}
|
||||
+95
@@ -0,0 +1,95 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import keyboard
|
||||
import librosa
|
||||
import sounddevice as sd
|
||||
import soundfile as sf
|
||||
from rich.console import Console
|
||||
from tqdm.rich import tqdm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def preprocess_classify(
|
||||
input_dir: Path | str, output_dir: Path | str, create_new: bool = True
|
||||
) -> None:
|
||||
# paths
|
||||
input_dir_ = Path(input_dir)
|
||||
output_dir_ = Path(output_dir)
|
||||
speed = 1
|
||||
if not input_dir_.is_dir():
|
||||
raise ValueError(f"{input_dir} is not a directory.")
|
||||
output_dir_.mkdir(exist_ok=True)
|
||||
|
||||
console = Console()
|
||||
# get audio paths and folders
|
||||
audio_paths = list(input_dir_.glob("*.*"))
|
||||
last_folders = [x for x in output_dir_.glob("*") if x.is_dir()]
|
||||
console.print("Press ↑ or ↓ to change speed. Press any other key to classify.")
|
||||
console.print(f"Folders: {[x.name for x in last_folders]}")
|
||||
|
||||
pbar_description = ""
|
||||
|
||||
pbar = tqdm(audio_paths)
|
||||
for audio_path in pbar:
|
||||
# read file
|
||||
audio, sr = sf.read(audio_path)
|
||||
|
||||
# update description
|
||||
duration = librosa.get_duration(y=audio, sr=sr)
|
||||
pbar_description = f"{duration:.1f} {pbar_description}"
|
||||
pbar.set_description(pbar_description)
|
||||
|
||||
while True:
|
||||
# start playing
|
||||
sd.play(librosa.effects.time_stretch(audio, rate=speed), sr, loop=True)
|
||||
|
||||
# wait for key press
|
||||
key = str(keyboard.read_key())
|
||||
if key == "down":
|
||||
speed /= 1.1
|
||||
console.print(f"Speed: {speed:.2f}")
|
||||
elif key == "up":
|
||||
speed *= 1.1
|
||||
console.print(f"Speed: {speed:.2f}")
|
||||
else:
|
||||
break
|
||||
|
||||
# stop playing
|
||||
sd.stop()
|
||||
|
||||
# print if folder changed
|
||||
folders = [x for x in output_dir_.glob("*") if x.is_dir()]
|
||||
if folders != last_folders:
|
||||
console.print(f"Folders updated: {[x.name for x in folders]}")
|
||||
last_folders = folders
|
||||
|
||||
# get folder
|
||||
folder_candidates = [x for x in folders if x.name.startswith(key)]
|
||||
if len(folder_candidates) == 0:
|
||||
if create_new:
|
||||
folder = output_dir_ / key
|
||||
else:
|
||||
console.print(f"No folder starts with {key}.")
|
||||
continue
|
||||
else:
|
||||
if len(folder_candidates) > 1:
|
||||
LOG.warning(
|
||||
f"Multiple folders ({[x.name for x in folder_candidates]}) start with {key}. "
|
||||
f"Using first one ({folder_candidates[0].name})."
|
||||
)
|
||||
folder = folder_candidates[0]
|
||||
folder.mkdir(exist_ok=True)
|
||||
|
||||
# move file
|
||||
new_path = folder / audio_path.name
|
||||
audio_path.rename(new_path)
|
||||
|
||||
# update description
|
||||
pbar_description = f"Last: {audio_path.name} -> {folder.name}"
|
||||
|
||||
# yield result
|
||||
# yield audio_path, key, folder, new_path
|
||||
+85
@@ -0,0 +1,85 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
from copy import deepcopy
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from random import shuffle
|
||||
|
||||
from librosa import get_duration
|
||||
from tqdm import tqdm
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
CONFIG_TEMPLATE_DIR = Path(__file__).parent / "config_templates"
|
||||
|
||||
|
||||
def preprocess_config(
|
||||
input_dir: Path | str,
|
||||
train_list_path: Path | str,
|
||||
val_list_path: Path | str,
|
||||
test_list_path: Path | str,
|
||||
config_path: Path | str,
|
||||
config_name: str,
|
||||
):
|
||||
input_dir = Path(input_dir)
|
||||
train_list_path = Path(train_list_path)
|
||||
val_list_path = Path(val_list_path)
|
||||
test_list_path = Path(test_list_path)
|
||||
config_path = Path(config_path)
|
||||
train = []
|
||||
val = []
|
||||
test = []
|
||||
spk_dict = {}
|
||||
spk_id = 0
|
||||
for speaker in os.listdir(input_dir):
|
||||
spk_dict[speaker] = spk_id
|
||||
spk_id += 1
|
||||
paths = []
|
||||
for path in tqdm(list((input_dir / speaker).rglob("*.wav"))):
|
||||
if get_duration(filename=path) < 0.3:
|
||||
LOG.warning(f"skip {path} because it is too short.")
|
||||
continue
|
||||
paths.append(path)
|
||||
shuffle(paths)
|
||||
if len(paths) <= 4:
|
||||
raise ValueError(
|
||||
f"too few files in {input_dir / speaker} (expected at least 5)."
|
||||
)
|
||||
train += paths[2:-2]
|
||||
val += paths[:2]
|
||||
test += paths[-2:]
|
||||
|
||||
LOG.info(f"Writing {train_list_path}")
|
||||
train_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
train_list_path.write_text(
|
||||
"\n".join([x.as_posix() for x in train]), encoding="utf-8"
|
||||
)
|
||||
|
||||
LOG.info(f"Writing {val_list_path}")
|
||||
val_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
val_list_path.write_text("\n".join([x.as_posix() for x in val]), encoding="utf-8")
|
||||
|
||||
LOG.info(f"Writing {test_list_path}")
|
||||
test_list_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
test_list_path.write_text("\n".join([x.as_posix() for x in test]), encoding="utf-8")
|
||||
|
||||
config = deepcopy(
|
||||
json.loads(
|
||||
(
|
||||
CONFIG_TEMPLATE_DIR
|
||||
/ (
|
||||
config_name
|
||||
if config_name.endswith(".json")
|
||||
else config_name + ".json"
|
||||
)
|
||||
).read_text(encoding="utf-8")
|
||||
)
|
||||
)
|
||||
config["spk"] = spk_dict
|
||||
config["data"]["training_files"] = train_list_path.as_posix()
|
||||
config["data"]["validation_files"] = val_list_path.as_posix()
|
||||
LOG.info(f"Writing {config_path}")
|
||||
config_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with config_path.open("w", encoding="utf-8") as f:
|
||||
json.dump(config, f, indent=2)
|
||||
+157
@@ -0,0 +1,157 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from random import shuffle
|
||||
from typing import Iterable, Literal
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchaudio
|
||||
from joblib import Parallel, cpu_count, delayed
|
||||
from tqdm import tqdm
|
||||
from transformers import HubertModel
|
||||
|
||||
import so_vits_svc_fork.f0
|
||||
from so_vits_svc_fork import utils
|
||||
|
||||
from ..hparams import HParams
|
||||
from ..modules.mel_processing import spec_to_mel_torch, spectrogram_torch
|
||||
from ..utils import get_optimal_device, get_total_gpu_memory
|
||||
from .preprocess_utils import check_hubert_min_duration
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
HUBERT_MEMORY = 2900
|
||||
HUBERT_MEMORY_CREPE = 3900
|
||||
|
||||
|
||||
def _process_one(
|
||||
*,
|
||||
filepath: Path,
|
||||
content_model: HubertModel,
|
||||
device: torch.device | str = get_optimal_device(),
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
force_rebuild: bool = False,
|
||||
hps: HParams,
|
||||
):
|
||||
audio, sr = librosa.load(filepath, sr=hps.data.sampling_rate, mono=True)
|
||||
|
||||
if not check_hubert_min_duration(audio, sr):
|
||||
LOG.info(f"Skip {filepath} because it is too short.")
|
||||
return
|
||||
|
||||
data_path = filepath.parent / (filepath.name + ".data.pt")
|
||||
if data_path.exists() and not force_rebuild:
|
||||
return
|
||||
|
||||
# Compute f0
|
||||
f0 = so_vits_svc_fork.f0.compute_f0(
|
||||
audio, sampling_rate=sr, hop_length=hps.data.hop_length, method=f0_method
|
||||
)
|
||||
f0, uv = so_vits_svc_fork.f0.interpolate_f0(f0)
|
||||
f0 = torch.from_numpy(f0).float()
|
||||
uv = torch.from_numpy(uv).float()
|
||||
|
||||
# Compute HuBERT content
|
||||
audio = torch.from_numpy(audio).float().to(device)
|
||||
c = utils.get_content(
|
||||
content_model,
|
||||
audio,
|
||||
device,
|
||||
sr=sr,
|
||||
legacy_final_proj=hps.data.get("contentvec_final_proj", True),
|
||||
)
|
||||
c = utils.repeat_expand_2d(c.squeeze(0), f0.shape[0])
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# Compute spectrogram
|
||||
audio, sr = torchaudio.load(filepath)
|
||||
spec = spectrogram_torch(audio, hps).squeeze(0)
|
||||
mel_spec = spec_to_mel_torch(spec, hps)
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# fix lengths
|
||||
lmin = min(spec.shape[1], mel_spec.shape[1], f0.shape[0], uv.shape[0], c.shape[1])
|
||||
spec, mel_spec, f0, uv, c = (
|
||||
spec[:, :lmin],
|
||||
mel_spec[:, :lmin],
|
||||
f0[:lmin],
|
||||
uv[:lmin],
|
||||
c[:, :lmin],
|
||||
)
|
||||
|
||||
# get speaker id
|
||||
spk_name = filepath.parent.name
|
||||
spk = hps.spk.__dict__[spk_name]
|
||||
spk = torch.tensor(spk).long()
|
||||
assert (
|
||||
spec.shape[1] == mel_spec.shape[1] == f0.shape[0] == uv.shape[0] == c.shape[1]
|
||||
), (spec.shape, mel_spec.shape, f0.shape, uv.shape, c.shape)
|
||||
data = {
|
||||
"spec": spec,
|
||||
"mel_spec": mel_spec,
|
||||
"f0": f0,
|
||||
"uv": uv,
|
||||
"content": c,
|
||||
"audio": audio,
|
||||
"spk": spk,
|
||||
}
|
||||
data = {k: v.cpu() for k, v in data.items()}
|
||||
with data_path.open("wb") as f:
|
||||
torch.save(data, f)
|
||||
|
||||
|
||||
def _process_batch(filepaths: Iterable[Path], pbar_position: int, **kwargs):
|
||||
hps = kwargs["hps"]
|
||||
content_model = utils.get_hubert_model(
|
||||
get_optimal_device(), hps.data.get("contentvec_final_proj", True)
|
||||
)
|
||||
|
||||
for filepath in tqdm(filepaths, position=pbar_position):
|
||||
_process_one(
|
||||
content_model=content_model,
|
||||
filepath=filepath,
|
||||
**kwargs,
|
||||
)
|
||||
|
||||
|
||||
def preprocess_hubert_f0(
|
||||
input_dir: Path | str,
|
||||
config_path: Path | str,
|
||||
n_jobs: int | None = None,
|
||||
f0_method: Literal["crepe", "crepe-tiny", "parselmouth", "dio", "harvest"] = "dio",
|
||||
force_rebuild: bool = False,
|
||||
):
|
||||
input_dir = Path(input_dir)
|
||||
config_path = Path(config_path)
|
||||
hps = utils.get_hparams(config_path)
|
||||
if n_jobs is None:
|
||||
# add cpu_count() to avoid SIGKILL
|
||||
memory = get_total_gpu_memory("total")
|
||||
n_jobs = min(
|
||||
max(
|
||||
memory
|
||||
// (HUBERT_MEMORY_CREPE if f0_method == "crepe" else HUBERT_MEMORY)
|
||||
if memory is not None
|
||||
else 1,
|
||||
1,
|
||||
),
|
||||
cpu_count(),
|
||||
)
|
||||
LOG.info(f"n_jobs automatically set to {n_jobs}, memory: {memory} MiB")
|
||||
|
||||
filepaths = list(input_dir.rglob("*.wav"))
|
||||
n_jobs = min(len(filepaths) // 16 + 1, n_jobs)
|
||||
shuffle(filepaths)
|
||||
filepath_chunks = np.array_split(filepaths, n_jobs)
|
||||
Parallel(n_jobs=n_jobs)(
|
||||
delayed(_process_batch)(
|
||||
filepaths=chunk,
|
||||
pbar_position=pbar_position,
|
||||
f0_method=f0_method,
|
||||
force_rebuild=force_rebuild,
|
||||
hps=hps,
|
||||
)
|
||||
for (pbar_position, chunk) in enumerate(filepath_chunks)
|
||||
)
|
||||
+143
@@ -0,0 +1,143 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import warnings
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Iterable
|
||||
|
||||
import librosa
|
||||
import soundfile
|
||||
from joblib import Parallel, delayed
|
||||
from tqdm_joblib import tqdm_joblib
|
||||
|
||||
from .preprocess_utils import check_hubert_min_duration
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
# input_dir and output_dir exists.
|
||||
# write code to convert input dir audio files to output dir audio files,
|
||||
# without changing folder structure. Use joblib to parallelize.
|
||||
# Converting audio files includes:
|
||||
# - resampling to specified sampling rate
|
||||
# - trim silence
|
||||
# - adjust volume in a smart way
|
||||
# - save as 16-bit wav file
|
||||
|
||||
|
||||
def _get_unique_filename(path: Path, existing_paths: Iterable[Path]) -> Path:
|
||||
"""Return a unique path by appending a number to the original path."""
|
||||
if path not in existing_paths:
|
||||
return path
|
||||
i = 1
|
||||
while True:
|
||||
new_path = path.parent / f"{path.stem}_{i}{path.suffix}"
|
||||
if new_path not in existing_paths:
|
||||
return new_path
|
||||
i += 1
|
||||
|
||||
|
||||
def is_relative_to(path: Path, *other):
|
||||
"""Return True if the path is relative to another path or False.
|
||||
Python 3.9+ has Path.is_relative_to() method, but we need to support Python 3.8.
|
||||
"""
|
||||
try:
|
||||
path.relative_to(*other)
|
||||
return True
|
||||
except ValueError:
|
||||
return False
|
||||
|
||||
|
||||
def _preprocess_one(
|
||||
input_path: Path,
|
||||
output_path: Path,
|
||||
sr: int,
|
||||
*,
|
||||
top_db: int,
|
||||
frame_seconds: float,
|
||||
hop_seconds: float,
|
||||
) -> None:
|
||||
"""Preprocess one audio file."""
|
||||
|
||||
try:
|
||||
audio, sr = librosa.load(input_path, sr=sr, mono=True)
|
||||
|
||||
# Audioread is the last backend it will attempt, so this is the exception thrown on failure
|
||||
except Exception as e:
|
||||
# Failure due to attempting to load a file that is not audio, so return early
|
||||
LOG.warning(f"Failed to load {input_path} due to {e}")
|
||||
return
|
||||
|
||||
if not check_hubert_min_duration(audio, sr):
|
||||
LOG.info(f"Skip {input_path} because it is too short.")
|
||||
return
|
||||
|
||||
# Adjust volume
|
||||
audio /= max(audio.max(), -audio.min())
|
||||
|
||||
# Trim silence
|
||||
audio, _ = librosa.effects.trim(
|
||||
audio,
|
||||
top_db=top_db,
|
||||
frame_length=int(frame_seconds * sr),
|
||||
hop_length=int(hop_seconds * sr),
|
||||
)
|
||||
|
||||
if not check_hubert_min_duration(audio, sr):
|
||||
LOG.info(f"Skip {input_path} because it is too short.")
|
||||
return
|
||||
|
||||
soundfile.write(output_path, audio, samplerate=sr, subtype="PCM_16")
|
||||
|
||||
|
||||
def preprocess_resample(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str,
|
||||
sampling_rate: int,
|
||||
n_jobs: int = -1,
|
||||
*,
|
||||
top_db: int = 30,
|
||||
frame_seconds: float = 0.1,
|
||||
hop_seconds: float = 0.05,
|
||||
) -> None:
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
"""Preprocess audio files in input_dir and save them to output_dir."""
|
||||
|
||||
in_paths = []
|
||||
out_paths = []
|
||||
for in_path in input_dir.rglob("*.*"):
|
||||
in_path_relative = in_path.relative_to(input_dir)
|
||||
if not in_path.is_absolute() and is_relative_to(
|
||||
in_path, Path("dataset_raw") / "44k"
|
||||
):
|
||||
new_in_path_relative = in_path_relative.relative_to("44k")
|
||||
warnings.warn(
|
||||
f"Recommended folder structure has changed since v1.0.0. "
|
||||
"Please move your dataset directly under dataset_raw folder. "
|
||||
f"Recoginzed {in_path_relative} as {new_in_path_relative}"
|
||||
)
|
||||
in_path_relative = new_in_path_relative
|
||||
|
||||
if len(in_path_relative.parts) < 2:
|
||||
continue
|
||||
speaker_name = in_path_relative.parts[0]
|
||||
file_name = in_path_relative.with_suffix(".wav").name
|
||||
out_path = output_dir / speaker_name / file_name
|
||||
out_path = _get_unique_filename(out_path, out_paths)
|
||||
out_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
in_paths.append(in_path)
|
||||
out_paths.append(out_path)
|
||||
|
||||
in_and_out_paths = list(zip(in_paths, out_paths))
|
||||
|
||||
with tqdm_joblib(desc="Preprocessing", total=len(in_and_out_paths)):
|
||||
Parallel(n_jobs=n_jobs)(
|
||||
delayed(_preprocess_one)(
|
||||
*args,
|
||||
sr=sampling_rate,
|
||||
top_db=top_db,
|
||||
frame_seconds=frame_seconds,
|
||||
hop_seconds=hop_seconds,
|
||||
)
|
||||
for args in in_and_out_paths
|
||||
)
|
||||
+93
@@ -0,0 +1,93 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from collections import defaultdict
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import librosa
|
||||
import soundfile as sf
|
||||
import torch
|
||||
from joblib import Parallel, delayed
|
||||
from pyannote.audio import Pipeline
|
||||
from tqdm import tqdm
|
||||
from tqdm_joblib import tqdm_joblib
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def _process_one(
|
||||
input_path: Path,
|
||||
output_dir: Path,
|
||||
sr: int,
|
||||
*,
|
||||
min_speakers: int = 1,
|
||||
max_speakers: int = 1,
|
||||
huggingface_token: str | None = None,
|
||||
) -> None:
|
||||
try:
|
||||
audio, sr = librosa.load(input_path, sr=sr, mono=True)
|
||||
except Exception as e:
|
||||
LOG.warning(f"Failed to read {input_path}: {e}")
|
||||
return
|
||||
pipeline = Pipeline.from_pretrained(
|
||||
"pyannote/speaker-diarization", use_auth_token=huggingface_token
|
||||
)
|
||||
if pipeline is None:
|
||||
raise ValueError("Failed to load pipeline")
|
||||
|
||||
LOG.info(f"Processing {input_path}. This may take a while...")
|
||||
diarization = pipeline(
|
||||
input_path, min_speakers=min_speakers, max_speakers=max_speakers
|
||||
)
|
||||
|
||||
LOG.info(f"Found {len(diarization)} tracks, writing to {output_dir}")
|
||||
speaker_count = defaultdict(int)
|
||||
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
for segment, track, speaker in tqdm(
|
||||
list(diarization.itertracks(yield_label=True)), desc=f"Writing {input_path}"
|
||||
):
|
||||
if segment.end - segment.start < 1:
|
||||
continue
|
||||
speaker_count[speaker] += 1
|
||||
audio_cut = audio[int(segment.start * sr) : int(segment.end * sr)]
|
||||
sf.write(
|
||||
(output_dir / f"{speaker}_{speaker_count[speaker]}.wav"),
|
||||
audio_cut,
|
||||
sr,
|
||||
)
|
||||
|
||||
LOG.info(f"Speaker count: {speaker_count}")
|
||||
|
||||
|
||||
def preprocess_speaker_diarization(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str,
|
||||
sr: int,
|
||||
*,
|
||||
min_speakers: int = 1,
|
||||
max_speakers: int = 1,
|
||||
huggingface_token: str | None = None,
|
||||
n_jobs: int = -1,
|
||||
) -> None:
|
||||
if huggingface_token is not None and not huggingface_token.startswith("hf_"):
|
||||
LOG.warning("Huggingface token probably should start with hf_")
|
||||
if not torch.cuda.is_available():
|
||||
LOG.warning("CUDA is not available. This will be extremely slow.")
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
input_dir.mkdir(parents=True, exist_ok=True)
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
input_paths = list(input_dir.rglob("*.*"))
|
||||
with tqdm_joblib(desc="Preprocessing speaker diarization", total=len(input_paths)):
|
||||
Parallel(n_jobs=n_jobs)(
|
||||
delayed(_process_one)(
|
||||
input_path,
|
||||
output_dir / input_path.relative_to(input_dir).parent / input_path.stem,
|
||||
sr,
|
||||
max_speakers=max_speakers,
|
||||
min_speakers=min_speakers,
|
||||
huggingface_token=huggingface_token,
|
||||
)
|
||||
for input_path in input_paths
|
||||
)
|
||||
+70
@@ -0,0 +1,70 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
|
||||
import librosa
|
||||
import soundfile as sf
|
||||
from joblib import Parallel, delayed
|
||||
from tqdm import tqdm
|
||||
from tqdm_joblib import tqdm_joblib
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
|
||||
|
||||
def _process_one(
|
||||
input_path: Path,
|
||||
output_dir: Path,
|
||||
sr: int,
|
||||
*,
|
||||
top_db: int = 30,
|
||||
frame_seconds: float = 0.5,
|
||||
hop_seconds: float = 0.1,
|
||||
):
|
||||
try:
|
||||
audio, sr = librosa.load(input_path, sr=sr, mono=True)
|
||||
except Exception as e:
|
||||
LOG.warning(f"Failed to read {input_path}: {e}")
|
||||
return
|
||||
intervals = librosa.effects.split(
|
||||
audio,
|
||||
top_db=top_db,
|
||||
frame_length=int(sr * frame_seconds),
|
||||
hop_length=int(sr * hop_seconds),
|
||||
)
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
for start, end in tqdm(intervals, desc=f"Writing {input_path}"):
|
||||
audio_cut = audio[start:end]
|
||||
sf.write(
|
||||
(output_dir / f"{input_path.stem}_{start / sr:.3f}_{end / sr:.3f}.wav"),
|
||||
audio_cut,
|
||||
sr,
|
||||
)
|
||||
|
||||
|
||||
def preprocess_split(
|
||||
input_dir: Path | str,
|
||||
output_dir: Path | str,
|
||||
sr: int,
|
||||
*,
|
||||
top_db: int = 30,
|
||||
frame_seconds: float = 0.5,
|
||||
hop_seconds: float = 0.1,
|
||||
n_jobs: int = -1,
|
||||
):
|
||||
input_dir = Path(input_dir)
|
||||
output_dir = Path(output_dir)
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
input_paths = list(input_dir.rglob("*.*"))
|
||||
with tqdm_joblib(desc="Splitting", total=len(input_paths)):
|
||||
Parallel(n_jobs=n_jobs)(
|
||||
delayed(_process_one)(
|
||||
input_path,
|
||||
output_dir / input_path.relative_to(input_dir).parent,
|
||||
sr,
|
||||
top_db=top_db,
|
||||
frame_seconds=frame_seconds,
|
||||
hop_seconds=hop_seconds,
|
||||
)
|
||||
for input_path in input_paths
|
||||
)
|
||||
+5
@@ -0,0 +1,5 @@
|
||||
from numpy import ndarray
|
||||
|
||||
|
||||
def check_hubert_min_duration(audio: ndarray, sr: int) -> bool:
|
||||
return len(audio) / sr >= 0.3
|
||||
@@ -0,0 +1,560 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
import warnings
|
||||
from logging import getLogger
|
||||
from multiprocessing import cpu_count
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import lightning.pytorch as pl
|
||||
import torch
|
||||
from lightning.pytorch.accelerators import MPSAccelerator, TPUAccelerator
|
||||
from lightning.pytorch.loggers import TensorBoardLogger
|
||||
from lightning.pytorch.strategies.ddp import DDPStrategy
|
||||
from lightning.pytorch.tuner import Tuner
|
||||
from torch.cuda.amp import autocast
|
||||
from torch.nn import functional as F
|
||||
from torch.utils.data import DataLoader
|
||||
from torch.utils.tensorboard.writer import SummaryWriter
|
||||
|
||||
import so_vits_svc_fork.f0
|
||||
import so_vits_svc_fork.modules.commons as commons
|
||||
import so_vits_svc_fork.utils
|
||||
|
||||
from . import utils
|
||||
from .dataset import TextAudioCollate, TextAudioDataset
|
||||
from .logger import is_notebook
|
||||
from .modules.descriminators import MultiPeriodDiscriminator
|
||||
from .modules.losses import discriminator_loss, feature_loss, generator_loss, kl_loss
|
||||
from .modules.mel_processing import mel_spectrogram_torch
|
||||
from .modules.synthesizers import SynthesizerTrn
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
torch.set_float32_matmul_precision("high")
|
||||
|
||||
|
||||
class VCDataModule(pl.LightningDataModule):
|
||||
batch_size: int
|
||||
|
||||
def __init__(self, hparams: Any):
|
||||
super().__init__()
|
||||
self.__hparams = hparams
|
||||
self.batch_size = hparams.train.batch_size
|
||||
if not isinstance(self.batch_size, int):
|
||||
self.batch_size = 1
|
||||
self.collate_fn = TextAudioCollate()
|
||||
|
||||
# these should be called in setup(), but we need to calculate check_val_every_n_epoch
|
||||
self.train_dataset = TextAudioDataset(self.__hparams, is_validation=False)
|
||||
self.val_dataset = TextAudioDataset(self.__hparams, is_validation=True)
|
||||
|
||||
def train_dataloader(self):
|
||||
return DataLoader(
|
||||
self.train_dataset,
|
||||
num_workers=min(cpu_count(), self.__hparams.train.get("num_workers", 8)),
|
||||
batch_size=self.batch_size,
|
||||
collate_fn=self.collate_fn,
|
||||
persistent_workers=True,
|
||||
)
|
||||
|
||||
def val_dataloader(self):
|
||||
return DataLoader(
|
||||
self.val_dataset,
|
||||
batch_size=1,
|
||||
collate_fn=self.collate_fn,
|
||||
)
|
||||
|
||||
|
||||
def train(
|
||||
config_path: Path | str, model_path: Path | str, reset_optimizer: bool = False
|
||||
):
|
||||
config_path = Path(config_path)
|
||||
model_path = Path(model_path)
|
||||
|
||||
hparams = utils.get_backup_hparams(config_path, model_path)
|
||||
utils.ensure_pretrained_model(model_path, hparams.model.get("type_", "hifi-gan"))
|
||||
|
||||
datamodule = VCDataModule(hparams)
|
||||
strategy = (
|
||||
(
|
||||
"ddp_find_unused_parameters_true"
|
||||
if os.name != "nt"
|
||||
else DDPStrategy(find_unused_parameters=True, process_group_backend="gloo")
|
||||
)
|
||||
if torch.cuda.device_count() > 1
|
||||
else "auto"
|
||||
)
|
||||
LOG.info(f"Using strategy: {strategy}")
|
||||
trainer = pl.Trainer(
|
||||
logger=TensorBoardLogger(
|
||||
model_path, "lightning_logs", hparams.train.get("log_version", 0)
|
||||
),
|
||||
# profiler="simple",
|
||||
val_check_interval=hparams.train.eval_interval,
|
||||
max_epochs=hparams.train.epochs,
|
||||
check_val_every_n_epoch=None,
|
||||
precision="16-mixed"
|
||||
if hparams.train.fp16_run
|
||||
else "bf16-mixed"
|
||||
if hparams.train.get("bf16_run", False)
|
||||
else 32,
|
||||
strategy=strategy,
|
||||
callbacks=[pl.callbacks.RichProgressBar()] if not is_notebook() else None,
|
||||
benchmark=True,
|
||||
enable_checkpointing=False,
|
||||
)
|
||||
tuner = Tuner(trainer)
|
||||
model = VitsLightning(reset_optimizer=reset_optimizer, **hparams)
|
||||
|
||||
# automatic batch size scaling
|
||||
batch_size = hparams.train.batch_size
|
||||
batch_split = str(batch_size).split("-")
|
||||
batch_size = batch_split[0]
|
||||
init_val = 2 if len(batch_split) <= 1 else int(batch_split[1])
|
||||
max_trials = 25 if len(batch_split) <= 2 else int(batch_split[2])
|
||||
if batch_size == "auto":
|
||||
batch_size = "binsearch"
|
||||
if batch_size in ["power", "binsearch"]:
|
||||
model.tuning = True
|
||||
tuner.scale_batch_size(
|
||||
model,
|
||||
mode=batch_size,
|
||||
datamodule=datamodule,
|
||||
steps_per_trial=1,
|
||||
init_val=init_val,
|
||||
max_trials=max_trials,
|
||||
)
|
||||
model.tuning = False
|
||||
else:
|
||||
batch_size = int(batch_size)
|
||||
# automatic learning rate scaling is not supported for multiple optimizers
|
||||
"""if hparams.train.learning_rate == "auto":
|
||||
lr_finder = tuner.lr_find(model)
|
||||
LOG.info(lr_finder.results)
|
||||
fig = lr_finder.plot(suggest=True)
|
||||
fig.savefig(model_path / "lr_finder.png")"""
|
||||
|
||||
trainer.fit(model, datamodule=datamodule)
|
||||
|
||||
|
||||
class VitsLightning(pl.LightningModule):
|
||||
def __init__(self, reset_optimizer: bool = False, **hparams: Any):
|
||||
super().__init__()
|
||||
self._temp_epoch = 0 # Add this line to initialize the _temp_epoch attribute
|
||||
self.save_hyperparameters("reset_optimizer")
|
||||
self.save_hyperparameters(*[k for k in hparams.keys()])
|
||||
torch.manual_seed(self.hparams.train.seed)
|
||||
self.net_g = SynthesizerTrn(
|
||||
self.hparams.data.filter_length // 2 + 1,
|
||||
self.hparams.train.segment_size // self.hparams.data.hop_length,
|
||||
**self.hparams.model,
|
||||
)
|
||||
self.net_d = MultiPeriodDiscriminator(self.hparams.model.use_spectral_norm)
|
||||
self.automatic_optimization = False
|
||||
self.learning_rate = self.hparams.train.learning_rate
|
||||
self.optim_g = torch.optim.AdamW(
|
||||
self.net_g.parameters(),
|
||||
self.learning_rate,
|
||||
betas=self.hparams.train.betas,
|
||||
eps=self.hparams.train.eps,
|
||||
)
|
||||
self.optim_d = torch.optim.AdamW(
|
||||
self.net_d.parameters(),
|
||||
self.learning_rate,
|
||||
betas=self.hparams.train.betas,
|
||||
eps=self.hparams.train.eps,
|
||||
)
|
||||
self.scheduler_g = torch.optim.lr_scheduler.ExponentialLR(
|
||||
self.optim_g, gamma=self.hparams.train.lr_decay
|
||||
)
|
||||
self.scheduler_d = torch.optim.lr_scheduler.ExponentialLR(
|
||||
self.optim_d, gamma=self.hparams.train.lr_decay
|
||||
)
|
||||
self.optimizers_count = 2
|
||||
self.load(reset_optimizer)
|
||||
self.tuning = False
|
||||
|
||||
def on_train_start(self) -> None:
|
||||
if not self.tuning:
|
||||
self.set_current_epoch(self._temp_epoch)
|
||||
total_batch_idx = self._temp_epoch * len(self.trainer.train_dataloader)
|
||||
self.set_total_batch_idx(total_batch_idx)
|
||||
global_step = total_batch_idx * self.optimizers_count
|
||||
self.set_global_step(global_step)
|
||||
|
||||
# check if using tpu or mps
|
||||
if isinstance(self.trainer.accelerator, (TPUAccelerator, MPSAccelerator)):
|
||||
# patch torch.stft to use cpu
|
||||
LOG.warning("Using TPU/MPS. Patching torch.stft to use cpu.")
|
||||
|
||||
def stft(
|
||||
input: torch.Tensor,
|
||||
n_fft: int,
|
||||
hop_length: int | None = None,
|
||||
win_length: int | None = None,
|
||||
window: torch.Tensor | None = None,
|
||||
center: bool = True,
|
||||
pad_mode: str = "reflect",
|
||||
normalized: bool = False,
|
||||
onesided: bool | None = None,
|
||||
return_complex: bool | None = None,
|
||||
) -> torch.Tensor:
|
||||
device = input.device
|
||||
input = input.cpu()
|
||||
if window is not None:
|
||||
window = window.cpu()
|
||||
return torch.functional.stft(
|
||||
input,
|
||||
n_fft,
|
||||
hop_length,
|
||||
win_length,
|
||||
window,
|
||||
center,
|
||||
pad_mode,
|
||||
normalized,
|
||||
onesided,
|
||||
return_complex,
|
||||
).to(device)
|
||||
|
||||
torch.stft = stft
|
||||
|
||||
elif "bf" in self.trainer.precision:
|
||||
LOG.warning("Using bf. Patching torch.stft to use fp32.")
|
||||
|
||||
def stft(
|
||||
input: torch.Tensor,
|
||||
n_fft: int,
|
||||
hop_length: int | None = None,
|
||||
win_length: int | None = None,
|
||||
window: torch.Tensor | None = None,
|
||||
center: bool = True,
|
||||
pad_mode: str = "reflect",
|
||||
normalized: bool = False,
|
||||
onesided: bool | None = None,
|
||||
return_complex: bool | None = None,
|
||||
) -> torch.Tensor:
|
||||
dtype = input.dtype
|
||||
input = input.float()
|
||||
if window is not None:
|
||||
window = window.float()
|
||||
return torch.functional.stft(
|
||||
input,
|
||||
n_fft,
|
||||
hop_length,
|
||||
win_length,
|
||||
window,
|
||||
center,
|
||||
pad_mode,
|
||||
normalized,
|
||||
onesided,
|
||||
return_complex,
|
||||
).to(dtype)
|
||||
|
||||
torch.stft = stft
|
||||
|
||||
def on_train_end(self) -> None:
|
||||
self.save_checkpoints(adjust=0)
|
||||
|
||||
def save_checkpoints(self, adjust=1):
|
||||
if self.tuning or self.trainer.sanity_checking:
|
||||
return
|
||||
|
||||
# only save checkpoints if we are on the main device
|
||||
if (
|
||||
hasattr(self.device, "index")
|
||||
and self.device.index != None
|
||||
and self.device.index != 0
|
||||
):
|
||||
return
|
||||
|
||||
# `on_train_end` will be the actual epoch, not a -1, so we have to call it with `adjust = 0`
|
||||
current_epoch = self.current_epoch + adjust
|
||||
total_batch_idx = self.total_batch_idx - 1 + adjust
|
||||
|
||||
utils.save_checkpoint(
|
||||
self.net_g,
|
||||
self.optim_g,
|
||||
self.learning_rate,
|
||||
current_epoch,
|
||||
Path(self.hparams.model_dir)
|
||||
/ f"G_{total_batch_idx if self.hparams.train.get('ckpt_name_by_step', False) else current_epoch}.pth",
|
||||
)
|
||||
utils.save_checkpoint(
|
||||
self.net_d,
|
||||
self.optim_d,
|
||||
self.learning_rate,
|
||||
current_epoch,
|
||||
Path(self.hparams.model_dir)
|
||||
/ f"D_{total_batch_idx if self.hparams.train.get('ckpt_name_by_step', False) else current_epoch}.pth",
|
||||
)
|
||||
keep_ckpts = self.hparams.train.get("keep_ckpts", 0)
|
||||
if keep_ckpts > 0:
|
||||
utils.clean_checkpoints(
|
||||
path_to_models=self.hparams.model_dir,
|
||||
n_ckpts_to_keep=keep_ckpts,
|
||||
sort_by_time=True,
|
||||
)
|
||||
|
||||
def set_current_epoch(self, epoch: int):
|
||||
LOG.info(f"Setting current epoch to {epoch}")
|
||||
self.trainer.fit_loop.epoch_progress.current.completed = epoch
|
||||
self.trainer.fit_loop.epoch_progress.current.processed = epoch
|
||||
assert self.current_epoch == epoch, f"{self.current_epoch} != {epoch}"
|
||||
|
||||
def set_global_step(self, global_step: int):
|
||||
LOG.info(f"Setting global step to {global_step}")
|
||||
self.trainer.fit_loop.epoch_loop.manual_optimization.optim_step_progress.total.completed = (
|
||||
global_step
|
||||
)
|
||||
self.trainer.fit_loop.epoch_loop.automatic_optimization.optim_progress.optimizer.step.total.completed = (
|
||||
global_step
|
||||
)
|
||||
assert self.global_step == global_step, f"{self.global_step} != {global_step}"
|
||||
|
||||
def set_total_batch_idx(self, total_batch_idx: int):
|
||||
LOG.info(f"Setting total batch idx to {total_batch_idx}")
|
||||
self.trainer.fit_loop.epoch_loop.batch_progress.total.ready = (
|
||||
total_batch_idx + 1
|
||||
)
|
||||
self.trainer.fit_loop.epoch_loop.batch_progress.total.completed = (
|
||||
total_batch_idx
|
||||
)
|
||||
assert (
|
||||
self.total_batch_idx == total_batch_idx + 1
|
||||
), f"{self.total_batch_idx} != {total_batch_idx + 1}"
|
||||
|
||||
@property
|
||||
def total_batch_idx(self) -> int:
|
||||
return self.trainer.fit_loop.epoch_loop.total_batch_idx + 1
|
||||
|
||||
def load(self, reset_optimizer: bool = False):
|
||||
latest_g_path = utils.latest_checkpoint_path(self.hparams.model_dir, "G_*.pth")
|
||||
latest_d_path = utils.latest_checkpoint_path(self.hparams.model_dir, "D_*.pth")
|
||||
if latest_g_path is not None and latest_d_path is not None:
|
||||
try:
|
||||
_, _, _, epoch = utils.load_checkpoint(
|
||||
latest_g_path,
|
||||
self.net_g,
|
||||
self.optim_g,
|
||||
reset_optimizer,
|
||||
)
|
||||
_, _, _, epoch = utils.load_checkpoint(
|
||||
latest_d_path,
|
||||
self.net_d,
|
||||
self.optim_d,
|
||||
reset_optimizer,
|
||||
)
|
||||
self._temp_epoch = epoch
|
||||
self.scheduler_g.last_epoch = epoch - 1
|
||||
self.scheduler_d.last_epoch = epoch - 1
|
||||
except Exception as e:
|
||||
raise RuntimeError("Failed to load checkpoint") from e
|
||||
else:
|
||||
LOG.warning("No checkpoint found. Start from scratch.")
|
||||
|
||||
def configure_optimizers(self):
|
||||
return [self.optim_g, self.optim_d], [self.scheduler_g, self.scheduler_d]
|
||||
|
||||
def log_image_dict(
|
||||
self, image_dict: dict[str, Any], dataformats: str = "HWC"
|
||||
) -> None:
|
||||
if not isinstance(self.logger, TensorBoardLogger):
|
||||
warnings.warn("Image logging is only supported with TensorBoardLogger.")
|
||||
return
|
||||
writer: SummaryWriter = self.logger.experiment
|
||||
for k, v in image_dict.items():
|
||||
try:
|
||||
writer.add_image(k, v, self.total_batch_idx, dataformats=dataformats)
|
||||
except Exception as e:
|
||||
warnings.warn(f"Failed to log image {k}: {e}")
|
||||
|
||||
def log_audio_dict(self, audio_dict: dict[str, Any]) -> None:
|
||||
if not isinstance(self.logger, TensorBoardLogger):
|
||||
warnings.warn("Audio logging is only supported with TensorBoardLogger.")
|
||||
return
|
||||
writer: SummaryWriter = self.logger.experiment
|
||||
for k, v in audio_dict.items():
|
||||
writer.add_audio(
|
||||
k,
|
||||
v.float(),
|
||||
self.total_batch_idx,
|
||||
sample_rate=self.hparams.data.sampling_rate,
|
||||
)
|
||||
|
||||
def log_dict_(self, log_dict: dict[str, Any], **kwargs) -> None:
|
||||
if not isinstance(self.logger, TensorBoardLogger):
|
||||
warnings.warn("Logging is only supported with TensorBoardLogger.")
|
||||
return
|
||||
writer: SummaryWriter = self.logger.experiment
|
||||
for k, v in log_dict.items():
|
||||
writer.add_scalar(k, v, self.total_batch_idx)
|
||||
kwargs["logger"] = False
|
||||
self.log_dict(log_dict, **kwargs)
|
||||
|
||||
def log_(self, key: str, value: Any, **kwargs) -> None:
|
||||
self.log_dict_({key: value}, **kwargs)
|
||||
|
||||
def training_step(self, batch: dict[str, torch.Tensor], batch_idx: int) -> None:
|
||||
self.net_g.train()
|
||||
self.net_d.train()
|
||||
|
||||
# get optims
|
||||
optim_g, optim_d = self.optimizers()
|
||||
|
||||
# Generator
|
||||
# train
|
||||
self.toggle_optimizer(optim_g)
|
||||
c, f0, spec, mel, y, g, lengths, uv = batch
|
||||
(
|
||||
y_hat,
|
||||
y_hat_mb,
|
||||
ids_slice,
|
||||
z_mask,
|
||||
(z, z_p, m_p, logs_p, m_q, logs_q),
|
||||
pred_lf0,
|
||||
norm_lf0,
|
||||
lf0,
|
||||
) = self.net_g(c, f0, uv, spec, g=g, c_lengths=lengths, spec_lengths=lengths)
|
||||
y_mel = commons.slice_segments(
|
||||
mel,
|
||||
ids_slice,
|
||||
self.hparams.train.segment_size // self.hparams.data.hop_length,
|
||||
)
|
||||
y_hat_mel = mel_spectrogram_torch(y_hat.squeeze(1), self.hparams)
|
||||
y_mel = y_mel[..., : y_hat_mel.shape[-1]]
|
||||
y = commons.slice_segments(
|
||||
y,
|
||||
ids_slice * self.hparams.data.hop_length,
|
||||
self.hparams.train.segment_size,
|
||||
)
|
||||
y = y[..., : y_hat.shape[-1]]
|
||||
|
||||
# generator loss
|
||||
y_d_hat_r, y_d_hat_g, fmap_r, fmap_g = self.net_d(y, y_hat)
|
||||
|
||||
with autocast(enabled=False):
|
||||
loss_mel = F.l1_loss(y_mel, y_hat_mel) * self.hparams.train.c_mel
|
||||
loss_kl = (
|
||||
kl_loss(z_p, logs_q, m_p, logs_p, z_mask) * self.hparams.train.c_kl
|
||||
)
|
||||
loss_fm = feature_loss(fmap_r, fmap_g)
|
||||
loss_gen, losses_gen = generator_loss(y_d_hat_g)
|
||||
loss_lf0 = F.mse_loss(pred_lf0, lf0)
|
||||
loss_gen_all = loss_gen + loss_fm + loss_mel + loss_kl + loss_lf0
|
||||
|
||||
# MB-iSTFT-VITS
|
||||
loss_subband = torch.tensor(0.0)
|
||||
if self.hparams.model.get("type_") == "mb-istft":
|
||||
from .modules.decoders.mb_istft import PQMF, subband_stft_loss
|
||||
|
||||
y_mb = PQMF(y.device, self.hparams.model.subbands).analysis(y)
|
||||
loss_subband = subband_stft_loss(self.hparams, y_mb, y_hat_mb)
|
||||
loss_gen_all += loss_subband
|
||||
|
||||
# log loss
|
||||
self.log_("lr", self.optim_g.param_groups[0]["lr"])
|
||||
self.log_dict_(
|
||||
{
|
||||
"loss/g/total": loss_gen_all,
|
||||
"loss/g/fm": loss_fm,
|
||||
"loss/g/mel": loss_mel,
|
||||
"loss/g/kl": loss_kl,
|
||||
"loss/g/lf0": loss_lf0,
|
||||
},
|
||||
prog_bar=True,
|
||||
)
|
||||
if self.hparams.model.get("type_") == "mb-istft":
|
||||
self.log_("loss/g/subband", loss_subband)
|
||||
if self.total_batch_idx % self.hparams.train.log_interval == 0:
|
||||
self.log_image_dict(
|
||||
{
|
||||
"slice/mel_org": utils.plot_spectrogram_to_numpy(
|
||||
y_mel[0].data.cpu().float().numpy()
|
||||
),
|
||||
"slice/mel_gen": utils.plot_spectrogram_to_numpy(
|
||||
y_hat_mel[0].data.cpu().float().numpy()
|
||||
),
|
||||
"all/mel": utils.plot_spectrogram_to_numpy(
|
||||
mel[0].data.cpu().float().numpy()
|
||||
),
|
||||
"all/lf0": so_vits_svc_fork.utils.plot_data_to_numpy(
|
||||
lf0[0, 0, :].cpu().float().numpy(),
|
||||
pred_lf0[0, 0, :].detach().cpu().float().numpy(),
|
||||
),
|
||||
"all/norm_lf0": so_vits_svc_fork.utils.plot_data_to_numpy(
|
||||
lf0[0, 0, :].cpu().float().numpy(),
|
||||
norm_lf0[0, 0, :].detach().cpu().float().numpy(),
|
||||
),
|
||||
}
|
||||
)
|
||||
|
||||
accumulate_grad_batches = self.hparams.train.get("accumulate_grad_batches", 1)
|
||||
should_update = (
|
||||
batch_idx + 1
|
||||
) % accumulate_grad_batches == 0 or self.trainer.is_last_batch
|
||||
# optimizer
|
||||
self.manual_backward(loss_gen_all / accumulate_grad_batches)
|
||||
if should_update:
|
||||
self.log_(
|
||||
"grad_norm_g", commons.clip_grad_value_(self.net_g.parameters(), None)
|
||||
)
|
||||
optim_g.step()
|
||||
optim_g.zero_grad()
|
||||
self.untoggle_optimizer(optim_g)
|
||||
|
||||
# Discriminator
|
||||
# train
|
||||
self.toggle_optimizer(optim_d)
|
||||
y_d_hat_r, y_d_hat_g, _, _ = self.net_d(y, y_hat.detach())
|
||||
|
||||
# discriminator loss
|
||||
with autocast(enabled=False):
|
||||
loss_disc, losses_disc_r, losses_disc_g = discriminator_loss(
|
||||
y_d_hat_r, y_d_hat_g
|
||||
)
|
||||
loss_disc_all = loss_disc
|
||||
|
||||
# log loss
|
||||
self.log_("loss/d/total", loss_disc_all, prog_bar=True)
|
||||
|
||||
# optimizer
|
||||
self.manual_backward(loss_disc_all / accumulate_grad_batches)
|
||||
if should_update:
|
||||
self.log_(
|
||||
"grad_norm_d", commons.clip_grad_value_(self.net_d.parameters(), None)
|
||||
)
|
||||
optim_d.step()
|
||||
optim_d.zero_grad()
|
||||
self.untoggle_optimizer(optim_d)
|
||||
|
||||
# end of epoch
|
||||
if self.trainer.is_last_batch:
|
||||
self.scheduler_g.step()
|
||||
self.scheduler_d.step()
|
||||
|
||||
def validation_step(self, batch, batch_idx):
|
||||
# avoid logging with wrong global step
|
||||
if self.global_step == 0:
|
||||
return
|
||||
with torch.no_grad():
|
||||
self.net_g.eval()
|
||||
c, f0, _, mel, y, g, _, uv = batch
|
||||
y_hat = self.net_g.infer(c, f0, uv, g=g)
|
||||
y_hat_mel = mel_spectrogram_torch(y_hat.squeeze(1).float(), self.hparams)
|
||||
self.log_audio_dict(
|
||||
{f"gen/audio_{batch_idx}": y_hat[0], f"gt/audio_{batch_idx}": y[0]}
|
||||
)
|
||||
self.log_image_dict(
|
||||
{
|
||||
"gen/mel": utils.plot_spectrogram_to_numpy(
|
||||
y_hat_mel[0].cpu().float().numpy()
|
||||
),
|
||||
"gt/mel": utils.plot_spectrogram_to_numpy(
|
||||
mel[0].cpu().float().numpy()
|
||||
),
|
||||
}
|
||||
)
|
||||
|
||||
def on_validation_end(self) -> None:
|
||||
self.save_checkpoints()
|
||||
@@ -0,0 +1,430 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import re
|
||||
import subprocess
|
||||
import warnings
|
||||
from itertools import groupby
|
||||
from logging import getLogger
|
||||
from pathlib import Path
|
||||
from typing import Any, Literal, Sequence
|
||||
|
||||
import matplotlib
|
||||
import matplotlib.pylab as plt
|
||||
import numpy as np
|
||||
import requests
|
||||
import torch
|
||||
import torch.backends.mps
|
||||
import torch.nn as nn
|
||||
import torchaudio
|
||||
from cm_time import timer
|
||||
from numpy import ndarray
|
||||
from tqdm import tqdm
|
||||
from transformers import HubertModel
|
||||
|
||||
from so_vits_svc_fork.hparams import HParams
|
||||
|
||||
LOG = getLogger(__name__)
|
||||
HUBERT_SAMPLING_RATE = 16000
|
||||
|
||||
|
||||
def get_optimal_device(index: int = 0) -> torch.device:
|
||||
if torch.cuda.is_available():
|
||||
return torch.device(f"cuda:{index % torch.cuda.device_count()}")
|
||||
elif torch.backends.mps.is_available():
|
||||
return torch.device("mps")
|
||||
else:
|
||||
try:
|
||||
import torch_xla.core.xla_model as xm # noqa
|
||||
|
||||
if xm.xrt_world_size() > 0:
|
||||
return torch.device("xla")
|
||||
# return xm.xla_device()
|
||||
except ImportError:
|
||||
pass
|
||||
return torch.device("cpu")
|
||||
|
||||
|
||||
def download_file(
|
||||
url: str,
|
||||
filepath: Path | str,
|
||||
chunk_size: int = 64 * 1024,
|
||||
tqdm_cls: type = tqdm,
|
||||
skip_if_exists: bool = False,
|
||||
overwrite: bool = False,
|
||||
**tqdm_kwargs: Any,
|
||||
):
|
||||
if skip_if_exists is True and overwrite is True:
|
||||
raise ValueError("skip_if_exists and overwrite cannot be both True")
|
||||
filepath = Path(filepath)
|
||||
filepath.parent.mkdir(parents=True, exist_ok=True)
|
||||
temppath = filepath.parent / f"{filepath.name}.download"
|
||||
if filepath.exists():
|
||||
if skip_if_exists:
|
||||
return
|
||||
elif not overwrite:
|
||||
filepath.unlink()
|
||||
else:
|
||||
raise FileExistsError(f"{filepath} already exists")
|
||||
temppath.unlink(missing_ok=True)
|
||||
resp = requests.get(url, stream=True)
|
||||
total = int(resp.headers.get("content-length", 0))
|
||||
kwargs = dict(
|
||||
total=total,
|
||||
unit="iB",
|
||||
unit_scale=True,
|
||||
unit_divisor=1024,
|
||||
desc=f"Downloading {filepath.name}",
|
||||
)
|
||||
kwargs.update(tqdm_kwargs)
|
||||
with temppath.open("wb") as f, tqdm_cls(**kwargs) as pbar:
|
||||
for data in resp.iter_content(chunk_size=chunk_size):
|
||||
size = f.write(data)
|
||||
pbar.update(size)
|
||||
temppath.rename(filepath)
|
||||
|
||||
|
||||
PRETRAINED_MODEL_URLS = {
|
||||
"hifi-gan": [
|
||||
[
|
||||
"https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/D_0.pth",
|
||||
"https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/G_0.pth",
|
||||
],
|
||||
[
|
||||
"https://huggingface.co/Himawari00/so-vits-svc4.0-pretrain-models/resolve/main/D_0.pth",
|
||||
"https://huggingface.co/Himawari00/so-vits-svc4.0-pretrain-models/resolve/main/G_0.pth",
|
||||
],
|
||||
],
|
||||
"contentvec": [
|
||||
[
|
||||
"https://huggingface.co/therealvul/so-vits-svc-4.0-init/resolve/main/checkpoint_best_legacy_500.pt"
|
||||
],
|
||||
[
|
||||
"https://huggingface.co/Himawari00/so-vits-svc4.0-pretrain-models/resolve/main/checkpoint_best_legacy_500.pt"
|
||||
],
|
||||
[
|
||||
"http://obs.cstcloud.cn/share/obs/sankagenkeshi/checkpoint_best_legacy_500.pt"
|
||||
],
|
||||
],
|
||||
}
|
||||
from joblib import Parallel, delayed
|
||||
|
||||
|
||||
def ensure_pretrained_model(
|
||||
folder_path: Path | str, type_: str, **tqdm_kwargs: Any
|
||||
) -> tuple[Path, ...] | None:
|
||||
folder_path = Path(folder_path)
|
||||
models_candidates = PRETRAINED_MODEL_URLS.get(type_, None)
|
||||
if models_candidates is None:
|
||||
LOG.warning(f"Unknown pretrained model type: {type_}")
|
||||
return
|
||||
for model_urls in models_candidates:
|
||||
paths = [folder_path / model_url.split("/")[-1] for model_url in model_urls]
|
||||
try:
|
||||
Parallel(n_jobs=len(paths))(
|
||||
[
|
||||
delayed(download_file)(
|
||||
url, path, position=i, skip_if_exists=True, **tqdm_kwargs
|
||||
)
|
||||
for i, (url, path) in enumerate(zip(model_urls, paths))
|
||||
]
|
||||
)
|
||||
return tuple(paths)
|
||||
except Exception as e:
|
||||
LOG.exception(e)
|
||||
return
|
||||
|
||||
|
||||
class HubertModelWithFinalProj(HubertModel):
|
||||
def __init__(self, config):
|
||||
super().__init__(config)
|
||||
|
||||
# The final projection layer is only used for backward compatibility.
|
||||
# Following https://github.com/auspicious3000/contentvec/issues/6
|
||||
# Remove this layer is necessary to achieve the desired outcome.
|
||||
self.final_proj = nn.Linear(config.hidden_size, config.classifier_proj_size)
|
||||
|
||||
|
||||
def get_hubert_model(
|
||||
device: str | torch.device, final_proj: bool = True
|
||||
) -> HubertModel:
|
||||
if final_proj:
|
||||
return HubertModelWithFinalProj.from_pretrained(
|
||||
"lengyue233/content-vec-best"
|
||||
).to(device)
|
||||
else:
|
||||
return HubertModel.from_pretrained("lengyue233/content-vec-best").to(device)
|
||||
|
||||
|
||||
def get_content(
|
||||
cmodel: HubertModel,
|
||||
audio: torch.Tensor | ndarray[Any, Any],
|
||||
device: torch.device | str,
|
||||
sr: int,
|
||||
legacy_final_proj: bool = False,
|
||||
) -> torch.Tensor:
|
||||
audio = torch.as_tensor(audio)
|
||||
if sr != HUBERT_SAMPLING_RATE:
|
||||
audio = (
|
||||
torchaudio.transforms.Resample(sr, HUBERT_SAMPLING_RATE)
|
||||
.to(audio.device)(audio)
|
||||
.to(device)
|
||||
)
|
||||
if audio.ndim == 1:
|
||||
audio = audio.unsqueeze(0)
|
||||
with torch.no_grad(), timer() as t:
|
||||
if legacy_final_proj:
|
||||
warnings.warn("legacy_final_proj is deprecated")
|
||||
if not hasattr(cmodel, "final_proj"):
|
||||
raise ValueError("HubertModel does not have final_proj")
|
||||
c = cmodel(audio, output_hidden_states=True)["hidden_states"][9]
|
||||
c = cmodel.final_proj(c)
|
||||
else:
|
||||
c = cmodel(audio)["last_hidden_state"]
|
||||
c = c.transpose(1, 2)
|
||||
wav_len = audio.shape[-1] / HUBERT_SAMPLING_RATE
|
||||
LOG.info(
|
||||
f"HuBERT inference time : {t.elapsed:.3f}s, RTF: {t.elapsed / wav_len:.3f}"
|
||||
)
|
||||
return c
|
||||
|
||||
|
||||
def _substitute_if_same_shape(to_: dict[str, Any], from_: dict[str, Any]) -> None:
|
||||
not_in_to = list(filter(lambda x: x not in to_, from_.keys()))
|
||||
not_in_from = list(filter(lambda x: x not in from_, to_.keys()))
|
||||
if not_in_to:
|
||||
warnings.warn(f"Keys not found in model state dict:" f"{not_in_to}")
|
||||
if not_in_from:
|
||||
warnings.warn(f"Keys not found in checkpoint state dict:" f"{not_in_from}")
|
||||
shape_missmatch = []
|
||||
for k, v in from_.items():
|
||||
if k not in to_:
|
||||
pass
|
||||
elif hasattr(v, "shape"):
|
||||
if not hasattr(to_[k], "shape"):
|
||||
raise ValueError(f"Key {k} is not a tensor")
|
||||
if to_[k].shape == v.shape:
|
||||
to_[k] = v
|
||||
else:
|
||||
shape_missmatch.append((k, to_[k].shape, v.shape))
|
||||
elif isinstance(v, dict):
|
||||
assert isinstance(to_[k], dict)
|
||||
_substitute_if_same_shape(to_[k], v)
|
||||
else:
|
||||
to_[k] = v
|
||||
if shape_missmatch:
|
||||
warnings.warn(
|
||||
f"Shape mismatch: {[f'{k}: {v1} -> {v2}' for k, v1, v2 in shape_missmatch]}"
|
||||
)
|
||||
|
||||
|
||||
def safe_load(model: torch.nn.Module, state_dict: dict[str, Any]) -> None:
|
||||
model_state_dict = model.state_dict()
|
||||
_substitute_if_same_shape(model_state_dict, state_dict)
|
||||
model.load_state_dict(model_state_dict)
|
||||
|
||||
|
||||
def load_checkpoint(
|
||||
checkpoint_path: Path | str,
|
||||
model: torch.nn.Module,
|
||||
optimizer: torch.optim.Optimizer | None = None,
|
||||
skip_optimizer: bool = False,
|
||||
) -> tuple[torch.nn.Module, torch.optim.Optimizer | None, float, int]:
|
||||
if not Path(checkpoint_path).is_file():
|
||||
raise FileNotFoundError(f"File {checkpoint_path} not found")
|
||||
with Path(checkpoint_path).open("rb") as f:
|
||||
with warnings.catch_warnings():
|
||||
warnings.filterwarnings(
|
||||
"ignore", category=UserWarning, message="TypedStorage is deprecated"
|
||||
)
|
||||
# NB(paul): iirc changing this to false prevented an error at some point
|
||||
# but it also worsens security
|
||||
checkpoint_dict = torch.load(f, map_location="cpu", weights_only=False)
|
||||
iteration = checkpoint_dict["iteration"]
|
||||
learning_rate = checkpoint_dict["learning_rate"]
|
||||
|
||||
# safe load module
|
||||
if hasattr(model, "module"):
|
||||
safe_load(model.module, checkpoint_dict["model"])
|
||||
else:
|
||||
safe_load(model, checkpoint_dict["model"])
|
||||
# safe load optim
|
||||
if (
|
||||
optimizer is not None
|
||||
and not skip_optimizer
|
||||
and checkpoint_dict["optimizer"] is not None
|
||||
):
|
||||
with warnings.catch_warnings():
|
||||
warnings.simplefilter("ignore")
|
||||
safe_load(optimizer, checkpoint_dict["optimizer"])
|
||||
|
||||
LOG.info(f"Loaded checkpoint '{checkpoint_path}' (epoch {iteration})")
|
||||
return model, optimizer, learning_rate, iteration
|
||||
|
||||
|
||||
def save_checkpoint(
|
||||
model: torch.nn.Module,
|
||||
optimizer: torch.optim.Optimizer,
|
||||
learning_rate: float,
|
||||
iteration: int,
|
||||
checkpoint_path: Path | str,
|
||||
) -> None:
|
||||
LOG.info(
|
||||
"Saving model and optimizer state at epoch {} to {}".format(
|
||||
iteration, checkpoint_path
|
||||
)
|
||||
)
|
||||
if hasattr(model, "module"):
|
||||
state_dict = model.module.state_dict()
|
||||
else:
|
||||
state_dict = model.state_dict()
|
||||
with Path(checkpoint_path).open("wb") as f:
|
||||
torch.save(
|
||||
{
|
||||
"model": state_dict,
|
||||
"iteration": iteration,
|
||||
"optimizer": optimizer.state_dict(),
|
||||
"learning_rate": learning_rate,
|
||||
},
|
||||
f,
|
||||
)
|
||||
|
||||
|
||||
def clean_checkpoints(
|
||||
path_to_models: Path | str, n_ckpts_to_keep: int = 2, sort_by_time: bool = True
|
||||
) -> None:
|
||||
"""Freeing up space by deleting saved ckpts
|
||||
|
||||
Arguments:
|
||||
path_to_models -- Path to the model directory
|
||||
n_ckpts_to_keep -- Number of ckpts to keep, excluding G_0.pth and D_0.pth
|
||||
sort_by_time -- True -> chronologically delete ckpts
|
||||
False -> lexicographically delete ckpts
|
||||
"""
|
||||
LOG.info("Cleaning old checkpoints...")
|
||||
path_to_models = Path(path_to_models)
|
||||
|
||||
# Define sort key functions
|
||||
name_key = lambda p: int(re.match(r"[GD]_(\d+)", p.stem).group(1))
|
||||
time_key = lambda p: p.stat().st_mtime
|
||||
path_key = lambda p: (p.stem[0], time_key(p) if sort_by_time else name_key(p))
|
||||
|
||||
models = list(
|
||||
filter(
|
||||
lambda p: (
|
||||
p.is_file()
|
||||
and re.match(r"[GD]_\d+", p.stem)
|
||||
and not p.stem.endswith("_0")
|
||||
),
|
||||
path_to_models.glob("*.pth"),
|
||||
)
|
||||
)
|
||||
|
||||
models_sorted = sorted(models, key=path_key)
|
||||
|
||||
models_sorted_grouped = groupby(models_sorted, lambda p: p.stem[0])
|
||||
|
||||
for group_name, group_items in models_sorted_grouped:
|
||||
to_delete_list = list(group_items)[:-n_ckpts_to_keep]
|
||||
|
||||
for to_delete in to_delete_list:
|
||||
if to_delete.exists():
|
||||
LOG.info(f"Removing {to_delete}")
|
||||
to_delete.unlink()
|
||||
|
||||
|
||||
def latest_checkpoint_path(dir_path: Path | str, regex: str = "G_*.pth") -> Path | None:
|
||||
dir_path = Path(dir_path)
|
||||
name_key = lambda p: int(re.match(r"._(\d+)\.pth", p.name).group(1))
|
||||
paths = list(sorted(dir_path.glob(regex), key=name_key))
|
||||
if len(paths) == 0:
|
||||
return None
|
||||
return paths[-1]
|
||||
|
||||
|
||||
def plot_spectrogram_to_numpy(spectrogram: ndarray) -> ndarray:
|
||||
matplotlib.use("Agg")
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
im = ax.imshow(spectrogram, aspect="auto", origin="lower", interpolation="none")
|
||||
plt.colorbar(im, ax=ax)
|
||||
plt.xlabel("Frames")
|
||||
plt.ylabel("Channels")
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep="")
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def get_backup_hparams(
|
||||
config_path: Path, model_path: Path, init: bool = True
|
||||
) -> HParams:
|
||||
model_path.mkdir(parents=True, exist_ok=True)
|
||||
config_save_path = model_path / "config.json"
|
||||
if init:
|
||||
with config_path.open() as f:
|
||||
data = f.read()
|
||||
with config_save_path.open("w") as f:
|
||||
f.write(data)
|
||||
else:
|
||||
with config_save_path.open() as f:
|
||||
data = f.read()
|
||||
config = json.loads(data)
|
||||
|
||||
hparams = HParams(**config)
|
||||
hparams.model_dir = model_path.as_posix()
|
||||
return hparams
|
||||
|
||||
|
||||
def get_hparams(config_path: Path | str) -> HParams:
|
||||
config = json.loads(Path(config_path).read_text("utf-8"))
|
||||
hparams = HParams(**config)
|
||||
return hparams
|
||||
|
||||
|
||||
def repeat_expand_2d(content: torch.Tensor, target_len: int) -> torch.Tensor:
|
||||
# content : [h, t]
|
||||
src_len = content.shape[-1]
|
||||
if target_len < src_len:
|
||||
return content[:, :target_len]
|
||||
else:
|
||||
return torch.nn.functional.interpolate(
|
||||
content.unsqueeze(0), size=target_len, mode="nearest"
|
||||
).squeeze(0)
|
||||
|
||||
|
||||
def plot_data_to_numpy(x: ndarray, y: ndarray) -> ndarray:
|
||||
matplotlib.use("Agg")
|
||||
fig, ax = plt.subplots(figsize=(10, 2))
|
||||
plt.plot(x)
|
||||
plt.plot(y)
|
||||
plt.tight_layout()
|
||||
|
||||
fig.canvas.draw()
|
||||
data = np.fromstring(fig.canvas.tostring_rgb(), dtype=np.uint8, sep="")
|
||||
data = data.reshape(fig.canvas.get_width_height()[::-1] + (3,))
|
||||
plt.close()
|
||||
return data
|
||||
|
||||
|
||||
def get_gpu_memory(type_: Literal["total", "free", "used"]) -> Sequence[int] | None:
|
||||
command = f"nvidia-smi --query-gpu=memory.{type_} --format=csv"
|
||||
try:
|
||||
memory_free_info = (
|
||||
subprocess.check_output(command.split())
|
||||
.decode("ascii")
|
||||
.split("\n")[:-1][1:]
|
||||
)
|
||||
memory_free_values = [int(x.split()[0]) for i, x in enumerate(memory_free_info)]
|
||||
return memory_free_values
|
||||
except Exception:
|
||||
return
|
||||
|
||||
|
||||
def get_total_gpu_memory(type_: Literal["total", "free", "used"]) -> int | None:
|
||||
memories = get_gpu_memory(type_)
|
||||
if memories is None:
|
||||
return
|
||||
return sum(memories)
|
||||
Reference in New Issue
Block a user